Topics / #embeddings
Embeddings projects on GitHub
Vector embeddings for semantic search and retrieval
As of , the most-starred Embeddings projects on GitHub are langchain (148K stars), awesome-llm-apps (142.2K stars) and supabase (111.7K stars). GitHub.Locker tracks 135 Embeddings repositories with 2.5M stars combined. The fastest-growing on October 17 was xerj, with +864 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
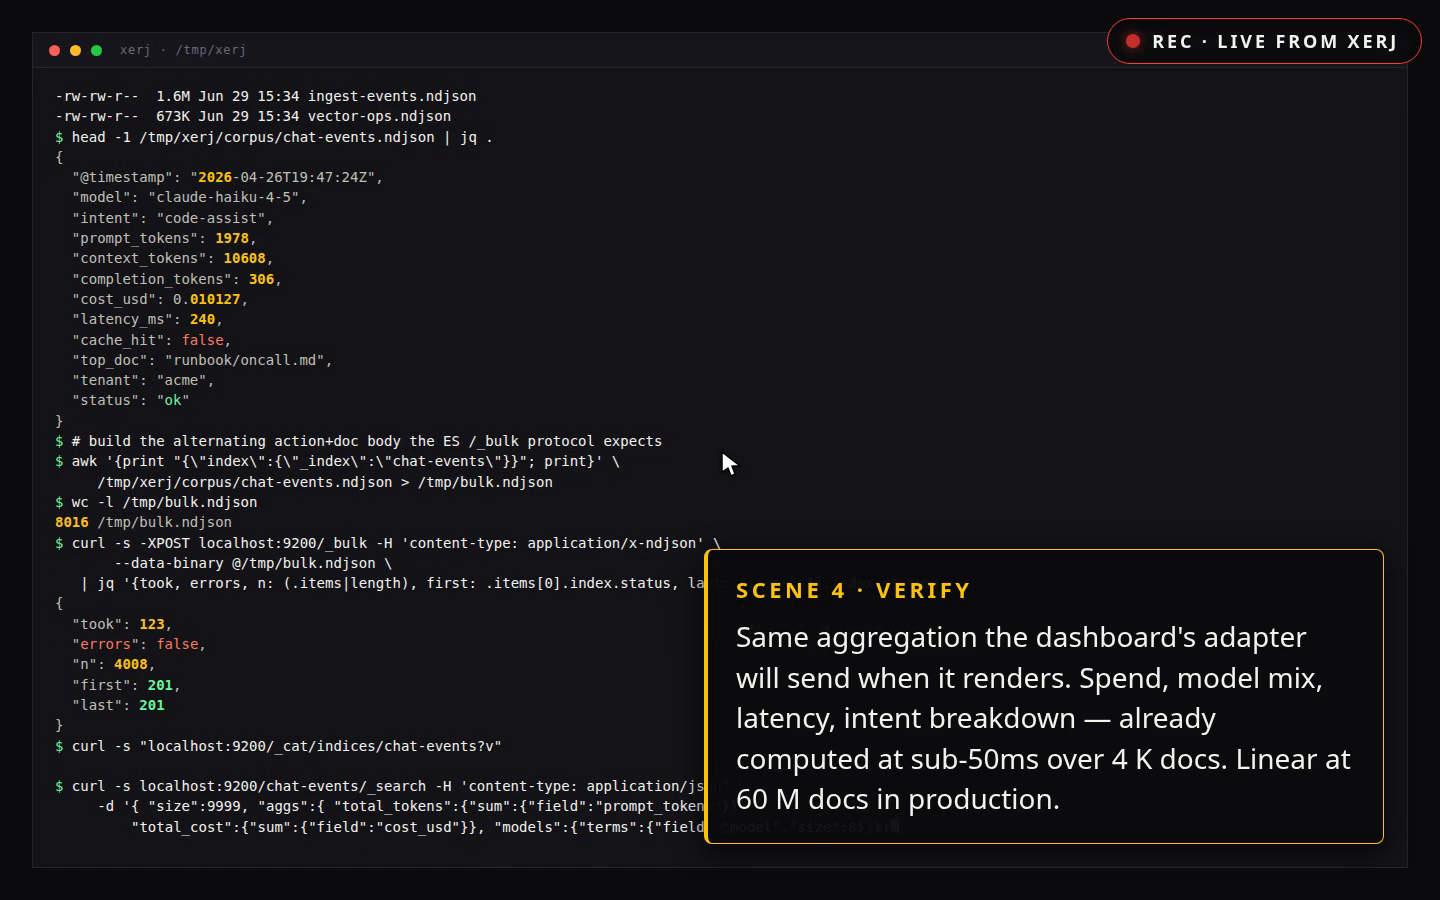 +864
xerj
xerj-org/xerj · ★ 7.8KXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
 +262
DigUp
ARahim3/DigUp · ★ 4.6KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
 +219
claude-mem
thedotmack/claude-mem · ★ 101.5KClaude-Mem gives coding agents persistent memory across sessions: it captures everything your agent does, compresses it with AI, and injects the relevant context back into future sessions.
pentagi
vxcontrol/pentagi · ★ 30.9KPentAGI (Penetration testing Artificial General Intelligence) is a fully autonomous AI agent system that performs complex penetration testing tasks for you.
The all-time top
Top 100 of 135 · by stars
- 148K
 #1 · langchain-ai/langchain
langchain
LangChain is a framework for building agents and LLM-powered applications: it chains together interoperable components and third-party integrations to simplify AI app development.
- 142.2K
 #2 · Shubhamsaboo/awesome-llm-apps
awesome-llm-apps
A collection of 100+ open-source AI agent, agent skill, and RAG app examples - hand-built, tested end-to-end, and released under Apache-2.0 so you can clone, run, or even sell them.
- 111.7K
 #3 · supabase/supabase
supabase
Supabase is an open source Postgres development platform that gives you a hosted Postgres database plus auth, auto-generated APIs, realtime subscriptions, storage, and edge functions, built as an open source alternative to Firebase.
- 4
claude-mem
101.5Kthedotmack/claude-mem · TypeScriptClaude-Mem gives coding agents persistent memory across sessions: it captures everything your agent does, compresses it with AI, and injects the relevant context back into future sessions.
- 5
unsloth
78.2Kunslothai/unsloth · PythonUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 6
the-algorithm
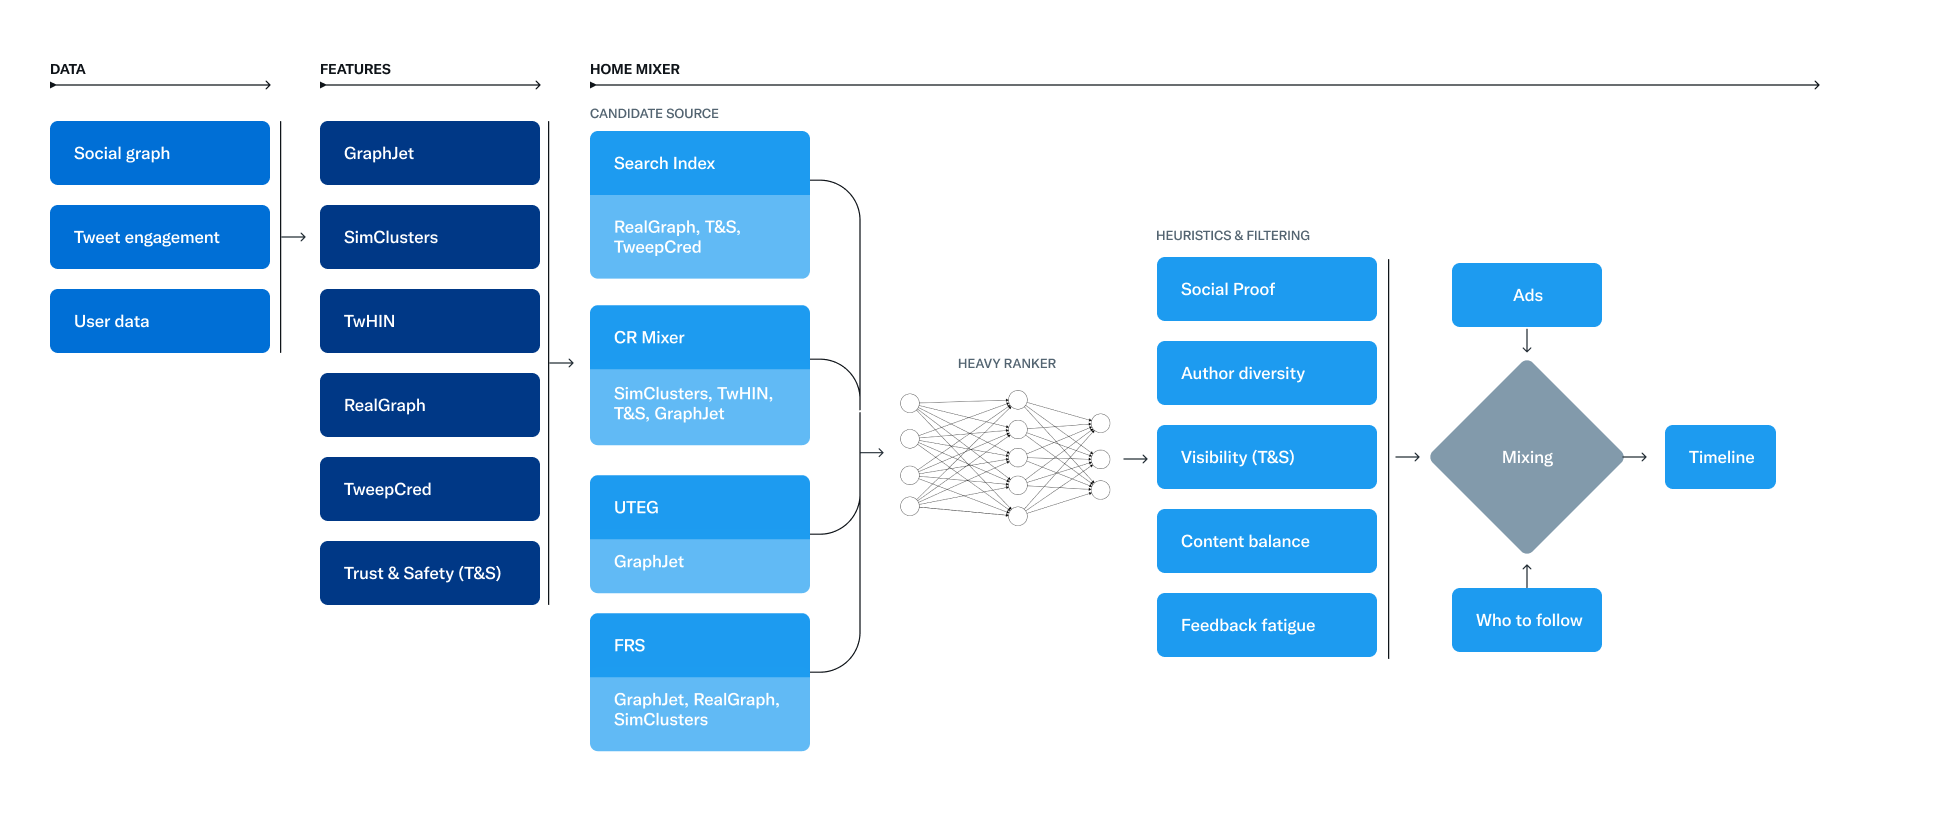
74Ktwitter/the-algorithm · ScalaThis is the actual source code for X's (Twitter's) recommendation algorithm — the collection of services and jobs that build and serve feeds like the For You Timeline, Search, Explore, and Notifications.
- 7
mem0
67.4Kmem0ai/mem0 · PythonMem0 is a memory layer for AI agents and apps: it stores user preferences and conversation history so your AI assistant remembers people across sessions instead of starting from zero every time.
- 8
private-gpt
57.6Kzylon-ai/private-gpt · PythonPrivateGPT is an open-source API layer that turns any local, OpenAI-compatible model into a full production-ready AI application backend, covering RAG, tools, MCP, text-to-sql and more.
- 9

claude-cookbooks
53.5Kanthropics/claude-cookbooks · Jupyter NotebookAnthropic's collection of notebooks and recipes showing fun and effective ways of using Claude, with copy-able code snippets you can drop straight into your own projects.
- 10

llama_index
52.5Krun-llama/llama_index · PythonLlamaIndex is an open-source Python framework for building agentic applications that augment LLMs with your own private data, letting you ingest, index, and query documents with LLM-powered pipelines.
- 11
GitNexus
47.9Kabhigyanpatwari/GitNexus · TypeScriptIt indexes any codebase into a knowledge graph — dependencies, call chains, clusters, execution flows — and serves it to AI coding agents via MCP tools so they stop making blind edits.
- 12
milvus
46.4Kmilvus-io/milvus · GoMilvus is a high-performance, cloud-native vector database built to store and search embedding vectors at scale for AI applications like semantic search, RAG, and recommendation systems.
- 13

faiss
41.2Kfacebookresearch/faiss · C++Faiss is a library for efficient similarity search and clustering of dense vectors, developed primarily at Meta's Fundamental AI Research group. It can search collections of vectors of any size, even ones that do not fit in RAM.
- 14
LightRAG
40.2KHKUDS/LightRAG · PythonLightRAG is an open-source, graph-based RAG framework (EMNLP 2025) by HKUDS. It indexes your documents into a knowledge graph plus vector embeddings so you can query them — a lighter, faster alternative to Microsoft GraphRAG.
- 15
bert
40Kgoogle-research/bert · PythonGoogle's official TensorFlow implementation of BERT together with pre-trained checkpoints — a method for pre-training language representations that set state-of-the-art results on a wide range of NLP tasks, from SQuAD question answering to natural language inference.
- 16
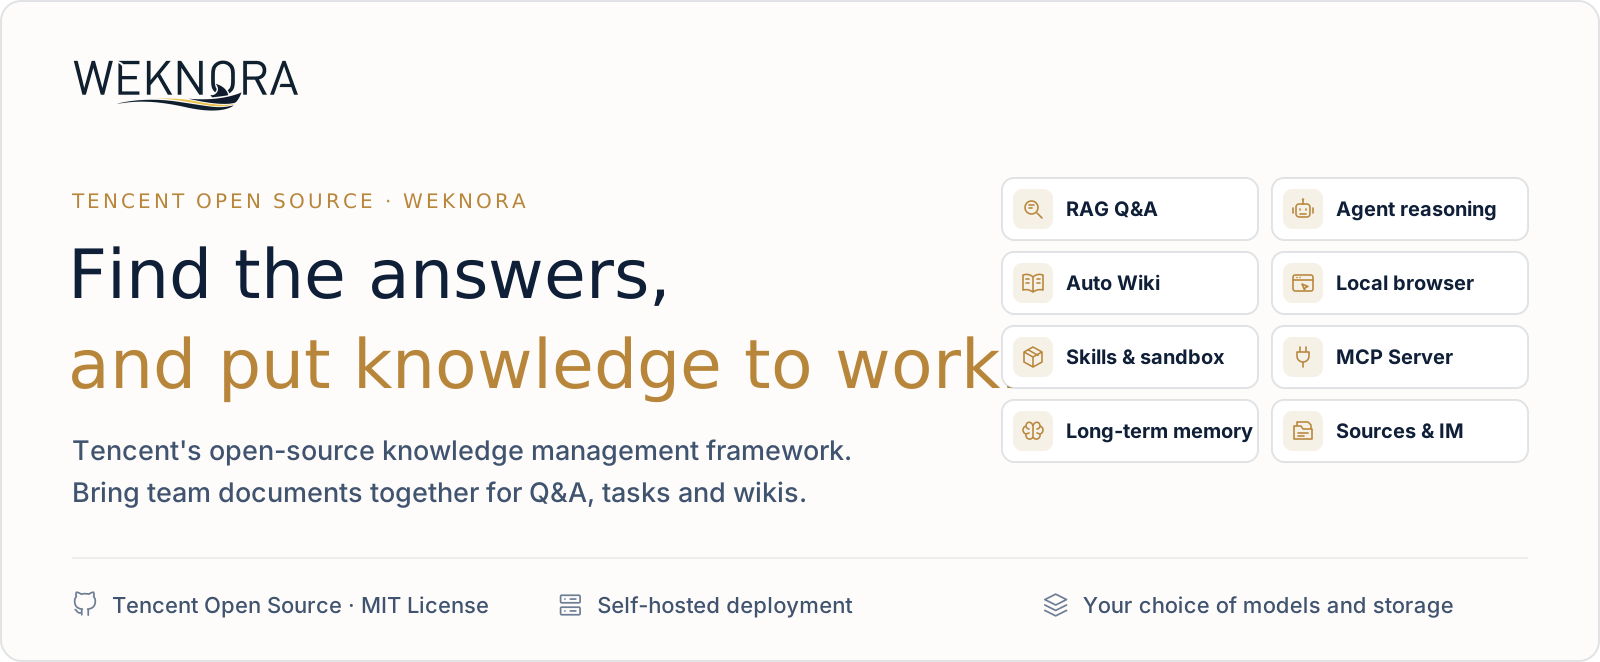
WeKnora
34.5KTencent/WeKnora · GoWeKnora is an open-source, self-hosted knowledge platform that turns raw documents into a queryable RAG knowledge base, an autonomous ReAct agent, and a self-maintaining Wiki with an interactive knowledge graph.
- 17
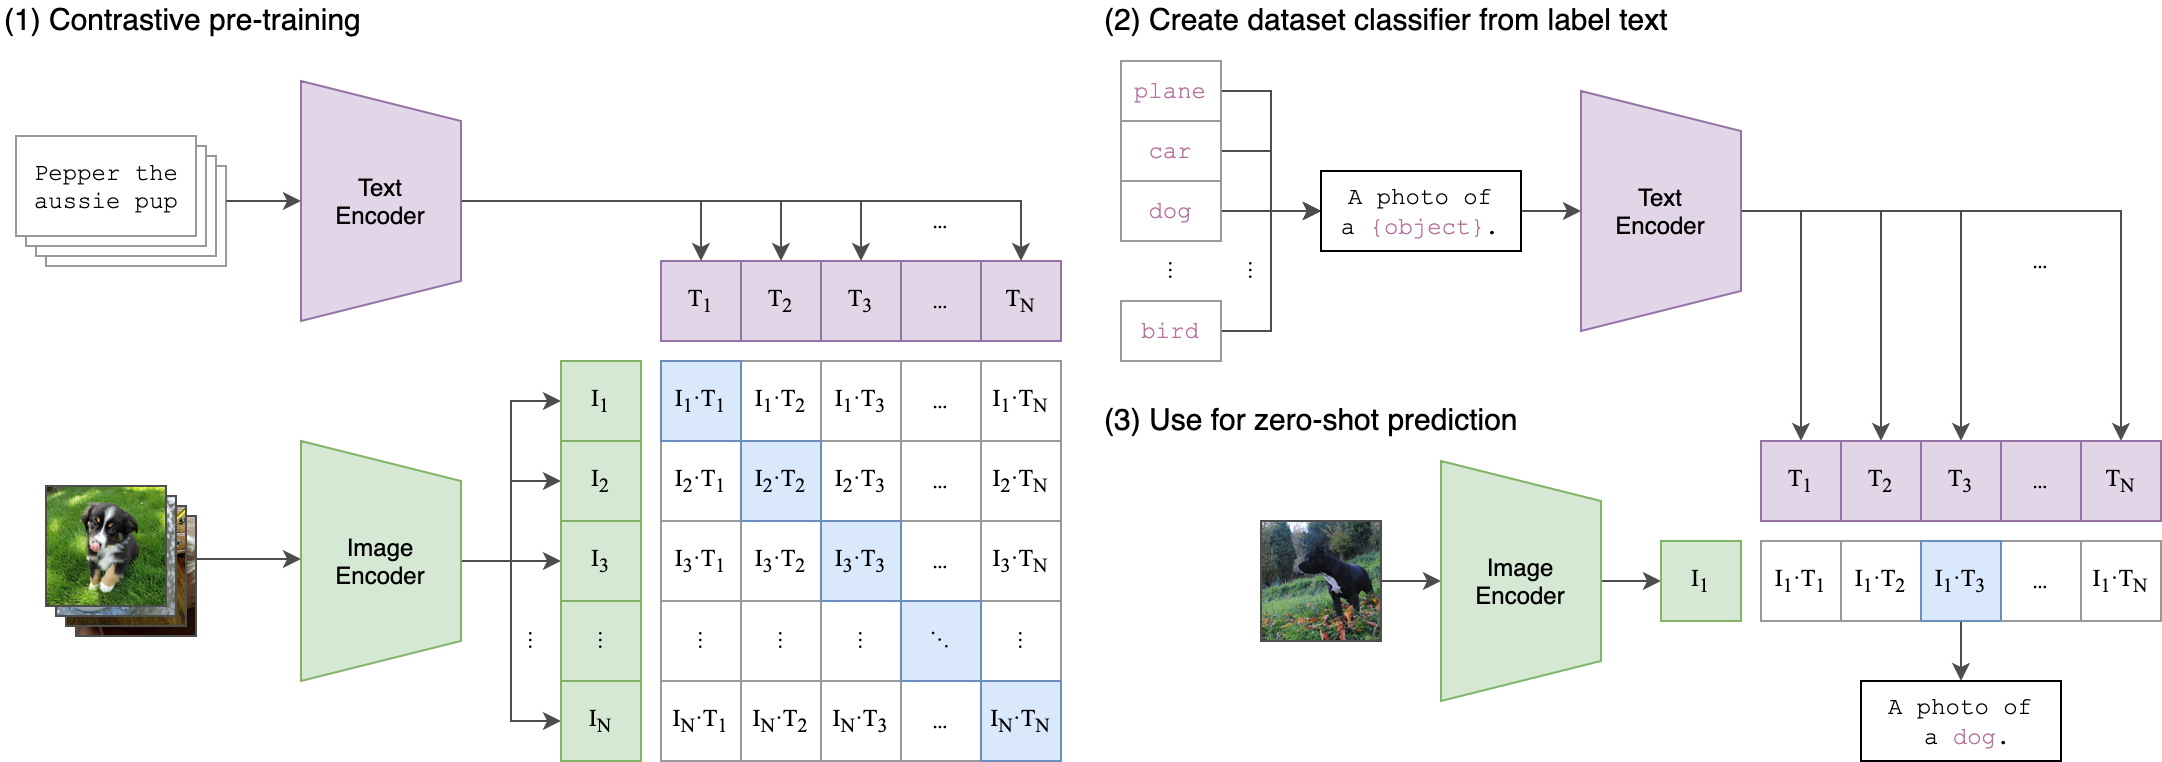
CLIP
34.5Kopenai/CLIP · Jupyter NotebookCLIP is a neural network trained on many (image, text) pairs: given an image, it predicts the most relevant text snippet in natural language, zero-shot, without directly optimizing for the task.
- 18

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 19
graphiti
31.9Kgetzep/graphiti · PythonA Python framework for building and querying temporal knowledge graphs for AI agents. Instead of static RAG, it continuously folds new data into a graph that tracks how facts change over time.
- 20

supermemory
31.3Ksupermemoryai/supermemory · TypeScriptSupermemory is a memory and context engine for AI: it learns from your conversations, extracts facts and builds user profiles, so your AI remembers you between sessions instead of starting from zero.
- 21
pentagi
30.9Kvxcontrol/pentagi · GoPentAGI (Penetration testing Artificial General Intelligence) is a fully autonomous AI agent system that performs complex penetration testing tasks for you.
- 22

applied-ml
30.6Keugeneyan/applied-mlapplied-ml is a curated collection of papers, articles, and tech blogs where companies like Airbnb, Uber, Netflix, Google, and DoorDash share how they run data science and machine learning in production.
- 23

qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 24

insightface
30Kdeepinsight/insightface · PythonAn open-source 2D and 3D deep face analysis toolbox that efficiently implements state-of-the-art face recognition, detection and alignment, optimized for both training and deployment.
- 25
RAG_Techniques
29.9KNirDiamant/RAG_Techniques · Jupyter NotebookA community-driven hub of advanced techniques for Retrieval-Augmented Generation (RAG) — grounding LLM answers in retrieved documents, distilled into runnable notebook tutorials.
- 26
Hands-On-Large-Language-Models
29.7KHandsOnLLM/Hands-On-Large-Language-Models · Jupyter NotebookThe official code repo for the O'Reilly book 'Hands-On Large Language Models', known as the Illustrated LLM Book. It contains a Jupyter notebook for each of the book's 12 chapters.
- 27
agentmemory
29.6Krohitg00/agentmemory · TypeScriptPersistent memory for AI coding agents: it captures what your agent does, compresses it into searchable memory, and injects the right context when the next session starts, so you stop re-explaining your project to Claude Code, Cursor or Codex.
- 28

chroma
29.5Kchroma-core/chroma · RustChroma is open-source data infrastructure for AI: a vector database that powers search for embeddings, used for things like retrieval-augmented generation (RAG) and AI agent memory.
- 29
fastText
26.5Kfacebookresearch/fastText · HTMLfastText is a library from Facebook Research for efficiently learning word vector representations and training text classifiers, such as for sentiment analysis.
- 30

kotaemon
25.8KCinnamon/kotaemon · PythonKotaemon is an open-source RAG tool for chatting with your documents: a clean web UI where you ask questions about your own files, serving both end users and developers.
- 31
RAG-Anything
23.7KHKUDS/RAG-Anything · PythonAn all-in-one multimodal RAG framework built on LightRAG: it ingests real-world documents that mix text, images, tables and equations, then answers queries across all content types through one pipeline instead of separate specialized tools.
- 32
deepface
23.6Kserengil/deepface · PythonDeepFace is a lightweight Python framework for face recognition and facial attribute analysis: it verifies whether two faces match, finds who someone is, and predicts age, gender, emotion and race.
- 33

pgvector
23.4Kpgvector/pgvector · Cpgvector is an open-source extension that adds vector similarity search to Postgres, so embeddings are stored and queried right next to your relational data. It supports exact and approximate nearest neighbor search.
- 34

omlx
22.9Kjundot/omlx · PythonoMLX is a local LLM inference server for Apple Silicon Macs. It serves text LLMs, vision models, OCR, embeddings and rerankers with continuous batching and a tiered KV cache, managed from the macOS menu bar.
- 35

unilm
22.2Kmicrosoft/unilm · PythonMicrosoft's research hub for large-scale self-supervised pre-training: a family of foundation models spanning NLP, vision, speech, and multimodal tasks across 100+ languages - including BEiT, LayoutLM, Kosmos, MiniLM, TrOCR, and WavLM.
- 36
localGPT
22.2KPromtEngineer/localGPT · PythonLocalGPT is a fully private, on-premise document intelligence platform: chat with, summarise and query your own documents using LLMs that run locally, so no data ever leaves your machine.
- 37
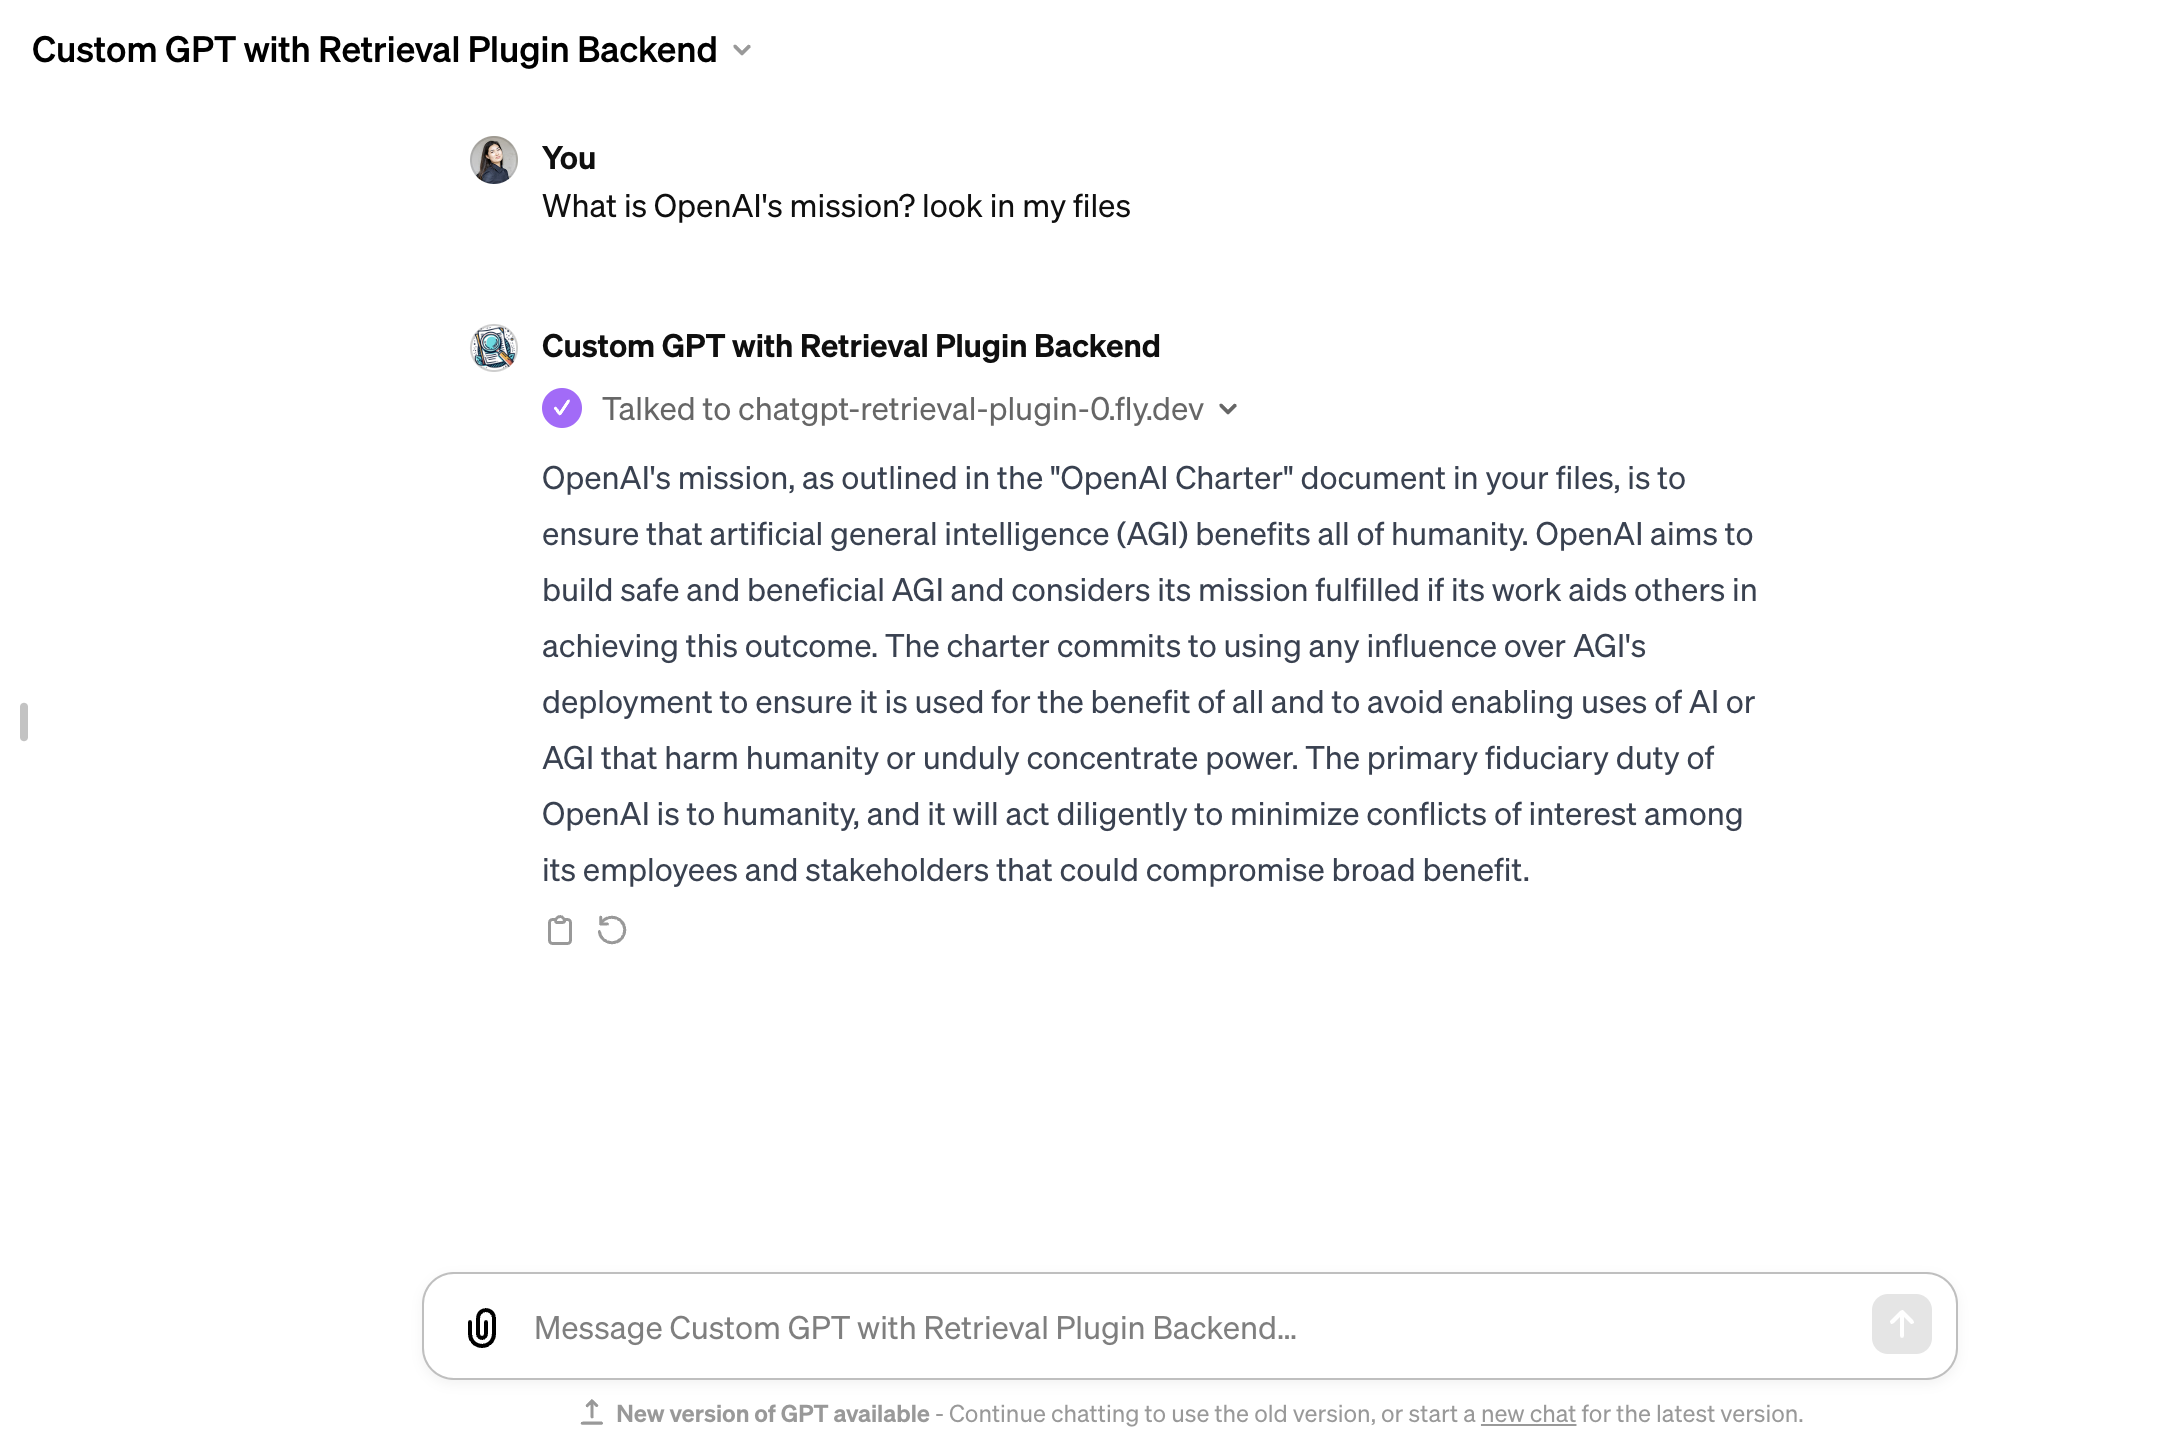
chatgpt-retrieval-plugin
21.3Kopenai/chatgpt-retrieval-plugin · PythonAn open-source retrieval backend for ChatGPT: it indexes your personal or work documents in a vector database and answers natural-language questions with the most relevant snippets — the RAG pattern. Enterprises use it to make internal docs searchable through ChatGPT.
- 38

pydantic-ai
20.7Kpydantic/pydantic-ai · PythonPydantic AI is the Python AI SDK for building agents: a typed, extensible agent loop where every model is a string swap away. The same agent runs behind a web frontend, in the terminal, on a voice call, or as a plain object you call run() on.
- 39

sentence-transformers
19.2Khuggingface/sentence-transformers · PythonSentence Transformers is a framework for computing embeddings and using or training state-of-the-art embedding and reranker models, covering dense sentence embeddings, cross-encoder rerankers, sparse encoders, and multi-vector (ColBERT-style) encoders.
- 40

awesome-nlp
19.1Kkeon/awesome-nlpA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
- 41

langchainjs
18.3Klangchain-ai/langchainjs · TypeScriptLangChain.js is a TypeScript framework for building LLM-powered applications, giving developers a standard interface for agents, models, embeddings, vector stores, and third-party integrations.
- 42
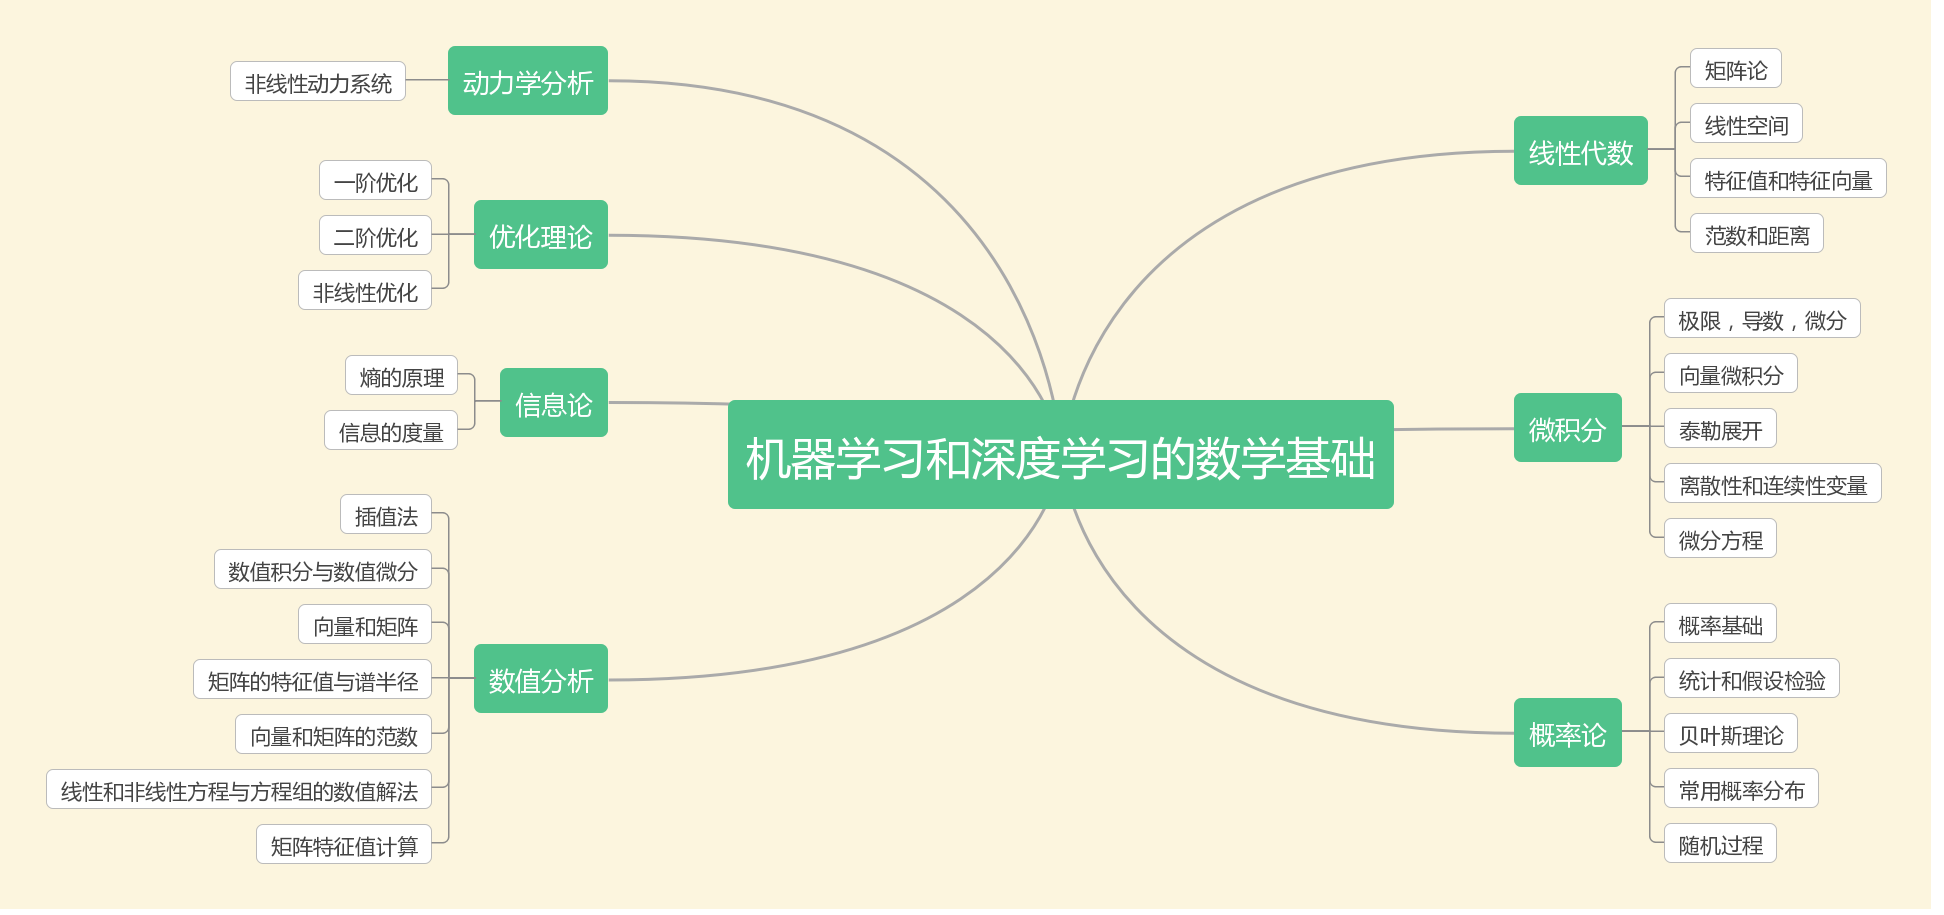
DeepLearning
17.8KMikoto10032/DeepLearning · Jupyter NotebookA Chinese-language deep learning tutorial — a huge curated collection of links to courses, books, lecture notes, surveys and code, taking you from math basics through CNNs, GANs, RNNs and GNNs to Kaggle practice and interview prep.
- 43

rocketride-server
17.8Krocketride-org/rocketride-server · PythonAn open-source AI Development Environment: a data pipeline builder and runtime for AI/ML workloads. It turns the IDE you already use into one place to compose, debug, observe, and deploy AI workflows on a multithreaded C++ engine.
- 44
turbovec
17.4KRyanCodrai/turbovec · RustA vector index for nearest-neighbor search over embeddings, written in Rust with Python bindings. It is built on Google Research's TurboQuant quantization and aimed at RAG where memory, latency and privacy matter.
- 45
weaviate
16.9Kweaviate/weaviate · GoWeaviate is an open-source, cloud-native vector database: it stores objects and vectors together and lets you combine vector search with structured filtering for semantic search at scale.
- 46

Awesome-pytorch-list
16.7Kbharathgs/Awesome-pytorch-listA curated, large-scale list of PyTorch-related projects on GitHub: models, libraries, tools, tutorials, books and paper implementations organized by category.
- 47
memvid
16.6Kmemvid/memvid · RustMemvid is a single-file memory layer for AI agents: it packs your data, embeddings and search index into one portable .mv2 file, so agents get instant retrieval and long-term memory without a RAG pipeline or a vector database server.
- 48
gensim
16.5Kpiskvorky/gensim · PythonGensim is a Python library for topic modelling, document indexing and similarity retrieval with large corpora, aimed at the natural language processing (NLP) and information retrieval (IR) community.
- 49
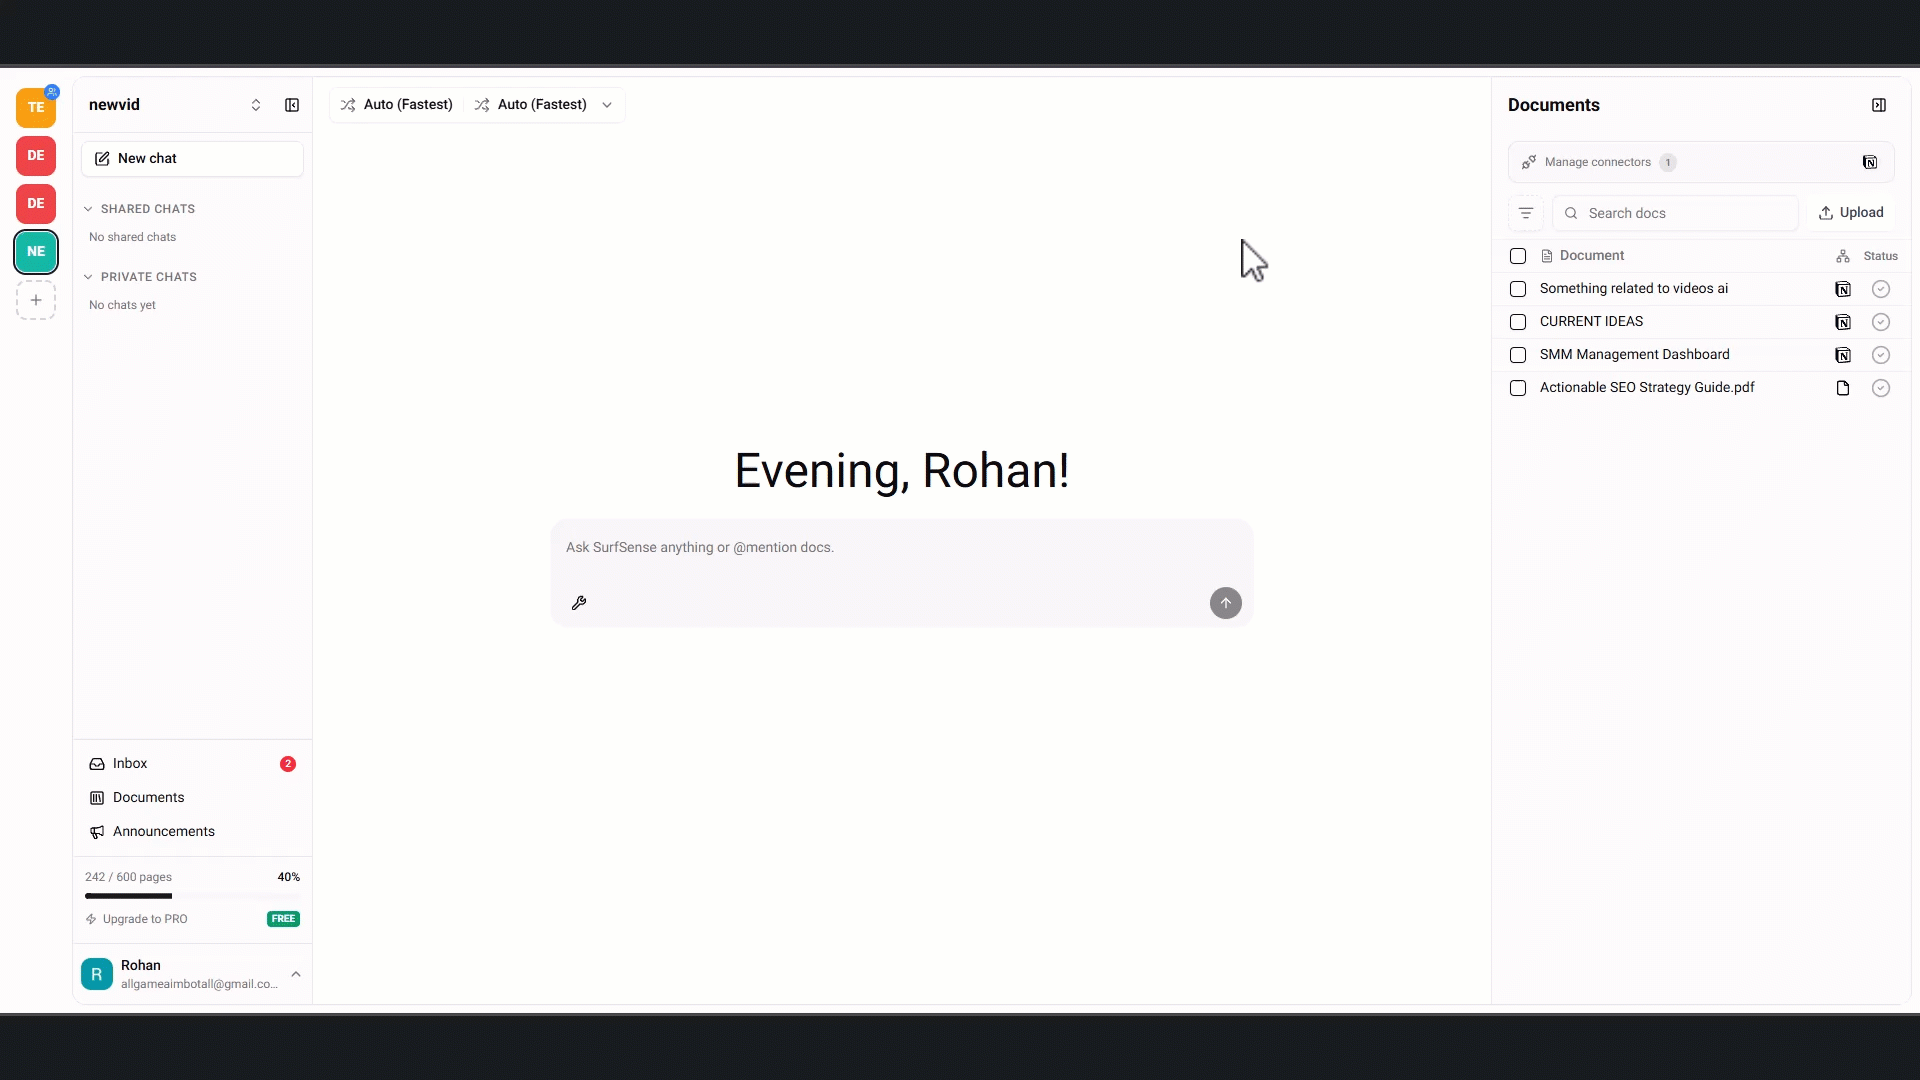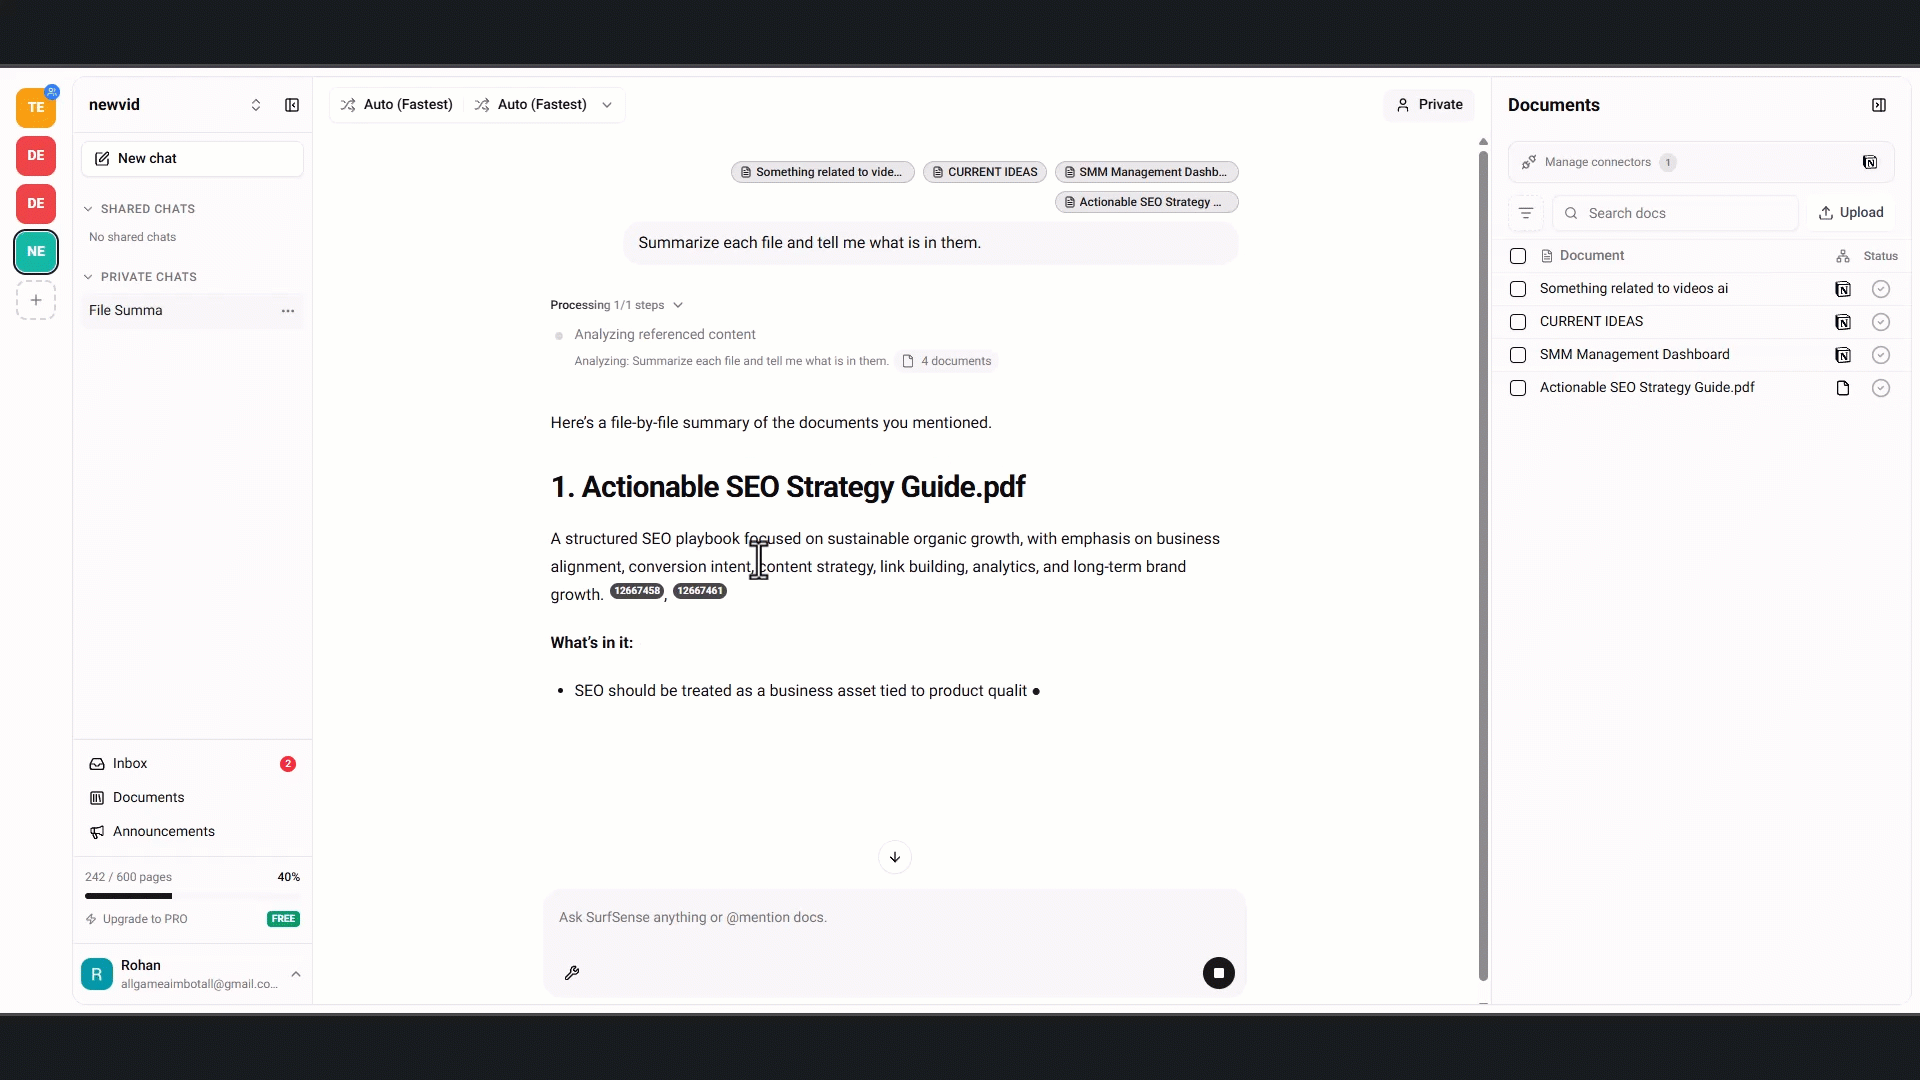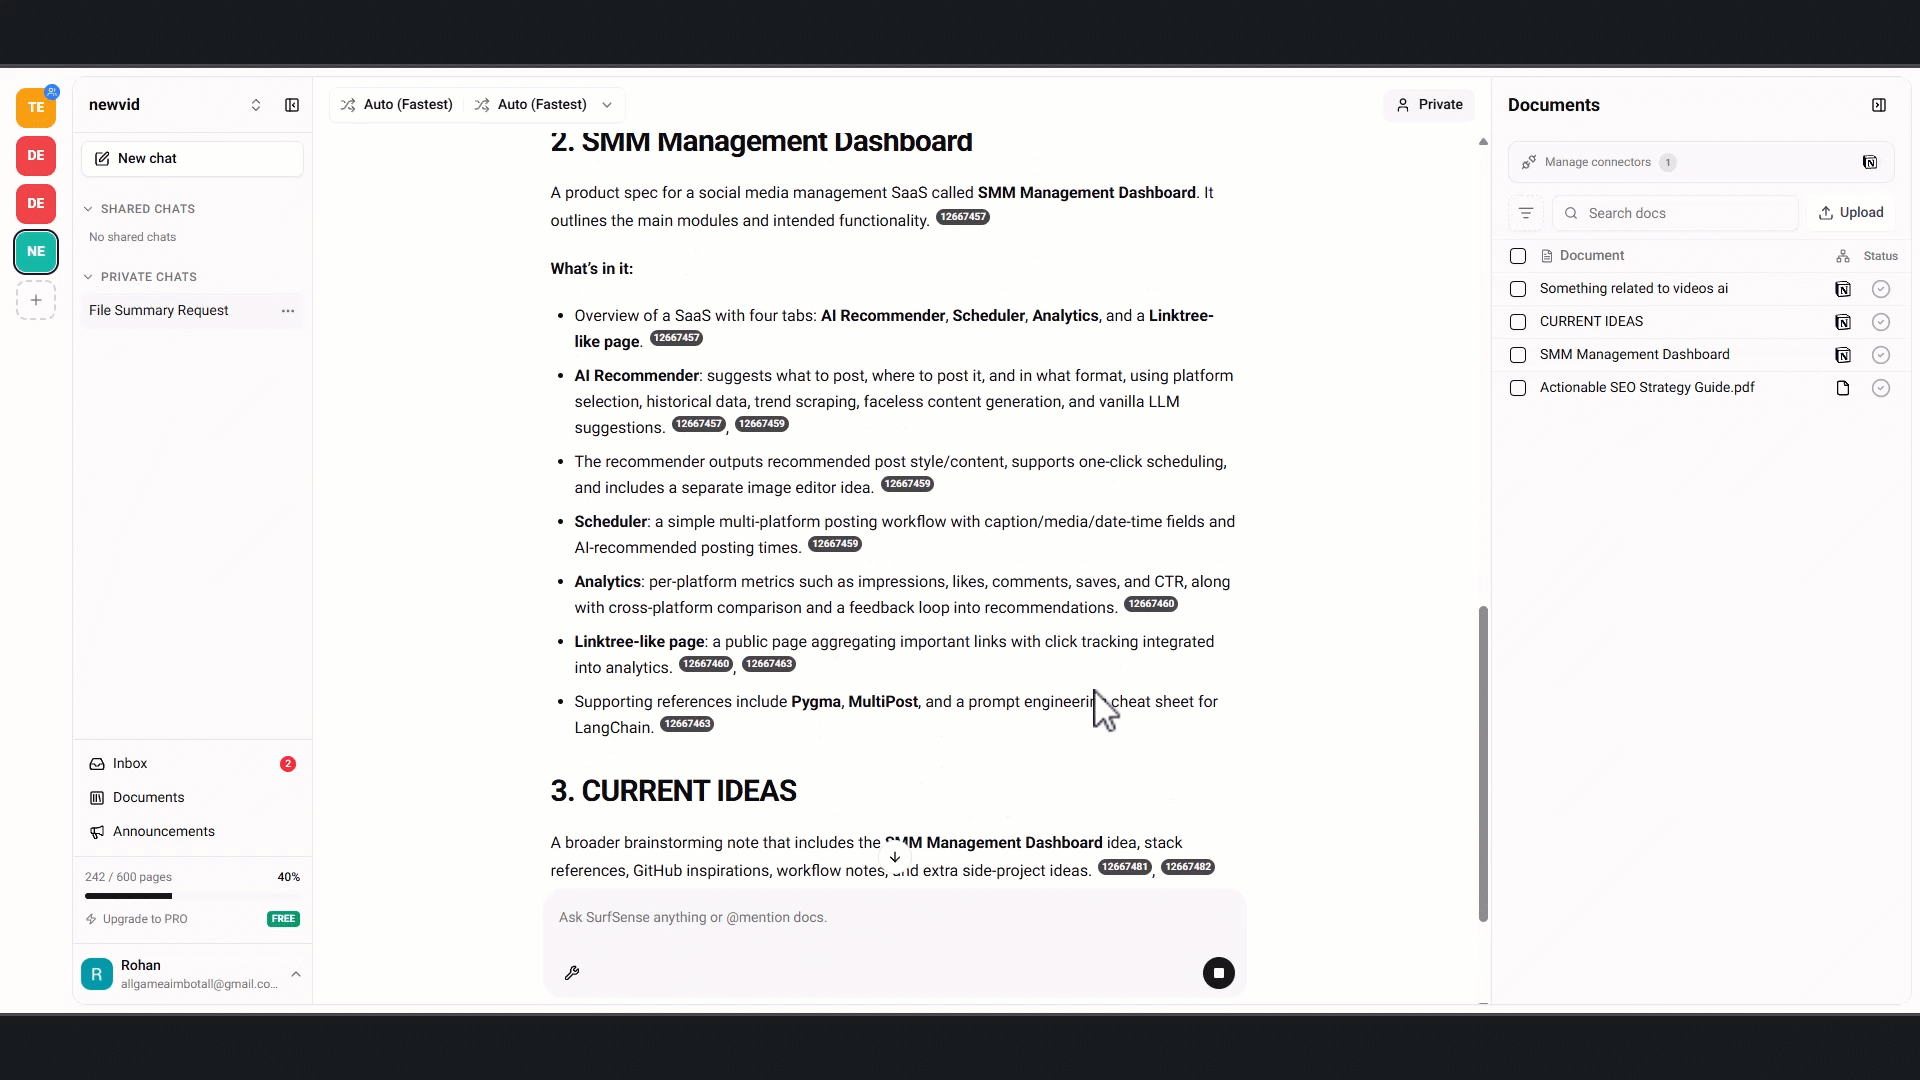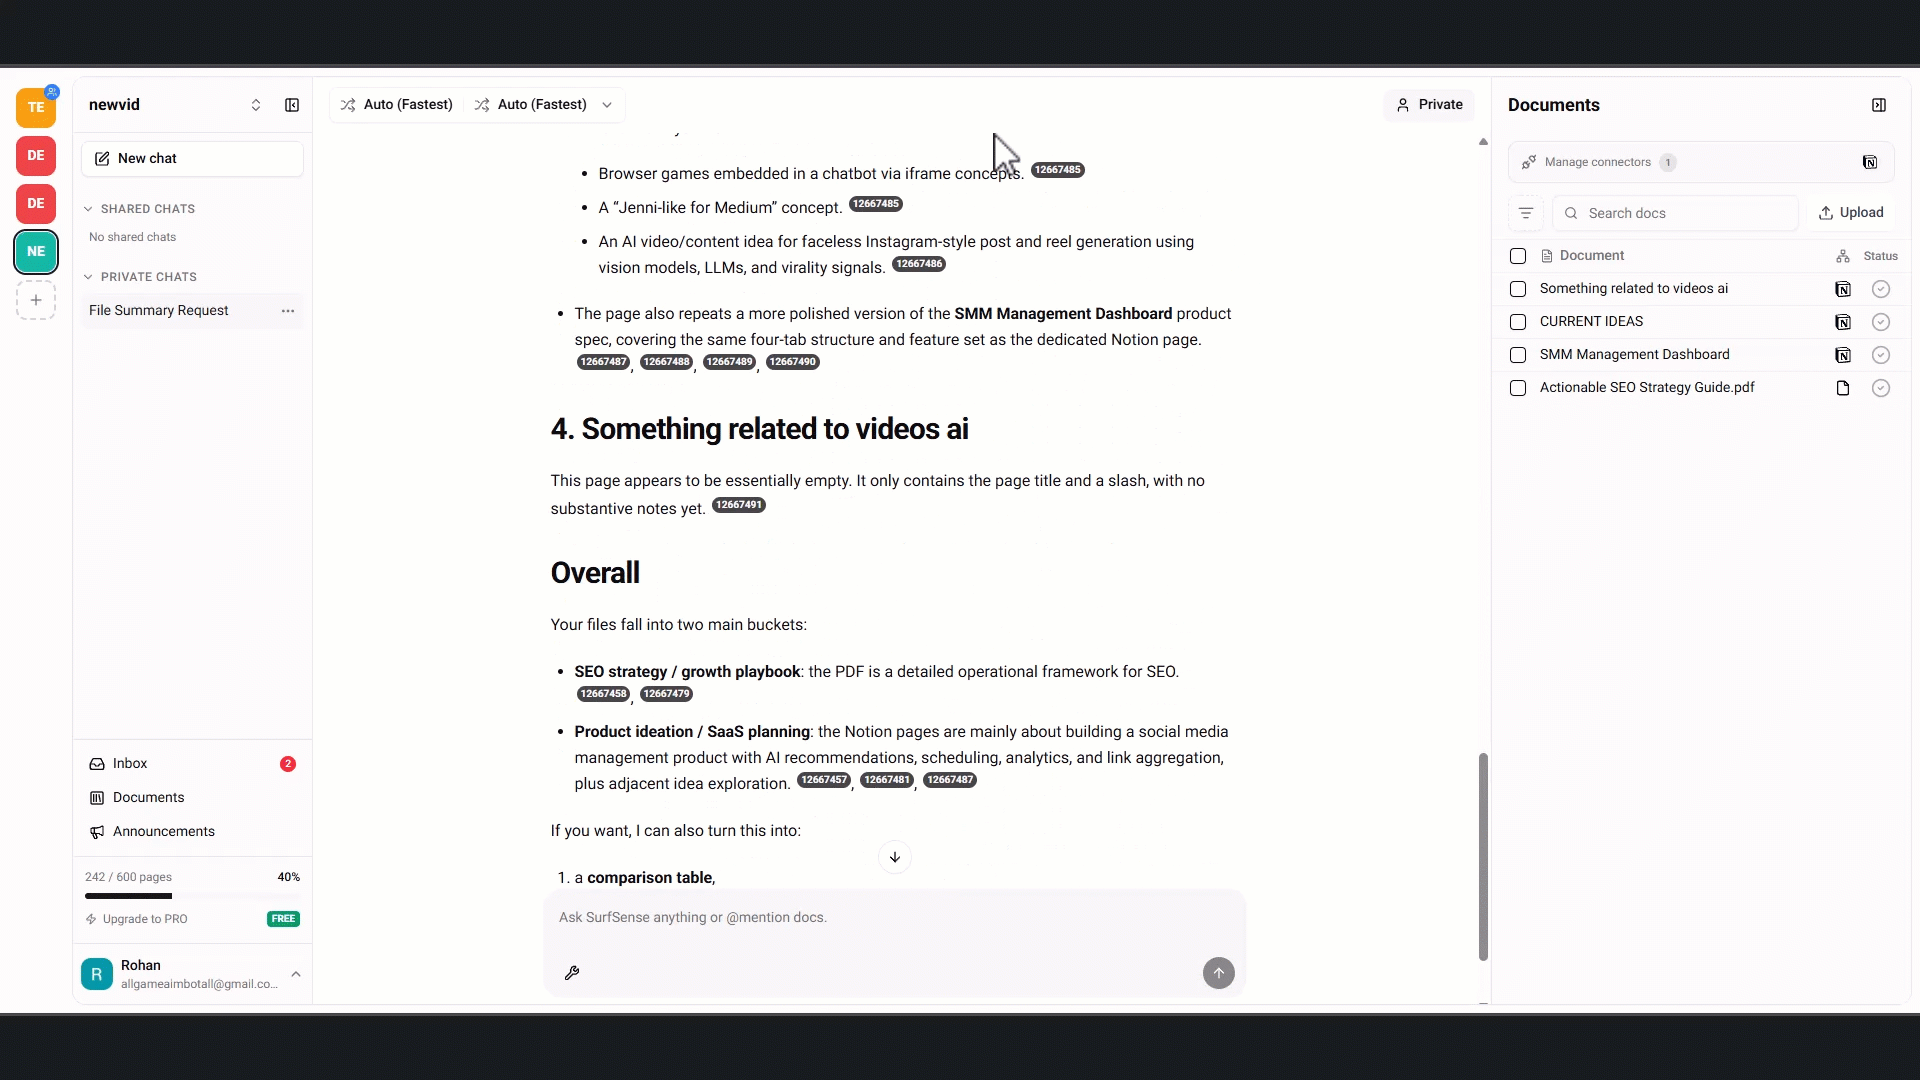
SurfSense
16.5KMODSetter/SurfSense · PythonAn open-source, self-hostable NotebookLM alternative: agents pull structured data from the live web (Reddit, YouTube, Amazon and more) through connectors, and a built-in knowledge base keeps every finding searchable with citations.
- 50

zvec
16.1Kalibaba/zvec · C++Alibaba's open-source, in-process vector database — a lightweight, lightning-fast similarity-search engine you embed directly into your application, battle-tested inside Alibaba Group.
- 51

llmware
14.8Kllmware-ai/llmware · Pythonllmware is a Python framework for building enterprise RAG (retrieval-augmented generation) pipelines using small, specialized models that can run locally, on-device, or in private/self-hosted environments instead of relying on large cloud LLMs.
- 52
memU
14.6KNevaMind-AI/memU · PythonmemU is a lightweight, agent-driven memory system that gives coding agents a shared LLM wiki across sessions, agents, and devices, automatically turning your agent history into reusable skills.
- 53
flair
14.4KflairNLP/flair · PythonFlair is a very simple framework for state-of-the-art natural language processing: a Python library for applying pre-trained NLP models to your text, developed by Humboldt University of Berlin and friends. The current release is version 0.15.1.
- 54

annoy
14.3Kspotify/annoy · C++Annoy (Approximate Nearest Neighbors Oh Yeah) is a C++ library with Python bindings that finds the points in space closest to a given query point. It is optimized for memory usage and for saving and loading indexes to disk.
- 55
QAnything
14.2Knetease-youdao/QAnything · PythonA local knowledge base question-answering system: load your own documents into it and ask questions — you get accurate answers drawn from your files instead of the open web.
- 56
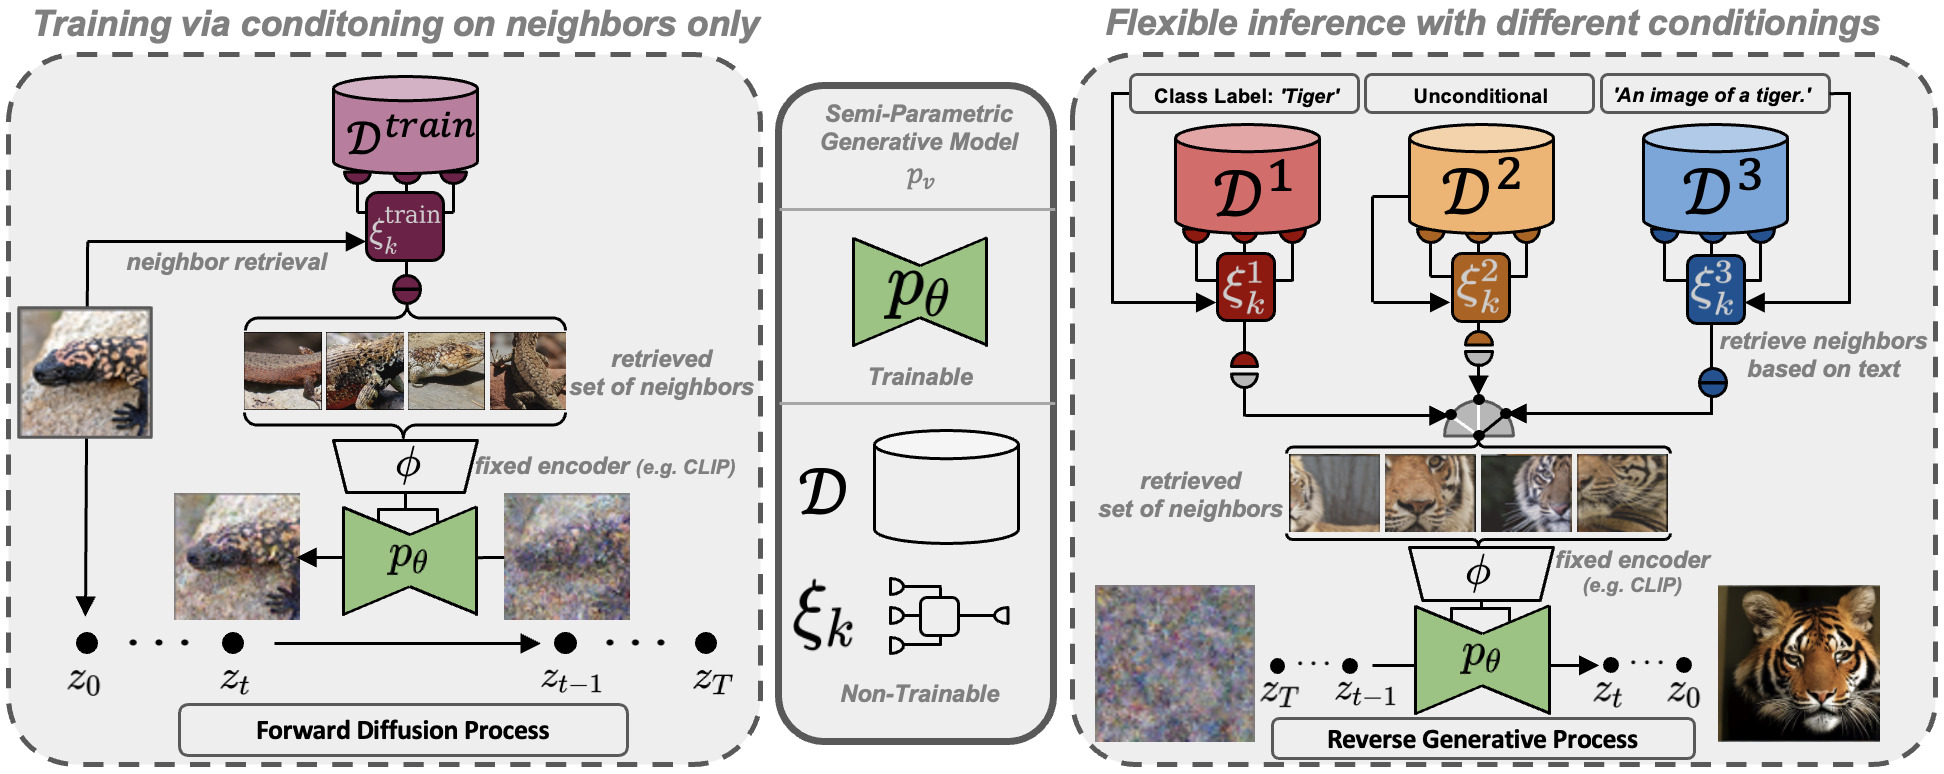
latent-diffusion
14.2KCompVis/latent-diffusion · Jupyter NotebookThis is the official research codebase for the paper 'High-Resolution Image Synthesis with Latent Diffusion Models' by CompVis, which introduced Latent Diffusion Models (LDMs) - diffusion models trained in a compressed latent space instead of raw pixel space for efficient, high-resolution image synthesis.
- 57

llm-universe
14.2Kdatawhalechina/llm-universe · Jupyter NotebookThis is a beginner-focused tutorial course on building large language model (LLM) applications, built around a personal knowledge-base assistant project that walks you through calling LLM APIs, building a vector knowledge base, and assembling a RAG pipeline.
- 58
needle
14.1Kcactus-compute/needle · PythonNeedle 2 is an open 45M-parameter model for tool calling, device use and structured extraction that ships as a single 14MB binary and runs a full session in about 28MB of RAM. This repo is its Python package for inference, LoRA fine-tuning and export.
- 59
dinov2
13.4Kfacebookresearch/dinov2 · Jupyter NotebookDINOv2, a self-supervised visual feature learning method from Meta AI's FAIR team, shipped as PyTorch code and pretrained models. Its features plug into classifiers as simple as linear layers across many vision tasks, with no fine-tuning required.
- 60

langchain4j
13.3Klangchain4j/langchain4j · JavaLangChain4j is an idiomatic, open-source Java library for building LLM-powered applications on the JVM, offering a unified API over popular LLM providers and vector stores.
- 61

InsForge
13.1KInsForge/InsForge · TypeScriptInsForge is an all-in-one, open-source backend platform built for coding agents: it gives agents database, auth, storage, compute, hosting, and an AI gateway so they can ship full-stack apps end-to-end without a human wiring up the backend.
- 62
LEANN
13KStarTrail-org/LEANN · PythonLEANN is a vector database that lets you run retrieval-augmented generation (RAG) over millions of personal documents on your own laptop using 97% less storage than traditional vector databases, with no accuracy loss.
- 63
txtai
13Kneuml/txtai · Pythontxtai is an all-in-one AI framework for semantic search, LLM orchestration and language model workflows. Its core is an embeddings database that combines vector indexes, graph networks and relational databases to power search or serve as a knowledge source for LLM apps.
- 64
PaddleNLP
13KPaddlePaddle/PaddleNLP · PythonPaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
- 65
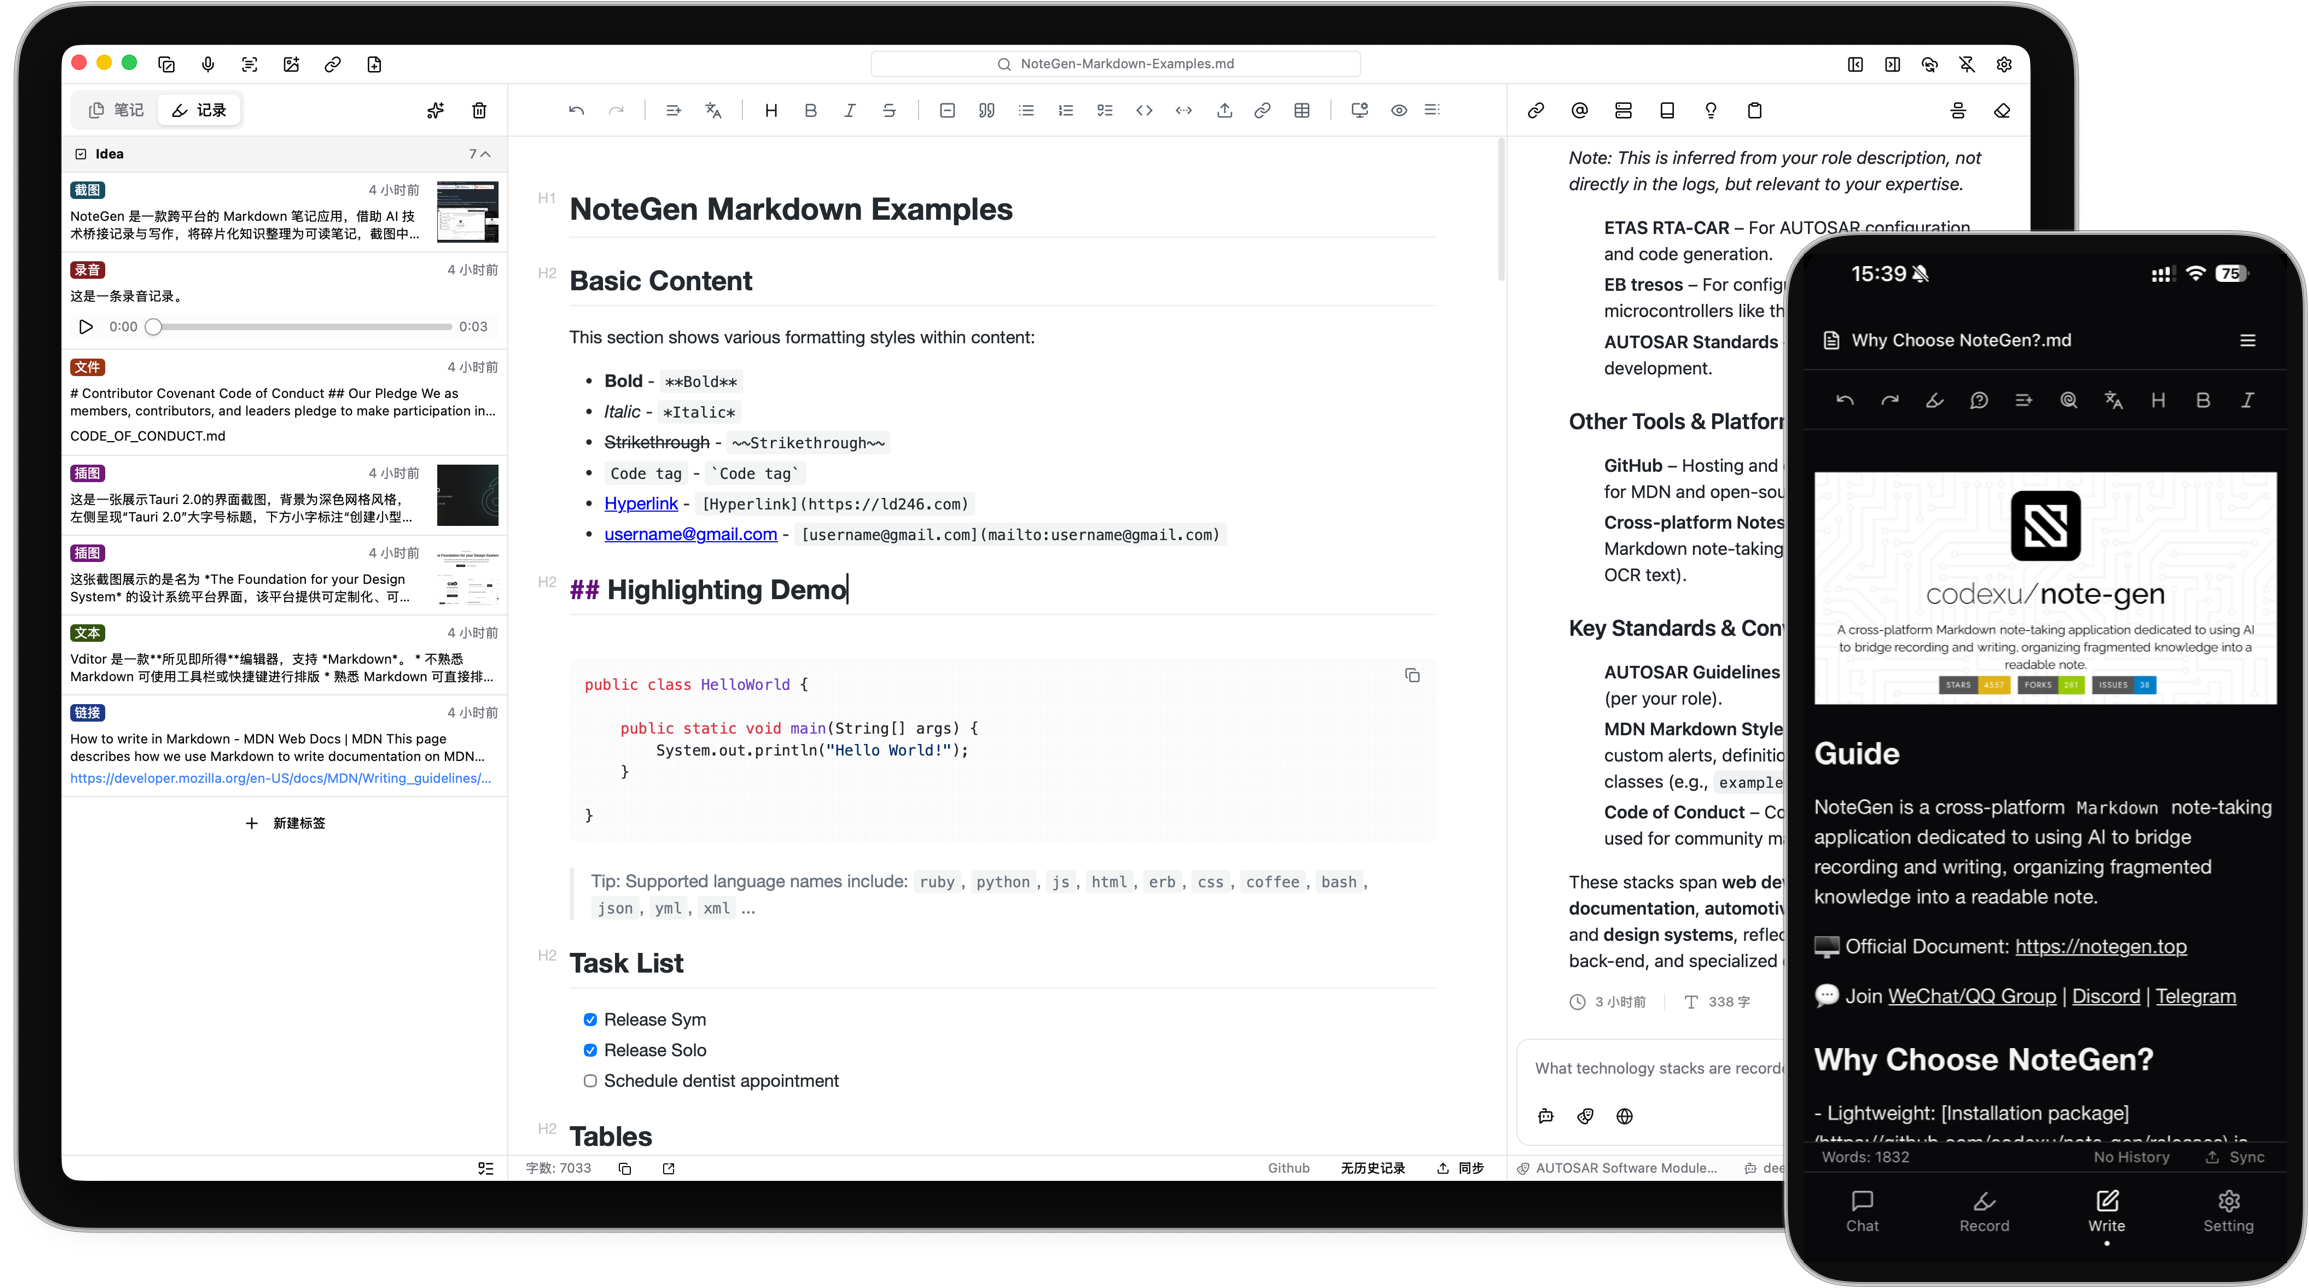
note-gen
12.9Kcodexu/note-gen · TypeScriptNoteGen is a local-first Markdown note app that lets you quickly capture scattered fragments like text, voice recordings, screenshots, links, or files, then use AI later to organize them into structured notes.
- 66
clip-as-service
12.8Kjina-ai/clip-as-service · PythonCLIP-as-service is a low-latency, high-scalability service for embedding images and text with CLIP models, so you can plug it into neural search or cross-modal retrieval apps as a microservice.
- 67

llm
12.6Ksimonw/llm · PythonLLM is a CLI tool and Python library for running prompts against OpenAI, Anthropic Claude, Google Gemini, Qwen, Gemma, Kimi, DeepSeek, Mistral and dozens of other large language models, either via remote APIs or models running locally on your own machine.
- 68
claude-context
12.6Kzilliztech/claude-context · TypeScriptClaude Context is an MCP server that gives AI coding agents semantic search over your entire codebase, so they can pull relevant code straight into context instead of loading whole directories.
- 69
FlagEmbedding
12.3KFlagOpen/FlagEmbedding · PythonFlagEmbedding (BGE) is a one-stop toolkit from BAAI for retrieval and retrieval-augmented LLMs, providing embedding models, rerankers, finetuning scripts, and evaluation tools for search and RAG.
- 70

Chinese-Word-Vectors
12.2KEmbedding/Chinese-Word-Vectors · PythonA collection of 100+ pre-trained Chinese word vectors (embeddings) trained with different representations, context features and corpora, plus the CA8 analogy dataset and an evaluation toolkit.
- 71

h2ogpt
11.9Kh2oai/h2ogpt · Pythonh2oGPT is an open-source private chat application that lets you query and summarize your own documents or just chat with local LLMs, with no data leaving your machine.
- 72

Transformers-Tutorials
11.8KNielsRogge/Transformers-Tutorials · Jupyter NotebookA collection of Jupyter notebook demos showing how to use HuggingFace's Transformers library in PyTorch, covering models like BERT, GPT-2, LayoutLM, DETR, Donut and many more.
- 73

lancedb
11.7Klancedb/lancedb · RustLanceDB is an open-source vector database for multimodal AI: a central platform where you store, index and search petabytes of vectors and multimodal data, built for fast, production-ready retrieval.
- 74
dinov3
11.6Kfacebookresearch/dinov3 · Jupyter NotebookMeta AI Research (FAIR)'s reference PyTorch implementation and model release for DINOv3, a family of vision foundation models that produce high-quality dense features and perform strongly across many vision tasks.
- 75

DALLE2-pytorch
11.3Klucidrains/DALLE2-pytorch · PythonIt is a PyTorch implementation of DALL-E 2, OpenAI's text-to-image synthesis model, built by a third-party community author (lucidrains).
- 76
llm-engineer-toolkit
10.9KKalyanKS-NLP/llm-engineer-toolkitA curated catalog of 120+ LLM libraries organized by category, covering training, application development, RAG, inference, serving, data extraction, agents, evaluation, monitoring, prompts, safety and embeddings.
- 77

go-openai
10.8Ksashabaranov/go-openai · Gogo-openai is an unofficial Go client library for the OpenAI API, giving Go developers typed access to text generation, chat, images, audio, embeddings, moderation, fine-tuning, batches and vector stores.
- 78

llama-cpp-python
10.6Kabetlen/llama-cpp-python · Python'llama-cpp-python' provides Python bindings for the llama.cpp C/C++ library, giving both low-level ctypes access and a high-level API for running GGUF language models locally for text completion, chat, embeddings and more.
- 79

ollama-python
10.6Kollama/ollama-python · PythonThis is the official Python library for Ollama, giving Python 3.8+ projects an easy way to call a local or cloud Ollama server to run large language models.
- 80

the-algorithm-ml
10.6Ktwitter/the-algorithm-ml · PythonThis is the source code for part of Twitter's (X's) recommendation algorithm, specifically the machine learning models used to rank and embed content for the 'For You' timeline.
- 81

orama
10.6Koramasearch/orama · TypeScriptOrama is a complete search engine and RAG pipeline that runs in your browser, on a server or at the edge, with support for full-text, vector and hybrid search.
- 82
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 83

PixelRAG
10.3KStarTrail-org/PixelRAG · PythonAn open-source research codebase from Berkeley for pixel-native search: PixelRAG renders web pages, PDFs and images as screenshots and retrieves over the images directly, instead of parsing pages into text.
- 84
Chinese-BERT-wwm
10.2Kymcui/Chinese-BERT-wwm · PythonThis project releases a family of pre-trained Chinese BERT models trained with Whole Word Masking (WWM), including BERT-wwm, BERT-wwm-ext, RoBERTa-wwm-ext, RoBERTa-wwm-ext-large, and smaller RBT3/RBT4/RBT6/RBTL3 variants, published alongside a paper in IEEE/ACM TASLP.
- 85
atlas
9.6Kpacifio/atlas · RustAtlas is source control built for coding agents: it records every agent session as a checkpoint linking a commit back to the prompts, tool calls, and reasoning that produced it, and lets you run Claude Code, Codex, its own native agent, or any ACP registry agent side by side with shared memory.
- 86
clawhub
9.5Kopenclaw/clawhub · TypeScriptClawHub is the public skill registry for OpenClaw: a place to publish, version, and search text-based agent skills (a SKILL.md plus supporting files), plus a catalog of OpenClaw code and bundle plugins.
- 87

nullclaw
8.1Knullclaw/nullclaw · Zignullclaw is a fully autonomous AI assistant infrastructure: one small static Zig binary that you self-host and connect to your chat apps and AI providers.
- 88
AIHOT
8KKKKKhazix/AIHOT · TypeScriptAIHOT is a framework for building an AI-curated news site: it pulls items from your sources, has an LLM filter and score each one twice, writes Chinese headlines and summaries, clusters reports of the same story into one event, ranks events by how many independent sources cover them, and publishes a daily briefing.
- 89
xerj
7.8Kxerj-org/xerj · RustXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
- 90
OpenSpace
7.8KHKUDS/OpenSpace · PythonOpenSpace is a skill management layer for AI agents that helps them retrieve the right skill for a task, evaluate it against real outcomes, share proven workflows, and evolve skills over time, across agents like Claude Code, Codex, OpenClaw, Hermès and nanobot.
- 91
opensquilla
7.1KTokenRhythm/opensquilla · PythonOpenSquilla is a token-efficient, microkernel AI agent that uses a local model router to send each conversation turn to the cheapest model that can handle it, while sharing memory, a sandbox, and web search across its CLI, Web UI, and chat-channel interfaces.
- 92
semble
6.2KMinishLab/semble · PythonSemble is a code search library built for coding agents. It returns the exact relevant code snippets for a query instead of making the agent grep and read full files, using about 99% fewer tokens than grep+read.
- 93
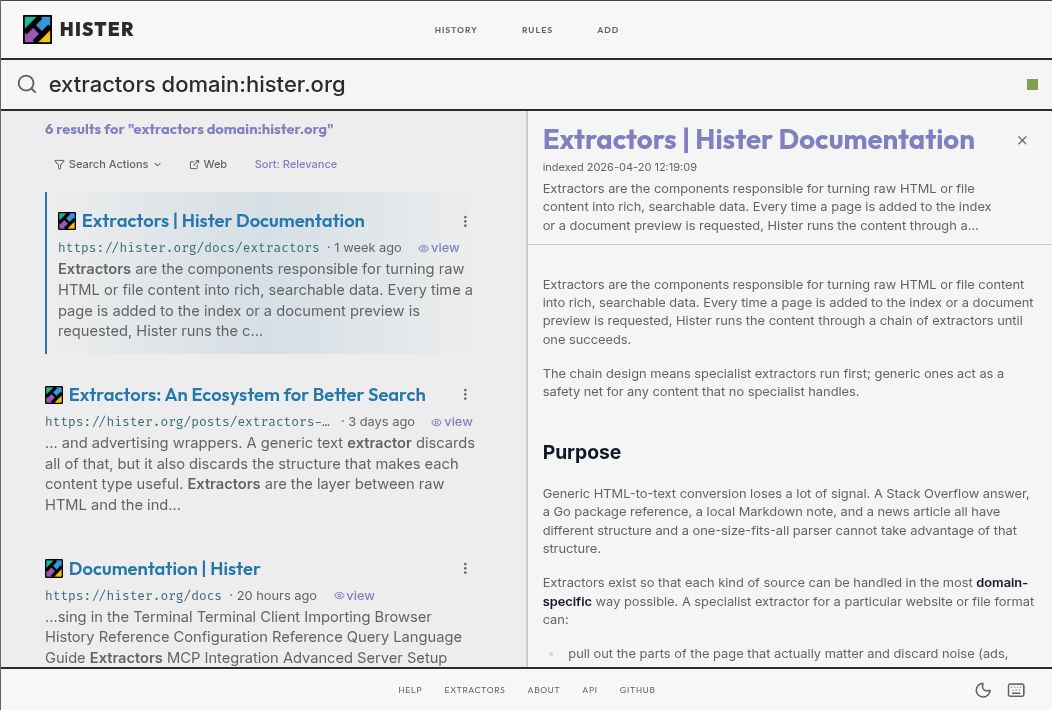
hister
6.1Kasciimoo/hister · GoHister is a private, self-hosted search engine that fully indexes the pages you visit and the files you keep, so you can search their content later from a web interface, terminal, or an AI assistant via MCP.
- 94
OpenExecutive
5.6KSenteLabsAI/OpenExecutive · PythonOpen Executive is an AI system that acts as a company's virtual executive team — presented as one senior advisor with Harvard MBA-level knowledge, backed by eight specialist agents (CSO, CFO, HR, General Counsel, COO, CMO, CPO, Board Communications).
- 95

Engram
4.8Kdeepseek-ai/Engram · PythonThis is the official code release for the DeepSeek paper 'Conditional Memory via Scalable Lookup', introducing Engram, a module that gives Transformers a native knowledge-lookup primitive by modernizing classic N-gram embeddings for O(1) retrieval, as a complement to Mixture-of-Experts sparsity.
- 96

OB1
4.7KNateBJones-Projects/OB1 · TypeScriptOpen Brain (OB1) is an infrastructure layer that gives every AI tool you use — Claude, ChatGPT, Cursor, Claude Code, and whatever ships next — shared, persistent access to the same memory of you, through one database and one AI gateway.
- 97
RuVector
4.6Kruvnet/RuVector · RustRuVector is a Rust-native persistent memory substrate for AI agents, combining local vector embeddings, graph relationships, feedback-driven learning, and memory lifecycle controls so agents can remember across sessions.
- 98
DigUp
4.6KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 99

sentrysearch
4.6Kssrajadh/sentrysearch · PythonSentrySearch is a CLI tool that lets you semantically search through video footage (like Tesla dashcam clips) by typing what you're looking for and getting back a trimmed clip of the matching moment.
- 100
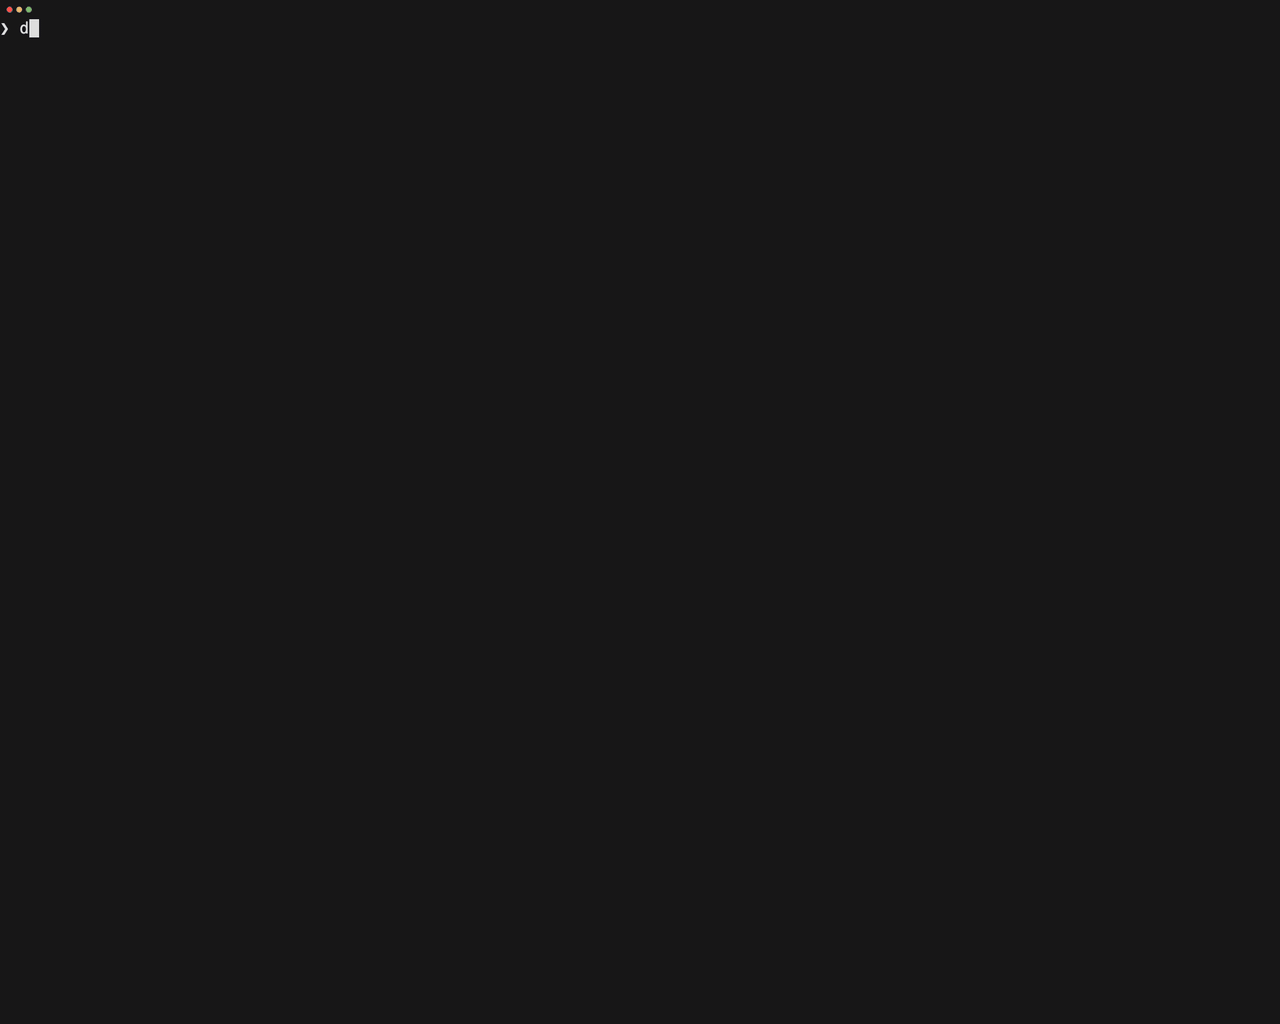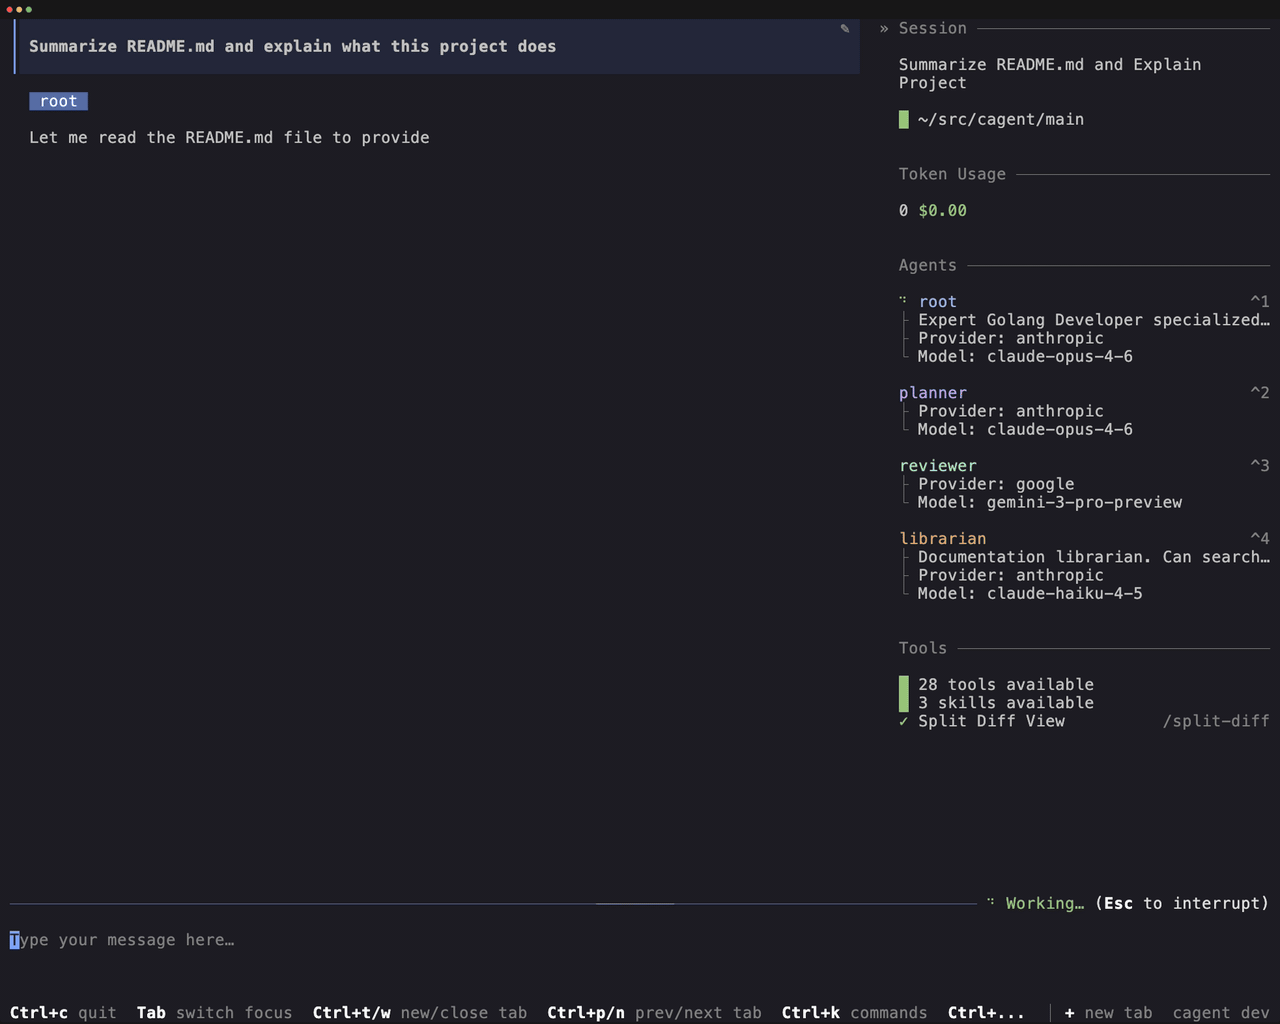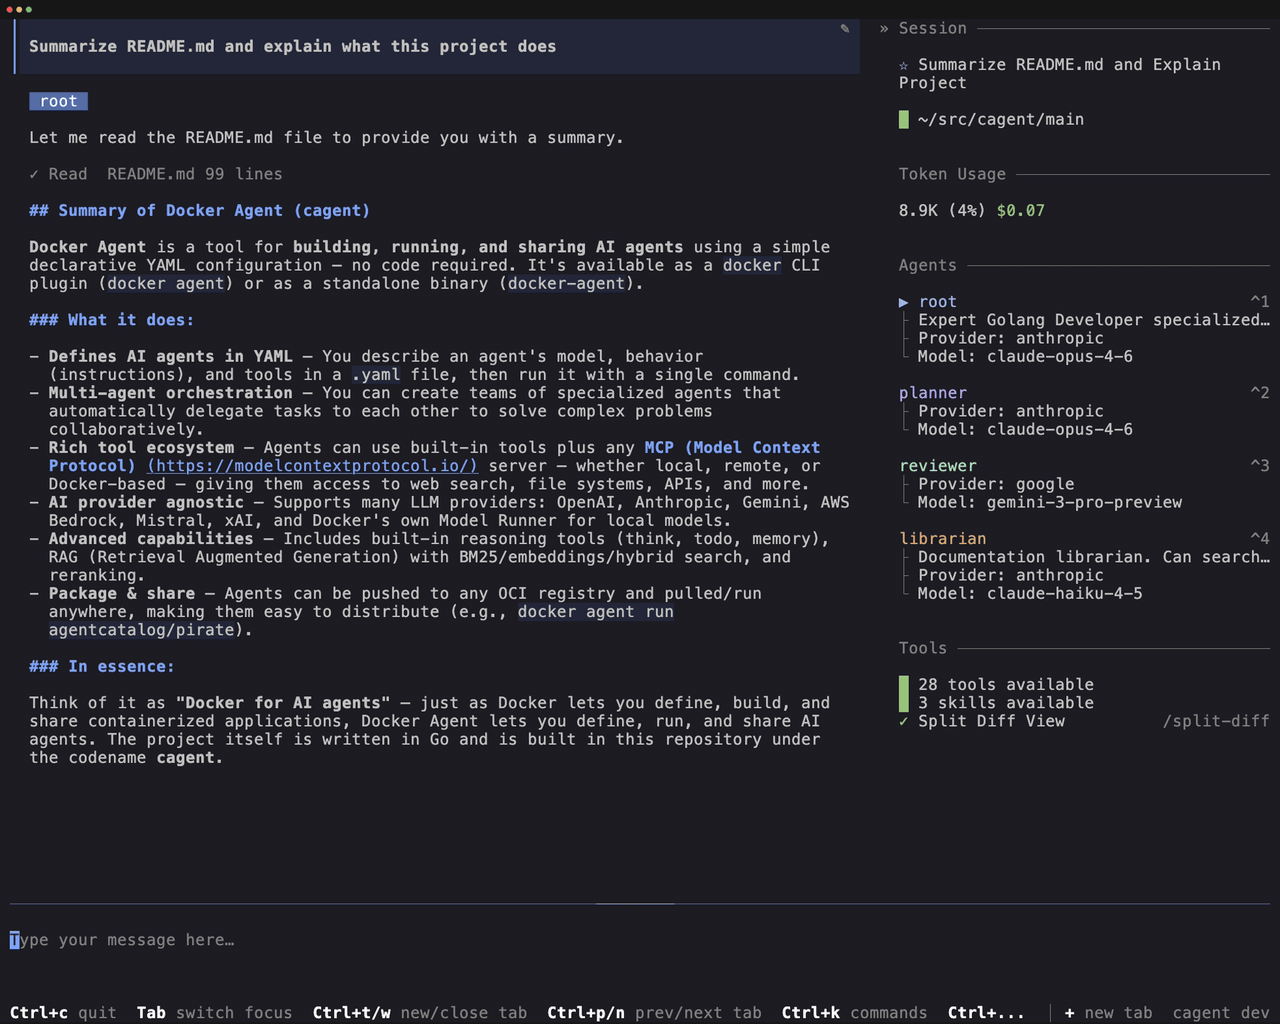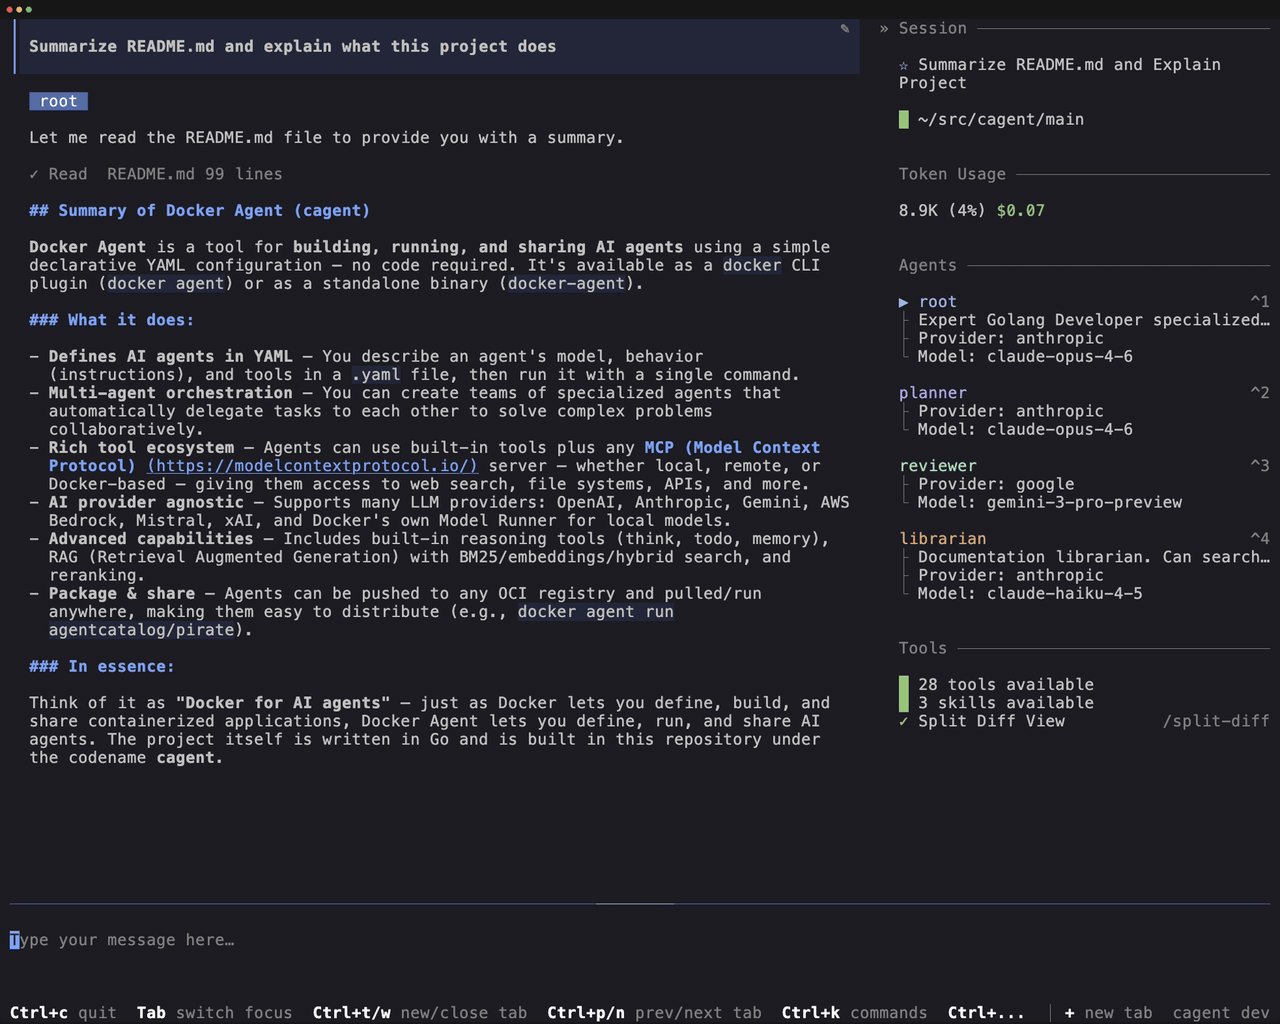
docker-agent
4.6Kdocker/docker-agent · GoDocker Agent is a tool for building, running, and sharing AI agents using a declarative YAML config, with built-in tools and multi-agent orchestration — no code required.
Showing the 100 most-starred of 135. See every one in the catalog.
Related topics
Often tagged together
- ai1,954
- python2,396
- llm1,483
- open-source5,666
- rag292
- linux4,181
- machine-learning915
- macos3,544
- semantic-search114
- self-hosted1,926
- apache-2.01,434
- windows3,401
- mcp917
- vector-database103
- ai-agents1,294
- mit3,311
- vector-search74
- developer-tools2,927
- cli2,227
- deep-learning736
- server1,459
- cross-platform2,622
- docker1,657
- openai576