Topics / #gguf
Gguf projects on GitHub
Single-file model weight format used for running LLMs locally.
As of , the most-starred Gguf projects on GitHub are vllm (94.1K stars), unsloth (78.2K stars) and gpt4all (77.3K stars). GitHub.Locker tracks 61 Gguf repositories with 848.6K stars combined. The fastest-growing on October 17 was Strata, with +608 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +608
Strata
Niko1221/Strata · ★ 27KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +86
StartLux-Decision
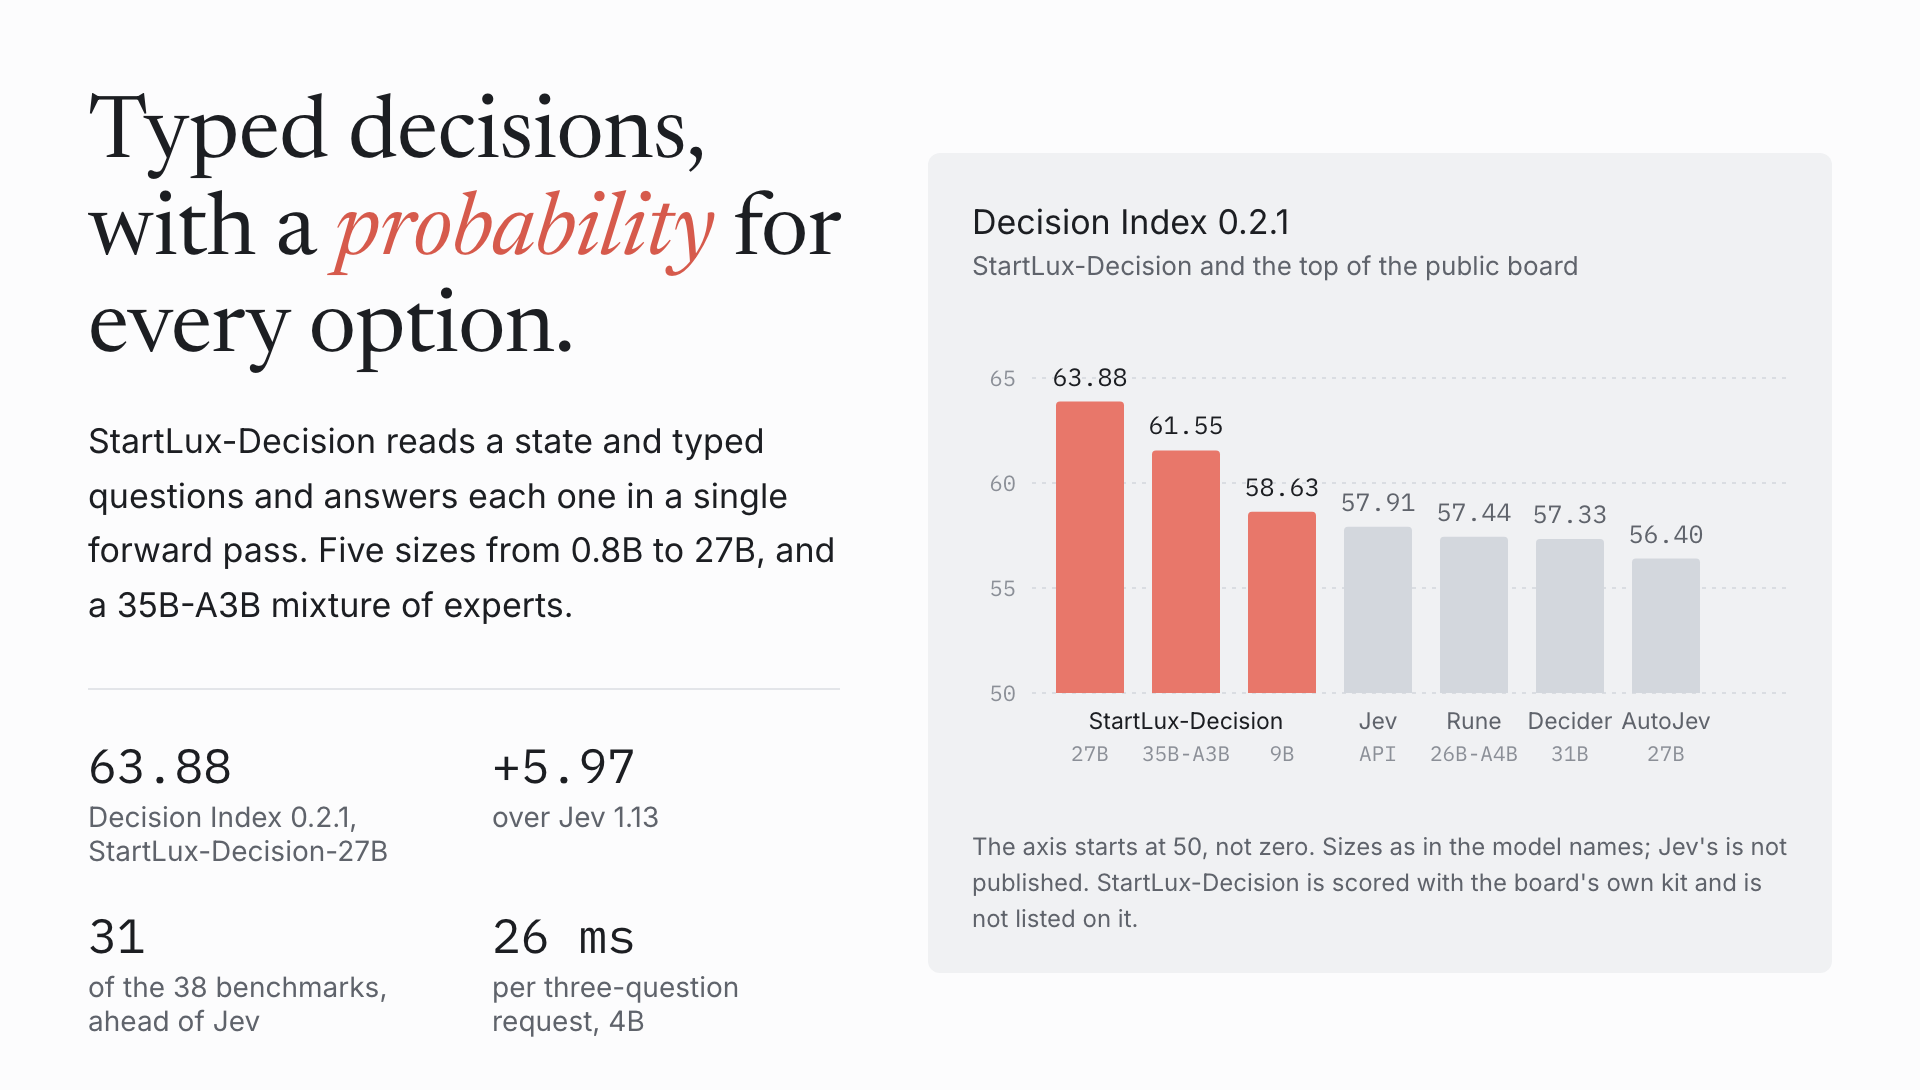
StartLuxLabs/StartLux-Decision · ★ 695StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
 +81
Soup
MakazhanAlpamys/Soup · ★ 9.3KSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
 +78
VoxCPM
OpenBMB/VoxCPM · ★ 39.5KVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
The all-time top
61 projects · by stars
- 94.1K
 #1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 78.2K
 #2 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 77.3K
 #3 · nomic-ai/gpt4all
gpt4all
GPT4All is a desktop application that runs large language models privately on everyday laptops and desktops, with no API calls or GPU required.
- 4
textgen
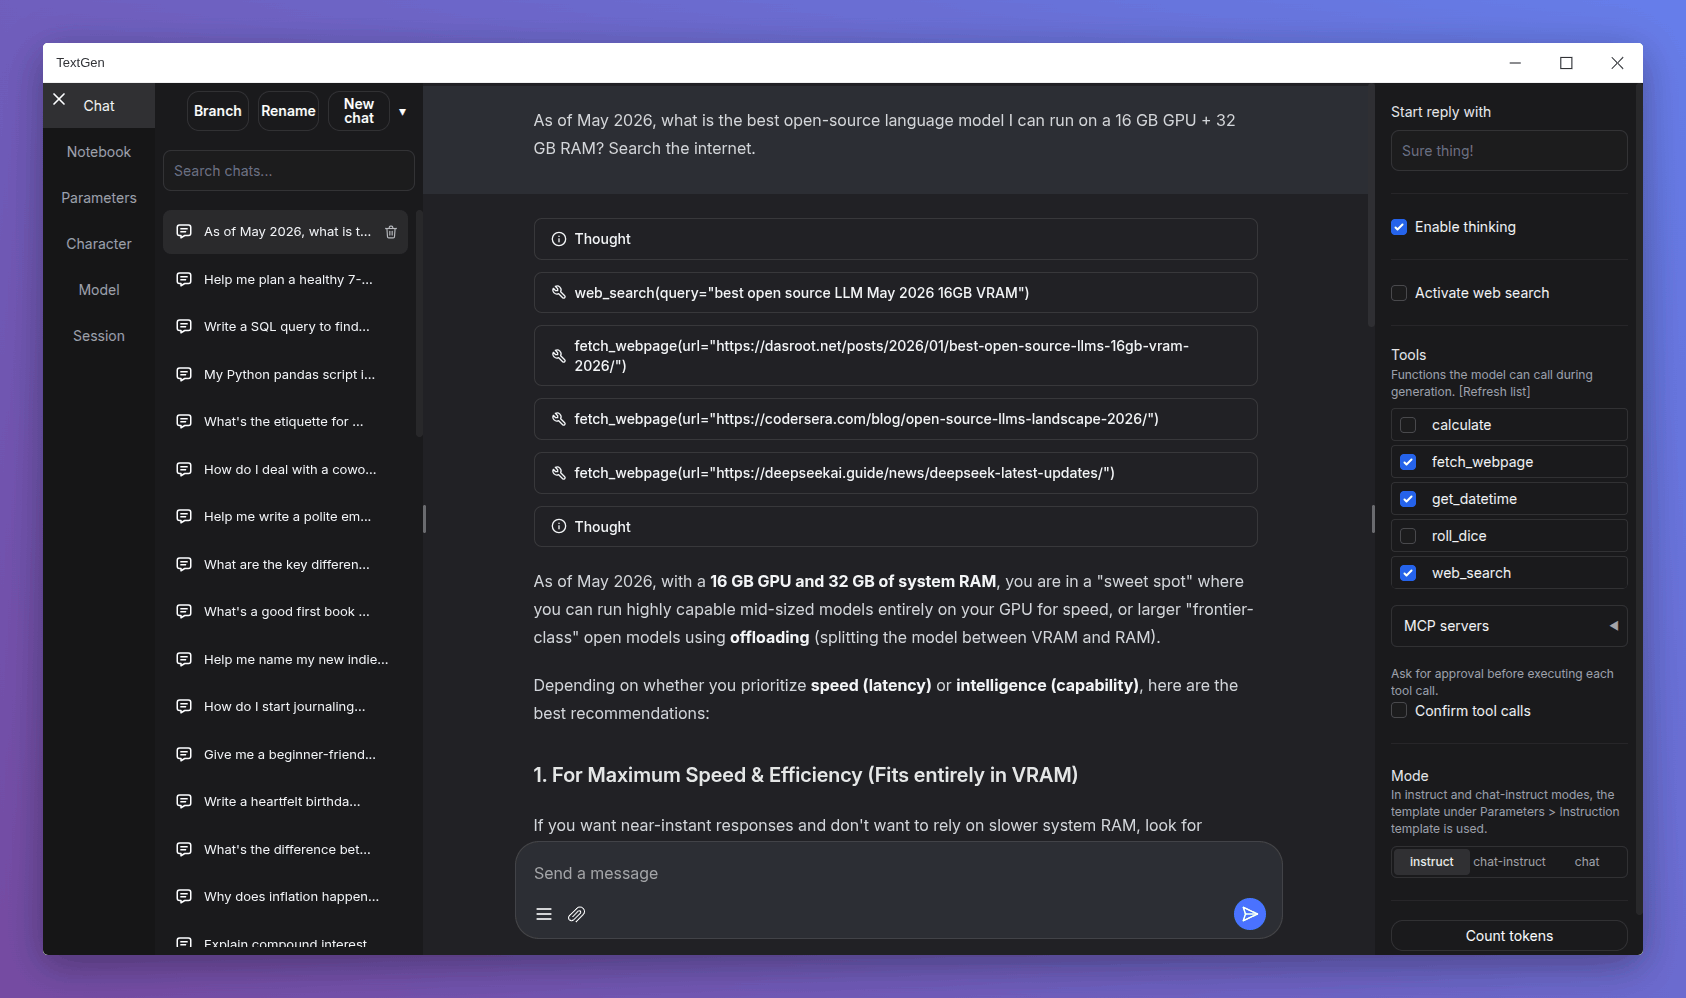
47.7Koobabooga/textgen · PythonTextGen is an open-source desktop app for running local LLMs with text, vision, tool-calling, and an OpenAI/Anthropic-compatible API, built to be 100% private with no telemetry.
- 5
jan
45Kjanhq/jan · RustJan is an open-source, self-hosted alternative to ChatGPT that runs 100% offline on your own computer, letting you download and run LLMs locally with full control and privacy.
- 6
VoxCPM
39.5KOpenBMB/VoxCPM · PythonVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
- 7

llmfit
38.1KAlexsJones/llmfit · Rustllmfit inspects your CPU, RAM, GPU(s), VRAM, and accelerator setup, then tells you which open-source LLMs and quantizations will actually run well on your machine.
- 8

qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 9

Qwen3
27.7KQwenLM/Qwen3 · PythonQwen3 is a series of open-weight large language models built by the Qwen team at Alibaba Cloud, released as both dense and Mixture-of-Experts (MoE) models from 0.6B up to 235B-A22B parameters, with switchable 'thinking' and 'non-thinking' reasoning modes.
- 10
Strata
27KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 11

MiniCPM-V
26.9KOpenBMB/MiniCPM-V · PythonA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 12
llamafile
26.4Kmozilla-ai/llamafile · C++llamafile turns open LLMs into single-file executables: one file that runs a chat model locally on most operating systems and CPU architectures, with no installation. It is a Mozilla Builders project, now revamped by Mozilla.ai.
- 13

kotaemon
25.8KCinnamon/kotaemon · PythonKotaemon is an open-source RAG tool for chatting with your documents: a clean web UI where you ask questions about your own files, serving both end users and developers.
- 14
ds4
23.9Kantirez/ds4 · CDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 15
candle
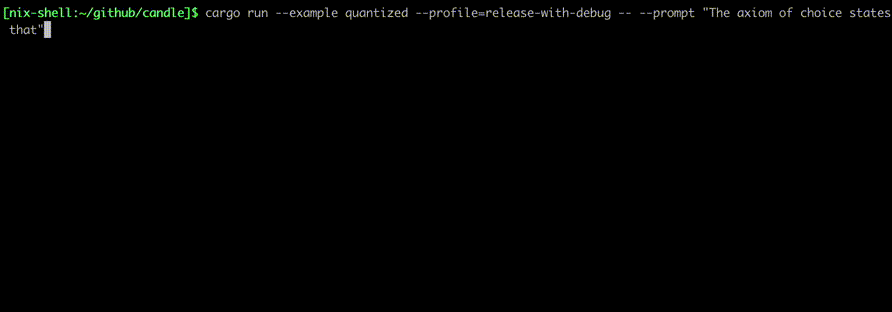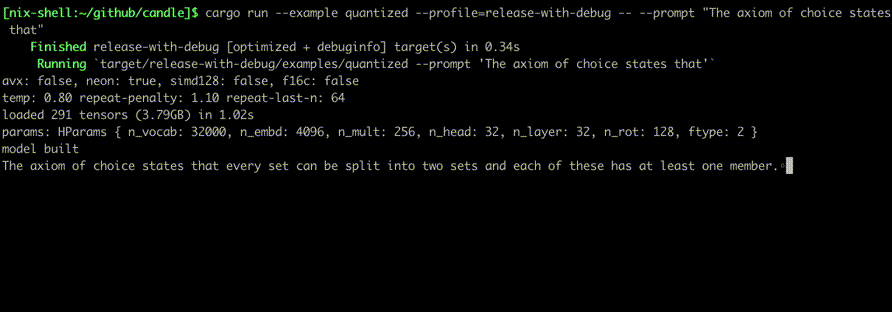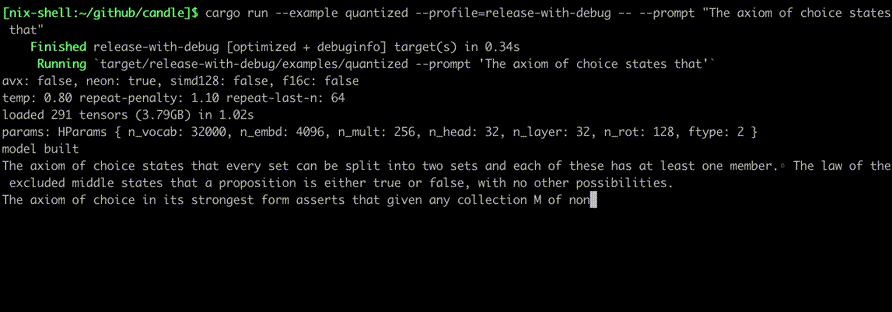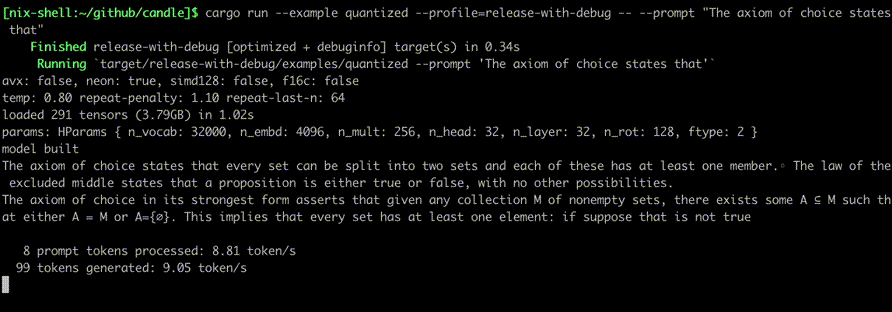
21.2Khuggingface/candle · RustCandle is a minimalist machine learning framework for Rust, focused on performance (including GPU support) and ease of use. It ships with ready examples for LLMs, speech, vision and text-to-image models.
- 16
FunASR
20.7Kmodelscope/FunASR · PythonFunASR is an open-source industrial speech recognition toolkit covering ASR, VAD, punctuation, speaker diarization, and emotion/audio-event models, deployable offline, in streaming mode, on edge devices, or behind an OpenAI-compatible API.
- 17
Qwen3-Coder
16.8KQwenLM/Qwen3-Coder · PythonQwen3-Coder is the code-focused branch of the Qwen3 large language model family from the Qwen team — open-weight models built for coding and agentic tasks, available in several sizes.
- 18
Llama-Chinese
14.8KLlamaChinese/Llama-Chinese · PythonLlama-Chinese is a Chinese-language community project built around Meta's Llama models (Llama2, Llama3, Llama4). It provides Chinese pretraining and fine-tuning, a custom Atom model series optimized for Chinese, and resources for training, deploying and using Llama in Chinese for free commercial use.
- 19
RWKV-LM
14.7KBlinkDL/RWKV-LM · PythonRWKV (pronounced 'RwaKuv') is an RNN architecture with transformer-level LLM performance that can also be trained in parallel like GPT. The current generation, RWKV-7 'Goose', is 100% attention-free, linear-time and constant-memory (no kv-cache).
- 20
GPU-Puzzles
12.5Ksrush/GPU-Puzzles · Jupyter NotebookGPU-Puzzles is an interactive Jupyter notebook that teaches beginner GPU programming by having you implement CUDA kernels directly, puzzle by puzzle, instead of reading theory.
- 21
MiniCPM
11.6KOpenBMB/MiniCPM · Jupyter NotebookMiniCPM is OpenBMB's family of small, open-source LLMs built for on-device and resource-constrained use. The newest release, MiniCPM5-2B, is a dense 2B-parameter model that reaches open-source state-of-the-art for its size class while staying competitive with much larger 4B-class models.
- 22

WanGP
10.7Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 23

llama-cpp-python
10.7Kabetlen/llama-cpp-python · Python'llama-cpp-python' provides Python bindings for the llama.cpp C/C++ library, giving both low-level ctypes access and a high-level API for running GGUF language models locally for text completion, chat, embeddings and more.
- 24
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 25
Soup
9.3KMakazhanAlpamys/Soup · PythonSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
- 26
Operit
8.8KAAswordman/Operit · KotlinOperit is an open-source AI agent platform for Android that connects cloud or local AI models to your phone's system, terminal, browser, files, and project workspaces so the AI can actually perform tasks like file management, coding, and device automation.
- 27
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 28
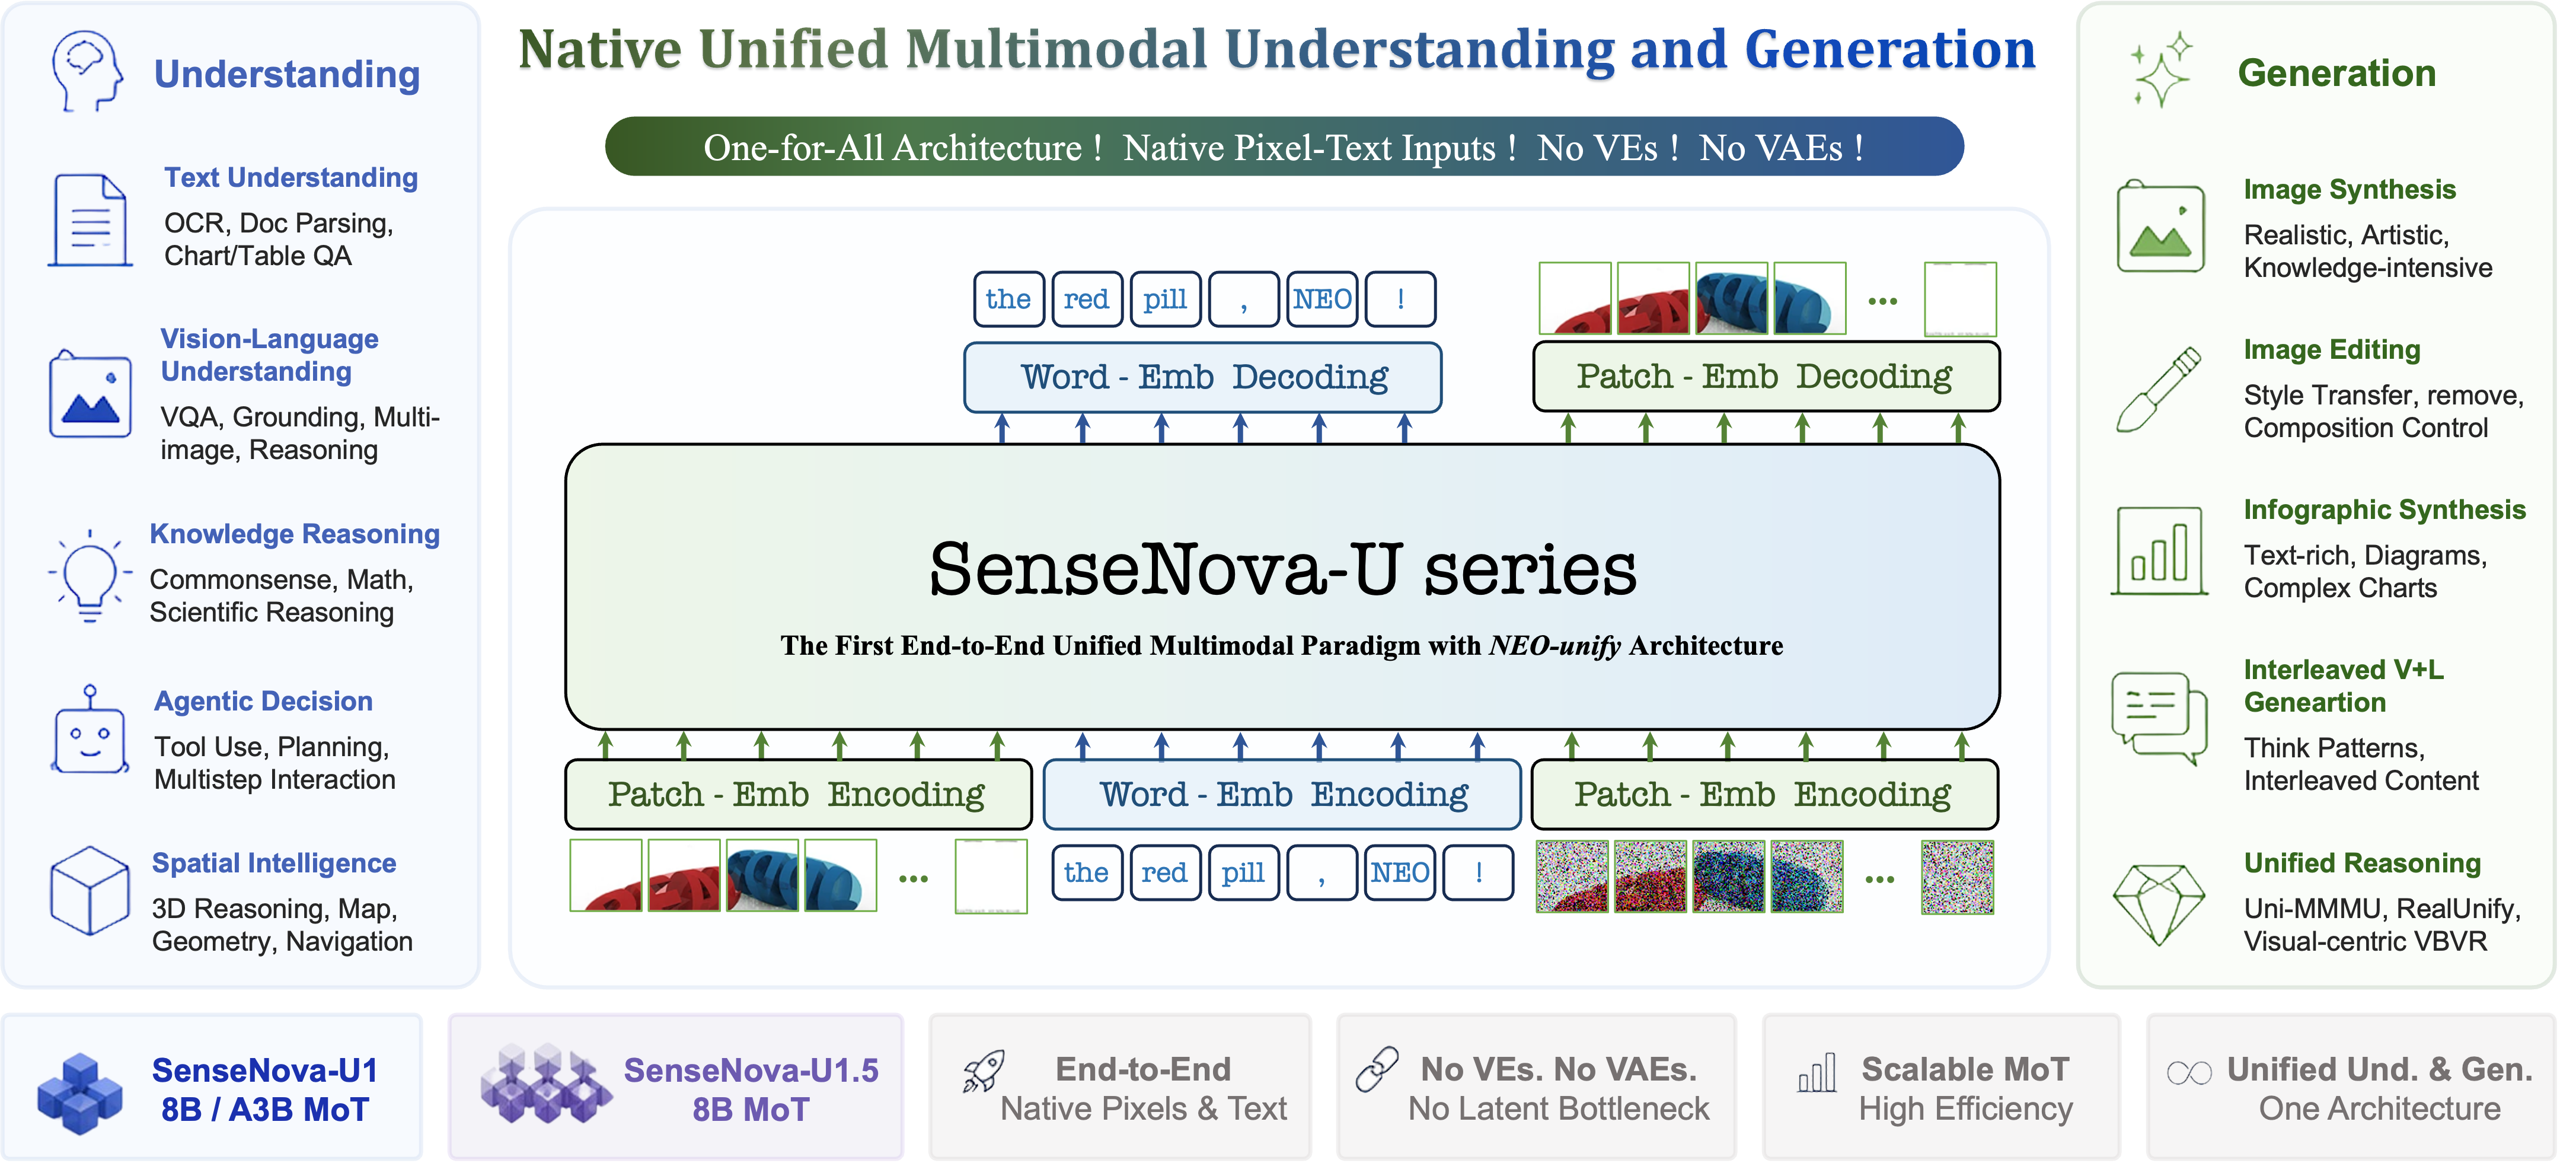
SenseNova-U1
6.9KOpenSenseNova/SenseNova-U1 · PythonOpen-source multimodal models that unify image understanding, reasoning and image generation in one architecture. The current release, SenseNova-U1.5-8B-MoT, creates and edits images up to native 4K.
- 29
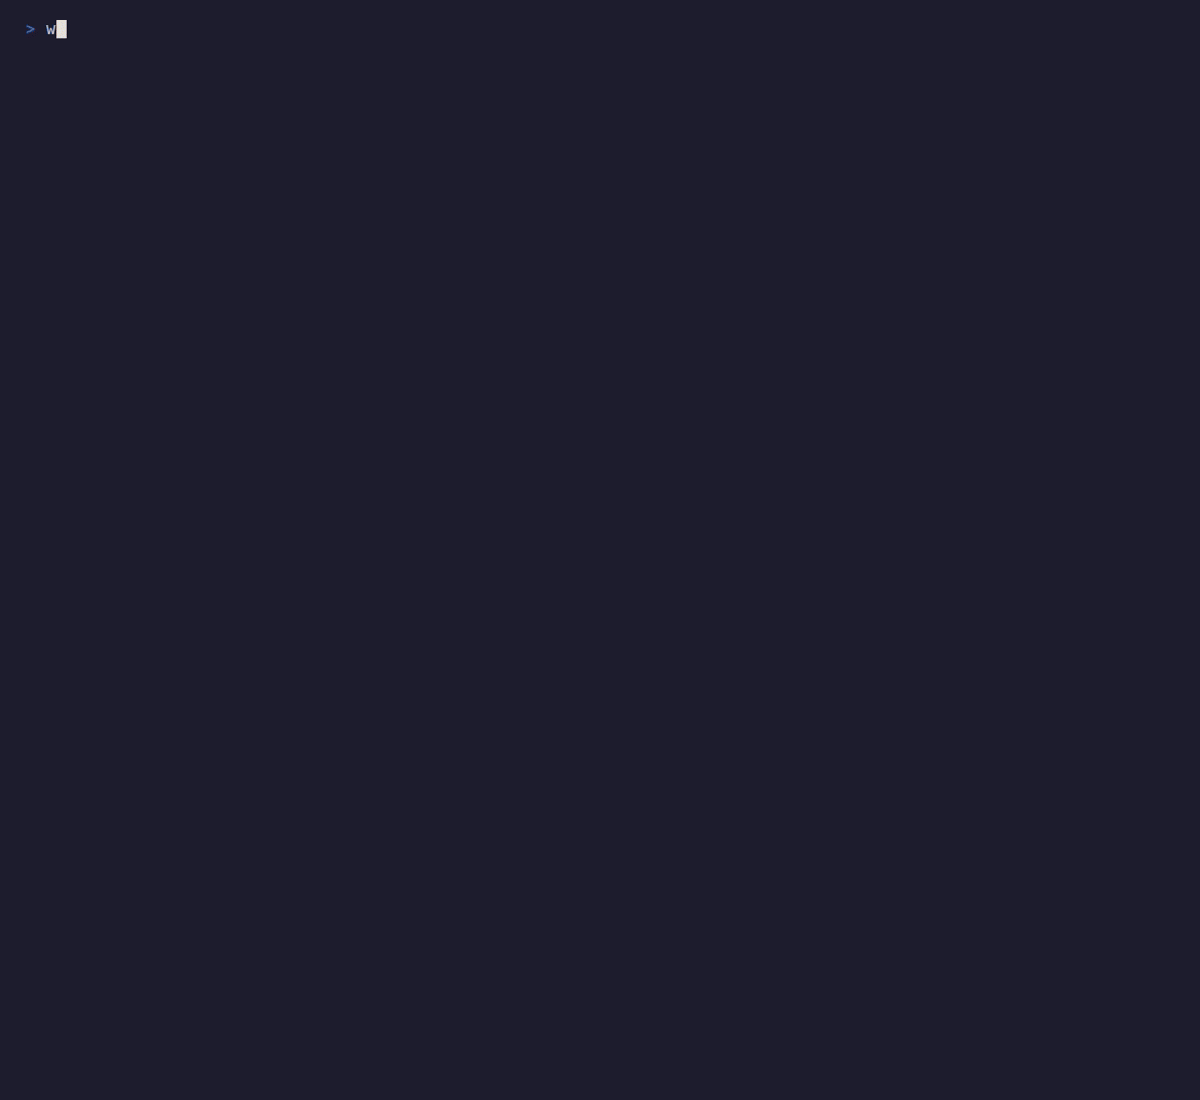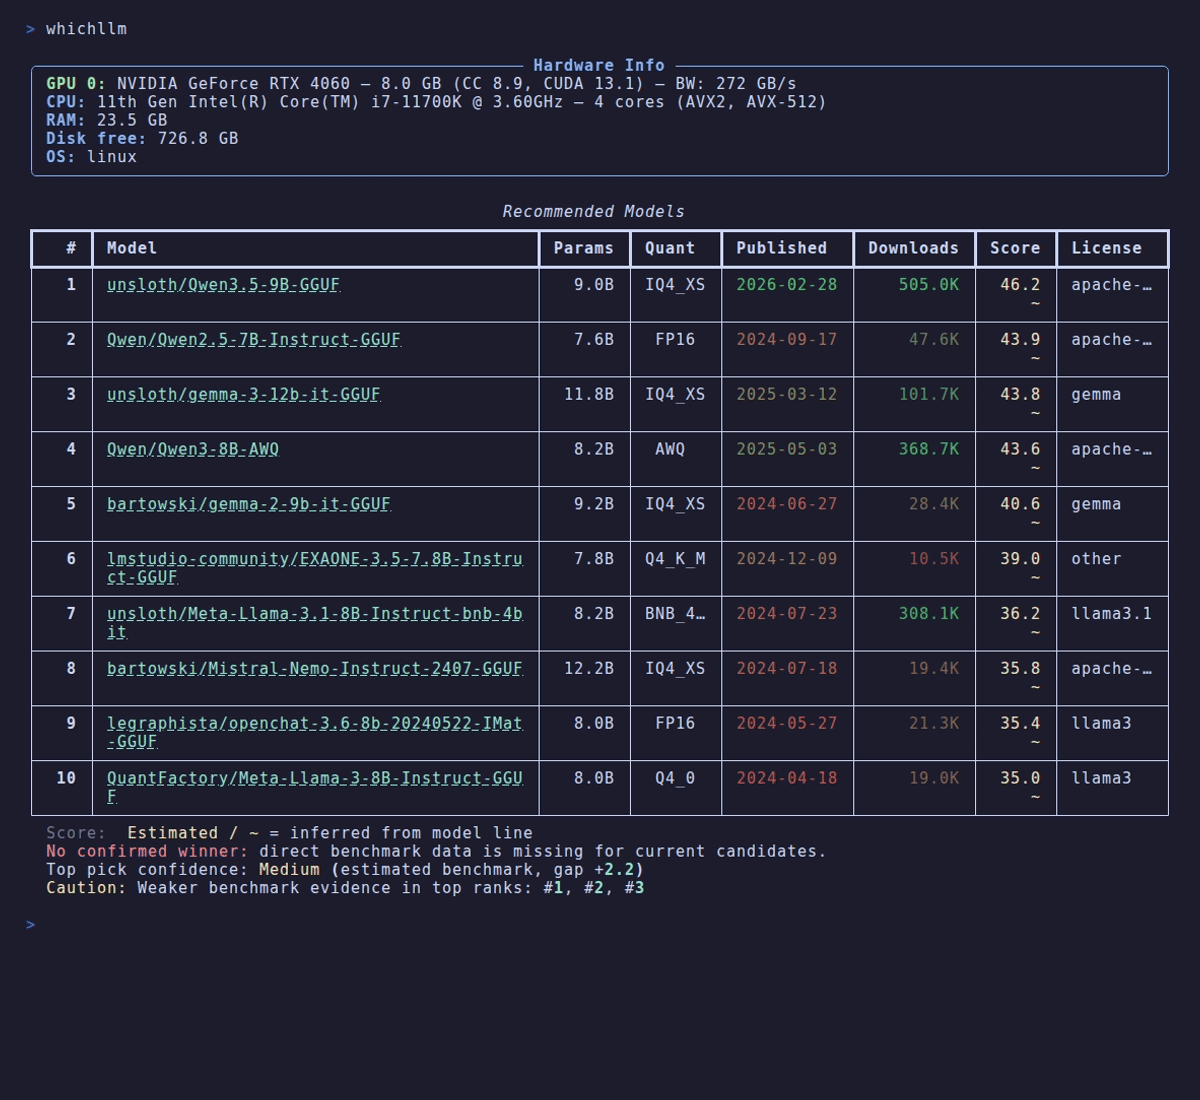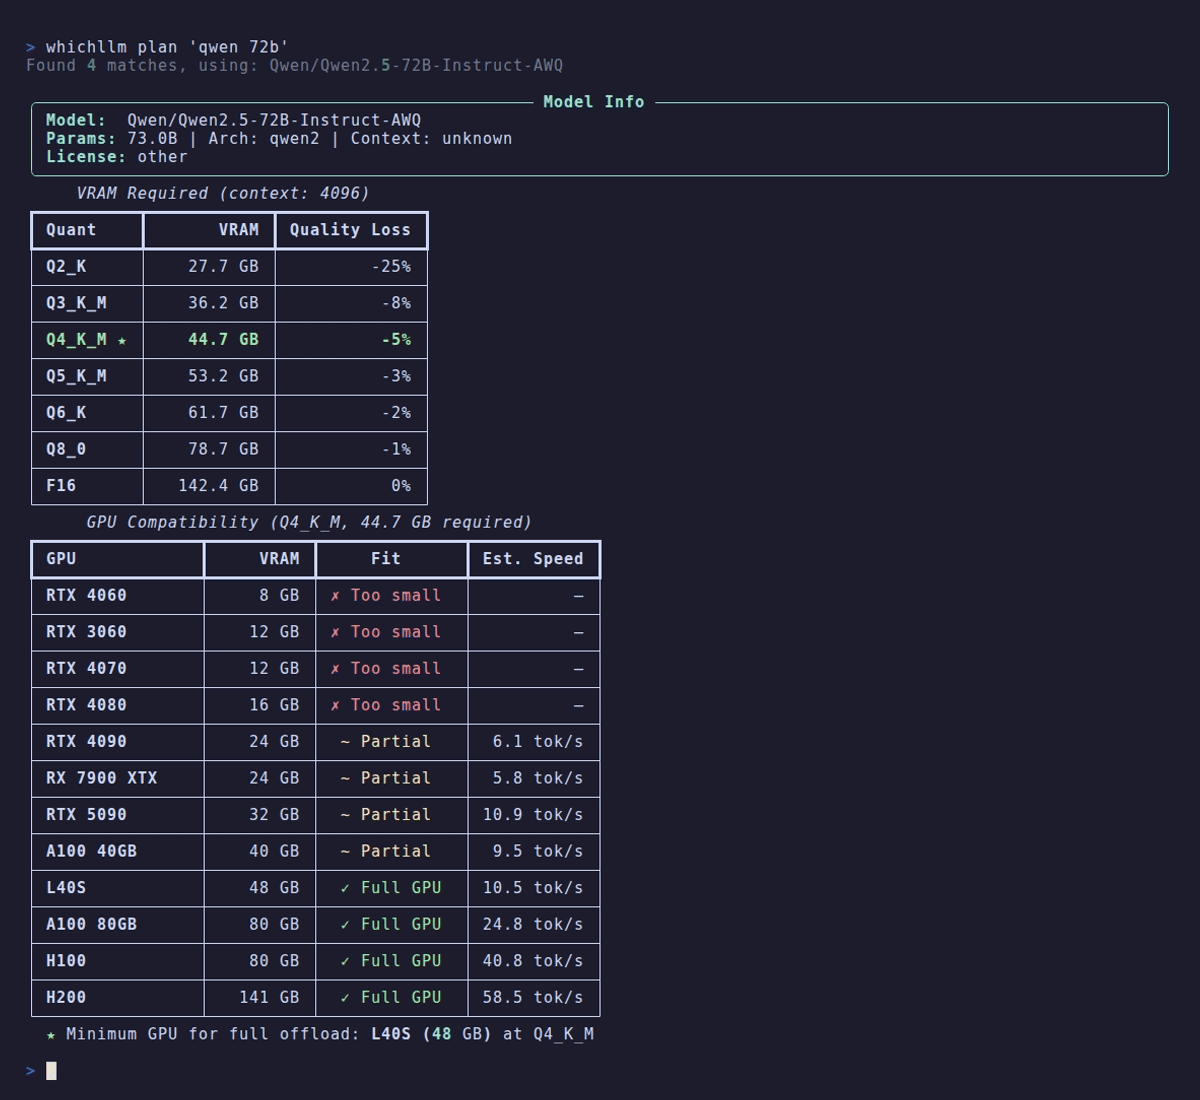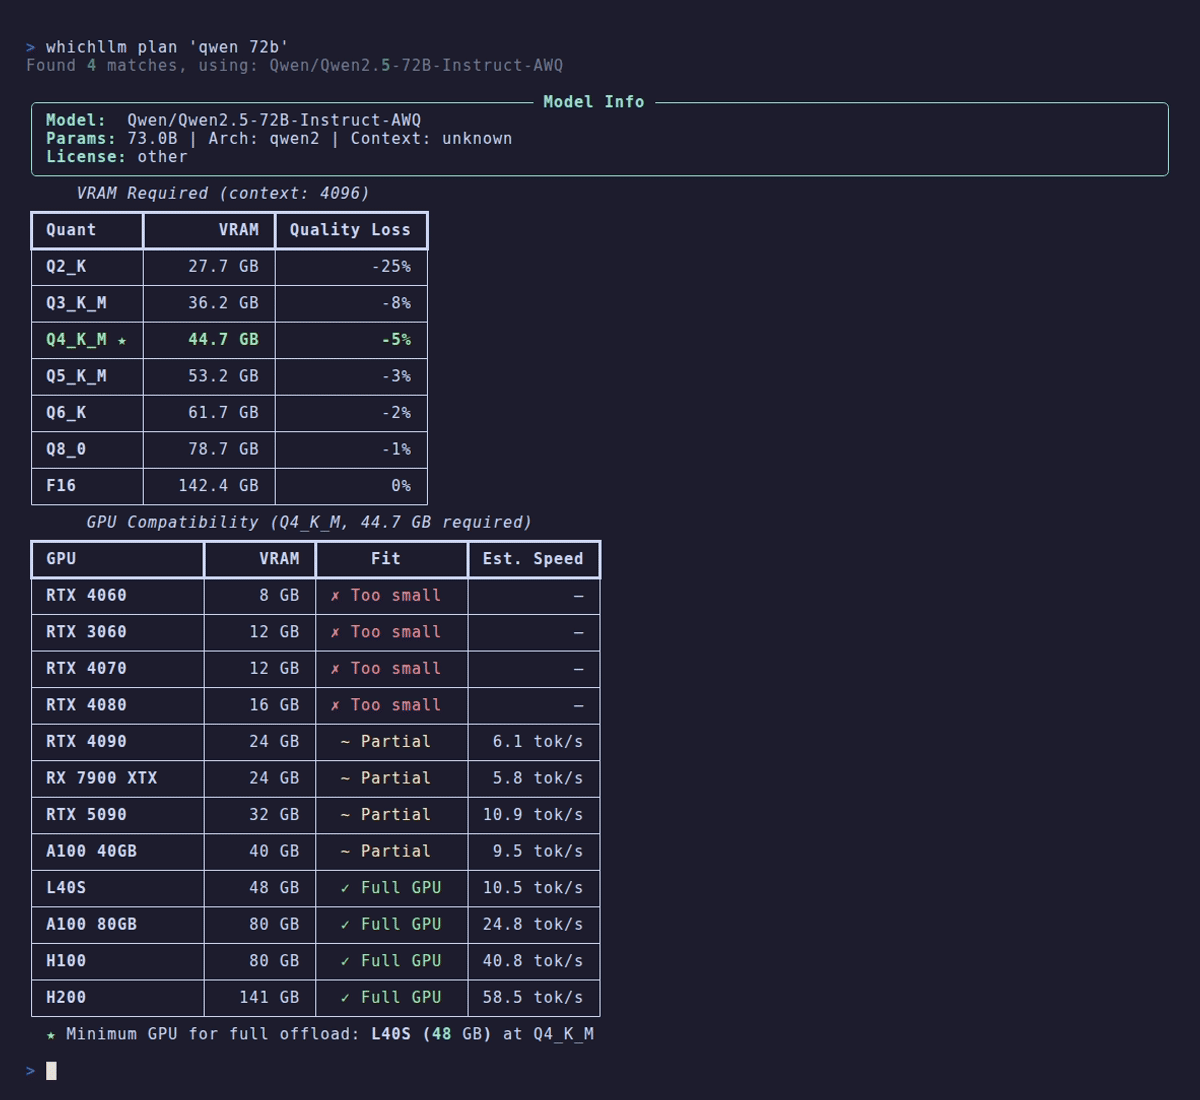
whichllm
6.8KAndyyyy64/whichllm · PythonA CLI tool that finds the best local LLM for your machine: it auto-detects your GPU/CPU/RAM and ranks HuggingFace models that fit, scored by real benchmarks rather than parameter count.
- 30
koharu
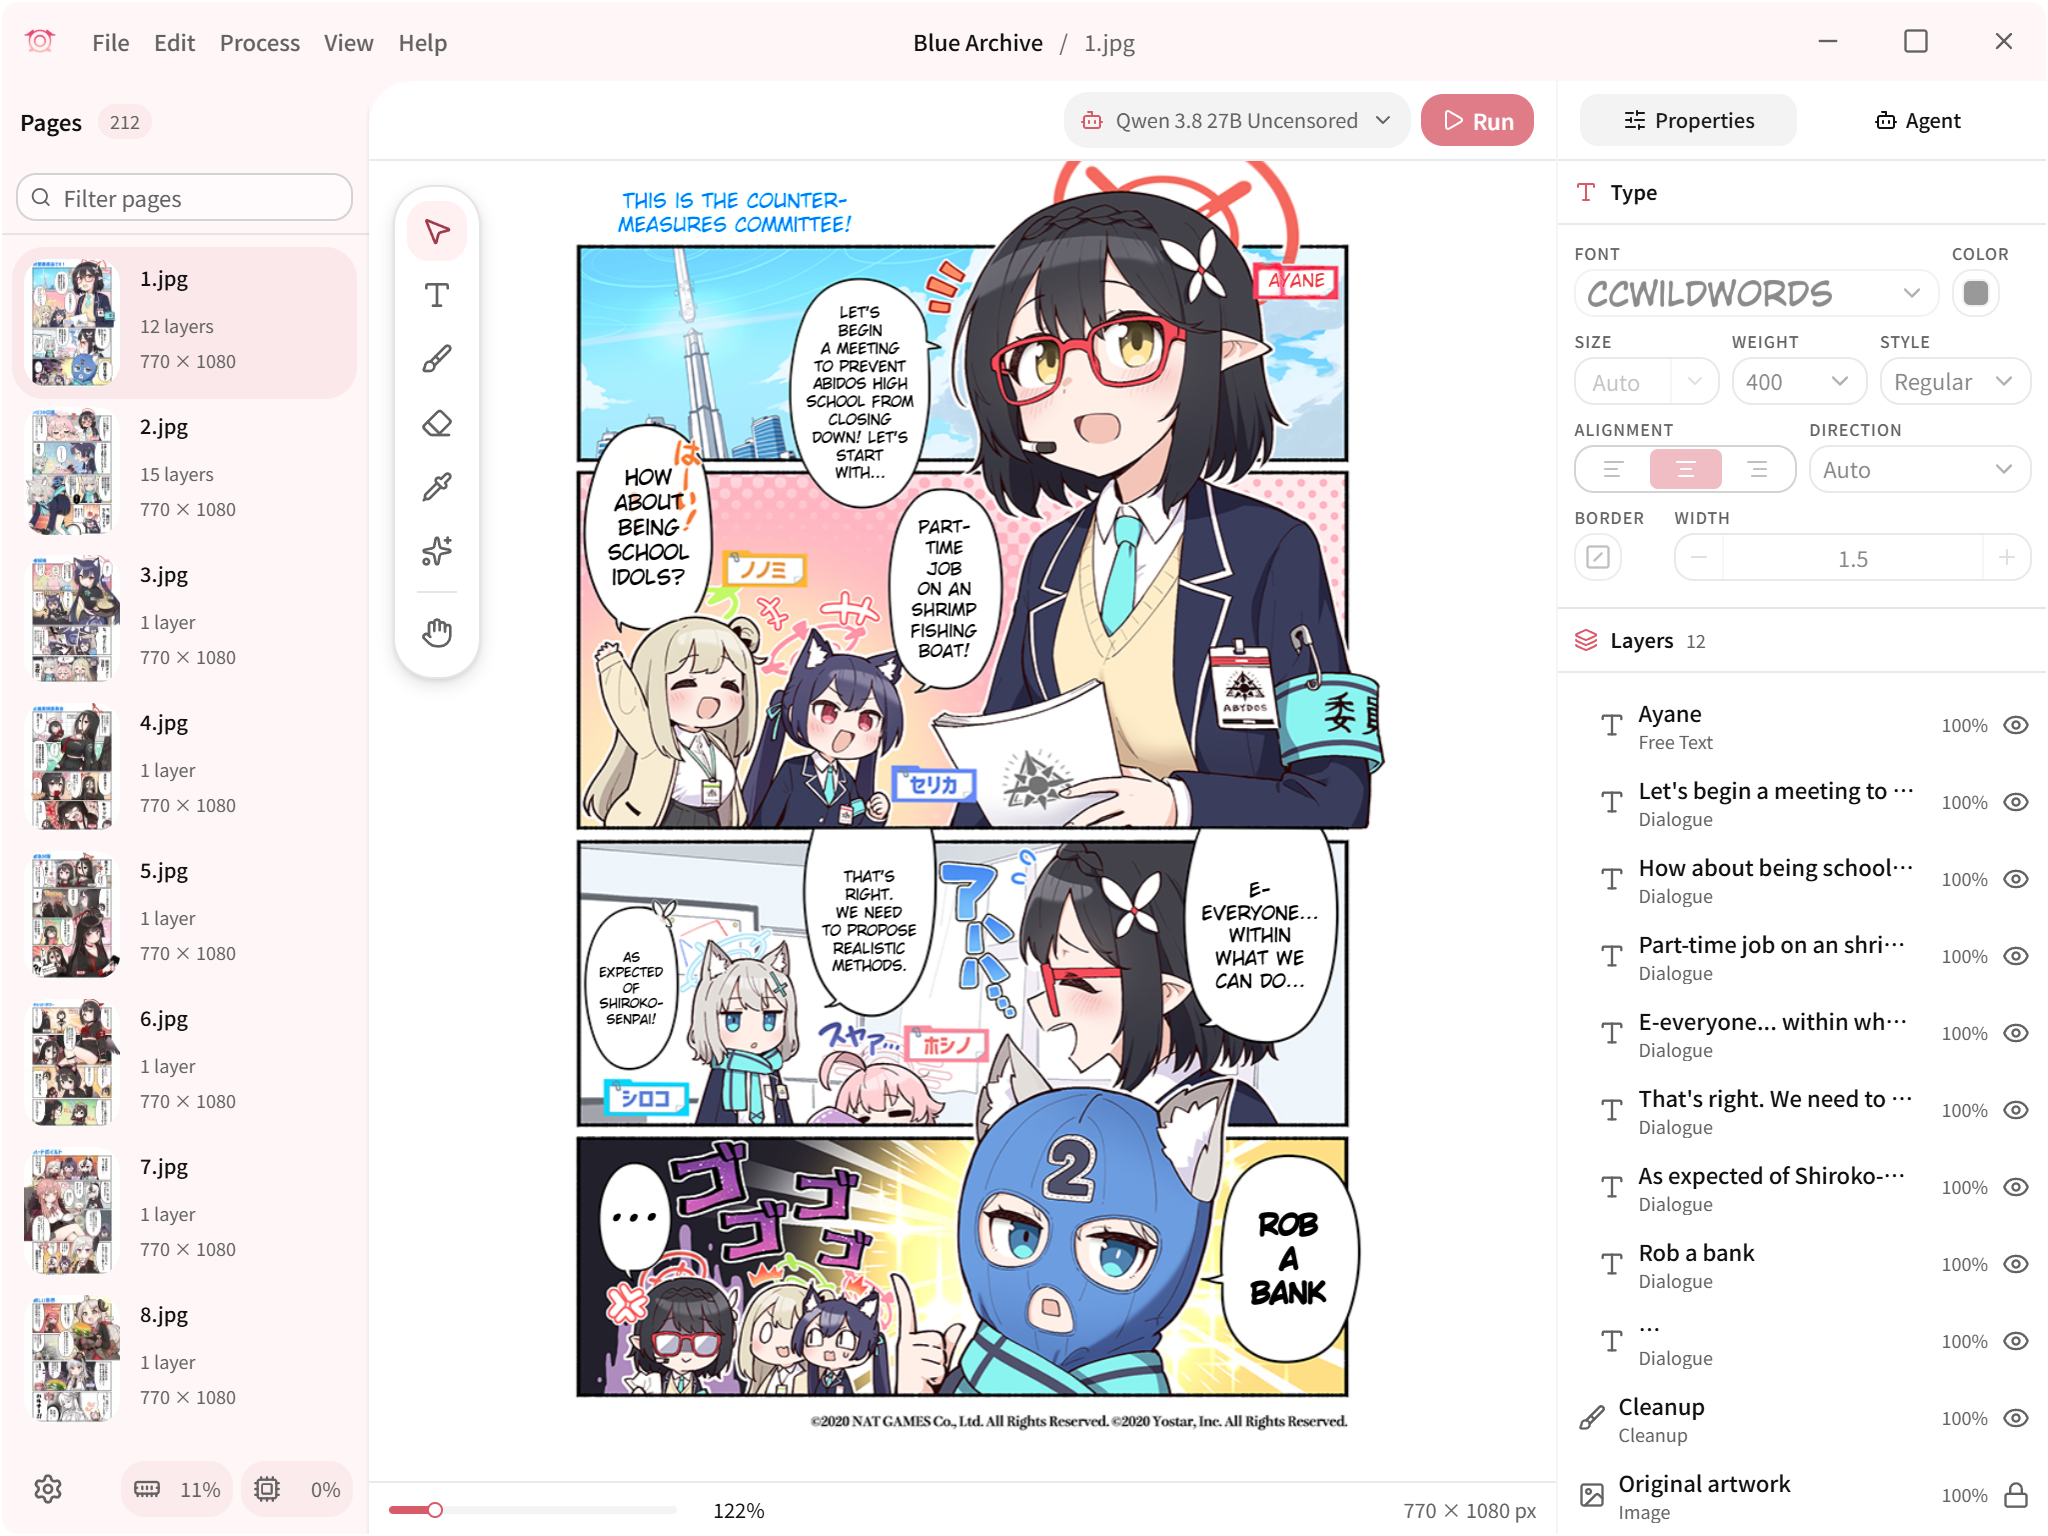
6.4Kkoharu-rs/koharu · RustKoharu is an ML-powered manga translator written in Rust that combines object detection, OCR, inpainting, and LLMs to automate translating manga pages while running everything locally.
- 31

neutts
6.3Kneuphonic/neutts · PythonNeuTTS is a collection of open-source, on-device text-to-speech language models that can clone a voice from just a few seconds of reference audio.
- 32
ai-agents-from-scratch
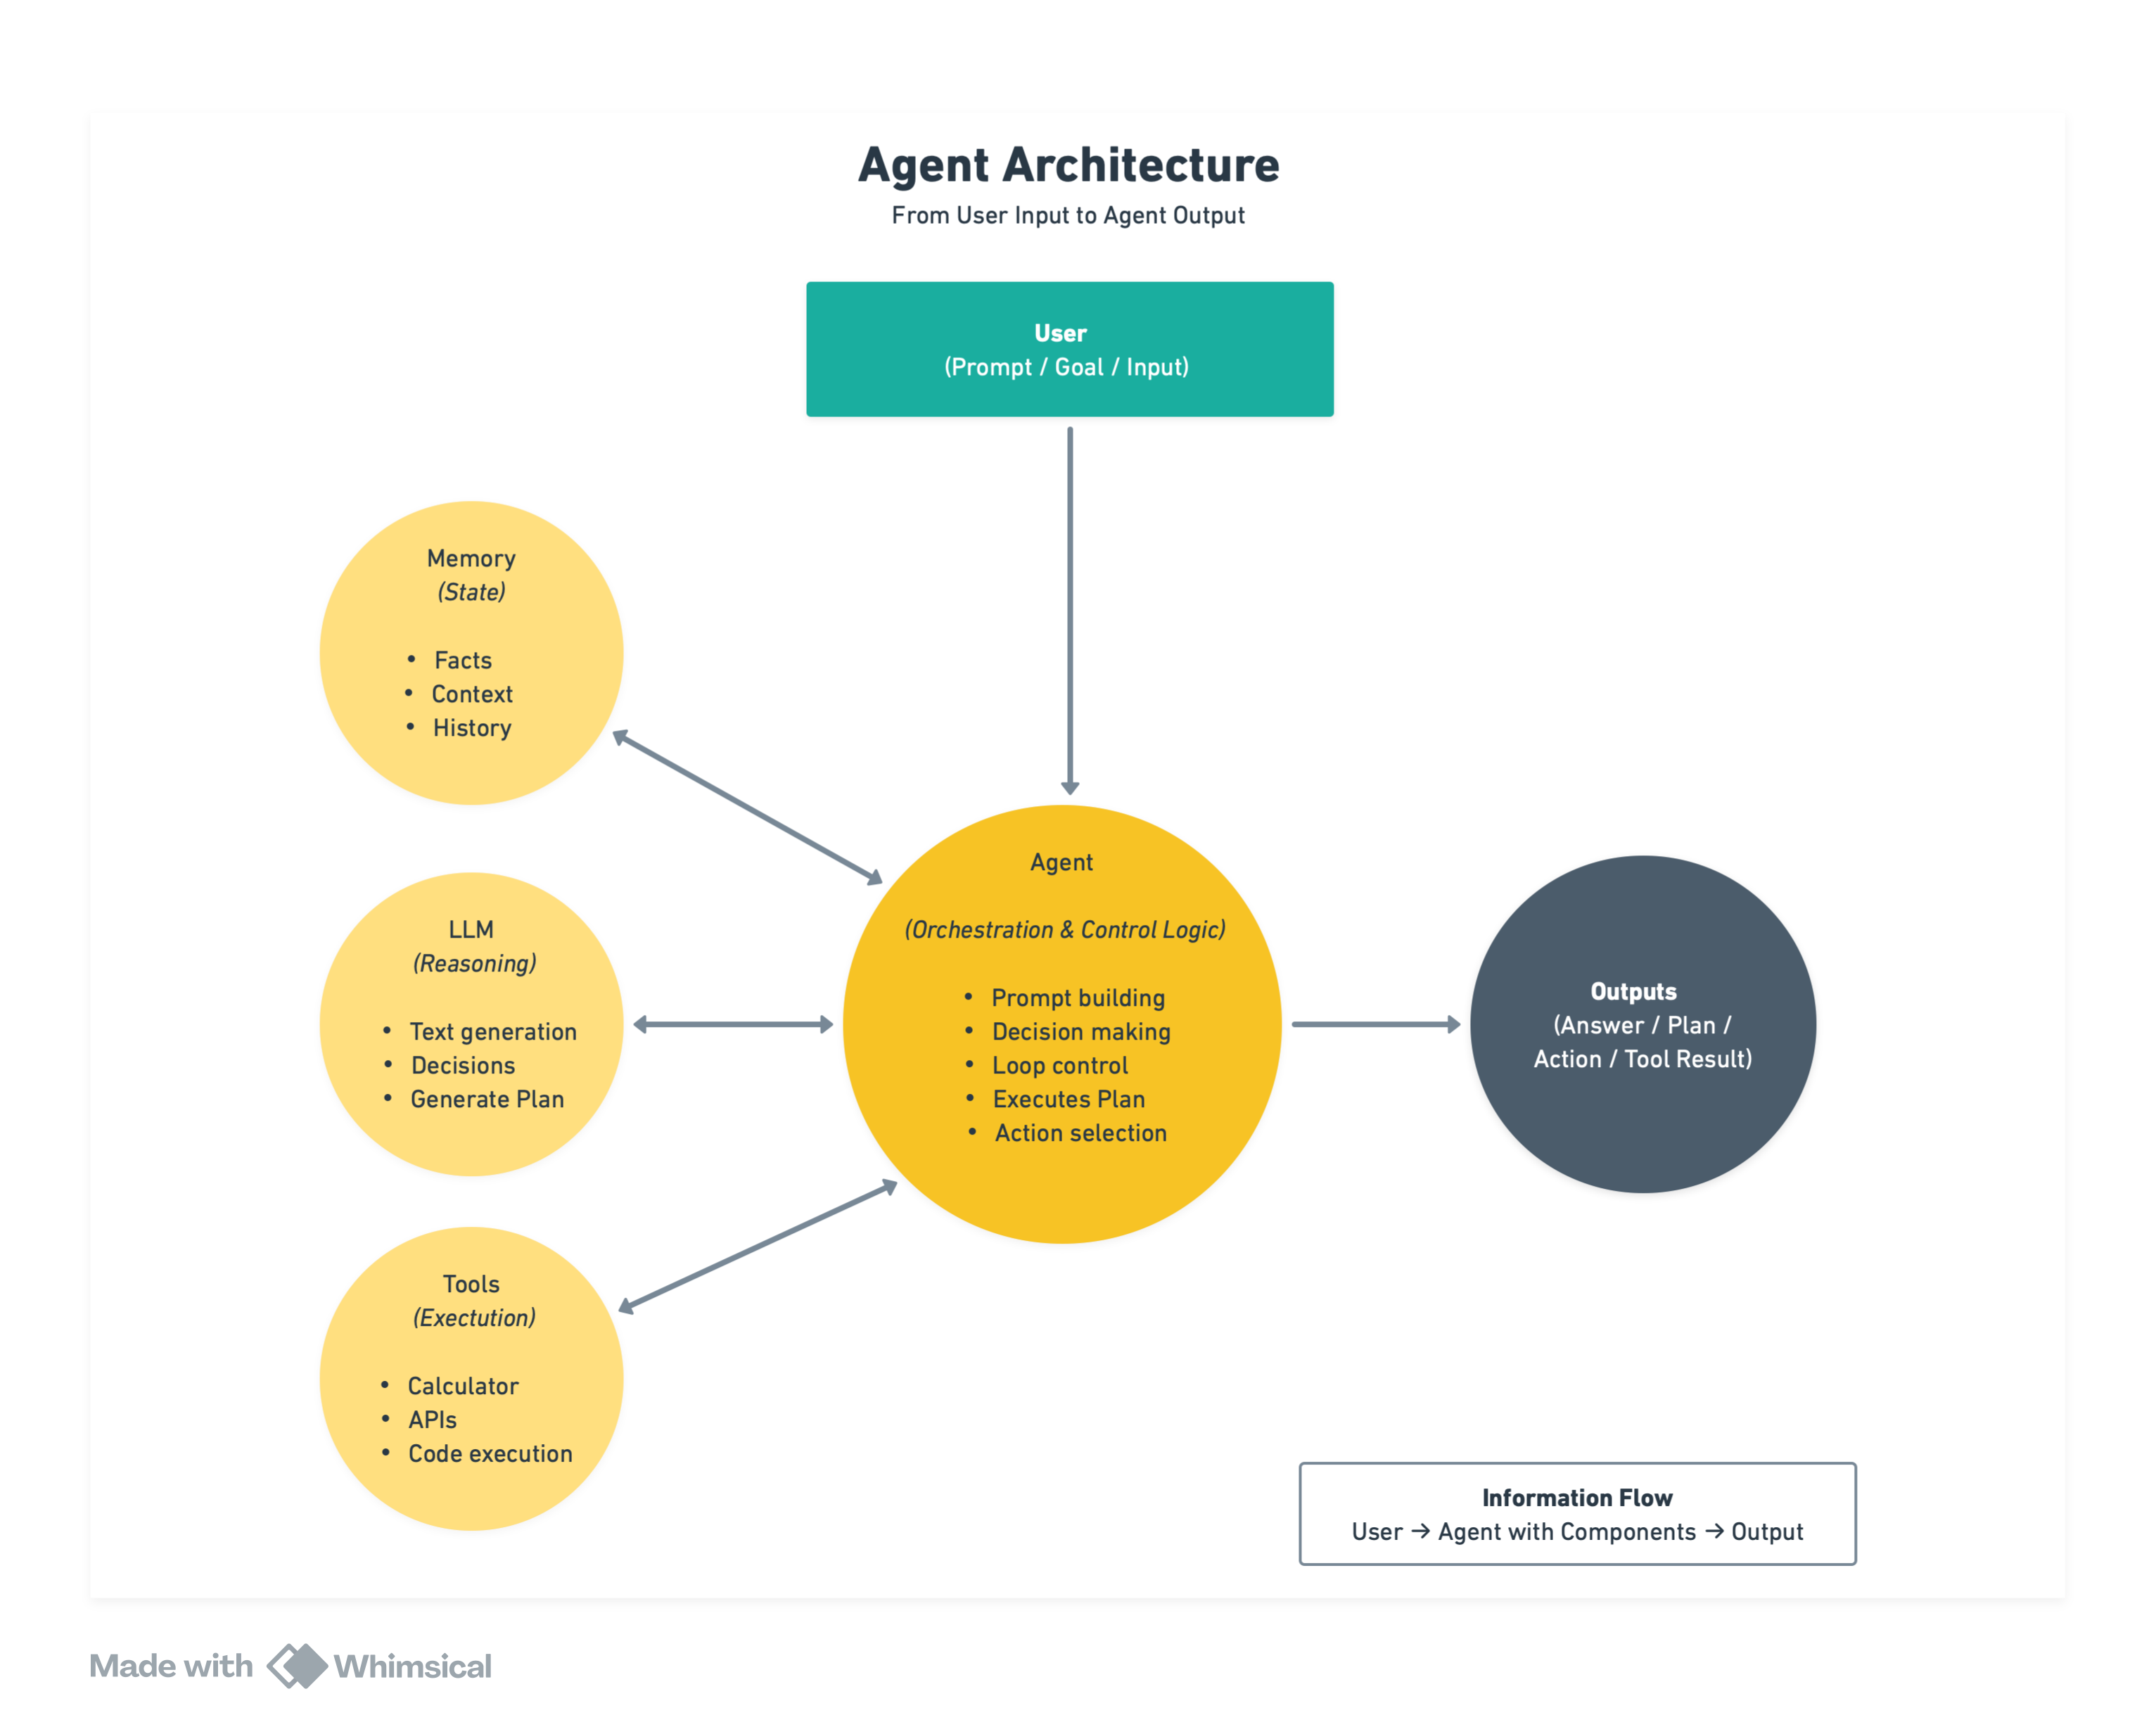
4.9Kpguso/ai-agents-from-scratch · JavaScriptA hands-on tutorial repo that teaches you to build AI agents from first principles using local LLMs via node-llama-cpp, with no frameworks involved, so you understand function calling, memory, and ReAct before using production frameworks.
- 33
SemIf-OpenJev
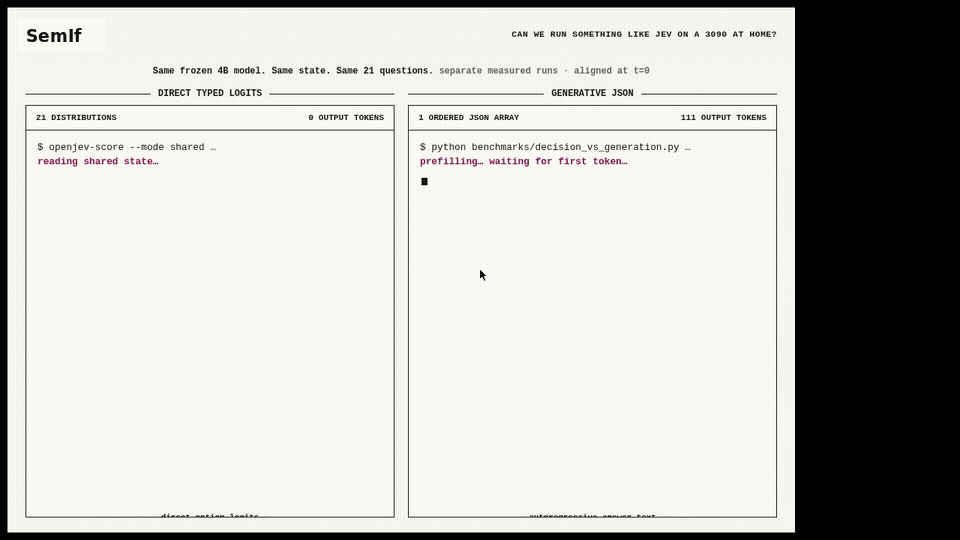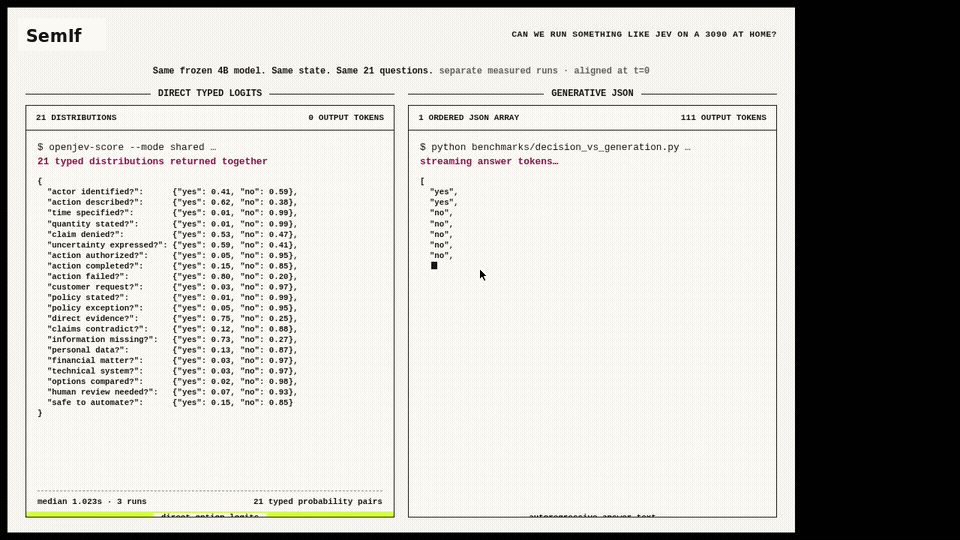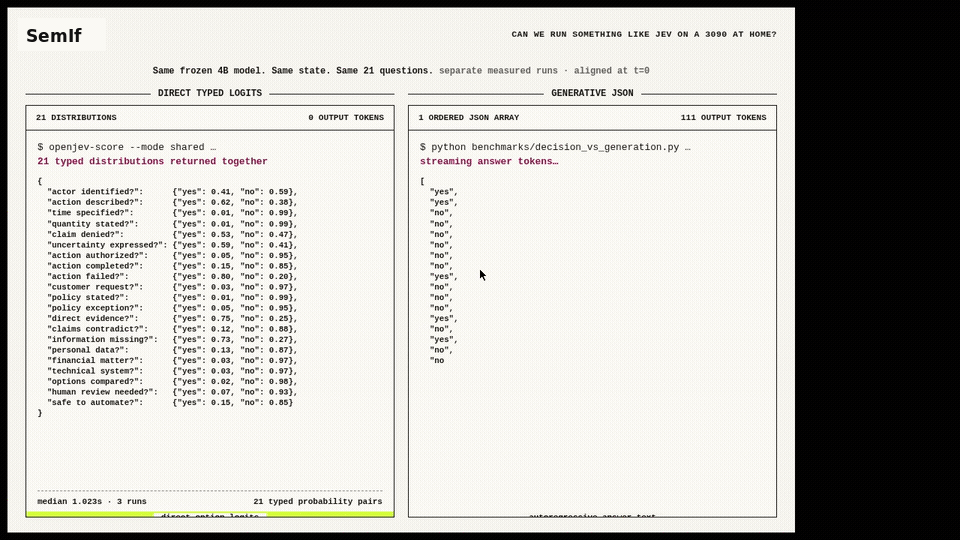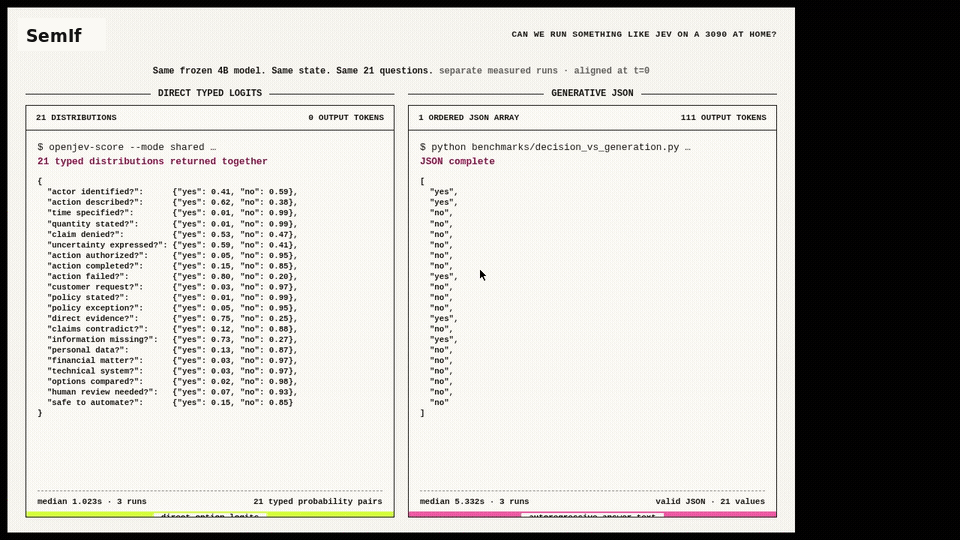
4.8KTheoLeeCJ/SemIf-OpenJev · PythonSemIf (formerly OpenJev) is an independent research project that runs runtime-defined semantic decisions with open models on one consumer GPU, mirroring the interface of TypeSafe's closed Jev service but not its undisclosed model.
- 34
Qwen3.8
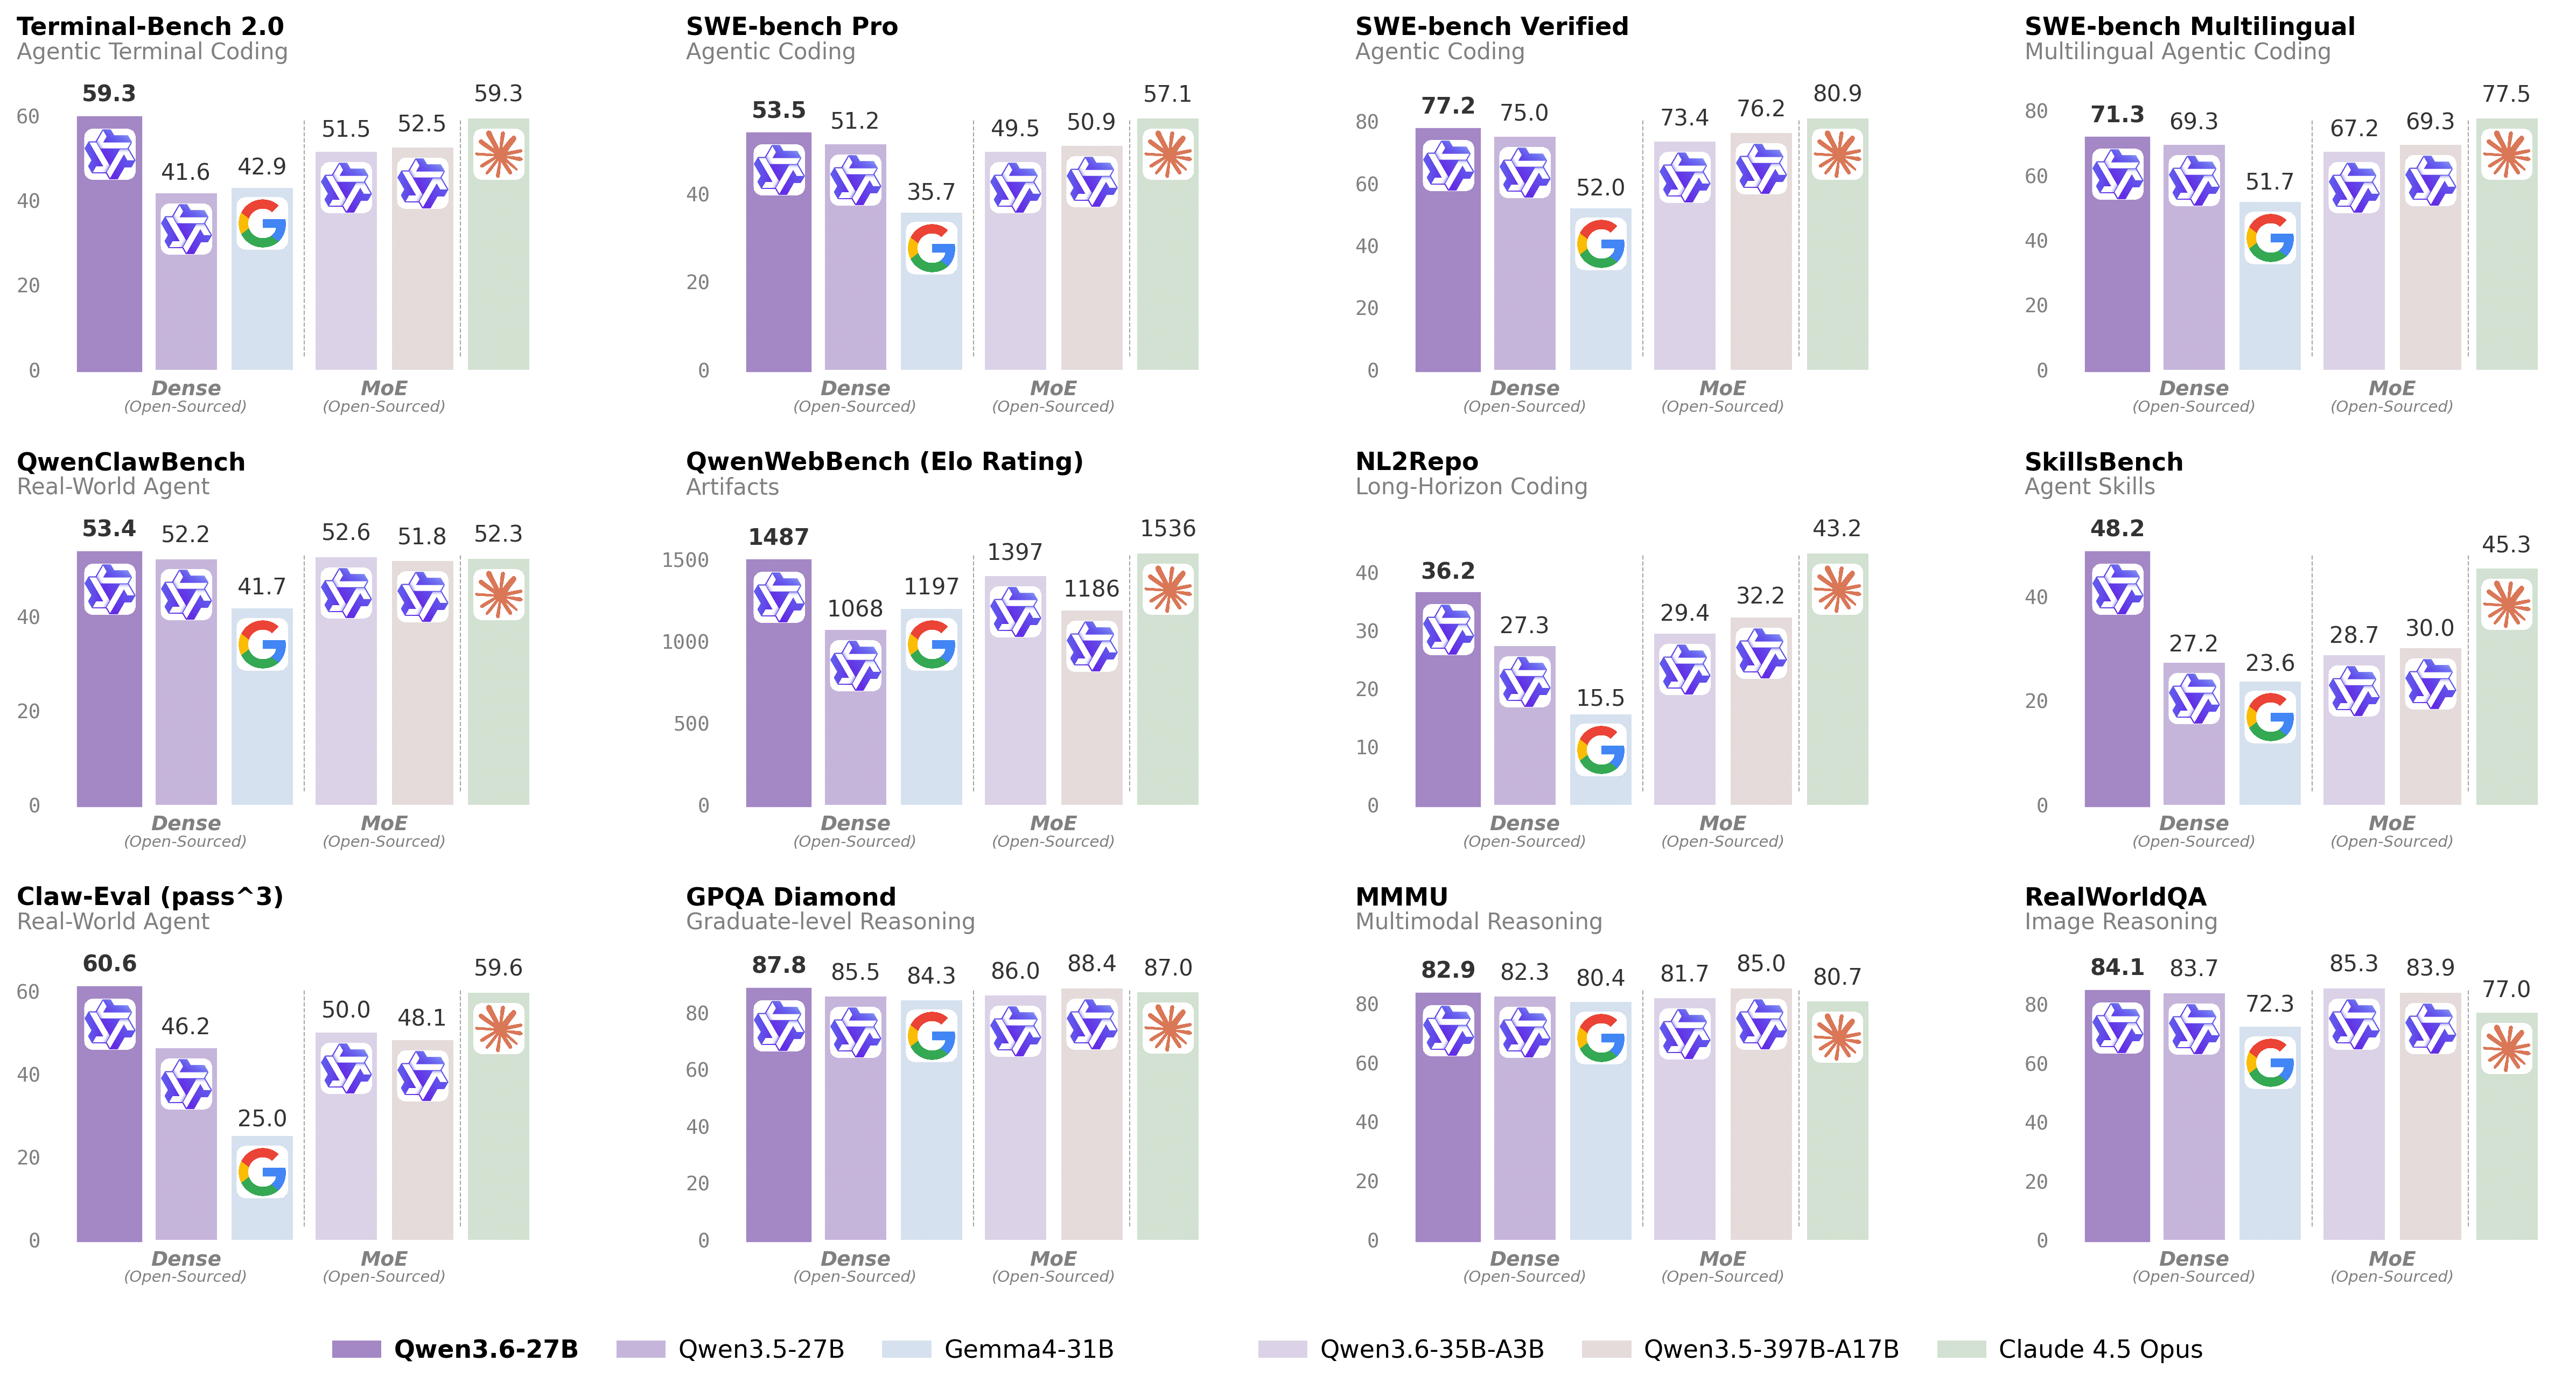
4.3KQwenLM/Qwen3.8Qwen3.8 is the latest open large language model release from Alibaba's Qwen team, part of the Qwen3.5 series that also includes Qwen3.5 and Qwen3.6, aimed at coding, professional work, research, and long-horizon agentic tasks.
- 35
MOSS-TTS
4.2KOpenMOSS/MOSS-TTS · PythonMOSS-TTS Family is an open-source speech and sound generation model family from OpenMOSS, covering long-form narration, multi-speaker dialogue, voice design, sound effects, and real-time streaming text-to-speech.
- 36

Bonsai-demo
3.4KPrismML-Eng/Bonsai-demo · ShellBonsai Demo is a local-inference demo for Bonsai 2 27B, a ternary-weight large language model that runs on a laptop or single GPU via llama.cpp or MLX, with chat, vision, and agentic tool-calling support out of the box.
- 37

atomic-agent
3.4KAtomicBot-ai/atomic-agent · TypeScriptAtomic Agent is a local-first AI agent that runs the full control loop and all its state on your own machine, using open-weight models through llama.cpp or cloud models. It can browse the web, edit files, run approved shell commands, inspect documents, and remember context across sessions.
- 38
mlx-serve
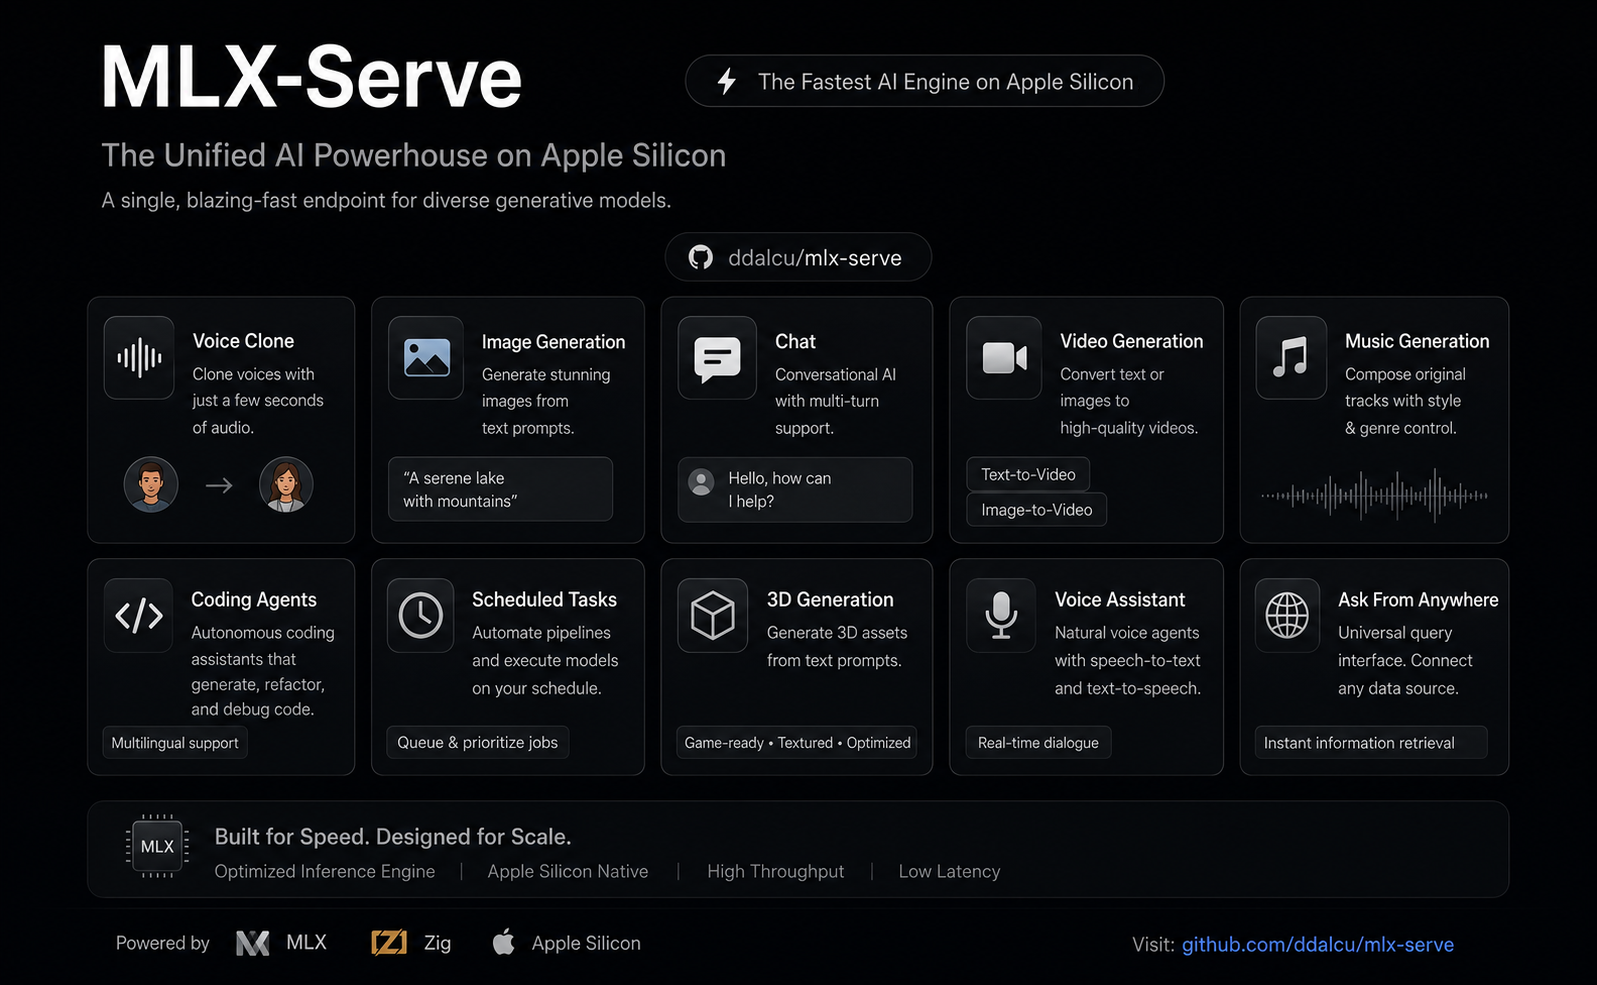
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 39
NeoHorse
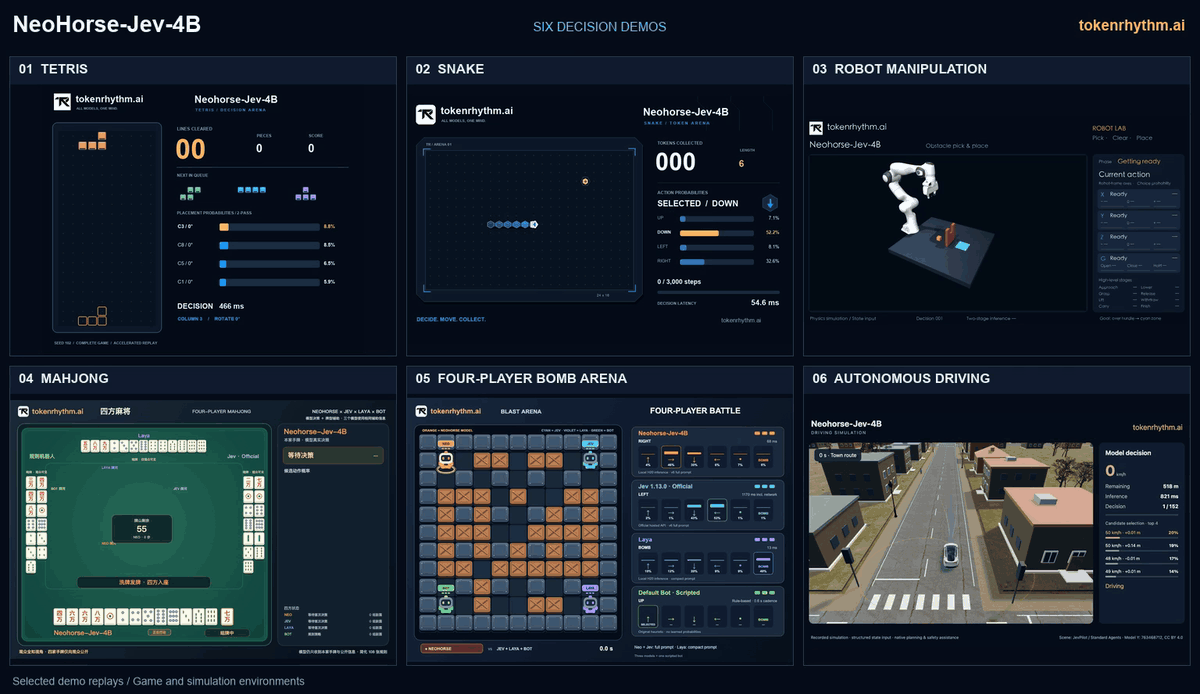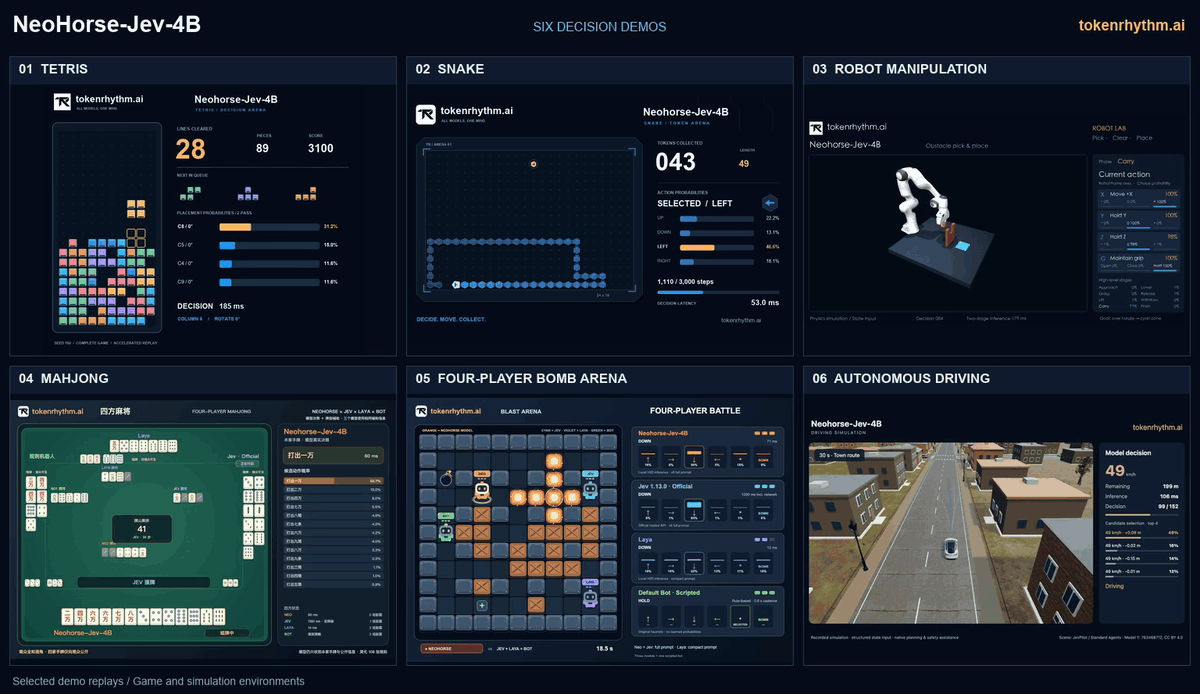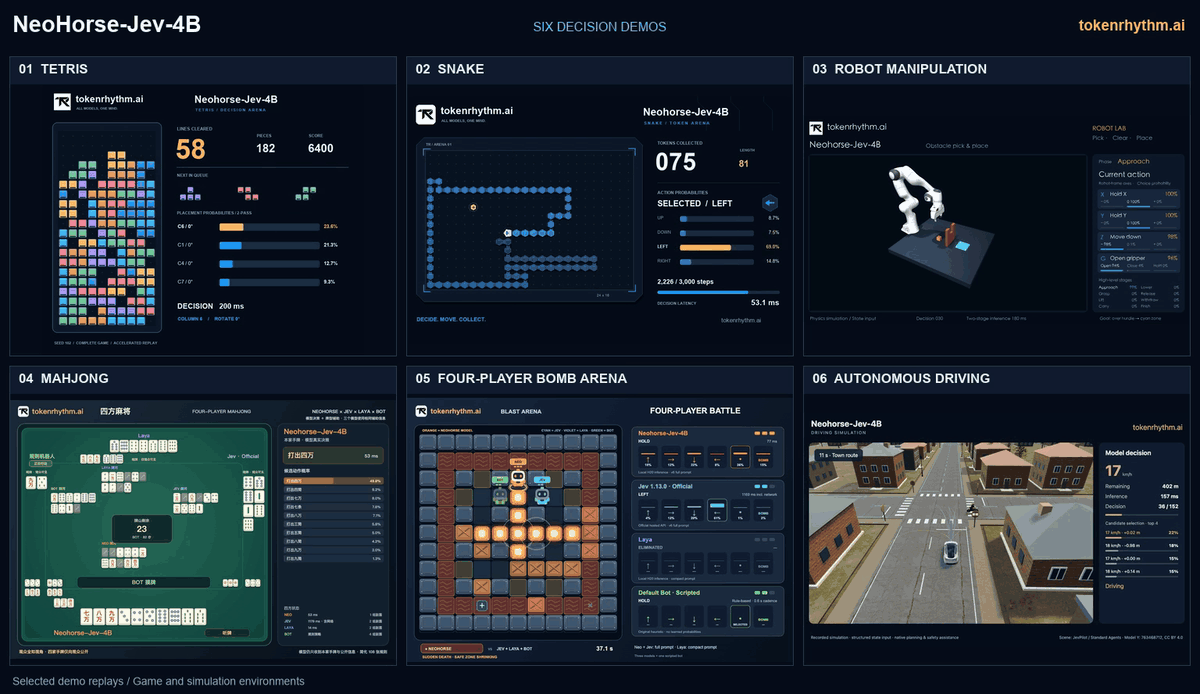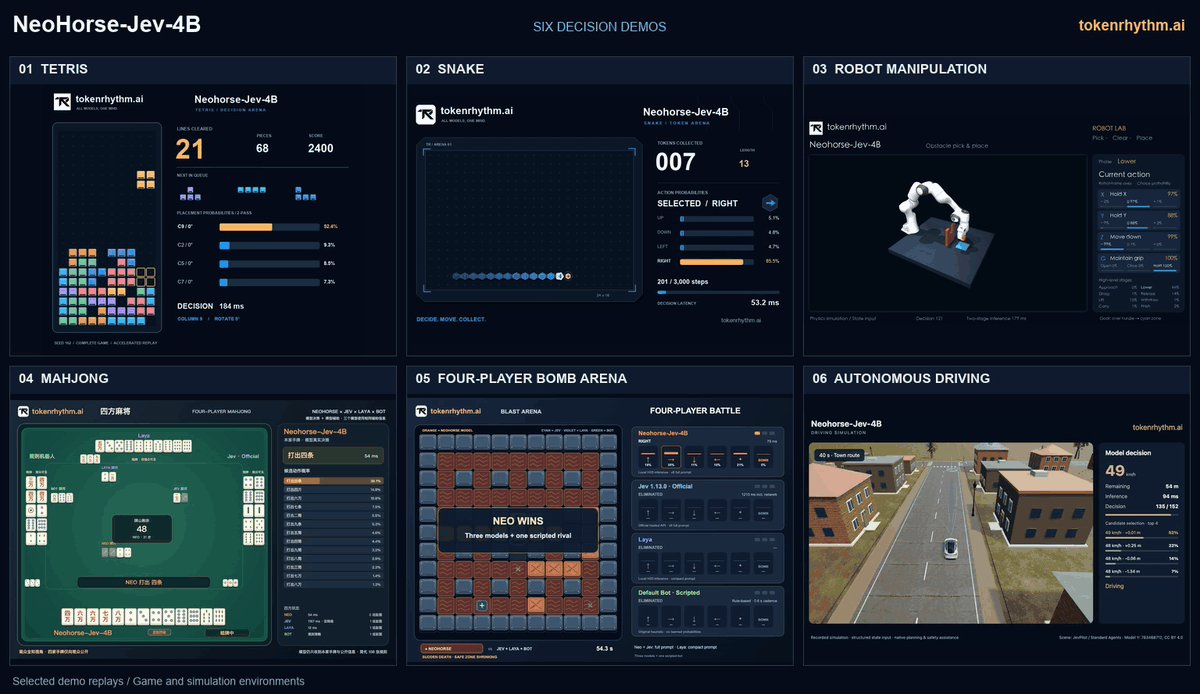
1.7KTokenRhythm/NeoHorse · PythonNeoHorse is TokenRhythm's family of open-weight language models built for agent workflows, with the 4B and 9B NeoHorse-1 checkpoints handling tool use, coding, and instruction following, plus a companion decision model called NeoHorse-Jev.
- 40
yovoice
1.7Kleemysw/yovoice · TypeScriptyovoice is an open-source desktop app for macOS and Windows that turns text into natural, expressive speech locally, with voice cloning and emotion control, and no cloud API calls or per-character fees.
- 41
nobodywho
1.6Knobodywho-ooo/nobodywho · RustNobodyWho is an open-source inference engine that runs LLMs locally and offline on phones, desktops and even Apple Watch — no API keys, no cloud calls. Under the hood it is powered by llama.cpp and accelerates through the GPU via Vulkan or Metal.
- 42
jev
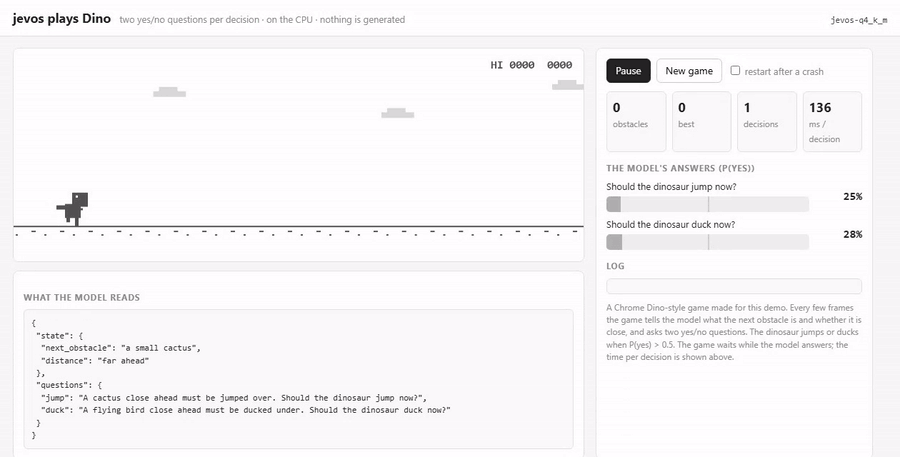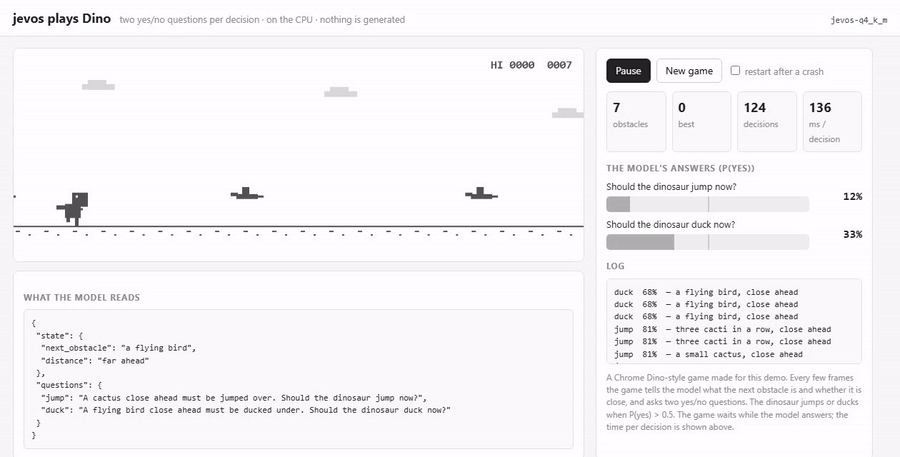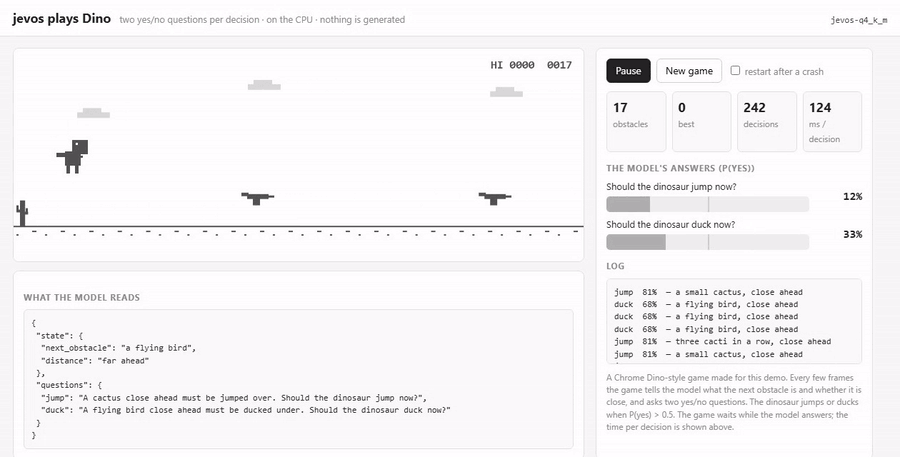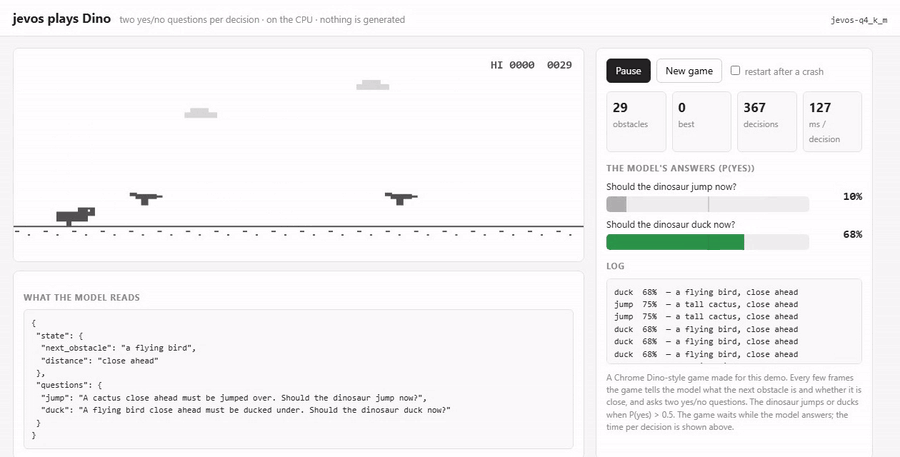
1.4Kfeder-cr/jev · C++jevos-1b is a free, open-source yes/no decision engine that runs locally on your laptop's CPU, returning the probability that the answer is 'yes' for a given text plus question in about 50-220 ms, as a self-hosted alternative to the cloud-based Jev service.
- 43
Hy-MT2
1.3KTencent-Hunyuan/Hy-MT2 · PythonHy-MT2 is Tencent Hunyuan's family of 'fast-thinking' multilingual translation models, released in three sizes (1.8B, 7B, and 30B-A3B MoE), that translate among 33 languages and follow complex translation instructions.
- 44
decider
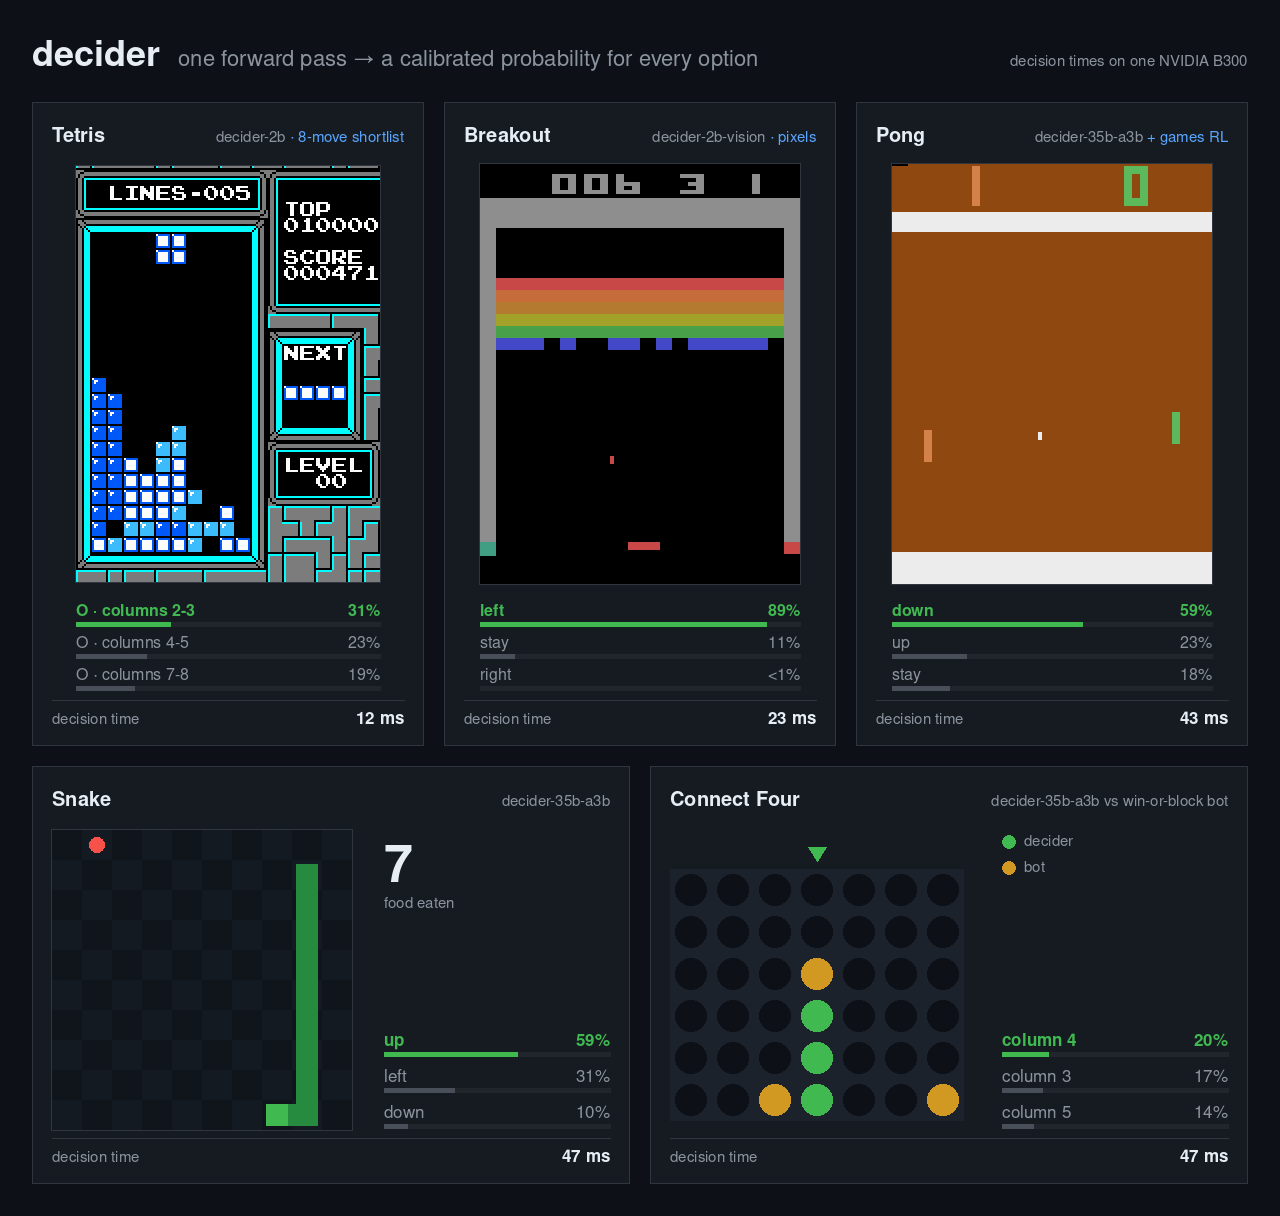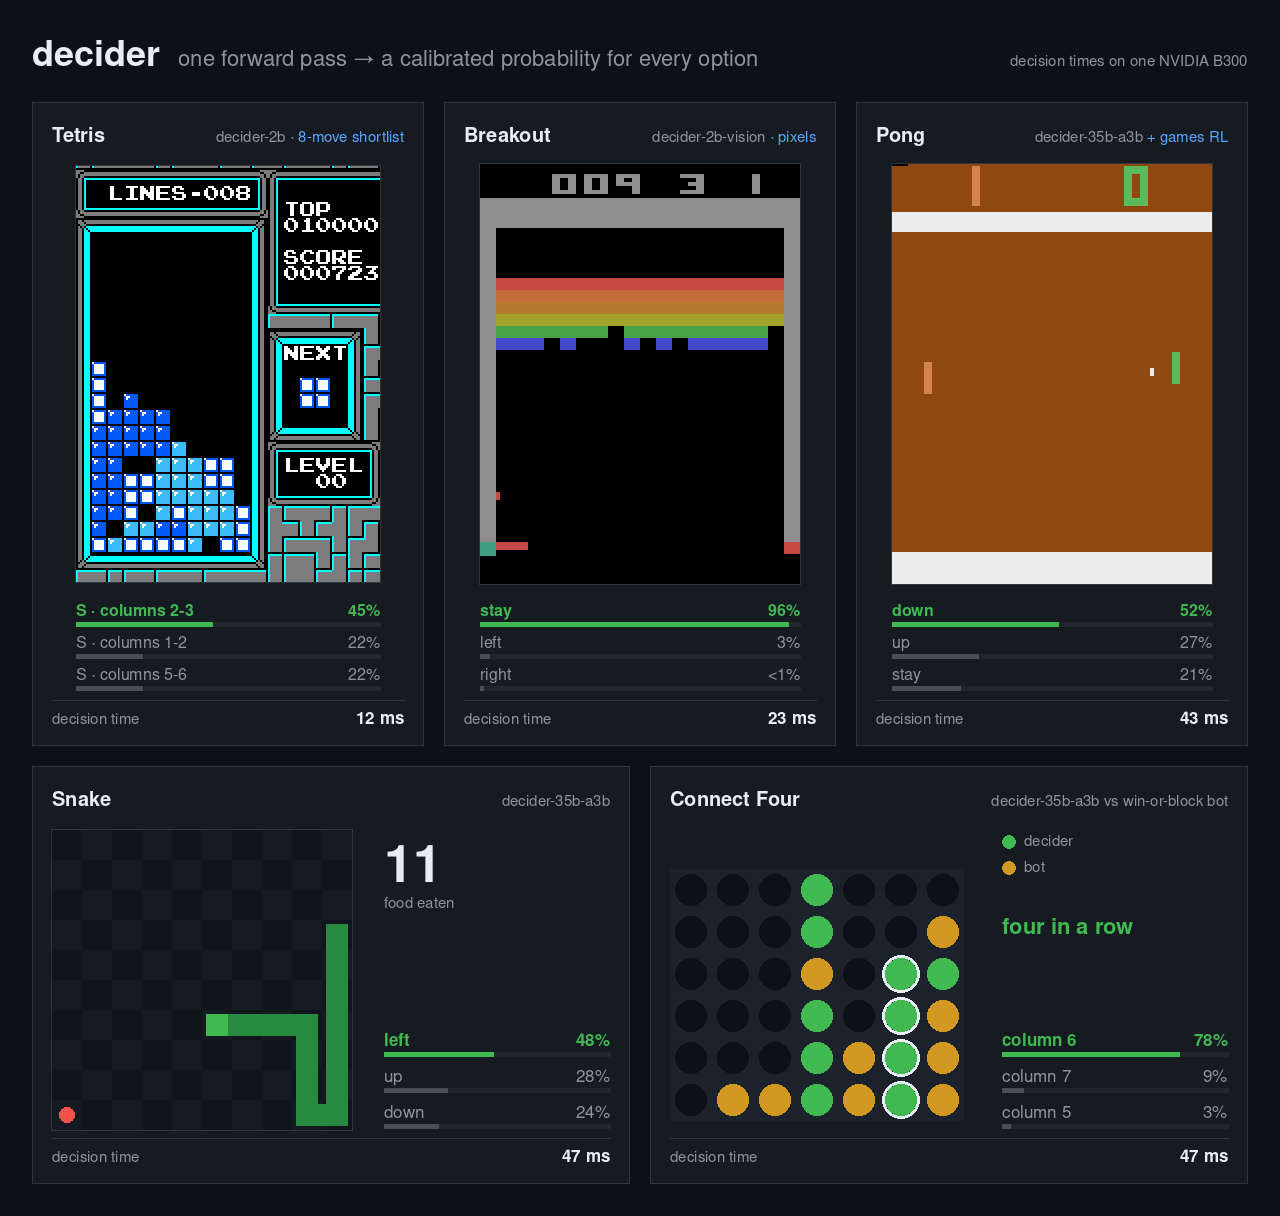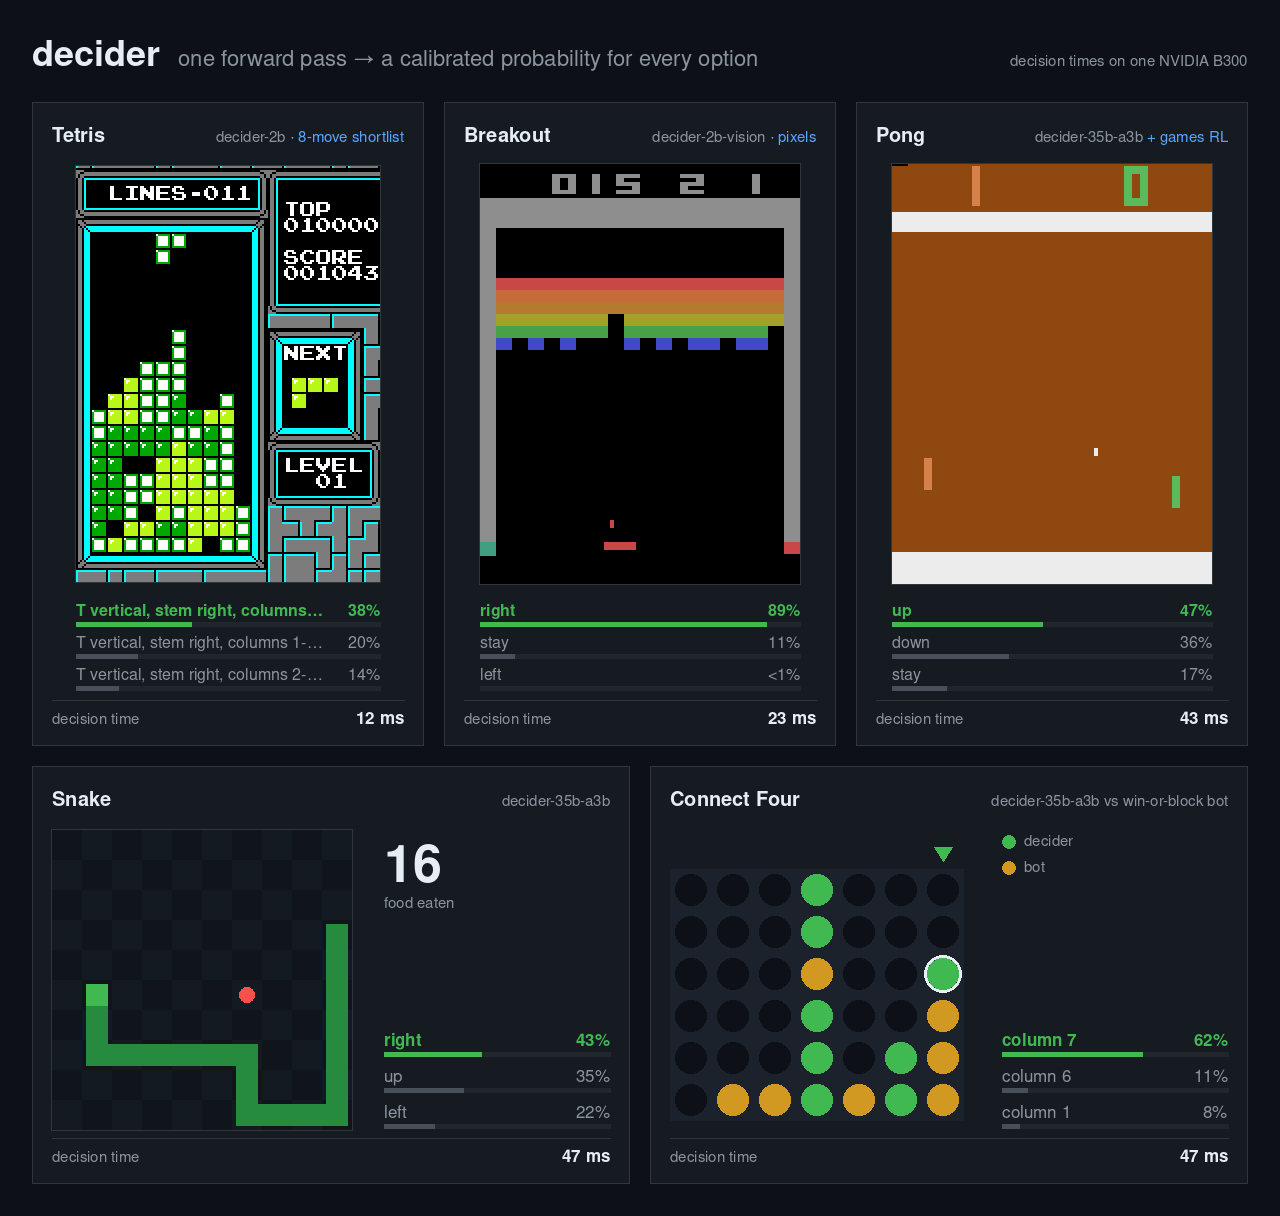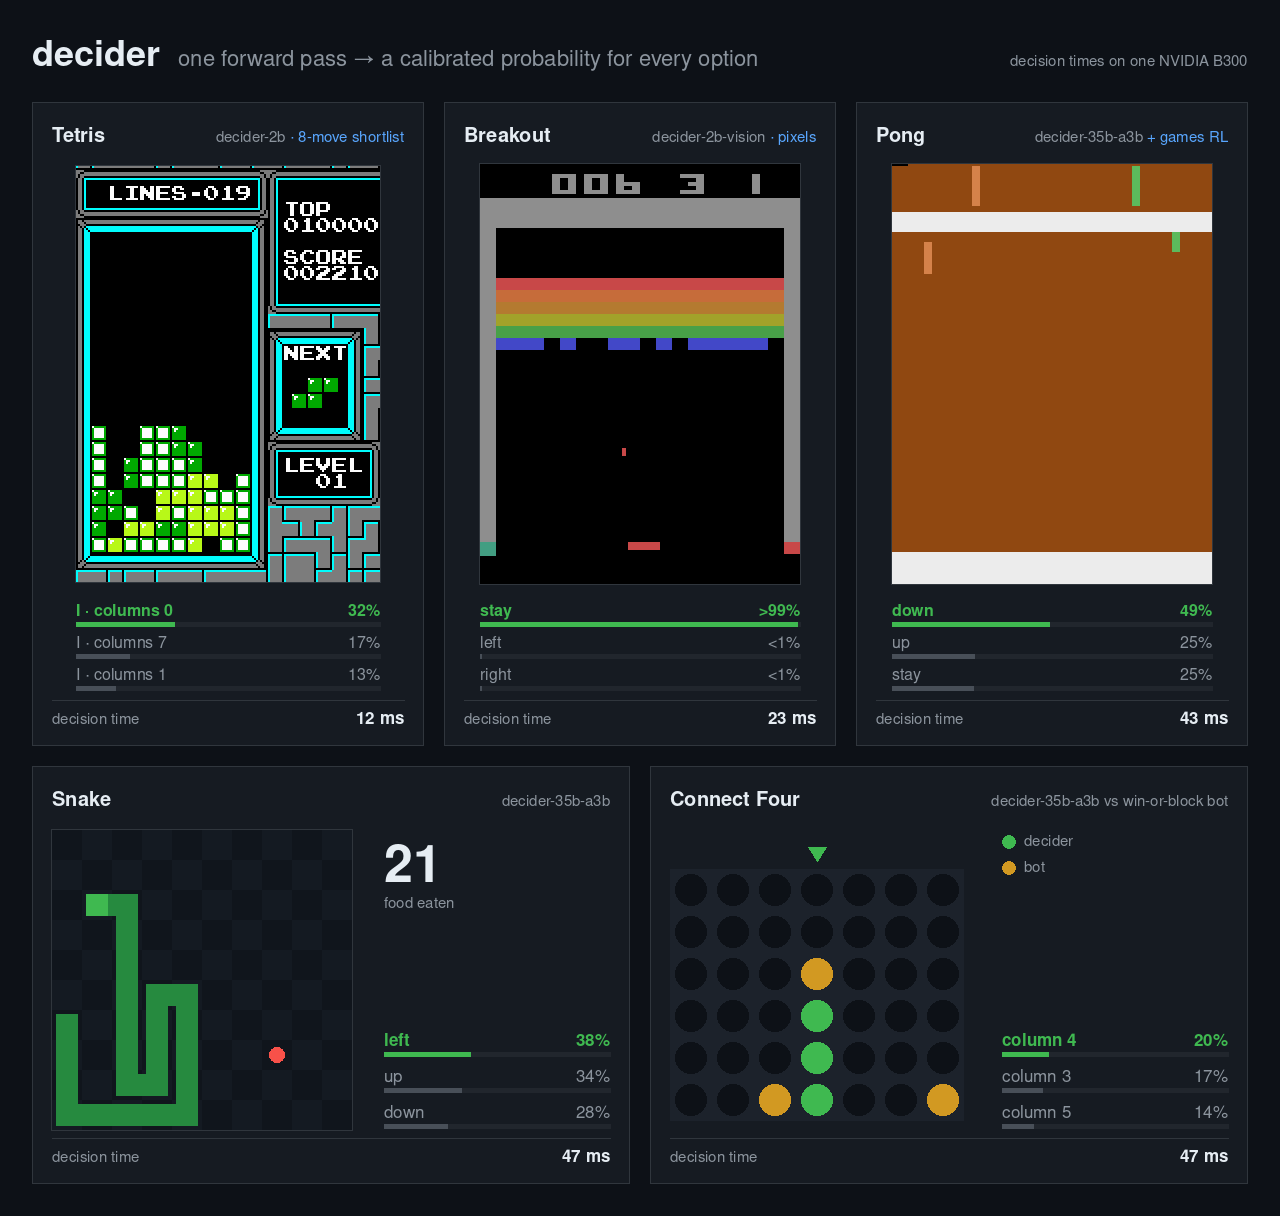
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 45

project-maya
1Kmw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 46
rizzo-flow
904Rizzo-AI-Academy/rizzo-flow · PythonRizzo Flow is an open-source, local-first implementation of TypeSafe's Jev 'System One' model: it takes unstructured state as input and returns typed, probabilistic decisions (a yes/no, a choice, a score, a number) without generating a single text token, running entirely on your own hardware via llama.cpp.
- 47
gufo
794gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 48
eleven
753Zfinix/eleven · TypeScriptEleven is a reverse-engineering desktop app for macOS, Windows and Linux built around AI agents: you open a binary, Android APK, GPU kernel, shader or model, and any agent that speaks the Agent Client Protocol (ACP) reads the code, renames functions, leaves notes and proposes patches while you watch and approve each change.
- 49
Offensive-Security-AI-Models
696JoasASantos/Offensive-Security-AI-ModelsA curated list of open-weight, uncensored language models fine-tuned for offensive-security tasks like penetration testing, red teaming, and security research. The README documents over 20 models sourced from HuggingFace model cards as of September 2026.
- 50
StartLux-Decision
695StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 51
SCM
488allenv0/SCM · TypeScriptSCM (Screen Memories) is a macOS desktop app that runs deep AI search locally over every photo and every video frame in a chosen folder, letting you search by meaning, on-screen text, or spoken dialogue, all without the cloud.
- 52
awesome-minimax-h3-integration
445MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 53
Qwen3.8-Flash-Next
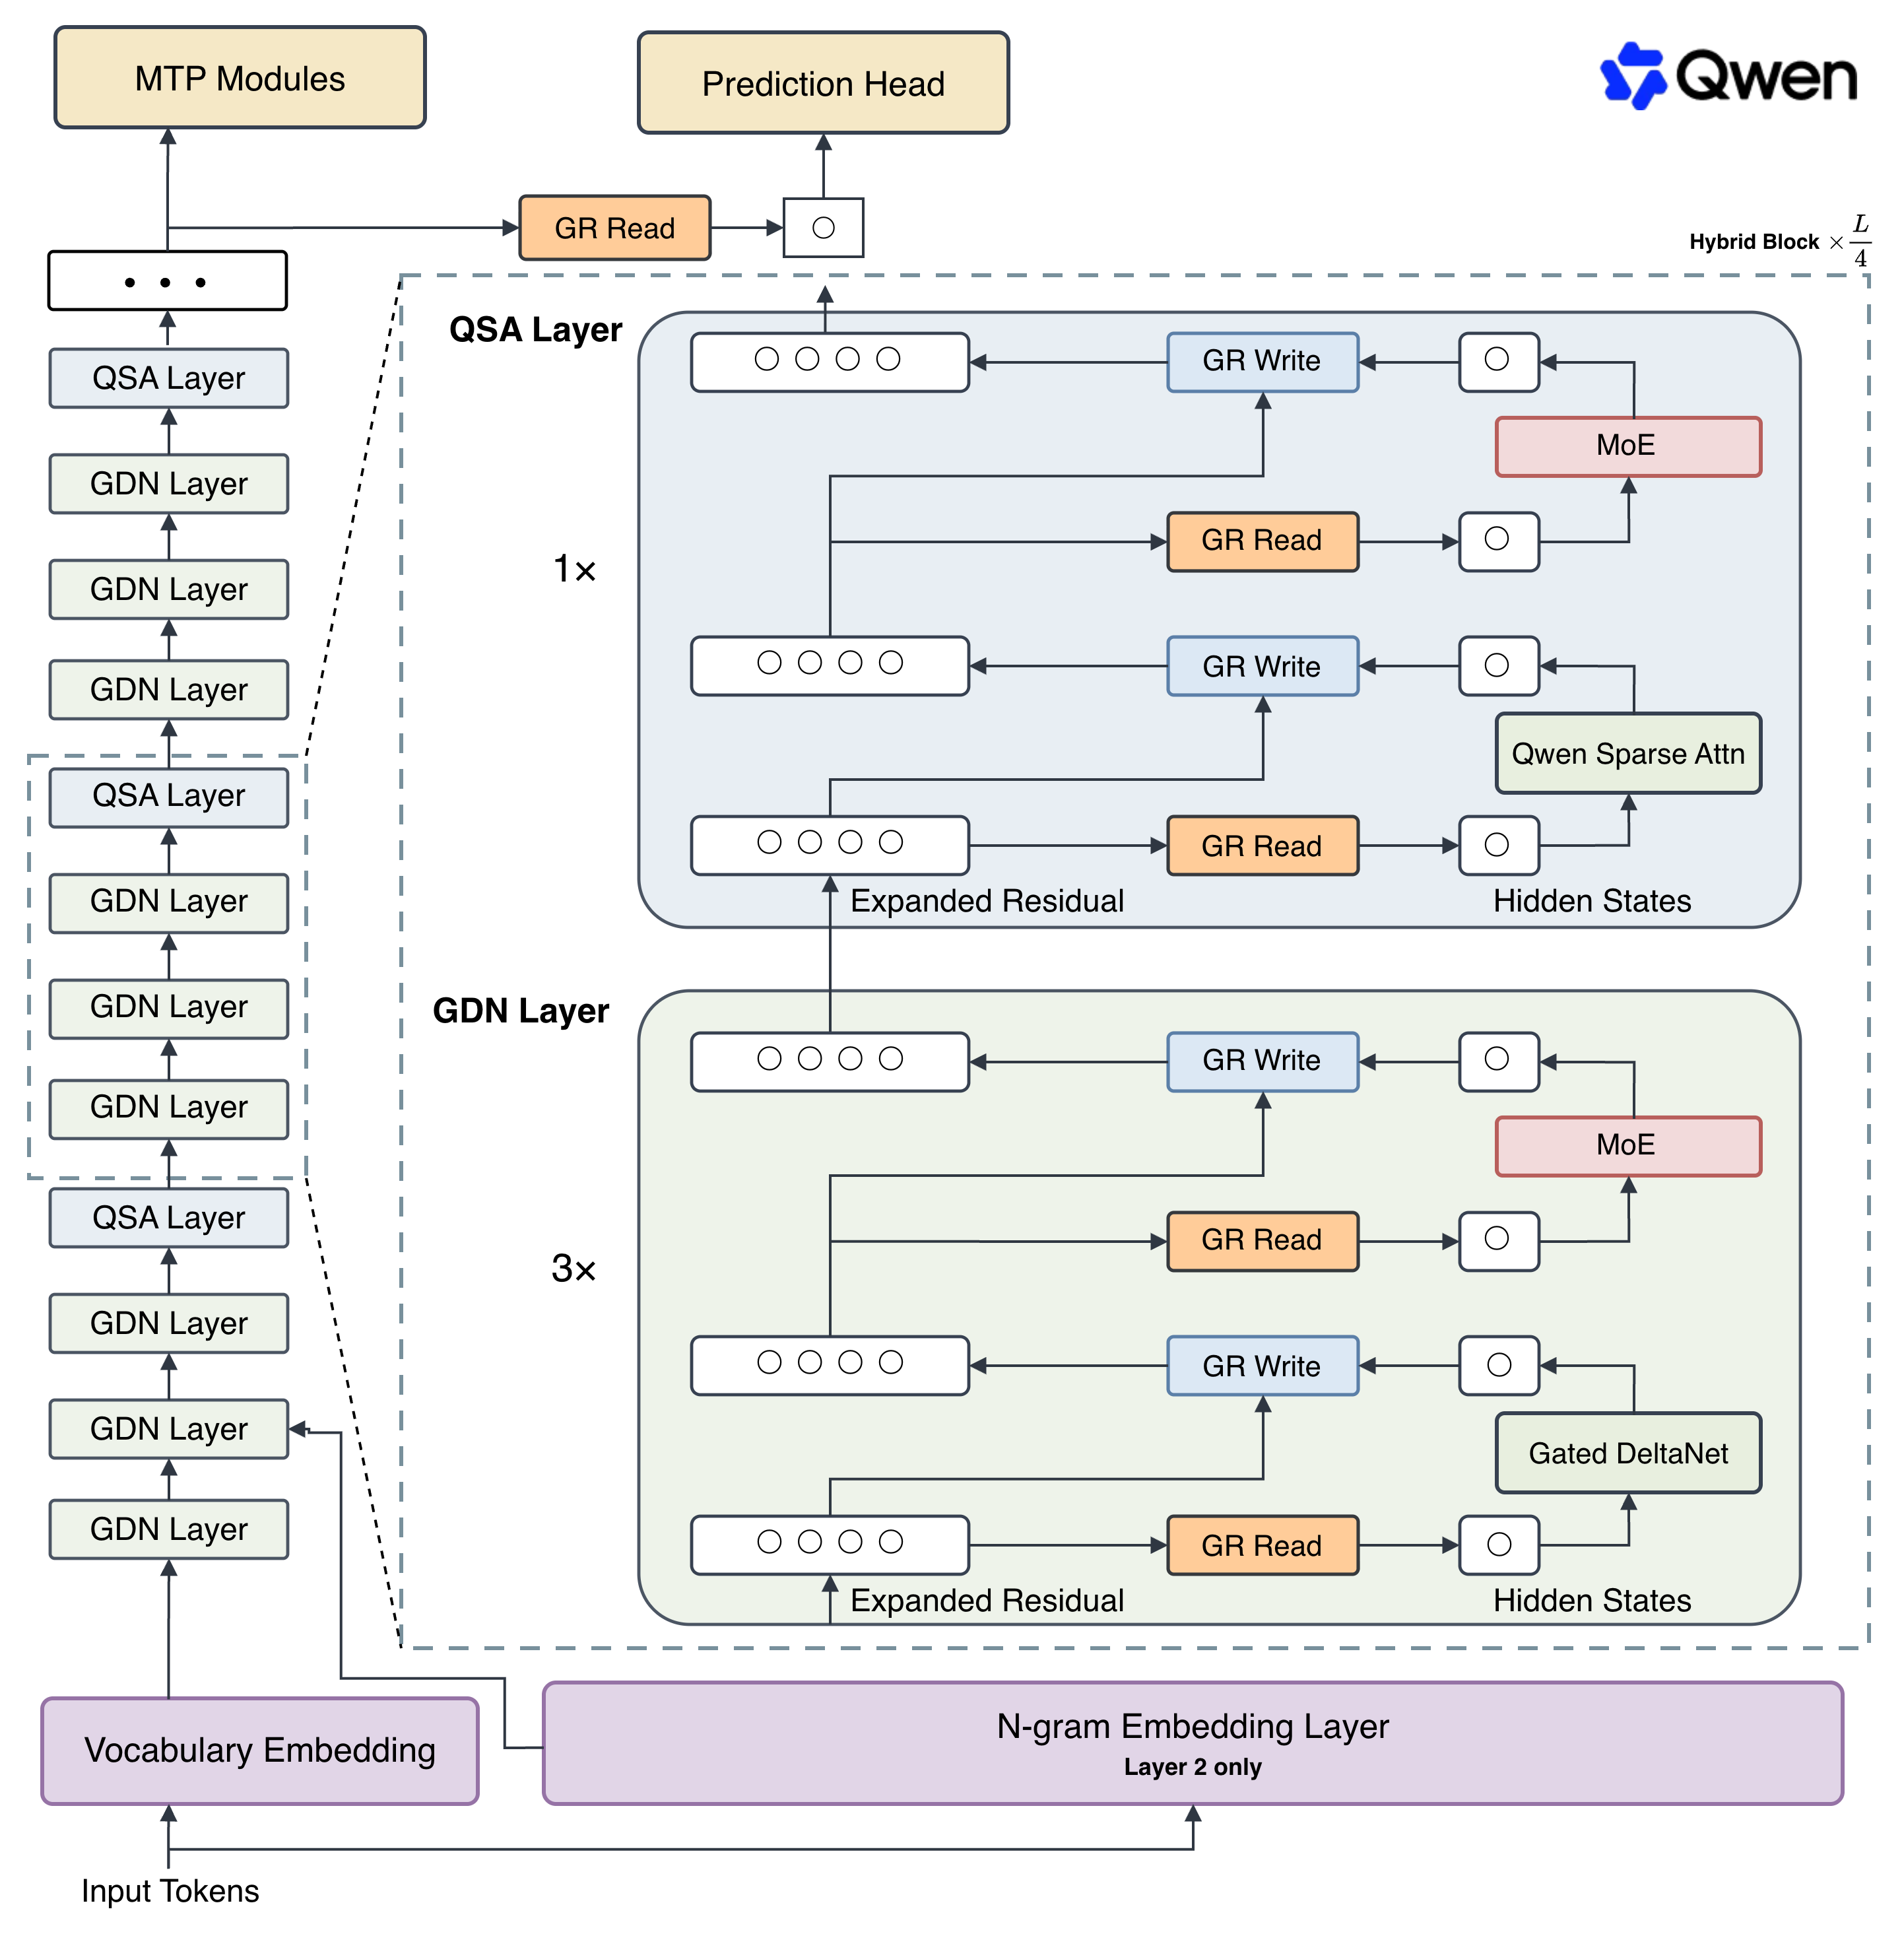
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 54
llm-inference-engineering
372amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 55
qwen38-uncensored
366Wassimyounes01/qwen38-uncensored · JavaScriptA Node.js install harness that sets up Qwen 3.8 27B as a fully uncensored local model, using weight-level abliterated GGUF weights plus a reinforcement SYSTEM prompt, runnable through Ollama or Apple's MLX.
- 56

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 57

MoE4All
304Headmaster218/MoE4All · RustMoE4All is a portable Windows app that runs large Mixture-of-Experts (MoE) LLMs beyond what fits in VRAM by streaming expert weights between GPU VRAM, system RAM and SSD, built on a Vulkan-first Rust inference engine so consumer AMD (and other Vulkan) GPUs can run huge models locally.
- 58

motion-bricks.cpp
304localai-org/motion-bricks.cpp · C++A C++23/GGML port of NVIDIA MotionBricks: a neural network that turns keyframe commands into skeletal character animations, for games and robots. It runs on CPU or Vulkan and exposes a stable C API.
- 59
skin-tokens.cpp
226localai-org/skin-tokens.cpp · C++skin-tokens.cpp is a C++/GGML port of VAST-AI's SkinTokens/TokenRig model that automatically generates a skeleton and skin weights for a static mesh, producing a rigged GLB file ready for animation.
- 60
Janus
135Vibra-Ingenn/Janus · GoJanus is a single Go binary that runs local .gguf language models on your machine (GPU or CPU) and exposes an OpenAI-compatible API, so you can use local models without Python, Docker, or Ollama.
- 61
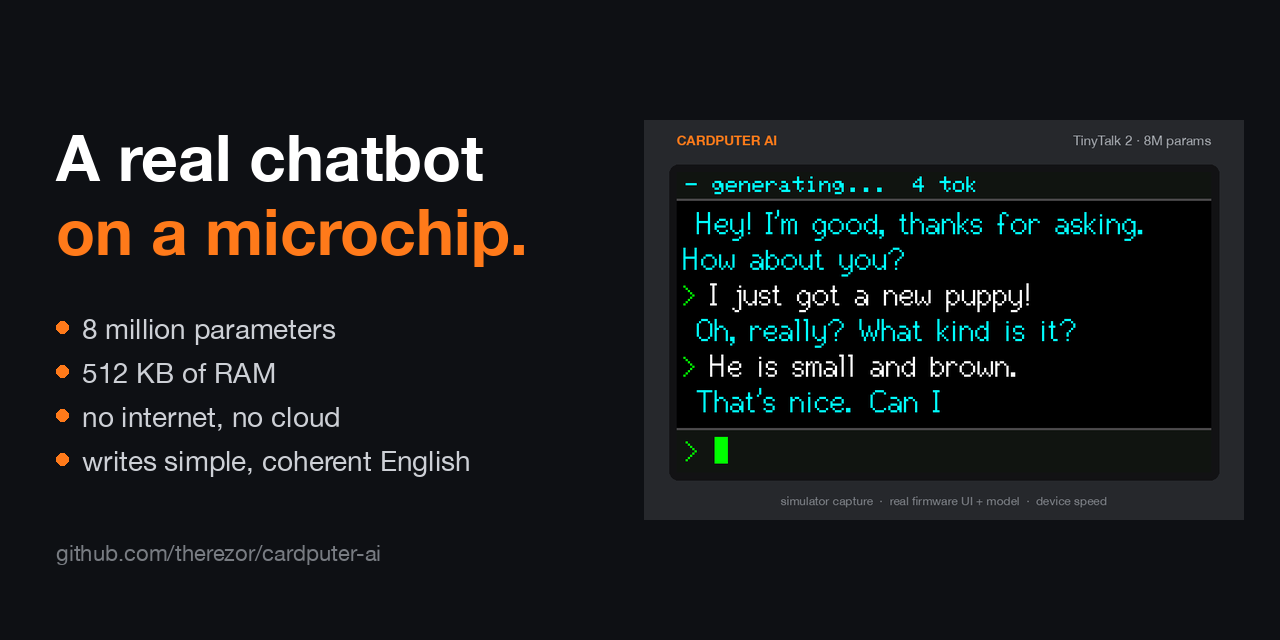
cardputer-ai
119therezor/cardputer-ai · C++Cardputer AI is a tiny offline chatbot that runs entirely on the M5Stack Cardputer / Cardputer ADV handheld, powered by an 8-million-parameter language model baked directly into the firmware.
Related topics
Often tagged together