Blazing fast Apple Silicon optimized inference engine built for Qwen & Nemotron. OpenAI + Anthropic API compatible. ai
kapitsa (nace-ai/kapitsa)
Searching Database…
The project's README from github.com/nace-ai/kapitsa. As one markdown file: README.md.

Kapitsa is an inference engine for Apple silicon that runs Qwen, Nemotron and Recursive's Flint models locally, built for coding agents. It starts opencode, Claude Code, Codex or pi on a local model, and serves OpenAI and Anthropic APIs.
Quickstart · CLI · Benchmarks · Models · How KFlash works · Docs
--model flint takes unsloth's 2-bit GGUF on 16-24 GB Macs: its routed experts run as stored, the rest requantized to 3-6 bits. 61 tok/s decode on an M1 Pro, in 11.6 GB (numbers).--disk-cache).kapitsa bench compare: see it on your own Mac. The same test against every engine installed here, in one command.Requirements: a Mac with Apple silicon (M1 or newer) and macOS 14 Sonoma or later.
brew install nace-ai/tap/kapitsa
# or: curl -fsSL https://raw.githubusercontent.com/nace-ai/kapitsa/main/install.sh | bash
kapitsa opencode --model 35b # also: claude, codex, pi
On a 16-24 GB Mac use --model 9b, or 4b for the quickest replies.
kapitsa serve                   # chat + OpenAI/Anthropic APIs at http://127.0.0.1:8000
kapitsa claude                  # Claude Code on Kapitsa
kapitsa doctor                  # this Mac's GPU and memory, and which models fit it
kapitsa cluster                 # the Macs on this network that run Kapitsa, and their models
kapitsa bench                   # benchmark this Mac, share it with the community
kapitsa bench compare           # the same test against the other engines installed here
kapitsa pull 27b                # download a model without starting it
kapitsa list                    # downloaded models and their size
kapitsa rm 27b                  # delete a downloaded model
kapitsa import model.gguf       # use a Qwen or Flint GGUF from LM Studio, Ollama or llama.cpp
kapitsa update                  # update now (it also updates itself)
--model picks the model and its precision (35b:6bit). kapitsa <command> --help has the options.
A Mac that cannot hold a model whole uses another Mac on the network that runs it, and two Macs that would each stream
Flash-Next pair to hold it in memory between them (Several Macs); --private keeps a
server to its own Mac. Usage guide
Kapitsa has the fastest decode in 32 of the 36 model and Mac pairs measured against nine engines (how each number was measured).

Each cell reads prefill / decode in tokens per second. Prefill is a 4K-token prompt, decode a 512-token answer at T 0.6 (Flint at its card's T 1.0). × cannot run that model · — not measured. How these were measured, run dates and flags: docs/benchmarks.md.
The poster's numbers, and the models it leaves out, are in each Mac's table under Models. Every recorded run, with its Mac, model, prefill and decode speed, is in the benchmark table. Measure your Mac: kapitsa bench --submit adds it to the community results. Another engine faster on your Mac? kapitsa bench compare ranks every engine you have installed, and --report writes a Markdown report.
The catalog models measured on each Mac, against the engines that run them: one collapsed section per Mac, with a table for each model family. Decode is a 512-token coding answer at T 0.6 (Flint at its card's T 1.0), prefill a 4K-token prompt. Under each model's name are the weights Kapitsa ran; the other engines' weights and how each number was measured are in docs/benchmarks.md. Flint's speed from 1K to 128K tokens of prompt on the M5 Pro, against llama.cpp: bench/results/2026-10-24-flint-m5pro-context.
Each cell: prefill / decode, tokens/s (a lone number is decode: no prefill run) · 🟩 fastest decode · ≈ a decode tie with Kapitsa · small type: the decoding method (none: no speculative decoding) · × can't run on that Mac · — not measured
| Model | Kapitsa | mlx‑serve 26.10.2 |
oMLX 0.7.1rc1 |
Splash 1.4.0 |
Ollama 0.40.5 / 0.40.6 |
MTPLX 2.12.2 |
MLX mlx-lm 0.32.2, mlx-vlm 0.7.8 |
llama.cpp b11669 |
LM Studio MLX runtime 1.13.1, llama.cpp runtime 2.60.0 |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 459 / 140 KFlash |
690 / 130 DFlash2 |
761 / 93 DFlash2 |
898 / 116 DFlash2 |
739 / 68 | 733 / 69 MTP |
784 / 54 MTP |
516 / 51 MTP |
217 / 32 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 4702 / 325 KFlash |
3818 / 264 MTP |
2968 / 232 DFlash2 |
6640 / 290 DFlash2 |
3690 / 166 | 4328 / 123 MTP |
4271 / 132 DFlash2 |
2881 / 171 MTP |
1873 / 127 |
Qwen3.8-Flash-Next 180B-A7B · flash-nextMoE, 7B active · 4-bit, 105.9 GB |
1165 / 106 KFlash |
🟩 1720 / 108 | 1260 / 107 MTP |
× | 60 | 1263 / 88 MTP |
1030 / 77 MTP |
842 / 96 | × |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 119 KFlash |
× | × | × | × | × | 76 | 9 | × |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 267 KFlash |
190 | 190 | × | 153 | 131 | 139 | 159 | 110 |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 1016 / 153 KFlash |
× | 913 / 69 | × | × | × | 941 / 69 | × | × |
Nemotron 3.5 Super-VL 120B-A12B · superhybrid MoE, 12B active · NVFP4, 76.4 GB |
🟩 94 KFlash |
× | 52 | × | 64 | 44 | 46 | 66 | 61 |
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve 26.10.2 |
oMLX 0.7.1rc1 |
Splash 1.4.0 |
Ollama 0.40.5 / 0.40.6 |
MTPLX 2.12.2 |
MLX mlx-lm 0.32.2, mlx-vlm 0.7.8 |
llama.cpp b11669 |
LM Studio MLX runtime 1.13.1, llama.cpp runtime 2.60.0 |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
606 / 77 KFlash |
🟩 464 / 78 DFlash2 |
446 / 51 DFlash2 |
674 / 72 DFlash2 |
470 / 40 MTP |
462 / 41 MTP |
421 / 32 MTP |
322 / 30 MTP |
118 / 17 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 2802 / 201 KFlash |
2494 / 156 MTP |
1619 / 144 DFlash2 |
3514 / 181 DFlash2 |
1518 / 102 MTP |
2569 / 89 MTP |
2474 / 98 DFlash2 |
1755 / 107 MTP |
997 / 96 |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 70 KFlash |
× | × | × | × | × | 53 | 13 | × |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 3141 / 159 KFlash |
1728 / 115 MTP |
1938 / 124 MTP |
× | 2369 / 92 | 1743 / 101 | 1881 / 94 | 1915 / 101 MTP |
1479 / 72 |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 79 KFlash |
× | 39 | × | × | × | 41 | × | × |
Recursive Flint
| Model | Kapitsa | llama.cpp b11804 |
rec 0.1.0 |
|---|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 2691 / 149 KFlash |
2072 / 92 | 2138 / 145 |
Qwen3.8-Flash-Next 180B-A7B does not fit in 48 GB, so both engines stream its experts from the SSD. With Q2_0 weights on both and Kapitsa's expert store pinned at 24 GB (the auto size here is about 29.9 GB, but four runs at that size were stopped at memory pressure), Kapitsa decodes faster than llama.cpp up to 4K tokens of context and slower at 16K and 32K, and its prefill is behind on short prompts, level at 4K and 16K and 2.7% ahead at 32K: not the fastest everywhere (numbers and caveats).
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve 26.10.2 |
oMLX 0.7.1rc1 |
Splash 1.4.0 |
Ollama 0.40.5 / 0.40.6 |
MTPLX 2.12.2 |
MLX mlx-lm 0.32.2, mlx-vlm 0.7.8 |
llama.cpp b11669 |
LM Studio MLX runtime 1.13.1, llama.cpp runtime 2.60.0 |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 1930 / 201 KFlash |
874 / 137 MTP |
803 / 102 MTP |
× | 758 / 109 MTP |
780 / 104 MTP |
843 / 88 MTP |
650 / 70 MTP |
801 / 81 |
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 396 / 63 KFlash |
129 / 54 DFlash2 |
136 / 45 DFlash2 |
53 DFlash2 |
124 / 32 MTP |
126 / 36 MTP |
131 / 28 MTP |
84 / 18 MTP |
127 / 15 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 1168 / 161 KFlash |
986 / 124 MTP |
1035 / 127 DFlash2 |
135 DFlash2 |
892 / 89 MTP |
918 / 80 MTP |
985 / 86 DFlash2 |
663 / 69 MTP |
957 / 86 |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 64 KFlash |
× | × | × | × | × | 48 | 6 | × |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 945 / 112 KFlash |
— | — | × | — | — | 721 / 65 DSpark |
— | — |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 519 / 69 KFlash |
— | 298 / 35 | × | — | — | 300 / 32 | × | — |
Recursive Flint
| Model | Kapitsa | llama.cpp b11804 |
rec 0.1.0 |
|---|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 968 / 128 KFlash |
977 / 80 | 796 / 127 |
Qwen and Nemotron
| Model | Kapitsa | Ollama 0.40.8 |
MTPLX 2.12.2 |
MLX mlx-lm 0.32.2, mlx-vlm 0.7.8 |
llama.cpp b11669 |
|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 703 / 120 KFlash |
600 / 67 MTP |
612 / 64 MTP |
642 / 56 MTP |
512 / 50 MTP · b11804 |
Qwen3.5-9B · 9bdense · 4-bit, 9.0 GB |
🟩 381 / 77 KFlash |
— | — | 353 / 27 | 307 / 23 b11804 |
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 110 / 40 KFlash |
99 / 23 MTP |
99 / 22 MTP |
102 / 18 MTP |
86 / 16 MTP · b11804 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 855 / 106 KFlash |
681 / 58 MTP |
671 / 53 MTP |
695 / 53 DFlash2 |
578 / 53 MTP · b11804 |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 450 / 36 KFlash |
× | × | 344 / 30 | — |
Nemotron 3 Nano 4B · nano-4bhybrid Mamba-2 · FP8, 5.3 GB |
765 / 34 KFlash |
— | — | — | 🟩 413 / 35 Q4_K_M, b11804 |
Nemotron Nano 9B v2 · nano-9bhybrid Mamba-2 · NVFP4, 7.9 GB |
330 / 21 KFlash |
— | — | 🟩 25 4-bit |
— |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 788 / 75 KFlash |
— | — | 514 / 39 DSpark |
— |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 256 / 50 KFlash |
— | — | — | — |
Recursive Flint
| Model | Kapitsa | llama.cpp b11804 |
|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 801 / 74 KFlash |
772 / 51 |
macOS 14.1, on AC power: Kapitsa's macOS 14 kernels (macOS 15 and later run fused ones). mlx-serve, oMLX and Splash need a newer macOS (×); LM Studio was not installed; rec 0.1.0 refuses this Mac: it requires 48 GiB. Each cell but Flint's is one run of the M4 Pro's protocol (Flint's is the mean of two runs, #341), the other engines in the M4 Pro's setup (not re-tuned here). Nano 4B and 9B v2: Kapitsa runs NVIDIA's published checkpoints, which keep some layers in BF16/FP8, so it reads more per token than the 4-bit files: the 4B's FP8 is ~1 byte per weight against Q4_K_M's ~0.6, the 9B's NVFP4 ~6.11 GB per token against 4.67 GB for mlx-lm's 4-bit. Nano 9B v2 on mlx-lm: no prefill shown, because its template ignores enable_thinking and the timed first token is a thinking token.
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve 26.10.2 |
oMLX 0.7.1rc1 |
Ollama 0.40.5 / 0.40.6 |
MTPLX 2.12.2 |
MLX mlx-lm 0.32.2, mlx-vlm 0.7.8 |
llama.cpp b11669 |
LM Studio MLX runtime 1.13.1, llama.cpp runtime 2.60.0 |
|---|---|---|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 401 / 97 KFlash |
286 / 62 MTP |
281 / 55 MTP |
298 / 55 MTP |
305 / 42 MTP |
308 / 46 | 315 / 38 MTP |
308 / 47 |
Qwen3.5-9B · 9bdense · 4-bit, 9.0 GB |
🟩 217 / 57 KFlash |
159 / 37 MTP |
— | — | — | 170 / 30 | — | — |
Qwen3.6-35B-A3B · 35b:16gbMoE, 3B active · 2-bit experts (unsloth's GGUF), 10.8 GB |
🟩 462 / 52 KFlash |
× | × | — | × | × | 38 | — |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 39 KFlash |
× | × | × | × | 30 | 4 | × |
Nemotron 3 Nano 4B · nano-4bhybrid Mamba-2 · FP8, 5.3 GB |
🟩 37 KFlash |
— | — | — | — | 21 BF16 |
28 Q4_K_M |
— |
Nemotron Nano 9B v2 · nano-9bhybrid Mamba-2 · NVFP4, 7.9 GB |
🟩 25 KFlash |
— | — | — | — | 18 | 14 Q4_K_M |
— |
Recursive Flint
| Model | Kapitsa | llama.cpp d772569 |
|---|---|---|
Recursive Flint 40B-A2.5B · flint:16gbMoE, 2.5B active · 2-bit experts (unsloth's GGUF), 11.9 GB |
🟩 414 / 61 KFlash |
43 |
Other precisions: --model 35b:6bit is five times closer to bf16 than the 4-bit default (KL). All but Lightning, Dory, the two Nemotron Nanos, Flint and the 35B's 16gb read images. Memory: 16 GB for the 4B and 9B models, 32 GB
for the 27B, 35B, Lightning, Bolt and Flint, 96 GB for Super-VL, 128 GB for Flash-Next. On a 16 or 24 GB Mac, 35b and flint take their 16gb variants: unsloth's 2-bit GGUFs, downloaded and imported in one step (how). Every model's variants and draft models

Kapitsa decodes with KFlash. A draft model such as DFlash2 guesses the next seven tokens, with a few candidates for each one. Engines that run it as published (Splash, oMLX, mlx-serve) check one chain of guesses and stop at the first wrong one. KFlash checks a best-first tree of the drafter's candidates in the same pass, so where the drafter hesitates, its runner-ups are checked too and more tokens survive each pass. The tree's size comes from what a verify row costs on your Mac, measured there, and it changes no output: the big model checks every token. It runs on the published drafters as they are: z-lab's DFlash, DFlash2, and NVIDIA's DSpark and LiLiCorr. How KFlash works
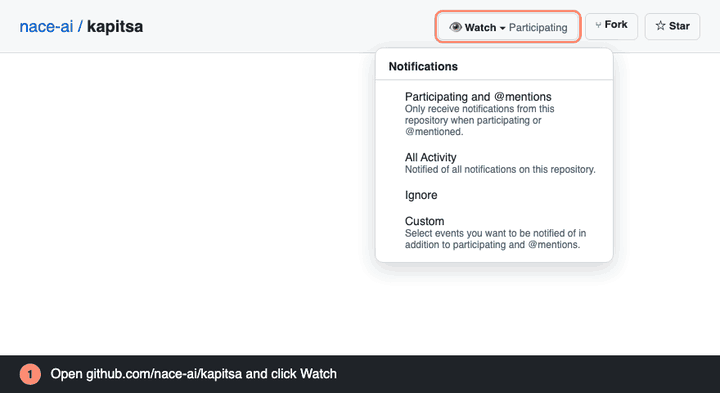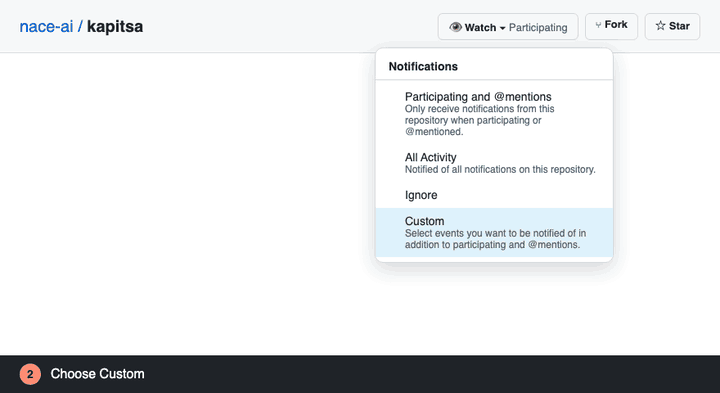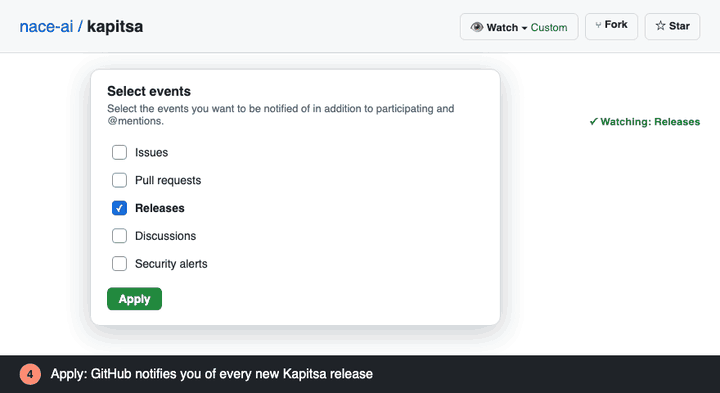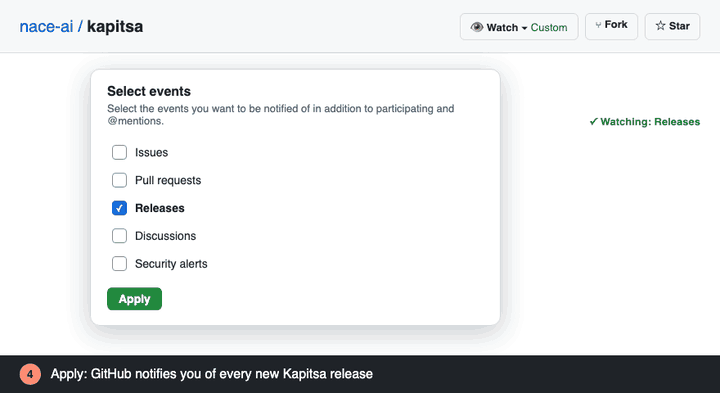
Watch → Custom → Releases on nace-ai/kapitsa puts every new version in your notifications. A drawn illustration of the steps, not a screen recording; the page source is in tools/readme_images.
How KFlash works · Architecture · Contributing · Press kit · Apache 2.0, © 2026 Nace AI · Third-party notices
Blazing fast Apple Silicon optimized inference engine built for Qwen & Nemotron. OpenAI + Anthropic API compatible. ai