Topics / #evaluation-framework
Evaluation-framework projects on GitHub
Frameworks for benchmarking model outputs, prompts, and pipelines.
As of , the most-starred Evaluation-framework projects on GitHub are promptfoo (26.1K stars), deepeval (18.9K stars) and lm-evaluation-harness (14.2K stars). GitHub.Locker tracks 9 Evaluation-framework repositories with 65.1K stars combined. The fastest-growing on October 16 was promptfoo, with +45 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +45
promptfoo
promptfoo/promptfoo · ★ 26.1Kpromptfoo is a CLI and library for evaluating and red-teaming LLM apps — you test prompts, agents, and RAGs and run security scans on them, instead of relying on trial-and-error.
 +21
deepeval
confident-ai/deepeval · ★ 18.9KDeepEval is an open-source LLM evaluation framework: a simple-to-use way to evaluate large-language model systems with research-backed metrics like G-Eval, answer relevancy, and hallucination checks.
 +11
livenerf
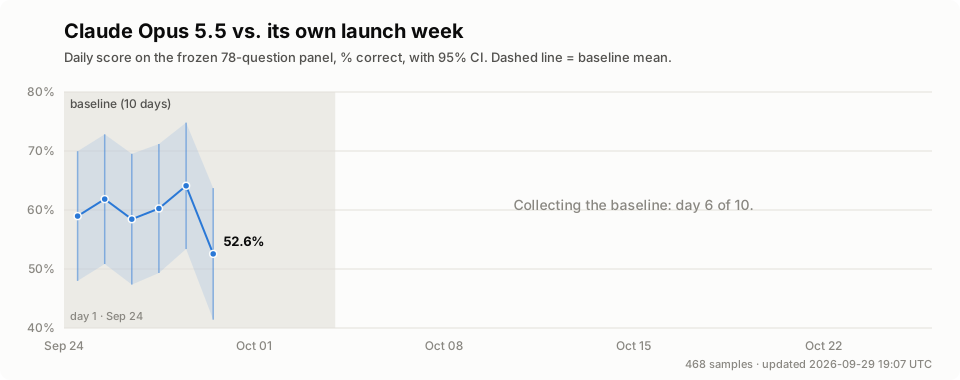
ninjahawk/livenerf · ★ 1.5Klivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
 +6
lm-evaluation-harness
EleutherAI/lm-evaluation-harness · ★ 14.2KIt is a unified framework for few-shot evaluation of language models across a huge number of standard academic benchmarks.
The all-time top
9 projects · by stars
- 26.1K#1 · promptfoo/promptfoo
promptfoo
promptfoo is a CLI and library for evaluating and red-teaming LLM apps — you test prompts, agents, and RAGs and run security scans on them, instead of relying on trial-and-error.
- 18.9K#2 · confident-ai/deepeval
deepeval
DeepEval is an open-source LLM evaluation framework: a simple-to-use way to evaluate large-language model systems with research-backed metrics like G-Eval, answer relevancy, and hallucination checks.
- 14.2K#3 · EleutherAI/lm-evaluation-harness
lm-evaluation-harness
It is a unified framework for few-shot evaluation of language models across a huge number of standard academic benchmarks.
- 4
ai-agents-the-definitive-guide
2.8KNicolepcx/ai-agents-the-definitive-guide · Jupyter NotebookIt is the companion code repository for the book 'AI Agents - The Definitive Guide': a set of runnable Jupyter notebooks that walk through every chapter, from basic agent patterns to production deployment and threat modeling.
- 5
livenerf
1.5Kninjahawk/livenerf · Pythonlivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
- 6
ParseBench
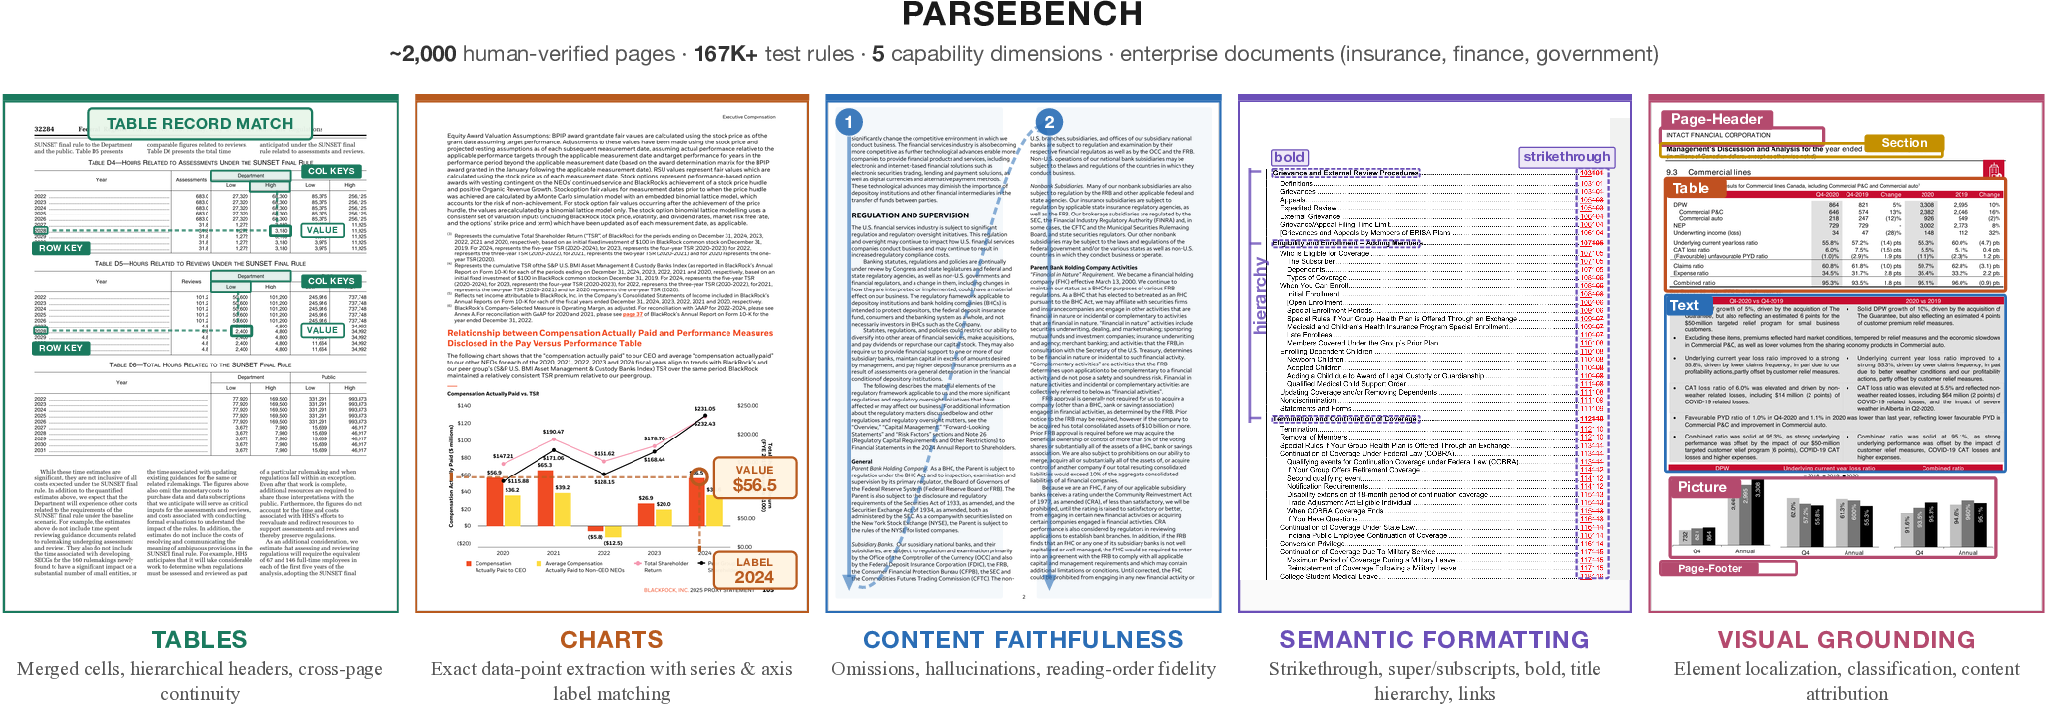
602run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 7
JIT
556bingreeky/JIT · PythonJIT-Agent is a compact meta-agent that writes a task-specific agent harness on the fly instead of relying on one precompiled general-purpose scaffold, wrapping any off-the-shelf agentic LLM in what the authors call 'Model-as-a-Harness'.
- 8
eval
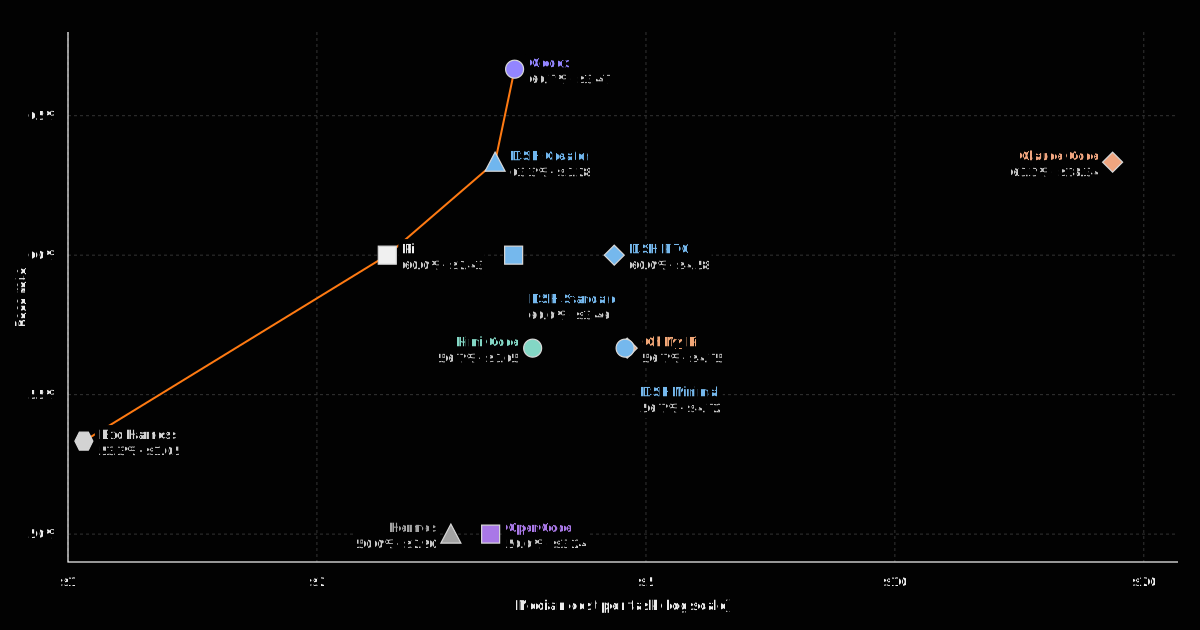
310frontier-harness-eval/eval · JavaScriptFrontierHarness Eval is a public benchmark that ran the same Kimi K3 model through nine coding-agent harnesses (12 configurations) on the same 30 software-engineering tasks, to see how pass rate, cost, cache behavior and speed change when only the harness changes.
- 9

jevals
105openlayer-ai/jevals · Pythonjevals is a Python library for evaluating and guardrailing AI agent traces using 'Jev' decision models instead of a text-generating LLM judge. It bundles every check for a trace into one request that costs a fraction of a cent and returns in a few hundred milliseconds, so you can eval every trace and even run checks inside the agent loop.
Related topics
Often tagged together