Topics / #blackwell
Blackwell projects on GitHub
Inference engines optimized for NVIDIA Blackwell GPUs.
As of , the most-starred Blackwell projects on GitHub are vllm (94K stars), sglang (37.2K stars) and TensorRT-LLM (14.8K stars). GitHub.Locker tracks 6 Blackwell repositories with 157.8K stars combined. The fastest-growing on October 17 was vllm, with +69 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +69
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +30
sglang
sgl-project/sglang · ★ 37.2KSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
 +22
tokenspeed
lightseekorg/tokenspeed · ★ 2.7KTokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
 +9
TensorRT-LLM
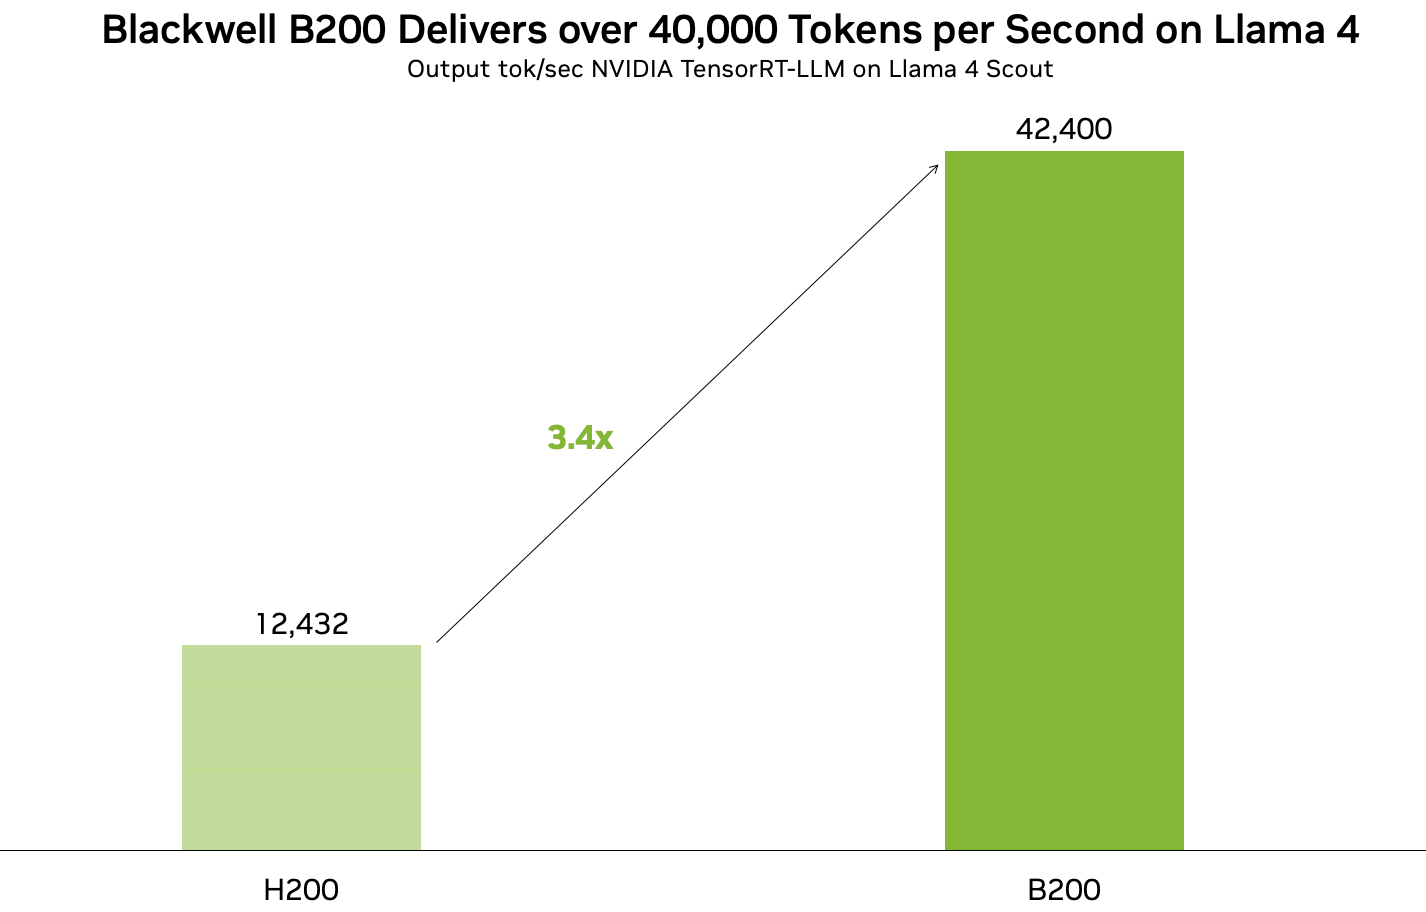
NVIDIA/TensorRT-LLM · ★ 14.8KTensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
The all-time top
6 projects · by stars
- 94K#1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 37.2K#2 · sgl-project/sglang
sglang
SGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 14.8K#3 · NVIDIA/TensorRT-LLM
TensorRT-LLM
TensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
- 4

tilelang
8.6Ktile-ai/tilelang · PythonTileLang (tile-lang) is a domain-specific language for writing high-performance GPU/CPU/NPU kernels like GEMM, Dequant GEMM, FlashAttention, and LinearAttention, using Pythonic syntax backed by a TVM-based compiler.
- 5
tokenspeed
2.7Klightseekorg/tokenspeed · PythonTokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
- 6
awesome-minimax-h3-integration
445MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
Related topics
Often tagged together