Topics / #parallel-computing
Parallel-computing projects on GitHub
Parallel programming: executing computations concurrently across cores or processors
As of , the most-starred Parallel-computing projects on GitHub are ray (44.1K stars), taichi (28.4K stars) and bend (23.7K stars). GitHub.Locker tracks 15 Parallel-computing repositories with 201.6K stars combined. The fastest-growing on October 16 was bend, with +44 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +44
bend
bendlang/bend · ★ 23.7KA high-level, massively parallel programming language. It feels like Python or Haskell (closures, unrestricted recursion, continuations) but scales across many cores and GPUs with no thread or lock code to write.
 +12
ray
ray-project/ray · ★ 44.1KRay is an open-source framework for scaling AI and Python applications: a core distributed runtime plus a set of AI libraries that simplify ML compute.
 +6
tiny-gpu
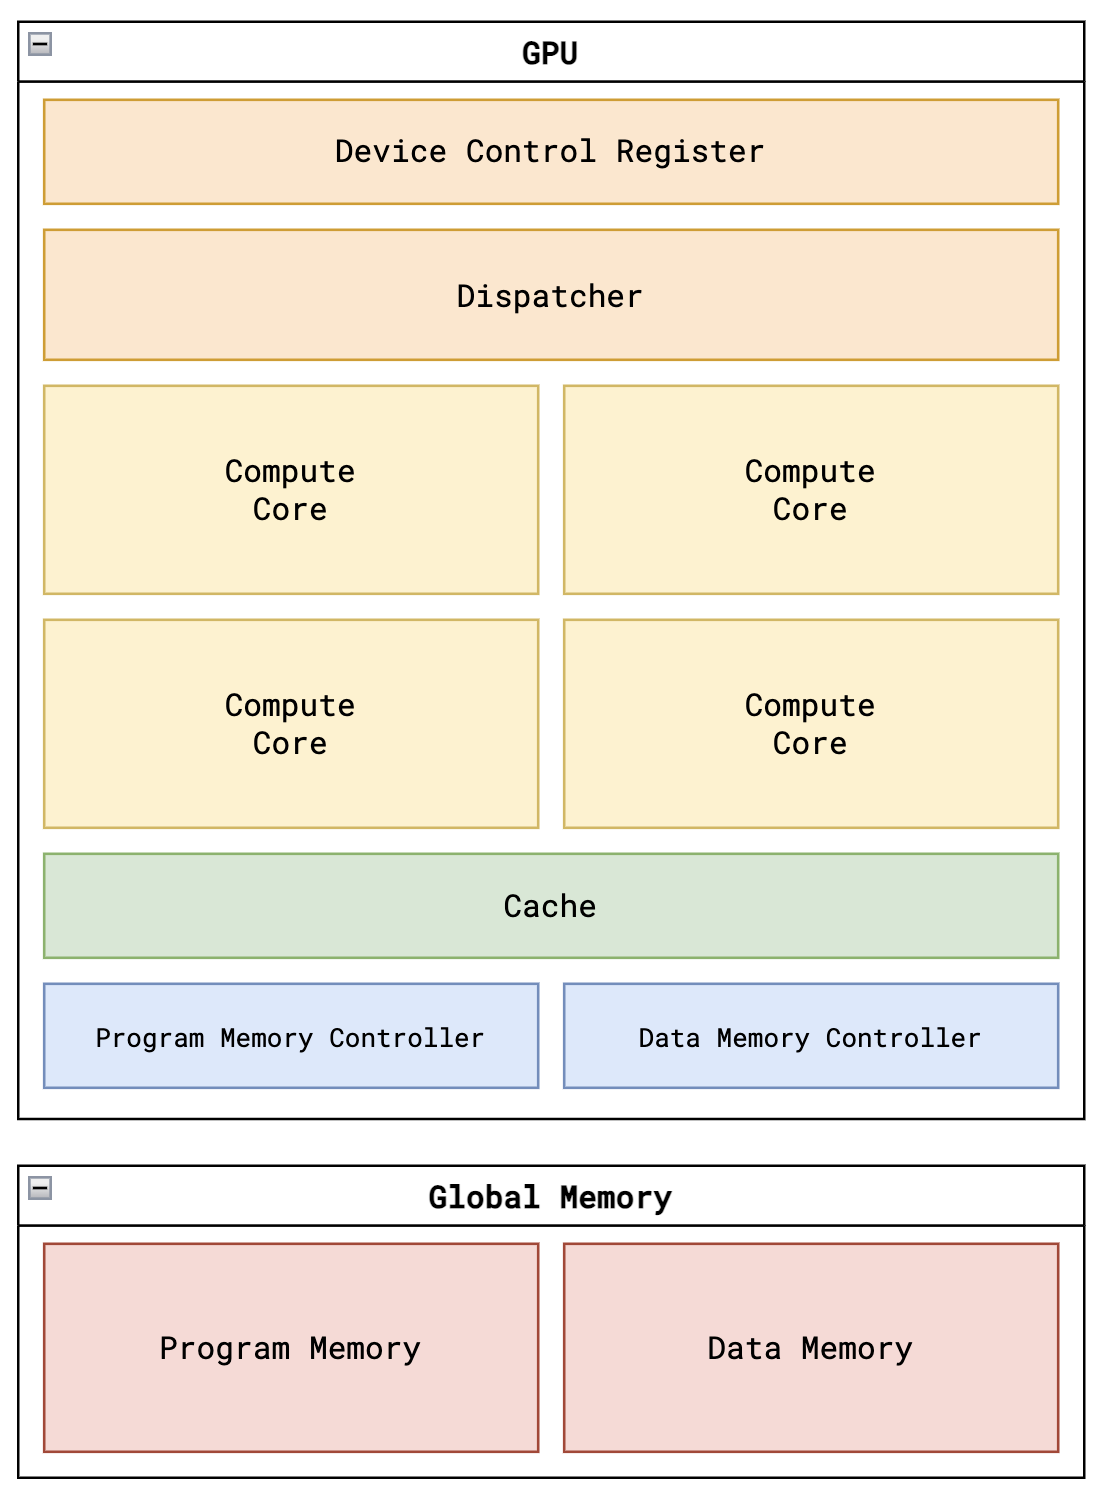
adam-maj/tiny-gpu · ★ 13.1Ktiny-gpu is a minimal GPU design written in Verilog (SystemVerilog) built purely to teach how GPU architecture works from the ground up, covering core concepts like SIMD parallelization, memory bandwidth management, and instruction execution.
 +5
optuna
optuna/optuna · ★ 14.9KOptuna is an open-source framework for automatic hyperparameter optimization, built primarily for machine learning: you wrap your training code in an objective function and it searches for the best settings automatically.
The all-time top
15 projects · by stars
- 44.1K#1 · ray-project/ray
ray
Ray is an open-source framework for scaling AI and Python applications: a core distributed runtime plus a set of AI libraries that simplify ML compute.
- 28.4K
 #2 · taichi-dev/taichi
taichi
Taichi Lang is an open-source language for high-performance GPU programming embedded in Python: you write Python-like code and its JIT compiler turns it into efficient parallel GPU or CPU machine code.
- 23.7K#3 · bendlang/bend
bend
A high-level, massively parallel programming language. It feels like Python or Haskell (closures, unrestricted recursion, continuations) but scales across many cores and GPUs with no thread or lock code to write.
- 4
gpu.js
15.5Kgpujs/gpu.js · JavaScriptGPU.js is a JavaScript library that takes the functions you write and runs them on your GPU as shaders instead of on the CPU — a big speedup for parallel math like matrix multiplication.
- 5
optuna
14.9Koptuna/optuna · PythonOptuna is an open-source framework for automatic hyperparameter optimization, built primarily for machine learning: you wrap your training code in an objective function and it searches for the best settings automatically.
- 6

rayon
13.4Krayon-rs/rayon · RustRayon is a data-parallelism library for Rust. It is extremely lightweight and makes it easy to turn a sequential computation into a parallel one, with data-race freedom guaranteed.
- 7
tiny-gpu
13.1Kadam-maj/tiny-gpu · SystemVerilogtiny-gpu is a minimal GPU design written in Verilog (SystemVerilog) built purely to teach how GPU architecture works from the ground up, covering core concepts like SIMD parallelization, memory bandwidth management, and instruction execution.
- 8

taskflow
12.2Ktaskflow/taskflow · C++Taskflow is a C++ library that helps you write high-performance task-parallel programs with high programming productivity, letting you build and run graphs of dependent tasks across CPU threads and GPUs.
- 9

numba
11.2Knumba/numba · PythonNumba is a Just-In-Time compiler that translates a subset of Python and NumPy code into fast machine code using LLVM, letting numerical functions run near C/Fortran speed without leaving Python.
- 10

conc
10.4Ksourcegraph/conc · Goconc is a Go library — a 'toolbelt' for structured concurrency that makes common concurrent patterns in Go easier and safer than raw goroutines and sync primitives.
- 11
modin
10.4Kmodin-project/modin · PythonModin is a drop-in replacement for pandas: you keep the same API and syntax, but your workflows run on all of your CPU cores instead of a single thread. Change one import line and your existing pandas code just runs faster.
- 12

gpgpu-sim_distribution
1.8Kgpgpu-sim/gpgpu-sim_distribution · C++GPGPU-Sim is a cycle-level simulator that models contemporary NVIDIA GPUs running CUDA or OpenCL workloads, letting researchers study GPU microarchitecture without real hardware. It also bundles a visualization tool (AerialVision) and a power model (AccelWattch).
- 13
TornadoVM
1.5Kbeehive-lab/TornadoVM · JavaAn open-source GPU programming framework for Java: it JIT-compiles Java bytecode at runtime into NVIDIA CUDA, OpenCL C or Apple Metal code, so Java programs run on GPUs and multi-core CPUs. Works with JDK 21-27.
- 14

pyrowave
761Themaister/pyrowave · C++An intra-only video codec — effectively a still-image codec — that runs entirely on the GPU as Vulkan compute shaders: under ~0.1 ms per frame at 1080p and ~0.2 ms at 4K. It is built for local-network game streaming.
- 15

DeepEP-Ascend
259deepseek-ai/DeepEP-Ascend · C++DeepEP-Ascend is a high-performance communication library for machine learning training and inference on Huawei Ascend NPUs, providing expert-parallel all-to-all operations for MoE dispatch and combine.
Related topics
Often tagged together
- open-source5,666
- gpu789
- performance633
- high-performance141
- linux4,184
- library1,587
- parallel23
- python2,383
- cross-platform2,623
- cuda396
- gpu-acceleration144
- macos3,544
- mit3,312
- c++418
- gpu-programming28
- machine-learning916
- systems-programming101
- apache-2.01,434
- compiler165
- concurrency93
- cpp383
- data-science231
- deep-learning737
- developer-tools2,924