Topics / #document-intelligence
Document-intelligence projects on GitHub
Extracting structured information from documents using machine learning
As of , the most-starred Document-intelligence projects on GitHub are localGPT (22.2K stars), surya (21.5K stars) and PaddleNLP (13K stars). GitHub.Locker tracks 5 Document-intelligence repositories with 61.6K stars combined. The fastest-growing on October 17 was knowhere, with +15 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +15
knowhere
Ontos-AI/knowhere · ★ 3.8KKnowhere is an open-source document parsing and retrieval system: it ingests messy files and turns them into structured, navigable memory for AI agents, ready for agentic RAG and any LLM workflow.
 +6
surya
datalab-to/surya · ★ 21.5KSurya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
 +1
PaddleNLP
PaddlePaddle/PaddleNLP · ★ 13KPaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
The all-time top
5 projects · by stars
- 22.2K
 #1 · PromtEngineer/localGPT
localGPT
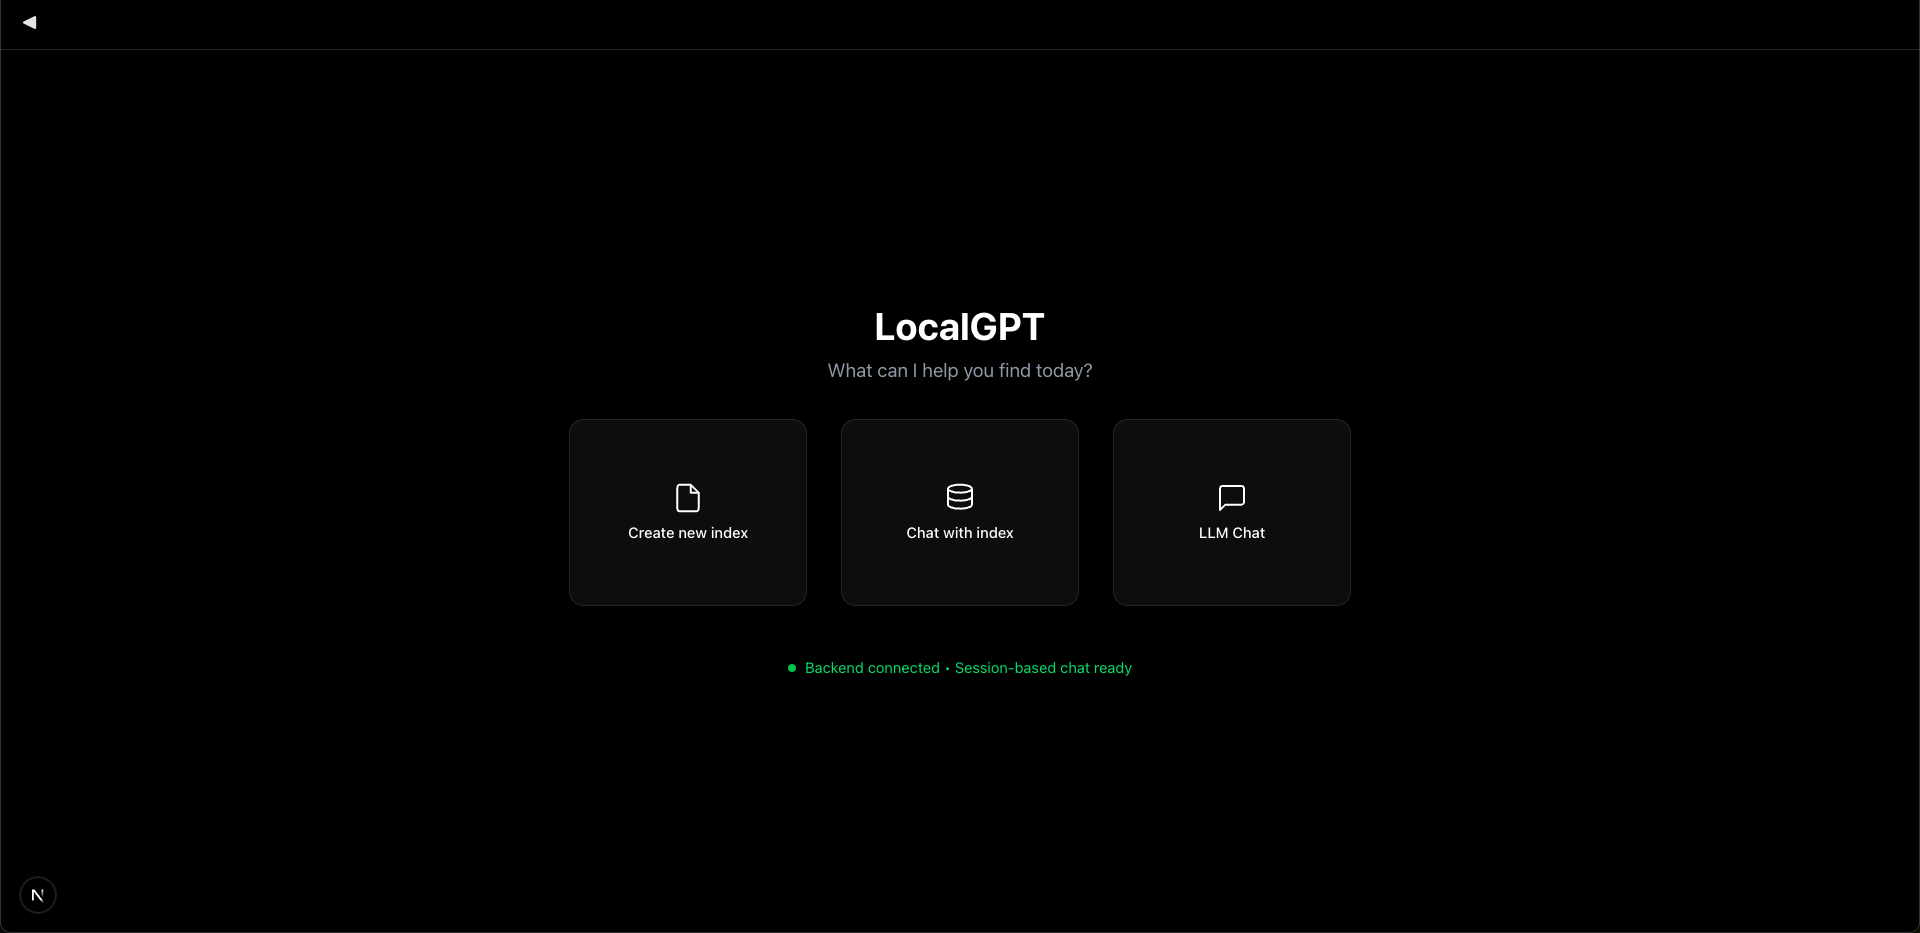
LocalGPT is a fully private, on-premise document intelligence platform: chat with, summarise and query your own documents using LLMs that run locally, so no data ever leaves your machine.
- 21.5K#2 · datalab-to/surya
surya
Surya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
- 13K#3 · PaddlePaddle/PaddleNLP
PaddleNLP
PaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
- 4
knowhere
3.8KOntos-AI/knowhere · PythonKnowhere is an open-source document parsing and retrieval system: it ingests messy files and turns them into structured, navigable memory for AI agents, ready for agentic RAG and any LLM workflow.
- 5
lift
1.2Kdatalab-to/lift · Pythonlift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
Related topics
Often tagged together