Topics / #model-serving
Model-serving projects on GitHub
Serving trained models as low latency APIs.
As of , the most-starred Model-serving projects on GitHub are vllm (94K stars), exo (47.9K stars) and ray (44.1K stars). GitHub.Locker tracks 46 Model-serving repositories with 400.4K stars combined. The fastest-growing on October 16 was solo_jev, with +149 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +149
solo_jev
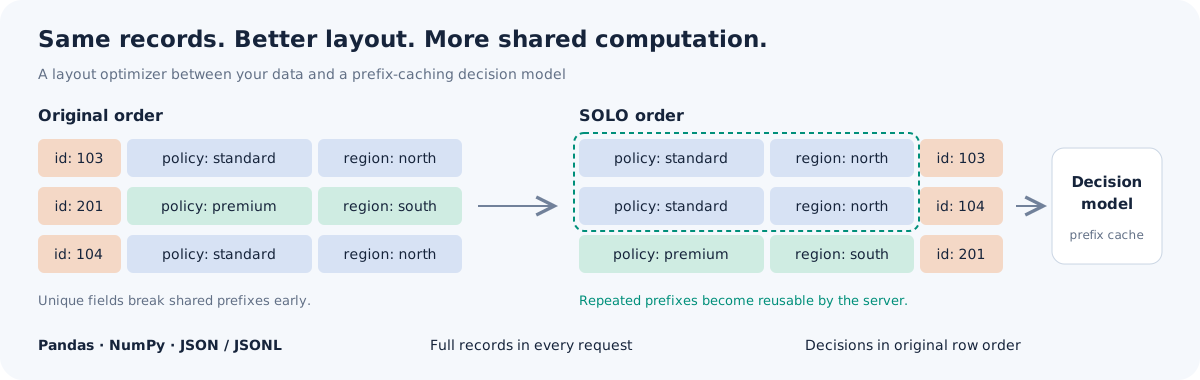
0814wdwd/solo_jev · ★ 622SOLO reorders the rows and fields of a dataset so an LLM decision backend with prefix caching can reuse computation across requests, running a natural-language decision over every row while returning results in the original row order.
 +135
magnitude
magnitudedev/magnitude · ★ 7KMagnitude is an open source inference server that profiles your machine, recommends local models that fit it, then downloads, tunes, and runs them for your coding agent.
 +73
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +58
project-maya
mw00/project-maya · ★ 954Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
The all-time top
46 projects · by stars
- 94K#1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 47.9K
 #2 · exo-explore/exo
exo
exo turns a group of your own devices (Macs, Linux boxes) into a single AI cluster so you can run large AI models that would never fit on one machine, pooling their memory and compute together.
- 44.1K
 #3 · ray-project/ray
ray
Ray is an open-source framework for scaling AI and Python applications: a core distributed runtime plus a set of AI libraries that simplify ML compute.
- 4

Detectron
26.4Kfacebookresearch/Detectron · PythonDetectron is Facebook AI Research's software system implementing state-of-the-art object detection algorithms like Mask R-CNN and RetinaNet, built as a research platform for computer vision.
- 5

omlx
22.9Kjundot/omlx · PythonoMLX is a local LLM inference server for Apple Silicon Macs. It serves text LLMs, vision models, OCR, embeddings and rerankers with continuous batching and a tiered KV cache, managed from the macOS menu bar.
- 6

serve
21.9Kjina-ai/serve · PythonJina is an open-source Python framework for building multimodal AI applications on a cloud-native stack — you wrap models into gRPC microservices, chain them into flows, and scale from local to cloud.
- 7
FreeToken
14.5KFlashML-org/FreeToken · PythonFreeToken is an edge-native Mixture-of-Experts (MoE) serving engine built to run frontier-scale open-weight models, including 290B+ parameter models, on consumer hardware like gaming PCs.
- 8

TensorRT
13.4KNVIDIA/TensorRT · C++TensorRT is NVIDIA's SDK for high-performance deep learning inference on NVIDIA GPUs. This repository holds the open source components: plugins, the ONNX parser, and sample applications that demonstrate TensorRT usage.
- 9
LMCache
12.1KLMCache/LMCache · PythonLMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 10

server
11.1Ktriton-inference-server/server · PythonTriton Inference Server is an open source serving system for deploying trained AI models from frameworks like TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL, running inference requests over HTTP/REST or gRPC.
- 11
openvino
11Kopenvinotoolkit/openvino · C++OpenVINO is Intel's open-source toolkit for optimizing and deploying AI inference — it takes trained deep learning models for vision, speech, NLP, and generative AI and runs them faster, from edge devices to cloud servers.
- 12
text-generation-inference
10.9Khuggingface/text-generation-inference · PythonText Generation Inference (TGI) is a toolkit for deploying and serving large language models — a Rust, Python and gRPC server that powers Hugging Chat, the Inference API and Inference Endpoints at Hugging Face.
- 13

petals
10.6Kbigscience-workshop/petals · PythonPetals lets you run big open LLMs at home, BitTorrent-style: you join a public swarm that serves models like Llama 3.1 (405B), Mixtral (8x22B), Falcon (40B+) and BLOOM (176B) for inference and fine-tuning right from your desktop or Google Colab, up to 10x faster than offloading.
- 14

kev
9.3Kjaredpalmer/kev · PythonKev is an open family of small decision models (0.8B to 27B parameters) built on Qwen3.5/3.8 that answer yes/no, multiple-choice and rating questions about text with calibrated probabilities, acting as a self-hosted drop-in replacement for TypeSafe's hosted Jev model.
- 15
vllm-omni
7.2Kvllm-project/vllm-omni · PythonvLLM-Omni is an inference and serving framework that extends vLLM beyond text-only LLMs to omni-modality models, handling text, image, audio, video, and action outputs.
- 16
magnitude
7Kmagnitudedev/magnitude · RustMagnitude is an open source inference server that profiles your machine, recommends local models that fit it, then downloads, tunes, and runs them for your coding agent.
- 17
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 18
dflash
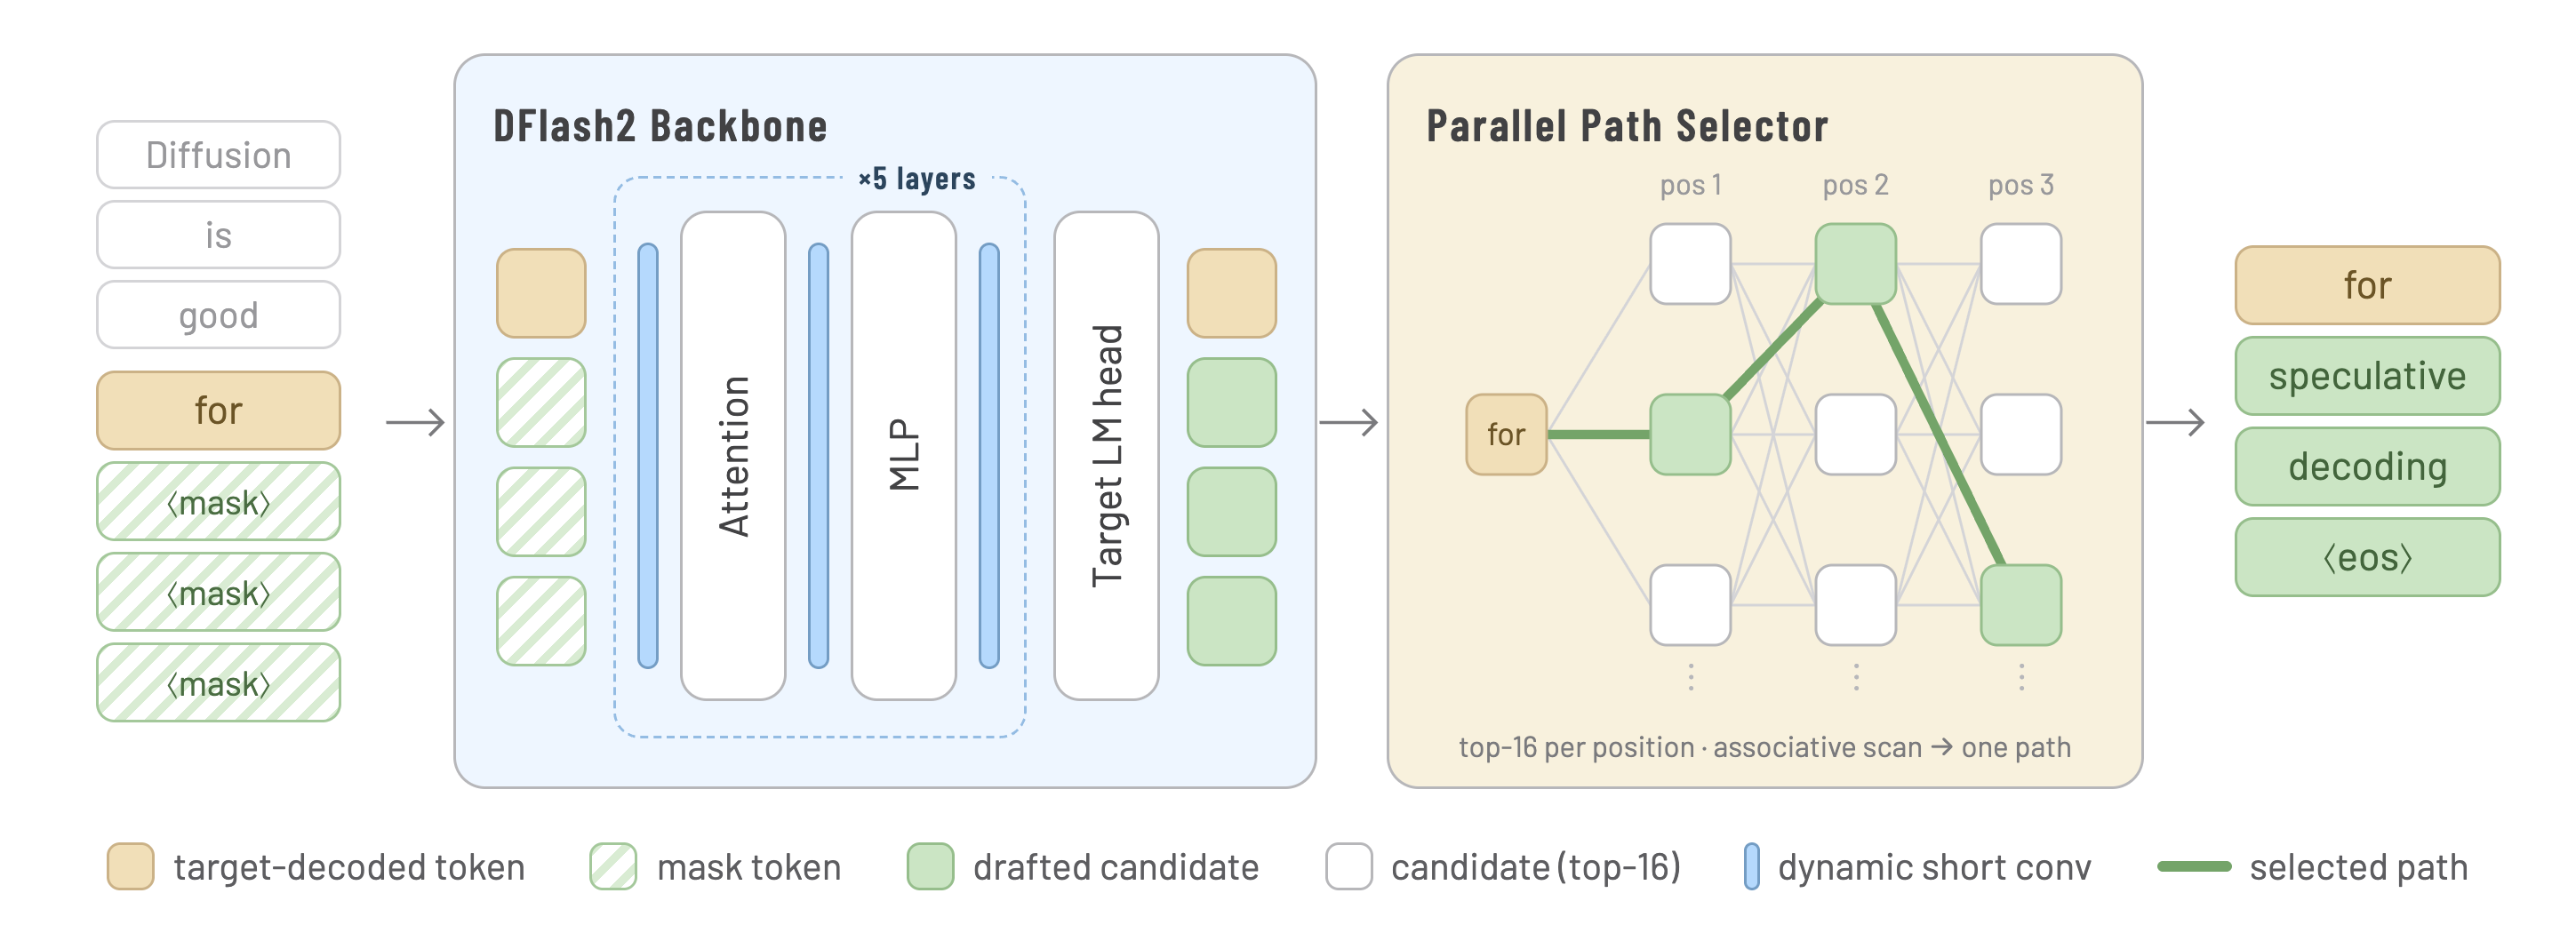
6.2Kz-lab/dflash · PythonDFlash is a lightweight block diffusion model built for speculative decoding, drafting tokens in parallel blocks so a larger target LLM can verify them faster than generating one token at a time.
- 19
CLM
3.1KContrastive-LM/CLM · PythonCLM (Contrastive Language Models) is a 'System One' model trained with a contrastive learning objective that connects states and actions, served behind a TypeSafe-compatible API as CLM-8B. It is meant to be plugged into agents as a fast scorer/verifier for decisions, tool calls, and best-of-N candidates.
- 20

warp
2.5Ksqliteai/warp · CWARP (Weight-Aware Runtime and Paging, formerly WASTE) is a dependency-free, embeddable C inference engine that runs huge mixture-of-experts models on consumer hardware by streaming each token's activated weights straight from NVMe — the full models, not distilled versions.
- 21
uzu
2.4Ktrymirai/uzu · Rustuzu is a high-performance inference engine for AI models that lets you run LLMs directly inside your app with zero latency, full data privacy, and no per-request inference costs.
- 22

HyperQwen
2Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 23

TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 24
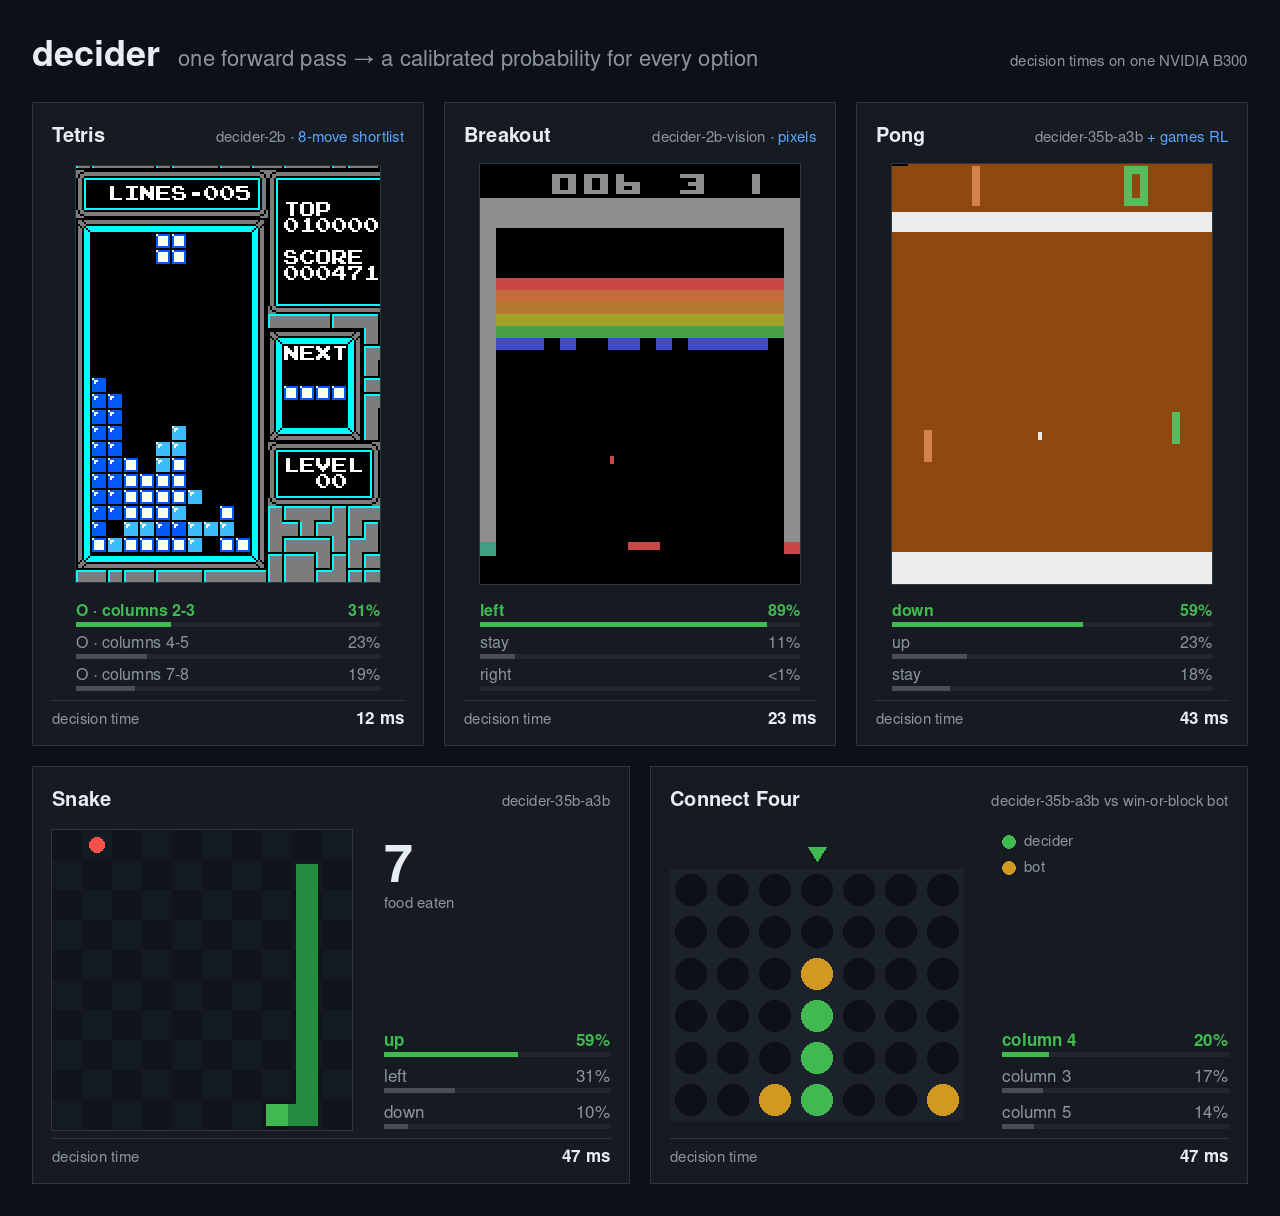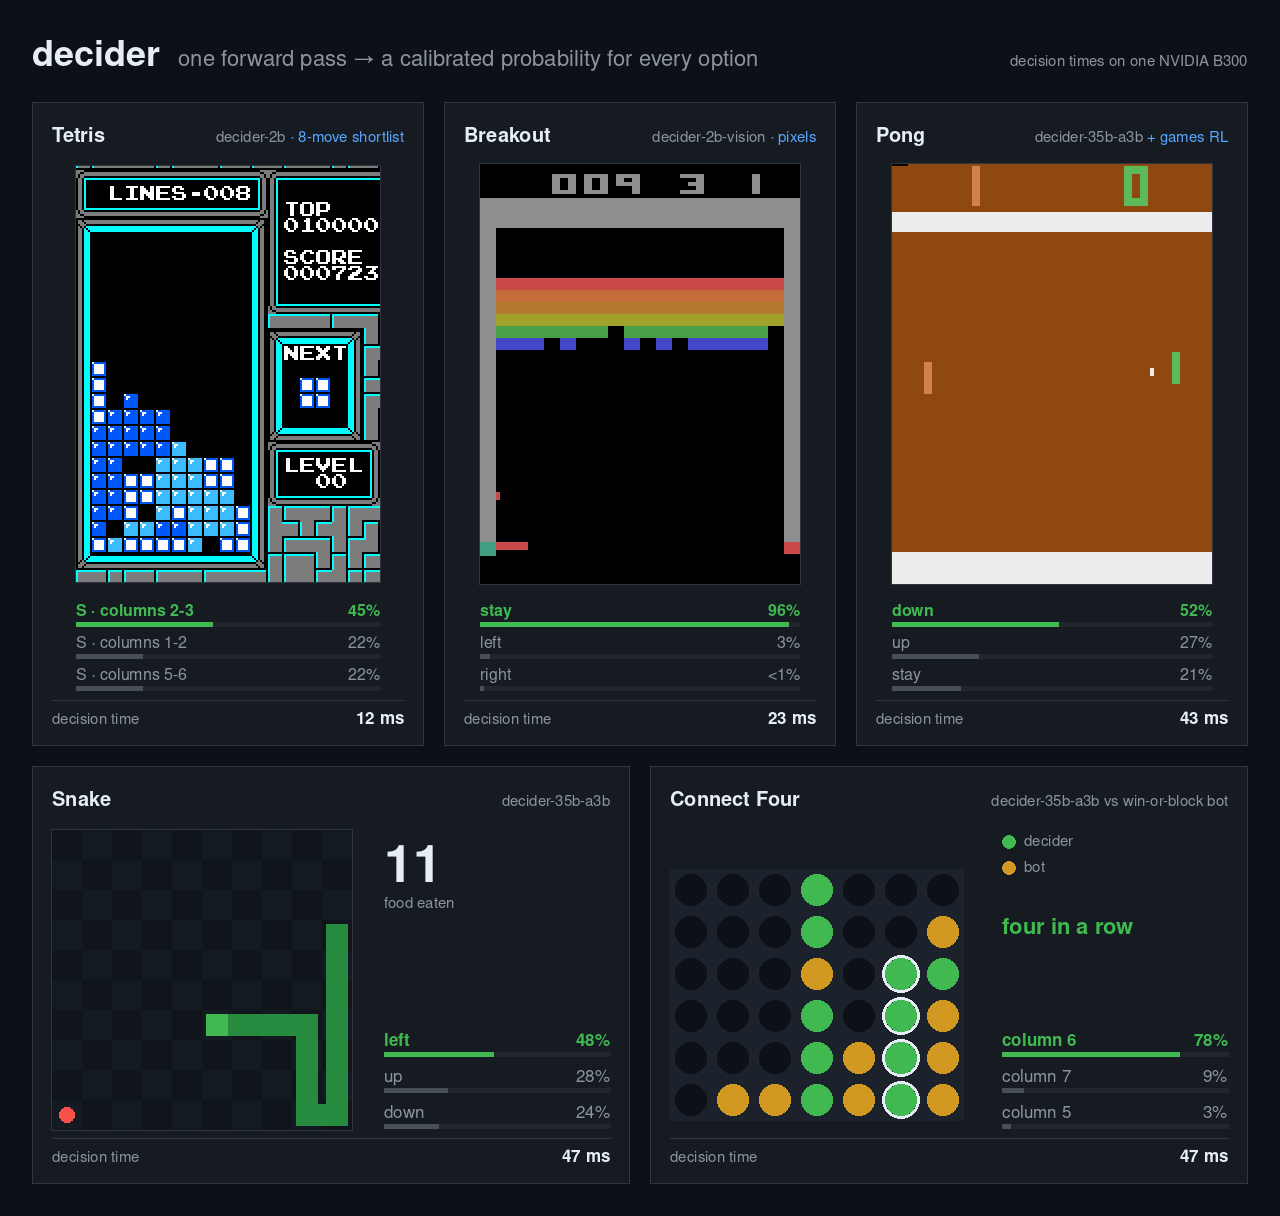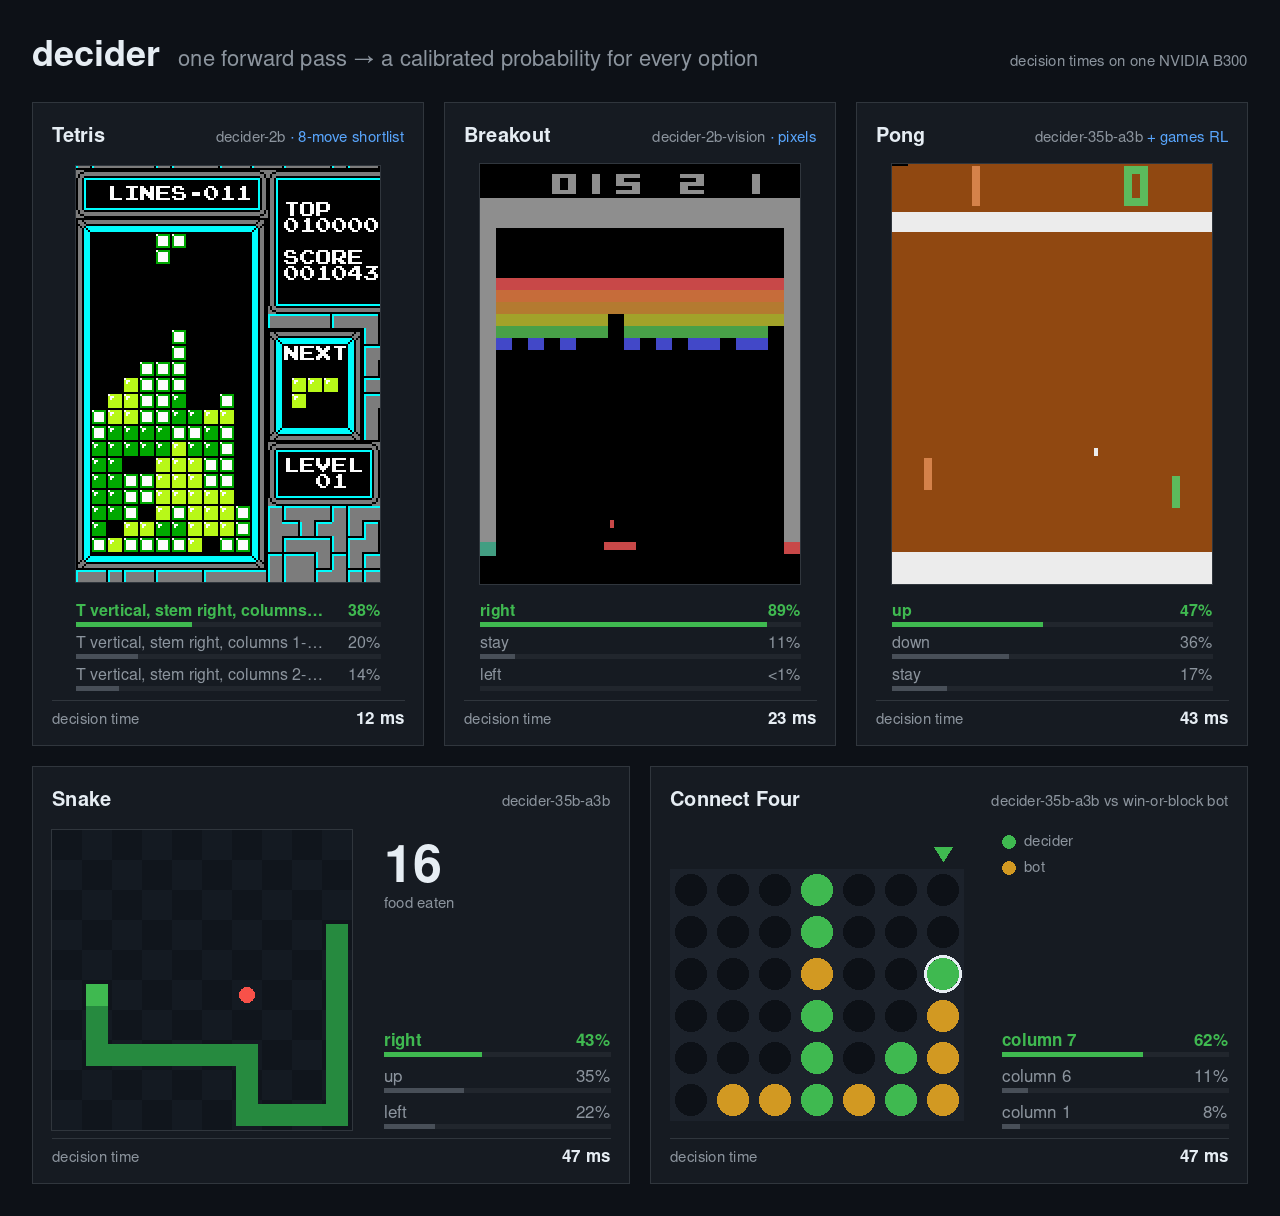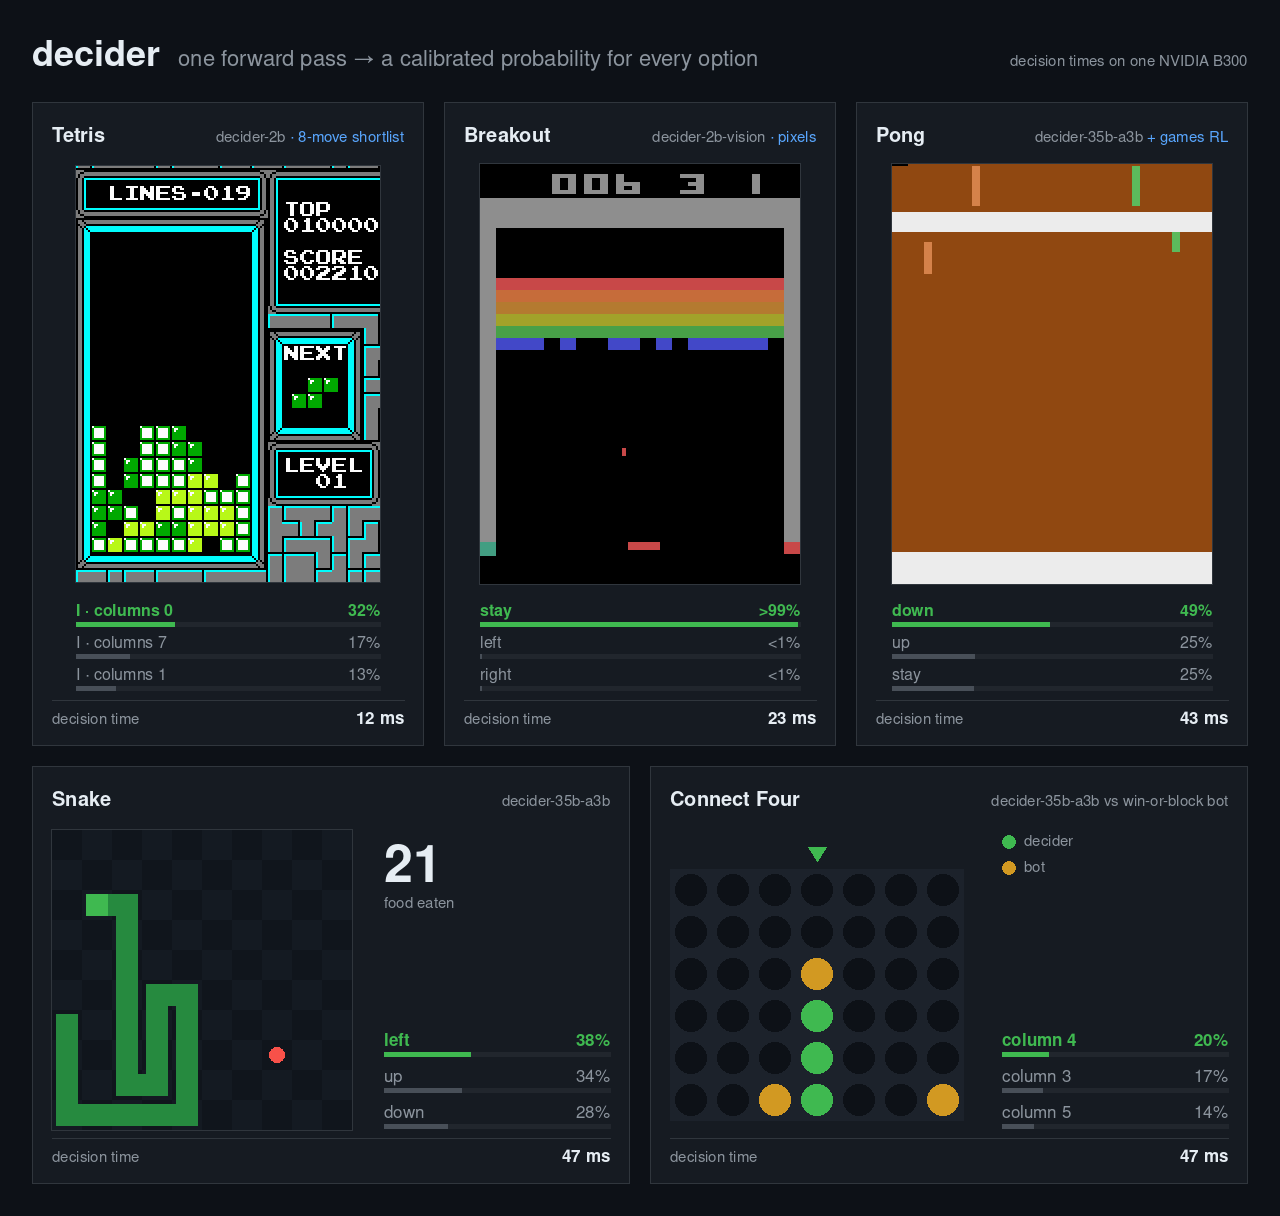
decider
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 25
MiniMax-Music3
961MiniMax-AI/MiniMax-Music3MiniMax Music 3 is a music generation model that creates complete songs up to five minutes long from lyrics and a music description, producing 32 kHz 16-bit stereo WAV audio with coherent structure and expressive vocals.
- 26
TypeLLM
956TypeLLM/TypeLLM · PythonTypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 27
project-maya
954mw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 28

GLM-5.3-Flash-EXL3-2x-DGX-Sparks
734MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks · PythonA deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
- 29
solo_jev
6220814wdwd/solo_jev · PythonSOLO reorders the rows and fields of a dataset so an LLM decision backend with prefix caching can reuse computation across requests, running a natural-language decision over every row while returning results in the original row order.
- 30
Qwen3.8-Flash-Next-Single-DGX-Spark
609MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark · PythonA self-contained recipe for serving the Qwen3.8-Flash-Next-NVFP4 checkpoint from a single NVIDIA DGX Spark machine's unified memory, using vLLM with the PLE table offloaded and memory-mapped.
- 31
djev-run
584taeold/djev-run · HTMLdjev-run serves DiffusionGemma-Jev (djev) behind a TypeSafe AI compatible API on Google Cloud Run with an NVIDIA RTX PRO 6000 Blackwell or L4 GPU, or runs it directly inside Google Colab Pro via colab.ipynb; it is built on mmastrac/djev.
- 32

GLiClass
563Knowledgator/GLiClass · PythonGLiClass is an efficient zero-shot model for sequence classification, inspired by GLiNER: give it a text and a list of candidate labels, and it classifies the text with accuracy comparable to cross-encoders.
- 33
Qwen3.8-27B-SGLang-DGX-Spark
474MiaAI-Lab/Qwen3.8-27B-SGLang-DGX-Spark · ShellA set of opinionated, ready-to-run Docker scripts that serve the Qwen3.8-27B model through SGLang on an NVIDIA DGX Spark (GB10, aarch64), offering three swap-in speculative-decoding modes — EAGLE/MTP, DSpark, and DFlash2 — each tuned with on-device measurements rather than guesses.
- 34

qwen3.8-Flash-DGX
453blazux/qwen3.8-Flash-DGX · PythonA recipe (scripts plus a patched Docker image) for serving the ~176B-parameter Qwen3.8-Flash-Next model with vLLM on a single NVIDIA DGX Spark (GB10). It solves the problem that the 126 GiB NVFP4 checkpoint doesn't fit next to a usable KV cache in the Spark's 128 GB unified memory, by streaming a 48 GiB lookup table from NVMe via mmap instead of keeping it resident.
- 35
GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold
444MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold · PythonThis project serves the GLM-5.3-Flash language model as an OpenAI-compatible API, with vision and video input, running across two linked NVIDIA DGX Spark machines (GB10, 128GB each) using TensorFold.
- 36
awesome-minimax-h3-integration
442MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 37
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 38
Qwen3.8-Flash-Next-Dual-DGX-Sparks
410MiaAI-Lab/Qwen3.8-Flash-Next-Dual-DGX-Sparks · HTMLA multi-node inference launcher that runs the Qwen3.8-Flash-Next-NVFP4 language model across two NVIDIA DGX Spark nodes using vLLM with tensor parallelism, expert parallelism and speculative decoding.
- 39
DeepSeek-v4-Flash-One-DGX-Spark
346MiaAI-Lab/DeepSeek-v4-Flash-One-DGX-Spark · PythonA single-node Docker launcher that serves the DeepSeek V4 Flash 0731 model (EXL3 3.0bpw quantization) with DSpark speculative decoding, tuned to run entirely on one NVIDIA DGX Spark machine.
- 40
llm-inference-engineering
344amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 41

GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark
236tonyd2wild/GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark · PythonA deployment recipe and set of patched Docker images for serving GLM-5.3-Flash (320B total / 18B active MoE) as an OpenAI-compatible API across two NVIDIA DGX Spark nodes, using vLLM tensor-parallel 2, NVFP4 quantization, and DFlash2 speculative decoding.
- 42
Qwen3.8-27B-DFlash2-EXL3-5.0bpw
232MiaAI-Lab/Qwen3.8-27B-DFlash2-EXL3-5.0bpw · PythonA deployment kit for serving Qwen3.8-27B (quantized to EXL3 3.5bpw) through an OpenAI-compatible server, using speculative decoding to speed up generation. It bundles the launcher, server, and config; the model weights live on Hugging Face and inference runs on the team's exllamav3 fork.
- 43

dgx-spark-qwen38
227hasso5703/dgx-spark-qwen38 · PythonA one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 44
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
- 45
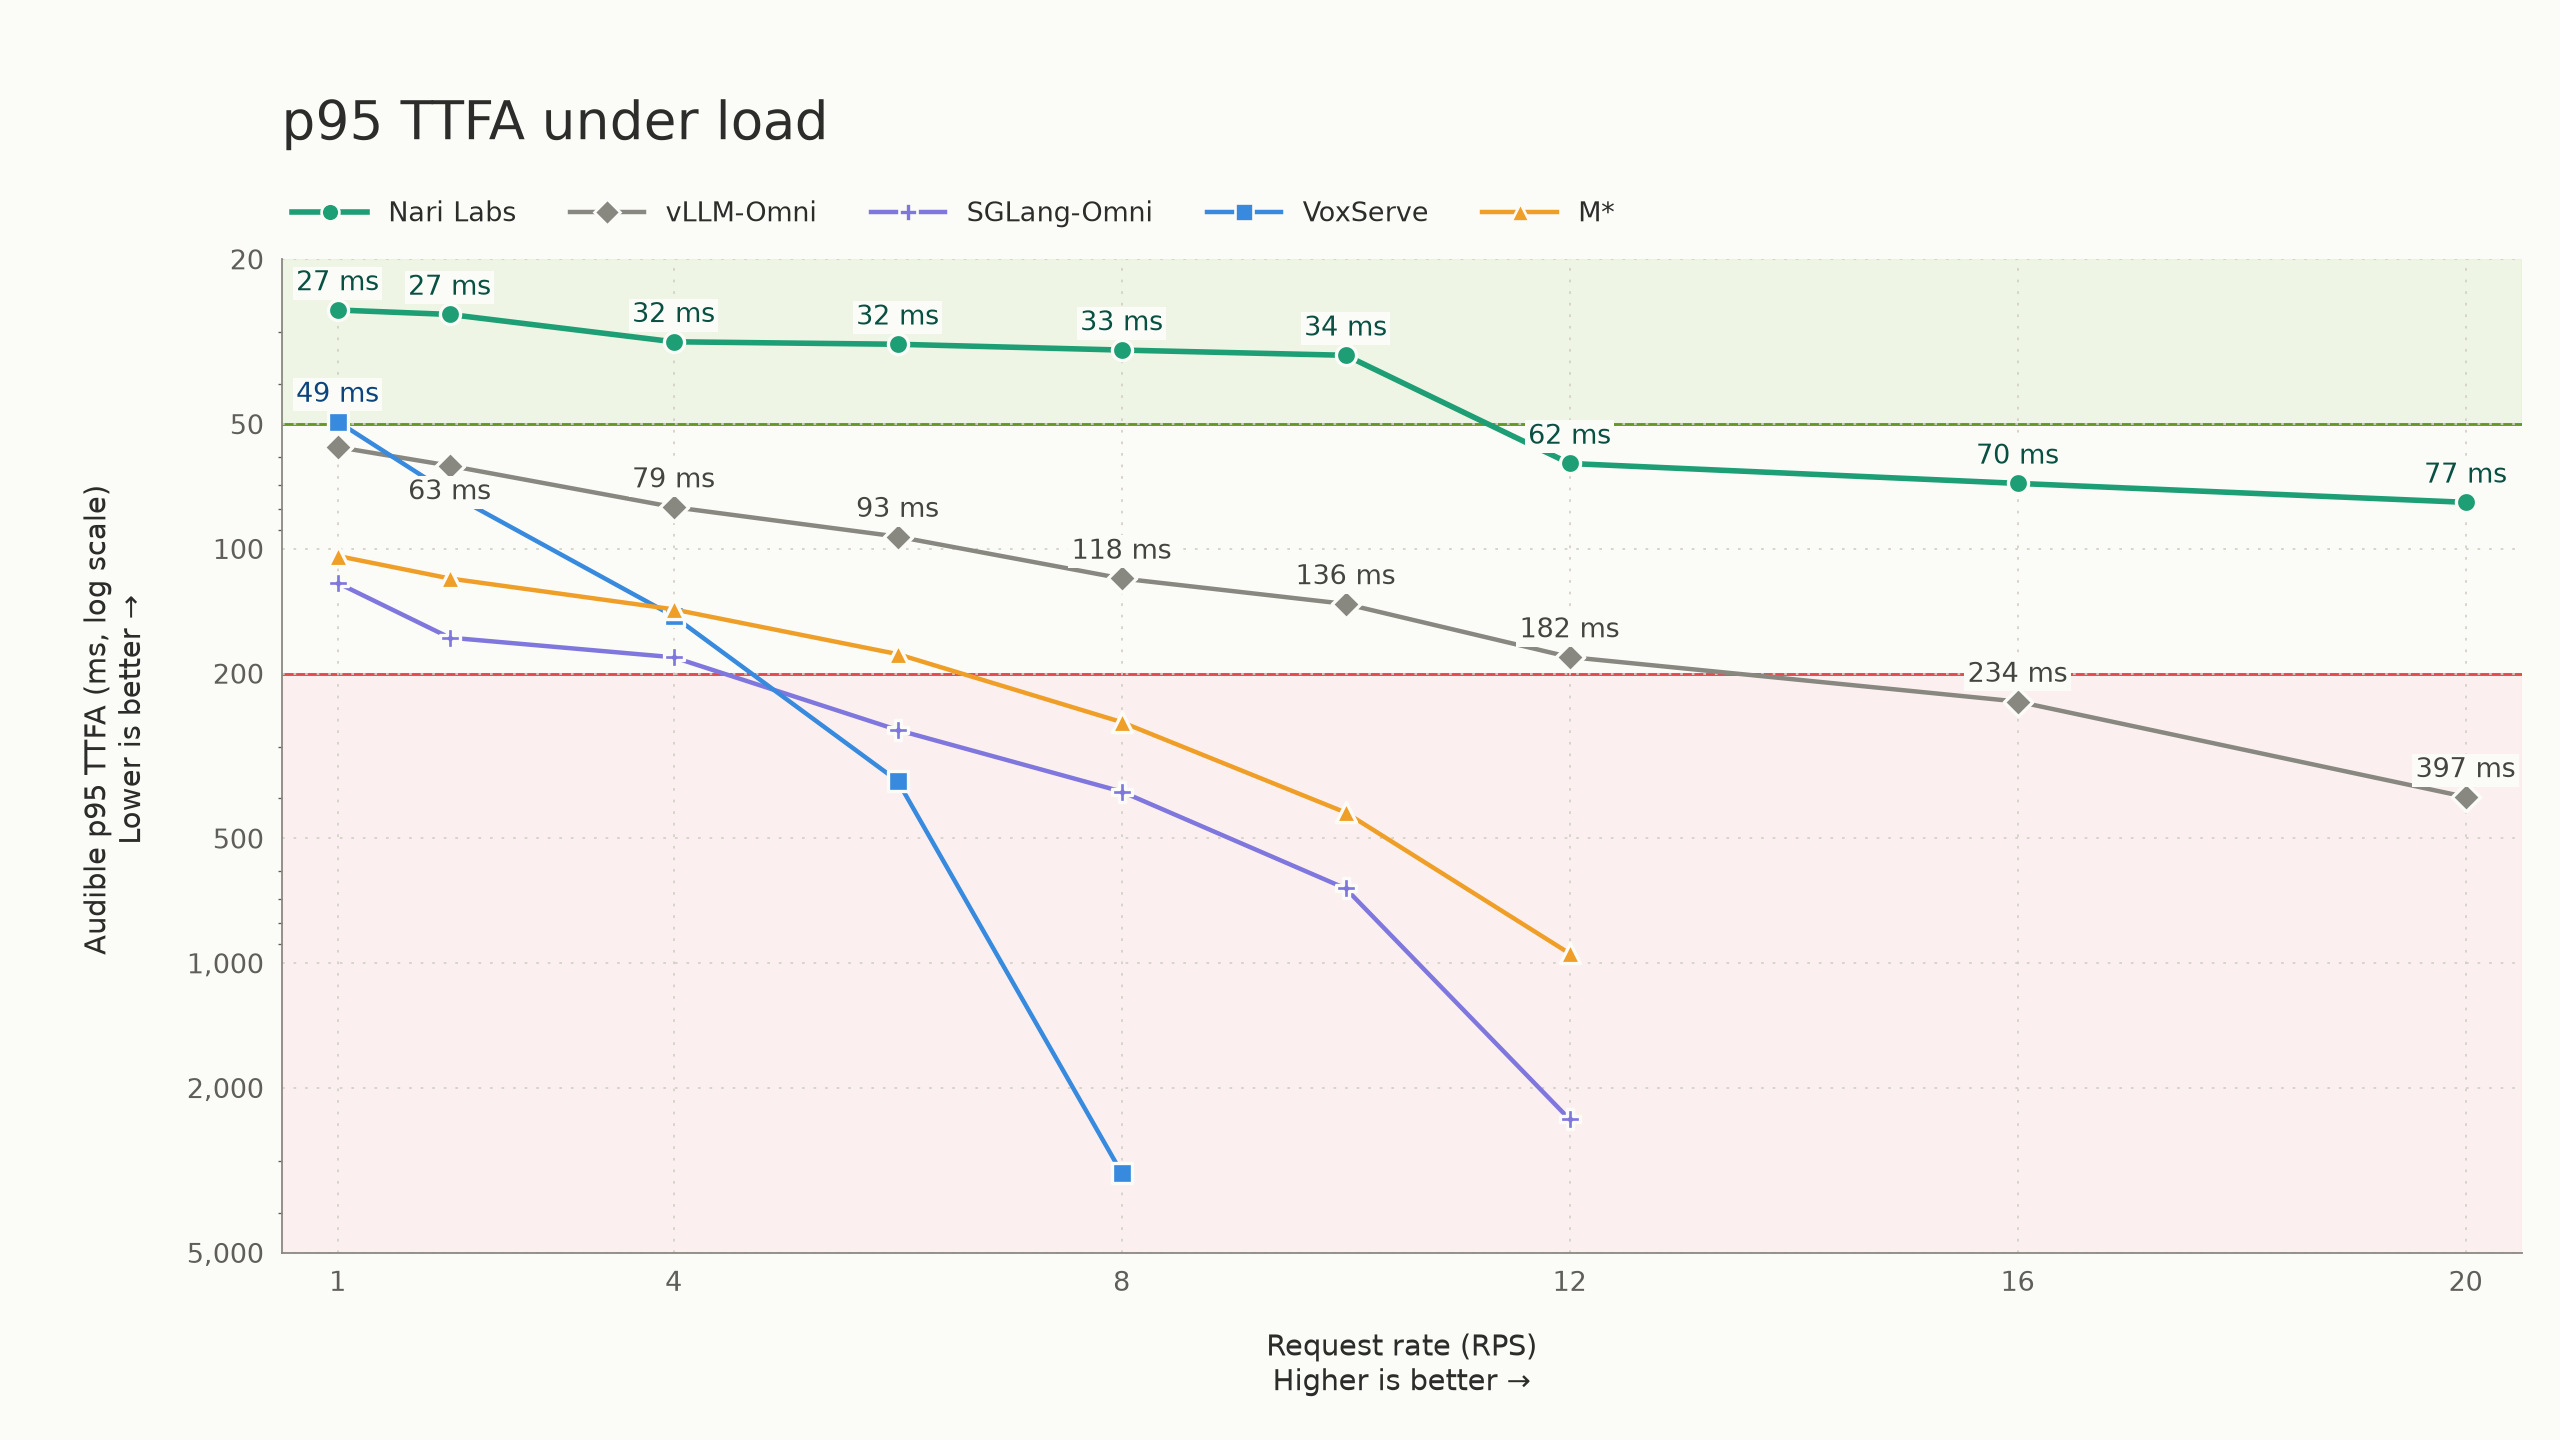
nari-qwen3-tts
187nari-labs/nari-qwen3-tts · PythonNari Qwen3-TTS is a high-performance serving implementation of the Qwen3-TTS 1.7B CustomVoice model, built to run on a single NVIDIA H100 and exposed as an API with streaming and non-streaming speech generation.
- 46

v100-skinny
172dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
Related topics
Often tagged together
- inference327
- gpu789
- llm-inference119
- python2,383
- llm1,483
- nvidia328
- cuda396
- linux4,184
- quantization183
- self-hosted1,929
- server1,459
- ai1,955
- machine-learning916
- local-llm218
- apache-2.01,434
- benchmark431
- huggingface362
- openai-compatible211
- api1,094
- deep-learning737
- large-language-models213
- docker1,660
- qwen154
- inference-engine45