Topics / #data-extraction
Data-extraction projects on GitHub
Extracting structured data from websites and documents.
As of , the most-starred Data-extraction projects on GitHub are firecrawl (192.8K stars), markitdown (191K stars) and Scrapling (88.5K stars). GitHub.Locker tracks 32 Data-extraction repositories with 1M stars combined. The fastest-growing on October 17 was firecrawl, with +311 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +311
firecrawl
firecrawl/firecrawl · ★ 192.8KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +188
Scrapling
D4Vinci/Scrapling · ★ 88.5KScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
 +160
markitdown
microsoft/markitdown · ★ 191KMarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
 +77
Noria
AhmadHassan-BTed/Noria · ★ 1.2KNoria is an agentic extractor that receives messages and URLs via WhatsApp, scrapes the linked web pages, evaluates the content against custom scoring matrices (e.g. jobs, scholarships) using an LLM, and sends back a structured summary with a calculated match score to the assigned WhatsApp number.
The all-time top
32 projects · by stars
- 192.8K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 191K#2 · microsoft/markitdown
markitdown
MarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
- 88.5K#3 · D4Vinci/Scrapling
Scrapling
Scrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 4
crawl4ai
85.8Kunclecode/crawl4ai · PythonCrawl4AI is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG pipelines, AI agents, and data extraction workflows.
- 5
MediaCrawler
67.2KNanmiCoder/MediaCrawler · PythonA multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
- 6

scrapy
64.9Kscrapy/scrapy · PythonScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 7
marker
40.5Kdatalab-to/marker · PythonMarker is a document conversion tool that turns PDFs (and other document types) into markdown, JSON, HTML, or chunked output quickly and accurately, extracting tables, equations, forms, and images along the way.
- 8
langextract
39Kgoogle/langextract · PythonLangExtract is a Python library that uses LLMs to pull structured information out of unstructured text, mapping each extraction back to its exact location in the source document.
- 9
Scrapegraph-ai
31.9KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 10
EasyOCR
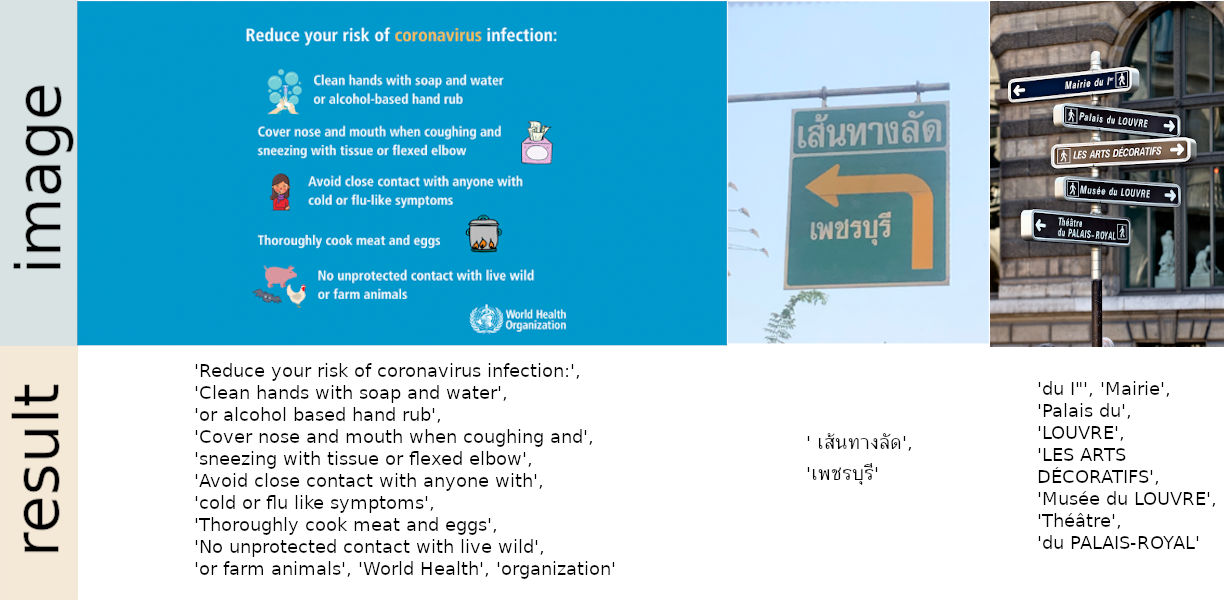
30.1KJaidedAI/EasyOCR · PythonA ready-to-use, open-source OCR library for Python: it detects and reads text in images across 80+ languages and popular writing scripts — Latin, Chinese, Arabic, Devanagari, Cyrillic and more.
- 11
stagehand
25.7Kbrowserbase/stagehand · TypeScriptStagehand is an SDK for building browser agents — code or AI agents that drive a real browser to extract data and interact with any website, with SDKs for TypeScript, Python, and Go.
- 12
surya
21.5Kdatalab-to/surya · PythonSurya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
- 13
maxun
17.9Kgetmaxun/maxun · TypeScriptMaxun is an open-source no-code web data platform that turns any website into structured, reliable data: it handles extraction, crawling, scraping, search and AI-powered data extraction.
- 14

pyspider
16.8Kbinux/pyspider · Pythonpyspider is a powerful web spider (crawler) system written in Python: you write crawling scripts in Python and manage your scraping projects through a built-in web interface.
- 15

twint
16.4Ktwintproject/twint · PythonTwint is a Python tool for scraping Twitter data — tweets, followers, following, likes and more — without using Twitter's official API, so it isn't bound by API limits or sign-up requirements.
- 16
unstructured
15.6KUnstructured-IO/unstructured · HTMLUnstructured is an open-source ETL toolkit that converts complex documents like PDFs, Word docs, HTML and images into clean, structured data (JSON) ready for LLMs, RAG pipelines and vector databases.
- 17
gjson
15.6Ktidwall/gjson · GoGJSON is a Go library for pulling values out of JSON documents quickly — one call with a path like 'name.last' returns the value. It also supports iteration and JSON Lines.
- 18

goquery
15KPuerkitoBio/goquery · Gogoquery is a Go library that brings jQuery-like syntax and features to HTML parsing and manipulation, built on Go's net/html package and the cascadia CSS selector library.
- 19
HackBrowserData
14.6KmoonD4rk/HackBrowserData · GoHackBrowserData is a command-line tool that decrypts and exports browser data — passwords, cookies, history, bookmarks, credit cards and more — from Chromium-based browsers, Firefox and Safari, built for security research.
- 20
zerox
12.2Kgetomni-ai/zerox · TypeScriptZerox is an open-source OCR and document-extraction tool powered by vision models: give it a PDF, DOCX or image and it returns Markdown — or structured data if you provide a schema.
- 21

spider-flow
11.4Kssssssss-team/spider-flow · JavaSpider-flow is a next-generation crawler platform that lets you design web scraping workflows as flowcharts instead of writing code.
- 22

pdfplumber
10.8Kjsvine/pdfplumber · Pythonpdfplumber is a Python library that inspects PDFs in detail, exposing each character, line, rectangle, and curve, and makes it easy to extract text and tables from them.
- 23
skills
6.2Kbrowser-act/skills · PythonBrowserAct Skills is a browser automation CLI/skill set that lets AI agents control a real browser, break through anti-bot protections, hand off to a human when stuck, and run parallel, isolated multi-account sessions.
- 24
scraping-apis-for-devs
3.9Kcporter202/scraping-apis-for-devs · JavaScriptA giant categorized directory of 2,622 ready-to-use scraping APIs for pulling data from websites, social media, e-commerce sites, job boards, real estate listings and more, so you don't have to build scrapers from scratch.
- 25
lift
1.2Kdatalab-to/lift · Pythonlift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
- 26
Noria
1.2KAhmadHassan-BTed/Noria · JavaScriptNoria is an agentic extractor that receives messages and URLs via WhatsApp, scrapes the linked web pages, evaluates the content against custom scoring matrices (e.g. jobs, scholarships) using an LLM, and sends back a structured summary with a calculated match score to the assigned WhatsApp number.
- 27
figranium
769figranium/figranium · TypeScriptFigranium is an open-source, deterministic browser automation platform: you stack blocks to build scraping and automation workflows visually, then call them as APIs — no usage credits or third-party data hosting.
- 28

EQAI
742AhmadHassan-BTed/EQAI · PythonThis is a reverse-engineering pipeline that transplants the original EverQuest Online Adventures (EQOA) character geometry into the EverQuest Online Adventures: Frontiers PS2 client, fixing engine-level bugs like VU1 shader errors, Emotion Engine memory overflows, and CDVD hardware faults so the original models load correctly.
- 29
deepcrawl
690lumpinif/deepcrawl · TypeScriptAn open-source, agent-oriented web data extraction platform — a self-deployable Firecrawl alternative that turns public pages into clean Markdown, a links tree, and LLM-friendly metadata.
- 30

wcdb-key-tool
654TANGandXUE/wcdb-key-tool · PythonA single-purpose Python tool that pulls the encryption keys out of WeChat's local WCDB/SQLCipher4 chat databases on Linux, macOS and Windows, so you can decrypt your own chat history.
- 31
wechat-ai-memory
348ikevss/wechat-ai-memoryA local-first Windows app that reads your WeChat 4.x chats directly, lets you filter them by conversation, date range and keyword, and exports the result as PDF, Markdown and structured JSON to build a personal, traceable chat memory archive.
- 32

steam2_downloader
229extremebleem/steam2_downloader · C#A desktop browser and downloader for the 'terarelease' Steam2 content leak - a dump of 10,876 depots and 116,339 files totaling 13.3 TB. It shows what the archive holds, works out which files a given depot version actually needs, downloads them, verifies them with sha256, and unpacks them.
Related topics
Often tagged together