Topics / #vision-language-model
Vision-language-model projects on GitHub
Multimodal models that understand images together with text for captioning, OCR, and visual QA.
As of , the most-starred Vision-language-model projects on GitHub are docling (69K stars), CLIP (34.5K stars) and MiniCPM-V (26.8K stars). GitHub.Locker tracks 45 Vision-language-model repositories with 438.7K stars combined. The fastest-growing on October 16 was esp32-iphone-agent, with +253 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +253
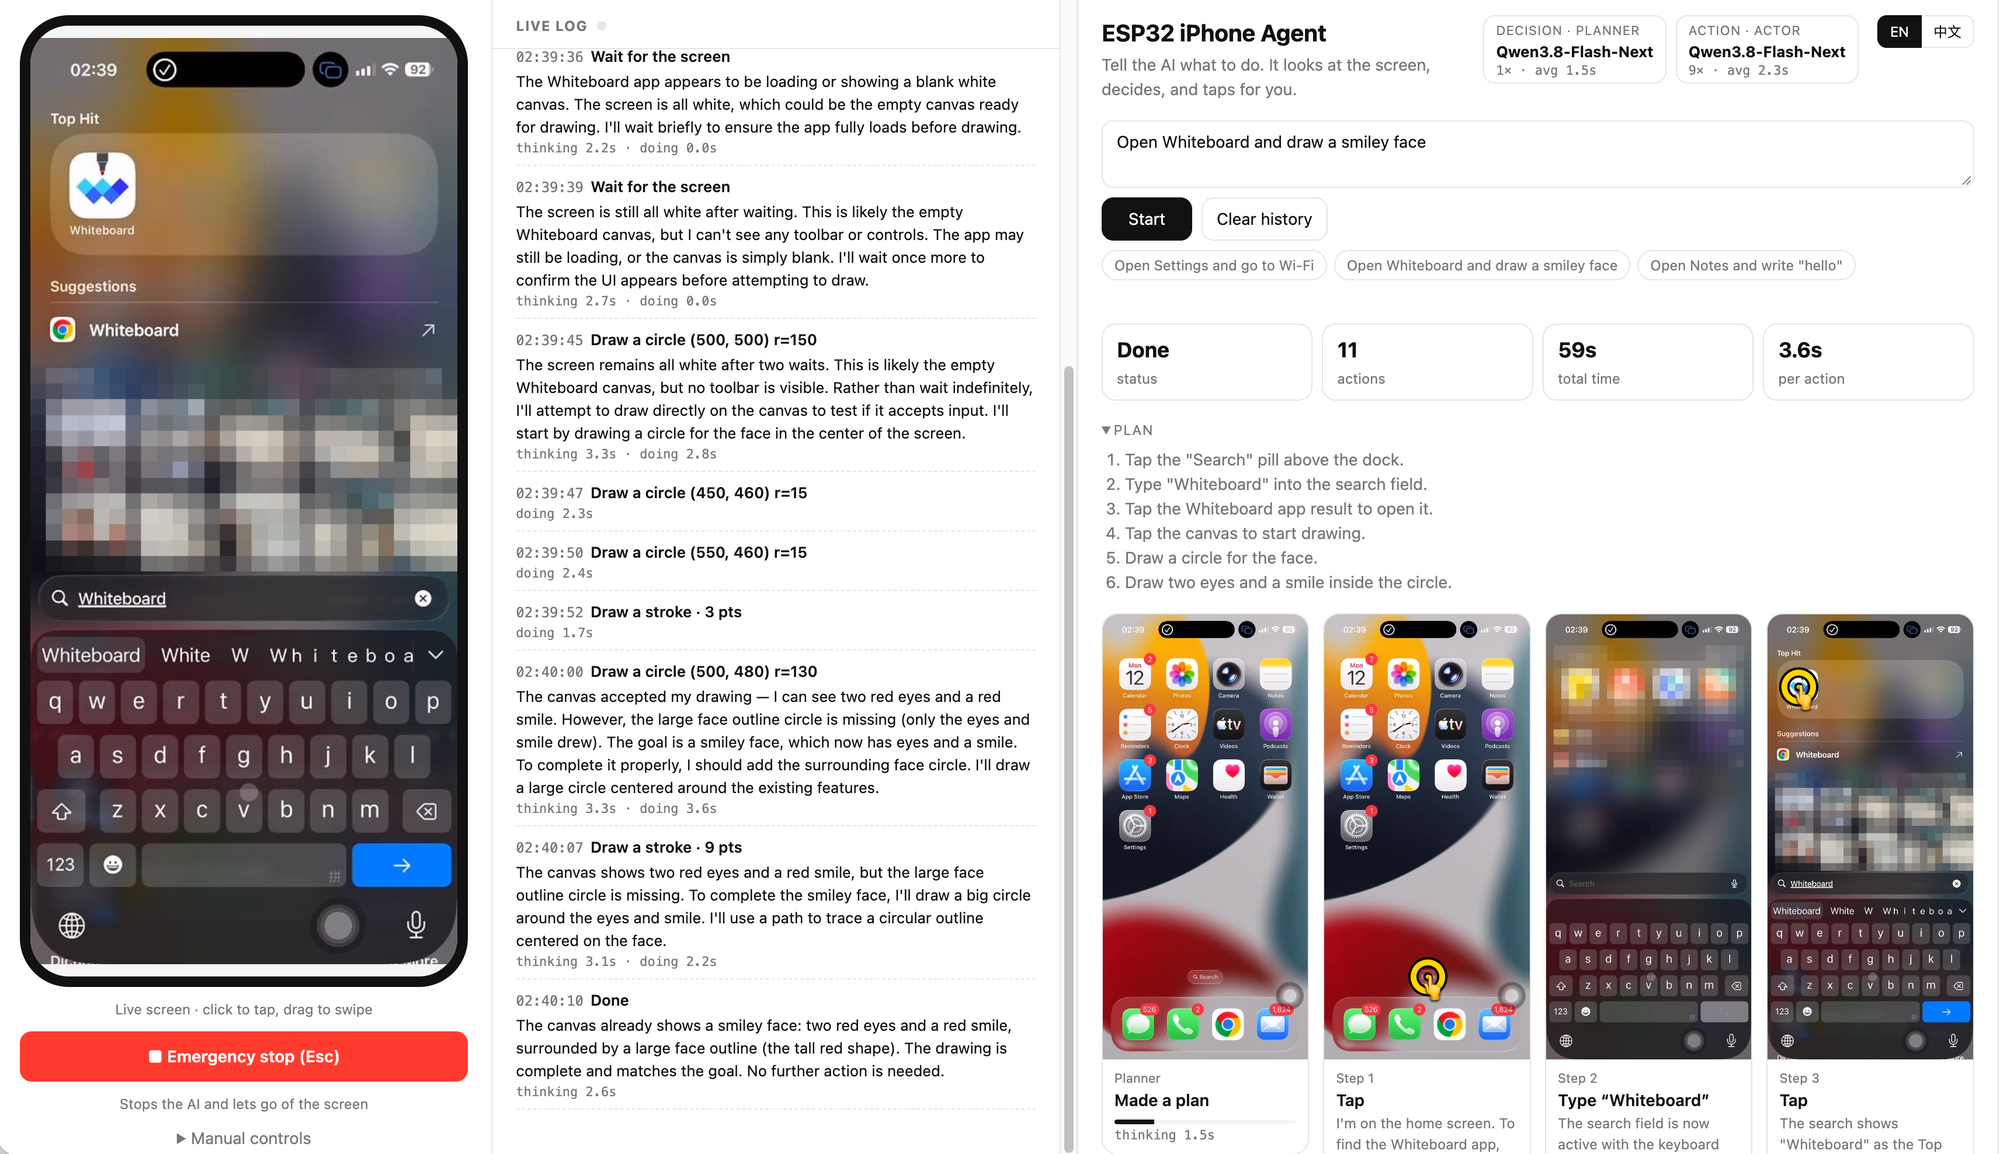
esp32-iphone-agent
onehumanbeing/esp32-iphone-agent · ★ 2.9KThis project lets an AI vision model control a real iPhone, using AirPlay screen mirroring as its 'eyes' and a $7 ESP32-S3 board acting as a USB mouse and keyboard as its 'hands', with no Mac, Apple developer account, or jailbreak required.
 +37
docling
docling-project/docling · ★ 69KDocling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
 +20
MiniCPM-V
OpenBMB/MiniCPM-V · ★ 26.8KA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
 +20
Intern-Decision
InternLM/Intern-Decision · ★ 811Intern-Decision turns a state, optional images, and multiple typed questions into decisions with probabilities, by fine-tuning the language backbone of Qwen3.5 while freezing its vision tower and projector.
The all-time top
45 projects · by stars
- 69K#1 · docling-project/docling
docling
Docling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
- 34.5K
 #2 · openai/CLIP
CLIP
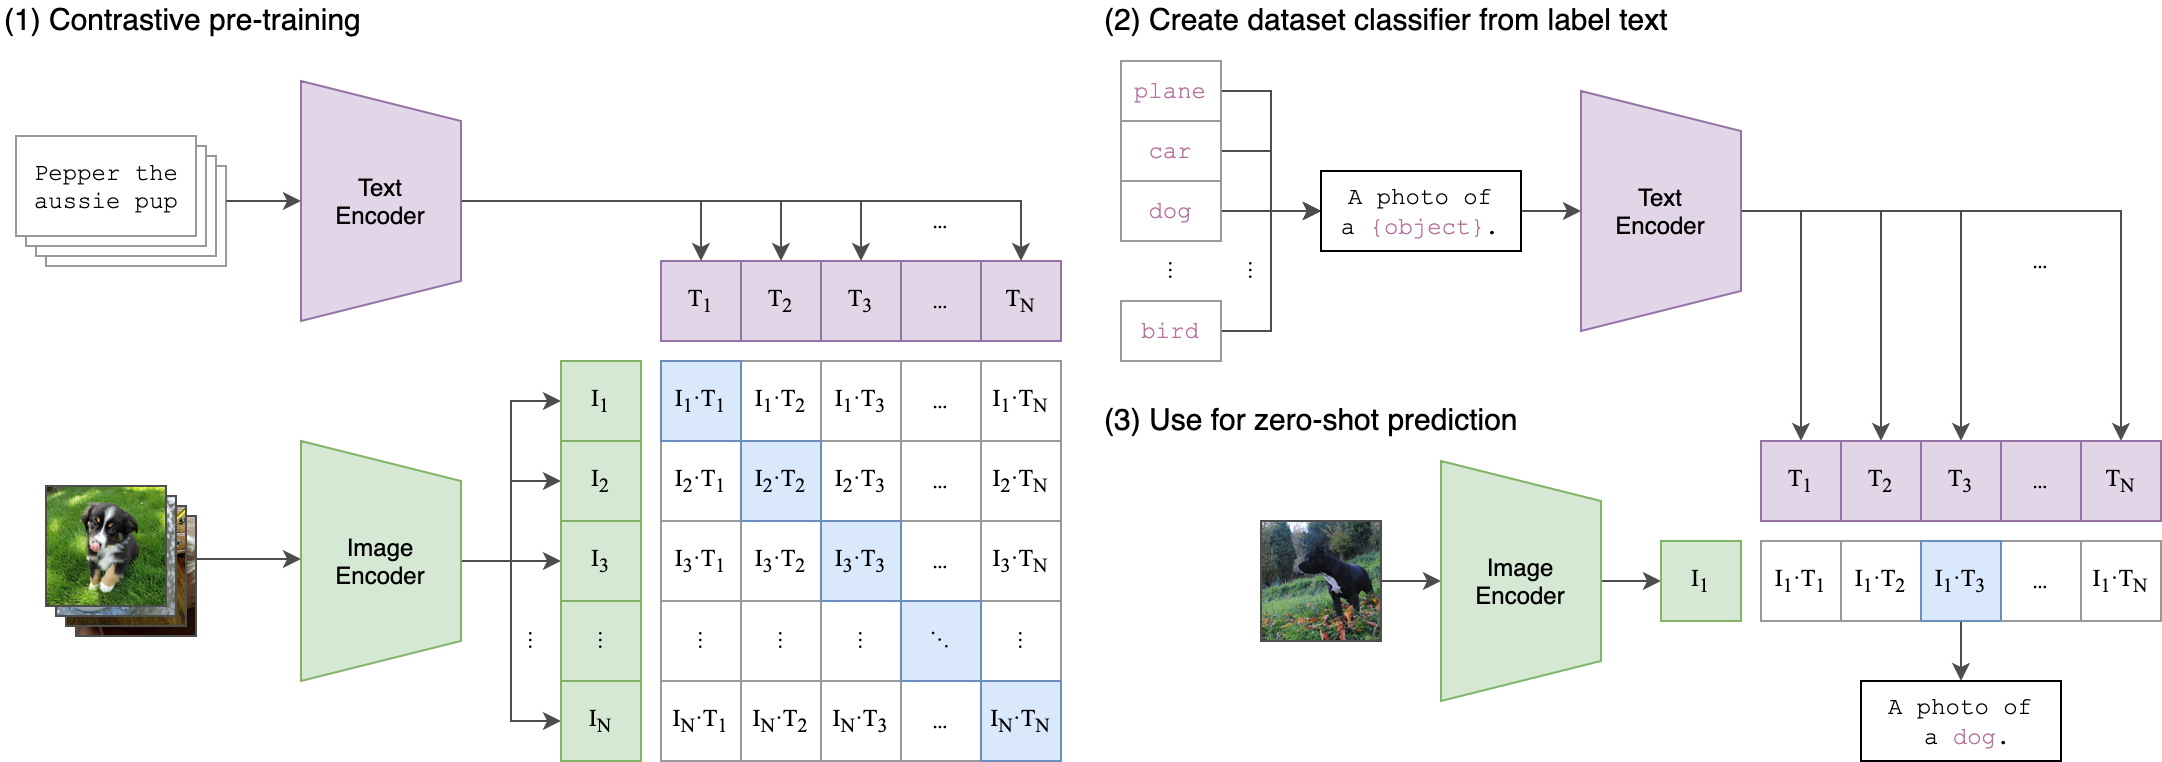
CLIP is a neural network trained on many (image, text) pairs: given an image, it predicts the most relevant text snippet in natural language, zero-shot, without directly optimizing for the task.
- 26.8K#3 · OpenBMB/MiniCPM-V
MiniCPM-V
A family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 4

Open-AutoGLM
26.4Kzai-org/Open-AutoGLM · PythonOpen-AutoGLM (Phone Agent) is an open phone-use agent framework built on the AutoGLM model that understands your phone screen visually and automates tasks via natural-language commands like 'open Xiaohongshu and search for food'.
- 5
MiniGPT-4
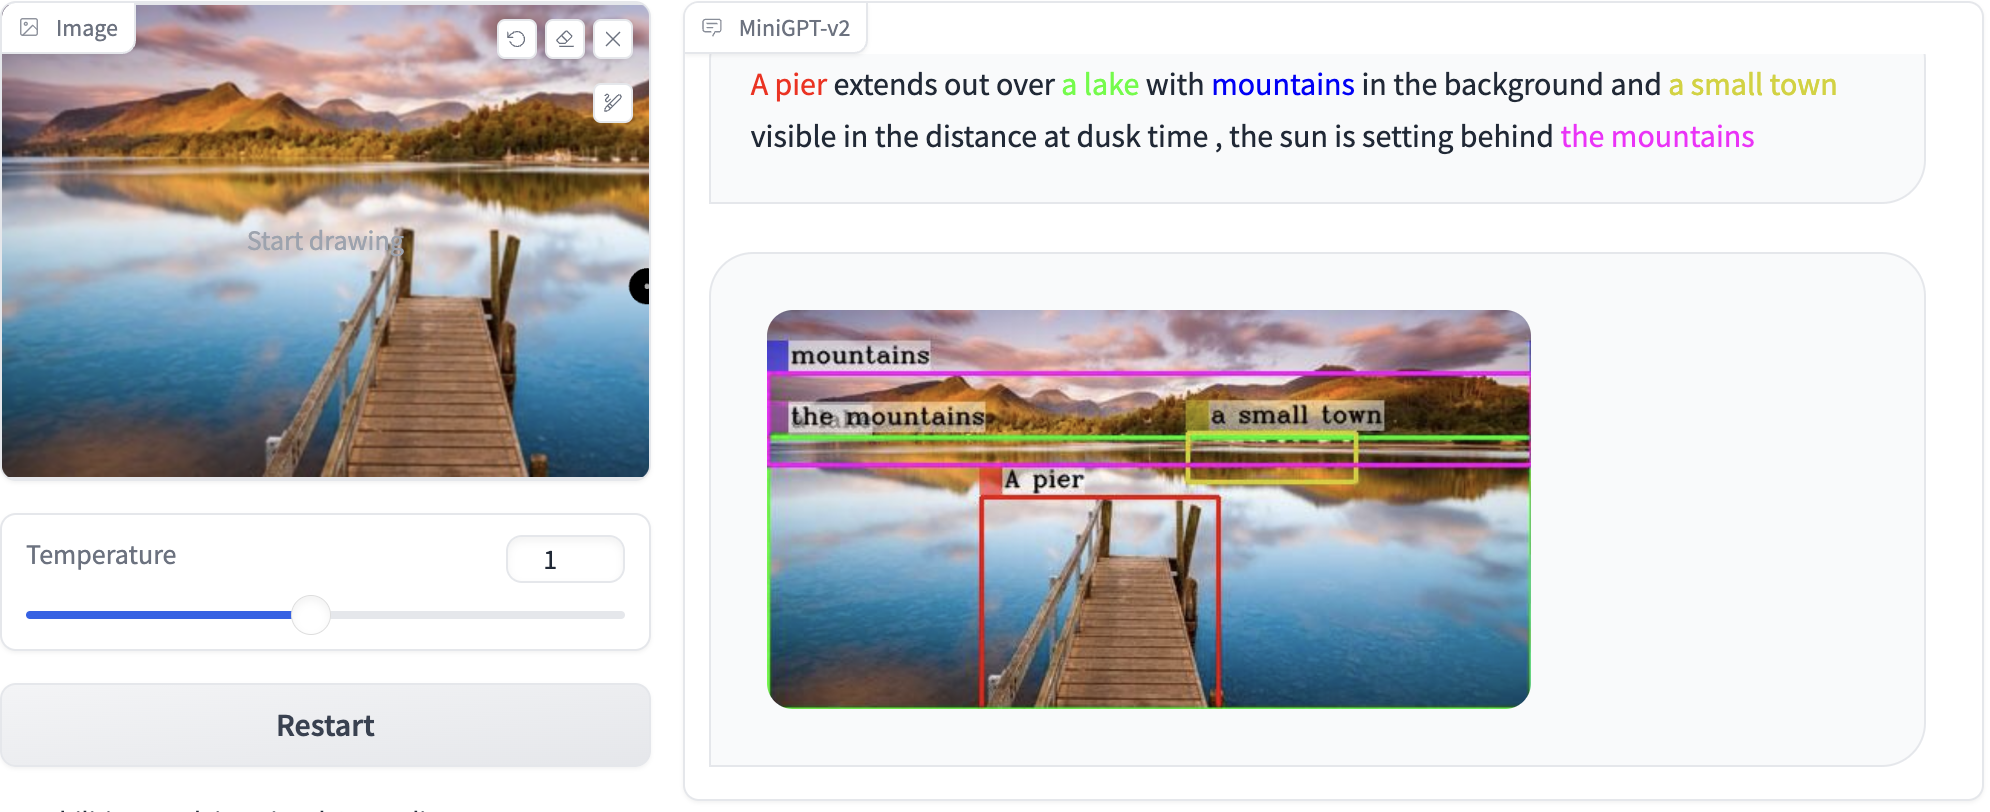
25.6KVision-CAIR/MiniGPT-4 · PythonThis is the open-sourced research code for MiniGPT-4 and MiniGPT-v2, two vision-language models that use a large language model as the interface for understanding and chatting about images.
- 6
OmniParser
25.5Kmicrosoft/OmniParser · Jupyter NotebookOmniParser parses GUI screenshots into structured, labeled elements (icons, text, interactable regions) so a vision model like GPT-4V can accurately decide what to click or type on a screen.
- 7
LLaVA
25.1Khaotian-liu/LLaVA · PythonLLaVA is an open-source large multimodal chatbot: a vision-language model you can show images to and talk with, built by visual instruction tuning toward GPT-4V-level capabilities (NeurIPS 2023 Oral).
- 8

DeepSeek-OCR
24Kdeepseek-ai/DeepSeek-OCR · PythonDeepSeek-OCR is a vision-language model built to explore 'contexts optical compression' -- squeezing text-heavy document images into a small number of vision tokens that an LLM can still read back accurately, as a research probe into how much text a vision encoder can represent visually.
- 9
skyvern
23.2KSkyvern-AI/skyvern · PythonSkyvern is an open-source AI agent that automates browser-based workflows using LLMs and computer vision — filling out forms, logging in, extracting data and downloading files on websites it has never seen before.
- 10
Qwen3-VL
20.1KQwenLM/Qwen3-VL · Jupyter NotebookQwen3-VL is a family of multimodal vision-language models built by the Qwen team at Alibaba Cloud, combining strong text understanding with deep visual perception, reasoning, and agent capabilities.
- 11

Janus
17.8Kdeepseek-ai/Janus · PythonJanus is DeepSeek's family of open multimodal AI models (Janus, Janus-Pro, JanusFlow). One model both understands images and text and generates images from a text prompt.
- 12
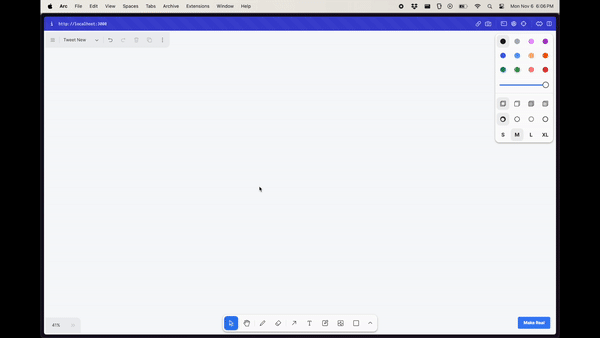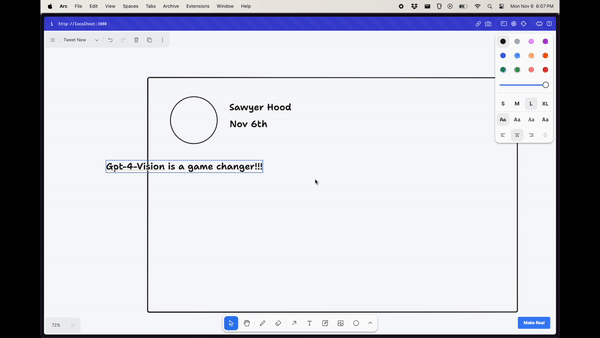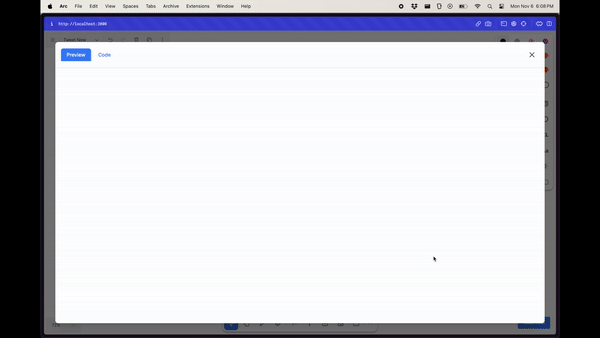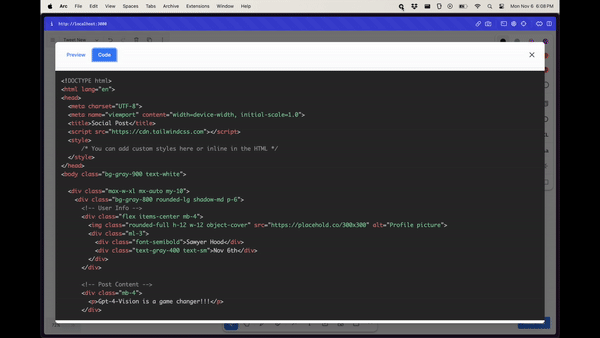
draw-a-ui
13.6KSawyerHood/draw-a-ui · TypeScriptAn app that lets you draw a UI wireframe on a canvas and uses GPT-4 Vision to generate a working HTML page (with Tailwind) based on the sketch.
- 13
chandra
12.5Kdatalab-to/chandra · PythonChandra OCR 2 is a state-of-the-art OCR model that converts images and PDFs into structured HTML, Markdown, or JSON while preserving the original layout. It handles complex tables, forms, handwriting, and math, and supports over 90 languages.
- 14
zerox
12.3Kgetomni-ai/zerox · TypeScriptZerox is an open-source OCR and document-extraction tool powered by vision models: give it a PDF, DOCX or image and it returns Markdown — or structured data if you provide a schema.
- 15
X-AnyLabeling
10.7KCVHub520/X-AnyLabeling · PythonA free cross-platform desktop app for AI-assisted annotation of text, image, video, and multimodal data — manual labeling tools plus built-in deep learning models that pre-label or batch-annotate, with multi-format export.
- 16

self-operating-computer
10.3KOthersideAI/self-operating-computer · PythonA framework that lets a multimodal AI model operate your computer: it views the screen and issues mouse and keyboard actions to reach the objective you give it. One of the first full computer-use projects (Nov 2023).
- 17
InternVL
10.2KOpenGVLab/InternVL · PythonA family of open-source multimodal chat models that understand images, video and text, positioned as an open alternative to GPT-4o. InternVL2.5-78B was the first open-source model to top 70% on the MMMU benchmark.
- 18
moondream
10.1Km87-labs/moondream · PythonMoondream is a tiny, open-source vision language model that understands images — captioning, visual question answering, and object detection — while being small enough to run almost anywhere.
- 19
Kimi-K3
8.9KMoonshotAI/Kimi-K3Kimi K3 is MoonshotAI's open-weight, native multimodal agentic model — a 2.8T-parameter Mixture-of-Experts system built for frontier-level long-horizon coding, agentic knowledge work, and reasoning.
- 20

GLM-OCR
7.5Kzai-org/GLM-OCR · PythonGLM-OCR is a multimodal OCR model for complex document understanding, built on a GLM-V encoder-decoder architecture with a lightweight SDK and inference toolchain around it.
- 21
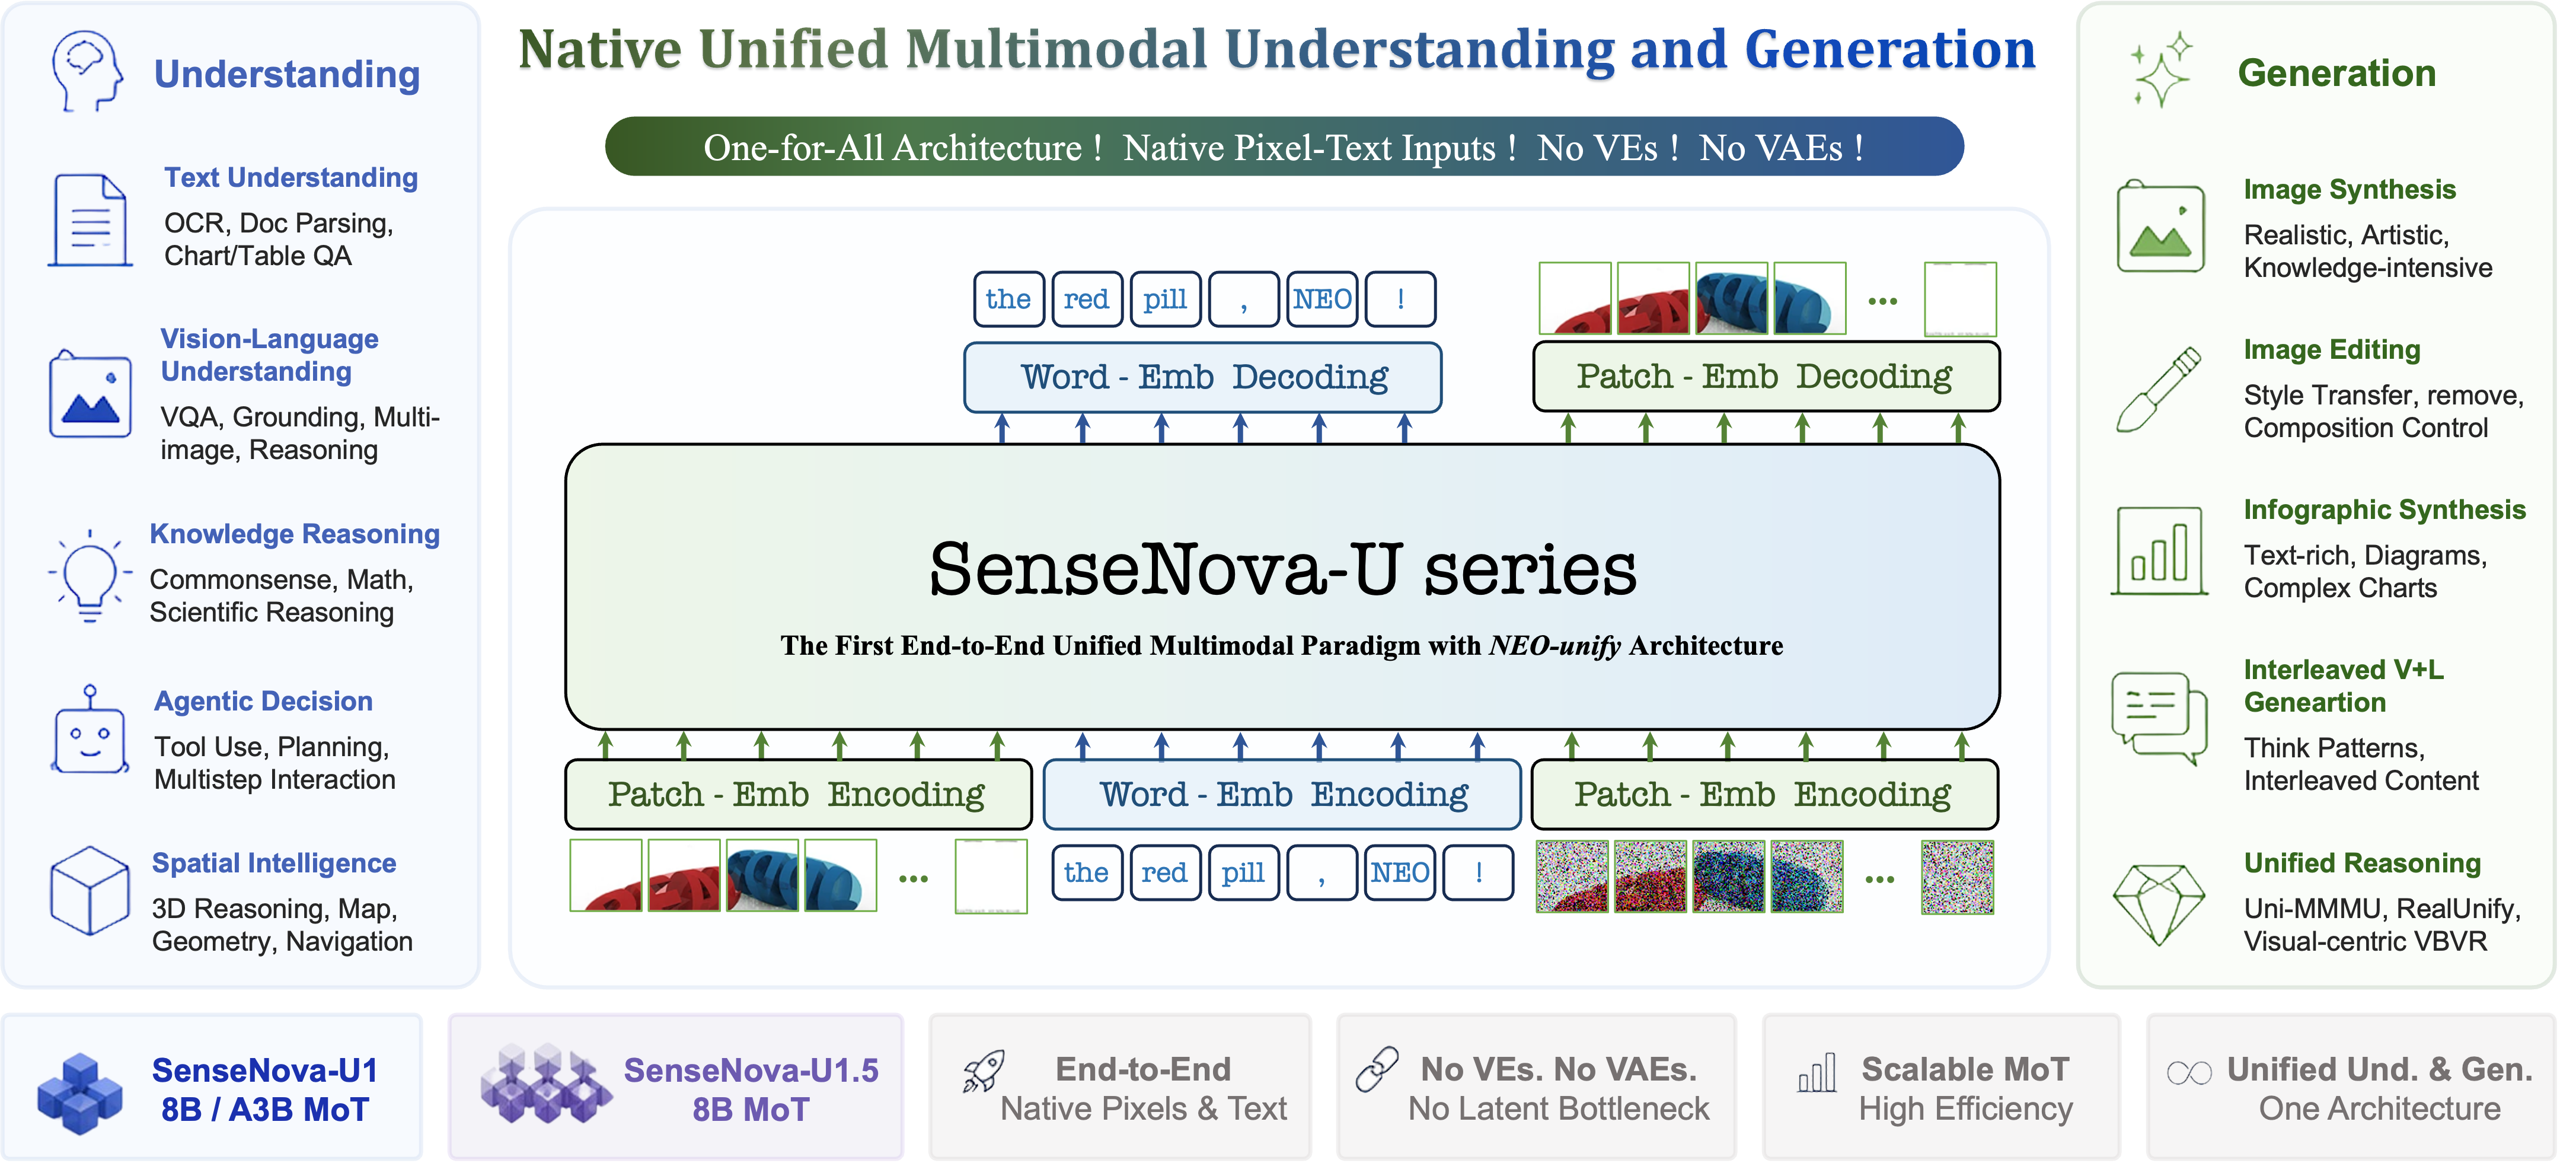
SenseNova-U1
6.9KOpenSenseNova/SenseNova-U1 · PythonOpen-source multimodal models that unify image understanding, reasoning and image generation in one architecture. The current release, SenseNova-U1.5-8B-MoT, creates and edits images up to native 4K.
- 22
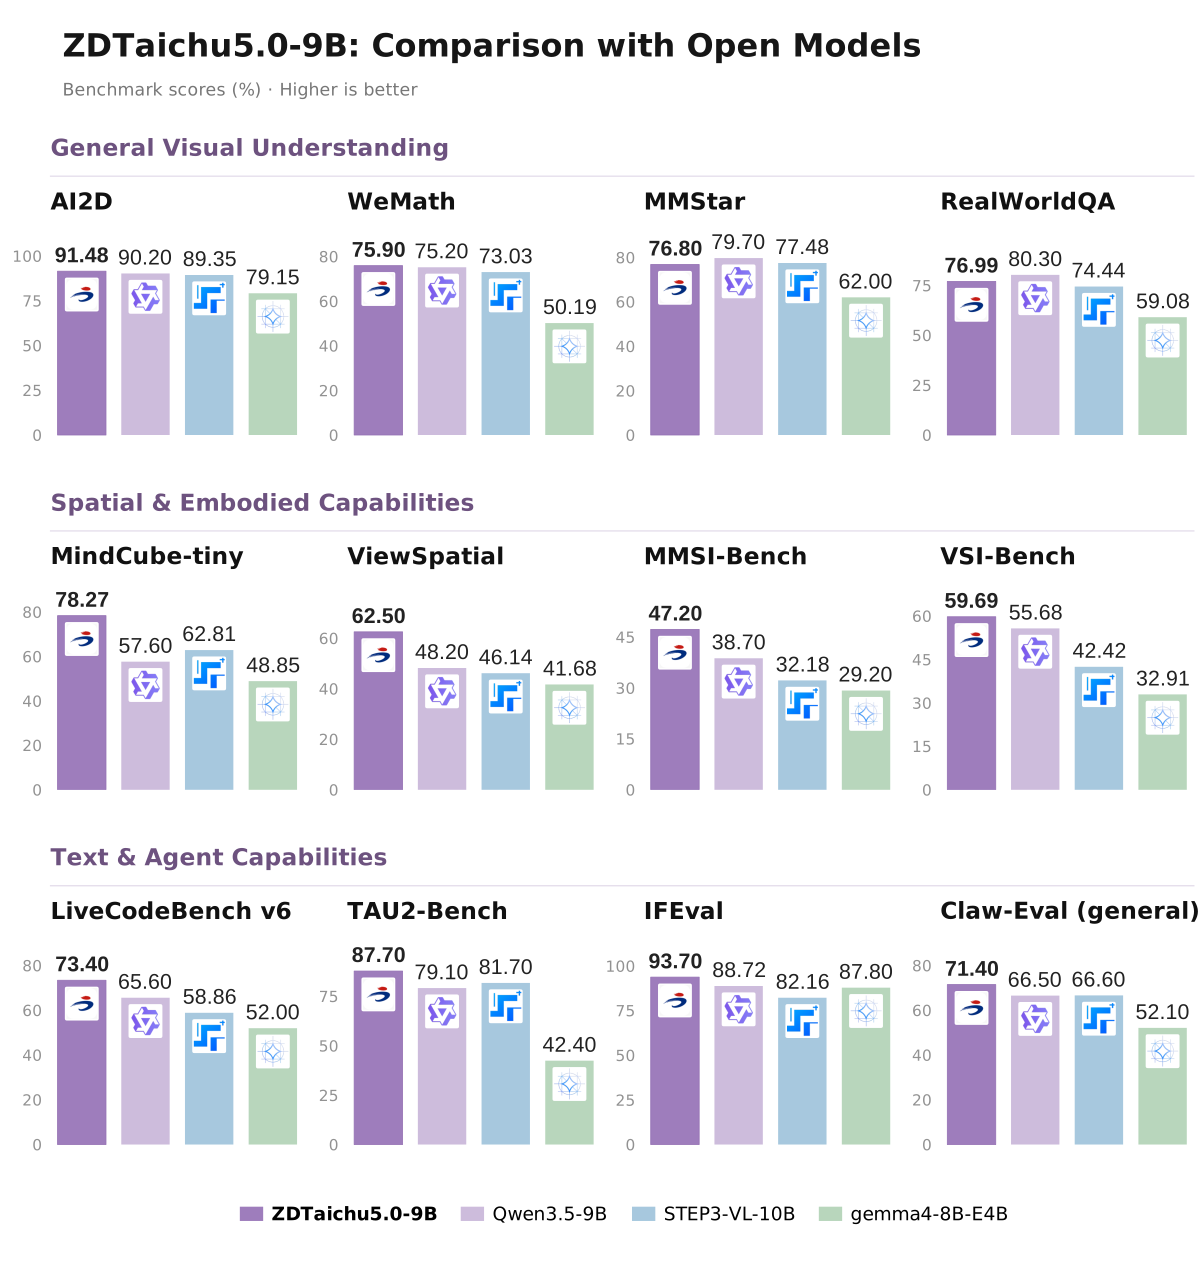
ZDTaichu5.0-9B
3.1KTaichu-AI/ZDTaichu5.0-9B · PythonZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 23
esp32-iphone-agent
2.9Konehumanbeing/esp32-iphone-agent · CThis project lets an AI vision model control a real iPhone, using AirPlay screen mirroring as its 'eyes' and a $7 ESP32-S3 board acting as a USB mouse and keyboard as its 'hands', with no Mac, Apple developer account, or jailbreak required.
- 24
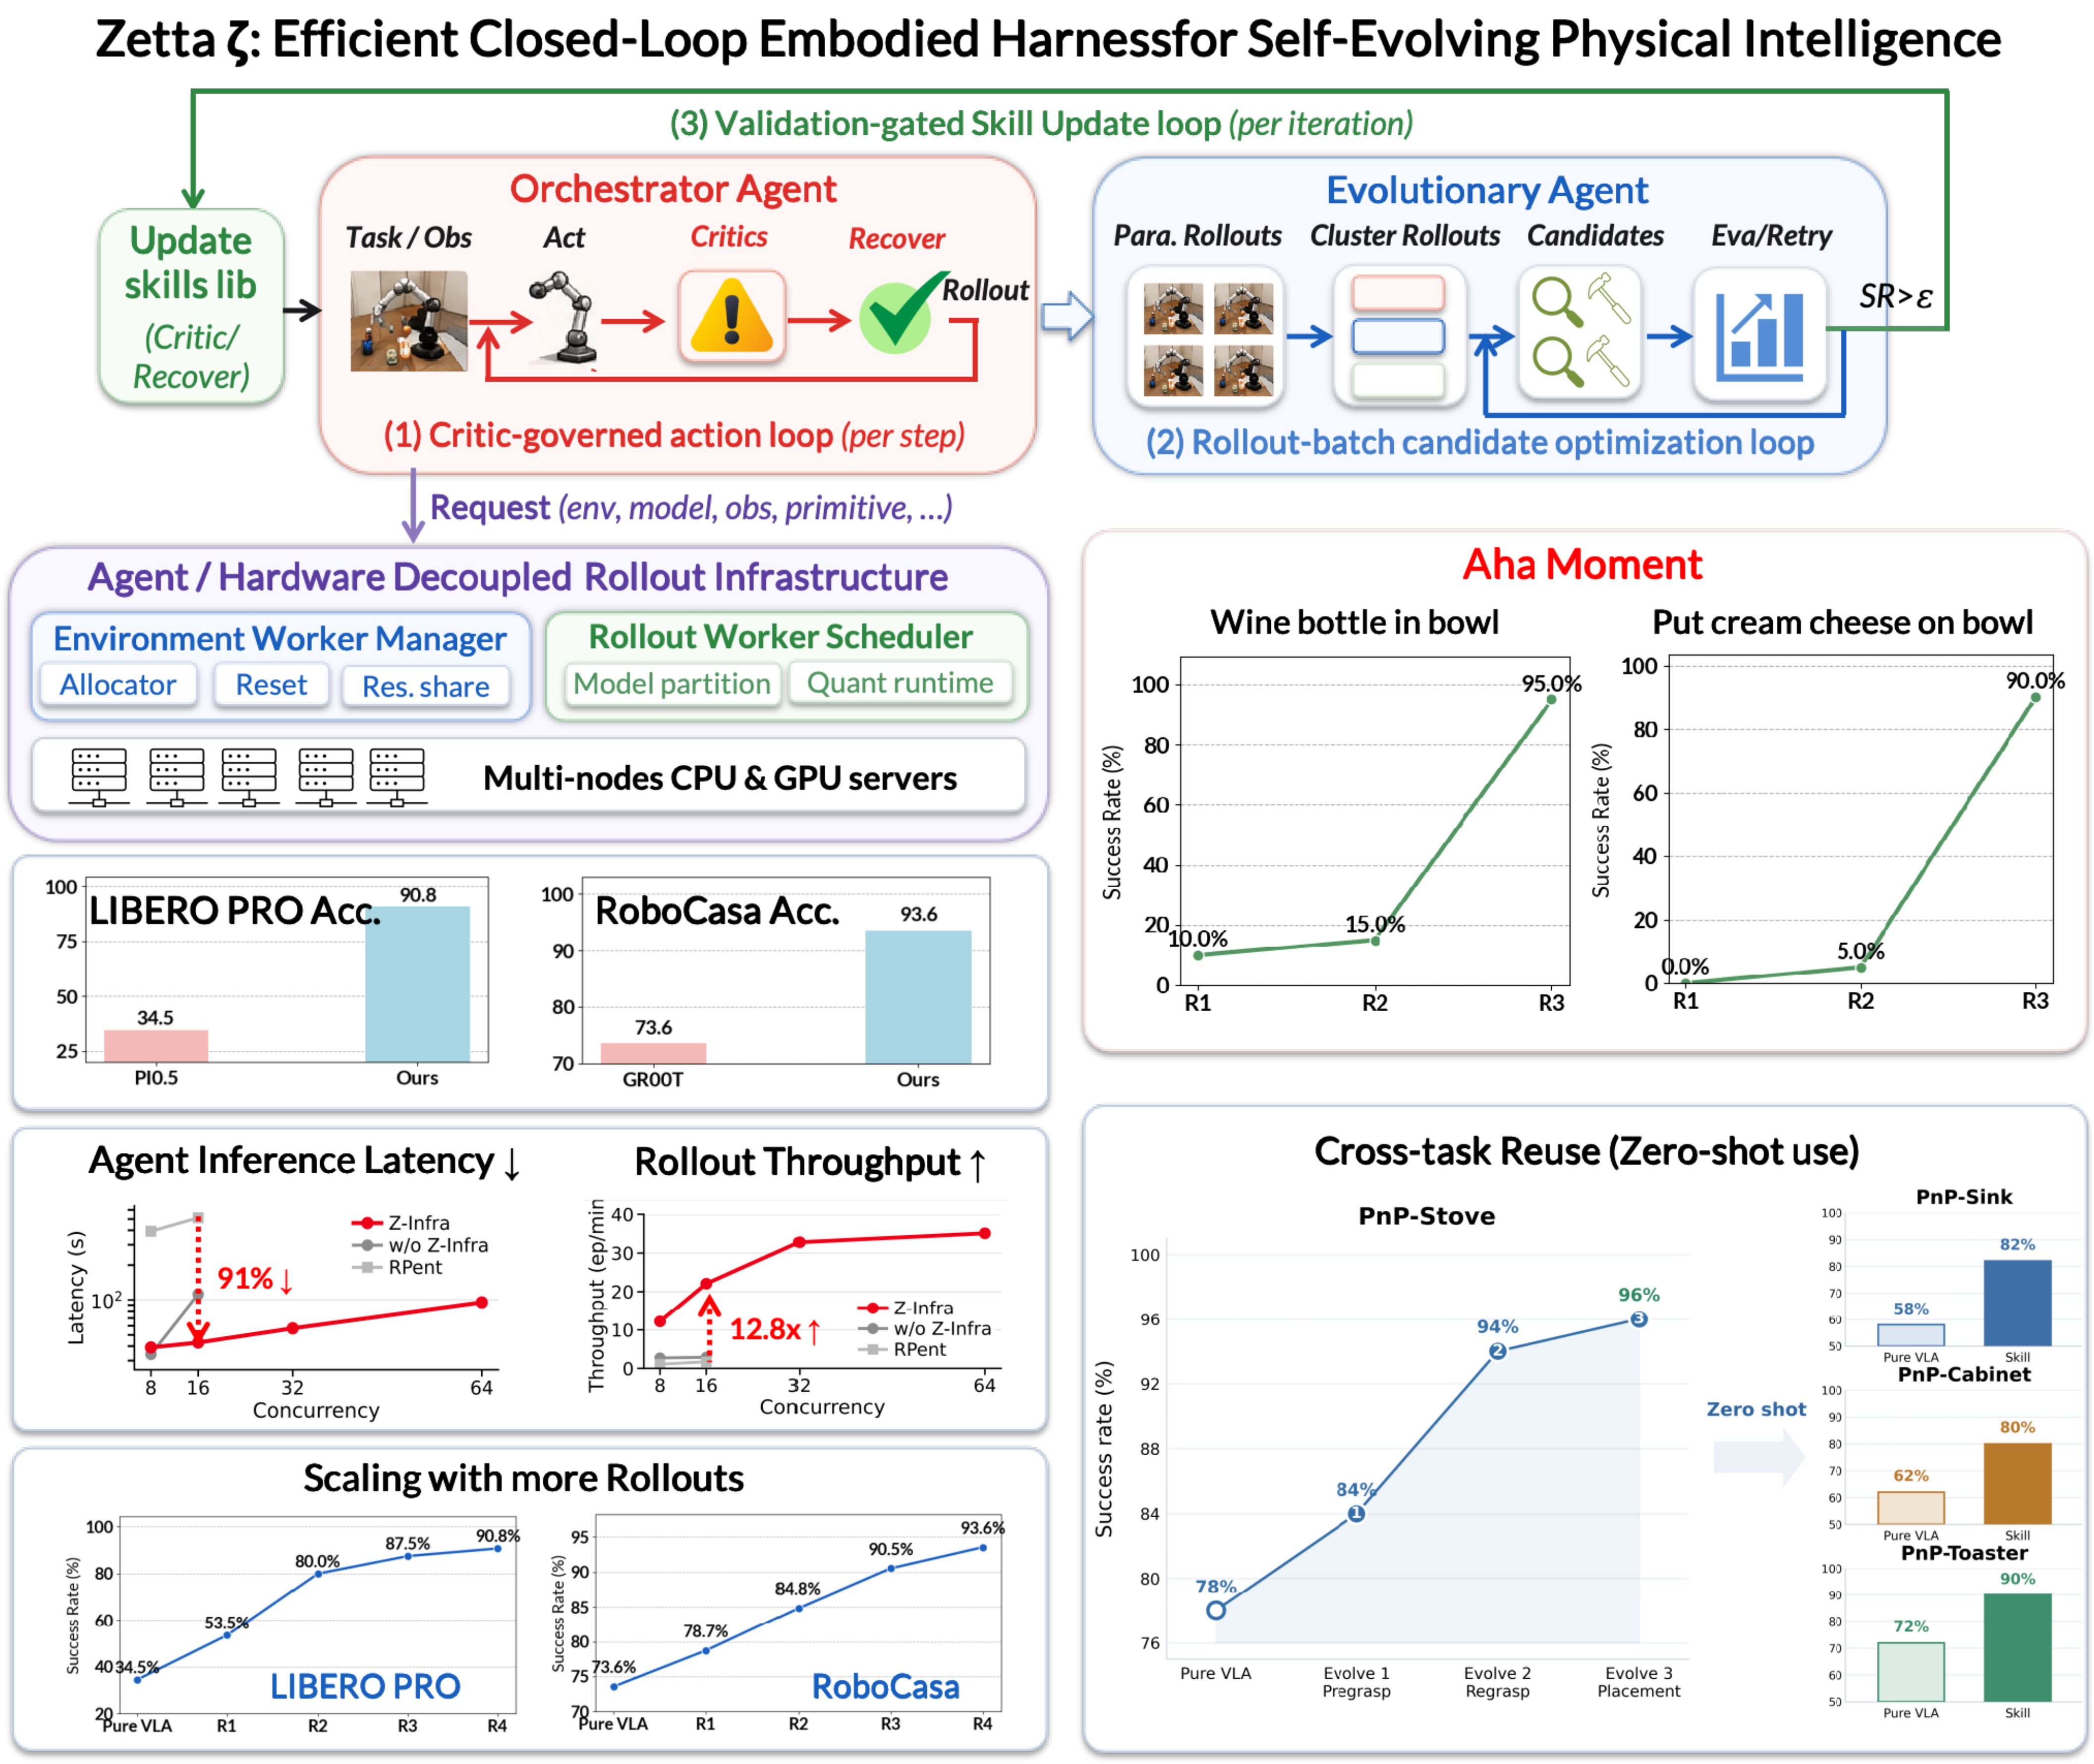
Zetta-Embodiment
1.3Kair-embodied-brain/Zetta-Embodiment · PythonZetta is a closed-loop embodied harness that evolves code-based runtime critics and recovery skills online while keeping the base robot policy frozen, reaching 90.8% success on LIBERO-Pro and 93.6% on RoboCasa with an 11.1x inference speedup.
- 25
OpenWAM
1KOpenWAM-Official/OpenWAM · PythonOpenWAM is an open research stack for systematically building World-Action Models (WAMs) for robots, breaking the usual tightly-coupled design choices into modular, swappable components you can compare in controlled experiments.
- 26
dsh-vision-toolkit
896Anionex/dsh-vision-toolkit · TypeScriptDSH Vision Toolkit is a plugin for DeepSeek Harness (DSH) that gives text-only AI models 'eyes': paste or reference an image and the agent can answer questions about it, OCR long screenshots, rebuild a UI from a mockup, locate elements, crop, vectorize, or diff pixels.
- 27
Intern-Decision
811InternLM/Intern-Decision · PythonIntern-Decision turns a state, optional images, and multiple typed questions into decisions with probabilities, by fine-tuning the language backbone of Qwen3.5 while freezing its vision tower and projector.
- 28
FluxVLA
748FluxVLA/FluxVLA · PythonFluxVLA is a full-stack engineering platform for embodied AI covering the whole loop from data to real-robot deployment for vision-language-action (VLA) models, built to lower the engineering barrier for VLA research and development.
- 29
LightNav-0
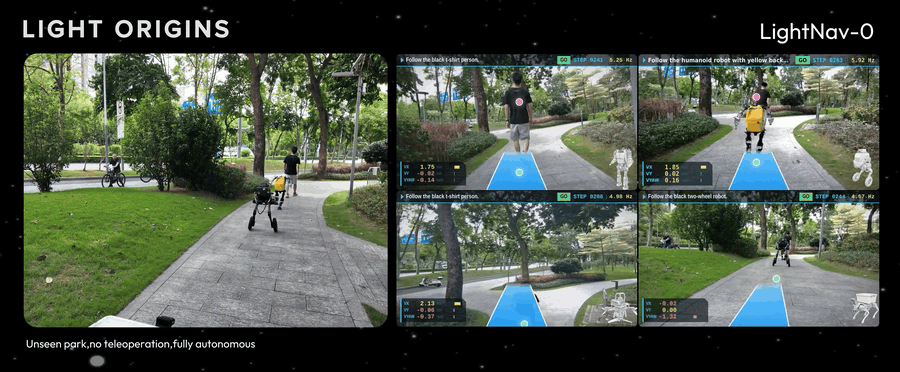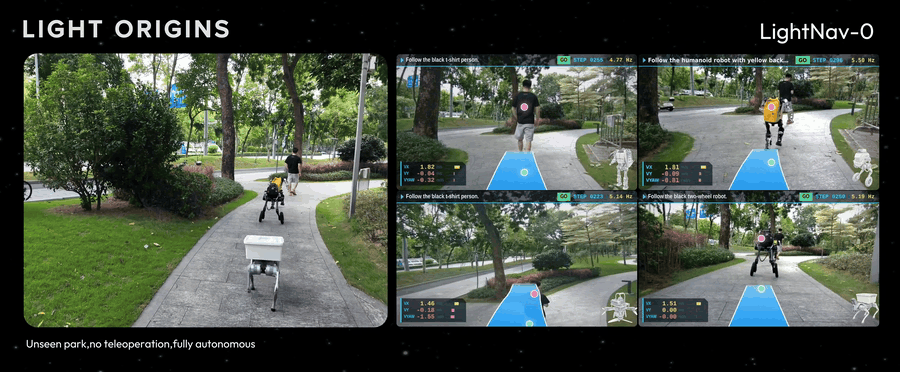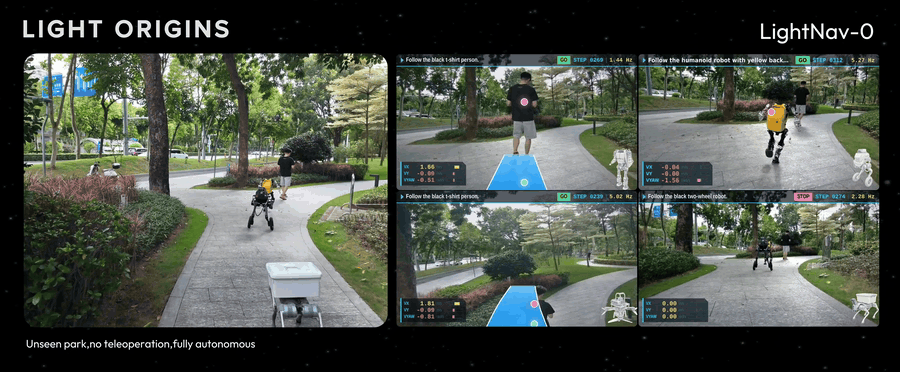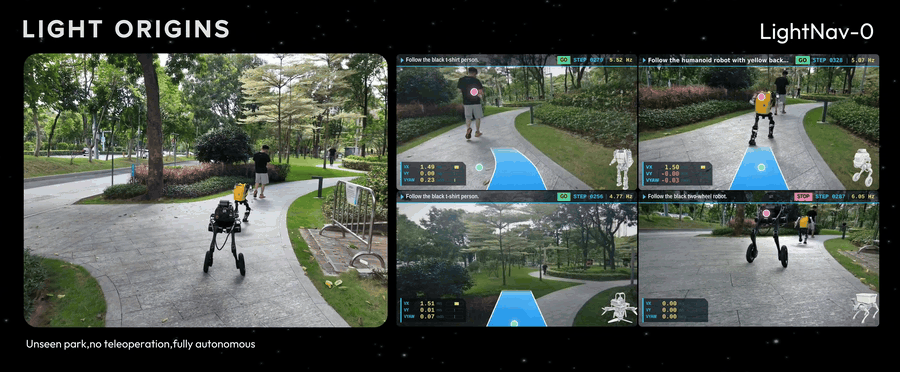
721lightorigins/LightNav-0 · PythonLightNav-0 is a compact generalist embodied navigation model that gives humanoid, quadruped, wheeled and aerial robots the ability to follow language instructions and navigate autonomously in unseen environments, without any teleoperation.
- 30

kaggle-tpu-lab
657ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 31

Qwen3.8-Flash-Next-Single-DGX-Spark
609MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark · PythonA self-contained recipe for serving the Qwen3.8-Flash-Next-NVFP4 checkpoint from a single NVIDIA DGX Spark machine's unified memory, using vLLM with the PLE table offloaded and memory-mapped.
- 32
ParseBench
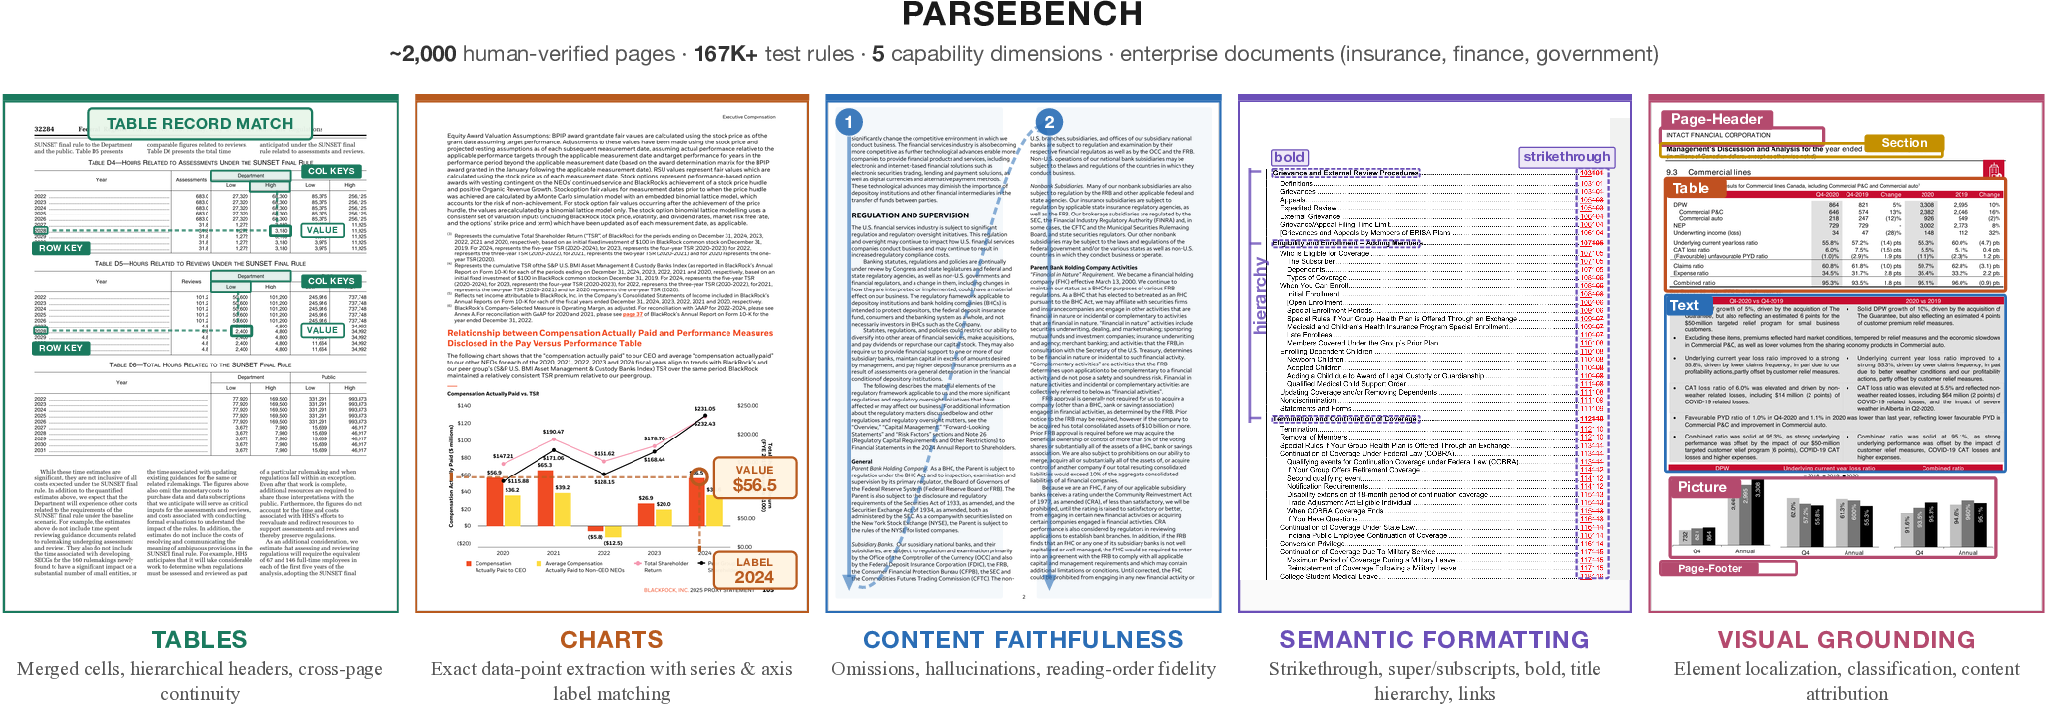
602run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 33

Omni-Interaction-Agent
565Omni-Interaction-Gander/Omni-Interaction-Agent · PythonGander is an open-source, end-to-end omni interaction agent that combines natural full-duplex voice chat, continuous audio-visual perception, and long-horizon agentic task execution in one system.
- 34
Qwen-Drive-1.0
515QwenLM/Qwen-Drive-1.0 · PythonQwen-Drive-1.0 is a vision-language foundation model for autonomous driving, built on the Qwen3.5-4B VLM and extended with 3D perception, visual question answering, and motion planning in one unified model.
- 35
SCM
486allenv0/SCM · TypeScriptSCM (Screen Memories) is a macOS desktop app that runs deep AI search locally over every photo and every video frame in a chosen folder, letting you search by meaning, on-screen text, or spoken dialogue, all without the cloud.
- 36

LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
- 37
GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold
444MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold · PythonThis project serves the GLM-5.3-Flash language model as an OpenAI-compatible API, with vision and video input, running across two linked NVIDIA DGX Spark machines (GB10, 128GB each) using TensorFold.
- 38
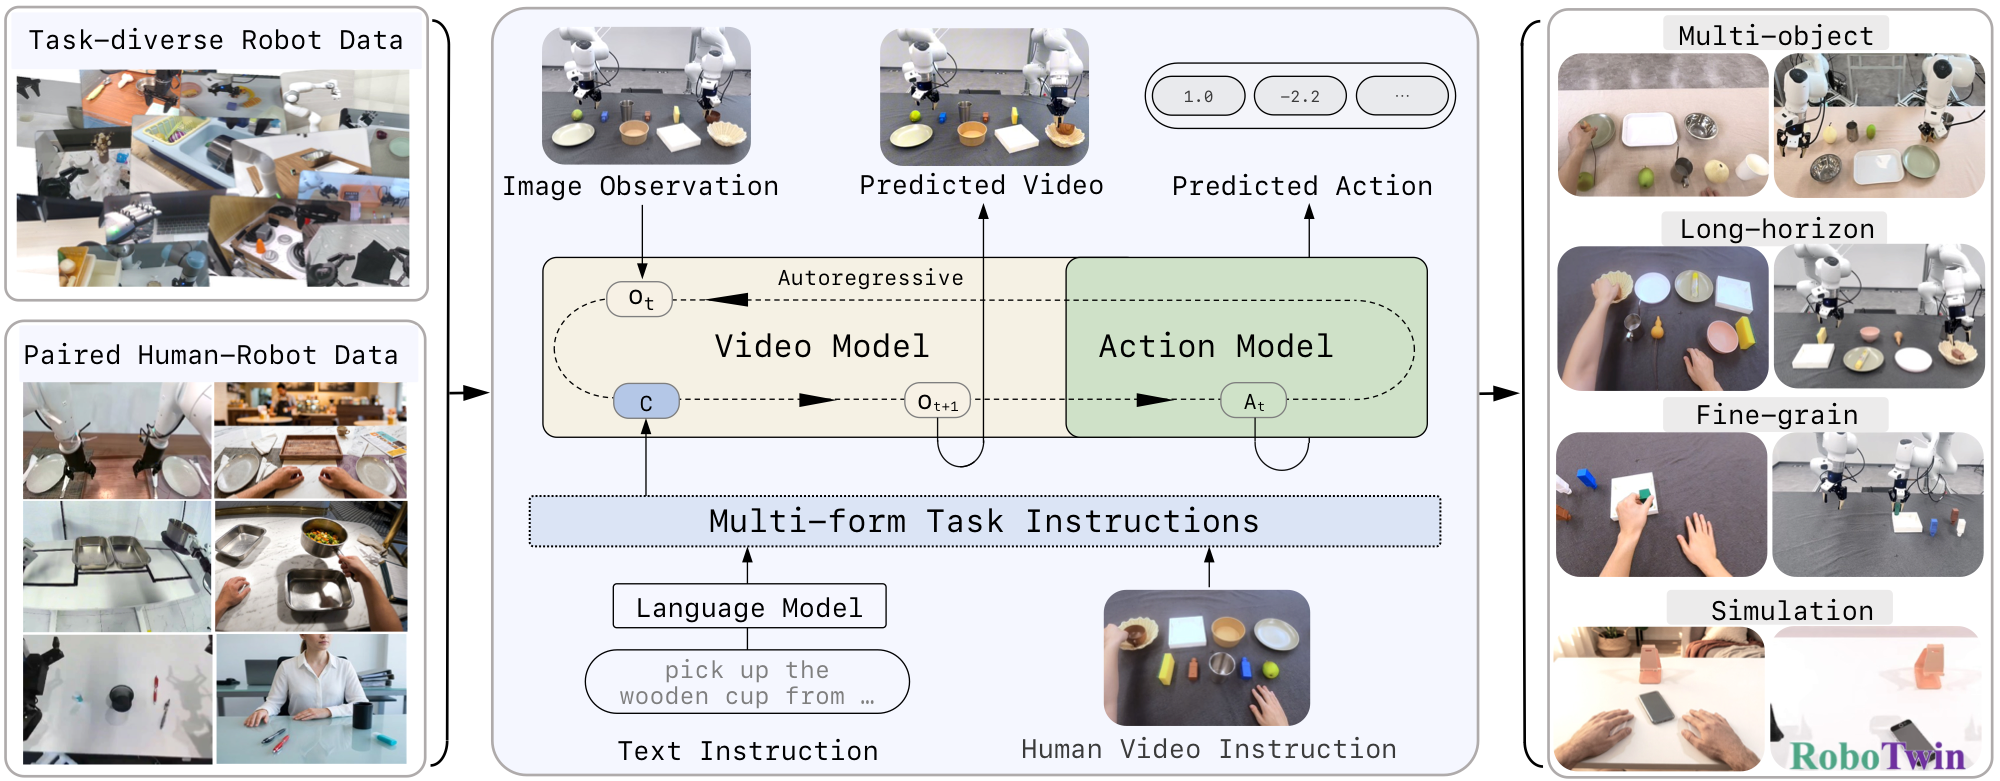
Zero-WAM
434robbyant-research/Zero-WAM · PythonZero-WAM is a research method for zero-shot cross-task robotic manipulation: a causal video-action policy that learns in-context world-action modeling, predicting future robot observations and executable actions from either language instructions or human demonstration videos.
- 39
TeleOCR
343caipeng328/TeleOCR · PythonTeleOCR is a lightweight (~1.2B parameter) open-source Vision-Language Model built specifically for document parsing, handling both regular digital documents and messy camera-captured photos with a single unified model.
- 40

Nex-N2.5
267nex-agi/Nex-N2.5Nex-N2.5 is a family of open-weight agentic large language models (mini, Pro, Max) from Nex-AGI built for long-horizon tasks like computer use, web browsing, and autonomous coding, with Max built on a 1.6-trillion-parameter Mixture-of-Experts foundation.
- 41
VideoHighlighter
212Aseiel/VideoHighlighter · PythonA free, open-source desktop app that finds and explains the strong moments in your footage, then exports a highlight reel and clips — an offline alternative to Twelve Labs, Runway and Descript.
- 42
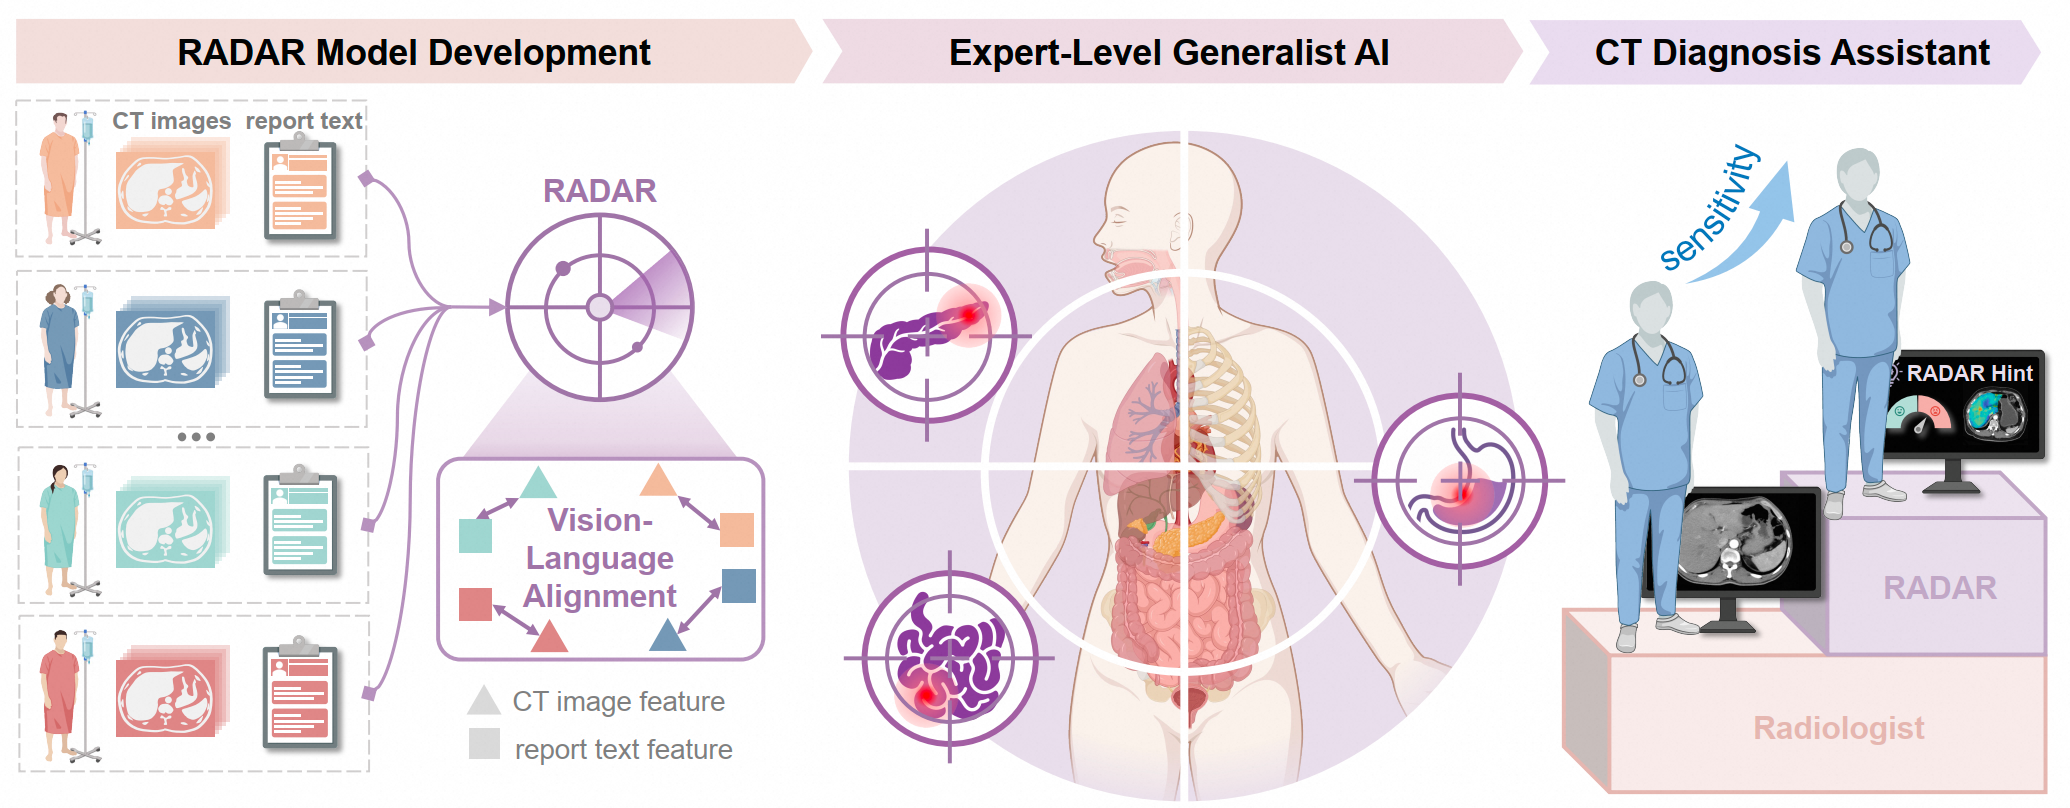
damo-radar
206alibaba-damo-academy/damo-radar · PythonRADAR is a generalist vision-language AI model for abdominal CT diagnosis, trained on over 400,000 contrast-enhanced abdominal CT exams with 15 million anatomy-aware image-text pairs derived directly from clinical reports.
- 43
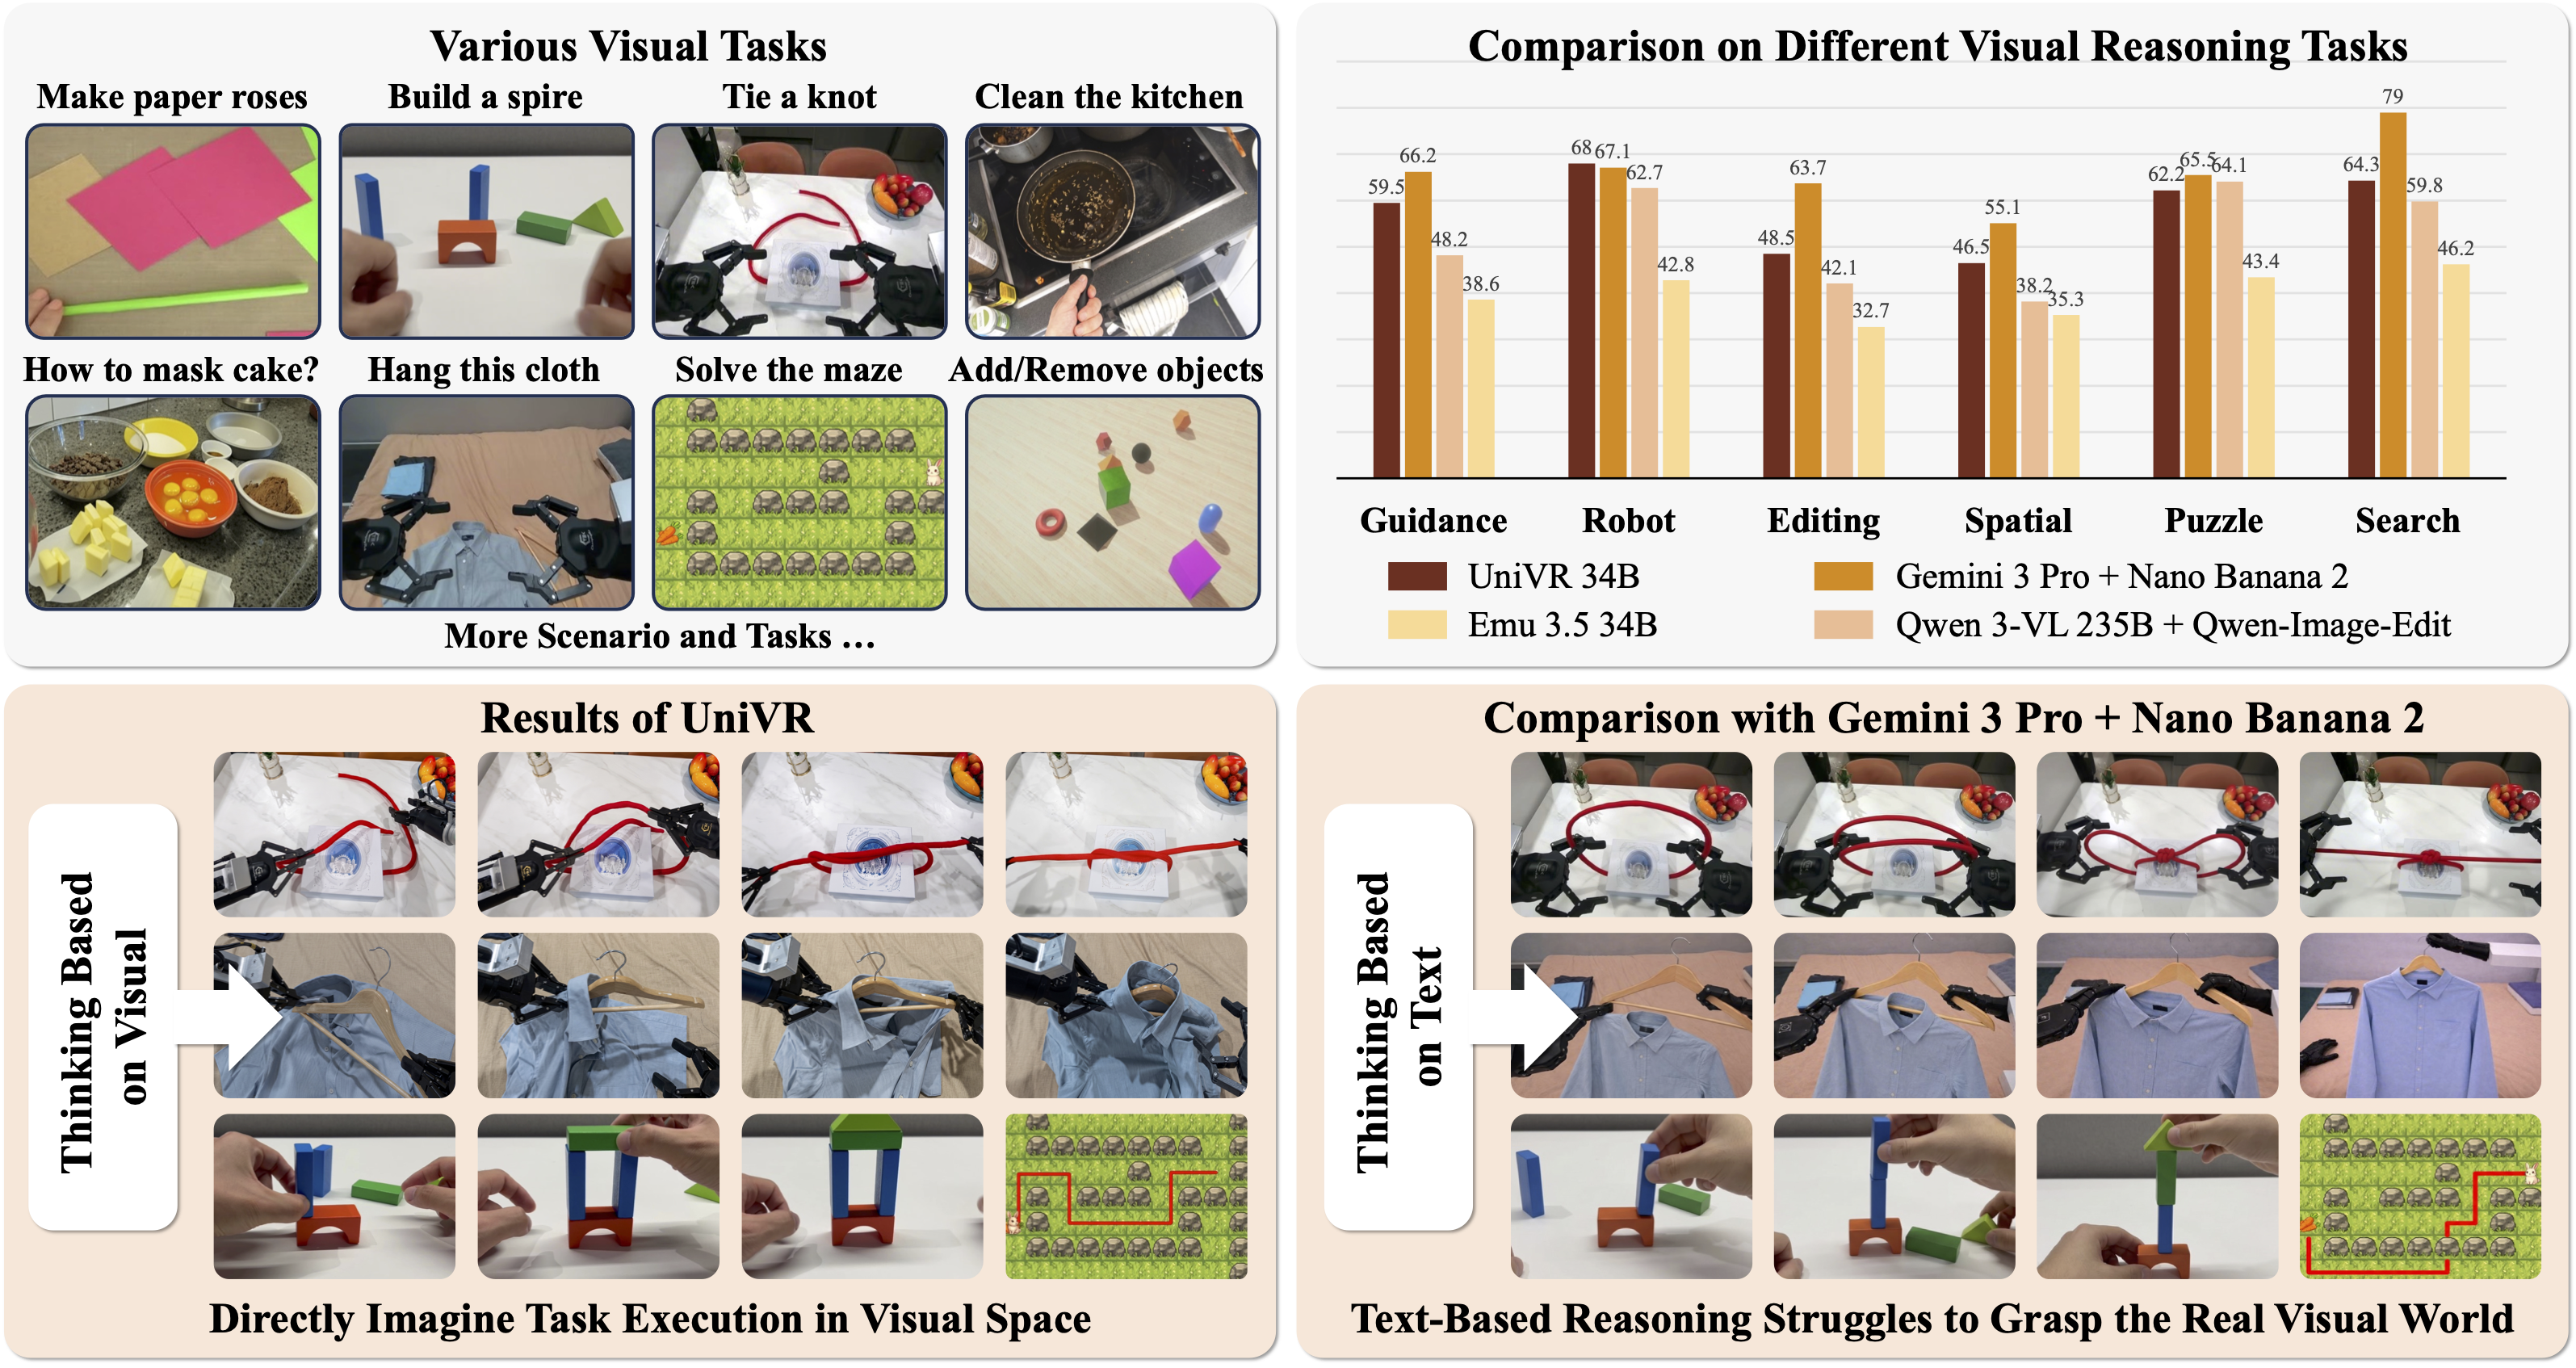
UniVR
178FlagOpen/UniVR · PythonUniVR is an end-to-end SFT and Reinforcement Learning (GRPO) training framework built specifically for Emu3.5 series unified generative models, letting you train visual reasoning tasks by swapping in your own data loader and reward function.
- 44
S-Space
174MirroS-Lab/S-Space · PythonS-Space is a research project that finds a three-dimensional linear subspace inside multimodal model activations which encodes object positions along horizontal, vertical, and distance axes, and shows it can be read out and even causally edited to change the model's spatial judgments.
- 45
OraRL
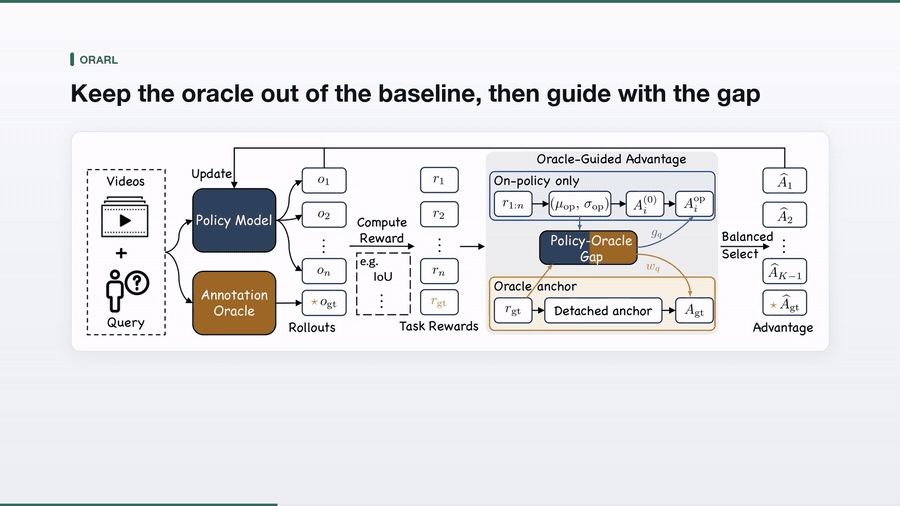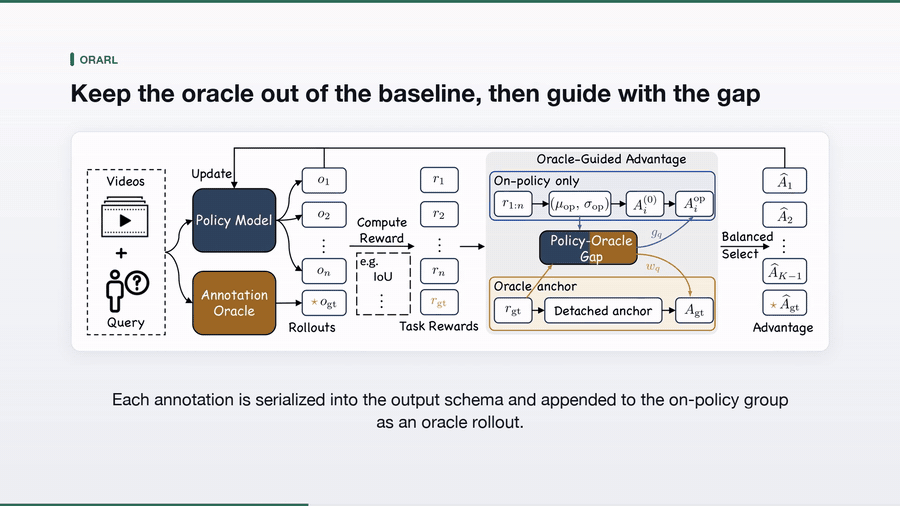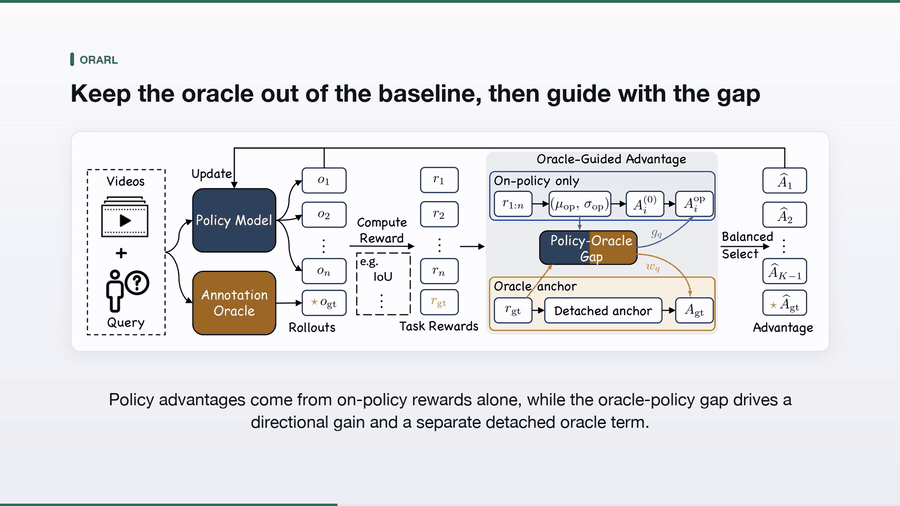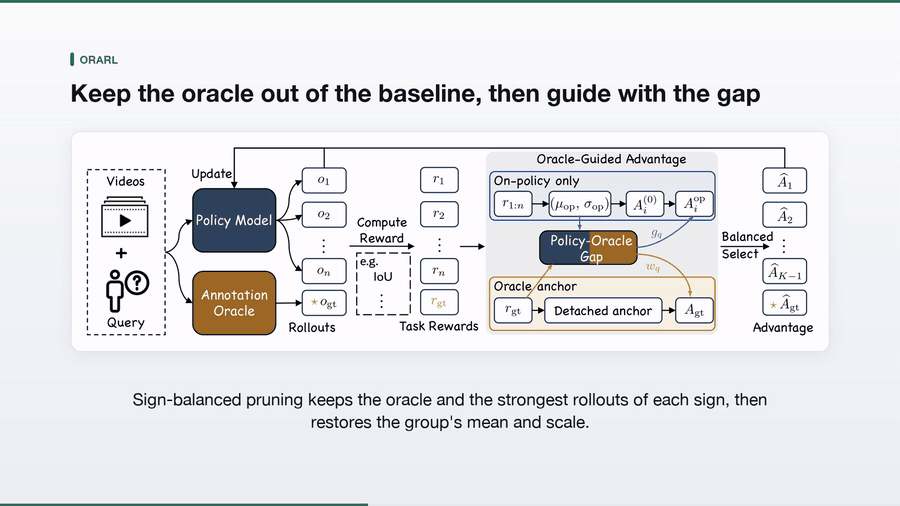
166HVision-NKU/OraRL · PythonOraRL is a reinforcement learning framework that treats annotations as rollouts to efficiently train unified video multimodal LLMs (MLLMs) across seven video task families.
Related topics
Often tagged together