Topics / #llama-cpp
Llama-cpp projects on GitHub
Runtime for quantized local inference of large language models on CPUs and laptops.
As of , the most-starred Llama-cpp projects on GitHub are gpt4all (77.4K stars), minimind (63.9K stars) and textgen (47.7K stars). GitHub.Locker tracks 37 Llama-cpp repositories with 543.4K stars combined. The fastest-growing on October 16 was Strata, with +718 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +718
Strata
Niko1221/Strata · ★ 26.4KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +215
DigUp
ARahim3/DigUp · ★ 4.3KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
 +179
PS5LM
cobanov/PS5LM · ★ 337llama.cpp on a jailbroken PS5: run any GGUF model natively on the console, starting with Qwen 3.8
 +150
StartLux-Decision
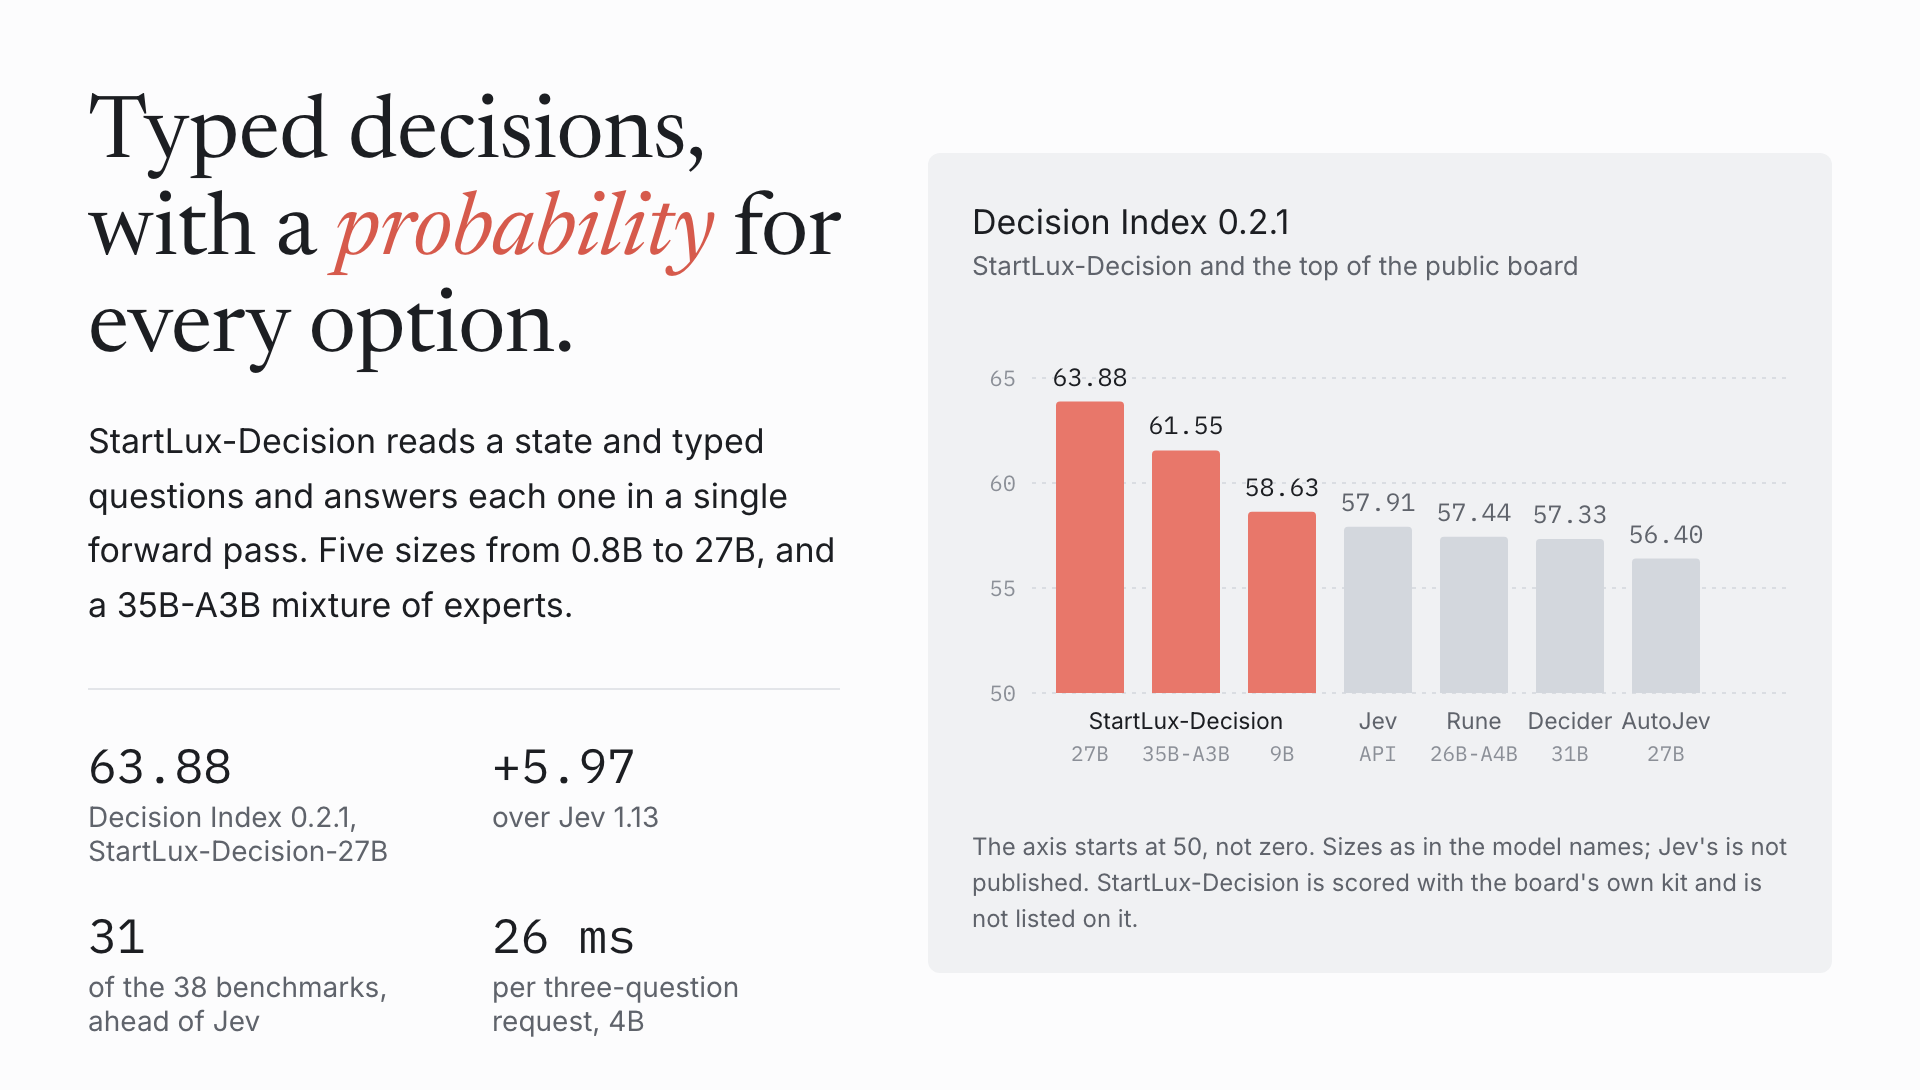
StartLuxLabs/StartLux-Decision · ★ 552StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
The all-time top
37 projects · by stars
- 77.4K
 #1 · nomic-ai/gpt4all
gpt4all
GPT4All is a desktop application that runs large language models privately on everyday laptops and desktops, with no API calls or GPU required.
- 63.9K
 #2 · jingyaogong/minimind
minimind
MiniMind is an open-source project that lets you train a tiny large language model (around 64M parameters) completely from scratch, in about 2 hours on a single RTX 3090 for roughly the cost of 3 RMB in GPU rental.
- 47.7K
 #3 · oobabooga/textgen
textgen
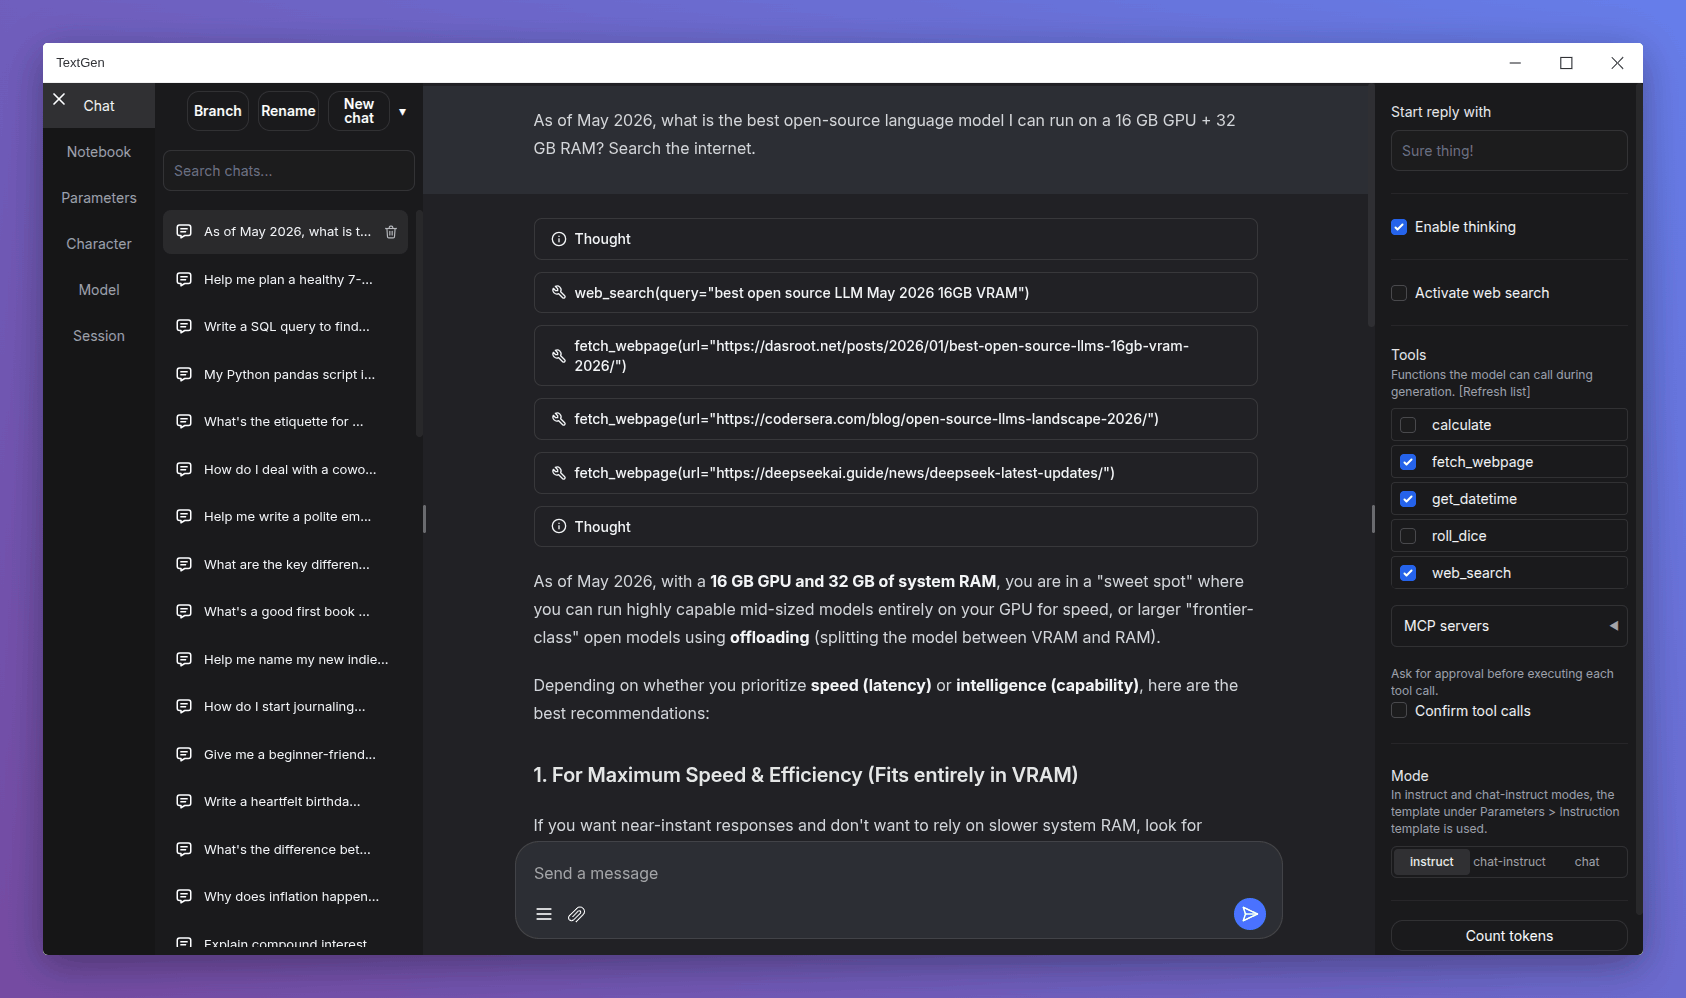
TextGen is an open-source desktop app for running local LLMs with text, vision, tool-calling, and an OpenAI/Anthropic-compatible API, built to be 100% private with no telemetry.
- 4
VoxCPM
39.4KOpenBMB/VoxCPM · PythonVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
- 5

llmfit
38KAlexsJones/llmfit · Rustllmfit inspects your CPU, RAM, GPU(s), VRAM, and accelerator setup, then tells you which open-source LLMs and quantizations will actually run well on your machine.
- 6

qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 7

MiniCPM-V
26.8KOpenBMB/MiniCPM-V · PythonA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 8
Strata
26.4KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 9
llamafile
26.4Kmozilla-ai/llamafile · C++llamafile turns open LLMs into single-file executables: one file that runs a chat model locally on most operating systems and CPU architectures, with no installation. It is a Mozilla Builders project, now revamped by Mozilla.ai.
- 10

guidance
21.8Kguidance-ai/guidance · Jupyter NotebookGuidance is a Python library — an efficient programming paradigm for steering large language models: you control how output is structured while reducing latency and cost compared with conventional prompting or fine-tuning.
- 11
FunASR
20.7Kmodelscope/FunASR · PythonFunASR is an open-source industrial speech recognition toolkit covering ASR, VAD, punctuation, speaker diarization, and emotion/audio-event models, deployable offline, in streaming mode, on edge devices, or behind an OpenAI-compatible API.
- 12
DB-GPT
20.2Keosphoros-ai/DB-GPT · PythonAn open-source agentic AI data assistant: connect databases, files or knowledge bases, ask questions in plain language, and the AI writes SQL and code, runs the analysis, and produces charts, dashboards and reports.
- 13
Llama-Chinese
14.8KLlamaChinese/Llama-Chinese · PythonLlama-Chinese is a Chinese-language community project built around Meta's Llama models (Llama2, Llama3, Llama4). It provides Chinese pretraining and fine-tuning, a custom Atom model series optimized for Chinese, and resources for training, deploying and using Llama in Chinese for free commercial use.
- 14

FluidVoice
12.2Kaltic-dev/FluidVoice · SwiftFluidVoice is an open-source voice-to-text dictation app for macOS that transcribes speech on-device and can enhance the text with AI, acting as a local alternative to Wispr Flow.
- 15

G0DM0D3
11.8Kelder-plinius/G0DM0D3 · TypeScriptG0DM0D3 is an open-source, privacy-transparent multi-model chat interface built to push past standard AI guardrails for red teaming, cognition research, and jailbreak experimentation.
- 16
llama-gpt
10.9Kgetumbrel/llama-gpt · TypeScriptLlamaGPT is a self-hosted, offline, ChatGPT-like chatbot powered by Llama 2 (and now Code Llama), so you get a familiar chat UI without sending any data to a third-party cloud.
- 17

Operit
8.7KAAswordman/Operit · KotlinOperit is an open-source AI agent platform for Android that connects cloud or local AI models to your phone's system, terminal, browser, files, and project workspaces so the AI can actually perform tasks like file management, coding, and device automation.
- 18
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 19
ODS
7.6KOsmantic/ODS · PythonODS (Osmantic Deployment System) turns your PC, Mac, or Linux box into a private AI server by installing and wiring together local LLM inference, a chat UI, agents, voice, RAG, image generation, and privacy tools in one go.
- 20

openplayground
6.3Knat/openplayground · TypeScriptopenplayground is a self-hosted LLM playground you run on your laptop: a web UI for trying out, tuning, and comparing models from many different providers.
- 21
SemIf-OpenJev
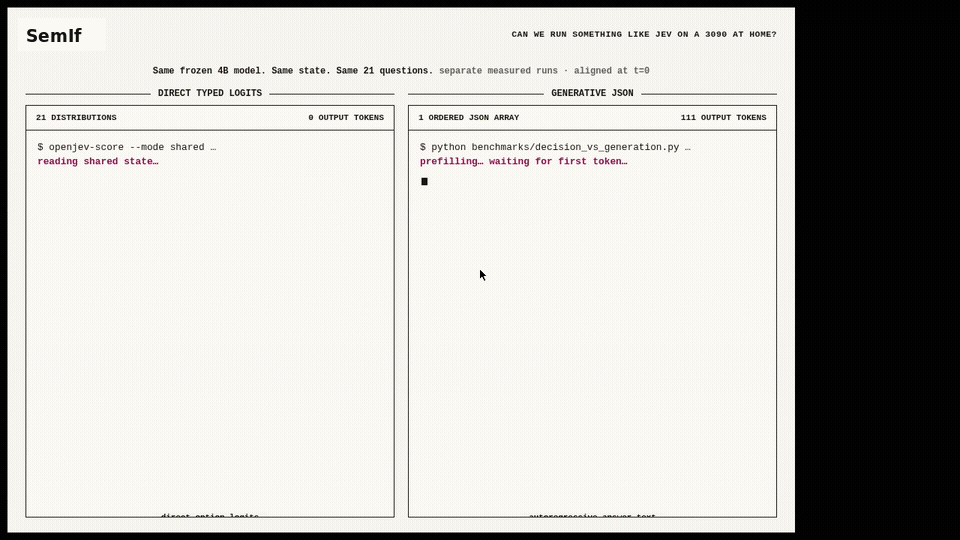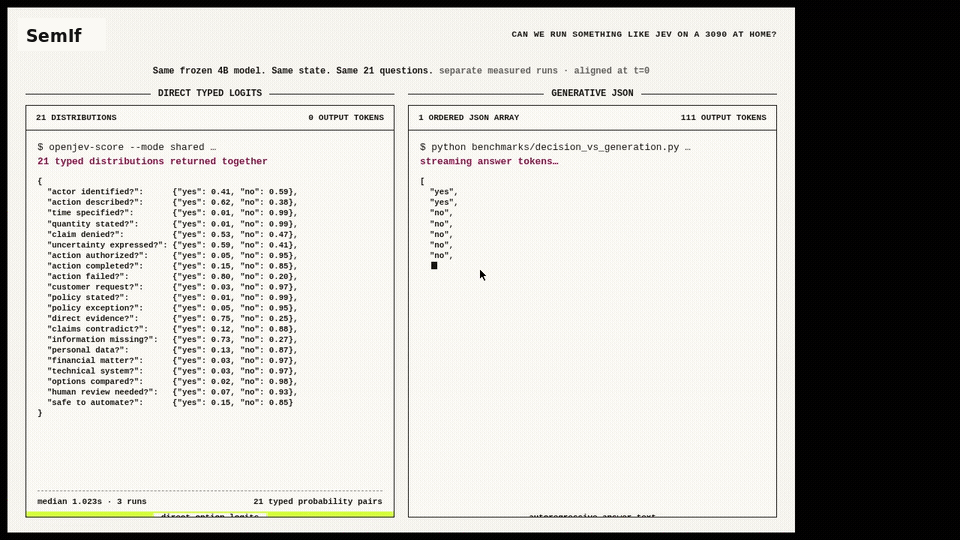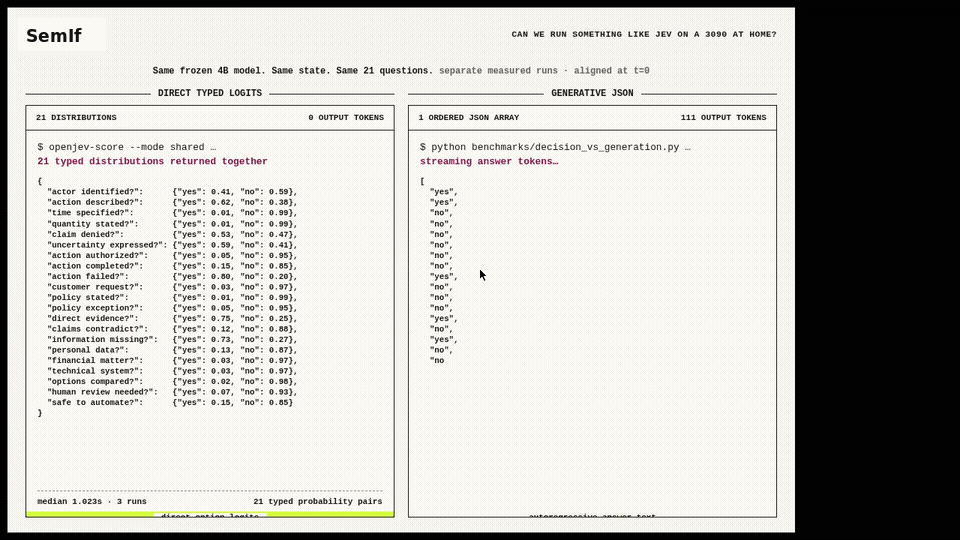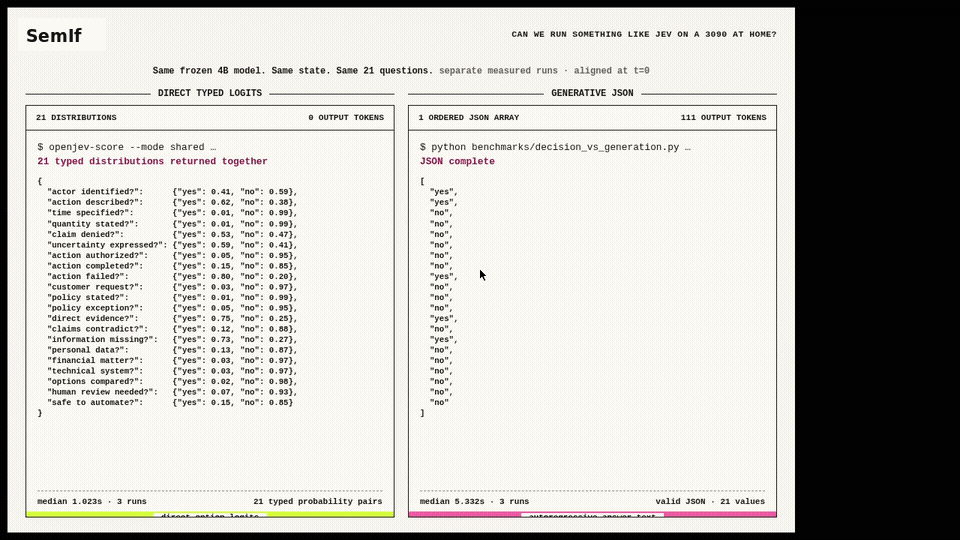
4.8KTheoLeeCJ/SemIf-OpenJev · PythonSemIf (formerly OpenJev) is an independent research project that runs runtime-defined semantic decisions with open models on one consumer GPU, mirroring the interface of TypeSafe's closed Jev service but not its undisclosed model.
- 22
DigUp
4.3KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 23

atomic-agent
3.4KAtomicBot-ai/atomic-agent · TypeScriptAtomic Agent is a local-first AI agent that runs the full control loop and all its state on your own machine, using open-weight models through llama.cpp or cloud models. It can browse the web, edit files, run approved shell commands, inspect documents, and remember context across sessions.
- 24
mlx-serve
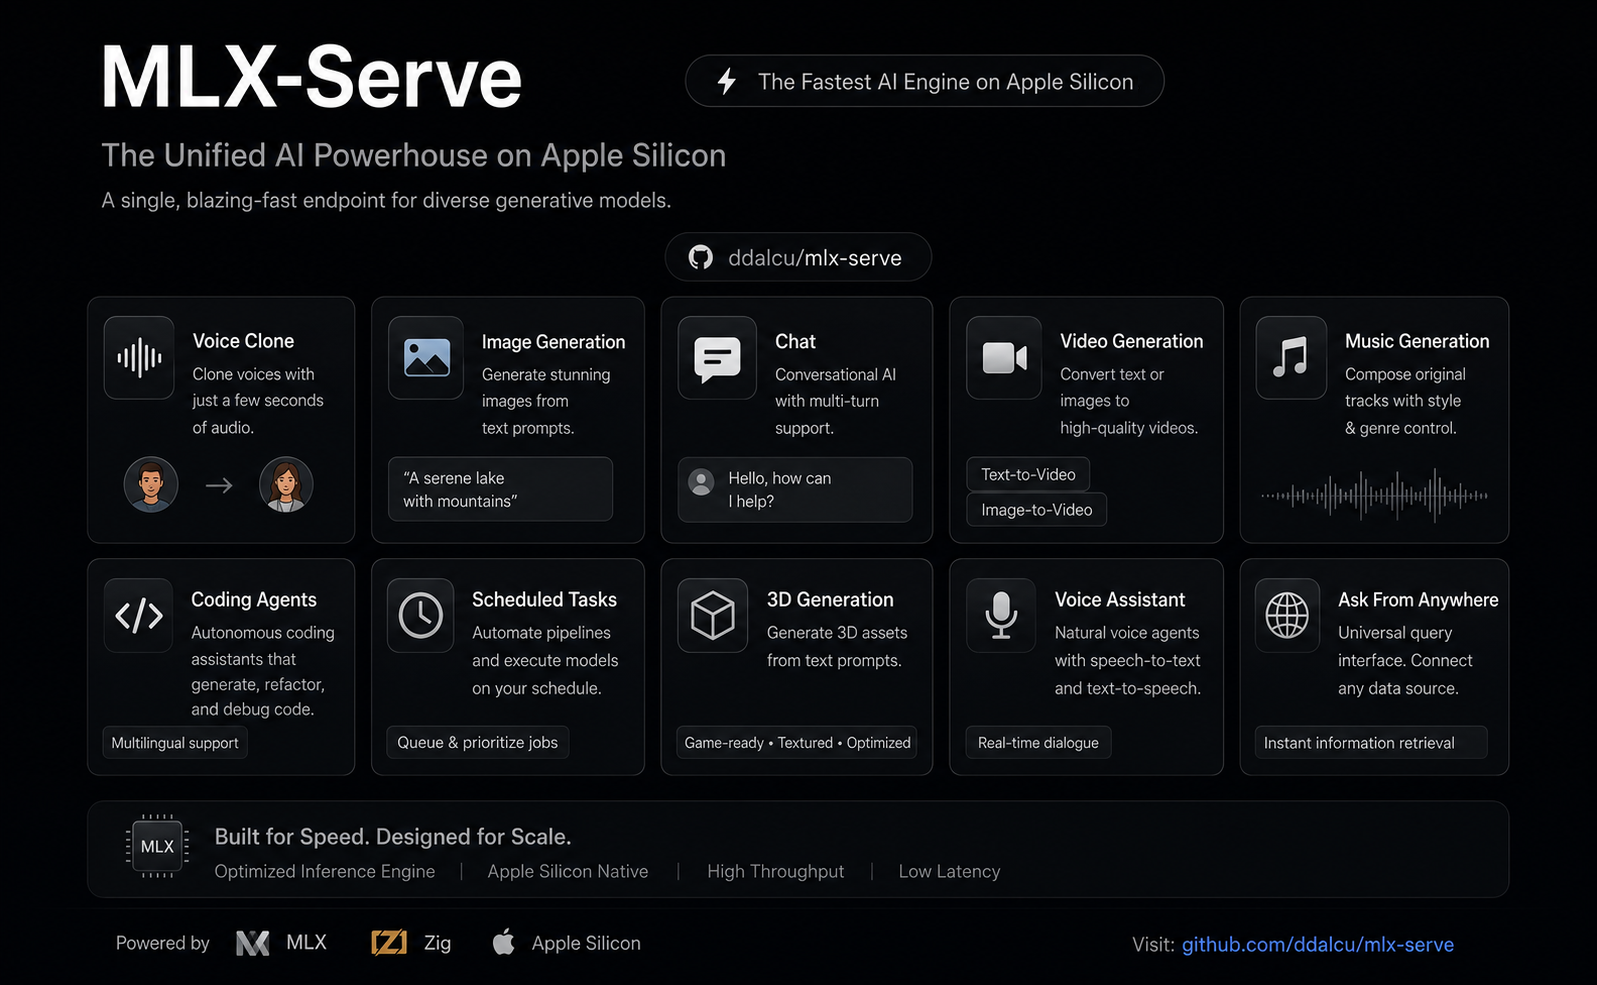
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 25
nobodywho
1.6Knobodywho-ooo/nobodywho · RustNobodyWho is an open-source inference engine that runs LLMs locally and offline on phones, desktops and even Apple Watch — no API keys, no cloud calls. Under the hood it is powered by llama.cpp and accelerates through the GPU via Vulkan or Metal.
- 26
jev
1.3Kfeder-cr/jev · C++jevos-1b is a free, open-source yes/no decision engine that runs locally on your laptop's CPU, returning the probability that the answer is 'yes' for a given text plus question in about 50-220 ms, as a self-hosted alternative to the cloud-based Jev service.
- 27
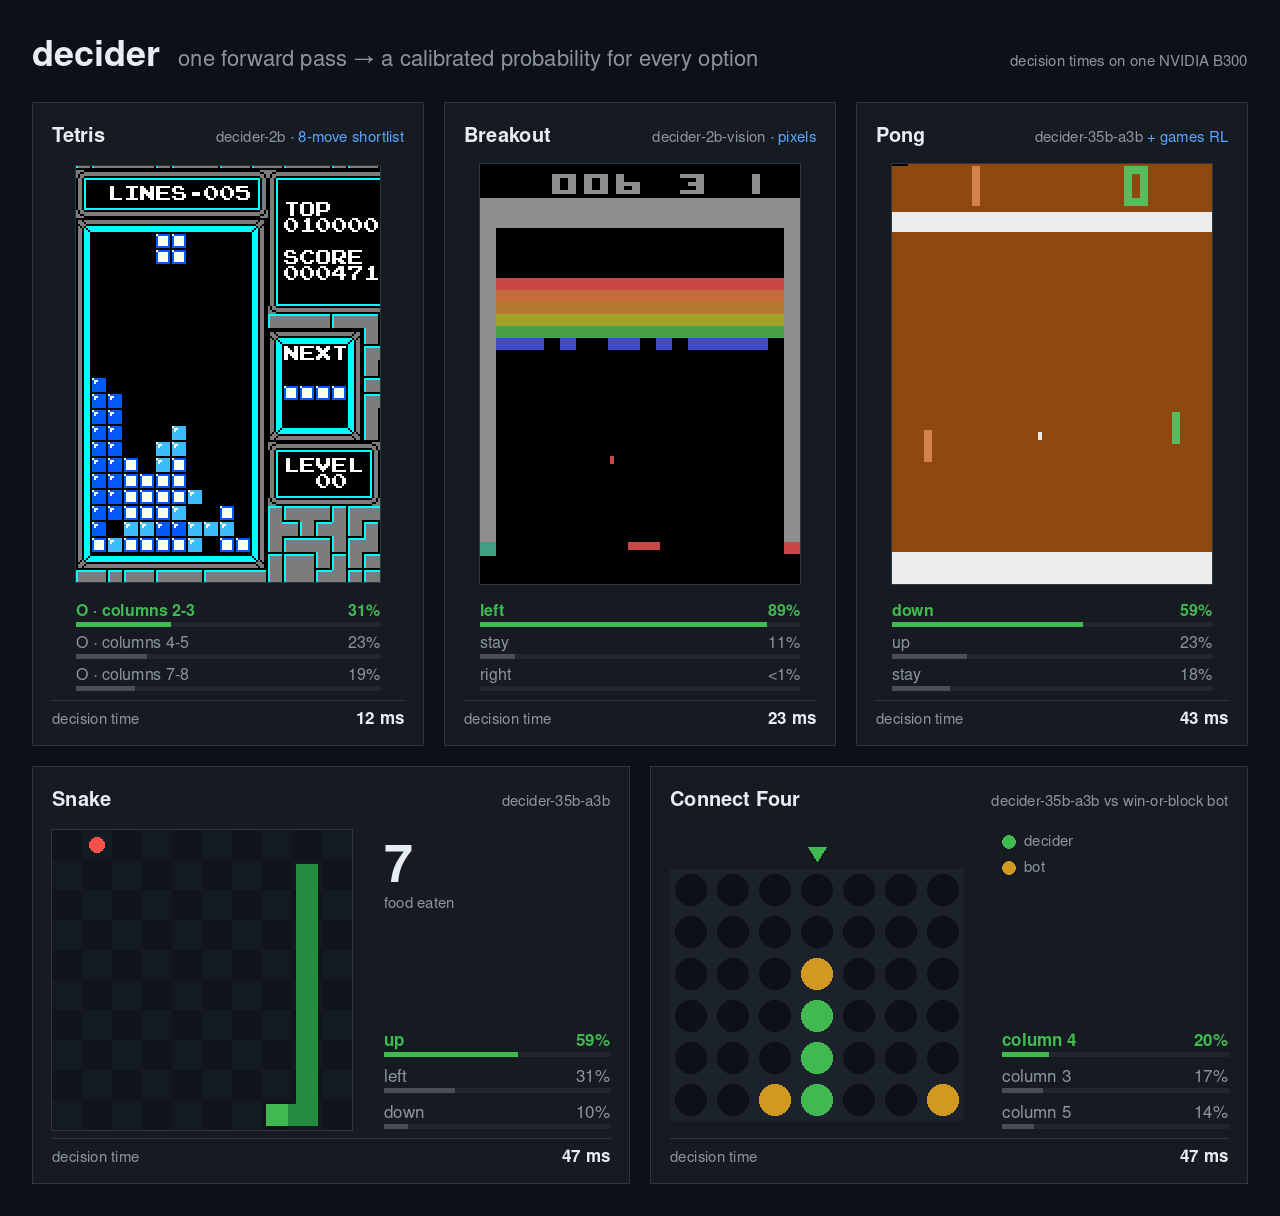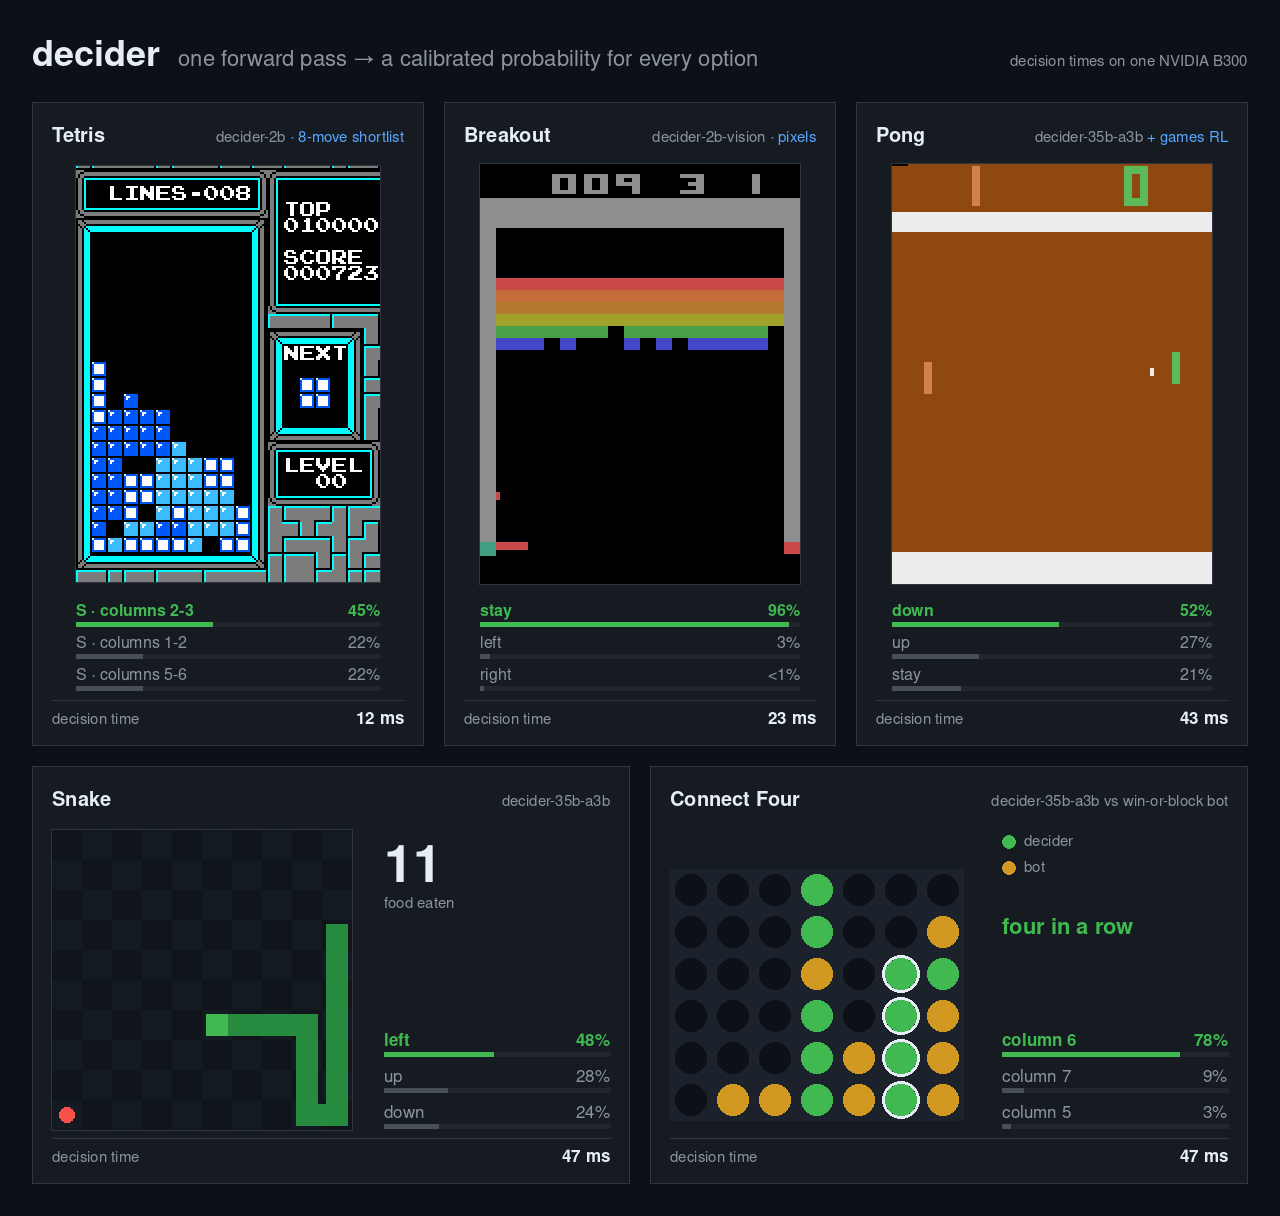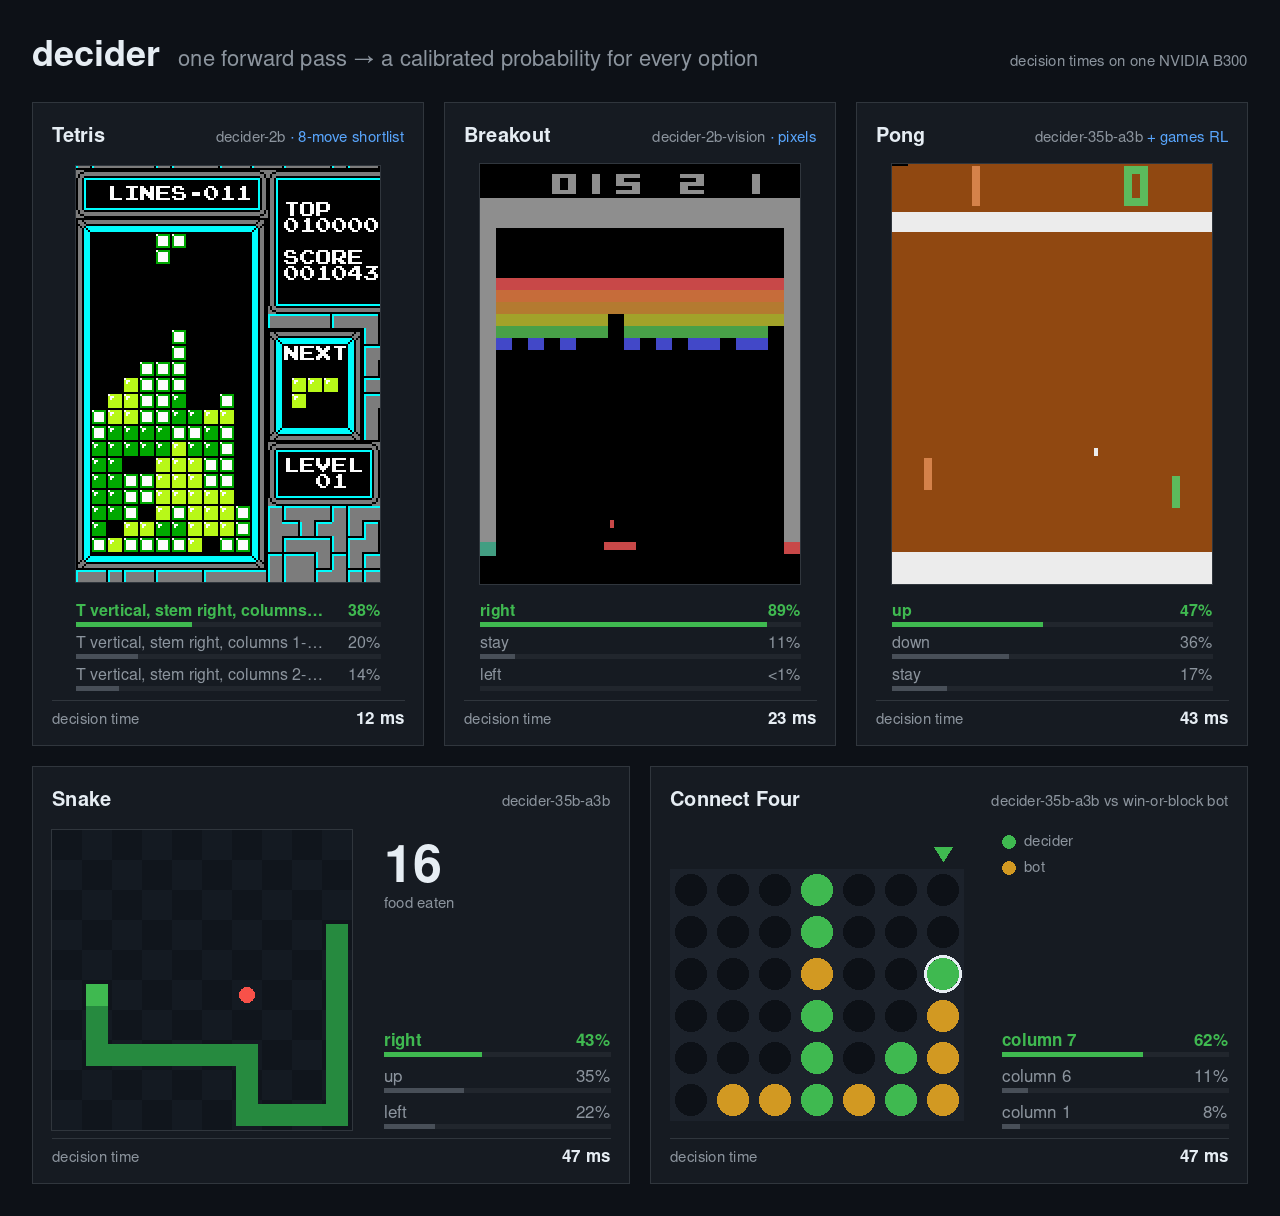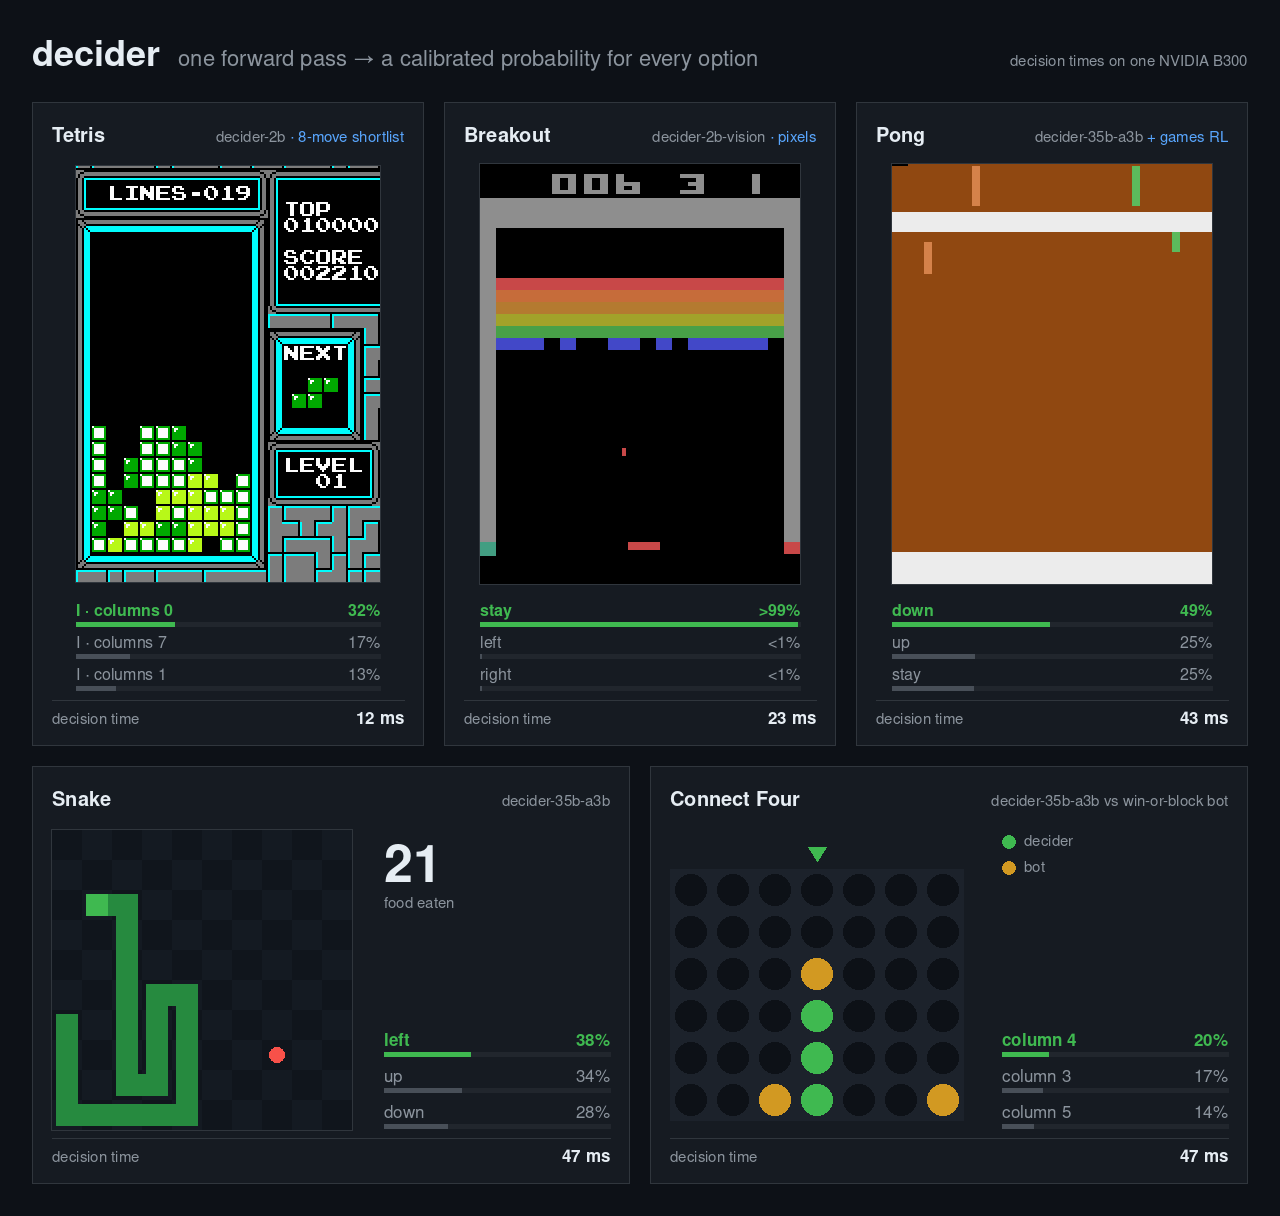
decider
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 28
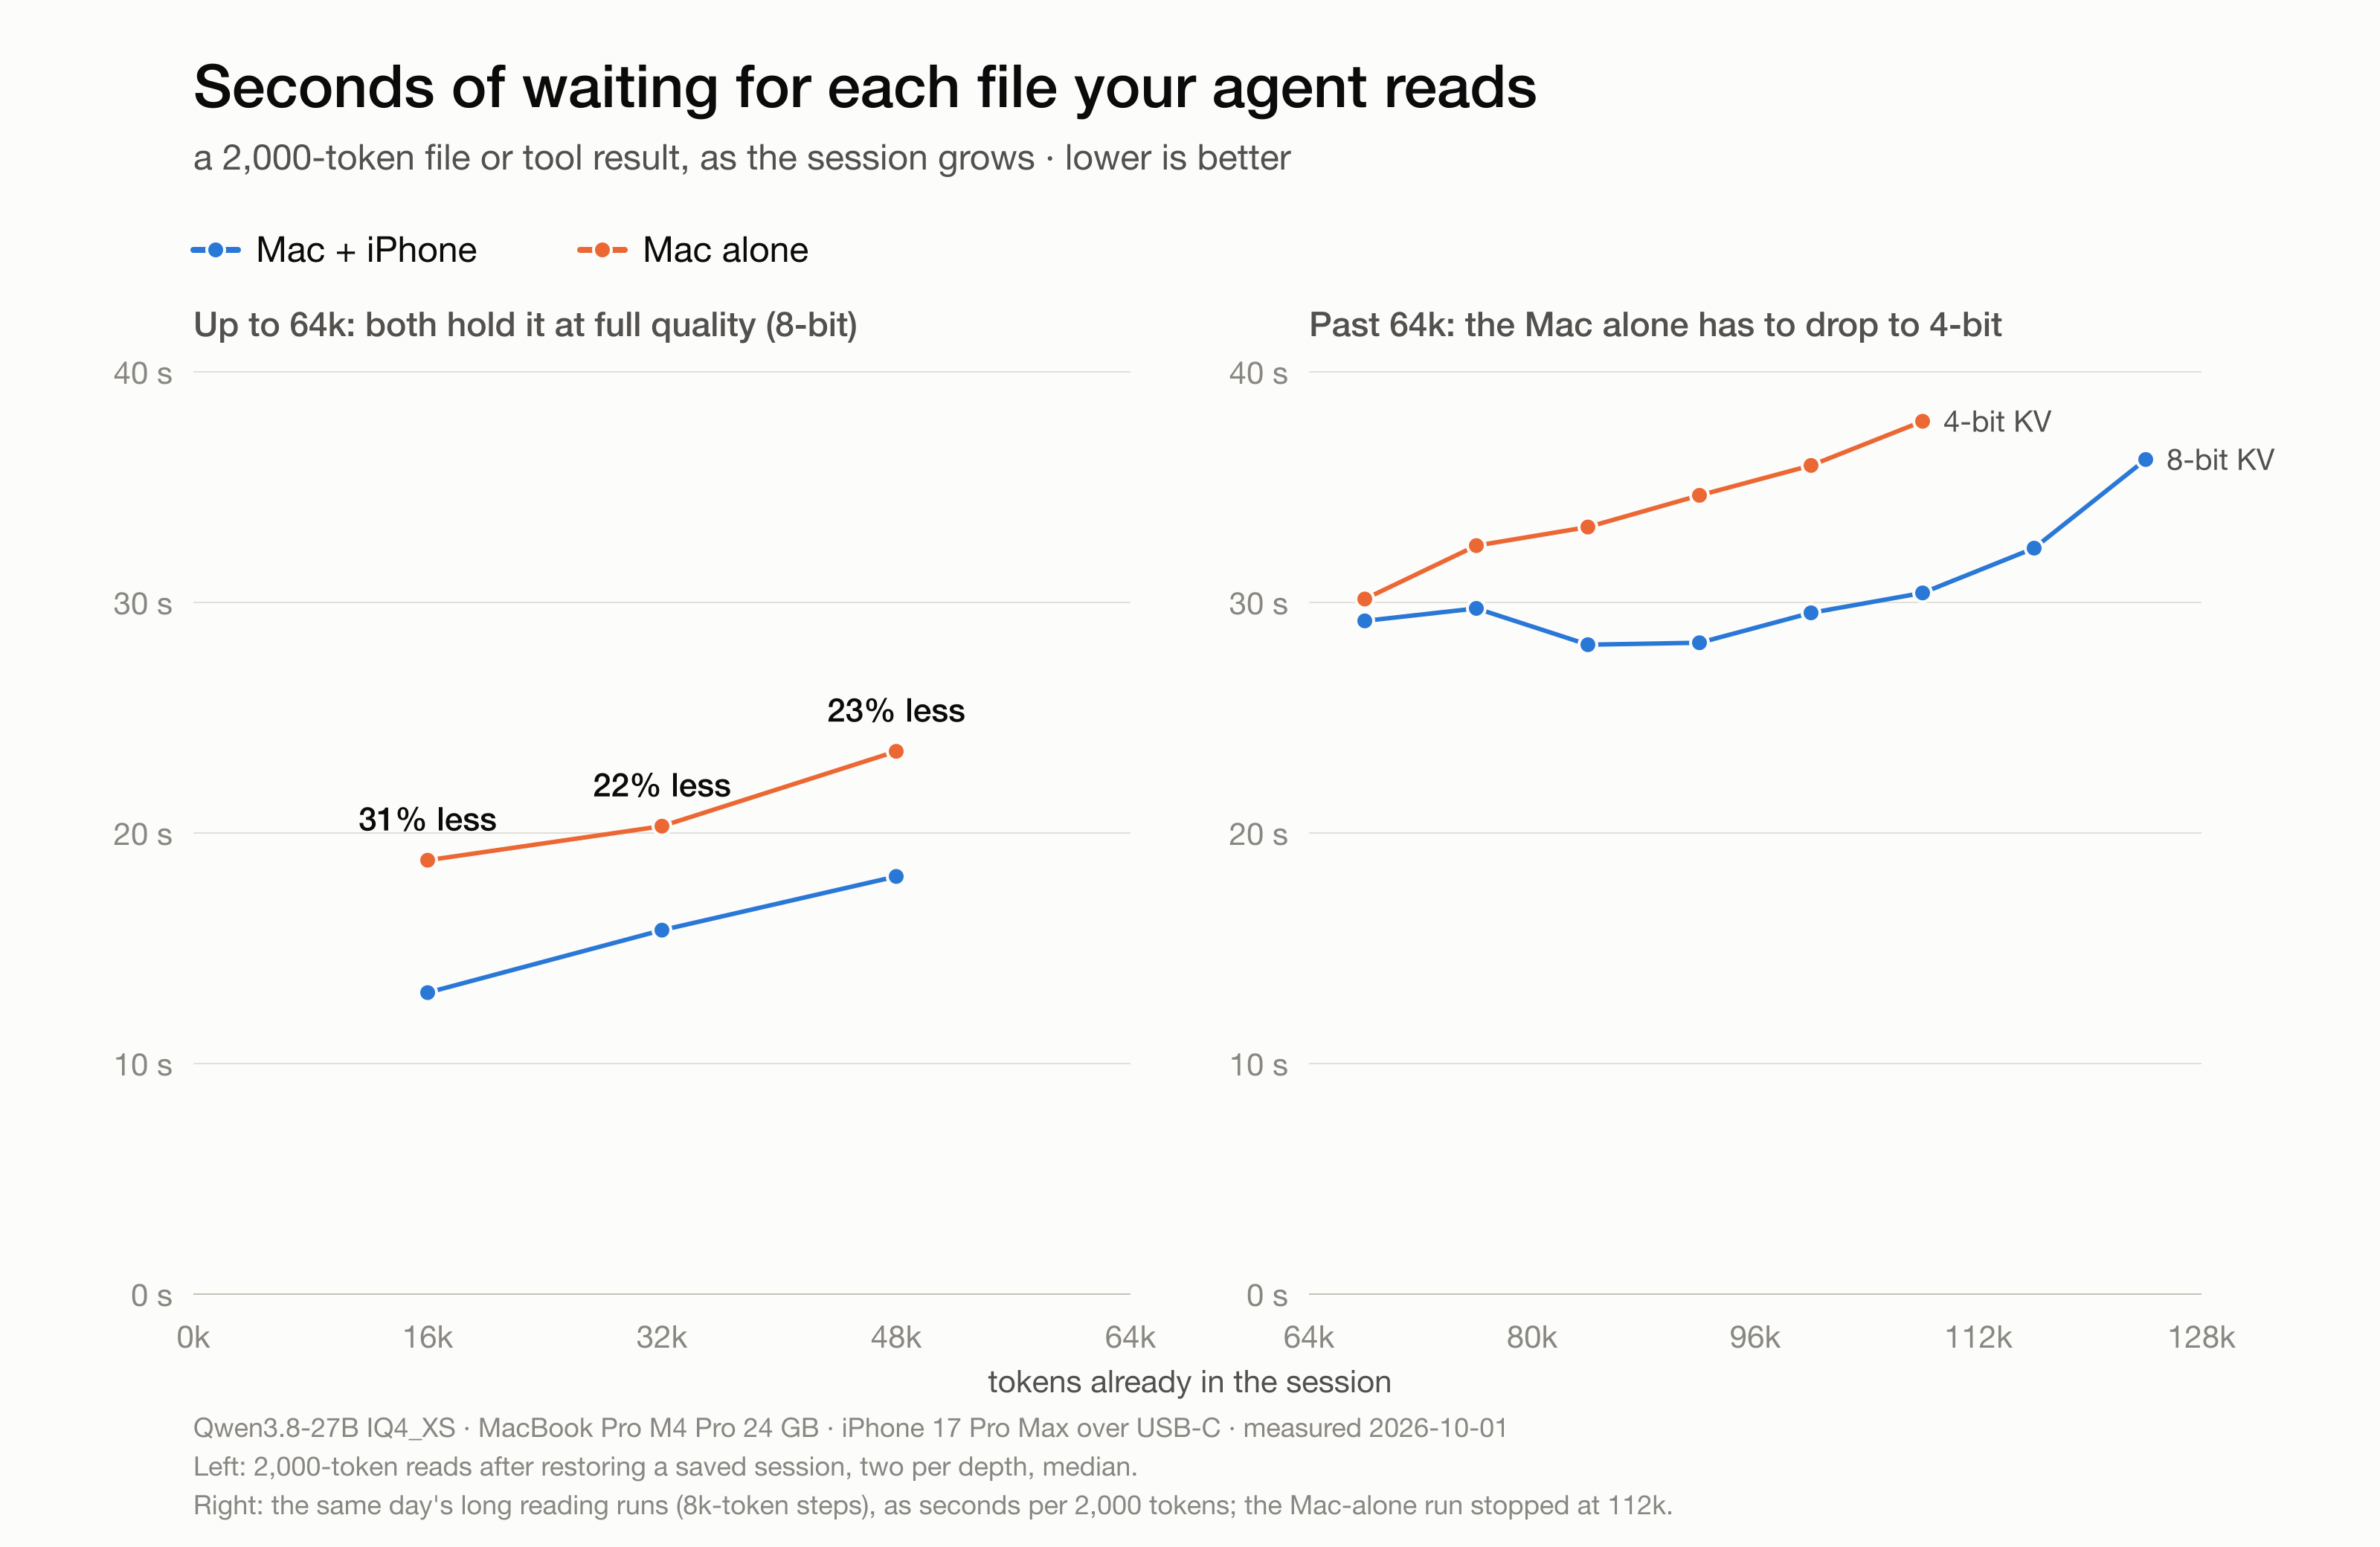
backburner
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 29

mac-performance-monitor
937Zesty0wl/mac-performance-monitor · SwiftA native macOS performance monitor and recorder that tracks CPU, memory, GPU, network, disk, battery, and sensor readings, letting you compare them against the processes behind them. It works as a menu bar readout, a quiet background recorder, or a window you open when needed.
- 30
rizzo-flow
903Rizzo-AI-Academy/rizzo-flow · PythonRizzo Flow is an open-source, local-first implementation of TypeSafe's Jev 'System One' model: it takes unstructured state as input and returns typed, probabilistic decisions (a yes/no, a choice, a score, a number) without generating a single text token, running entirely on your own hardware via llama.cpp.
- 31
souchastnik
725MShverdiakov/souchastnik · KotlinAn Android app (Souchastnik) that tells you what criminal charge you might face in Russia for something you wrote online, and flags mentions of 'foreign agents' or banned social networks.
- 32
StartLux-Decision
552StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 33
qwen38-uncensored
365Wassimyounes01/qwen38-uncensored · JavaScriptA Node.js install harness that sets up Qwen 3.8 27B as a fully uncensored local model, using weight-level abliterated GGUF weights plus a reinforcement SYSTEM prompt, runnable through Ollama or Apple's MLX.
- 34

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 35
PS5LM
337cobanov/PS5LM · C++llama.cpp on a jailbroken PS5: run any GGUF model natively on the console, starting with Qwen 3.8
- 36

CUDA-for-AMD-Windows
321Speedstu/CUDA-for-AMD-Windows · PythonA Windows compatibility stack that runs CUDA-targeted applications on AMD GPUs via ZLUDA plus AMD ROCm/HIP, with tooling to verify the work truly executes on the GPU instead of silently falling back to CPU or producing wrong results.
- 37

gemma4.c
173qmog-ai/gemma4.c · Cgemma4.c is a CPU inference runtime for Google's Gemma 4 E2B model written in about 700 lines of pure C, built to show how LLM inference actually works under the hood.
Related topics
Often tagged together