


25.2K ·GitHub
What is this?
 It is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
Is this a library or tool I can install, or something else?Neither - it is a curated reading index, not software. The content is Chinese markdown articles plus links to companion code repos for each experiment; there is nothing to install or run from this repo itself.
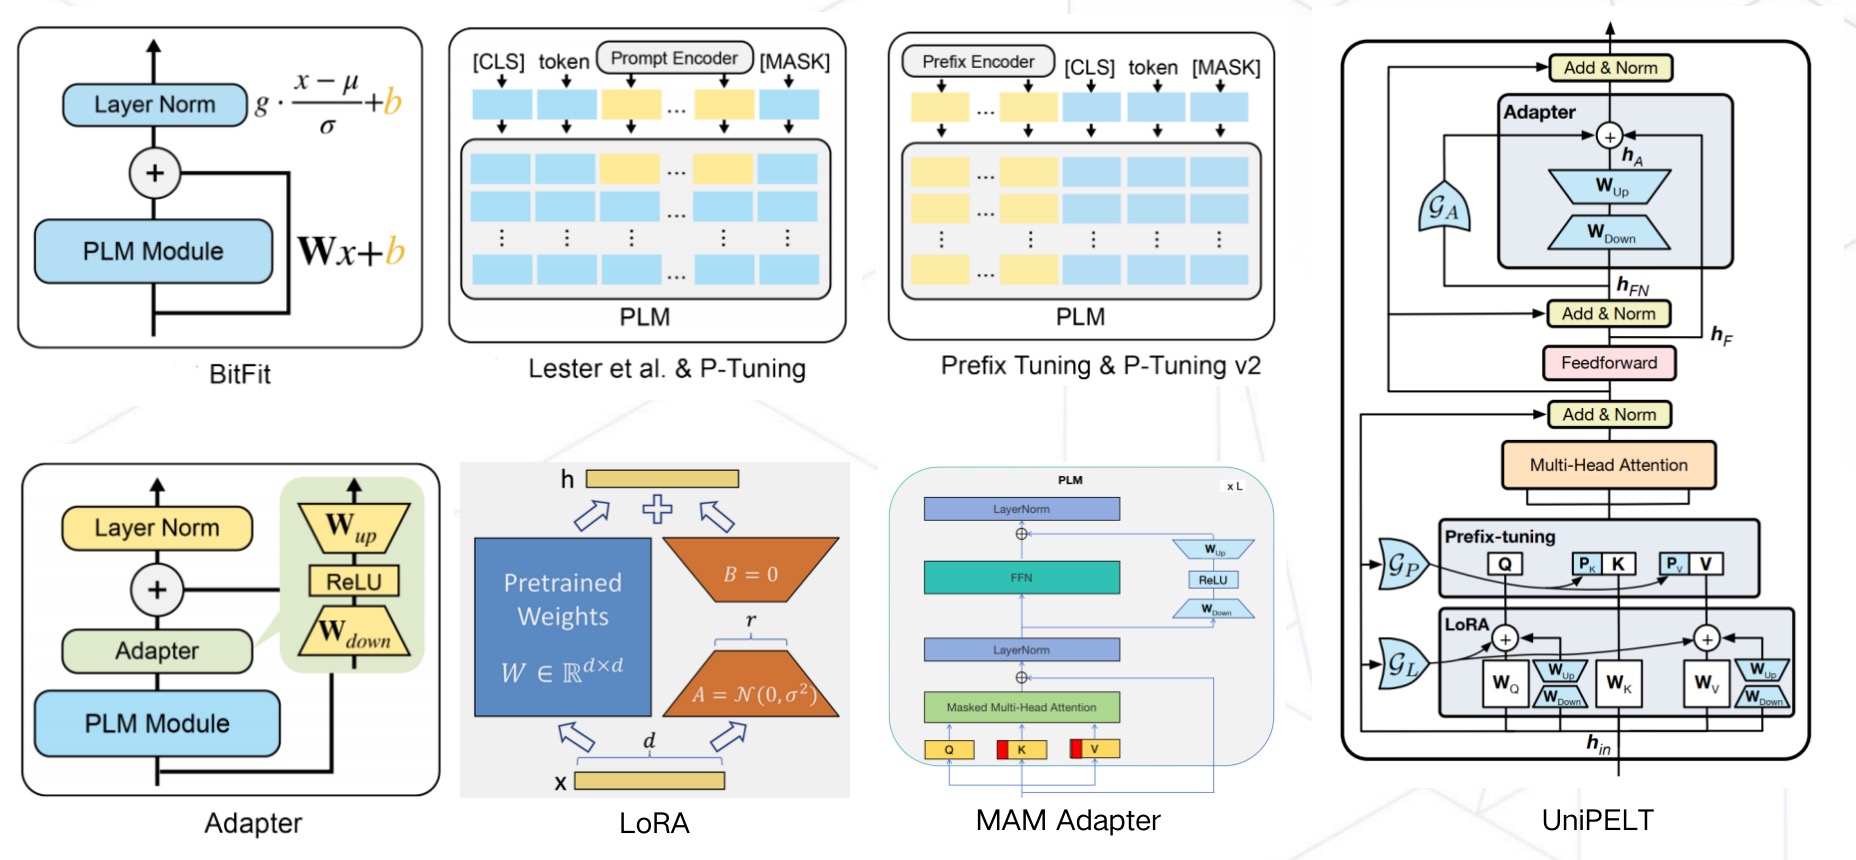
Neither - it is a curated reading index, not software. The content is Chinese markdown articles plus links to companion code repos for each experiment; there is nothing to install or run from this repo itself.Where should someone new to LLM engineering start here?Start with the table of contents at the top of the README. A natural path is the 7-article parameter-efficient fine-tuning series (BitFit, P-Tuning, LoRA, QLoRA and more), then the 9-article distributed-training parallelism series, then inference and serving.
Start with the table of contents at the top of the README. A natural path is the 7-article parameter-efficient fine-tuning series (BitFit, P-Tuning, LoRA, QLoRA and more), then the 9-article distributed-training parallelism series, then inference and serving.Which frameworks and tools do the tutorials build on?The hands-on fine-tuning series is built on HuggingFace PEFT (plus bitsandbytes for INT8/FP4/NF4); training tutorials use PyTorch, Megatron-LM and DeepSpeed; the inference side covers vLLM, SGLang, TensorRT-LLM and the Triton serving framework.
The hands-on fine-tuning series is built on HuggingFace PEFT (plus bitsandbytes for INT8/FP4/NF4); training tutorials use PyTorch, Megatron-LM and DeepSpeed; the inference side covers vLLM, SGLang, TensorRT-LLM and the Triton serving framework.Is the collection complete, or still being filled in?It is a living document and still growing: the distributed-training network-communication section is explicitly marked 'to be updated' (待更新), so not every item promised in the table of contents is filled in yet.
It is a living document and still growing: the distributed-training network-communication section is explicitly marked 'to be updated' (待更新), so not every item promised in the table of contents is filled in yet.Is it aimed at researchers, or can a regular developer benefit too?Both. The author notes parameter-efficient fine-tuning exists precisely so ordinary researchers and developers can fine-tune large models, so beginners can start with PEFT, while the distributed-training and serving material serves advanced practitioners.
Both. The author notes parameter-efficient fine-tuning exists precisely so ordinary researchers and developers can fine-tune large models, so beginners can start with PEFT, while the distributed-training and serving material serves advanced practitioners.Do I need a big GPU setup to follow along?Only for the hands-on parts, and not always a cluster: QLoRA fine-tuning of LLaMA-65B fits in 48GB of VRAM and GaLore can pretrain LLaMA-7B on a single RTX 4090, while the distributed-training series targets multi-GPU and multi-node setups.
Only for the hands-on parts, and not always a cluster: QLoRA fine-tuning of LLaMA-65B fits in 48GB of VRAM and GaLore can pretrain LLaMA-7B on a single RTX 4090, while the distributed-training series targets multi-GPU and multi-node setups.Which inference engines does it cover for production serving?It treats vLLM and SGLang as production-grade engines and also covers LMDeploy, LightLLM, MNN-LLM and the on-device multimodal engine mllm, plus step-by-step TensorRT-LLM tutorials and a three-part guide to the Triton serving framework.
It treats vLLM and SGLang as production-grade engines and also covers LMDeploy, LightLLM, MNN-LLM and the on-device multimodal engine mllm, plus step-by-step TensorRT-LLM tutorials and a three-part guide to the Triton serving framework.Is there material for learning how inference engines work internally?Yes - it links Nano-vLLM, an annotated lightweight vLLM reimplementation, and Mini-SGLang, a compact SGLang implementation, both described as very suitable for source-code study.
Yes - it links Nano-vLLM, an annotated lightweight vLLM reimplementation, and Mini-SGLang, a compact SGLang implementation, both described as very suitable for source-code study.Does it help with LLM job interview preparation?Yes - there is a dedicated LLM interview questions section, alongside a server environment setup guide and a WeChat study group for discussing LLM engineering.
Yes - there is a dedicated LLM interview questions section, alongside a server environment setup guide and a WeChat study group for discussing LLM engineering.Does it cover running LLMs on domestic Chinese AI hardware?Yes - the index includes sections on LLM adaptation to domestic hardware, AI accelerator cards, AI compilers, AI infrastructure and AI cluster networking.
Yes - the index includes sections on LLM adaptation to domestic hardware, AI accelerator cards, AI compilers, AI infrastructure and AI cluster networking.Which topics is it in?peft, ai-infrastructure, knowledge-distillation, llm-training, rlhf, llm-serving, llmops, llm-evaluation, data-engineering, lora, llm-inference, vllm
peft, ai-infrastructure, knowledge-distillation, llm-training, rlhf, llm-serving, llmops, llm-evaluation, data-engineering, lora, llm-inference, vllm