Topics / #data-pipeline
Data-pipeline projects on GitHub
Integration and streaming tools for moving data between sources and destinations.
As of , the most-starred Data-pipeline projects on GitHub are quivr (39.6K stars), airbyte (22.2K stars) and shardingsphere (20.8K stars). GitHub.Locker tracks 14 Data-pipeline repositories with 174.3K stars combined. The fastest-growing on October 16 was debezium, with +9 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +9
debezium
debezium/debezium · ★ 13.2KDebezium is an open source change data capture (CDC) platform that monitors databases and streams row-level change events to applications in real time.
dbt
dbt-labs/dbt · ★ 14Kdbt lets data analysts and engineers transform data in their warehouse by writing SQL select statements ('models'), applying the same practices — version control, testing, modularity — that software engineers use to build applications.
 +7
quivr
The-Vibe-Company/quivr · ★ 39.6KQuivr is an open-source engine that turns your files and content streams into search and monitoring — a 'second brain' you can query, built around an opinionated RAG powered by generative AI.
 +3
airbyte
airbytehq/airbyte · ★ 22.2KAirbyte is an open-source data movement platform for ELT pipelines and AI agents: it moves data from APIs, databases, and files into warehouses, data lakes, and AI applications, backed by a catalog of 600+ connectors. You can run it self-hosted or as Airbyte Cloud.
The all-time top
14 projects · by stars
- 39.6K#1 · The-Vibe-Company/quivr
quivr
Quivr is an open-source engine that turns your files and content streams into search and monitoring — a 'second brain' you can query, built around an opinionated RAG powered by generative AI.
- 22.2K#2 · airbytehq/airbyte
airbyte
Airbyte is an open-source data movement platform for ELT pipelines and AI agents: it moves data from APIs, databases, and files into warehouses, data lakes, and AI applications, backed by a catalog of 600+ connectors. You can run it self-hosted or as Airbyte Cloud.
- 20.8K
#3 · apache/shardingsphere
shardingsphere
An Apache Top-Level Project positioned as 'Database Plus': a layer built over your existing heterogeneous databases that adds distributed SQL - sharding, read/write splitting, encryption - without making you replace them.
- 4

rocketride-server
17.8Krocketride-org/rocketride-server · PythonAn open-source AI Development Environment: a data pipeline builder and runtime for AI/ML workloads. It turns the IDE you already use into one place to compose, debug, observe, and deploy AI workflows on a multithreaded C++ engine.
- 5

DataX
17.4Kalibaba/DataX · JavaDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
- 6
dbt
14Kdbt-labs/dbt · Rustdbt lets data analysts and engineers transform data in their warehouse by writing SQL select statements ('models'), applying the same practices — version control, testing, modularity — that software engineers use to build applications.
- 7

dask
13.9Kdask/dask · PythonDask is a flexible parallel computing library for analytics — it runs Python data workloads as scheduled tasks so they can use many cores or machines instead of a single process.
- 8
fluentd
13.6Kfluent/fluentd · RubyFluentd is an open-source log collector that sits at the center of your logging setup: it gathers events from many data sources and writes them to files, RDBMS, NoSQL, IaaS, SaaS, Hadoop and more.
- 9
debezium
13.2Kdebezium/debezium · JavaDebezium is an open source change data capture (CDC) platform that monitors databases and streams row-level change events to applications in real time.
- 10

elosys
458YuriRDev/elosys · TypeScriptElosys builds a consolidated database of Brazilian political candidates (2014-2026) from official government sources, cross-referenced by CPF/CNPJ, to investigate relationships between politicians and surface indicia of suspicious patterns like circular donations, shell companies, and wealth incompatible with declared income.
- 11
Zero-WAM
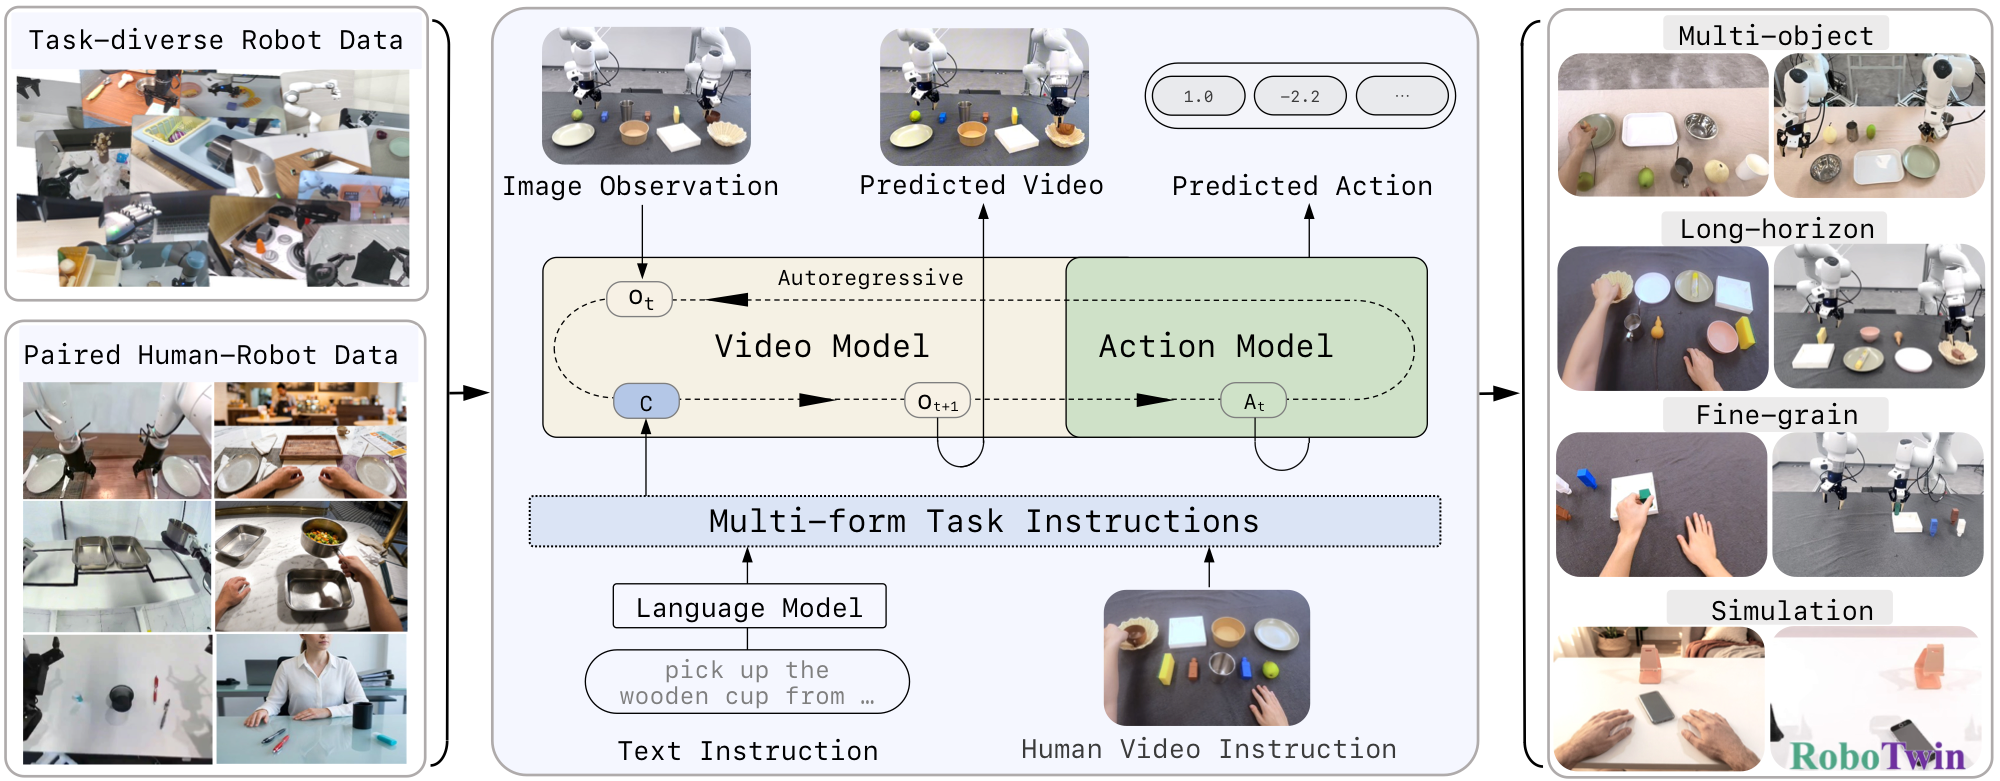
434robbyant-research/Zero-WAM · PythonZero-WAM is a research method for zero-shot cross-task robotic manipulation: a causal video-action policy that learns in-context world-action modeling, predicting future robot observations and executable actions from either language instructions or human demonstration videos.
- 12
hflow
298Hebbian-Robotics/hflow · PythonHFlow is an open source SDK from Hebbian Robotics (YC S26) for building scalable multimodal data pipelines for robotics and physical AI, letting teams verify the quality of the data they use to train AI models.
- 13

projeto-dados-ia-databricks
279lvgalvao/projeto-dados-ia-databricks · PythonThis is a 4-night hands-on course that builds the data and sales analytics stack of a fictional B2B perfume distributor from scratch, using Databricks Free Edition, SQL, Python and Claude Code.
- 14
walshadow
242ClickHouse/walshadow · Rustwalshadow replicates PostgreSQL rows into ClickHouse by reading the physical WAL — initial load, continuous changes, schema evolution, restarts, and planned source switchover are all part of the flow.
Related topics
Often tagged together