Topics / #video-understanding
Video-understanding projects on GitHub
AI models that comprehend actions and content in video.
As of , the most-starred Video-understanding projects on GitHub are MiniCPM-V (26.8K stars), Qwen3-VL (20.1K stars) and VideoAgent (2K stars). GitHub.Locker tracks 8 Video-understanding repositories with 50K stars combined. The fastest-growing on October 16 was MiniCPM-V, with +20 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +20
MiniCPM-V
OpenBMB/MiniCPM-V · ★ 26.8KA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
 +18
VideoHighlighter
Aseiel/VideoHighlighter · ★ 212A free, open-source desktop app that finds and explains the strong moments in your footage, then exports a highlight reel and clips — an offline alternative to Twelve Labs, Runway and Descript.
 +3
Qwen3-VL
QwenLM/Qwen3-VL · ★ 20.1KQwen3-VL is a family of multimodal vision-language models built by the Qwen team at Alibaba Cloud, combining strong text understanding with deep visual perception, reasoning, and agent capabilities.
 +2
VideoAgent
HKUDS/VideoAgent · ★ 2KVideoAgent is an all-in-one agentic framework that understands, edits, and remakes videos from natural-language requests, handling everything from summarization to meme remixes and cross-lingual comedy adaptations.
The all-time top
8 projects · by stars
- 26.8K#1 · OpenBMB/MiniCPM-V
MiniCPM-V
A family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 20.1K#2 · QwenLM/Qwen3-VL
Qwen3-VL
Qwen3-VL is a family of multimodal vision-language models built by the Qwen team at Alibaba Cloud, combining strong text understanding with deep visual perception, reasoning, and agent capabilities.
- 2K#3 · HKUDS/VideoAgent
VideoAgent
VideoAgent is an all-in-one agentic framework that understands, edits, and remakes videos from natural-language requests, handling everything from summarization to meme remixes and cross-lingual comedy adaptations.
- 4
Code-as-World
419MirroS-Lab/Code-as-World · PythonCode-as-World is a research project that represents the physical world as executable code, discovered through an agentic loop of simulation and verification, so models get reusable physical data (states, dynamics, mechanisms) instead of just raw pixels.
- 5

LeVJEPA
270MLO-lab/LeVJEPA · Jupyter NotebookThe official implementation of LeVJEPA — a self-supervised video encoder trained with LeJEPA's collapse-free objective. Unlike V-JEPA or VideoMAE it needs no EMA target encoder, stop-gradient, predictor, or pixel-reconstruction decoder: just an encoder, a small projector, and one loss hyperparameter.
- 6
VideoHighlighter
212Aseiel/VideoHighlighter · PythonA free, open-source desktop app that finds and explains the strong moments in your footage, then exports a highlight reel and clips — an offline alternative to Twelve Labs, Runway and Descript.
- 7
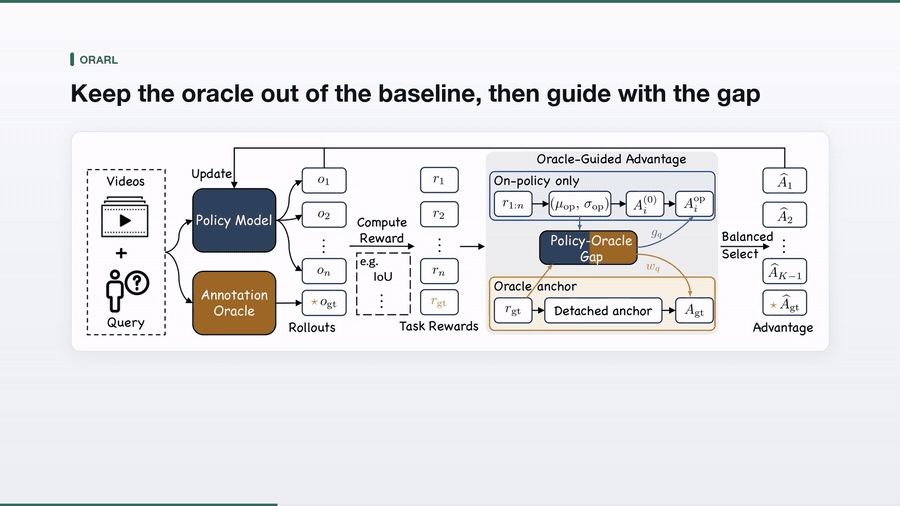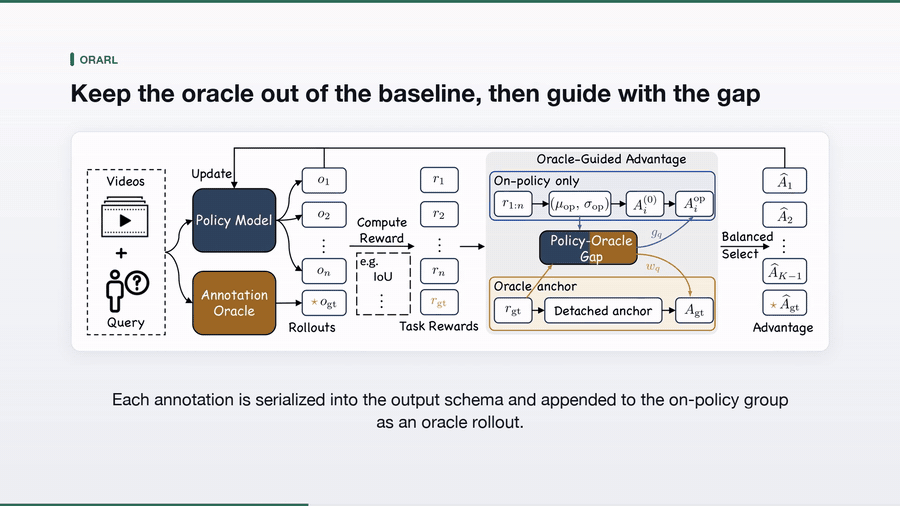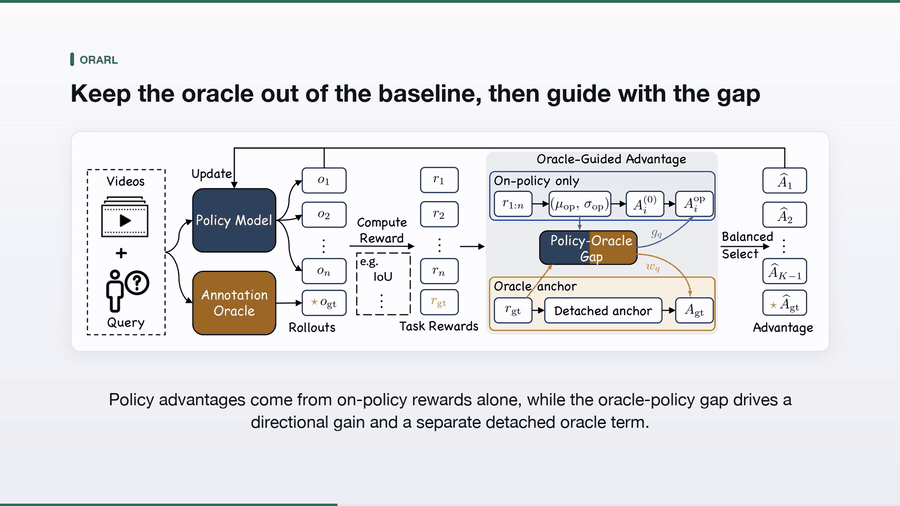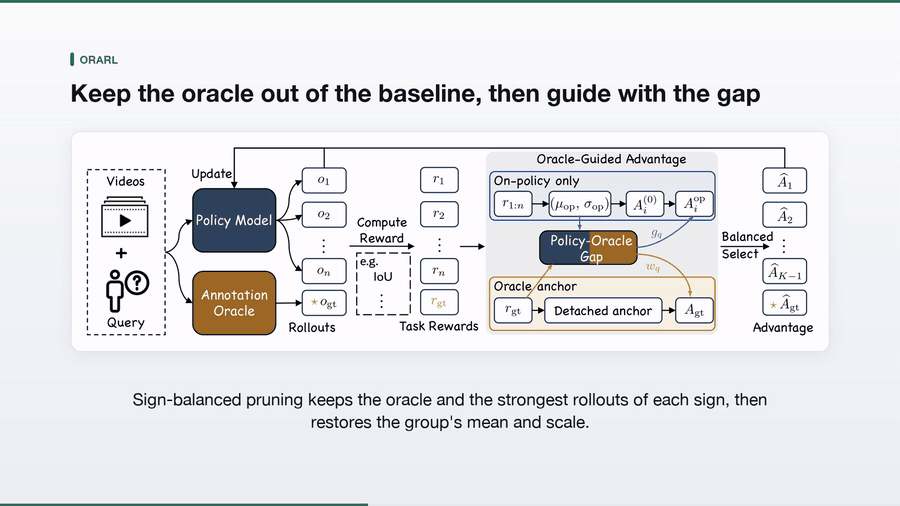
OraRL
166HVision-NKU/OraRL · PythonOraRL is a reinforcement learning framework that treats annotations as rollouts to efficiently train unified video multimodal LLMs (MLLMs) across seven video task families.
- 8

dance-video-to-prompt
143CattleZ/dance-video-to-prompt · PythonDance-video-to-prompt takes a short local video (dancing, posing, outfit changes, travel check-ins, walking in an outfit, ideally 10 seconds or less) and reverse-engineers it into a structured prompt you can feed straight into an AI video generator.
Related topics
Often tagged together
- computer-vision384
- python2,383
- gpu789
- machine-learning916
- multimodal189
- deep-learning737
- ai1,955
- apache-2.01,434
- cuda396
- llm1,483
- research764
- video-processing130
- vision-language-model45
- huggingface362
- linux4,184
- macos3,544
- open-source5,666
- pytorch419
- transformer212
- video279
- vllm124
- academic-research209
- audio-processing64
- automation1,183