Topics / #triton
Triton projects on GitHub
As of , the most-starred Triton projects on GitHub are fauxpilot (14.7K stars), Spark-TTS (11K stars) and lectures (6.9K stars). GitHub.Locker tracks 9 Triton repositories with 39.5K stars combined. The fastest-growing on October 17 was SparkDiffusion, with +7 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +7
SparkDiffusion
AlibabaResearch/SparkDiffusion · ★ 518SparkDiffusion is an acceleration framework for Diffusion Transformer (DiT) video-generation models. It combines sparse low-rank attention (RoLa), few-step distillation (CrossDistill), and custom GPU operators to deliver 200x+ faster inference than a dense multi-step baseline while preserving generation quality.
 +5
lectures
gpu-mode/lectures · ★ 6.9KThis is the supplementary material repository for the GPU MODE lectures YouTube channel — a growing collection of notebooks, slides and code from each numbered lecture on GPU and CUDA programming.
 +2
Spark-TTS
SparkAudio/Spark-TTS · ★ 11KSpark-TTS is a text-to-speech system that uses a large language model (built on Qwen2.5) to generate highly natural, accurate speech, including zero-shot voice cloning.
 +2
Hyperloom
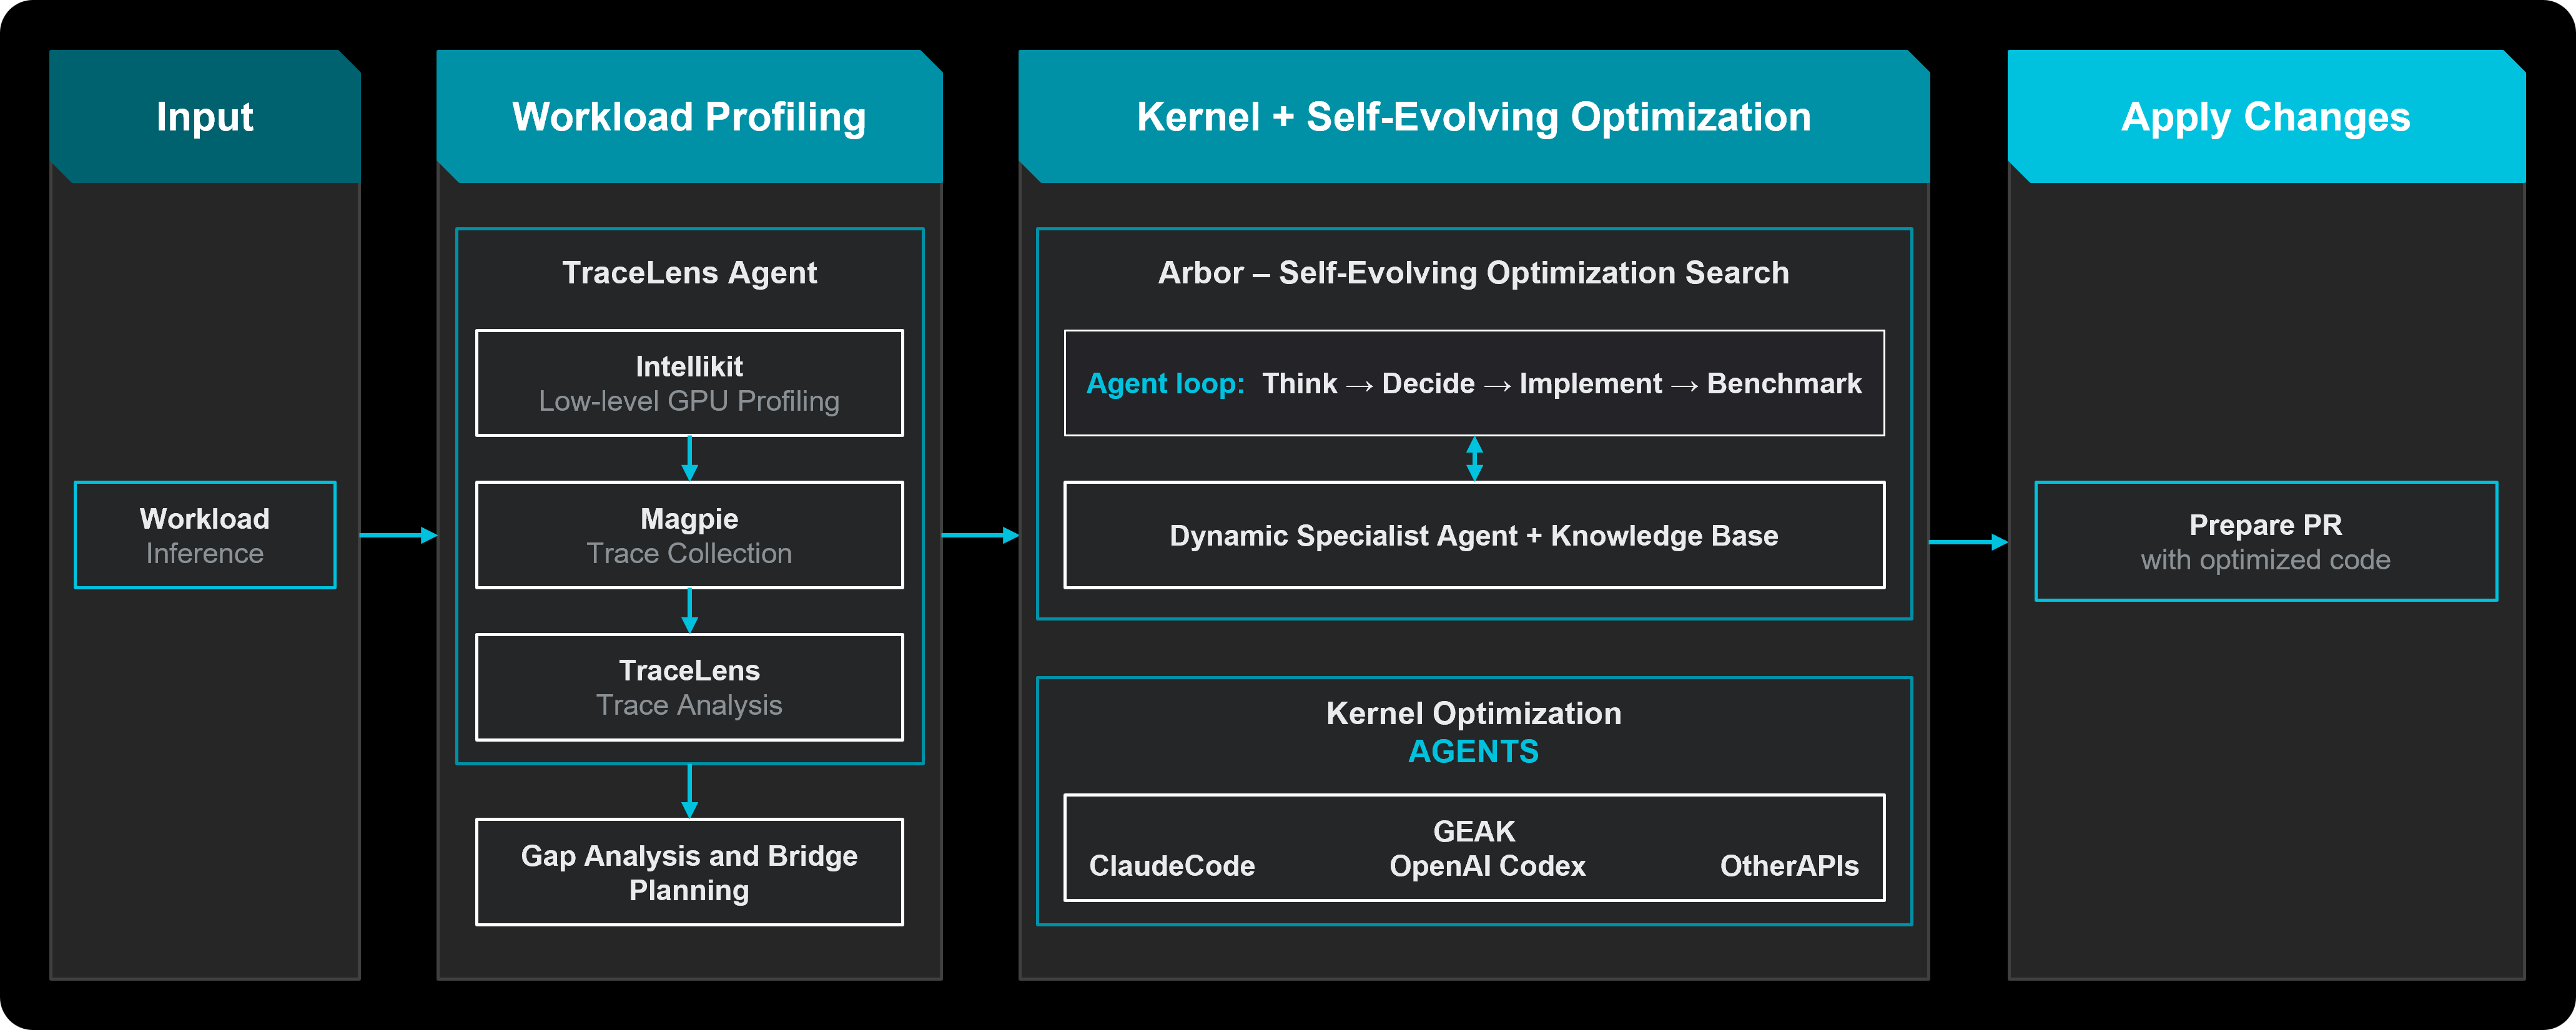
AMD-AGI/Hyperloom · ★ 242A multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
The all-time top
9 projects · by stars
- 14.7K
 #1 · fauxpilot/fauxpilot
fauxpilot
FauxPilot is an open-source, self-hosted alternative to GitHub Copilot that runs SalesForce CodeGen models locally on your own NVIDIA GPU via Triton Inference Server with the FasterTransformer backend.
- 11K#2 · SparkAudio/Spark-TTS
Spark-TTS
Spark-TTS is a text-to-speech system that uses a large language model (built on Qwen2.5) to generate highly natural, accurate speech, including zero-shot voice cloning.
- 6.9K#3 · gpu-mode/lectures
lectures
This is the supplementary material repository for the GPU MODE lectures YouTube channel — a growing collection of notebooks, slides and code from each numbered lecture on GPU and CUDA programming.
- 4
parameter-golf
5.2Kopenai/parameter-golf · PythonThis is OpenAI's 'Model Craft Challenge: Parameter Golf' - a competition to train the best language model that fits in a 16MB artifact and trains in under 10 minutes on 8xH100 GPUs, scored by bits-per-byte compression on the FineWeb validation set.
- 5
vdn-minimax-h3
618OpenVDN/vdn-minimax-h3 · PythonVDN-Minimax-H3 is a hybrid-attention video generation model built on MiniMax H3 that renders video faster than it plays, supporting text-to-video-audio, image-to-video-audio, first/last-frame-to-video and more from one checkpoint.
- 6
SparkDiffusion
518AlibabaResearch/SparkDiffusion · PythonSparkDiffusion is an acceleration framework for Diffusion Transformer (DiT) video-generation models. It combines sparse low-rank attention (RoLa), few-step distillation (CrossDistill), and custom GPU operators to deliver 200x+ faster inference than a dense multi-step baseline while preserving generation quality.
- 7
Hyperloom
242AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
- 8

Qwen3.8-27B-DFlash2-EXL3-5.0bpw
232MiaAI-Lab/Qwen3.8-27B-DFlash2-EXL3-5.0bpw · PythonA deployment kit for serving Qwen3.8-27B (quantized to EXL3 3.5bpw) through an OpenAI-compatible server, using speculative decoding to speed up generation. It bundles the launcher, server, and config; the model weights live on Hugging Face and inference runs on the team's exllamav3 fork.
- 9
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
Related topics
Often tagged together
- gpu788
- python2,397
- inference326
- nvidia327
- cuda395
- linux4,181
- quantization183
- huggingface361
- machine-learning915
- deep-learning736
- large-language-models212
- llm1,484
- research764
- ai1,955
- apache-2.01,434
- gpu-acceleration144
- performance633
- pytorch419
- attention-mechanism53
- benchmark430
- mit3,311
- self-hosted1,926
- server1,459
- transformer212