Topics / #tokenizer
Tokenizer projects on GitHub
Tokenizing text into subword units for language model training and inference.
As of , the most-starred Tokenizer projects on GitHub are LLMs-from-scratch (106.7K stars), autoresearch (98K stars) and grok-1 (52.2K stars). GitHub.Locker tracks 10 Tokenizer repositories with 302.3K stars combined. The fastest-growing on October 16 was LLMs-from-scratch, with +65 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +65
LLMs-from-scratch
rasbt/LLMs-from-scratch · ★ 106.7KThis is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
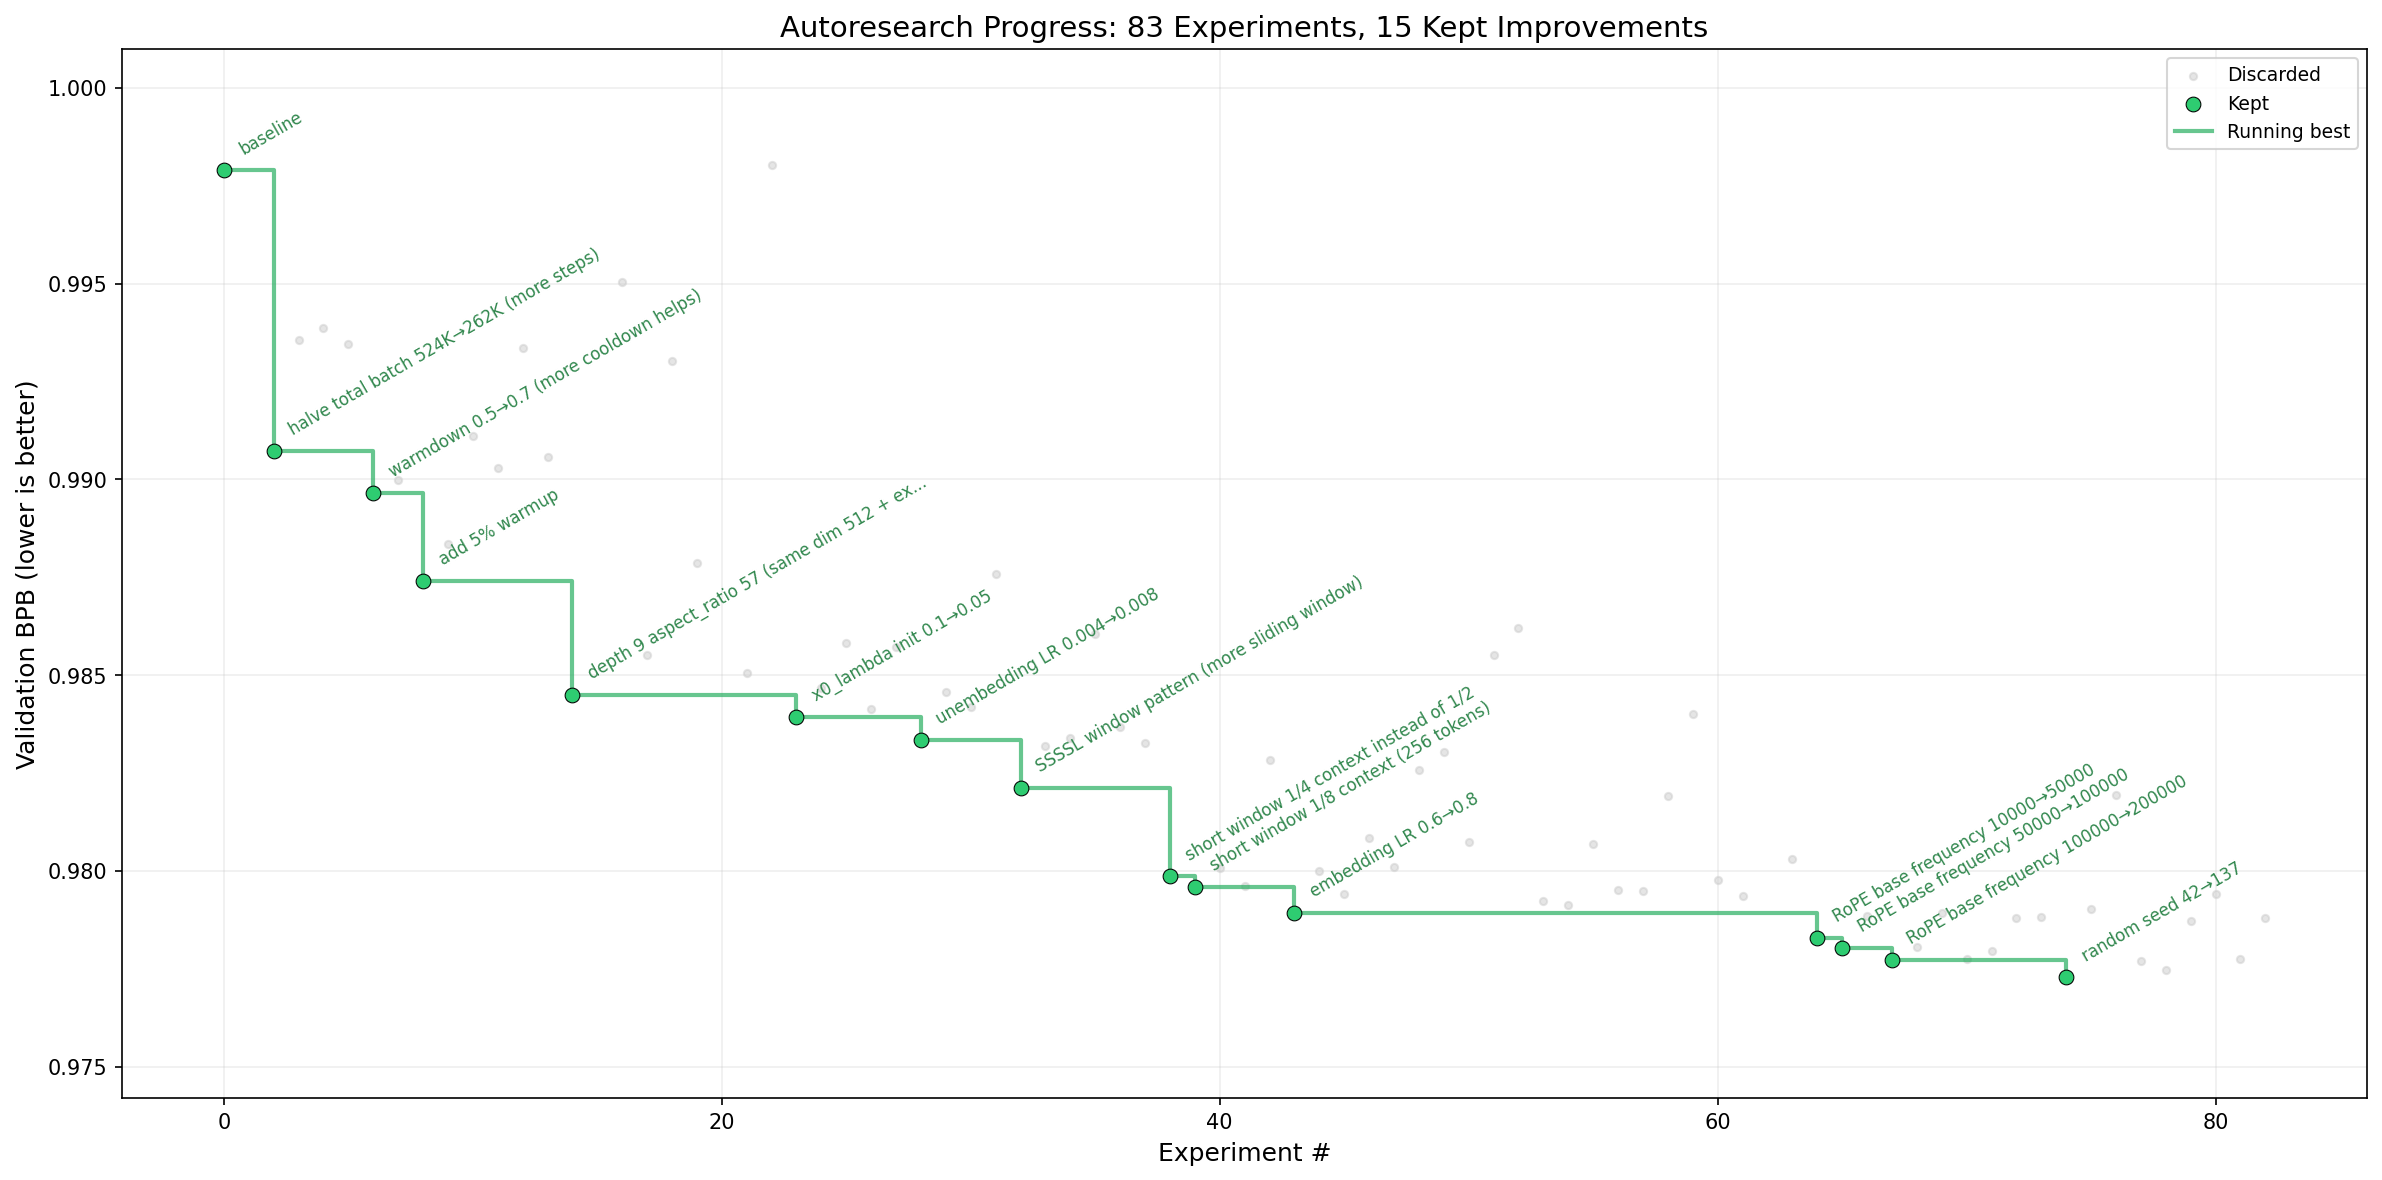 +59
autoresearch
karpathy/autoresearch · ★ 98Kautoresearch gives an AI coding agent a small, real LLM training setup (a simplified single-GPU version of nanochat) and lets it autonomously edit the training code, run 5-minute experiments, and keep what works overnight, so you wake up to a log of experiments and hopefully a better model.
 +6
tokenizers
huggingface/tokenizers · ★ 11.2KTokenizers is a library implementing today's most-used tokenizers (BPE, WordPiece, Unigram) for NLP, built in Rust for speed and exposed to other languages via bindings. It's made by Hugging Face and powers tokenization for transformer models.
 +2
grok-1
xai-org/grok-1 · ★ 52.2KGrok-1 is the 314B-parameter Mixture-of-Experts language model that xAI opened up; this repository holds the JAX example code for loading and running it.
The all-time top
10 projects · by stars
- 106.7K#1 · rasbt/LLMs-from-scratch
LLMs-from-scratch
This is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
- 98K#2 · karpathy/autoresearch
autoresearch
autoresearch gives an AI coding agent a small, real LLM training setup (a simplified single-GPU version of nanochat) and lets it autonomously edit the training code, run 5-minute experiments, and keep what works overnight, so you wake up to a log of experiments and hopefully a better model.
- 52.2K#3 · xai-org/grok-1
grok-1
Grok-1 is the 314B-parameter Mixture-of-Experts language model that xAI opened up; this repository holds the JAX example code for loading and running it.
- 4
compromise
12.2Kspencermountain/compromise · JavaScriptCompromise is a lightweight JavaScript natural-language processing library that parses text into structured data: tokenizing words and sentences, tagging part-of-speech, and letting you query phrases like numbers, names, or dates.
- 5
tokenizers
11.2Khuggingface/tokenizers · RustTokenizers is a library implementing today's most-used tokenizers (BPE, WordPiece, Unigram) for NLP, built in Rust for speed and exposed to other languages via bindings. It's made by Hugging Face and powers tokenization for transformer models.
- 6

lexer
11.1Kdoctrine/lexer · PHPDoctrine Lexer is a base PHP library for building lexers — the components that turn raw text into tokens — for top-down, recursive descent parsers.
- 7
parameter-golf
5.2Kopenai/parameter-golf · PythonThis is OpenAI's 'Model Craft Challenge: Parameter Golf' - a competition to train the best language model that fits in a 16MB artifact and trains in under 10 minutes on 8xH100 GPUs, scored by bits-per-byte compression on the FineWeb validation set.
- 8

gigatoken
4.1Kmarcelroed/gigatoken · RustGigatoken is an extremely fast tokenizer for language models, built as a near drop-in replacement for HuggingFace Tokenizers and tiktoken, encoding text at multi-GB/s speeds.
- 9

fastembed-rs
1Kanush008/fastembed-rs · RustA Rust library that generates vector embeddings and reranks results entirely locally — no external API calls. It covers dense and sparse text embeddings, image embeddings, multimodal models, and rerankers.
- 10

LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
Related topics
Often tagged together
- llm1,483
- machine-learning916
- deep-learning737
- nlp214
- open-source5,666
- python2,383
- research764
- ai1,955
- gpu789
- huggingface362
- large-language-models213
- library1,587
- mit3,312
- linux4,184
- apache-2.01,434
- cuda396
- developer-tools2,924
- gpt138
- language-model53
- macos3,544
- natural-language-processing96
- pytorch419
- quantization183
- rust679