Topics / #evals
Evals projects on GitHub
Evaluating and scoring the behavior of models and AI agents.
As of , the most-starred Evals projects on GitHub are mastra (28.9K stars), evals (19.6K stars) and ragas (16K stars). GitHub.Locker tracks 14 Evals repositories with 95.8K stars combined. The fastest-growing on October 17 was failproofai, with +146 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +146
failproofai
FailproofAI/failproofai · ★ 5.8KFailproof AI is an observability and enforcement layer that sits inside AI agent harnesses (coding CLIs, chat gateways, self-hosted assistants), capturing every run and blocking dangerous tool calls before they execute.
 +22
cayu
cayu-dev/cayu · ★ 918Cayu is an open-source Python framework for building and running domain-specific long-horizon AI agents, with a durable runtime built in that handles sessions, task dispatch, recovery, approvals, and observability.
 +13
mastra
mastra-ai/mastra · ★ 28.9KMastra is a TypeScript framework for building AI-powered applications and agents, designed to take you from early prototypes to production-ready products.
 +12
phoenix
Arize-ai/phoenix · ★ 11.9KArize Phoenix is an open-source AI observability platform for tracing, evaluating, and troubleshooting LLM applications, agents, and RAG pipelines.
The all-time top
14 projects · by stars
- 28.9K#1 · mastra-ai/mastra
mastra
Mastra is a TypeScript framework for building AI-powered applications and agents, designed to take you from early prototypes to production-ready products.
- 19.6K
 #2 · openai/evals
evals
Evals is OpenAI's framework for evaluating LLMs and LLM-based systems, bundled with an open-source registry of benchmarks you can run or extend.
- 16K
 #3 · vibrantlabsai/ragas
ragas
Ragas is an open-source Python toolkit for evaluating and optimizing LLM applications: objective metrics, automatic test-set generation and data-driven insights replace slow, subjective manual assessment.
- 4
phoenix
11.9KArize-ai/phoenix · PythonArize Phoenix is an open-source AI observability platform for tracing, evaluating, and troubleshooting LLM applications, agents, and RAG pipelines.
- 5
harness-sdk
8.9Kstrands-agents/harness-sdk · PythonStrands Agents - an open-source SDK for building and running AI agents in Python and TypeScript, with a model-driven approach where a working agent takes just a few lines of code.
- 6
failproofai
5.8KFailproofAI/failproofai · TypeScriptFailproof AI is an observability and enforcement layer that sits inside AI agent harnesses (coding CLIs, chat gateways, self-hosted assistants), capturing every run and blocking dangerous tool calls before they execute.
- 7
rrsi
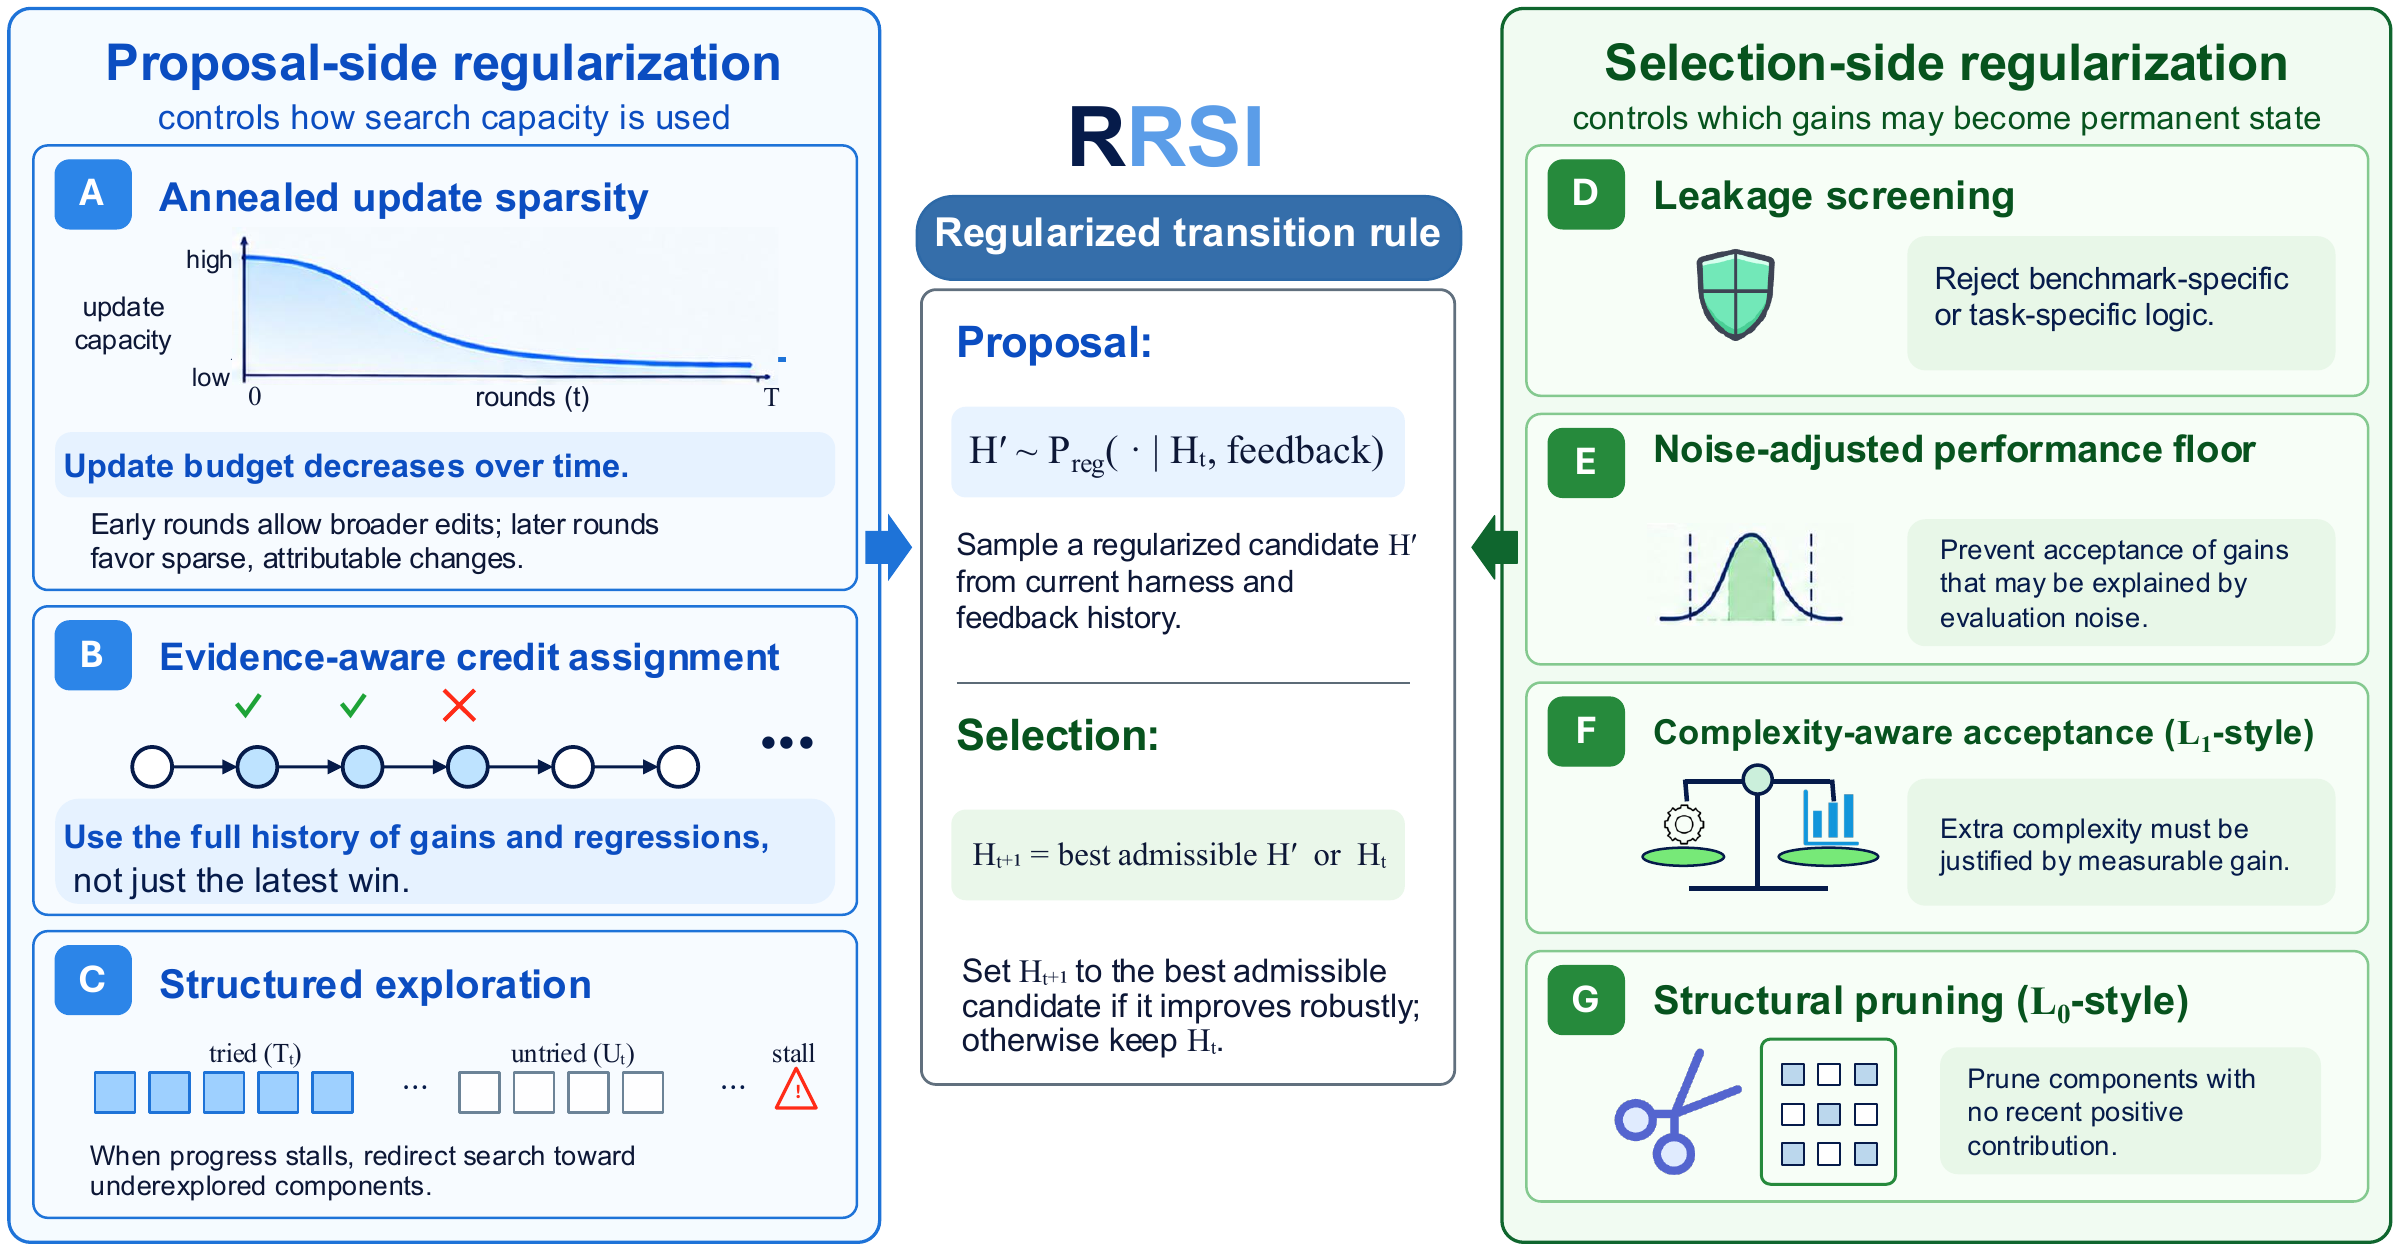
1.5Kgoogle-research/rrsi · PythonRRSI (Regularized Recursive Self-Improvement) is a Google research framework that automatically improves an LLM agent's harness (prompts, control flow, tools, memory, context management around a frozen model) by searching over harness edits and keeping only those with measured, auditable gains.
- 8
cayu
918cayu-dev/cayu · PythonCayu is an open-source Python framework for building and running domain-specific long-horizon AI agents, with a durable runtime built in that handles sessions, task dispatch, recovery, approvals, and observability.
- 9
ai-engineer-notebooks
703calmrocks/ai-engineer-notebooks · Jupyter NotebookA collection of framework-free, hands-on Jupyter/Colab notebooks teaching the applied-LLM engineer skill set — model APIs, RAG, evals, agents, fine-tuning, security, and LLMOps — built for engineers moving into AI Engineer / Forward Deployed Engineer (FDE) roles.
- 10
overmind
663overmind-core/overmind · PythonOvermind points at your AI agent's codebase and production traces, then turns them into a fine-tuned model that is benchmarked against metrics you define and served through one unified API — no separate ML infrastructure to build.
- 11
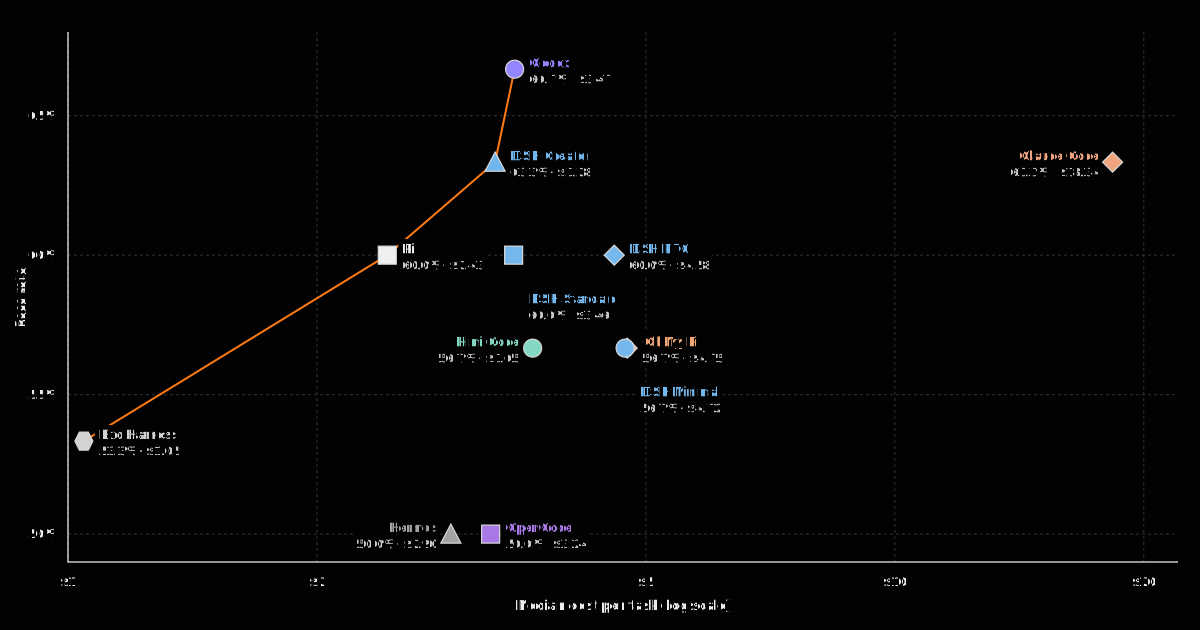
eval
311frontier-harness-eval/eval · JavaScriptFrontierHarness Eval is a public benchmark that ran the same Kimi K3 model through nine coding-agent harnesses (12 configurations) on the same 30 software-engineering tasks, to see how pass rate, cost, cache behavior and speed change when only the harness changes.
- 12
ASI-Bench
301apexin-ai/ASI-Bench · PythonASI-Bench is a benchmark for evaluating AI agents on long-horizon scientific research: it jointly tests general intelligence, innovation, and autonomous execution across 60 project-level tasks in 11 domains.
- 13

arc-code
143jerber/arc-code · Pythonarc-code is a research harness that lets Claude Code (or Codex) play the ARC-AGI-3 benchmark games through a shell and filesystem, writing its own parsers, simulators and search code for each game instead of relying on built-in ARC-specific tooling.
- 14

jevals
105openlayer-ai/jevals · Pythonjevals is a Python library for evaluating and guardrailing AI agent traces using 'Jev' decision models instead of a text-generating LLM judge. It bundles every check for a trace into one request that costs a fraction of a cent and returns in a few hundred milliseconds, so you can eval every trace and even run checks inside the agent loop.
Related topics
Often tagged together