Topics / #statistics
Statistics projects on GitHub
Statistical analysis and probability methods
As of , the most-starred Statistics projects on GitHub are cs-self-learning (76.3K stars), awesome-courses (72K stars) and scikit-learn (67.7K stars). GitHub.Locker tracks 61 Statistics repositories with 1.1M stars combined. The fastest-growing on October 17 was ModelTrace, with +40 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +40
ModelTrace
xqy2006/ModelTrace · ★ 1.7KModelTrace is a locally-run active model attribution tool: it sends three fixed challenge prompts to a target model, extracts an output fingerprint, and matches it against a known-model library to guess the model family and specific version.
 +32
awesome-courses
prakhar1989/awesome-courses · ★ 72KIt is a curated list of free, high-quality computer science courses from universities around the world, each one making its lecture materials, assignments, notes and readings available online.
 +30
analytics
plausible/analytics · ★ 29.5KPlausible Analytics is an open source, privacy-first web analytics tool — a lightweight, cookie-free Google Analytics alternative, offered as a managed cloud or a self-hosted Community Edition.
 +27
cs-self-learning
PKUFlyingPig/cs-self-learning · ★ 76.3KA free, open-source online guide that curates the best open courseware from top international universities so anyone can self-study computer science from scratch, aiming to turn a beginner into a well-rounded programmer in 2-3 years.
The all-time top
61 projects · by stars
- 76.3K#1 · PKUFlyingPig/cs-self-learning
cs-self-learning
A free, open-source online guide that curates the best open courseware from top international universities so anyone can self-study computer science from scratch, aiming to turn a beginner into a well-rounded programmer in 2-3 years.
- 72K#2 · prakhar1989/awesome-courses
awesome-courses
It is a curated list of free, high-quality computer science courses from universities around the world, each one making its lecture materials, assignments, notes and readings available online.
- 67.7K
 #3 · scikit-learn/scikit-learn
scikit-learn
scikit-learn is a Python library for machine learning, offering ready-made algorithms for classification, regression, clustering, dimensionality reduction and more, built on top of SciPy.
- 4

wrk
40.4Kwg/wrk · Cwrk is a modern HTTP benchmarking tool that generates significant load against a server using a single multi-core machine, measuring latency and throughput.
- 5
umami
39.4Kumami-software/umami · TypeScriptUmami is a privacy-first web analytics platform that tracks traffic, campaigns, behavior, conversions, and revenue without cookies or surveillance, as either a self-hosted app or a cloud service.
- 6

numpy
33Knumpy/numpy · PythonNumPy is the fundamental package for scientific computing with Python — the array-and-math foundation that most numerical Python code builds on.
- 7
awesome-datascience
30.2Kacademic/awesome-datascienceAn open-source, community-maintained Data Science repository — essentially a giant curated list of resources (courses, tutorials, algorithms, tools, books, datasets, communities) for learning and applying data science to real-world problems. Around 30k stars, around since 2014.
- 8

awesome-quant
30.2Kwilsonfreitas/awesome-quant · HTMLA curated list of libraries, packages and resources for quants - people doing quantitative finance: pricing, trading, backtesting, risk and market data.
- 9
analytics
29.5Kplausible/analytics · ElixirPlausible Analytics is an open source, privacy-first web analytics tool — a lightweight, cookie-free Google Analytics alternative, offered as a managed cloud or a self-hosted Community Edition.
- 10
hyperfine
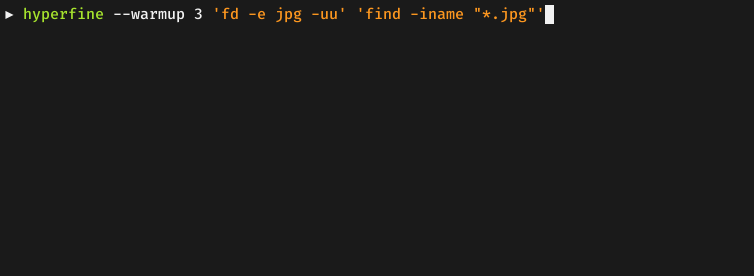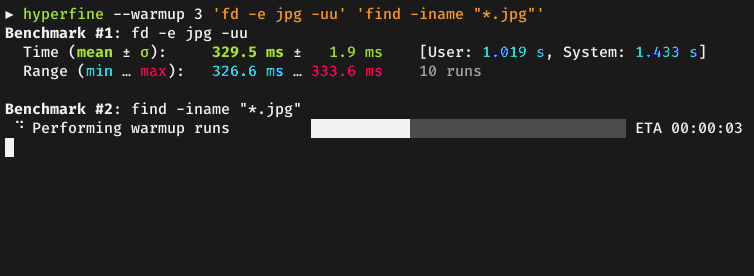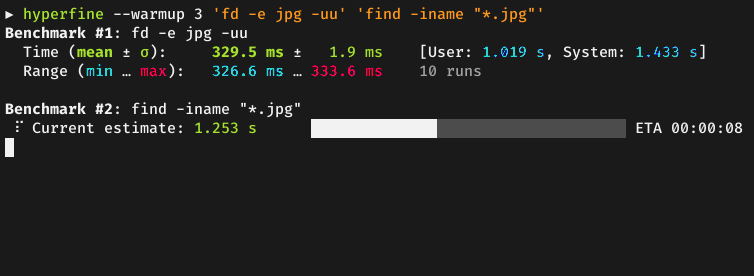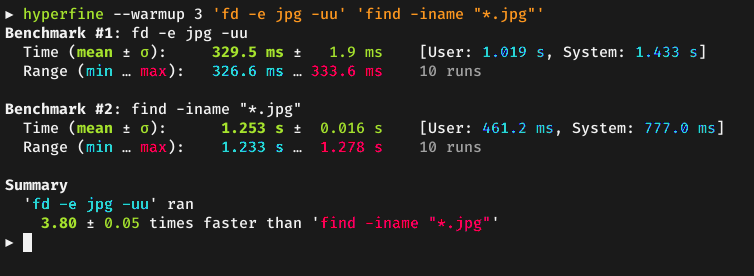
29.1Ksharkdp/hyperfine · Rusthyperfine is a command-line benchmarking tool: it times shell commands over many runs and gives you solid statistics — mean, min, max and relative speed — instead of a single noisy number.
- 11

COVID-19
28.9KCSSEGISandData/COVID-19The COVID-19 data repository by Johns Hopkins University's Center for Systems Science and Engineering (CSSE) — the case data behind their widely used pandemic Visual Dashboard.
- 12

Probabilistic-Programming-and-Bayesian-Methods-for-Hackers
28.2KCamDavidsonPilon/Probabilistic-Programming-and-Bayesian-Methods-for-Hackers · Jupyter NotebookAn open-source introductory book, Bayesian Methods for Hackers, that teaches Bayesian inference and probabilistic programming in pure Python with PyMC, built around runnable Jupyter notebook chapters.
- 13

go
26.3Kdatasciencemasters/goThe Open Source Data Science Masters (OSDSM) is a free, self-guided curriculum that collects the best open university courses, books, and tutorials to prepare someone for an entry-level Data Scientist role.
- 14
homemade-machine-learning
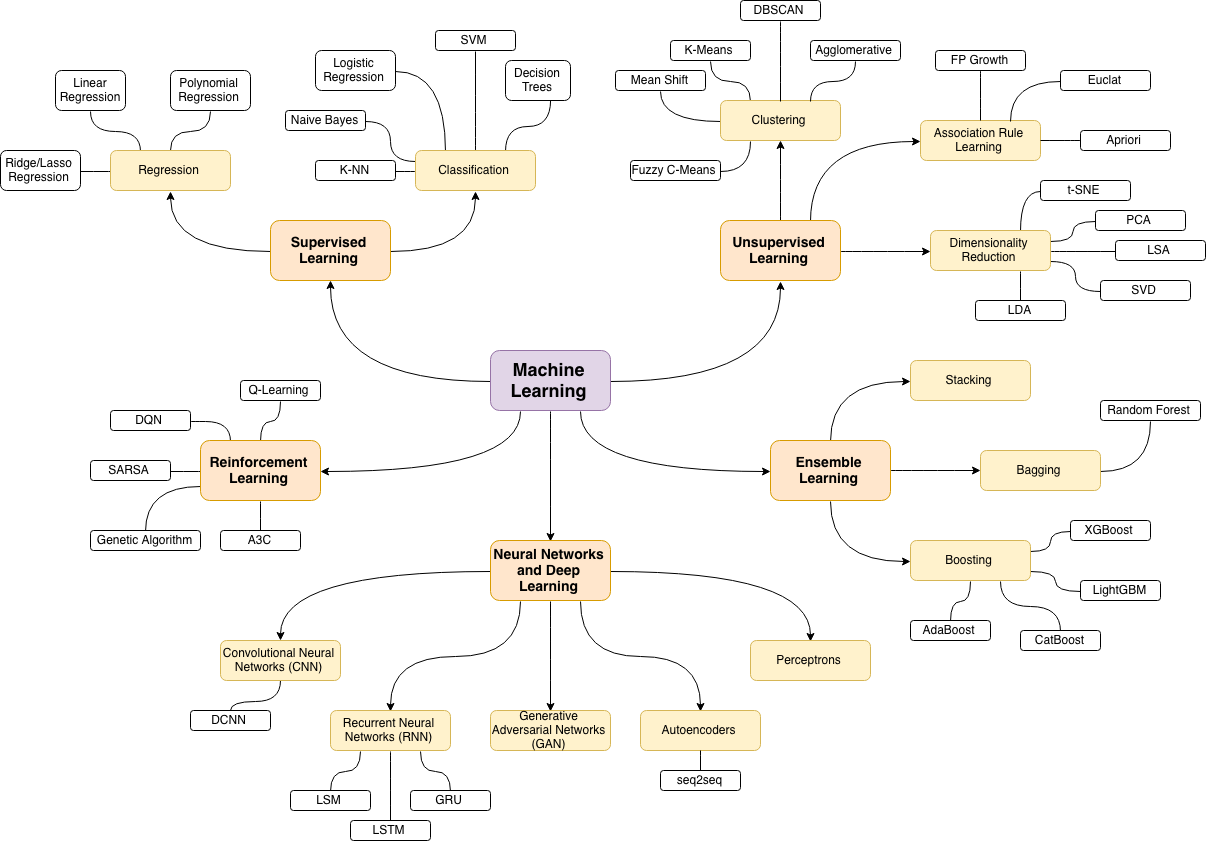
24.8Ktrekhleb/homemade-machine-learning · Jupyter NotebookA collection of popular machine learning algorithms implemented from scratch in Python, each paired with an interactive Jupyter Notebook demo and an explanation of the math behind it.
- 15
data-science
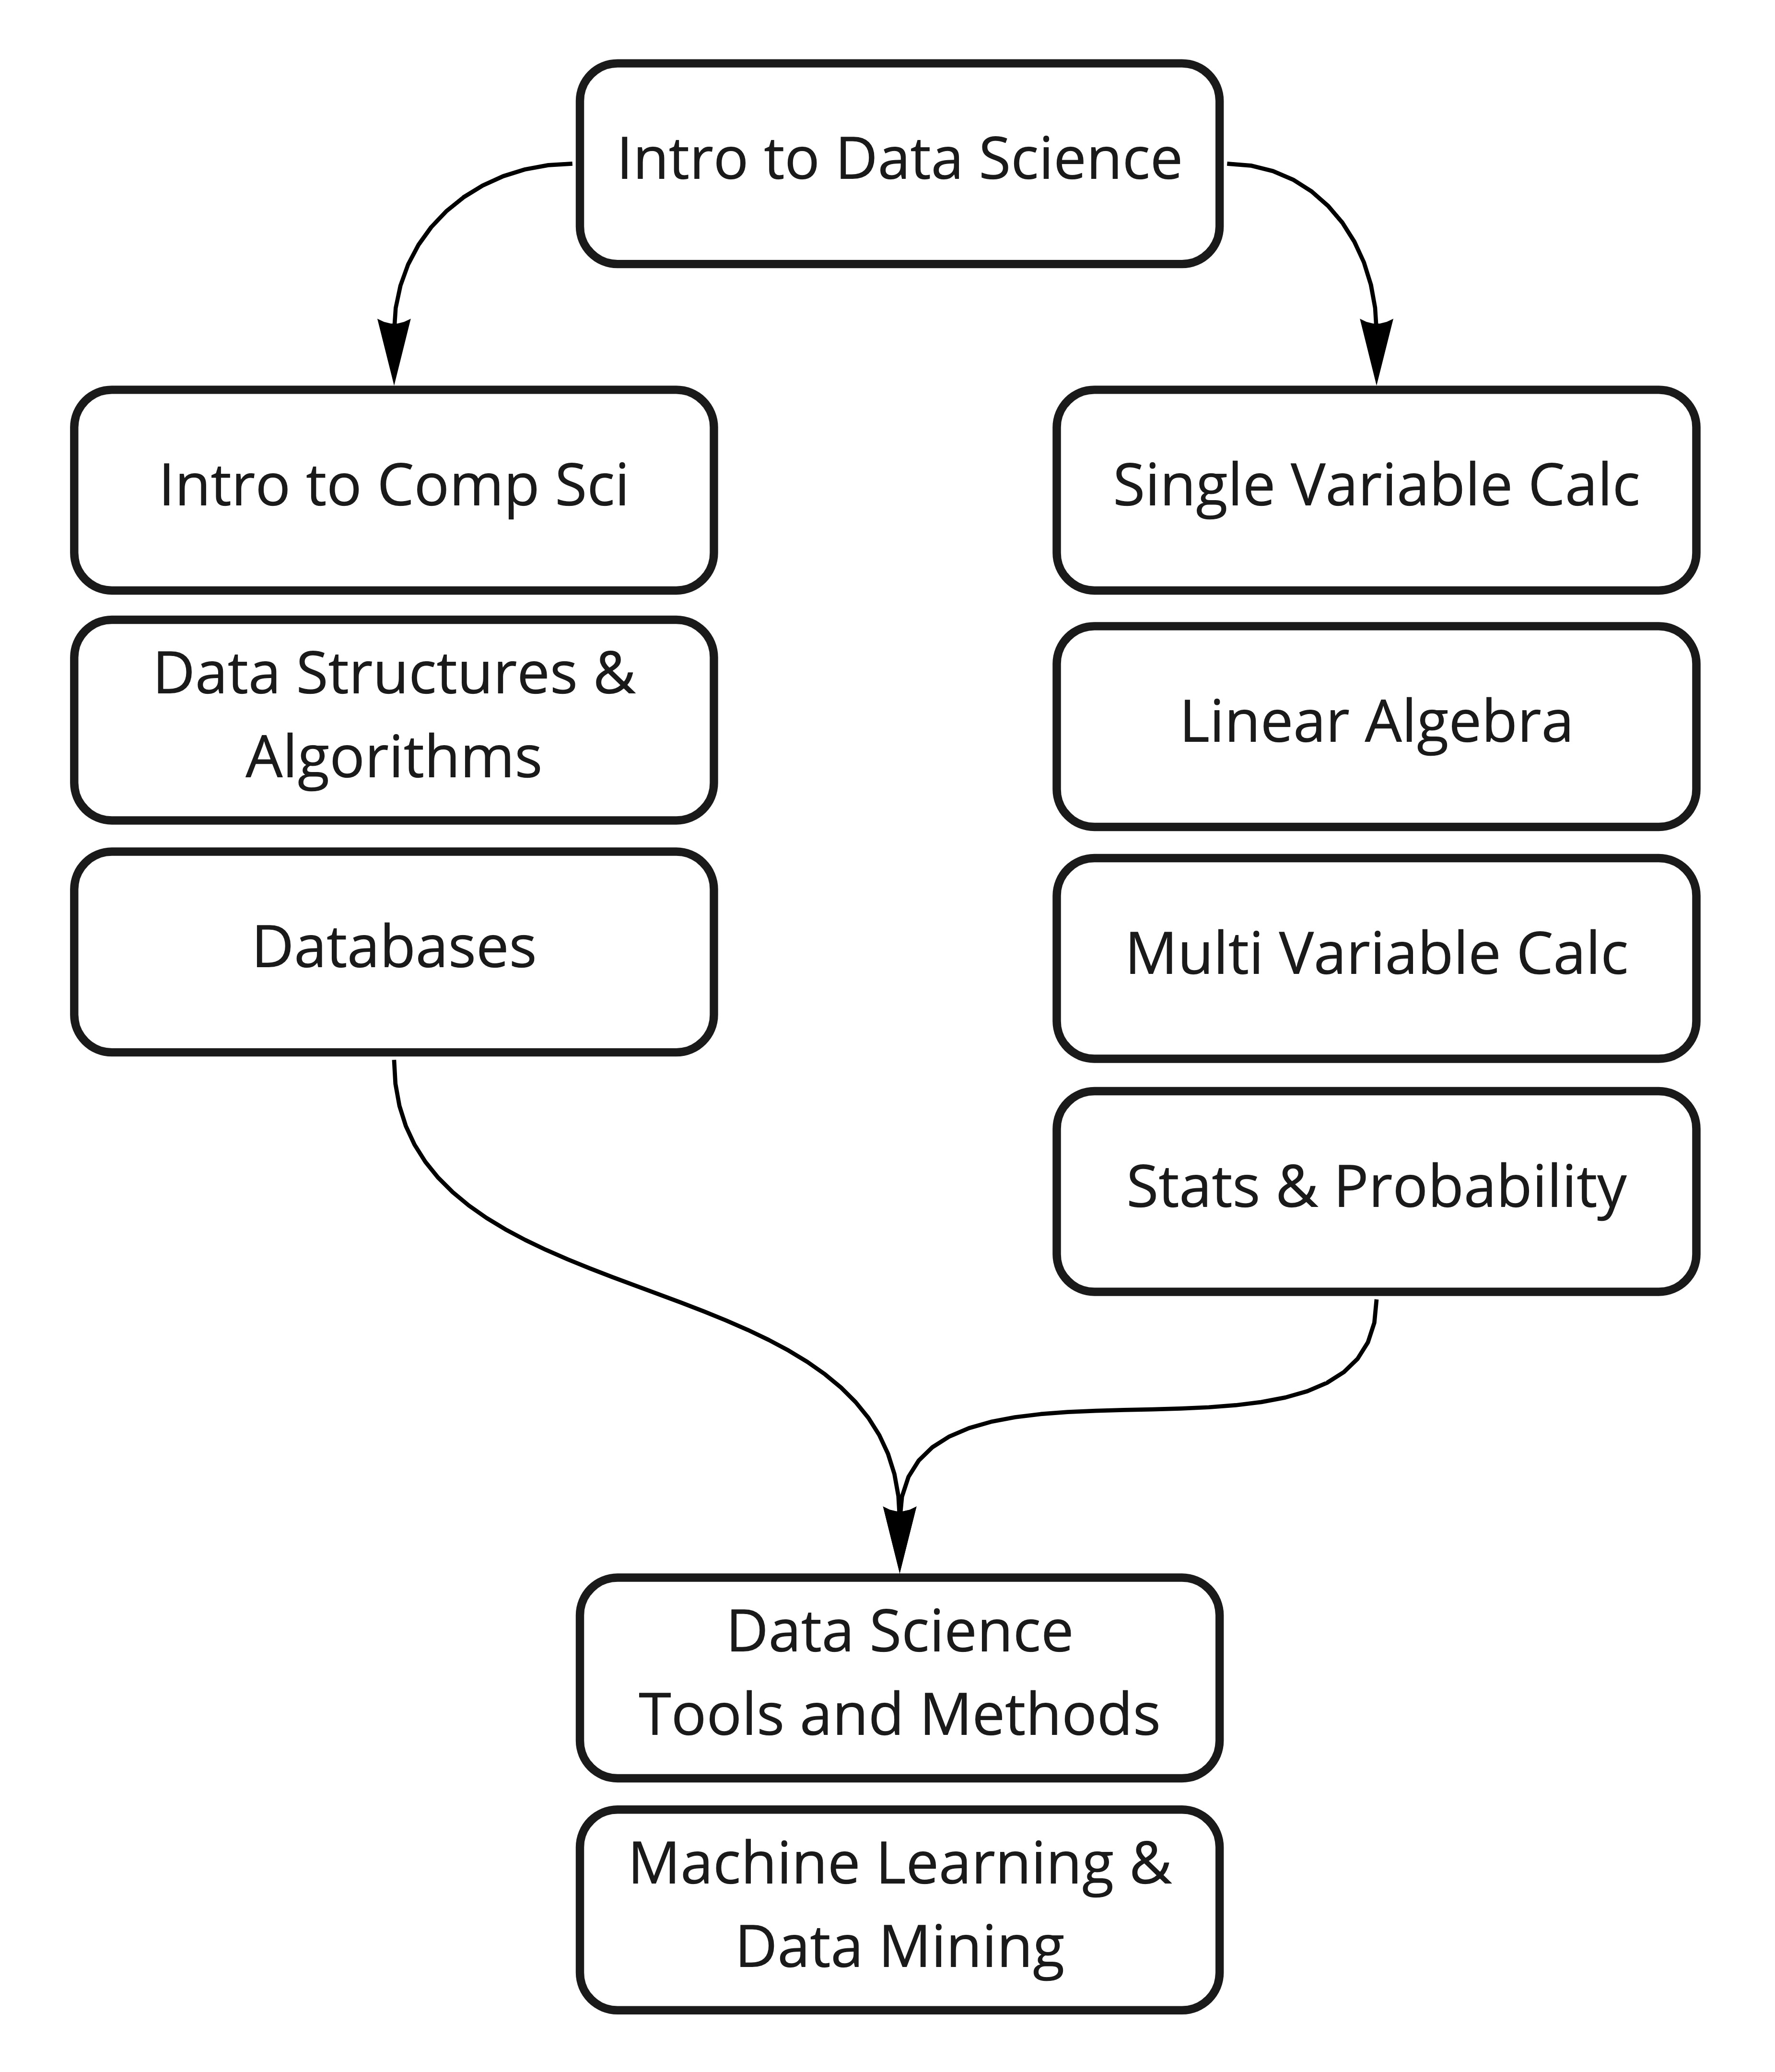
22.3Kossu/data-scienceOSSU Data Science is a free, self-taught curriculum that mirrors an undergraduate degree in data science, built from MOOCs offered by top universities, covering everything from intro programming through machine learning and a final project.
- 16
100-Days-Of-ML-Code
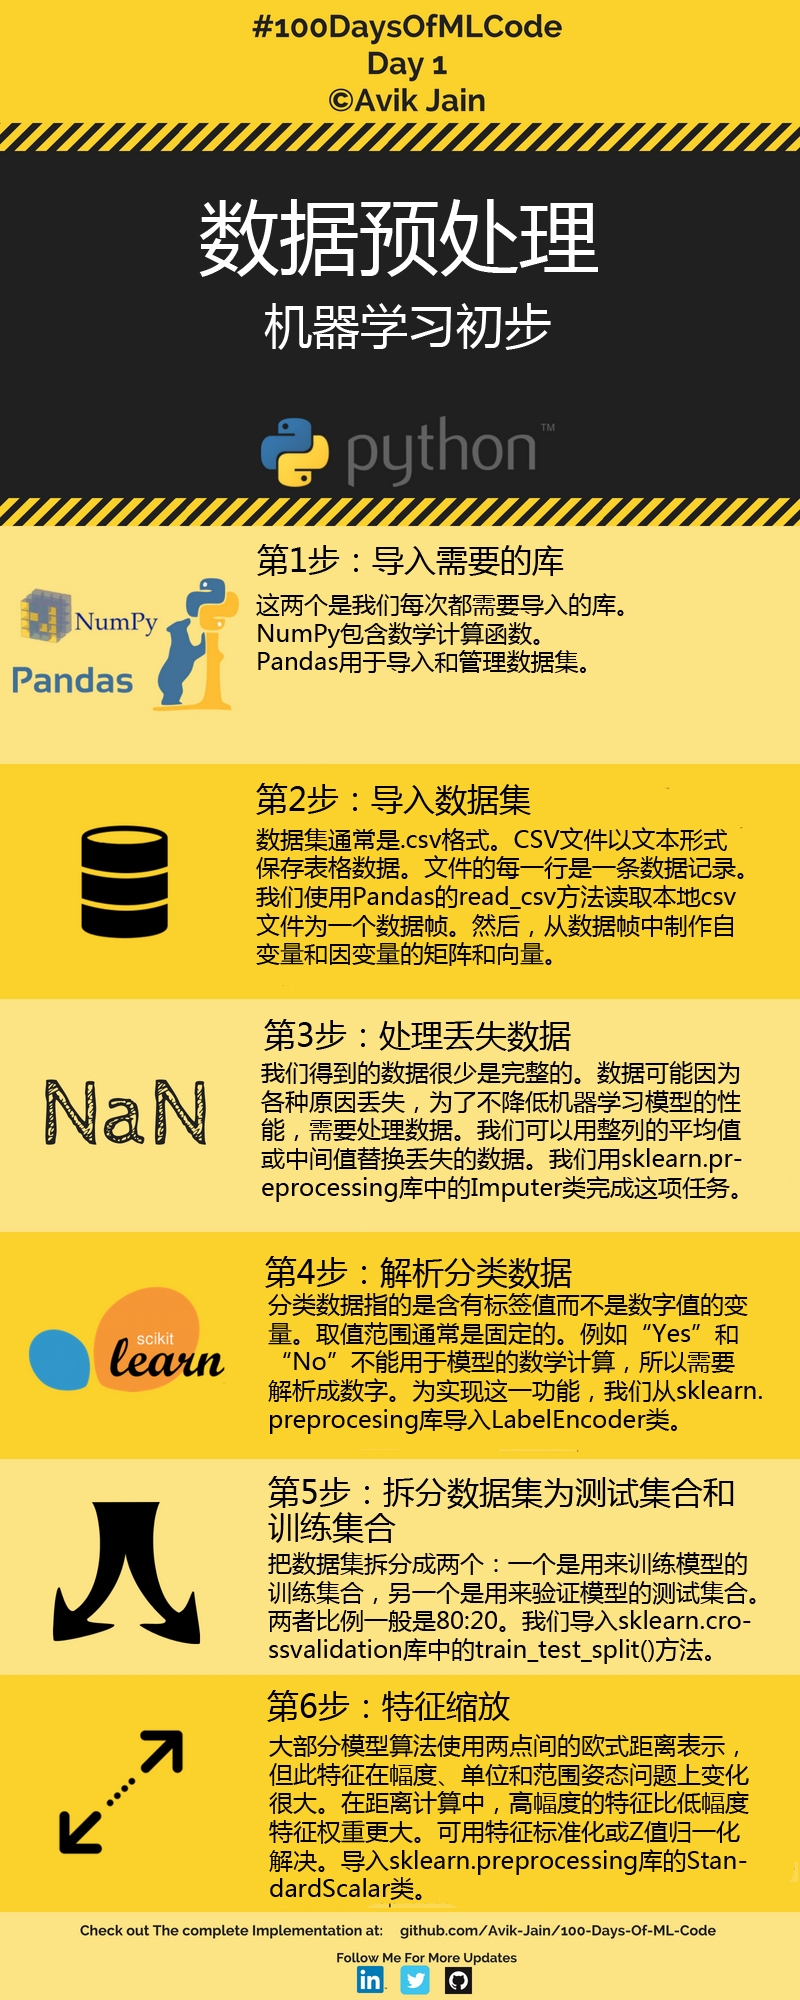
22.2KMLEveryday/100-Days-Of-ML-Code · PythonThe Chinese edition of the 100 Days of ML Code challenge: a day-by-day machine learning learning log with infographics, notes and Python code, spanning supervised and unsupervised learning. It translates the original challenge by Avik-Jain and has gathered 22k+ stars.
- 17

matomo
22Kmatomo-org/matomo · PHPMatomo (formerly Piwik) is the leading free open-source web analytics platform — a privacy-focused alternative to Google Analytics that you install on your own server. It is already used on more than 1,400,000 websites.
- 18

excelize
21Kqax-os/excelize · GoExcelize is a library written in pure Go for reading and writing Microsoft Excel spreadsheet files in the XLAM, XLSM, XLSX, XLTM and XLTX formats.
- 19

Administrative-divisions-of-China
21Kmodood/Administrative-divisions-of-China · JavaScriptChina's administrative divisions at five levels — provinces, cities, counties, towns and villages — each with its official statistics code and name, provided as JSON, CSV and SQLite files.
- 20

prophet
20.4Kfacebook/prophet · PythonProphet is an open-source forecasting procedure for time series: an additive model fits non-linear trends with yearly, weekly and daily seasonality plus holiday effects. It is aimed at series with strong seasonal effects and several seasons of history, and handles missing data, trend shifts and outliers well.
- 21
SummaryOfLoanSuspension
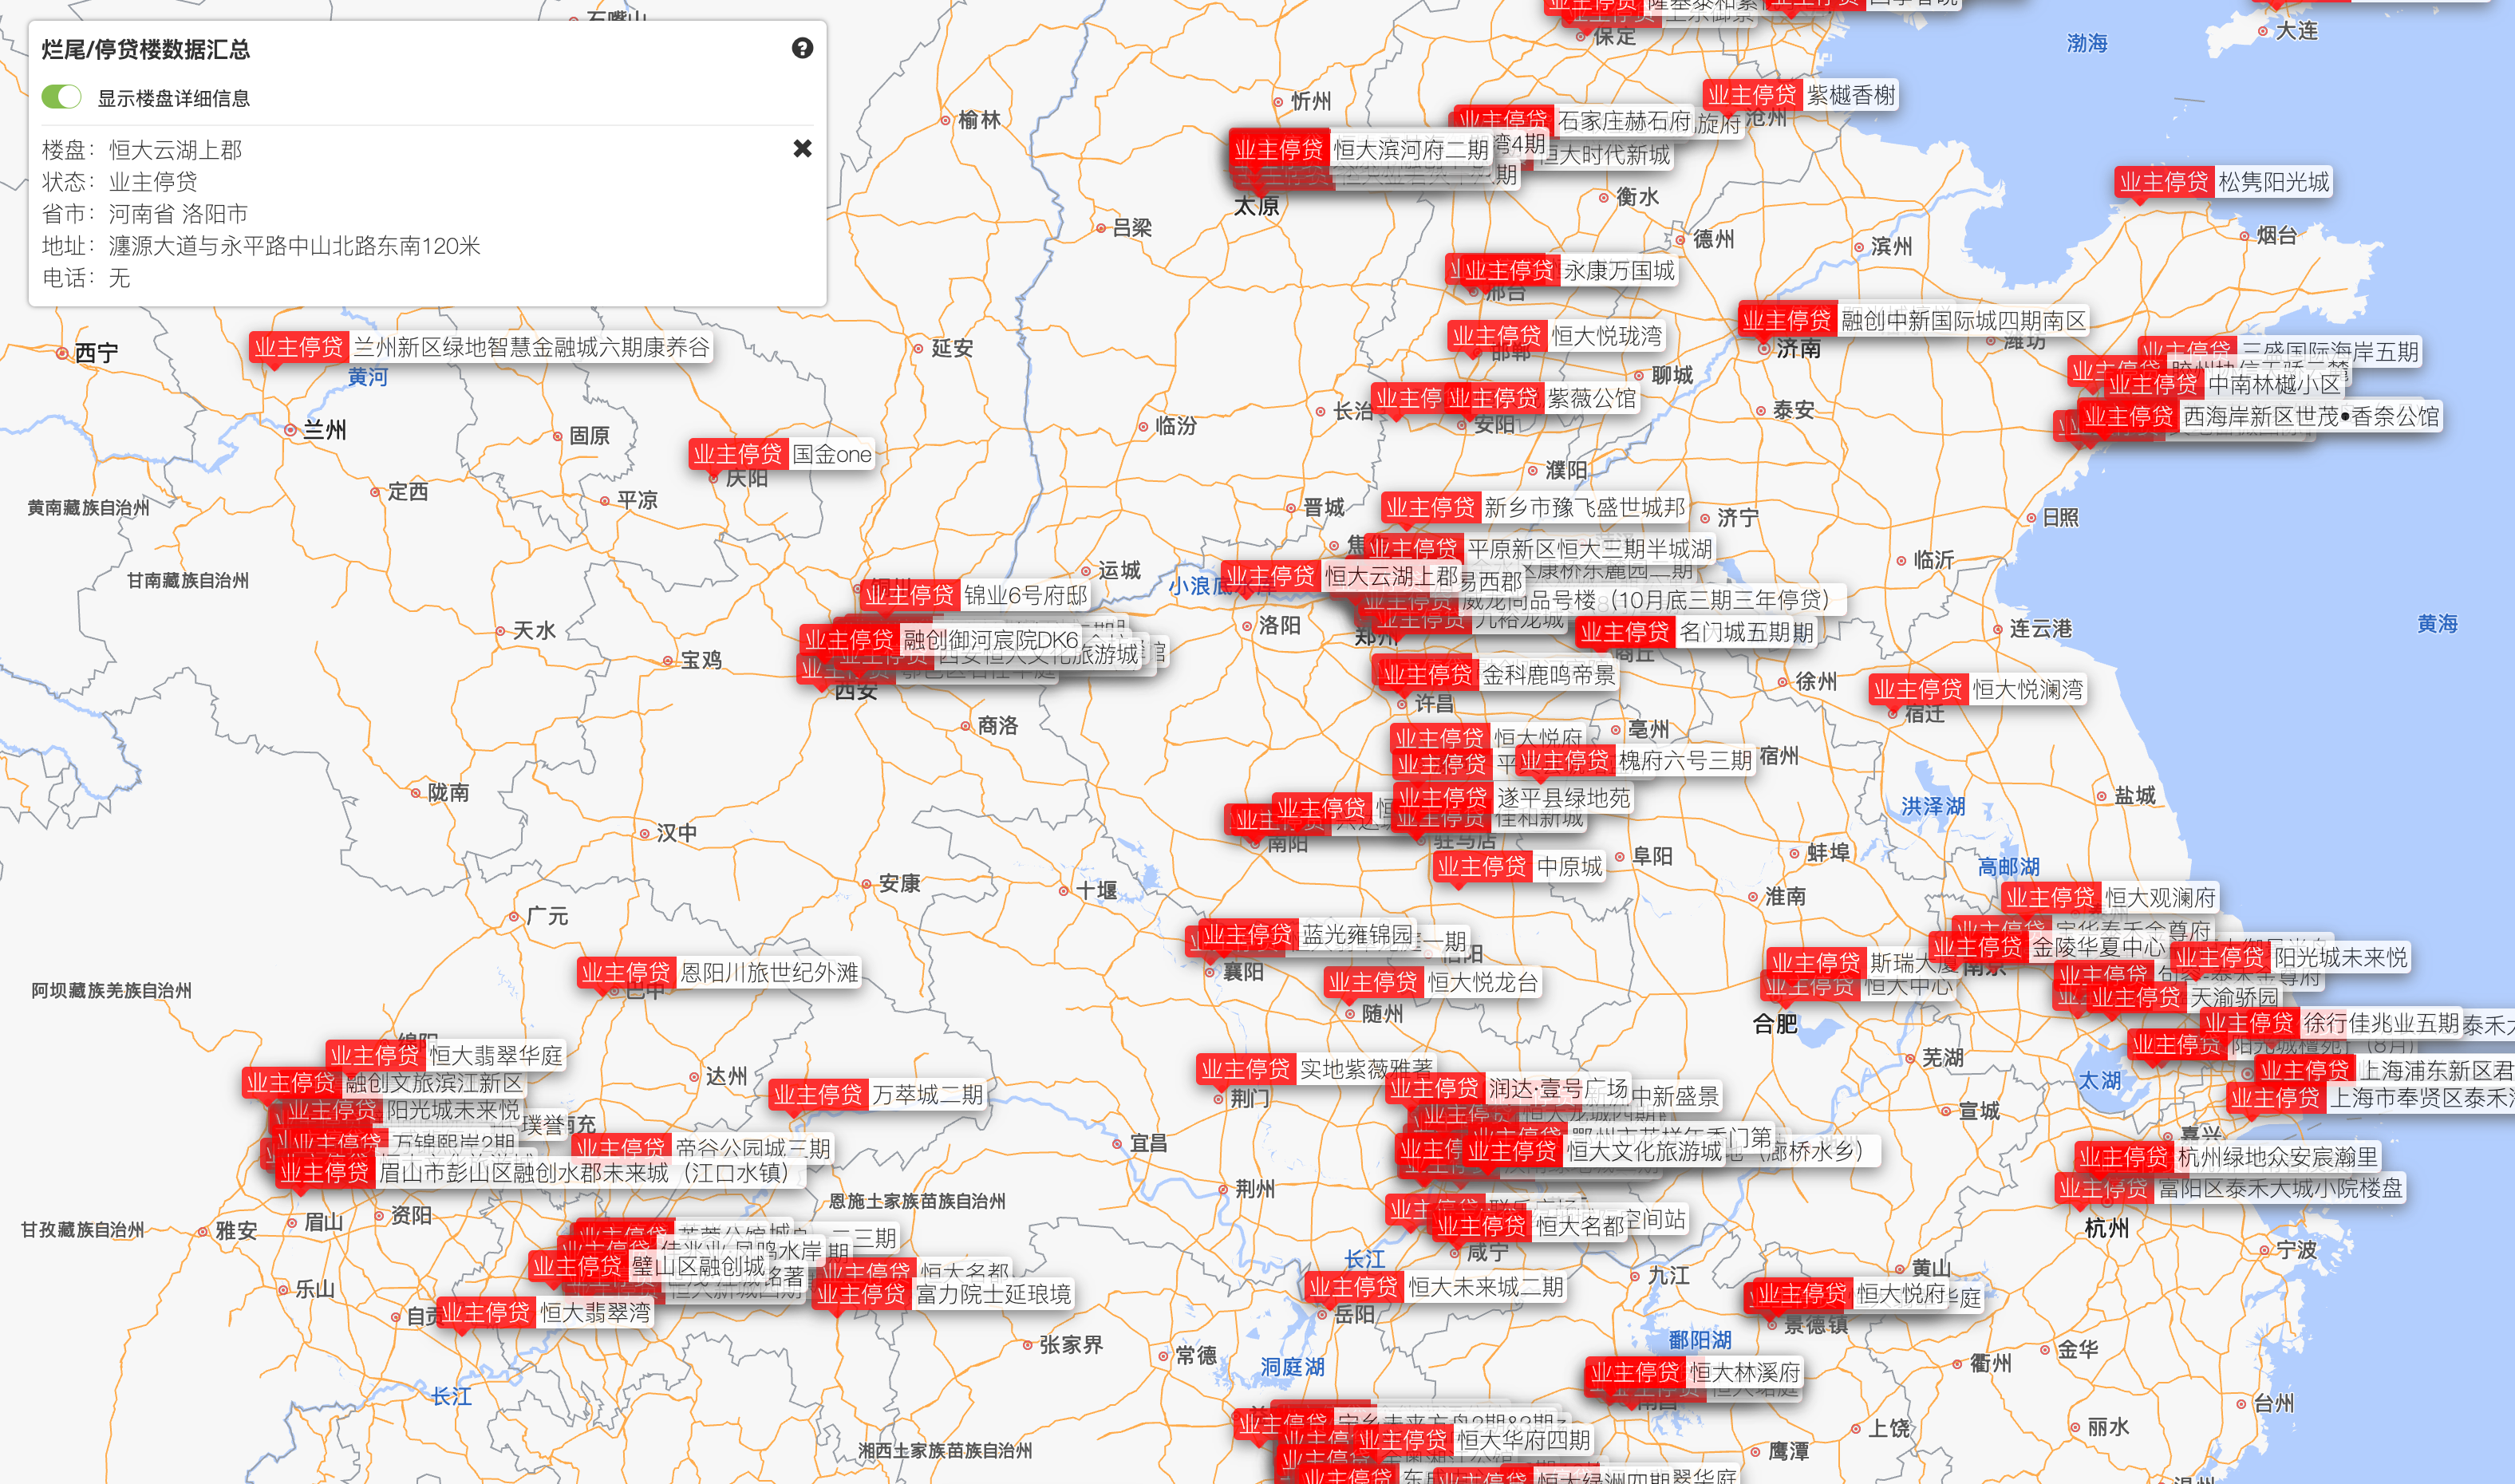
20.3KWeNeedHome/SummaryOfLoanSuspension · HTMLA community-run summary of mortgage-suspension notices from buyers of unfinished apartment projects across China — about 351 projects by 135 developers, organized by province, city and developer.
- 22
stanford-cs-229-machine-learning
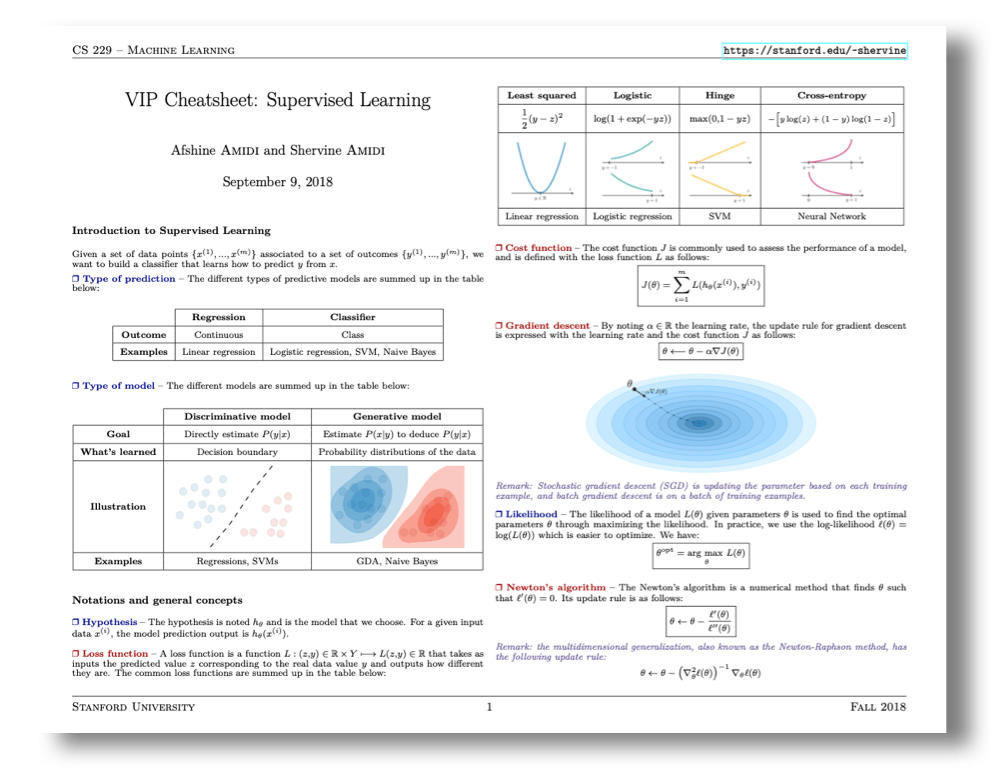
20.3Kafshinea/stanford-cs-229-machine-learningA collection of cheatsheets and refreshers that summarize all the key concepts taught in Stanford's CS 229 Machine Learning course, covering supervised learning, unsupervised learning, deep learning, and training tips.
- 23

lihang-code
19.6Kfengdu78/lihang-code · Jupyter NotebookA collection of Jupyter Notebook code implementations for every algorithm covered in Li Hang's book 'Statistical Learning Methods' (《统计学习方法》, 2nd edition), organized chapter by chapter.
- 24
Kalman-and-Bayesian-Filters-in-Python
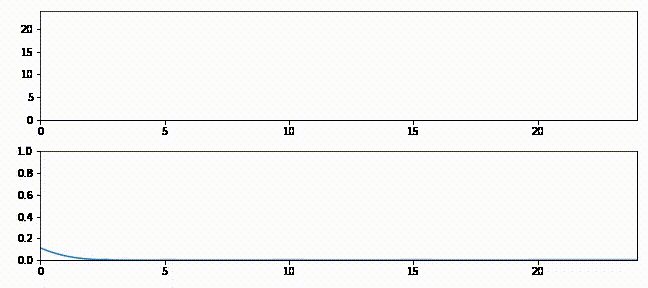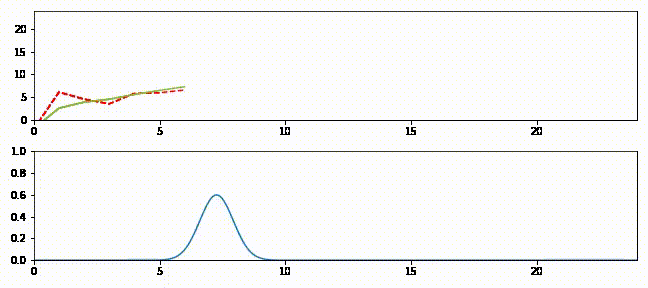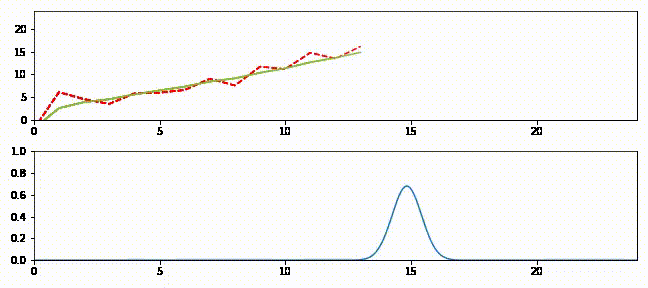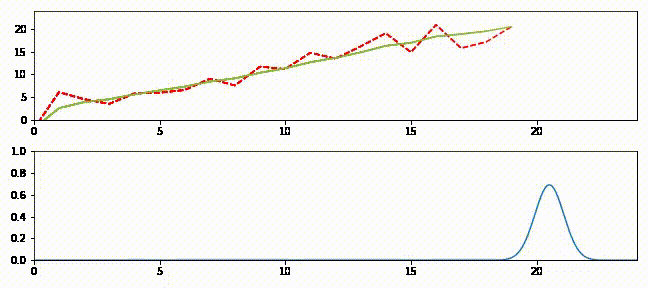
19.4Krlabbe/Kalman-and-Bayesian-Filters-in-Python · Jupyter NotebookAn interactive book that teaches Kalman and Bayesian filters (Kalman, extended Kalman, unscented Kalman, particle filters) using Python and Jupyter Notebook, focused on intuition rather than formal proofs.
- 25
caffeine
17.9Kben-manes/caffeine · JavaCaffeine is a high-performance, near-optimal in-memory caching library for Java with a Guava-inspired API.
- 26

data
17.5Kfivethirtyeight/data · Jupyter NotebookThis is the public repository of data sets and code behind the articles, graphics, and interactive features published by the journalism outlet FiveThirtyEight.
- 27

awesome-math
16.6Krossant/awesome-math · PythonA curated GitHub list of high-quality resources for learning, teaching, and doing mathematics — covering pure math, applied math, computation, formal proof, and AI in mathematics.
- 28

numpy-ml
16.3Kddbourgin/numpy-ml · PythonA collection of machine learning algorithms — Gaussian mixture models, HMMs, neural networks, tree ensembles, reinforcement learning agents and more — implemented from scratch in pure NumPy.
- 29

mml-book.github.io
16.1Kmml-book/mml-book.github.io · Jupyter NotebookThis is the companion website for the book 'Mathematics For Machine Learning', providing exercises and Jupyter notebooks that go along with the book's chapters.
- 30
github-trends
15.9Kavgupta456/github-trends · PythonGitHub Trends generates customizable stat cards for your GitHub profile README, computing your real contribution metrics from the GitHub API — lines of code written, by language, repository, and over time.
- 31

scipy
15.1Kscipy/scipy · PythonSciPy (pronounced 'Sigh Pie') is an open-source Python library for mathematics, science, and engineering.
- 32

tokei
15KXAMPPRocky/tokei · RustTokei is a CLI tool that counts code statistics (files, lines, blanks, comments, code) grouped by programming language across your codebase.
- 33
Virgilio
15Kvirgili0/Virgilio · Jupyter NotebookA free, open-source initiative that mentors anyone into Data Science: instead of drowning in a chaotic jungle of tutorials, you follow structured learning paths it has put together.
- 34
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 35

gs-quant
13.2Kgoldmansachs/gs-quant · PythonGS Quant is a Python toolkit for quantitative finance built by Goldman Sachs quants on top of their risk transfer platform, used for derivative structuring, trading strategy development, and risk management.
- 36
python-machine-learning-book
12.7Krasbt/python-machine-learning-book · Jupyter NotebookThis is the official code repository for the 1st edition of the 'Python Machine Learning' book by Sebastian Raschka, published by Packt in 2015. It holds the Jupyter notebooks with all the code examples from the book's 13 chapters, from basic classifiers to neural networks.
- 37

Github-Ranking
12.4KEvanLi/Github-Ranking · PythonGithub-Ranking is a repository that tracks and lists the most-starred and most-forked repositories on GitHub, with both an overall Top 100 and per-language Top 100 breakdowns.
- 38
MathModel
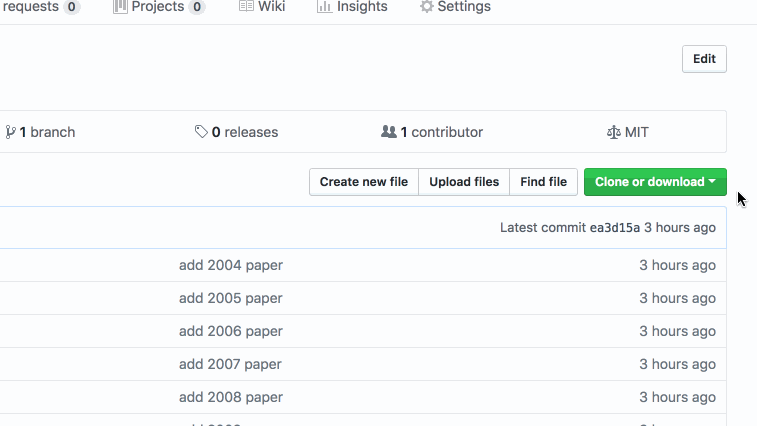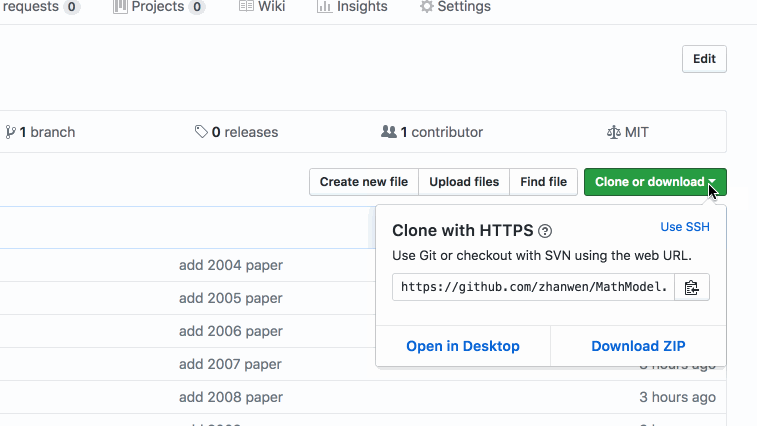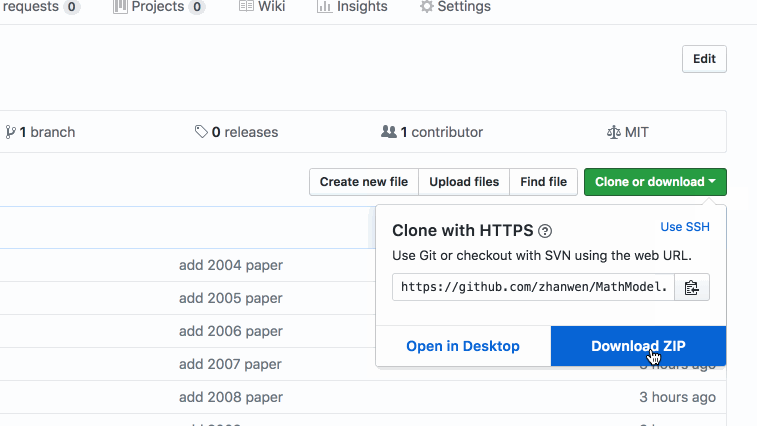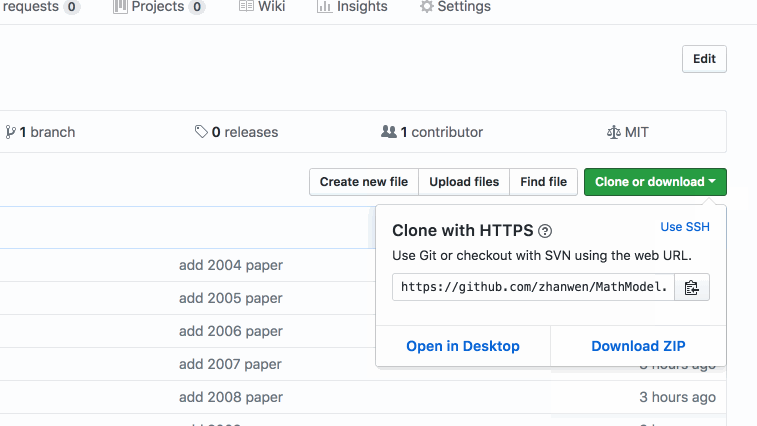
12.4Kzhanwen/MathModel · TeXA large Chinese repository collecting resources for mathematical modeling competitions: contest problems and award-winning papers from China's graduate and undergraduate math modeling contests (and some American MCM papers), plus LaTeX/Word paper templates, algorithm mind maps, textbooks, and Matlab tutorials.
- 39

PRML
11.7Kctgk/PRML · Jupyter NotebookA collection of Python implementations of the algorithms described in Christopher Bishop's book 'Pattern Recognition and Machine Learning' (PRML), organized as Jupyter notebooks by chapter.
- 40

statsmodels
11.7Kstatsmodels/statsmodels · Pythonstatsmodels is a Python package for statistical modeling and econometrics, providing estimation and inference for a wide range of statistical models as a complement to scipy.
- 41

Statistical-Learning-Method_Code
11.6KDod-o/Statistical-Learning-Method_Code · PythonA from-scratch Python implementation of every algorithm covered in Li Hang's book 'Statistical Learning Method' (统计学习方法), with heavily commented code that maps directly to the formulas in the book.
- 42

BenchmarkDotNet
11.5Kdotnet/BenchmarkDotNet · C#BenchmarkDotNet is a .NET library that turns ordinary methods into reliable, repeatable performance benchmarks and reports detailed statistics about the results.
- 43
mlcourse.ai
10.8KYorko/mlcourse.ai · PythonAn open Machine Learning course by the OpenDataScience (ods.ai) community, led by Yury Kashnitsky: 10 weeks that pair math-heavy lectures with hands-on assignments and Kaggle Inclass competitions, now taken self-paced.
- 44

xsv
10.8KBurntSushi/xsv · Rustxsv is a fast command-line toolkit written in Rust for working with CSV files: it indexes, slices, analyzes, splits and joins them right in the terminal.
- 45
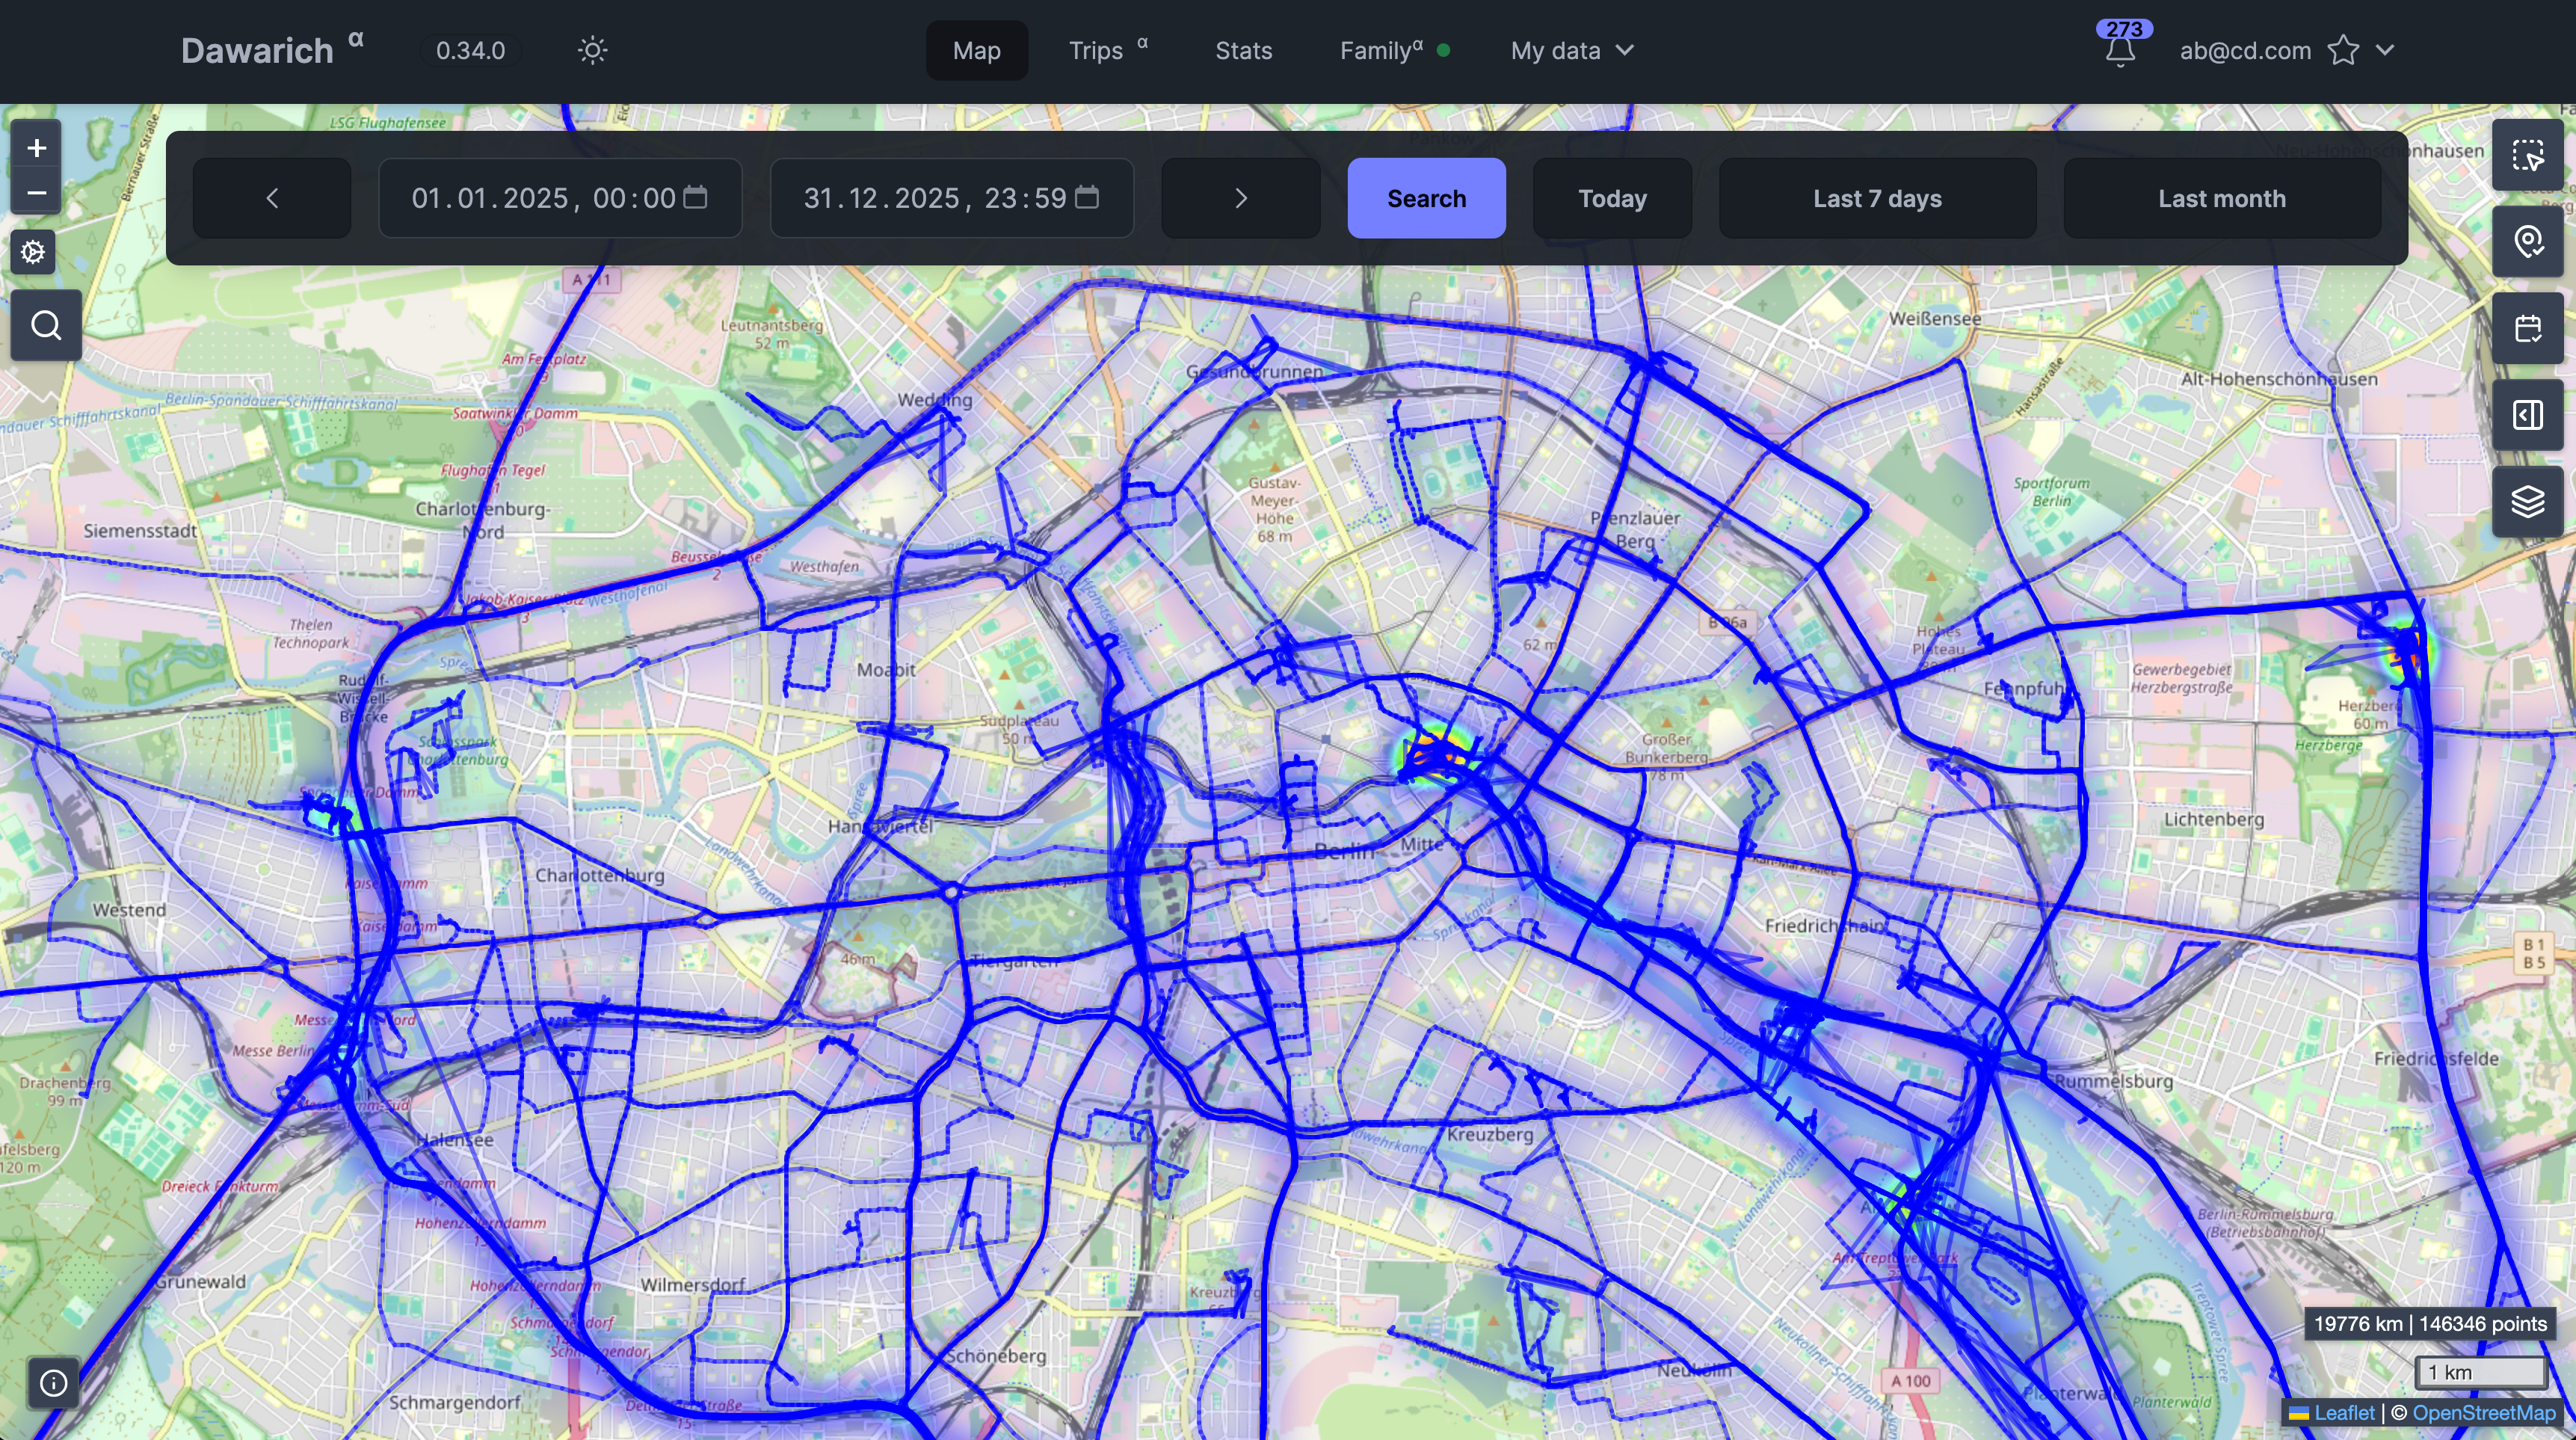
dawarich
10.7KFreika/dawarich · RubyDawarich is a self-hostable web app that replaces Google Timeline: it tracks your location history, shows it on an interactive map, and analyzes your travels.
- 46
turf
10.5KTurfjs/turf · TypeScriptTurf is a modular geospatial engine for JavaScript and TypeScript — a library for spatial analysis that works with GeoJSON data.
- 47

Book4_Power-of-Matrix
10.1KVisualize-ML/Book4_Power-of-Matrix · Jupyter NotebookThis is the companion repository for '矩阵力量' (Power of Matrix), the third book in the 'Iris Flower Book' (鸢尾花书) series. It teaches linear algebra and matrix theory step by step as a foundation for machine learning, paired with Jupyter notebooks that run every example.
- 48
sktime
10.1Ksktime/sktime · Pythonsktime is a Python library for machine learning with time series: one unified interface for forecasting, classification, clustering, and anomaly or changepoint detection.
- 49
tpot
10.1KEpistasisLab/tpot · Jupyter NotebookTPOT, the Tree-based Pipeline Optimization Tool, is a Python AutoML library that uses genetic programming to automatically optimize machine learning pipelines for your data; the README calls it your Data Science Assistant.
- 50
miller
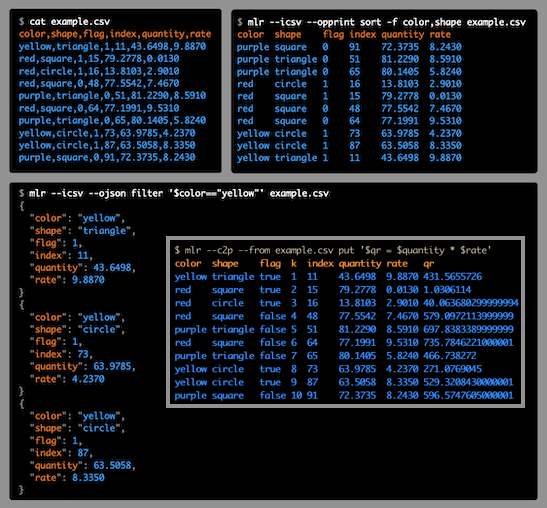
10Kjohnkerl/miller · GoMiller is a command-line toolkit like awk, sed, cut, join, and sort, but built for name-indexed data such as CSV, TSV, JSON, and JSON Lines: you address fields by name instead of counting column positions.
- 51
maths-cs-ai-compendium
7.7KHenryNdubuaku/maths-cs-ai-compendium · TypeScriptAn open, unconventional online textbook covering maths, computing and AI from the ground up — intuition first, real-world context, for practitioners who want deep understanding rather than exam survival.
- 52

codex-claude-academic-skills
5KzLanqing/codex-claude-academic-skills · PythonThree Claude Code / Codex Agent Skills built for Chinese academic researchers, covering the full research workflow: research-writing-skill for drafting and polishing papers, office-academic-skill for generating academic Word/PPT documents, and scientific-toolkit-skill for MATLAB/Python scientific computing and publication-quality figures.
- 53

prediction-market-analysis
3.9KJon-Becker/prediction-market-analysis · PythonIt's a framework for collecting and analyzing prediction market data from Polymarket and Kalshi, bundled with the largest publicly available dataset of their market and trade history.
- 54
lieflat-less-ai-tone
2.9Klarashero3-dotcom/lieflat-less-ai-tone · PythonA research-backed skill that detects and removes 'AI tone' from Chinese writing, based on a statistical study of a 2.83-million-character corpus comparing AI-generated and human-written text.
- 55
ModelTrace
1.7Kxqy2006/ModelTrace · JavaScriptModelTrace is a locally-run active model attribution tool: it sends three fixed challenge prompts to a target model, extracts an output fingerprint, and matches it against a known-model library to guess the model family and specific version.
- 56
livenerf
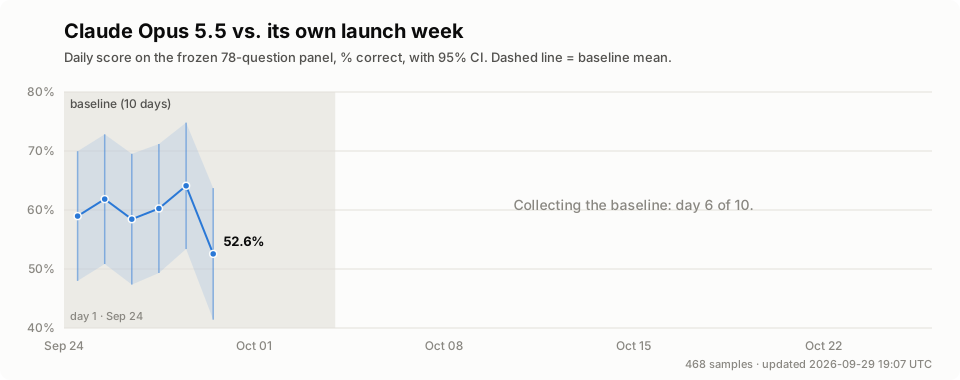
1.5Kninjahawk/livenerf · Pythonlivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
- 57

anti-gambling-trader-tw
1.1Kmars-tw/anti-gambling-trader-tw · PythonA free, open-source Python tool that analyzes trading records (Taiwan stocks, US stocks, crypto, forex) to statistically test whether your profits are a repeatable edge or just luck plus survivorship bias, scans for scam language and fake performance claims, and can scaffold backtestable or paper-trading automation projects.
- 58

hypoarena
555OpSafari/hypoarena · Pythonhypoarena is a fully offline workbench that decomposes the generate-debate-evolve 'AI co-scientist' pipeline into individually testable mechanisms: a citation-bearing hypothesis-evidence graph, a synthetic literature factory, grounding verification, pluggable agent adapters, Elo tournaments, paraphrase dedup, and Bayesian evidence accumulation.
- 59
From-Calibrated-Confidence-to-Calibrated-Reliance
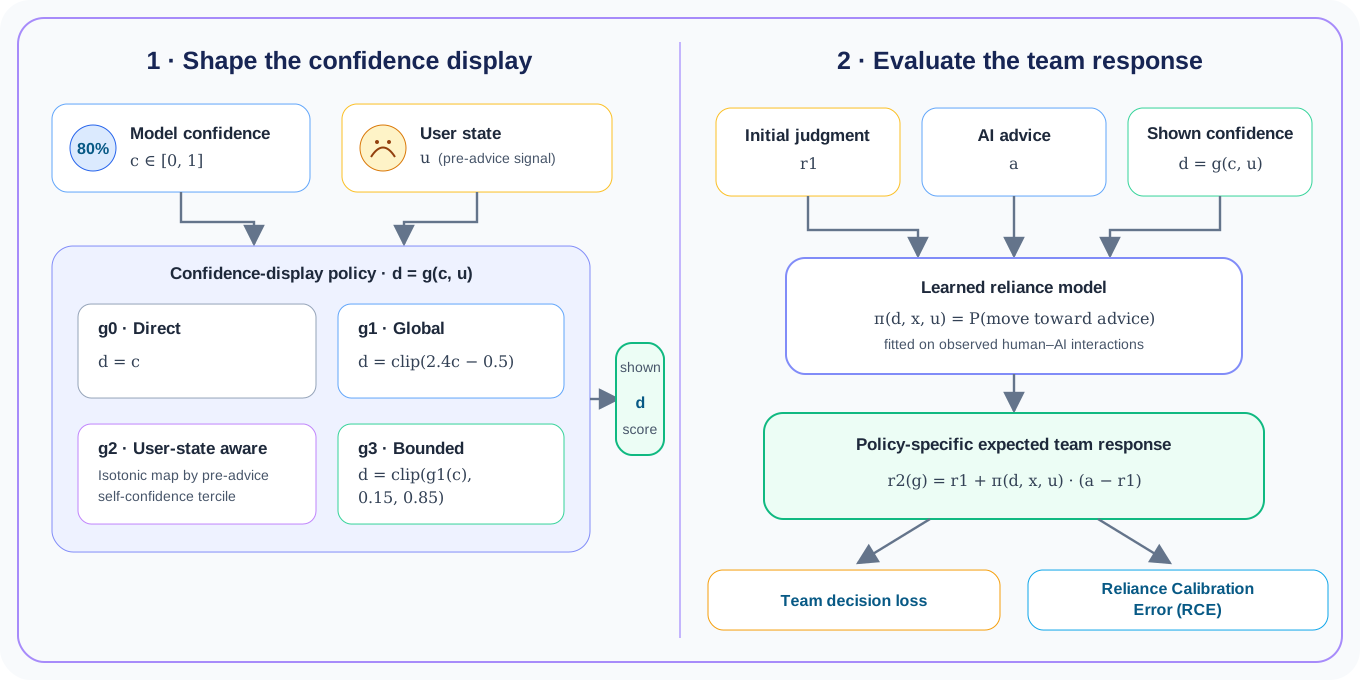
304OliverDOU776/From-Calibrated-Confidence-to-Calibrated-Reliance · PythonCompanion code for an accepted ACM TSC paper: it implements the Reliance Calibration Error (RCE) metric, the g0-g3 confidence-display policies, and a reproducible CPU-only analysis of how well human-AI teams calibrate on displayed confidence.
- 60

cumcm-c-problem-lfs
148liufanshan11/cumcm-c-problem-lfs · TeXA skill for AI agents that handles Problem C of CUMCM, China's national undergraduate math-modeling contest: a full modeling-and-paper production workflow distilled from 2018–2025 official C-problem papers, expert commentary and grading standards.
- 61

timeseries-atlas
133dreamers-laboratory/timeseries-atlas · PythonA curated map of modern time-series forecasting architectures, from DLinear to foundation models like Chronos-2, each in its own directory with a short README and, for some, a runnable PyTorch implementation.
Related topics
Often tagged together
- open-source5,666
- python2,397
- data-science231
- machine-learning915
- education933
- mit3,311
- research764
- tutorial626
- data-analysis73
- library1,587
- linux4,181
- data-visualization201
- algorithms142
- developer-tools2,927
- learning512
- macos3,544
- cross-platform2,622
- mathematics53
- resources706
- windows3,401
- chinese1,157
- deep-learning736
- free970
- numpy73