Topics / #document-parsing
Document-parsing projects on GitHub
Extracting structured content from PDFs, scans, and office documents.
As of , the most-starred Document-parsing projects on GitHub are markitdown (190.8K stars), ragflow (92.4K stars) and PaddleOCR (91.3K stars). GitHub.Locker tracks 13 Document-parsing repositories with 593.2K stars combined. The fastest-growing on October 17 was markitdown, with +160 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +160
markitdown
microsoft/markitdown · ★ 190.8KMarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
 +46
PaddleOCR
PaddlePaddle/PaddleOCR · ★ 91.3KPaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
 +45
ragflow
infiniflow/ragflow · ★ 92.4KRAGFlow is an open-source Retrieval-Augmented Generation (RAG) engine that combines RAG with Agent capabilities to build a context layer for LLMs, turning complex enterprise data into production-ready AI systems.
 +43
docling
docling-project/docling · ★ 69KDocling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
The all-time top
13 projects · by stars
- 190.8K#1 · microsoft/markitdown
markitdown
MarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
- 92.4K#2 · infiniflow/ragflow
ragflow
RAGFlow is an open-source Retrieval-Augmented Generation (RAG) engine that combines RAG with Agent capabilities to build a context layer for LLMs, turning complex enterprise data into production-ready AI systems.
- 91.3K#3 · PaddlePaddle/PaddleOCR
PaddleOCR
PaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
- 4
docling
69Kdocling-project/docling · PythonDocling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
- 5
marker
40.5Kdatalab-to/marker · PythonMarker is a document conversion tool that turns PDFs (and other document types) into markdown, JSON, HTML, or chunked output quickly and accurately, extracting tables, equations, forms, and images along the way.
- 6
opendataloader-pdf
29.7Kopendataloader-project/opendataloader-pdf · JavaAn open-source PDF parser built for AI pipelines: it turns PDFs into Markdown, JSON (with bounding boxes) and HTML, and can auto-tag untagged PDFs into screen-reader-ready Tagged PDFs.
- 7

kotaemon
25.8KCinnamon/kotaemon · PythonKotaemon is an open-source RAG tool for chatting with your documents: a clean web UI where you ask questions about your own files, serving both end users and developers.
- 8
unstructured
15.6KUnstructured-IO/unstructured · HTMLUnstructured is an open-source ETL toolkit that converts complex documents like PDFs, Word docs, HTML and images into clean, structured data (JSON) ready for LLMs, RAG pipelines and vector databases.
- 9
easy-dataset
15KConardLi/easy-dataset · JavaScriptEasy Dataset is an app that turns domain documents (PDF, Markdown, DOCX, TXT, EPUB) into structured datasets for LLM fine-tuning, RAG, and model evaluation. It extracts questions from your text, generates answers with an LLM, and exports ready-to-use training data.
- 10
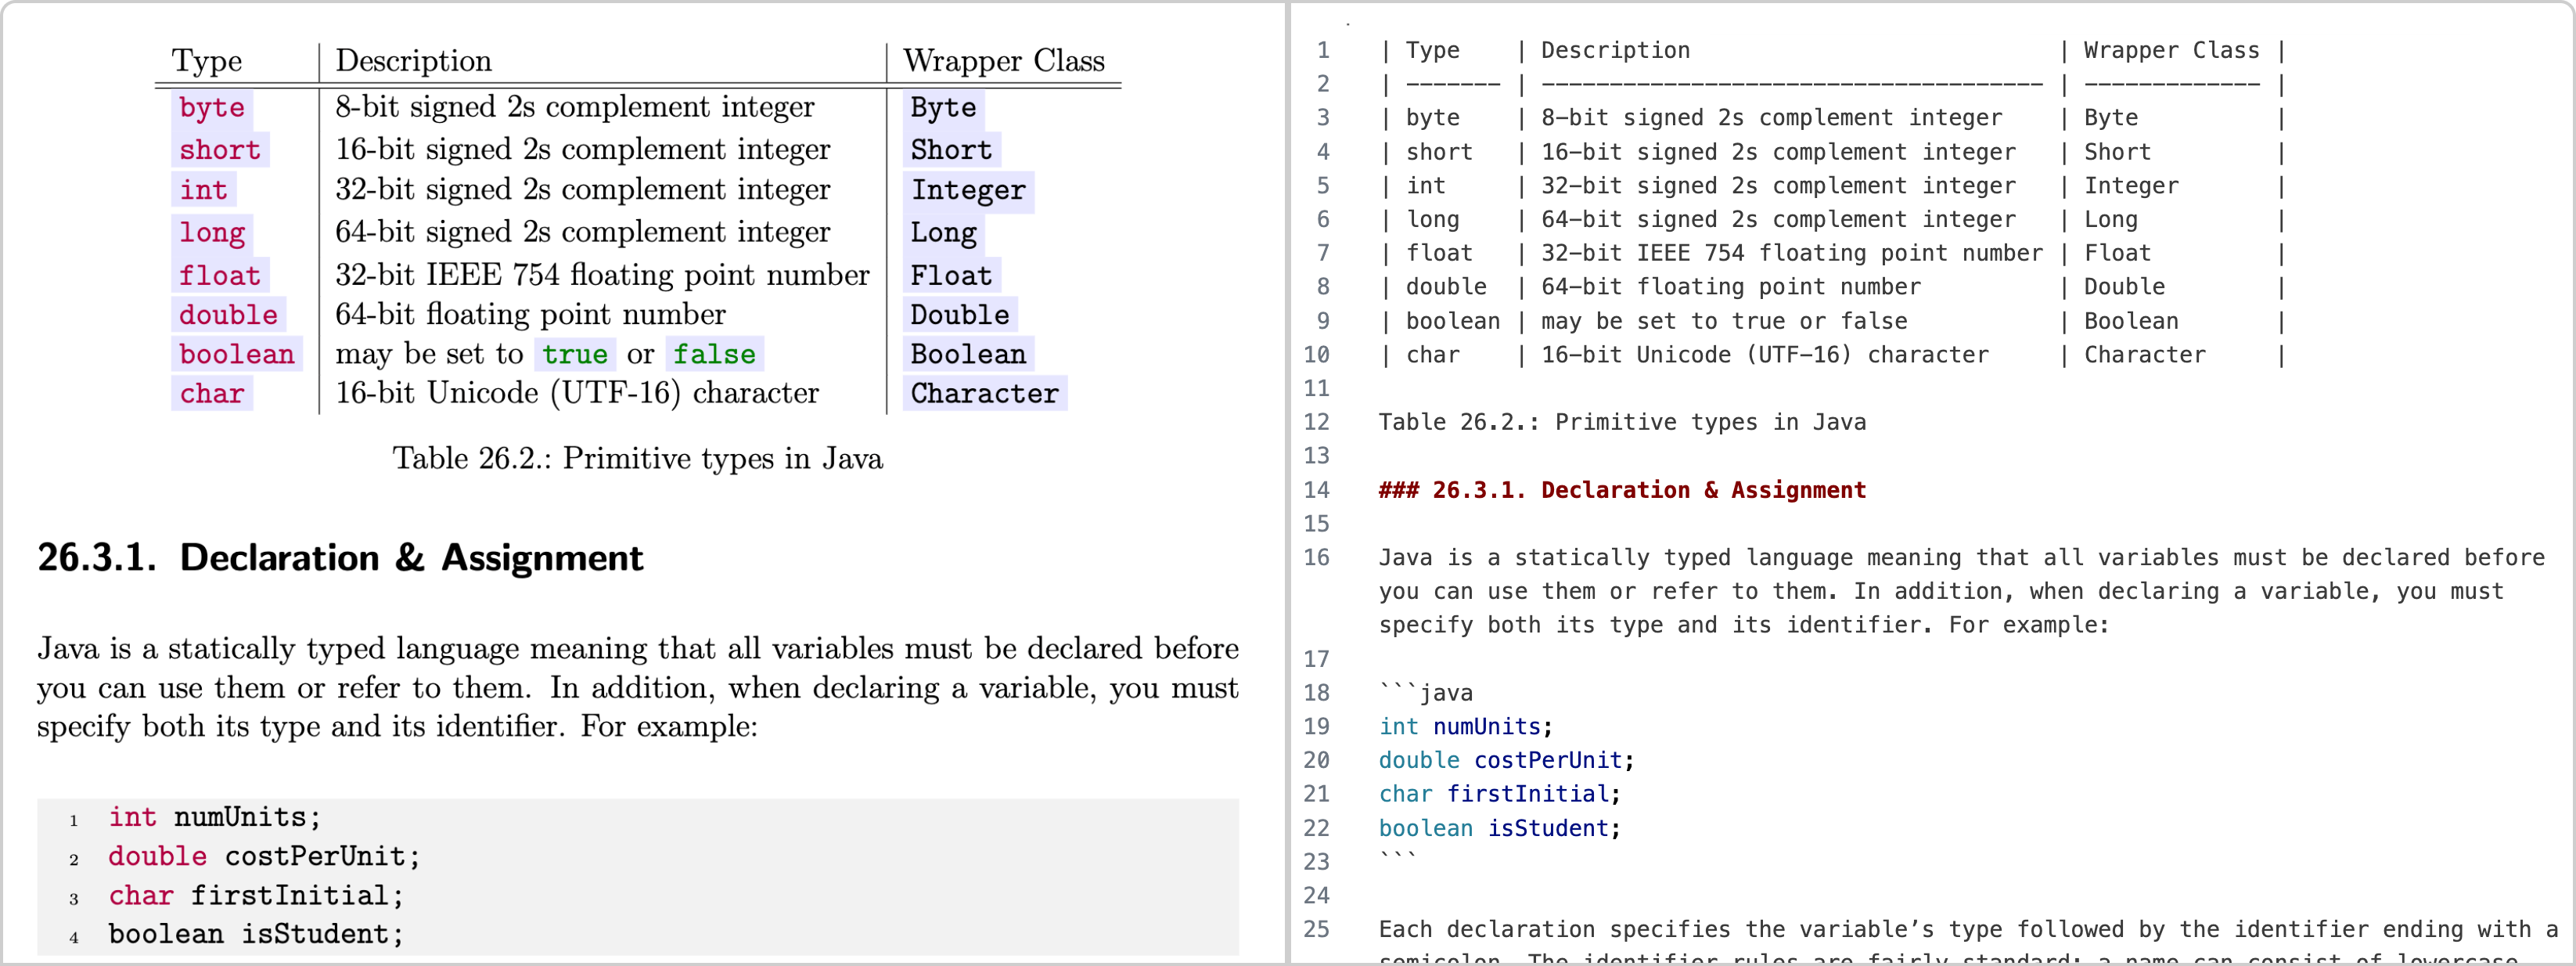
zerox
12.3Kgetomni-ai/zerox · TypeScriptZerox is an open-source OCR and document-extraction tool powered by vision models: give it a PDF, DOCX or image and it returns Markdown — or structured data if you provide a schema.
- 11

PDF-Extract-Kit
10Kopendatalab/PDF-Extract-Kit · PythonPDF-Extract-Kit is an open-source Python toolkit that bundles state-of-the-art models for layout detection, formula detection, formula recognition, OCR, and table recognition to pull high-quality content out of complex PDF documents.
- 12
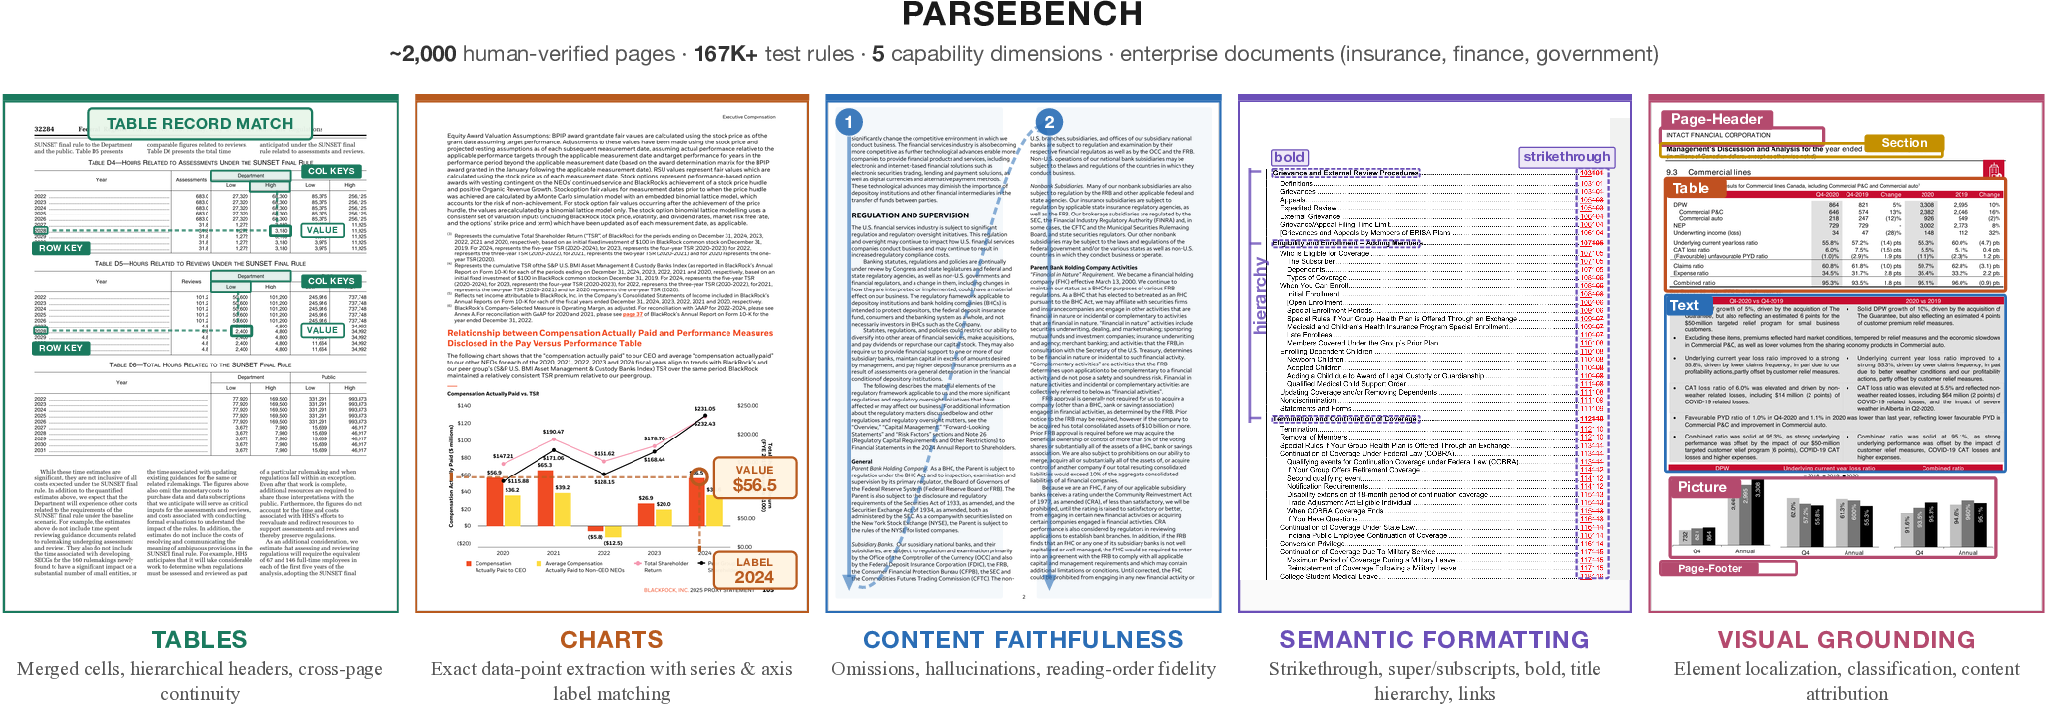
ParseBench
603run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 13
paper-docx
126paper-instruments/paper-docx · Pythonpaper-docx is an agent-safe fork of python-docx for creating and editing Microsoft Word (.docx) documents, built to refuse unsupported operations instead of silently corrupting files.
Related topics
Often tagged together