Topics / #pandas
Pandas projects on GitHub
Python library for tabular data manipulation and analysis.
As of , the most-starred Pandas projects on GitHub are Python-100-Days (187.3K stars), 30-Days-Of-Python (76.5K stars) and scikit-learn (67.7K stars). GitHub.Locker tracks 44 Pandas repositories with 1.1M stars combined. The fastest-growing on October 17 was solo_jev, with +143 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +143
solo_jev
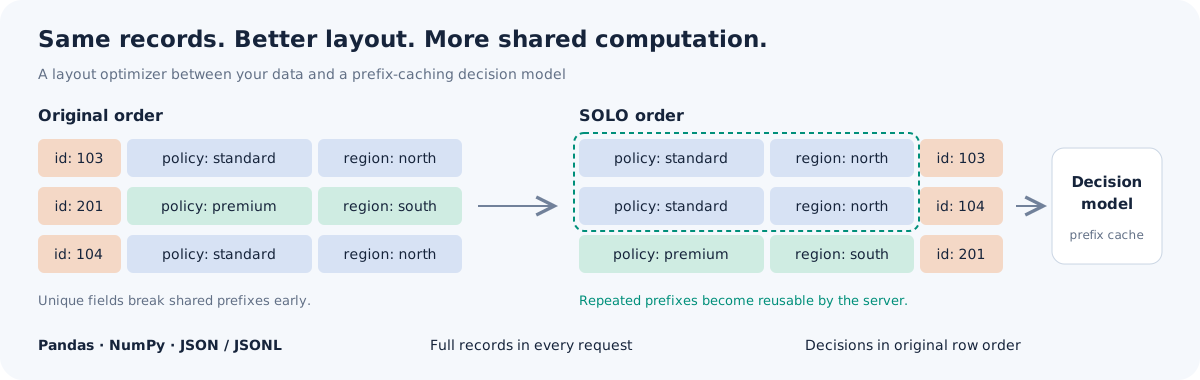
0814wdwd/solo_jev · ★ 764SOLO reorders the rows and fields of a dataset so an LLM decision backend with prefix caching can reuse computation across requests, running a natural-language decision over every row while returning results in the original row order.
 +87
30-Days-Of-Python
Asabeneh/30-Days-Of-Python · ★ 76.5KA free 30-day structured curriculum for learning Python from scratch, covering everything from basic syntax to building web APIs and working with databases.
 +32
Python-100-Days
jackfrued/Python-100-Days · ★ 187.3KA free, day-by-day Python curriculum by Luo Hao (骆昊) that takes a complete beginner through 100 days of lessons covering core language fundamentals, file and database handling, web development with Django, web scraping, data analysis, and machine learning.
 +26
scikit-learn
scikit-learn/scikit-learn · ★ 67.7Kscikit-learn is a Python library for machine learning, offering ready-made algorithms for classification, regression, clustering, dimensionality reduction and more, built on top of SciPy.
The all-time top
44 projects · by stars
- 187.3K#1 · jackfrued/Python-100-Days
Python-100-Days
A free, day-by-day Python curriculum by Luo Hao (骆昊) that takes a complete beginner through 100 days of lessons covering core language fundamentals, file and database handling, web development with Django, web scraping, data analysis, and machine learning.
- 76.5K#2 · Asabeneh/30-Days-Of-Python
30-Days-Of-Python
A free 30-day structured curriculum for learning Python from scratch, covering everything from basic syntax to building web APIs and working with databases.
- 67.7K#3 · scikit-learn/scikit-learn
scikit-learn
scikit-learn is a Python library for machine learning, offering ready-made algorithms for classification, regression, clustering, dimensionality reduction and more, built on top of SciPy.
- 4

100-Days-Of-ML-Code
51.9KAvik-Jain/100-Days-Of-ML-CodeThis is a personal learning log by Avik Jain documenting 100 days of machine learning coding, following the #100DaysOfMLCode challenge proposed by Siraj Raval. It records daily progress on ML topics with notes, code, and infographics.
- 5
PythonDataScienceHandbook
50.2Kjakevdp/PythonDataScienceHandbook · Jupyter NotebookThis is the full text of the Python Data Science Handbook, provided as a set of free Jupyter notebooks covering the core Python data science stack.
- 6

pandas
50.2Kpandas-dev/pandas · Pythonpandas is a Python library providing fast, flexible data structures (Series and DataFrame) for working with labeled/relational data, aiming to be the fundamental building block for practical data analysis in Python.
- 7
spark
44.2Kapache/spark · ScalaApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 8

ailearning
42.6Kapachecn/ailearning · PythonAiLearning is a Chinese-language, practice-first study guide covering data analysis, machine learning, linear algebra, PyTorch, NLTK, and TensorFlow 2, built mainly around code-along notes for the book 'Machine Learning in Action'.
- 9

duckdb
42.2Kduckdb/duckdb · C++DuckDB is a high-performance analytical SQL database system, designed to be fast, reliable, portable and easy to use, with a rich SQL dialect that goes far beyond basic SQL.
- 10
Data-Science-For-Beginners
37.6Kmicrosoft/Data-Science-For-Beginners · Jupyter NotebookA free 10-week, 20-lesson data science curriculum from Microsoft's Azure Cloud Advocates, built to take complete beginners from core concepts all the way to real-world projects.
- 11

tqdm
31.4Ktqdm/tqdm · PythonA fast, extensible progress bar for Python and the CLI: wrap any iterable with tqdm(iterable) and your loop instantly shows a smart meter with percentage, speed and ETA.
- 12
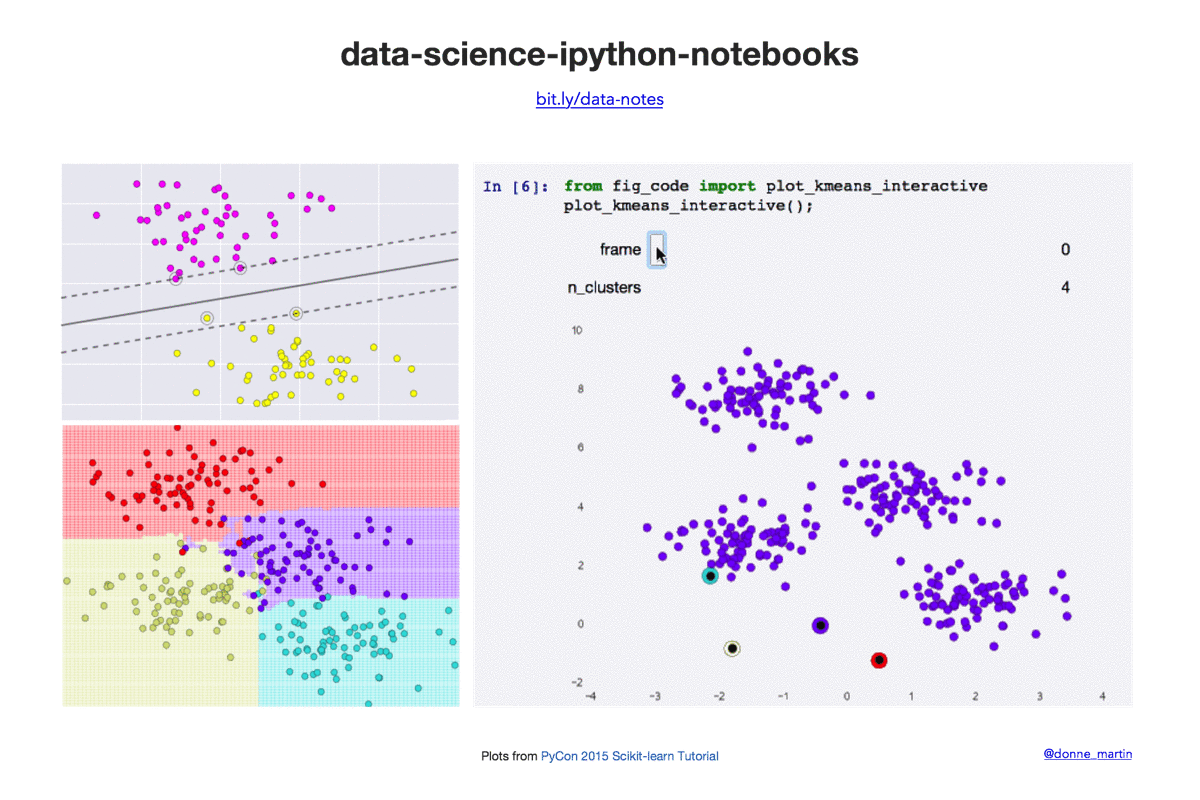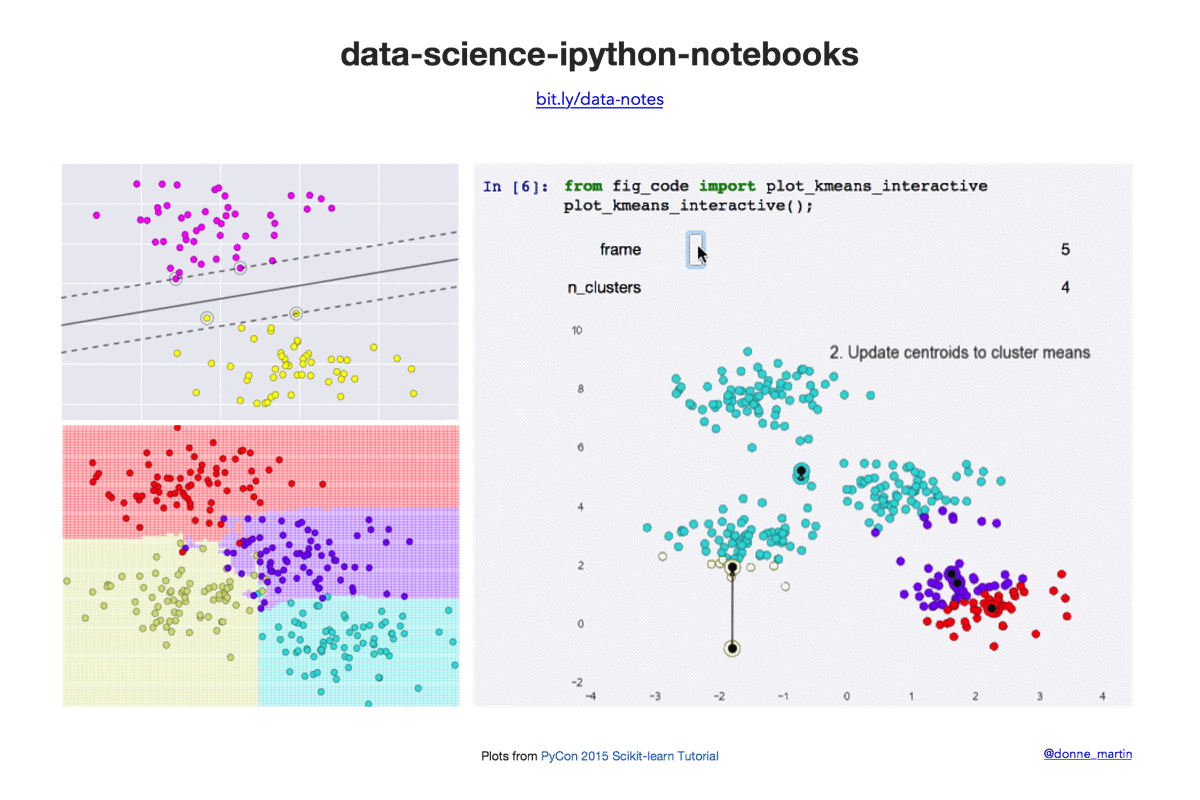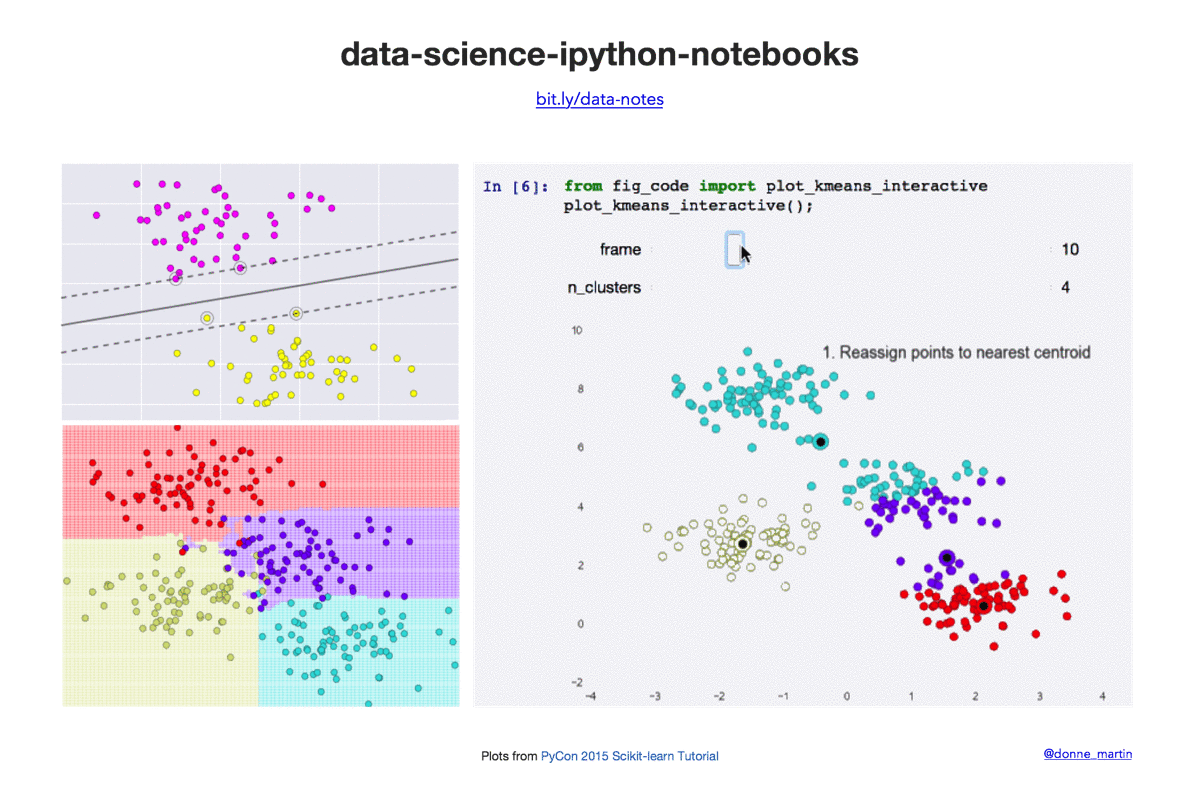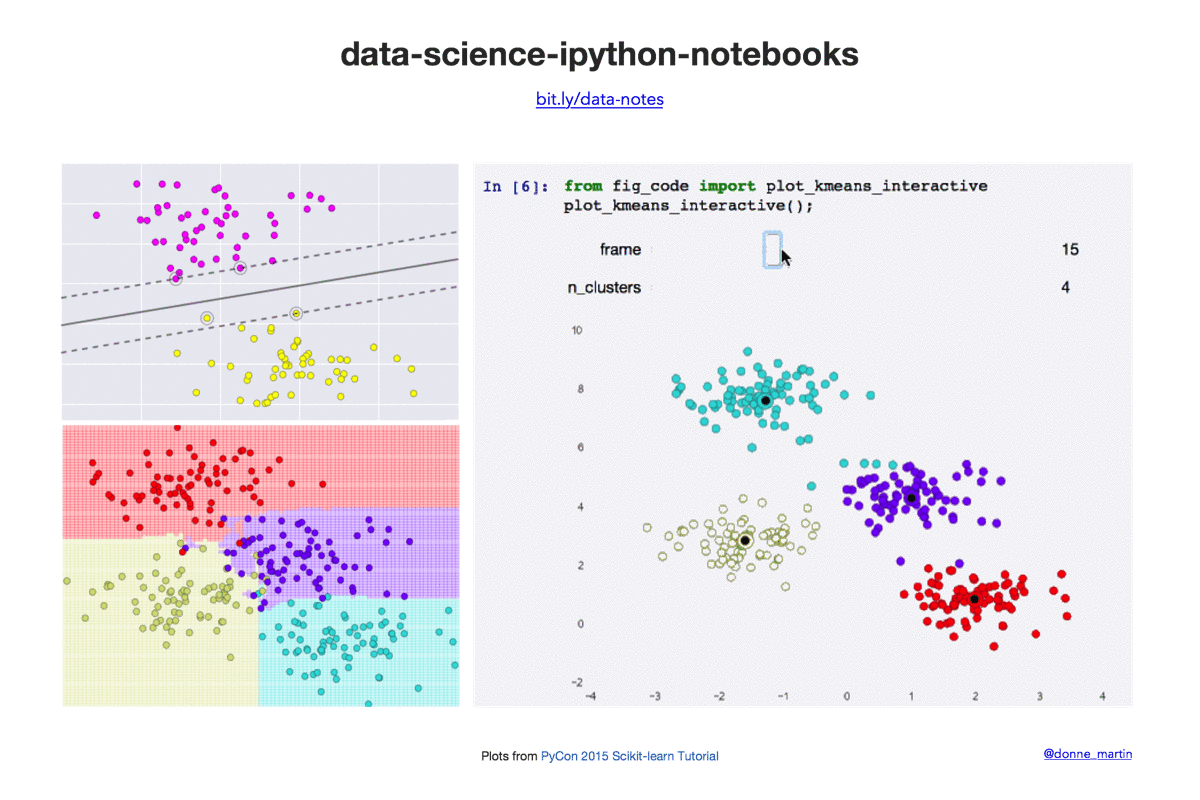
data-science-ipython-notebooks
29.4Kdonnemartin/data-science-ipython-notebooks · PythonA large curated collection of IPython/Jupyter notebooks covering the Python data science stack: deep learning (TensorFlow, Theano, Caffe, Keras), scikit-learn, statistics with SciPy, pandas, matplotlib, NumPy, Kaggle competition analyses, big data (Spark, Hadoop MapReduce, HDFS), AWS, and command-line essentials.
- 13

yfinance
25.5Kranaroussi/yfinance · Pythonyfinance is a Python library that downloads financial and market data from Yahoo! Finance's API - stock quotes, live streaming, search and screener queries - straight from your Python code.
- 14

pydata-book
25Kwesm/pydata-book · Jupyter NotebookThis is the companion repository of Jupyter notebooks and materials for the book 'Python for Data Analysis' by Wes McKinney, covering pandas, NumPy, and data analysis techniques.
- 15
pandas-ai
23.9Ksinaptik-ai/pandas-ai · PythonPandasAI is a Python library that lets you ask questions about your data (SQL, CSV, parquet, dataframes) in plain natural language, powered by LLMs.
- 16
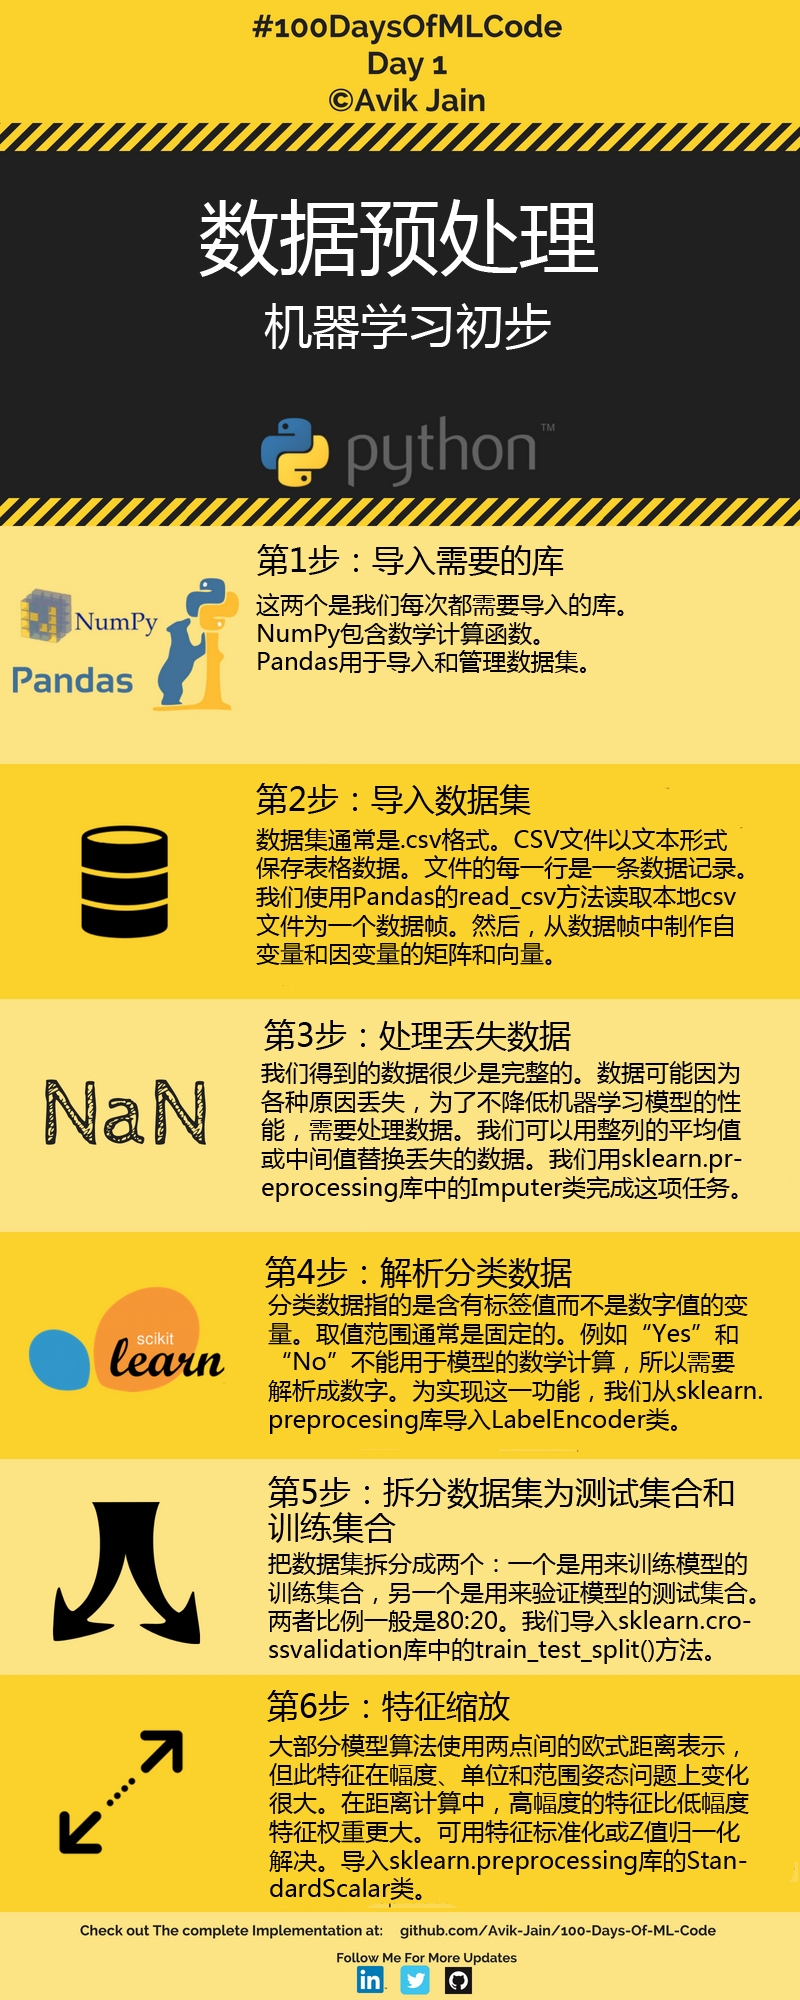
100-Days-Of-ML-Code
22.2KMLEveryday/100-Days-Of-ML-Code · PythonThe Chinese edition of the 100 Days of ML Code challenge: a day-by-day machine learning learning log with infographics, notes and Python code, spanning supervised and unsupervised learning. It translates the original challenge by Avik-Jain and has gathered 22k+ stars.
- 17

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 18

zipline
20.2Kquantopian/zipline · PythonZipline is a Pythonic algorithmic trading library — an event-driven system for backtesting trading strategies written in Python. It is used in production as the backtesting and live-trading engine behind Quantopian.
- 19

abu
18.9Kbbfamily/abu · PythonThis is 'abu' (阿布量化), an open-source Python framework for building, backtesting and running quantitative trading strategies across US/A-share/HK stocks, futures, options and cryptocurrencies like Bitcoin, using machine learning to optimize the strategies.
- 20
pygwalker
16KKanaries/pygwalker · PythonPyGWalker is a Python library that turns your pandas dataframe into an interactive UI for visual analysis, so you can explore and chart data with drag-and-drop right inside Jupyter Notebook.
- 21

tushare
15.5Kwaditu/tushare · PythonTuShare is a Python utility for crawling, cleaning and storing historical and realtime data for China's stock and futures markets, built for quant analysts and anyone learning data analysis.
- 22

cheatsheets-ai
15.4Kkailashahirwar/cheatsheets-aiA curated collection of one-page cheat sheets covering popular machine learning and deep learning tools such as TensorFlow, Keras, NumPy, Pandas, Scikit-learn, Matplotlib, PySpark, Dask, and R's dplyr/tidyr, aimed at ML and DL researchers.
- 23
Virgilio
15Kvirgili0/Virgilio · Jupyter NotebookA free, open-source initiative that mentors anyone into Data Science: instead of drowning in a chaotic jungle of tutorials, you follow structured learning paths it has put together.
- 24
pyodide
14.9Kpyodide/pyodide · PythonA port of CPython to WebAssembly (via Emscripten) — a Python distribution for the browser and Node.js that can install and run Python packages from PyPI right where JavaScript runs.
- 25
machine-learning-zoomcamp
14.8KDataTalksClub/machine-learning-zoomcamp · Jupyter NotebookMachine Learning Zoomcamp is a free, hands-on course that teaches you how to build, evaluate, and deploy real machine learning systems, going from a raw problem all the way to a production service.
- 26

seaborn
14.1Kmwaskom/seaborn · PythonSeaborn is a Python visualization library based on matplotlib that provides a high-level interface for drawing attractive statistical graphics.
- 27

dask
13.9Kdask/dask · PythonDask is a flexible parallel computing library for analytics — it runs Python data workloads as scheduled tasks so they can use many cores or machines instead of a single process.
- 28
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 29

Ai-Learn
13.4Ktangyudi/Ai-LearnThis is a free, structured roadmap of nearly 200 hands-on AI learning projects covering Python, math, machine learning, data analysis, deep learning, computer vision and NLP, created by instructor Tangyudi (唐宇迪) to help beginners become job-ready in AI.
- 30

pandas_exercises
13.2Kguipsamora/pandas_exercises · Jupyter NotebookA collection of exercises for practicing pandas, the Python data analysis library, organized by topic like filtering, grouping, merging, and visualization.
- 31

tutorials
13.1KMorvanZhou/tutorials · PythonThis is a large collection of beginner-friendly Python tutorials by MorvanZhou (莫烦Python) covering machine learning, deep learning, reinforcement learning and related tools, each tutorial paired with a video lesson.
- 32

ta-lib-python
12.3KTA-Lib/ta-lib-python · CythonA Python wrapper around the TA-Lib C library for technical analysis of financial market data: 150+ indicators such as RSI, MACD and Bollinger Bands, plus candlestick pattern recognition.
- 33

lancedb
11.7Klancedb/lancedb · RustLanceDB is an open-source vector database for multimodal AI: a central platform where you store, index and search petabytes of vectors and multimodal data, built for fast, production-ready retrieval.
- 34

statsmodels
11.7Kstatsmodels/statsmodels · Pythonstatsmodels is a Python package for statistical modeling and econometrics, providing estimation and inference for a wide range of statistical models as a complement to scipy.
- 35
QUANTAXIS
11.3Kyutiansut/QUANTAXIS · PythonQUANTAXIS is a local-first quantitative trading framework for China's stock, futures and options markets, covering data fetching, backtesting, paper trading, live trading, visualization and multi-account management, with support for distributed task scheduling.
- 36
mlcourse.ai
10.8KYorko/mlcourse.ai · PythonAn open Machine Learning course by the OpenDataScience (ods.ai) community, led by Yury Kashnitsky: 10 weeks that pair math-heavy lectures with hands-on assignments and Kaggle Inclass competitions, now taken self-paced.
- 37
modin
10.4Kmodin-project/modin · PythonModin is a drop-in replacement for pandas: you keep the same API and syntax, but your workflows run on all of your CPU cores instead of a single thread. Change one import line and your existing pandas code just runs faster.
- 38
sktime
10.1Ksktime/sktime · Pythonsktime is a Python library for machine learning with time series: one unified interface for forecasting, classification, clustering, and anomaly or changepoint detection.
- 39
tpot
10.1KEpistasisLab/tpot · Jupyter NotebookTPOT, the Tree-based Pipeline Optimization Tool, is a Python AutoML library that uses genetic programming to automatically optimize machine learning pipelines for your data; the README calls it your Data Science Assistant.
- 40

visidata
9.4Ksaulpw/visidata · PythonVisiData is a terminal spreadsheet multitool for exploring, cleaning, and arranging tabular data, supporting formats like CSV, TSV, SQLite, JSON, Excel (xlsx), and HDF5.
- 41

codex-claude-academic-skills
5KzLanqing/codex-claude-academic-skills · PythonThree Claude Code / Codex Agent Skills built for Chinese academic researchers, covering the full research workflow: research-writing-skill for drafting and polishing papers, office-academic-skill for generating academic Word/PPT documents, and scientific-toolkit-skill for MATLAB/Python scientific computing and publication-quality figures.
- 42

PythonCall.jl
1.1KJuliaPy/PythonCall.jl · JuliaPythonCall.jl (with its Python-side counterpart JuliaCall) lets you call Python code from Julia and Julia code from Python through a symmetric interface, converting objects between the two languages.
- 43
solo_jev
7640814wdwd/solo_jev · PythonSOLO reorders the rows and fields of a dataset so an LLM decision backend with prefix caching can reuse computation across requests, running a natural-language decision over every row while returning results in the original row order.
- 44

huashu-excel
439alchaincyf/huashu-excel · PythonThis is a Skill for AI coding agents that handles the entire Excel/data-analysis workflow: it profiles a messy spreadsheet, cleans it, aligns with the user on what to actually analyze, runs the analysis, reconciles the numbers against the sheet's own totals, and only then delivers a report.
Related topics
Often tagged together
- python2,397
- data-science231
- open-source5,666
- numpy73
- machine-learning915
- data-analysis73
- education933
- library1,587
- data-visualization201
- tutorial626
- mit3,311
- linux4,181
- matplotlib18
- scikit-learn29
- windows3,401
- deep-learning736
- learning512
- macos3,544
- chinese1,157
- beginner-friendly310
- cross-platform2,622
- database473
- developer-tools2,927
- jupyter notebook176