Topics / #data
Data projects on GitHub
General topic for data handling, pipelines, and tooling.
As of , the most-starred Data projects on GitHub are Scrapling (88.3K stars), 30-Days-Of-Python (76.5K stars) and llama_index (52.5K stars). GitHub.Locker tracks 42 Data repositories with 918.9K stars combined. The fastest-growing on October 17 was os-taxonomy, with +473 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +473
os-taxonomy
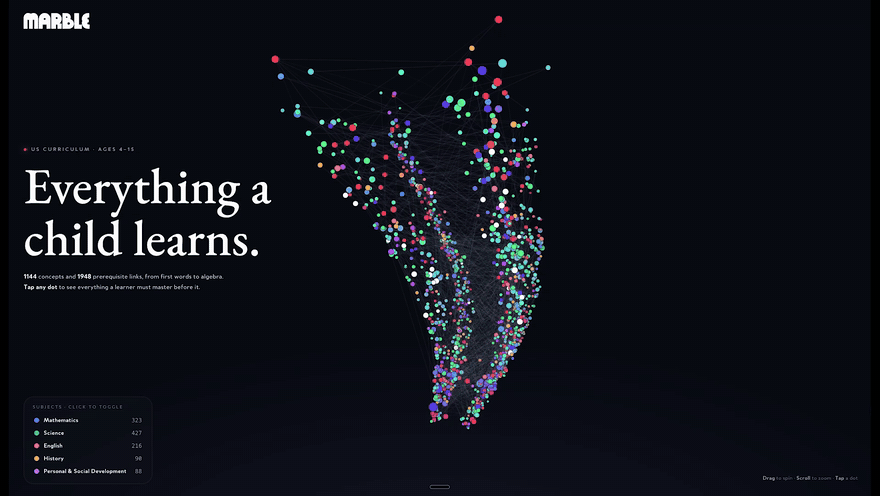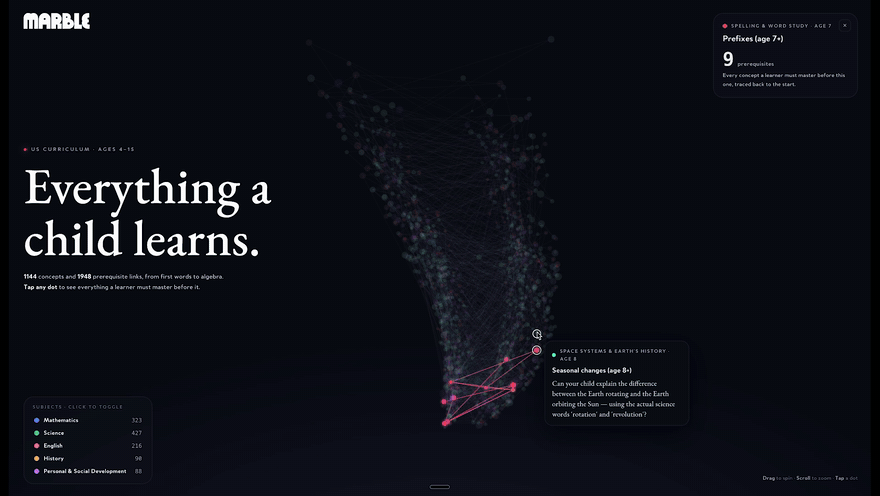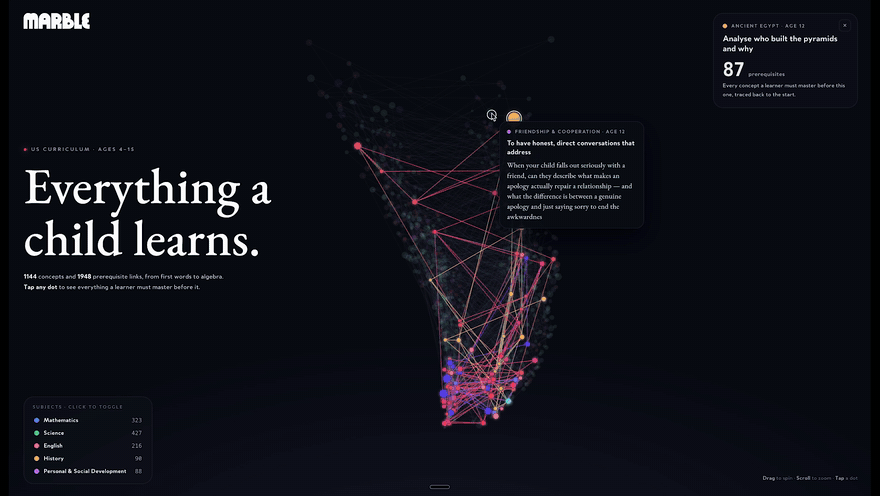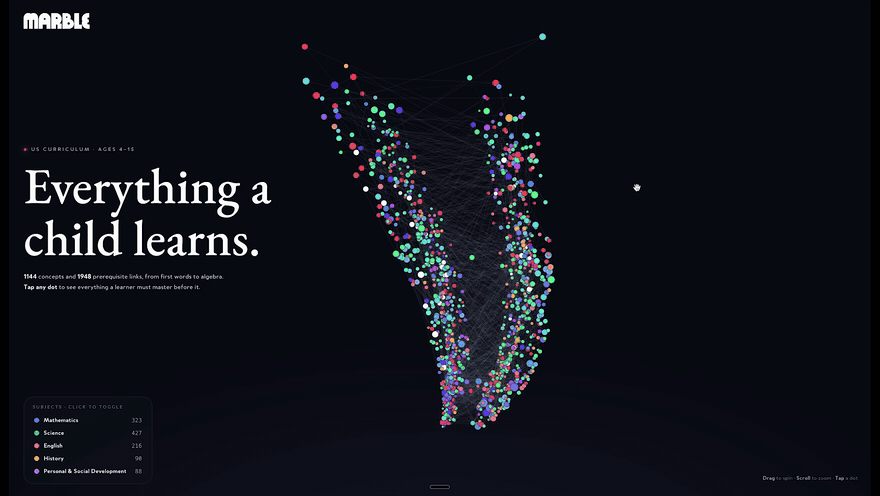
withmarbleapp/os-taxonomy · ★ 5.6KMarble Skill Taxonomy is an open dataset mapping what children learn in primary/elementary school, broken into 1,590 fine-grained micro-topics linked by a prerequisite graph and aligned to national curriculum standards like NGSS and Common Core.
 +188
Scrapling
D4Vinci/Scrapling · ★ 88.3KScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
 +87
30-Days-Of-Python
Asabeneh/30-Days-Of-Python · ★ 76.5KA free 30-day structured curriculum for learning Python from scratch, covering everything from basic syntax to building web APIs and working with databases.
 +28
mihomo
MetaCubeX/mihomo · ★ 35KIt is a Python library built on Pydantic that models and parses the data returned by the Mihomo API for Honkai: Star Rail, giving you typed, autocomplete-friendly access to a player's parsed character and showcase info.
The all-time top
42 projects · by stars
- 88.3K#1 · D4Vinci/Scrapling
Scrapling
Scrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 76.5K#2 · Asabeneh/30-Days-Of-Python
30-Days-Of-Python
A free 30-day structured curriculum for learning Python from scratch, covering everything from basic syntax to building web APIs and working with databases.
- 52.5K
 #3 · run-llama/llama_index
llama_index
LlamaIndex is an open-source Python framework for building agentic applications that augment LLMs with your own private data, letting you ingest, index, and query documents with LLM-powered pipelines.
- 4

query
50.5KTanStack/query · TypeScriptTanStack Query is an async state management library that simplifies fetching, caching, synchronizing, and updating server state in web apps.
- 5
metabase
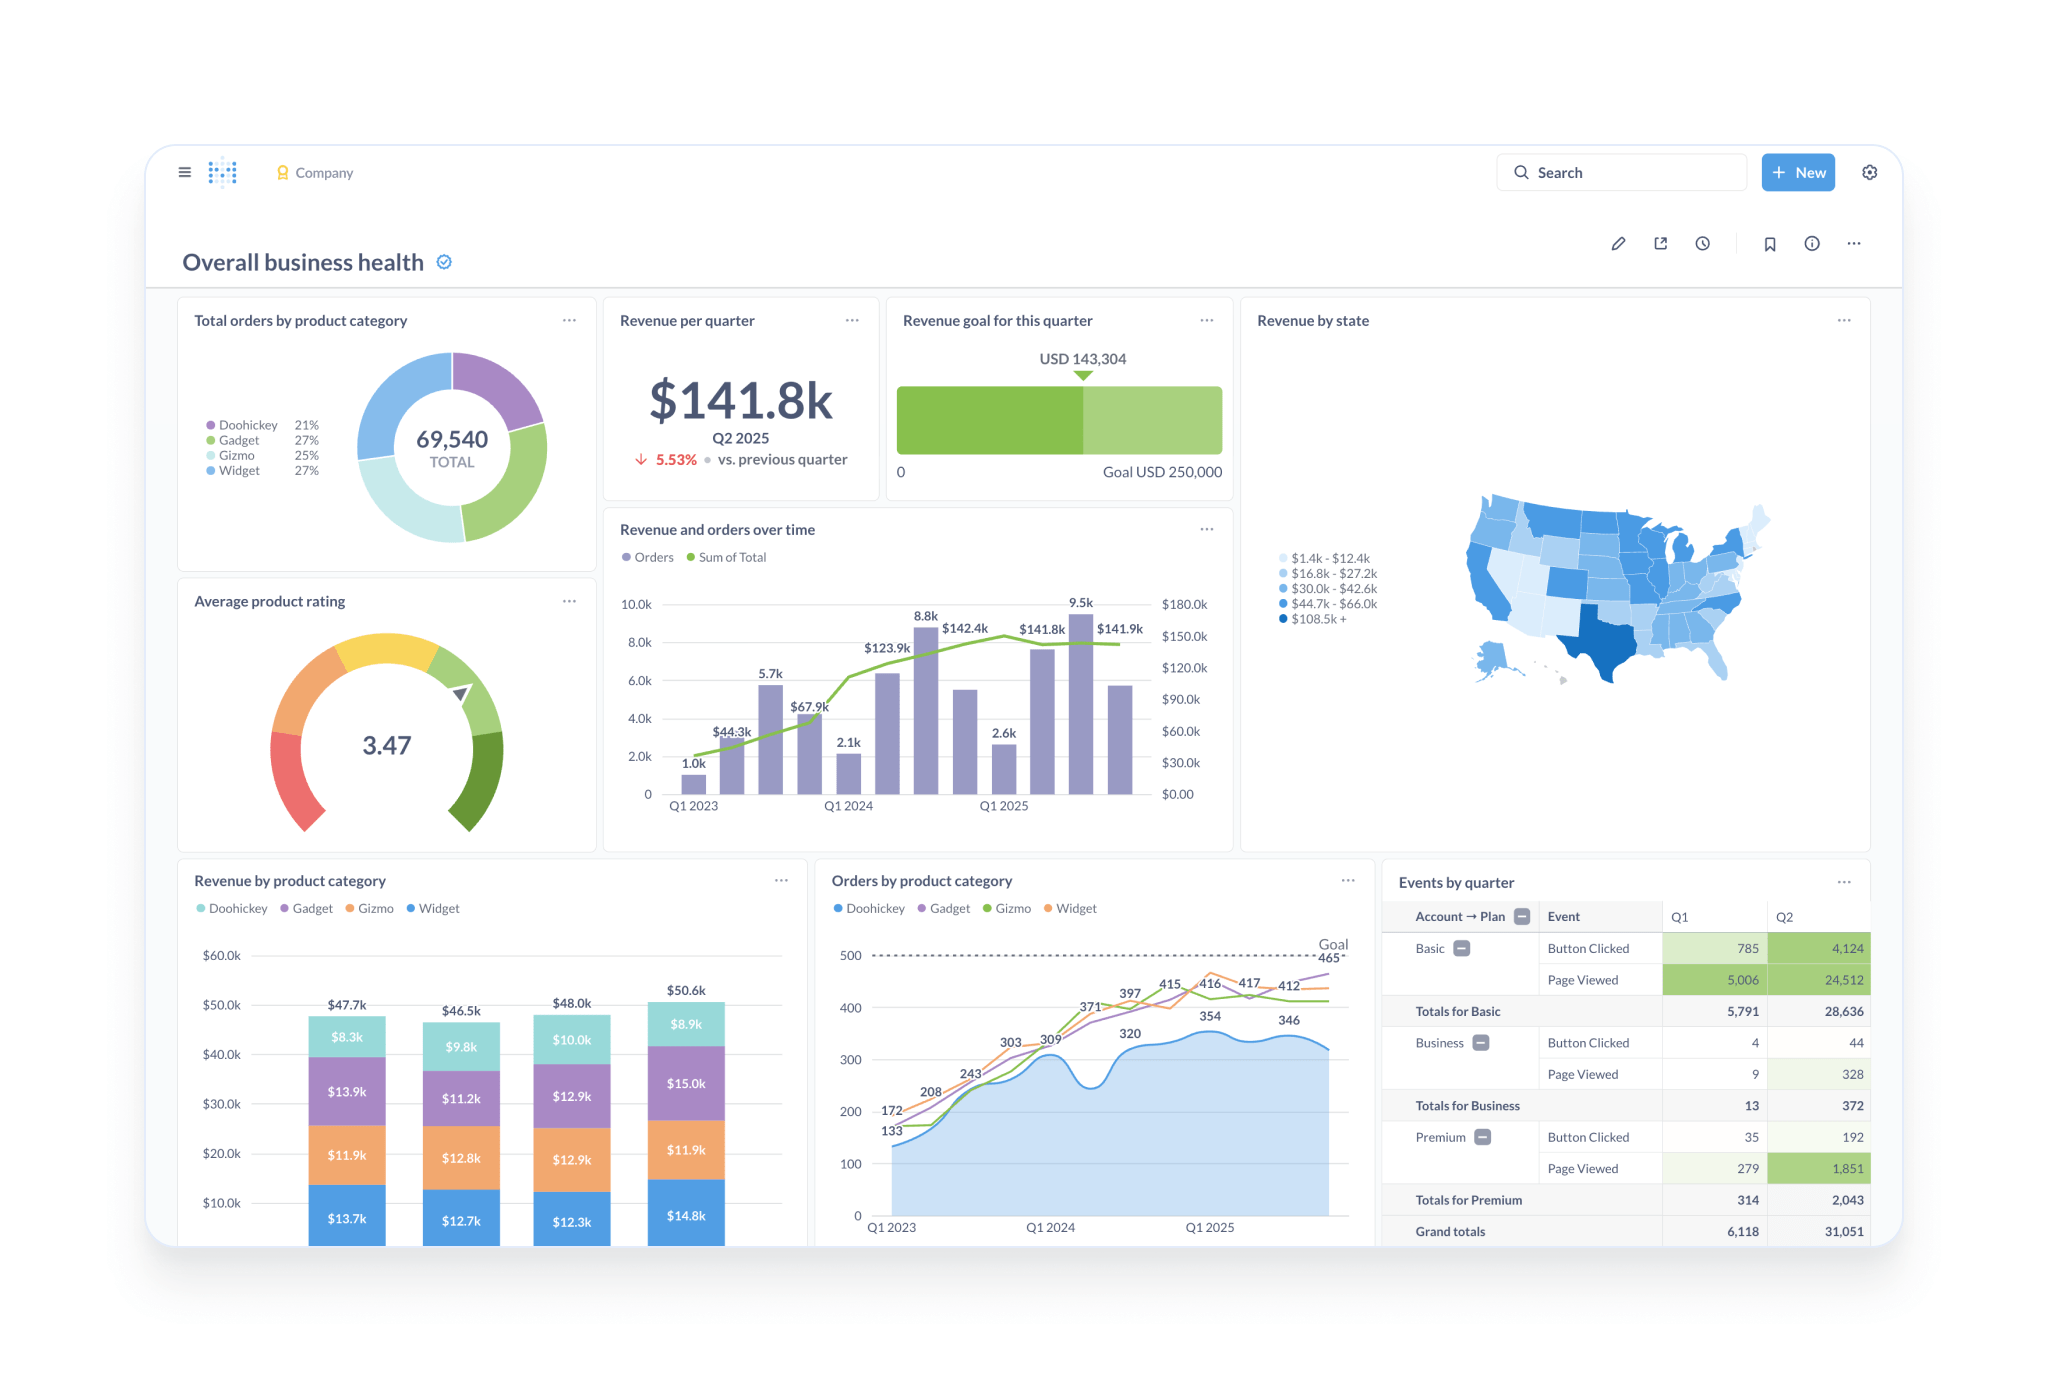
49.7Kmetabase/metabase · ClojureMetabase is an open-source business intelligence tool that lets anyone on a team ask questions about data and build dashboards without knowing SQL.
- 6

big-list-of-naughty-strings
47.7Kminimaxir/big-list-of-naughty-strings · PythonIt is a curated collection of strings with a high probability of breaking software when used as user input, meant to help QA testing of input validation.
- 7

data-engineer-handbook
44.5KDataExpert-io/data-engineer-handbook · Jupyter NotebookA curated handbook of links and resources for learning data engineering: roadmaps, bootcamp materials, books, communities, company tooling lists, blogs, whitepapers, and a directory of data engineering content creators.
- 8

WeChatMsg
42.1KLC044/WeChatMsgWeChatMsg is a desktop tool (built with PyQt) that extracts and exports your personal WeChat chat history, letting you keep a lasting local record of your conversations and optionally feed that data into LLMs like ChatGPT to build a personalized AI trained on your own messages.
- 9

sheetjs
36.3KSheetJS/sheetjsSheetJS Community Edition is an open-source JavaScript toolkit for spreadsheet data: it extracts useful data from almost any complex spreadsheet and generates new spreadsheets that work with legacy and modern software alike.
- 10
mihomo
35KMetaCubeX/mihomo · PythonIt is a Python library built on Pydantic that models and parses the data returned by the Mihomo API for Honkai: Star Rail, giving you typed, autocomplete-friendly access to a player's parsed character and showcase info.
- 11
swr
32.5Kvercel/swr · TypeScriptSWR is a React Hooks library for data fetching. The name comes from stale-while-revalidate (HTTP RFC 5861): cached data is shown first, then the request revalidates and fresh data updates the UI.
- 12

awesome-quant
30.2Kwilsonfreitas/awesome-quant · HTMLA curated list of libraries, packages and resources for quants - people doing quantitative finance: pricing, trading, backtesting, risk and market data.
- 13

yfinance
25.5Kranaroussi/yfinance · Pythonyfinance is a Python library that downloads financial and market data from Yahoo! Finance's API - stock quotes, live streaming, search and screener queries - straight from your Python code.
- 14
prefect
24KPrefectHQ/prefect · PythonPrefect is a Python workflow orchestration framework for turning ordinary scripts into resilient, production-grade data pipelines with scheduling, retries, caching, and event-based automations.
- 15
pandas-ai
23.9Ksinaptik-ai/pandas-ai · PythonPandasAI is a Python library that lets you ask questions about your data (SQL, CSV, parquet, dataframes) in plain natural language, powered by LLMs.
- 16

akshare
23Kakfamily/akshare · PythonAKShare is a free, open-source Python library that wraps a large set of financial data interfaces behind simple function calls - one line of code is enough to fetch a dataset.
- 17

airbyte
22.2Kairbytehq/airbyte · PythonAirbyte is an open-source data movement platform for ELT pipelines and AI agents: it moves data from APIs, databases, and files into warehouses, data lakes, and AI applications, backed by a catalog of 600+ connectors. You can run it self-hosted or as Airbyte Cloud.
- 18

data
17.5Kfivethirtyeight/data · Jupyter NotebookThis is the public repository of data sets and code behind the articles, graphics, and interactive features published by the journalism outlet FiveThirtyEight.
- 19

DataX
17.4Kalibaba/DataX · JavaDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
- 20

presto
16.8Kprestodb/presto · JavaPresto is a distributed SQL query engine for running interactive analytic queries against big data sources.
- 21

faker
15.5Kfaker-js/faker · TypeScriptFaker is a JavaScript/TypeScript library that generates massive amounts of fake but realistic data — names, addresses, dates, finance records — for testing and development, in the browser and Node.js.
- 22

awesome-bigdata
14.7Koxnr/awesome-bigdataA curated list of frameworks, databases, tools, papers, and resources related to big data, covering everything from distributed processing engines to key-value stores and visualization tools.
- 23

pgx
14.3Kjackc/pgx · Gopgx is a pure Go driver and toolkit for PostgreSQL, providing a low-level, high-performance interface that exposes PostgreSQL-specific features like LISTEN/NOTIFY and COPY, plus an adapter for the standard database/sql interface.
- 24

Github-Ranking
12.4KEvanLi/Github-Ranking · PythonGithub-Ranking is a repository that tracks and lists the most-starred and most-forked repositories on GitHub, with both an overall Top 100 and per-language Top 100 breakdowns.
- 25

english-words
12.3Kdwyl/english-words · PythonA text file of English words — over 466k per the README, 479k in the repo description — published for dictionary and word-based projects such as auto-complete and autosuggestion.
- 26

chinese-xinhua
11.7Kpwxcoo/chinese-xinhua · PythonA Chinese Xinhua Dictionary database (中华新华字典数据库): four JSON datasets with 31,648 idioms, 264,434 words, 16,142 characters and 14,032 xiehouyu (two-part allegorical sayings), collected from the web.
- 27

pkl
11.5Kapple/pkl · JavaPkl (pronounced Pickle) is a configuration-as-code language created by Apple, built for writing config with rich validation and tooling support.
- 28
sql-server-samples
11.3Kmicrosoft/sql-server-samples · PowerShellThis is Microsoft's official repository of code samples demonstrating how to use SQL Server, Azure SQL Database, Azure Synapse, and Azure SQL Edge, including sample databases, demos, and feature walkthroughs.
- 29
prql
10.9KPRQL/prql · RustPRQL (pronounced 'Prequel') is a modern language for transforming data — a simple, powerful, pipelined replacement for SQL.
- 30
altair
10.5Kvega/altair · PythonVega-Altair is a declarative statistical visualization library for Python, letting you build charts by describing data mappings instead of drawing commands.
- 31

electric
10.4Kelectric-sql/electric · TypeScriptElectric is a real-time sync engine for Postgres: it replicates data out of your database into anything — web apps, mobile clients, AI agents — handling the hard parts like partial replication, fan-out and data delivery.
- 32
os-taxonomy
5.6Kwithmarbleapp/os-taxonomy · JavaScriptMarble Skill Taxonomy is an open dataset mapping what children learn in primary/elementary school, broken into 1,590 fine-grained micro-topics linked by a prerequisite graph and aligned to national curriculum standards like NGSS and Common Core.
- 33
Edit-Banana
5.5KBIT-DataLab/Edit-Banana · PythonIt converts images of static diagrams — flowcharts, multi-level architecture diagrams, technical schematics, scientific formulas — into fully editable DrawIO files, powered by fine-tuned SAM 3 segmentation and multimodal LLMs.
- 34
DeepAnalyze
4.7Kruc-datalab/DeepAnalyze · PythonDeepAnalyze is an open-source agentic large language model built for fully autonomous data science: it can handle data preparation, analysis, modeling, visualization, and report generation on its own, across structured, semi-structured, and unstructured data sources.
- 35

prediction-market-analysis
3.9KJon-Becker/prediction-market-analysis · PythonIt's a framework for collecting and analyzing prediction market data from Polymarket and Kalshi, bundled with the largest publicly available dataset of their market and trade history.
- 36
ducklake
3.3Kduckdb/ducklake · C++DuckLake is an open lakehouse table format that stores data in Parquet files and stores metadata/catalog info in a SQL database, implemented as a DuckDB extension.
- 37
REDox
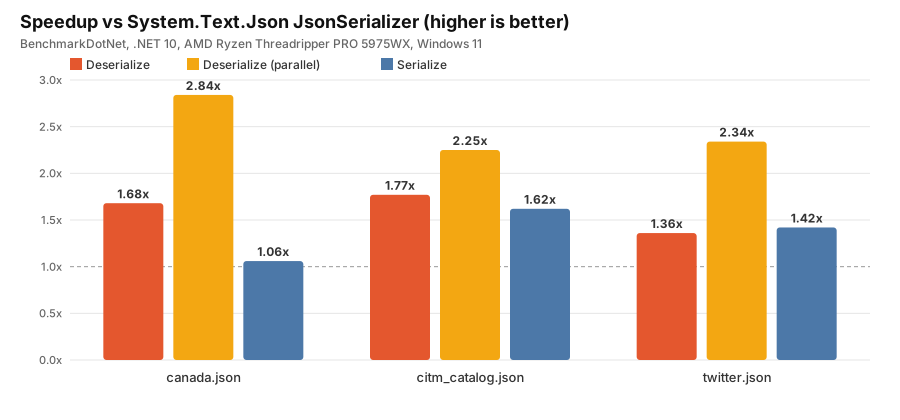
1.6KCAPCOM-TD-OSS/REDox · C#RE:Dox is a high-performance, token-based structured data engine for .NET, built as a core component of CAPCOM's 'REX' technology for its next-generation game engine. It parses structured data into a compact token DOM that is used for reading, editing, format conversion, serialization and parallel deserialization.
- 38
SolarWM
777Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 39

blocklist-abuseipdb
600borestad/blocklist-abuseipdb · ShellA continuously updated set of IP blocklists aggregating AbuseIPDB's worst IPv4 and IPv6 offenders (~99% confidence), plus other free public threat sources, meant to be loaded straight into a firewall to block malicious traffic.
- 40

elosys
459YuriRDev/elosys · TypeScriptElosys builds a consolidated database of Brazilian political candidates (2014-2026) from official government sources, cross-referenced by CPF/CNPJ, to investigate relationships between politicians and surface indicia of suspicious patterns like circular donations, shell companies, and wealth incompatible with declared income.
- 41

LEAKSFORUMS
364FSECDEV/LEAKSFORUMSLEAKSFORUMS is a collection of leaked data from hacker forums — a README table listing breached communities like Breached Forums, Black Market Reloaded, and Russian boards, each with a download link.
- 42
leis
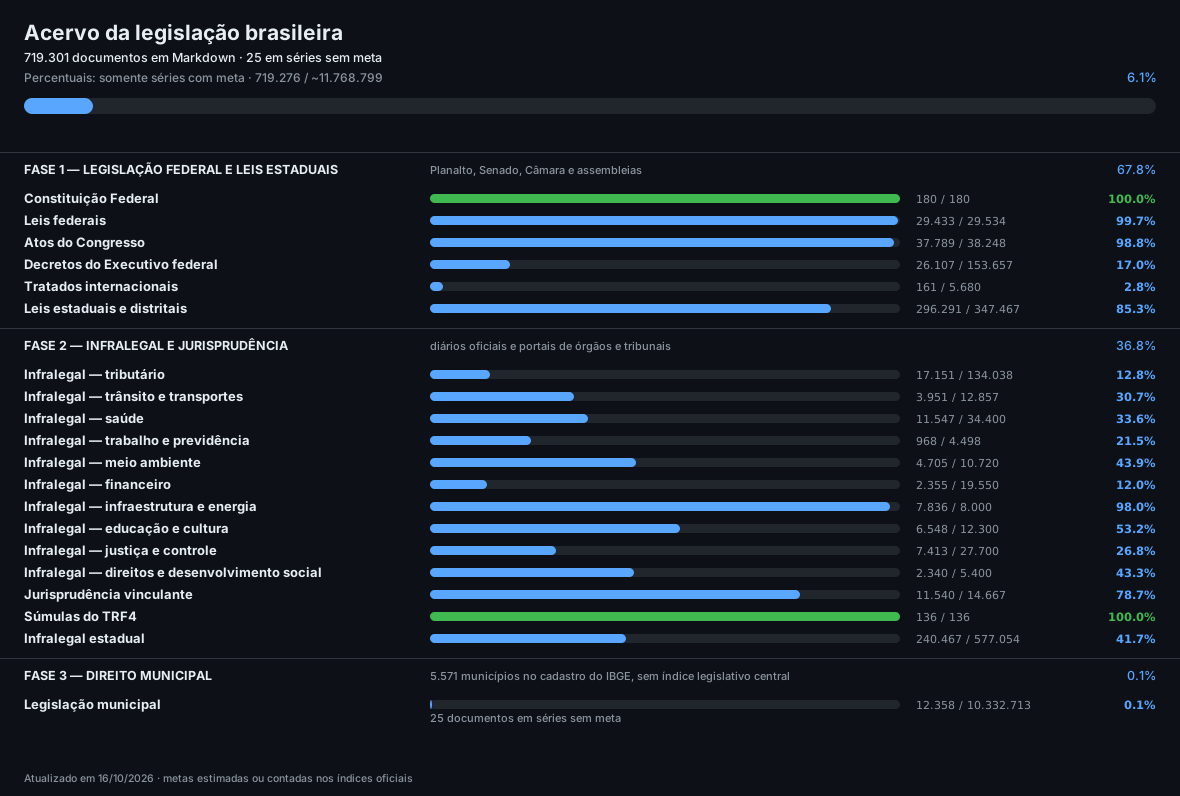
337ctresb/leisIt is a repository that converts Brazil's entire body of law — the Federal Constitution plus federal, state, district and municipal norms — from official sources into plain Markdown, each file carrying a structured header and a link back to its source.
Related topics
Often tagged together