Topics / #llm-evaluation
LLM evaluation projects on GitHub
Testing, tracing and scoring LLM output quality
As of , the most-starred LLM evaluation projects on GitHub are funNLP (83K stars), langfuse (35.9K stars) and iFixAi (28.9K stars). GitHub.Locker tracks 37 LLM evaluation repositories with 369.4K stars combined. The fastest-growing on October 16 was iFixAi, with +458 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +458
iFixAi
ifixai-ai/iFixAi · ★ 28.9KiFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
langfuse
langfuse/langfuse · ★ 35.9KLangfuse is an open source LLM engineering platform for tracing, evaluating, and debugging LLM and agent applications, with prompt management and a playground built in.
 +45
promptfoo
promptfoo/promptfoo · ★ 26.1Kpromptfoo is a CLI and library for evaluating and red-teaming LLM apps — you test prompts, agents, and RAGs and run security scans on them, instead of relying on trial-and-error.
 +34
funNLP
fighting41love/funNLP · ★ 83KA huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
The all-time top
37 projects · by stars
- 83K#1 · fighting41love/funNLP
funNLP
A huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
- 35.9K
#2 · langfuse/langfuse
langfuse
Langfuse is an open source LLM engineering platform for tracing, evaluating, and debugging LLM and agent applications, with prompt management and a playground built in.
- 28.9K#3 · ifixai-ai/iFixAi
iFixAi
iFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
- 4

mlflow
28.4Kmlflow/mlflow · PythonMLflow is an open source AI engineering platform for agents, LLM apps, and classic ML models: one place to trace, evaluate, monitor, and optimize production AI while controlling costs. It is widely adopted, with over 60 million monthly downloads.
- 5
promptfoo
26.1Kpromptfoo/promptfoo · TypeScriptpromptfoo is a CLI and library for evaluating and red-teaming LLM apps — you test prompts, agents, and RAGs and run security scans on them, instead of relying on trial-and-error.
- 6
llm-action
25.2Kliguodongiot/llm-action · HTMLIt is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
- 7

opik
22.7Kcomet-ml/opik · PythonOpik is an open-source platform for debugging, evaluating, and monitoring LLM applications, RAG systems, and agentic workflows, with tracing, automated evaluation, and production dashboards.
- 8

evals
19.6Kopenai/evals · PythonEvals is OpenAI's framework for evaluating LLMs and LLM-based systems, bundled with an open-source registry of benchmarks you can run or extend.
- 9

deepeval
18.9Kconfident-ai/deepeval · PythonDeepEval is an open-source LLM evaluation framework: a simple-to-use way to evaluate large-language model systems with research-backed metrics like G-Eval, answer relevancy, and hallucination checks.
- 10
ragas
16Kvibrantlabsai/ragas · PythonRagas is an open-source Python toolkit for evaluating and optimizing LLM applications: objective metrics, automatic test-set generation and data-driven insights replace slow, subjective manual assessment.
- 11

lm-evaluation-harness
14.2KEleutherAI/lm-evaluation-harness · PythonIt is a unified framework for few-shot evaluation of language models across a huge number of standard academic benchmarks.
- 12

phoenix
11.9KArize-ai/phoenix · PythonArize Phoenix is an open-source AI observability platform for tracing, evaluating, and troubleshooting LLM applications, agents, and RAG pipelines.
- 13
arc-task-gen
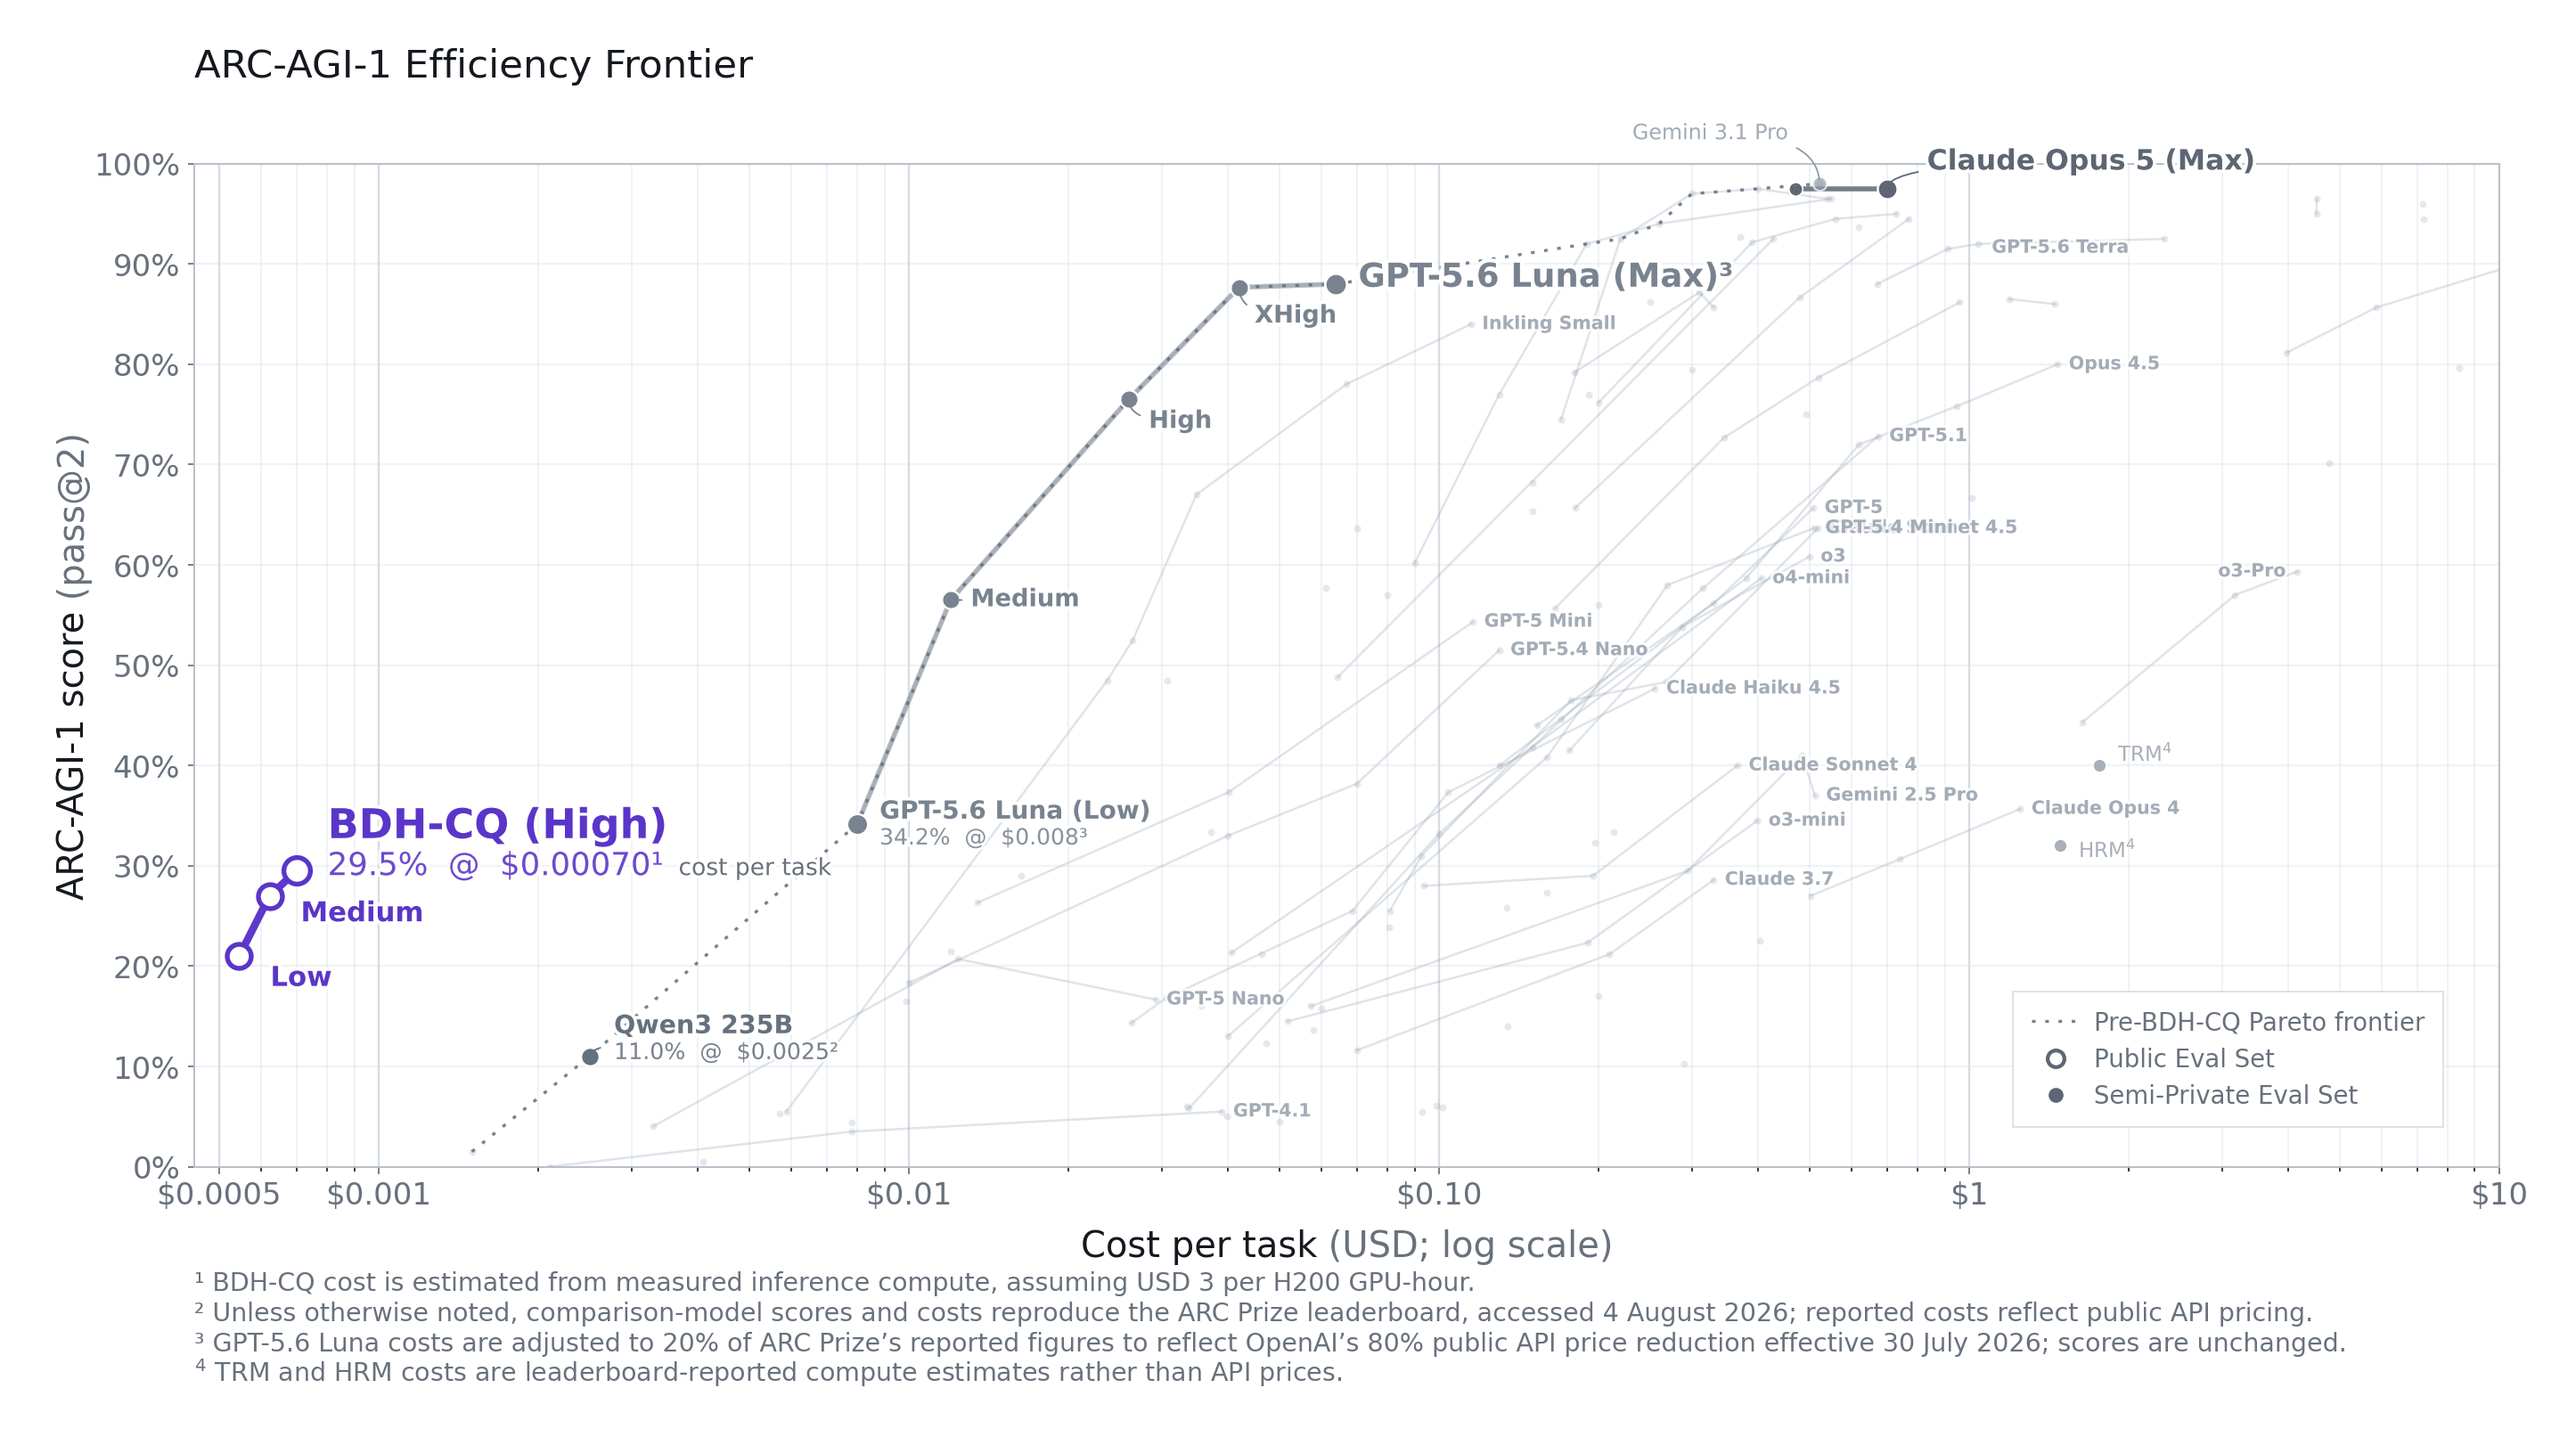
11Kpathwaycom/arc-task-gen · PythonA generator for fresh, original ARC-AGI-1-style puzzle tasks whose statistical distribution matches the public ARC-AGI-1 evaluation set, so models can be tested on problems they haven't seen before.
- 14
AI-Infra-Guard
6.9KTencent/AI-Infra-Guard · PythonAI-Infra-Guard (A.I.G) is a full-stack AI red teaming platform built by Tencent Zhuque Lab that scans AI agents, MCP servers, agent skills, and AI infrastructure components for security vulnerabilities, and evaluates LLMs against jailbreak attacks.
- 15
ouroboros
6.2KQ00/ouroboros · PythonOuroboros is an 'Agent OS' for AI coding — a local-first runtime layer that turns non-deterministic coding-agent work into a replayable, observable, policy-bound workflow (interview, crystallize, execute, evaluate, evolve) instead of ad-hoc prompting.
- 16
ai-agents-the-definitive-guide
2.8KNicolepcx/ai-agents-the-definitive-guide · Jupyter NotebookIt is the companion code repository for the book 'AI Agents - The Definitive Guide': a set of runnable Jupyter notebooks that walk through every chapter, from basic agent patterns to production deployment and threat modeling.
- 17
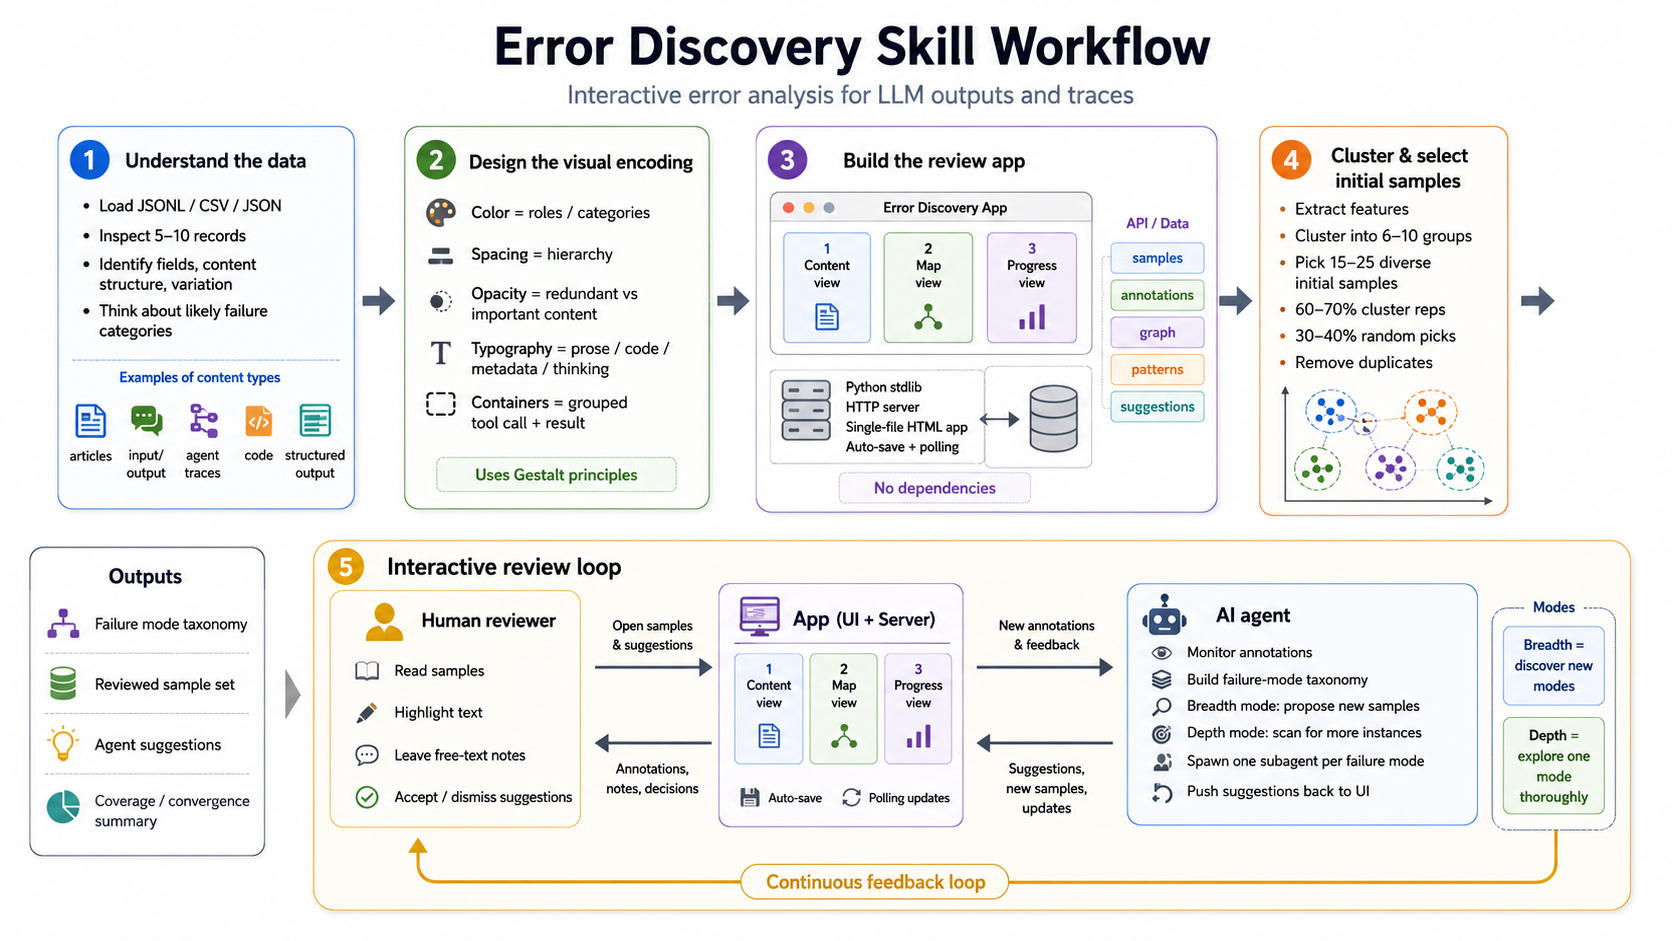
evals-skills
1.5Kai-evals-course/evals-skillsA collection of agent skills that guide AI coding agents to build product-specific AI evals — not foundation-model benchmarks. It encodes mistakes the authors saw across 50+ companies and thousands of students in their AI Evals course.
- 18
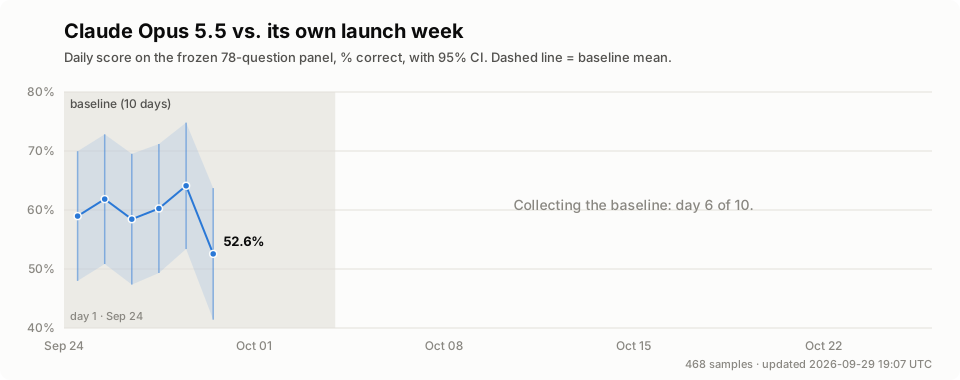
livenerf
1.5Kninjahawk/livenerf · Pythonlivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
- 19
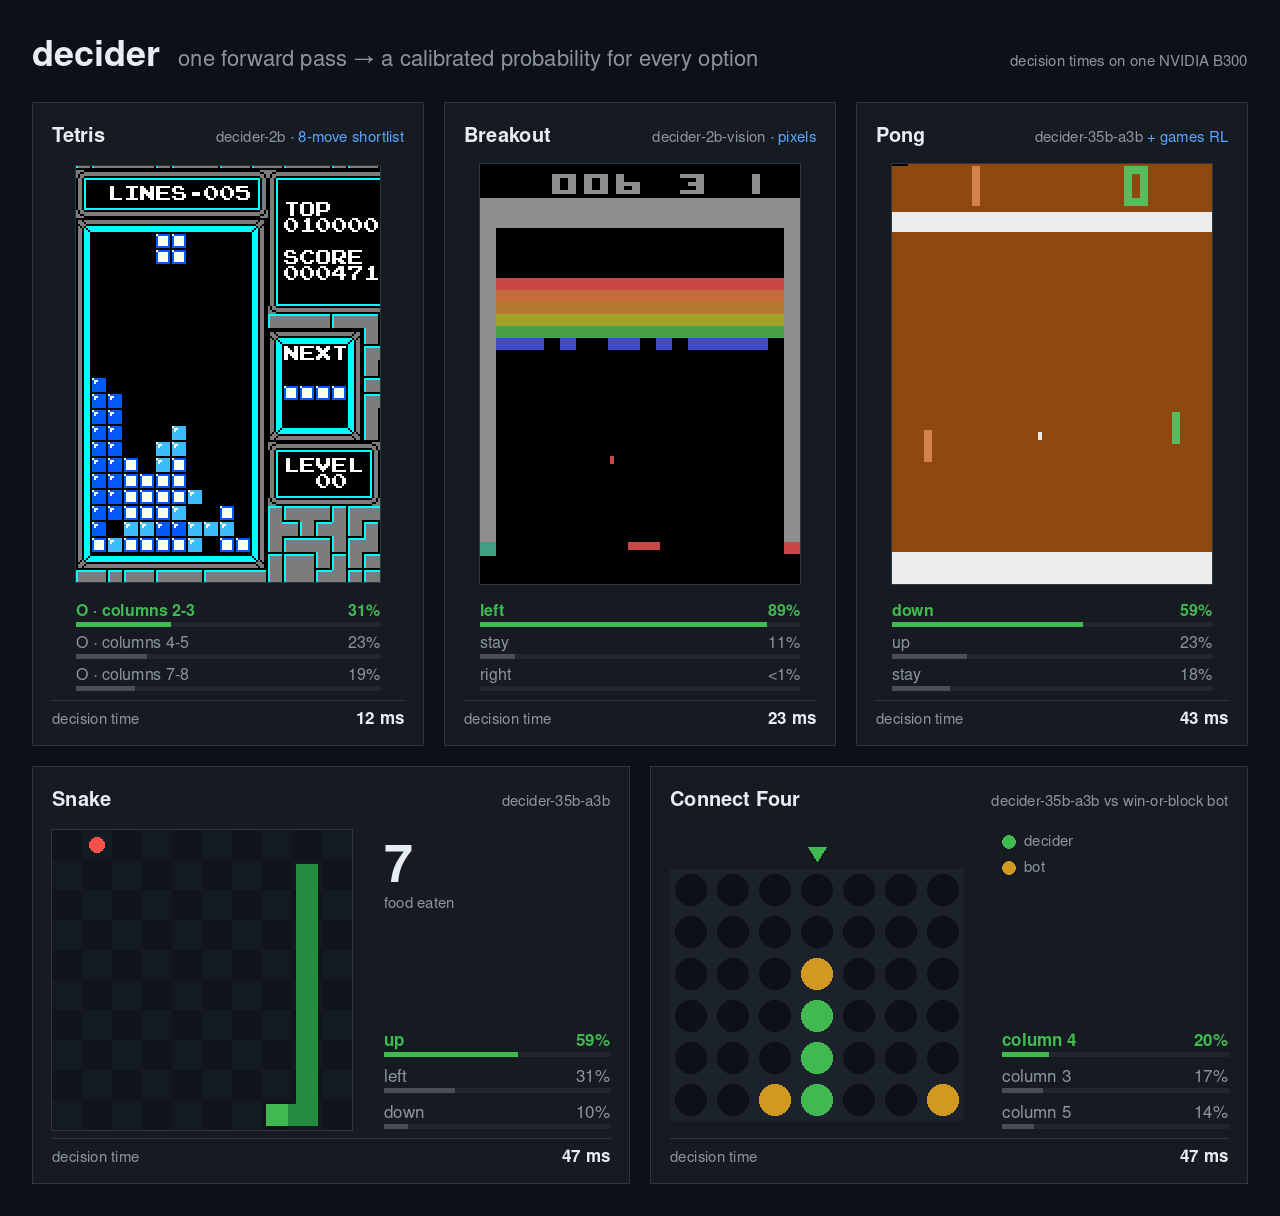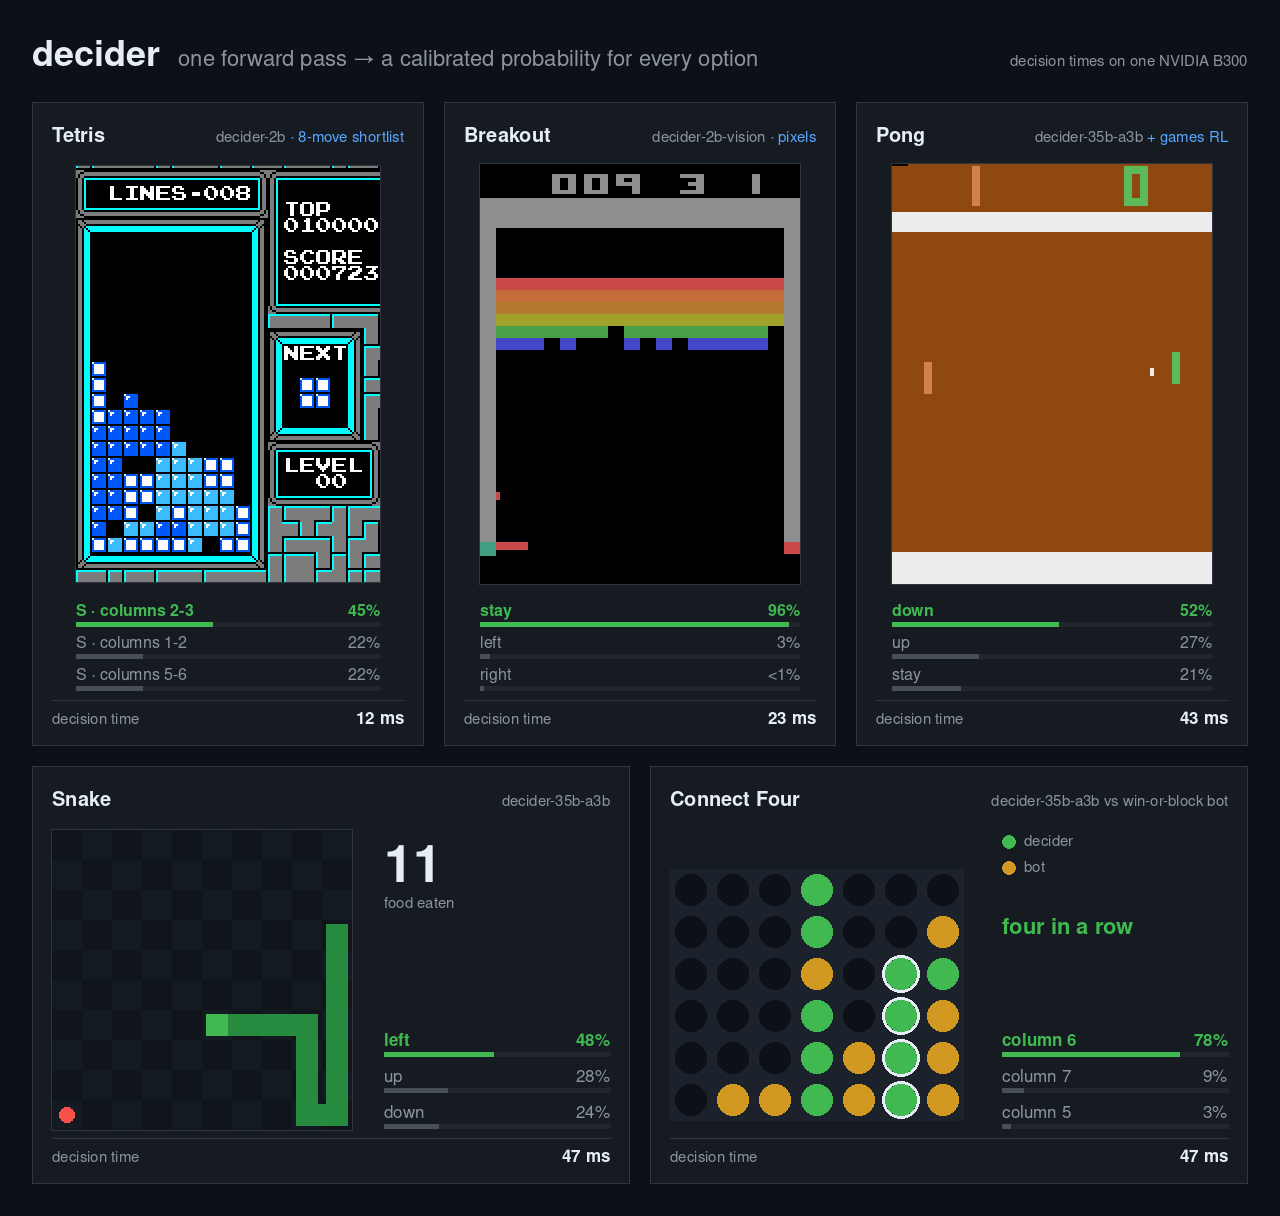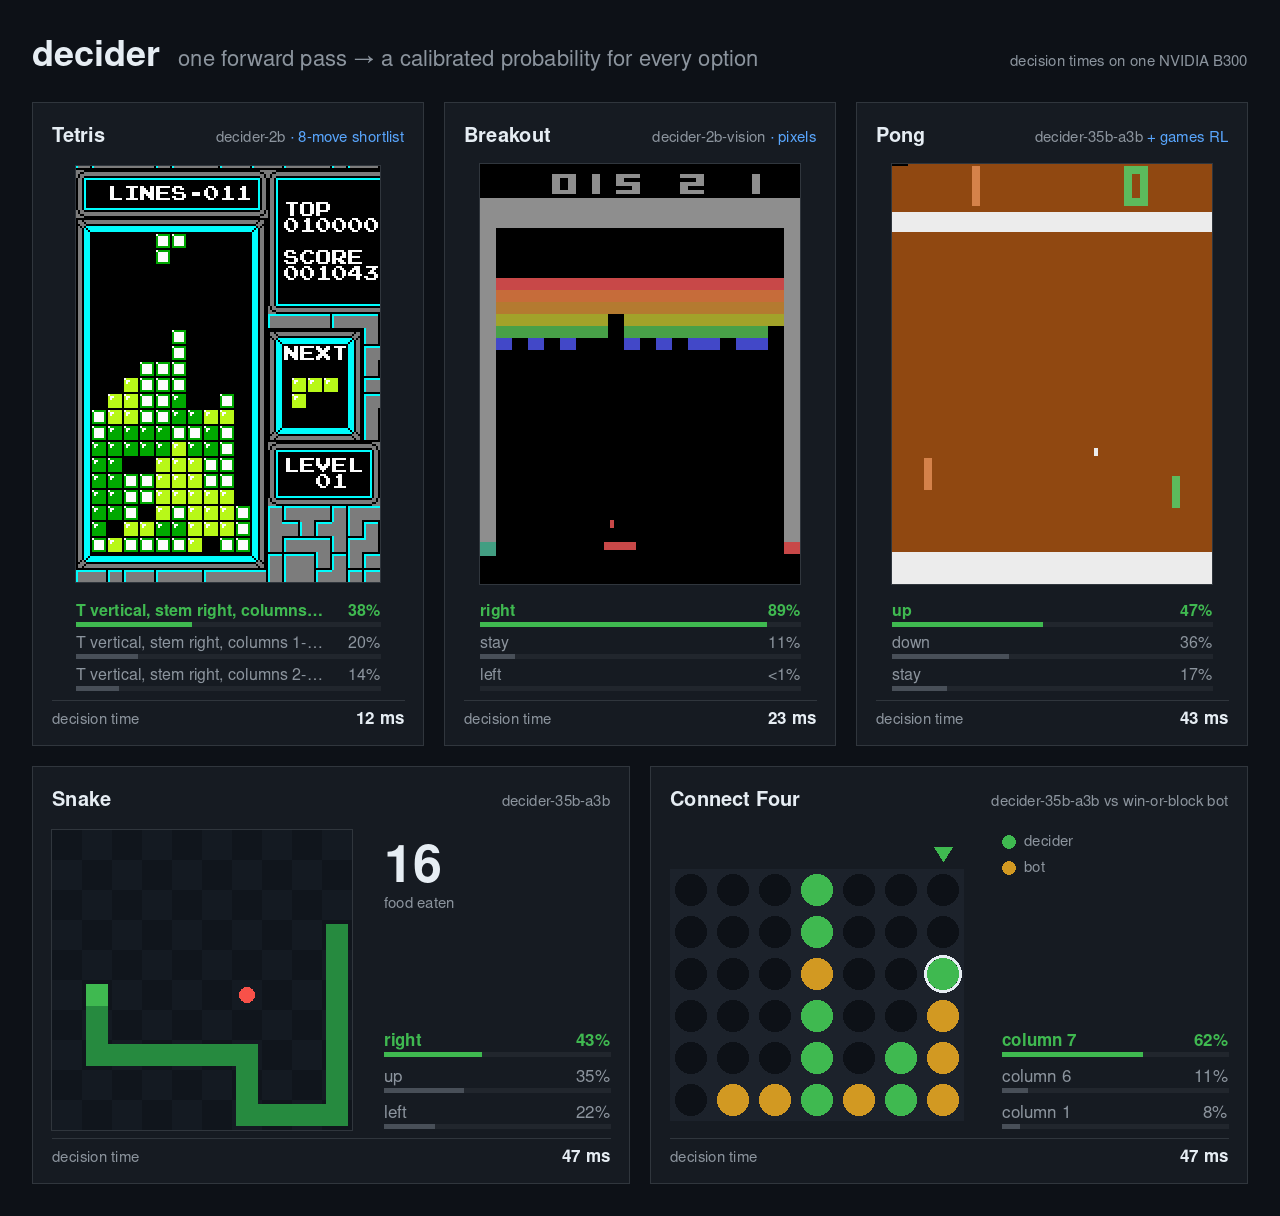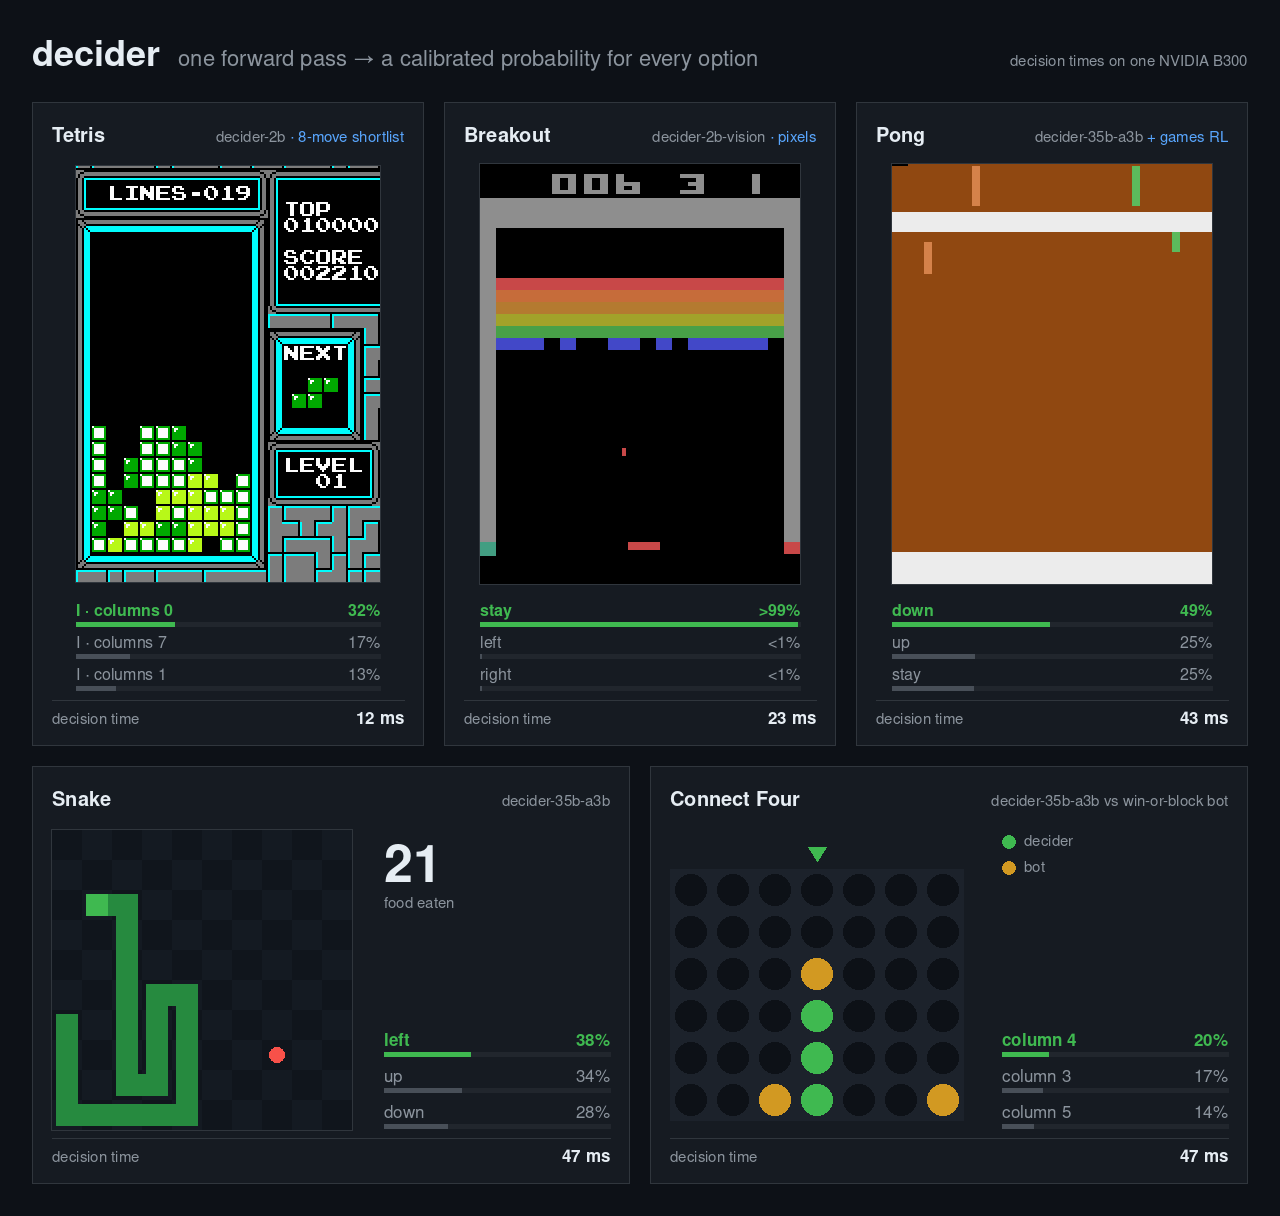
decider
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 20

Tracely-ai
829jwuthri-cloud/Tracely-ai · PythonTracely is a trace-native CI/CD platform for AI agents: it grades every production agent trace, clusters failures into issues, freezes bad runs into hermetic regression tests, blocks the PR that would ship them again, and alerts you when it happens.
- 21
GVS5H
750slee-persis/GVS5H · PythonGVS5H is the code and experiment data for a research paper introducing 'ledger-based zero-shot self-orchestration': fresh instances of one model decompose a coding problem and coordinate through a shared filesystem holding a plan, notes and the current solution, letting several cheap open models match or approach the accuracy of a much larger proprietary model.
- 22
SkillCorpus
686EverMind-AI/SkillCorpus · PythonSkillCorpus is EverMind's open-source pipeline that aggregates scattered SKILL.md files from public repos, applies safety/license/quality gates, and exports a curated, retrieval-ready corpus plus two fine-tuned retrieval models so agents can fetch the right skill at answer time.
- 23
overmind
662overmind-core/overmind · PythonOvermind points at your AI agent's codebase and production traces, then turns them into a fine-tuned model that is benchmarked against metrics you define and served through one unified API — no separate ML infrastructure to build.
- 24
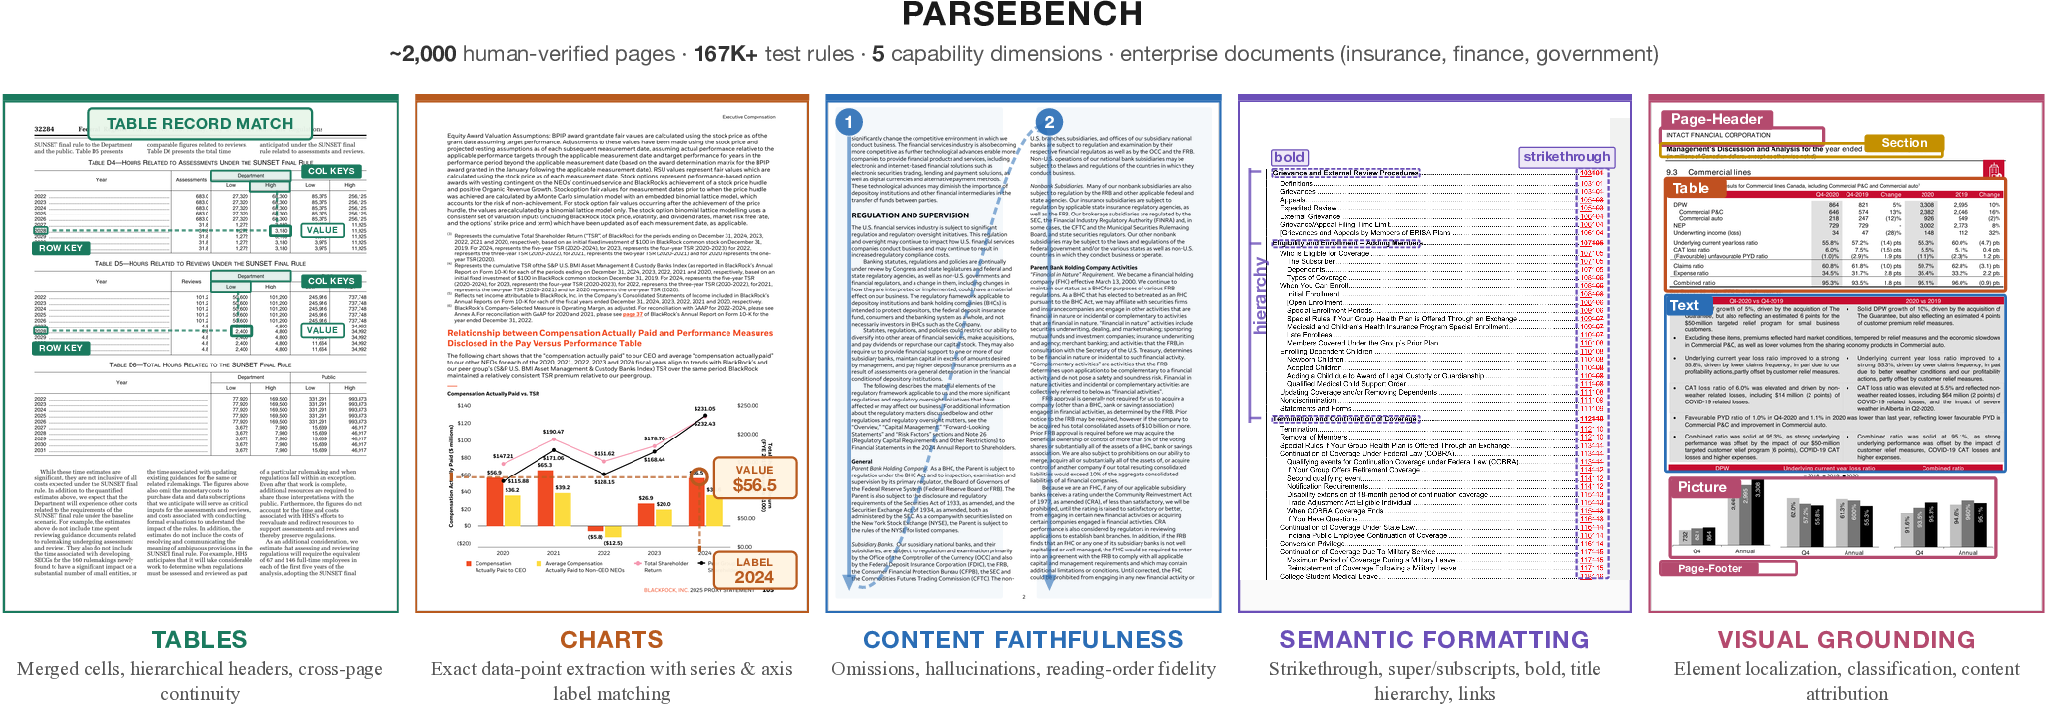
ParseBench
602run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 25
awesome-jev
601kydlikebtc/awesome-jev · PythonA curated index of 1207 public resources for Jev, TypeSafe AI's System One decision model, organised by the decision each resource illustrates. It's an independent catalog, not the product or an SDK.
- 26
safelabs-eval
569AgentSafeLabs/safelabs-eval · Pythonsafelabs-eval is an open-source red-teaming and evaluation framework for AI agents, built around an OWASP-inspired ASI01-ASI10 taxonomy. It fires 300 curated adversarial prompts at an agent and scores every response with pattern-based detectors to produce a structured security report.
- 27

GamePhanes
462GamePhanesStudio/GamePhanes · PythonGameForgeBench is a benchmark that evaluates coding agents on building, debugging, and repairing real game projects (Godot and other engines) through terminal workflows, judged by actual runtime behavior rather than just file diffs.
- 28
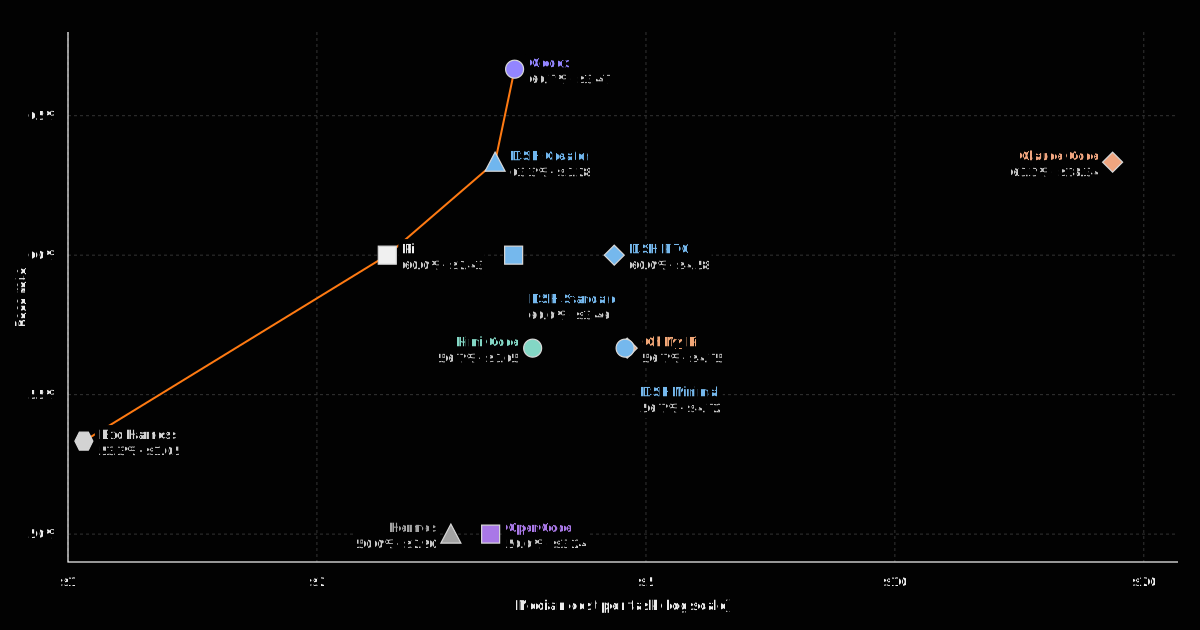
eval
310frontier-harness-eval/eval · JavaScriptFrontierHarness Eval is a public benchmark that ran the same Kimi K3 model through nine coding-agent harnesses (12 configurations) on the same 30 software-engineering tasks, to see how pass rate, cost, cache behavior and speed change when only the harness changes.
- 29

jev-align
309sutro-sh/jev-align · PythonAn experimental CLI from Sutro for building calibrated AI Functions on TypeSafe's Jev: it finds uncertain examples in your dataset, has you label them, and uses GEPA to keep improving the function.
- 30
ASI-Bench
301apexin-ai/ASI-Bench · PythonASI-Bench is a benchmark for evaluating AI agents on long-horizon scientific research: it jointly tests general intelligence, innovation, and autonomous execution across 60 project-level tasks in 11 domains.
- 31
EvoTrace
292jinzijian/EvoTrace · PythonEvoTrace mines the Claude Code and Codex coding-agent sessions already on your machine, finds the ones worth keeping, and compiles them into verified, reusable post-training assets: preference data, replayable coding tasks, RL environments, and execution-reward candidates.
- 32
OrcaReplay
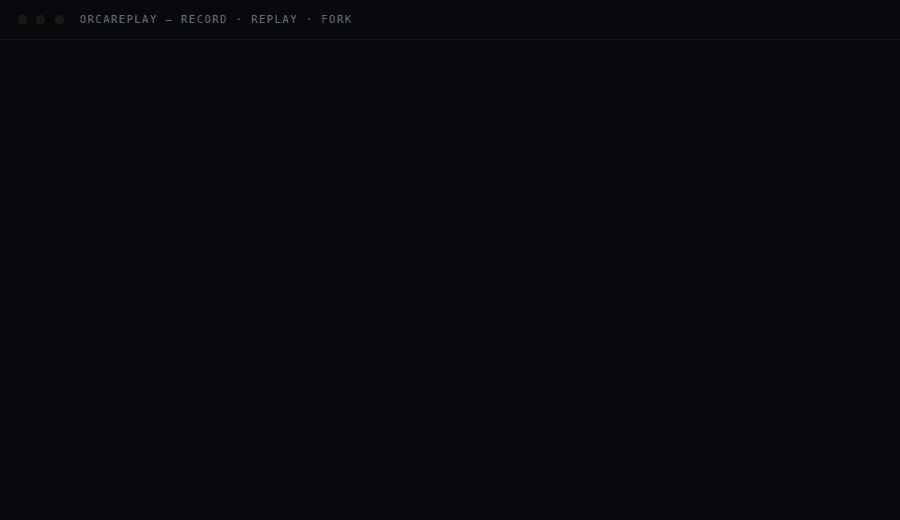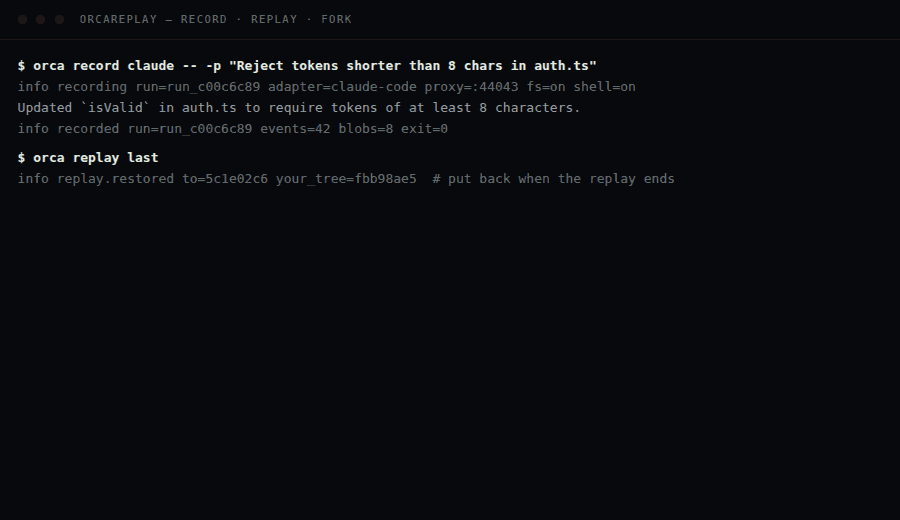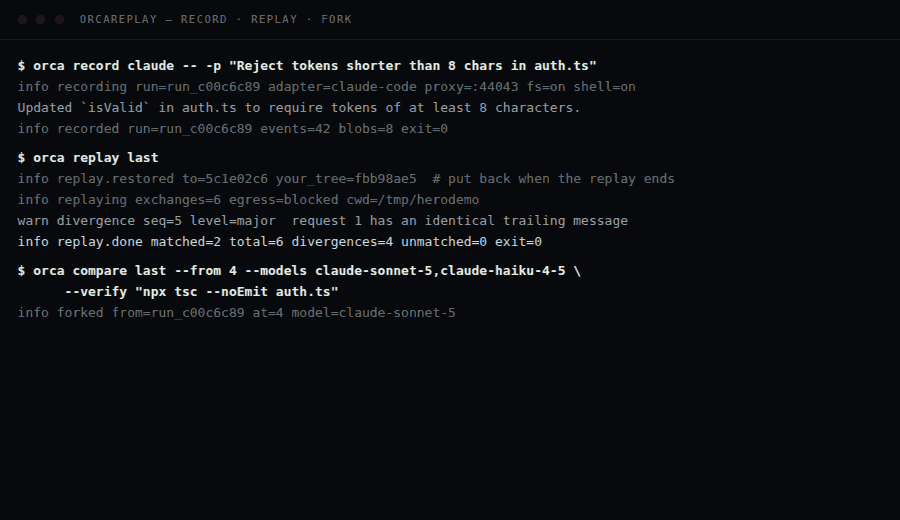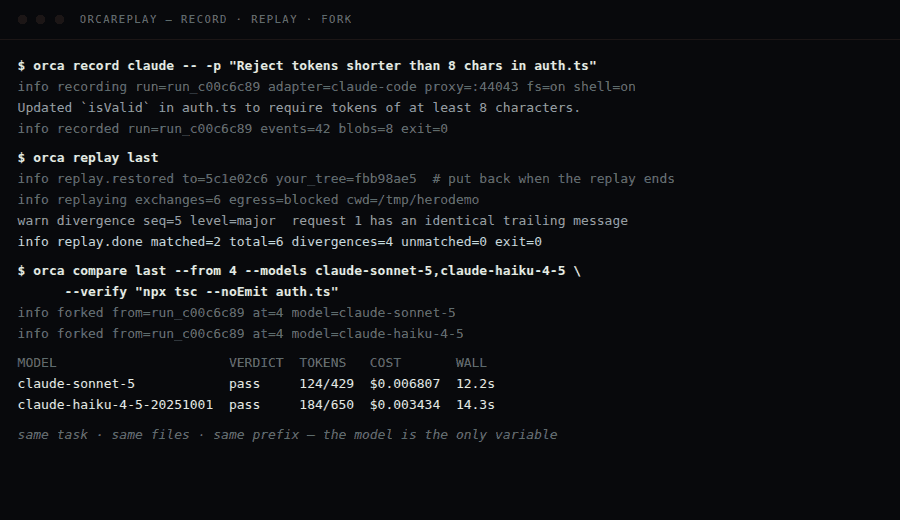
285Continuum-AI-Corp/OrcaReplay · TypeScriptOrcaReplay records a coding agent's entire run (model calls, tool calls, shell commands, file changes), then lets you replay that exact run offline with no model called, fork it from any checkpoint onto a different model, and compare models side by side on the same task.
- 33
Recuris
241Gen-Verse/Recuris · PythonRecuris is a recursive self-improvement framework that boosts long-horizon LLM agents by evolving their memory instead of their weights or prompt. A frozen agent is paired with a structured Skill Memory, and a meta-agent patches it based on execution traces, only keeping changes that pass a validation gate.
- 34
EvalForge
210jsdhwfmax/EvalForge · PythonEvalForge turns AI evaluation results into reviewable, vendor-neutral release evidence for RAG applications and AI assistants, combining an offline RAG evaluator, a portable JSON artifact, and policy-as-code gates that output JSON, JUnit, and SARIF for CI systems.
- 35

XRepoTest
167solis-team/XRepoTest · PythonXRepoTest is a multilingual benchmark that evaluates how well large language models generate unit tests for real-world functions across five programming languages, using Docker-based execution to compile and run every generated test against the actual source code.
- 36
memoket-kite
144memoket/memoket-kite · PythonKITE is an open-source, vector-free long-term memory engine for AI agents: it turns conversations into structured, topic-indexed facts and answers questions with inspectable retrieval plans instead of embedding similarity search, topping the LoCoMo and LongMemEval benchmarks.
- 37

jevals
105openlayer-ai/jevals · Pythonjevals is a Python library for evaluating and guardrailing AI agent traces using 'Jev' decision models instead of a text-generating LLM judge. It bundles every check for a trace into one request that costs a fraction of a cent and returns in a few hundred milliseconds, so you can eval every trace and even run checks inside the agent loop.
Related topics
Often tagged together