Topics / #data-engineering
Data-engineering projects on GitHub
Building pipelines and infrastructure that move and transform data at scale.
As of , the most-starred Data-engineering projects on GitHub are superset (75.2K stars), ClickHouse (50.5K stars) and Made-With-ML (49.8K stars). GitHub.Locker tracks 56 Data-engineering repositories with 1M stars combined. The fastest-growing on October 16 was kestra, with +29 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +29
kestra
kestra-io/kestra · ★ 29.7KKestra is an open-source, event-driven orchestration platform for building data, AI, and infrastructure workflows. You describe them in declarative YAML and manage everything from a built-in web UI.
 +29
helix-foundry
HelixDB/helix-foundry · ★ 1.5KHelix Foundry is a local-first data workspace that connects your company's tools (databases, Stripe, WorkOS, PostHog, files, APIs) into one suggested ontology stored in HelixDB, letting you explore and ask questions about your data.
 +17
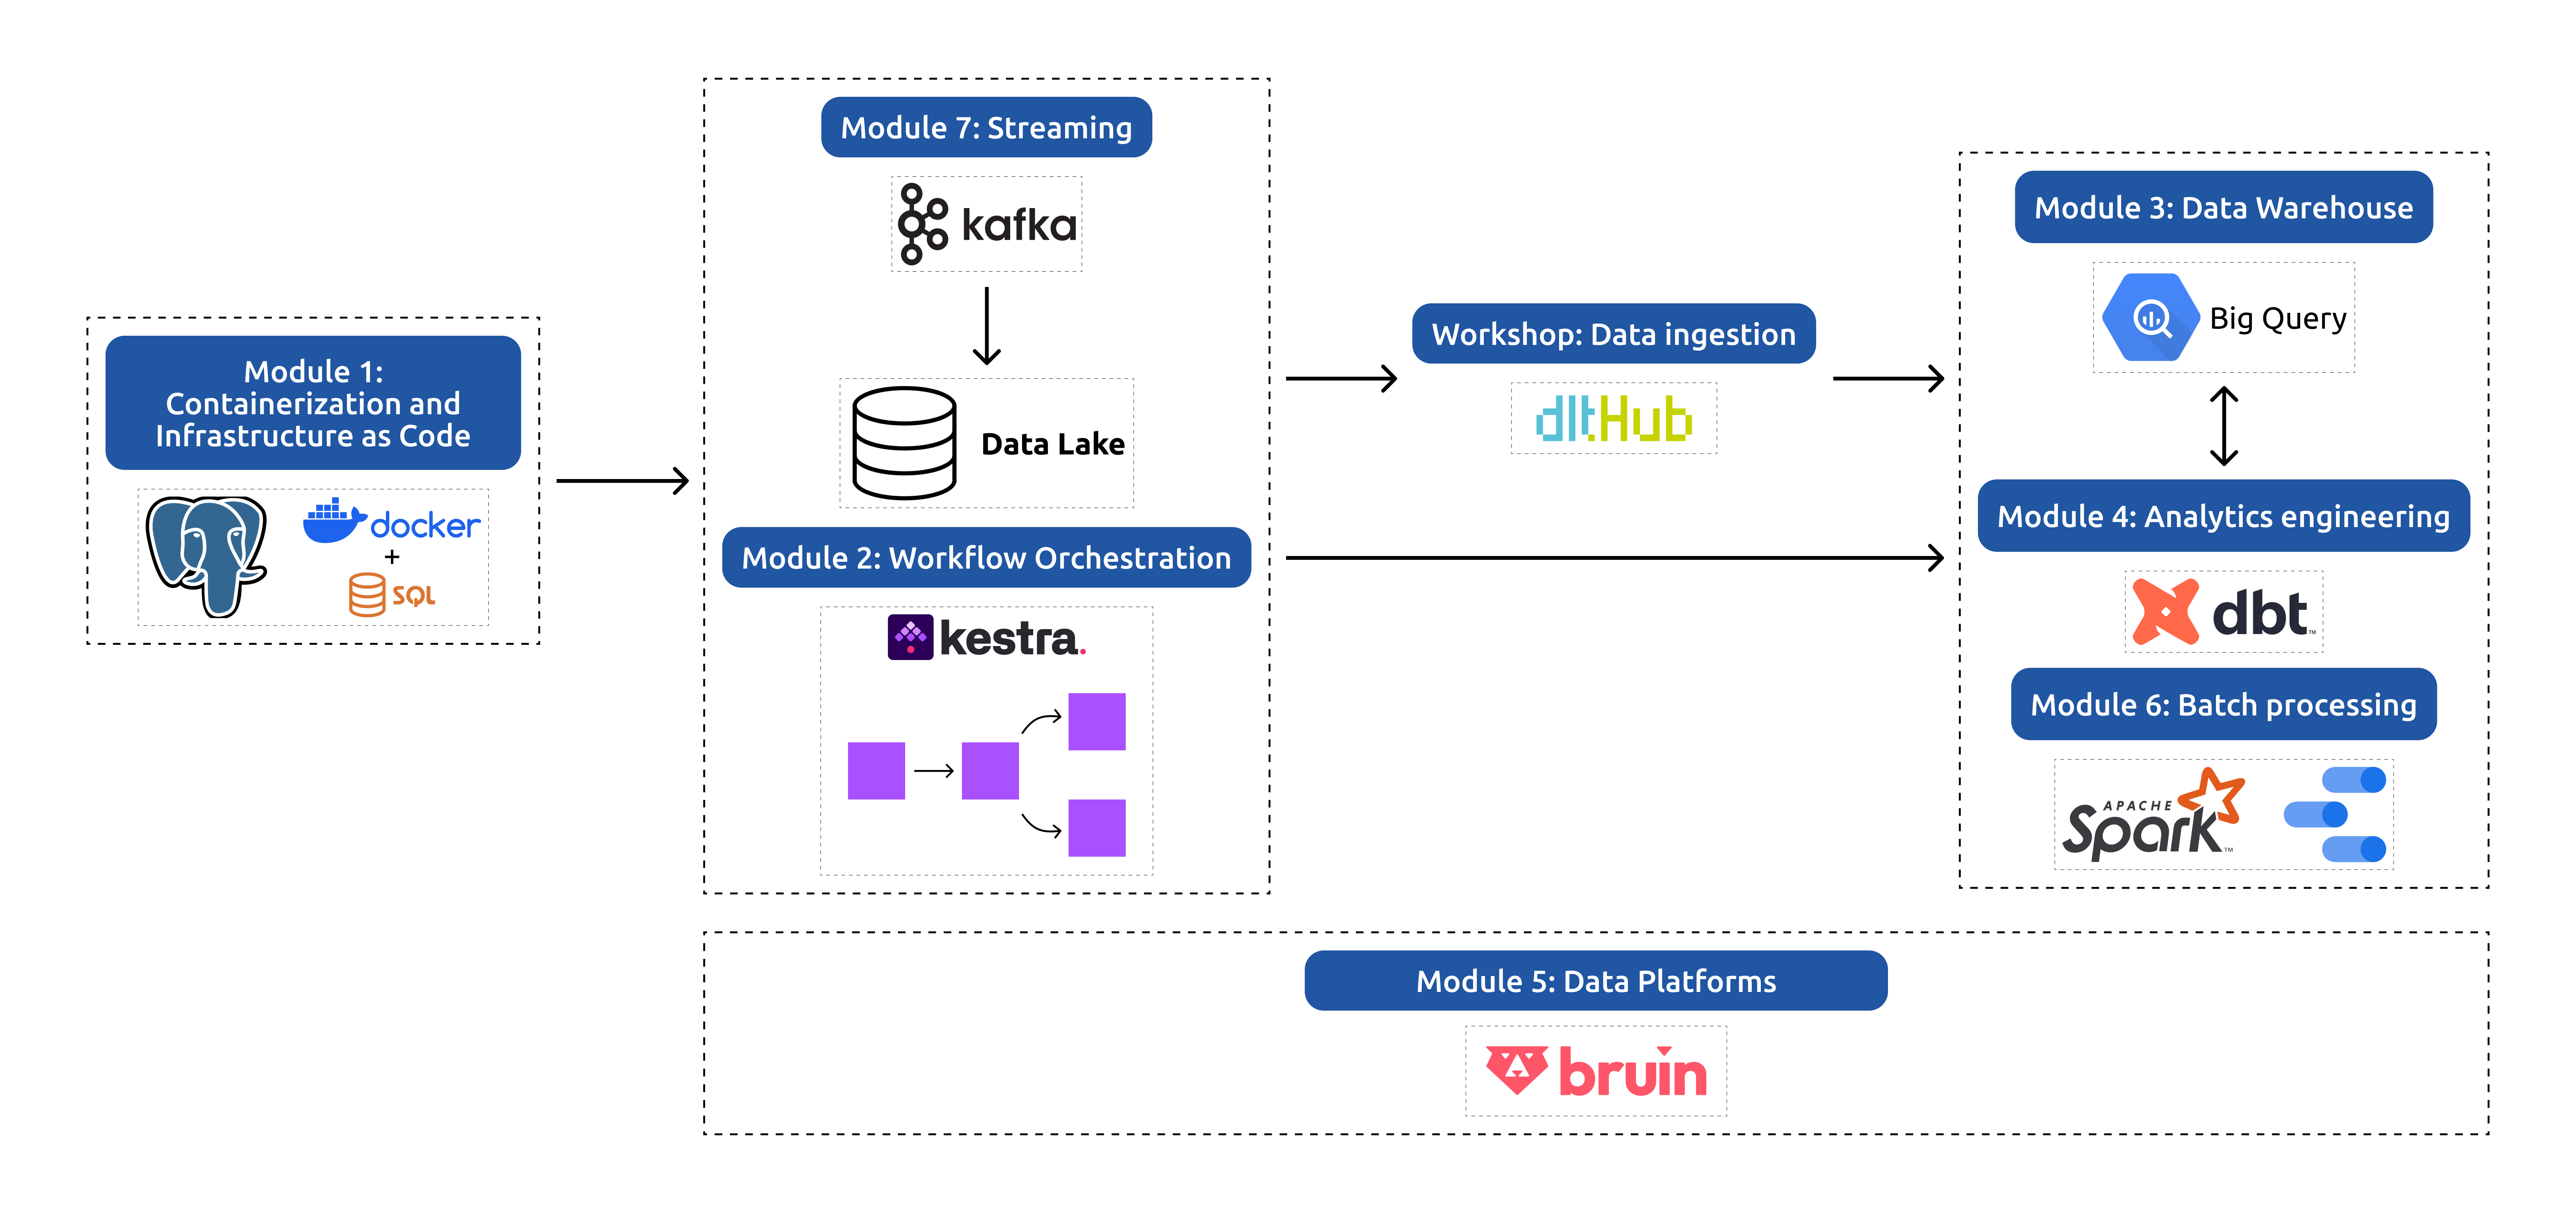
data-engineering-zoomcamp
DataTalksClub/data-engineering-zoomcamp · ★ 46.2KThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
 +16
superset
apache/superset · ★ 75.2KApache Superset is a modern, enterprise-ready business intelligence web application for data exploration and visualization: build dashboards, charts, and query data with a built-in SQL editor.
The all-time top
56 projects · by stars
- 75.2K#1 · apache/superset
superset
Apache Superset is a modern, enterprise-ready business intelligence web application for data exploration and visualization: build dashboards, charts, and query data with a built-in SQL editor.
- 50.5K
 #2 · ClickHouse/ClickHouse
ClickHouse
ClickHouse is an open-source column-oriented database management system for generating analytical data reports in real time.
- 49.8K
 #3 · GokuMohandas/Made-With-ML
Made-With-ML
Made-With-ML is a free hands-on course that teaches how to design, develop, deploy, and iterate on production-grade machine learning applications, combining ML with software engineering best practices.
- 4
airflow
47.2Kapache/airflow · PythonApache Airflow is a platform to programmatically author, schedule, and monitor workflows, defined as code using Python.
- 5
data-engineering-zoomcamp
46.2KDataTalksClub/data-engineering-zoomcamp · Jupyter NotebookThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
- 6

data-engineer-handbook
44.5KDataExpert-io/data-engineer-handbook · Jupyter NotebookA curated handbook of links and resources for learning data engineering: roadmaps, bootcamp materials, books, communities, company tooling lists, blogs, whitepapers, and a directory of data engineering content creators.
- 7
spark
44.2Kapache/spark · ScalaApache Spark is a unified analytics engine for large-scale data processing, offering high-level APIs in Scala, Java, Python, and R on top of an optimized execution engine.
- 8

AI-Expert-Roadmap
31.3KAMAI-GmbH/AI-Expert-Roadmap · JavaScriptA set of charts that map the paths and technologies for becoming a data scientist, machine learning engineer, or AI expert — the i.am.ai AI Expert Roadmap, drawn up by AMAI and published as the 2022 edition.
- 9

applied-ml
30.6Keugeneyan/applied-mlapplied-ml is a curated collection of papers, articles, and tech blogs where companies like Airbnb, Uber, Netflix, Google, and DoorDash share how they run data science and machine learning in production.
- 10
kestra
29.7Kkestra-io/kestra · JavaKestra is an open-source, event-driven orchestration platform for building data, AI, and infrastructure workflows. You describe them in declarative YAML and manage everything from a built-in web UI.
- 11
flink
26.4Kapache/flink · JavaApache Flink is an open source stream processing framework with powerful stream- and batch-processing capabilities, running your programs on its own distributed runtime.
- 12
llm-action
25.2Kliguodongiot/llm-action · HTMLIt is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
- 13
prefect
24KPrefectHQ/prefect · PythonPrefect is a Python workflow orchestration framework for turning ordinary scripts into resilient, production-grade data pipelines with scheduling, retries, caching, and event-based automations.
- 14

ddia
23.8KVonng/ddia · PythonA free Chinese translation of Martin Kleppmann's 'Designing Data-Intensive Applications' (DDIA), covering both the 1st and the complete 2nd edition; 210 contributors have polished it since 2018.
- 15

airbyte
22.2Kairbytehq/airbyte · PythonAirbyte is an open-source data movement platform for ELT pipelines and AI agents: it moves data from APIs, databases, and files into warehouses, data lakes, and AI applications, backed by a catalog of 600+ connectors. You can run it self-hosted or as Airbyte Cloud.
- 16
taipy
19.4KAvaiga/taipy · PythonTaipy is a Python framework that turns data and AI code into production-ready web applications, taking you from a simple pilot script to a deployable app without extra web development work.
- 17

luigi
18.8Kspotify/luigi · PythonLuigi is a Python package for building complex pipelines of batch jobs. It handles dependency resolution, workflow management, visualization, failure handling and command line integration.
- 18

DataX
17.4Kalibaba/DataX · JavaDataX is an offline data synchronization tool/platform from Alibaba Cloud, open-sourced from the DataWorks Data Integration product, used widely inside Alibaba to move data between heterogeneous data sources.
- 19
arrow
17.2Kapache/arrow · C++Apache Arrow is a universal columnar format plus a multi-language toolbox for fast data interchange and in-memory analytics — technologies that let data systems store, process, and move tabular data efficiently.
- 20

argo-workflows
17Kargoproj/argo-workflows · GoAn open source, container-native workflow engine for Kubernetes: it orchestrates parallel jobs where every step of your workflow runs as a container. It is a CNCF graduated project.
- 21

BigData-Notes
17Kheibaiying/BigData-Notes · JavaThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
- 22

presto
16.8Kprestodb/presto · JavaPresto is a distributed SQL query engine for running interactive analytic queries against big data sources.
- 23

dagster
16.3Kdagster-io/dagster · PythonDagster is a cloud-native data pipeline orchestrator covering the whole development lifecycle: it builds, runs, and observes data assets like tables, datasets, ML models, and reports, with built-in lineage and observability.
- 24

doris
16.1Kapache/doris · JavaApache Doris is an open-source, real-time analytics and search database built on MPP architecture. It serves fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
- 25

dvc
15.9Ktreeverse/dvc · PythonDVC (Data Version Control) is an open-source tool for versioning data and tracking ML experiments; its own citation tagline calls it 'Git for Data & Models'.
- 26
hadoop
15.7Kapache/hadoop · JavaApache Hadoop is the open-source big data platform for reliable, distributed storage and processing of very large data sets across clusters of machines.
- 27
OpenMetadata
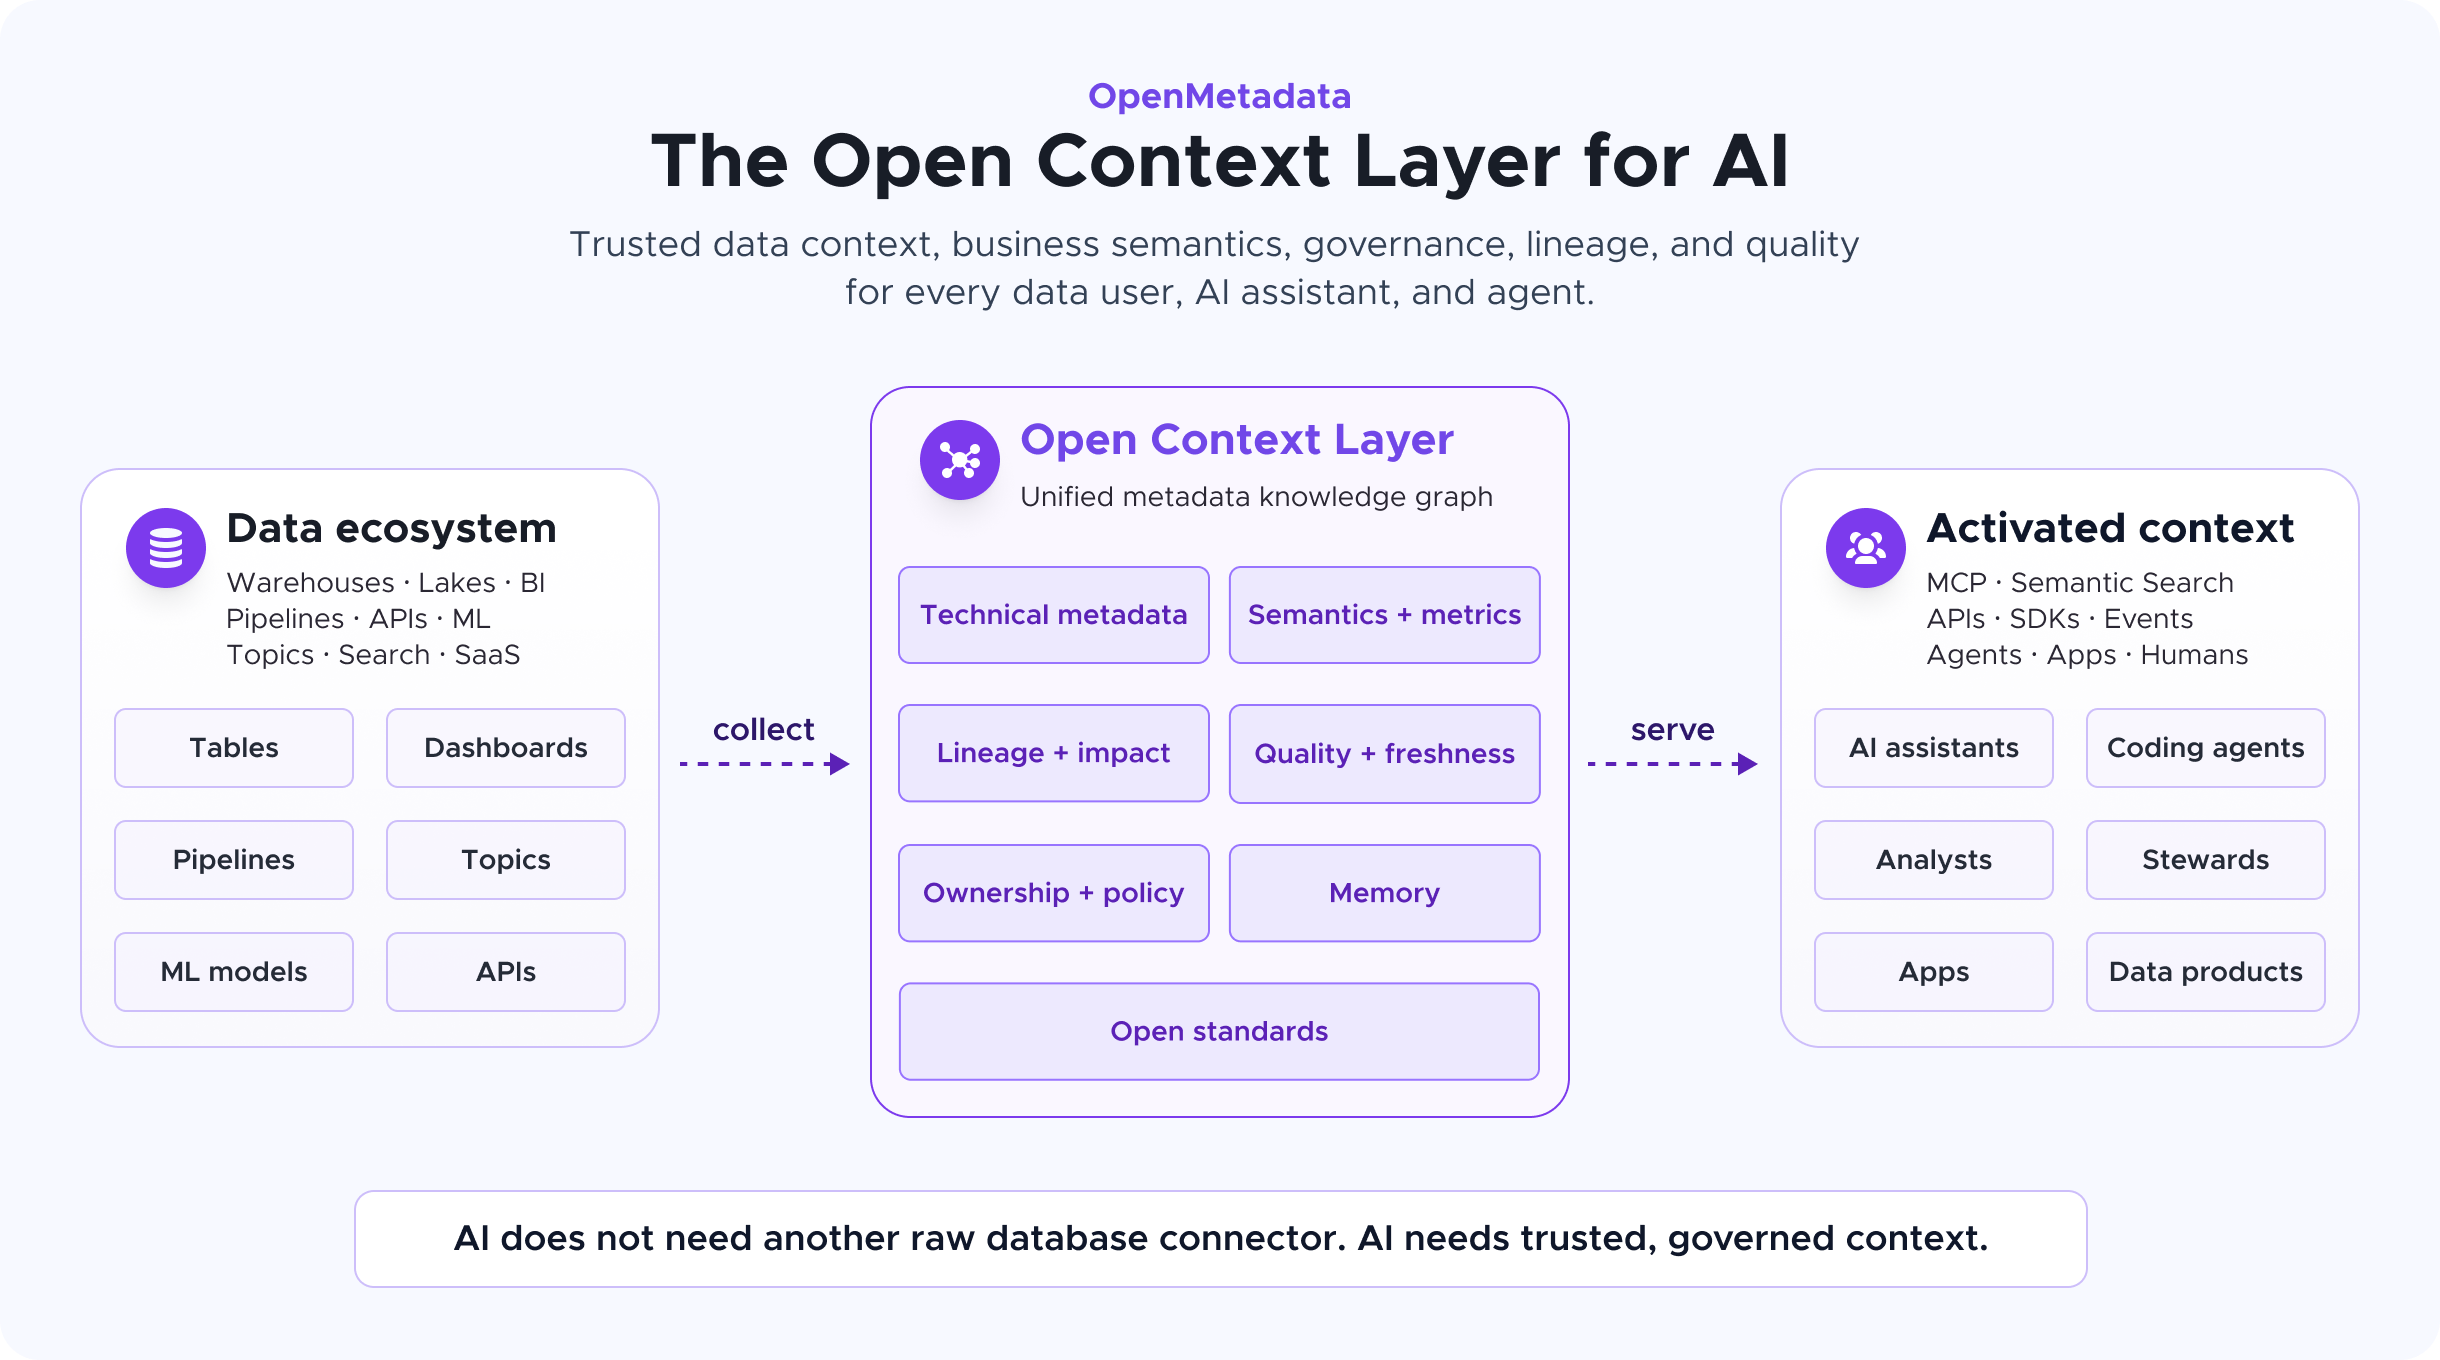
15.5Kopen-metadata/OpenMetadata · TypeScriptOpenMetadata is an open platform that unifies technical metadata, lineage, data quality, ownership and business glossaries into one knowledge graph so both humans and AI agents can discover, trust and reuse context about enterprise data.
- 28

Cookbook
15.5Kandkret/Cookbook · PythonA free online book (the Data Engineering Cookbook) that covers everything a data engineer needs to know, from basic engineering skills to advanced platform design, case studies and interview prep.
- 29

flink-learning
15.1Kzhisheng17/flink-learning · JavaA companion repo to a Chinese-language Apache Flink learning blog, packed with runnable example code, source-code analysis articles, and real-world project case studies (PV/UV stats, log storage, large-scale dedup, monitoring/alerting).
- 30

logstash
15Kelastic/logstash · JavaLogstash is a server-side data processing pipeline, part of the Elastic Stack, that ingests data from many sources at once, transforms it, and sends it to a destination like Elasticsearch.
- 31

dolphinscheduler
14.5Kapache/dolphinscheduler · JavaApache DolphinScheduler is a modern data orchestration platform for building and running complex data pipeline workflows with low-code, drag-and-drop tools.
- 32

awesome-mlops
14.2Kvisenger/awesome-mlopsA curated list of references for MLOps (Machine Learning Operations) — links to articles, books, courses, papers, tools and communities about running machine learning systems in production.
- 33
druid
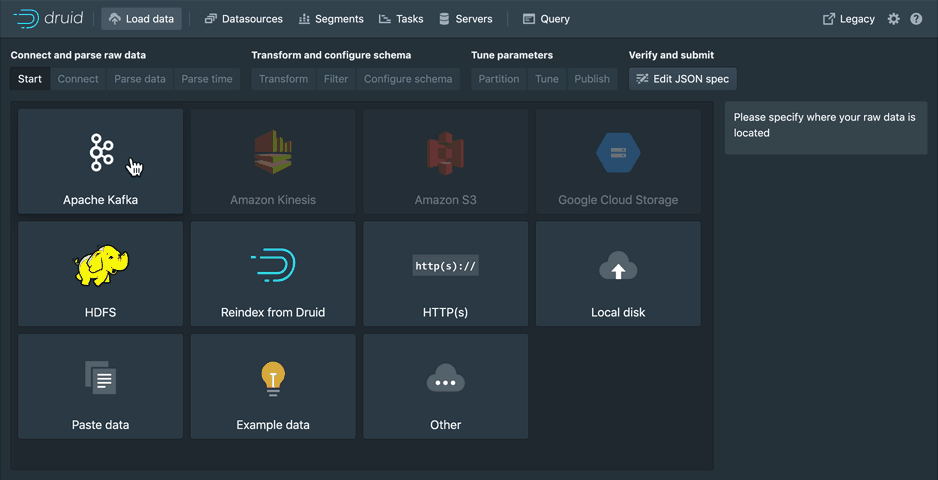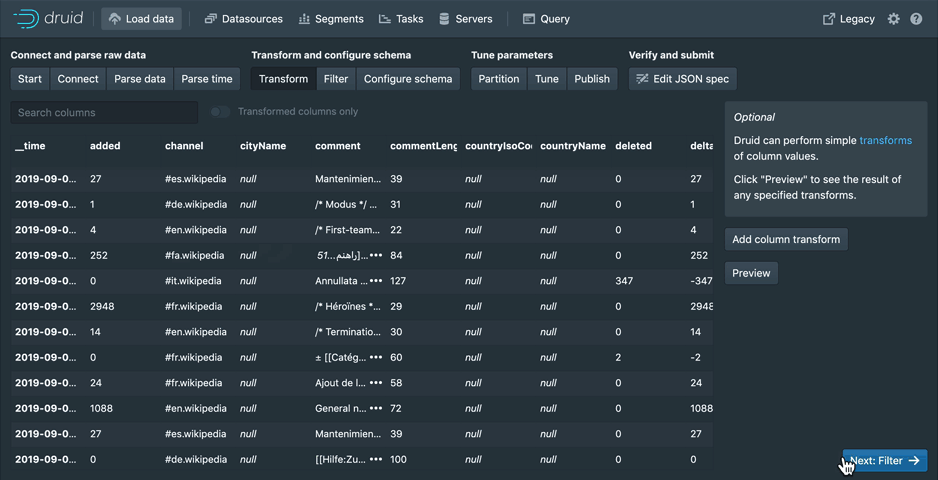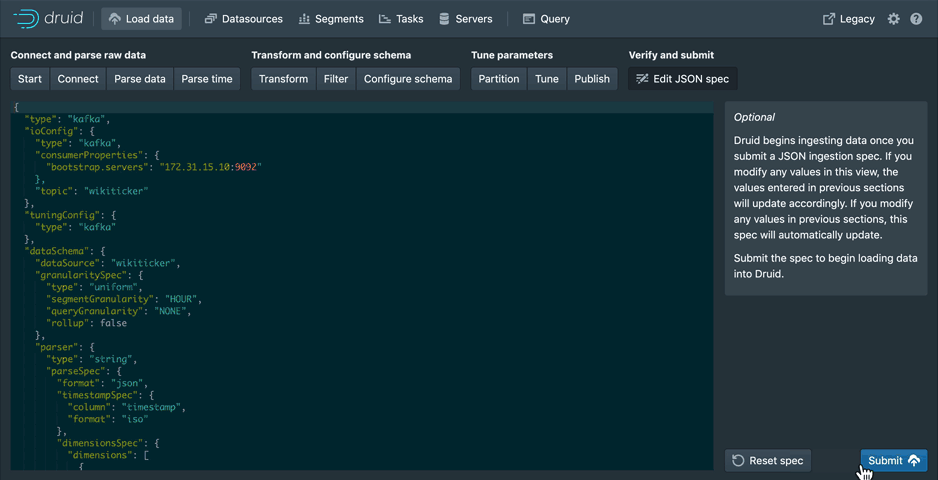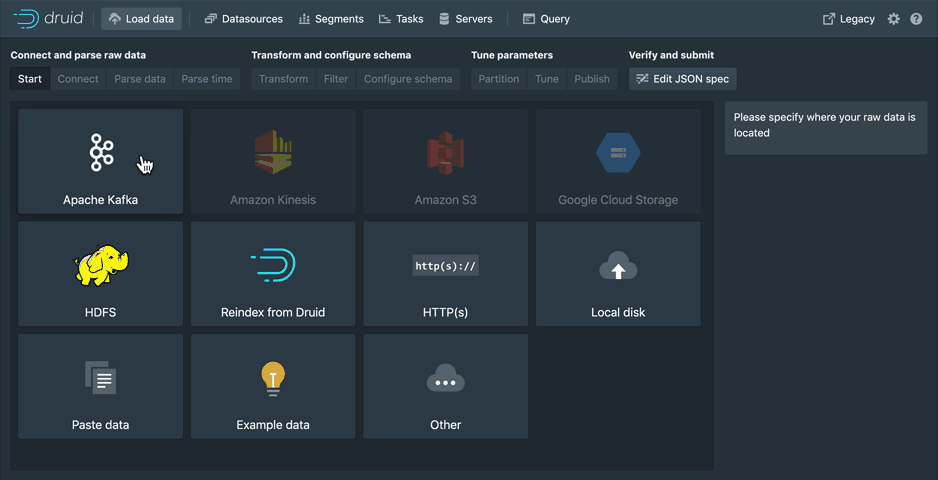
14.1Kapache/druid · JavaApache Druid is a high-performance real-time analytics database built to reduce the time between data arriving and being queryable, so dashboards and ad-hoc queries stay fast even under high concurrency.
- 34
semantica
14.1Ksemantica-agi/semantica · PythonSemantica is an open-source, graph-native infrastructure layer that ingests enterprise data and builds a structured Context Graph and knowledge graph with deterministic reasoning, ontology governance, and full decision provenance, so AI systems can be explained and audited instead of treated as black boxes.
- 35
dbt
14Kdbt-labs/dbt · Rustdbt lets data analysts and engineers transform data in their warehouse by writing SQL select statements ('models'), applying the same practices — version control, testing, modularity — that software engineers use to build applications.
- 36

dask
13.9Kdask/dask · PythonDask is a flexible parallel computing library for analytics — it runs Python data workloads as scheduled tasks so they can use many cores or machines instead of a single process.
- 37
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 38
trino
13.3Ktrinodb/trino · JavaTrino is a fast distributed SQL query engine for big data analytics — you run it as a server (or cluster) and query large datasets with standard SQL. It was formerly known as PrestoSQL.
- 39

debezium
13.2Kdebezium/debezium · JavaDebezium is an open source change data capture (CDC) platform that monitors databases and streams row-level change events to applications in real time.
- 40

datahub
12.9Kdatahub-project/datahub · PythonDataHub is an open-source metadata platform that lets you discover, understand, and govern data across your entire data stack, connecting warehouses, lakes, BI tools, and AI agents into one unified metadata graph.
- 41

data-engineer-roadmap
12.8Kdatastacktv/data-engineer-roadmapA roadmap that maps out the modern data engineering landscape, meant to serve as a study guide for people who want to become data engineers.
- 42

great_expectations
11.9Kfivetran/great_expectations · PythonGX Core (Great Expectations) is a Python framework for testing, validating, and documenting the quality of your data. Its core concept is the 'Expectation' — an expressive unit test for your data, built from the collective experience of thousands of data quality deployments.
- 43

cocoindex
11.7Kcocoindex-io/cocoindex · RustCocoIndex is an incremental engine that turns codebases, meeting notes, inboxes, Slack, PDFs, and videos into live, continuously fresh context for AI agents and LLM apps, using minimal incremental processing instead of stale batch jobs.
- 44

software-architecture-books
11.4Kmhadidg/software-architecture-booksA comprehensive list of books on Software Architecture — explicitly not a recommendation list — where each entry is a table row with title, ISBN, Goodreads rating, number of raters, and publication year.
- 45
kedro
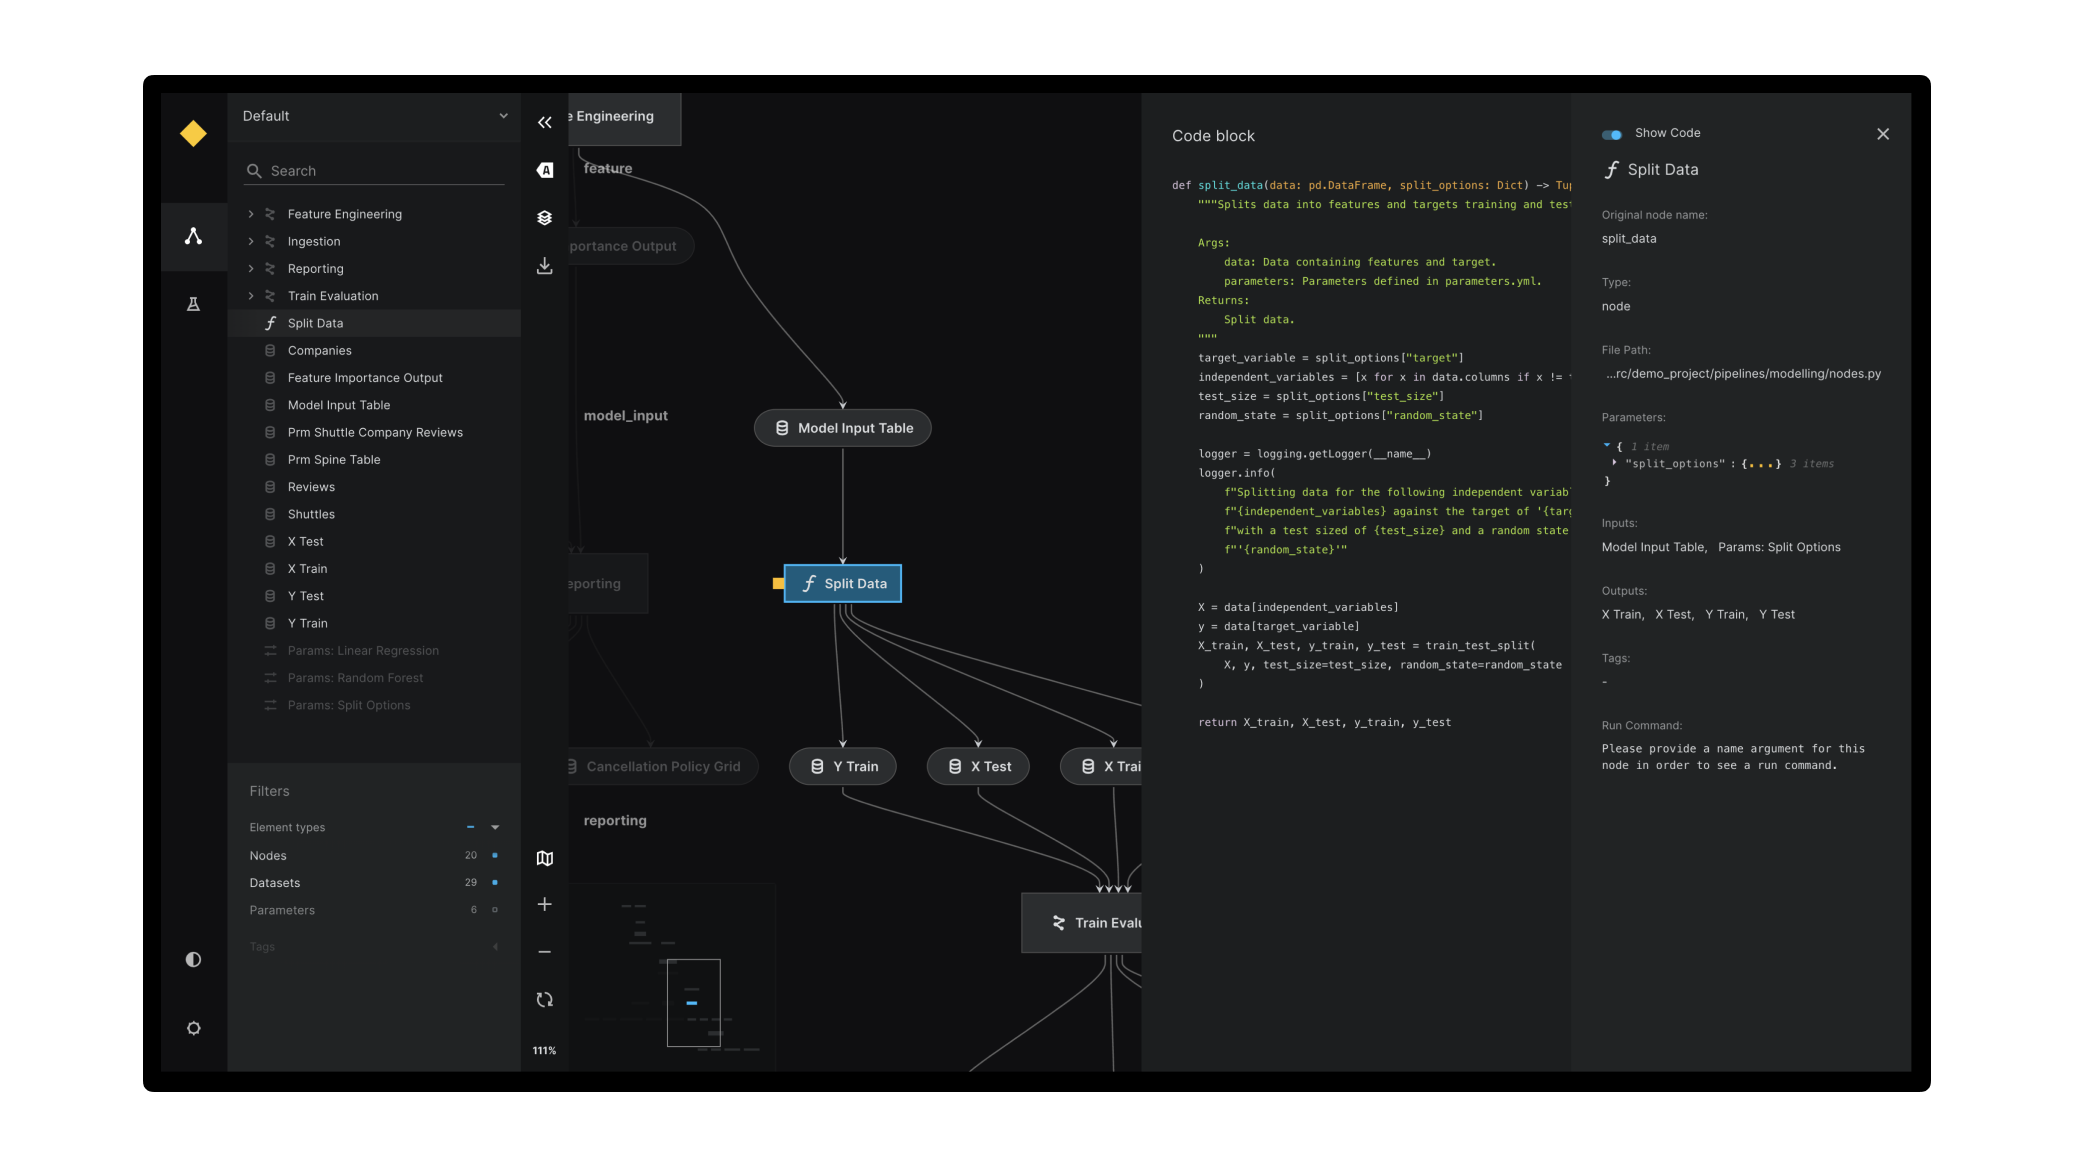
11Kkedro-org/kedro · PythonKedro is an open-source Python framework for building production-ready data engineering and data science pipelines, using software engineering best practices to make them reproducible, maintainable, and modular.
- 46

machine-learning-systems-design
10.7Kchiphuyen/machine-learning-systems-design · HTMLA free booklet on designing machine learning systems, covering four main steps: project setup, data pipeline, modeling (selecting, training, debugging), and serving (testing, deploying, maintaining), with links to practical resources and case studies.
- 47

knowledge-catalog
9.5KGoogleCloudPlatform/knowledge-catalog · TypeScriptThis is the samples and tools repository for Google Cloud's Knowledge Catalog, an AI-powered data catalog and metadata management platform (formerly called Dataplex) that builds a dynamic knowledge graph over structured and unstructured data to give AI agents semantic and business context.
- 48
DeepAnalyze
4.7Kruc-datalab/DeepAnalyze · PythonDeepAnalyze is an open-source agentic large language model built for fully autonomous data science: it can handle data preparation, analysis, modeling, visualization, and report generation on its own, across structured, semi-structured, and unstructured data sources.
- 49
ducklake
3.3Kduckdb/ducklake · C++DuckLake is an open lakehouse table format that stores data in Parquet files and stores metadata/catalog info in a SQL database, implemented as a DuckDB extension.
- 50
hotdata-cli
1.8Khotdata-dev/hotdata-cli · RustHotdata CLI is a command-line client that lets you query, search, and join data from one place — external databases, APIs, cloud storage, Iceberg catalogs, and uploaded files — using plain SQL and a handful of commands.
- 51
helix-foundry
1.5KHelixDB/helix-foundry · TypeScriptHelix Foundry is a local-first data workspace that connects your company's tools (databases, Stripe, WorkOS, PostHog, files, APIs) into one suggested ontology stored in HelixDB, letting you explore and ask questions about your data.
- 52
hflow
298Hebbian-Robotics/hflow · PythonHFlow is an open source SDK from Hebbian Robotics (YC S26) for building scalable multimodal data pipelines for robotics and physical AI, letting teams verify the quality of the data they use to train AI models.
- 53

projeto-dados-ia-databricks
279lvgalvao/projeto-dados-ia-databricks · PythonThis is a 4-night hands-on course that builds the data and sales analytics stack of a fictional B2B perfume distributor from scratch, using Databricks Free Edition, SQL, Python and Claude Code.
- 54
walshadow
242ClickHouse/walshadow · Rustwalshadow replicates PostgreSQL rows into ClickHouse by reading the physical WAL — initial load, continuous changes, schema evolution, restarts, and planned source switchover are all part of the flow.
- 55
crab
155crabbuild/crab · RustCrab is a Git extension that keeps large files like models, datasets, media, and build artifacts out of ordinary Git blobs. Git stores small pointer files while Crab stores the real content as deduplicated chunks in an S3, GCS, Azure, or S3-compatible bucket you own.
- 56

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.

Related topics
Often tagged together