Topics / #text-processing
Text-processing projects on GitHub
Manipulating and transforming text with code and CLI tools.
As of , the most-starred Text-processing projects on GitHub are markitdown (190.7K stars), bat (60.8K stars) and pandoc (46.6K stars). GitHub.Locker tracks 40 Text-processing repositories with 751.2K stars combined. The fastest-growing on October 16 was markitdown, with +216 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +216
markitdown
microsoft/markitdown · ★ 190.7KMarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
 +115
yomiyasu
nanaism/yomiyasu · ★ 2.1Kyomiyasu is an Agent Skill that revises AI-generated Japanese text into more natural, information-dense Japanese, meant to be loaded into AI coding environments such as Codex, Claude Code, and Cursor.
 +71
asd-ste100-skill
danyuchn/asd-ste100-skill · ★ 5.1KA Claude Code skill that rewrites dense, ambiguous English into ASD-STE100 Simplified Technical English (the controlled-language standard aerospace manuals use), but aimed at text an AI agent has to parse — tool descriptions, error messages, and inter-agent messages — instead of human readers.
 +20
lieflat-less-ai-tone
larashero3-dotcom/lieflat-less-ai-tone · ★ 2.8KA research-backed skill that detects and removes 'AI tone' from Chinese writing, based on a statistical study of a 2.83-million-character corpus comparing AI-generated and human-written text.
The all-time top
40 projects · by stars
- 190.7K#1 · microsoft/markitdown
markitdown
MarkItDown is a lightweight Python utility that converts files like PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV/JSON/XML, ZIP archives, EPubs and even YouTube URLs into Markdown, designed for feeding documents into LLMs and text analysis pipelines.
- 60.8K
 #2 · sharkdp/bat
bat
bat is a cat(1) clone that prints files in the terminal with syntax highlighting for a large number of programming and markup languages, plus Git modification markers in the sidebar.
- 46.6K
 #3 · jgm/pandoc
pandoc
Pandoc is a Haskell library for converting documents from one markup format to another, plus the command-line tool built on top of it — a universal markup converter.
- 4
tesseract.js
38.8Knaptha/tesseract.js · JavaScriptTesseract.js is a pure JavaScript OCR library that extracts text from images in more than 100 languages, running the Tesseract engine compiled to WebAssembly.
- 5

jq
35.8Kjqlang/jq · Cjq is a lightweight command-line JSON processor, akin to sed, awk and grep but for JSON data: it slices, filters, maps and transforms structured data right in your terminal.
- 6

jieba
35.2Kfxsjy/jieba · PythonJieba is a popular open-source Python library for Chinese word segmentation: it cuts Chinese text into words, supporting Simplified and Traditional Chinese. 'Jieba' means 'to stutter' in Chinese.
- 7

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 8
fmt
25.9Kfmtlib/fmt · C++{fmt} is an open-source C++ formatting library — a fast, safe alternative to C stdio and C++ iostreams, with a format string syntax similar to Python's.
- 9

markdown-it
22Kmarkdown-it/markdown-it · TypeScriptmarkdown-it is a fast Markdown parser for JavaScript with 100% CommonMark support. It also adds syntax extensions and sugar like URL autolinking and a typographer.
- 10

tiktoken
19.5Kopenai/tiktoken · Pythontiktoken is a fast byte pair encoding (BPE) tokenizer built for use with OpenAI's models, converting text into tokens and back again.
- 11

newspaper
15.2Kcodelucas/newspaper · PythonNewspaper3k is a Python 3 library that downloads, parses, and extracts the article text, authors, publish date, top image, and keywords/summary from news articles and news sites.
- 12

languagetool
15.1Klanguagetool-org/languagetool · JavaOpen-source proofreading software that checks grammar and style in English, German, French, Spanish, Polish, Dutch and more — over 25 languages — catching many errors a simple spell checker misses.
- 13

parsedown
15Kerusev/parsedown · PHPParsedown is a Markdown parser library for PHP: you feed it Markdown text and it converts it into HTML.
- 14

nltk
14.7Knltk/nltk · PythonNLTK is a suite of open source Python modules, bundled data sets, and tutorials supporting research and development in Natural Language Processing.
- 15

linguist
13.7Kgithub-linguist/linguist · RubyLinguist is the library GitHub.com uses to detect the programming language of files (blobs), ignore binary or vendored files, suppress generated files in diffs, and build the language breakdown graphs shown on repository pages.
- 16
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 17
compromise
12.2Kspencermountain/compromise · JavaScriptCompromise is a lightweight JavaScript natural-language processing library that parses text into structured data: tokenizing words and sentences, tagging part-of-speech, and letting you query phrases like numbers, names, or dates.
- 18
presidio
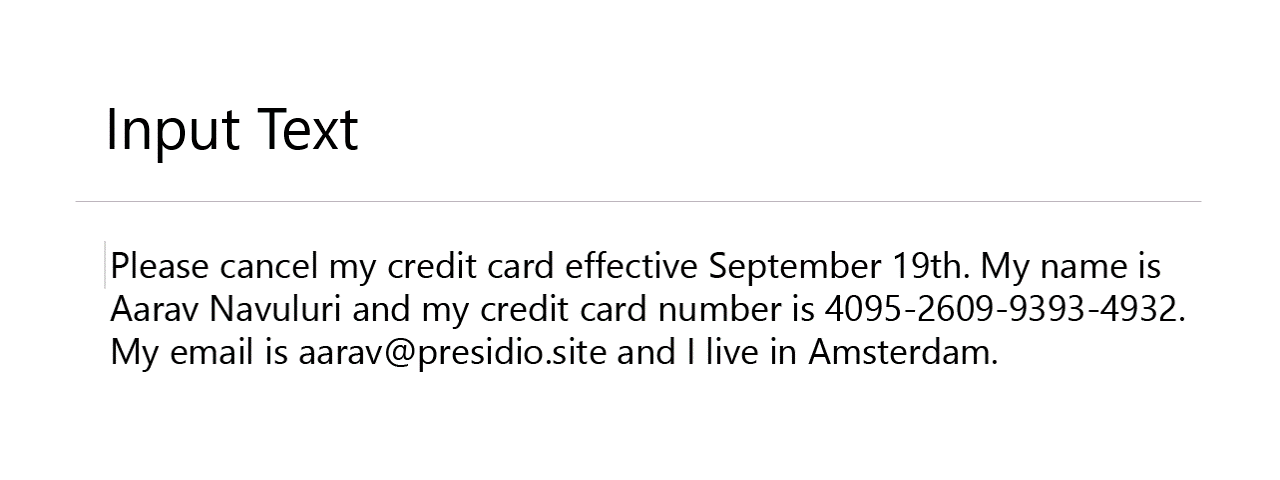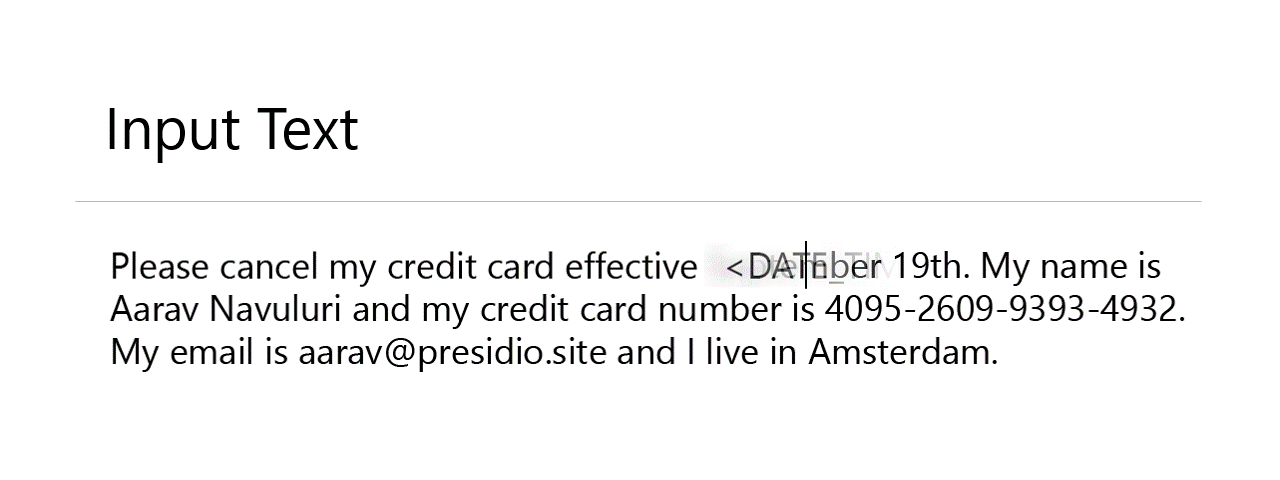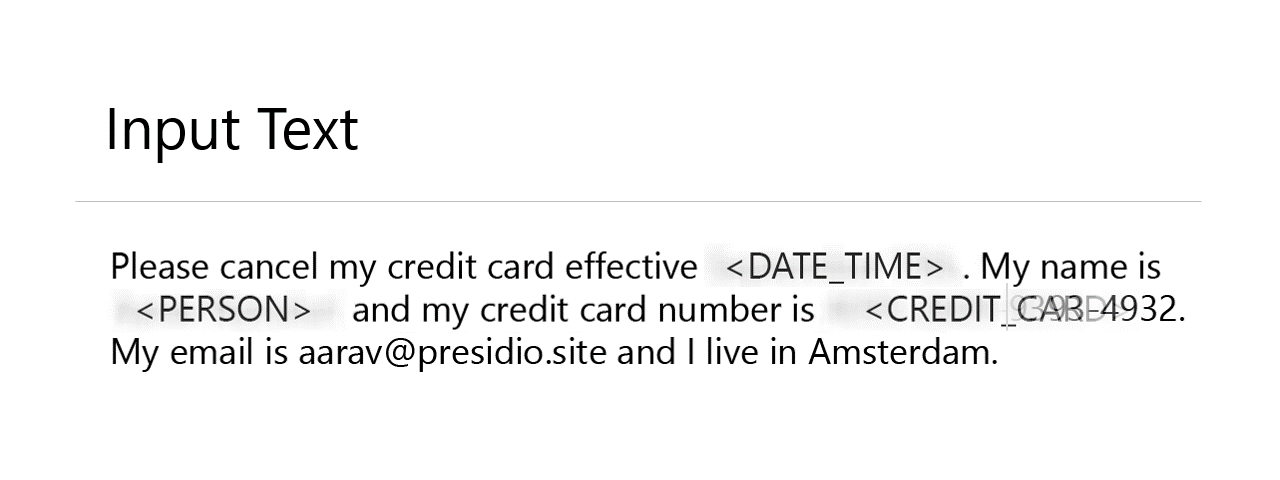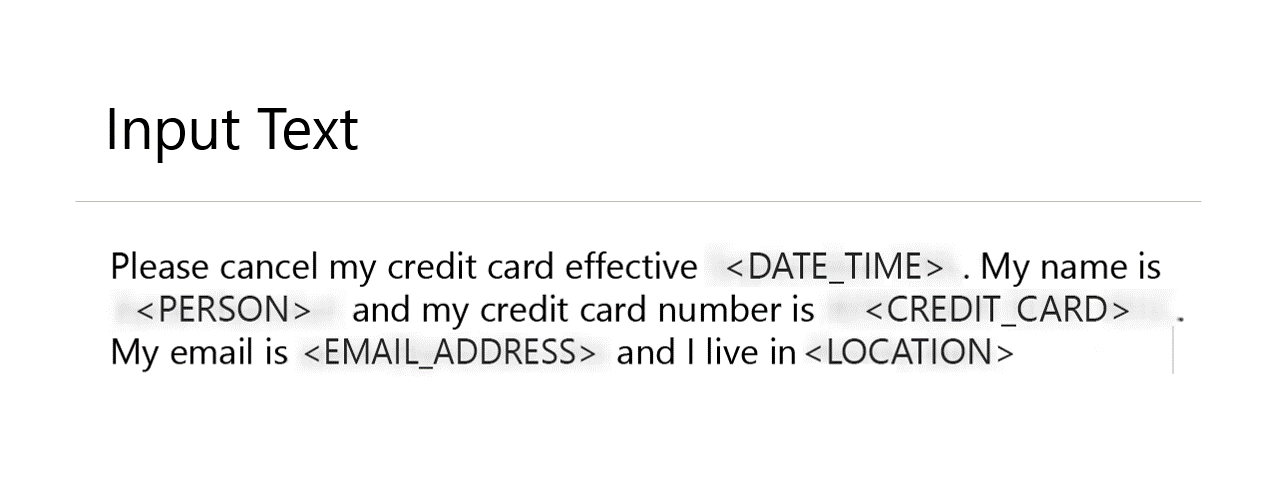
11.4Kdata-privacy-stack/presidio · PythonAn open-source framework (SDK) that detects, redacts, masks and anonymizes sensitive data (PII) — names, credit card numbers, SSNs, phone numbers — in text, images and structured data.
- 19

inflector
11.3Kdoctrine/inflector · PHPDoctrine Inflector is a small PHP library that performs string manipulations with regard to uppercase/lowercase and singular/plural forms of words.
- 20
lexer
11.1Kdoctrine/lexer · PHPDoctrine Lexer is a base PHP library for building lexers — the components that turn raw text into tokens — for top-down, recursive descent parsers.
- 21

PyMuPDF
10.9Kpymupdf/PyMuPDF · PythonPyMuPDF is a high-performance Python library for extracting, analyzing, converting, rendering, and manipulating PDF and other document formats, built on the MuPDF C engine.
- 22
natural
10.9KNaturalNode/natural · JavaScriptNatural is a general-purpose natural language processing library for Node.js that bundles tokenizers, stemmers, classifiers and other NLP utilities into one package.
- 23

pdfplumber
10.8Kjsvine/pdfplumber · Pythonpdfplumber is a Python library that inspects PDFs in detail, exposing each character, line, rectangle, and curve, and makes it easy to extract text and tables from them.
- 24
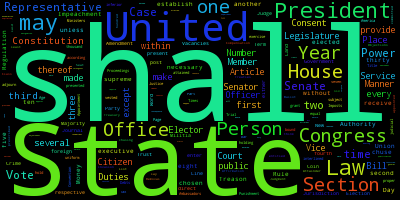
word_cloud
10.5Kamueller/word_cloud · Pythonword_cloud is a little word cloud generator in Python: it turns a body of text into an image where each word is sized by how often it appears. It works as a Python library and also ships a small command-line tool called wordcloudcli.
- 25

nom
10.5Krust-bakery/nom · Rustnom is a parser combinator library for Rust: you build safe parsers by composing small functions, without giving up speed or memory efficiency.
- 26

q
10.4Kharelba/q · Pythonq is a command-line tool that runs SQL directly on delimited text files (CSV, TSV) and on multi-file SQLite databases, treating files as tables you can query.
- 27

pypdf
10.3Kpy-pdf/pypdf · PythonA free and open-source pure-python PDF library: it splits, merges, crops and transforms the pages of PDF files, and can add custom data, viewing options and passwords to them.
- 28

Command-line-text-processing
10.2Klearnbyexample/Command-line-text-processing · ShellA learning repository that teaches command-line text processing tools on Linux: grep, sed, awk, Perl one-liners, Ruby one-liners, sort, diff, and more, organized into chapters with examples and exercises.
- 29
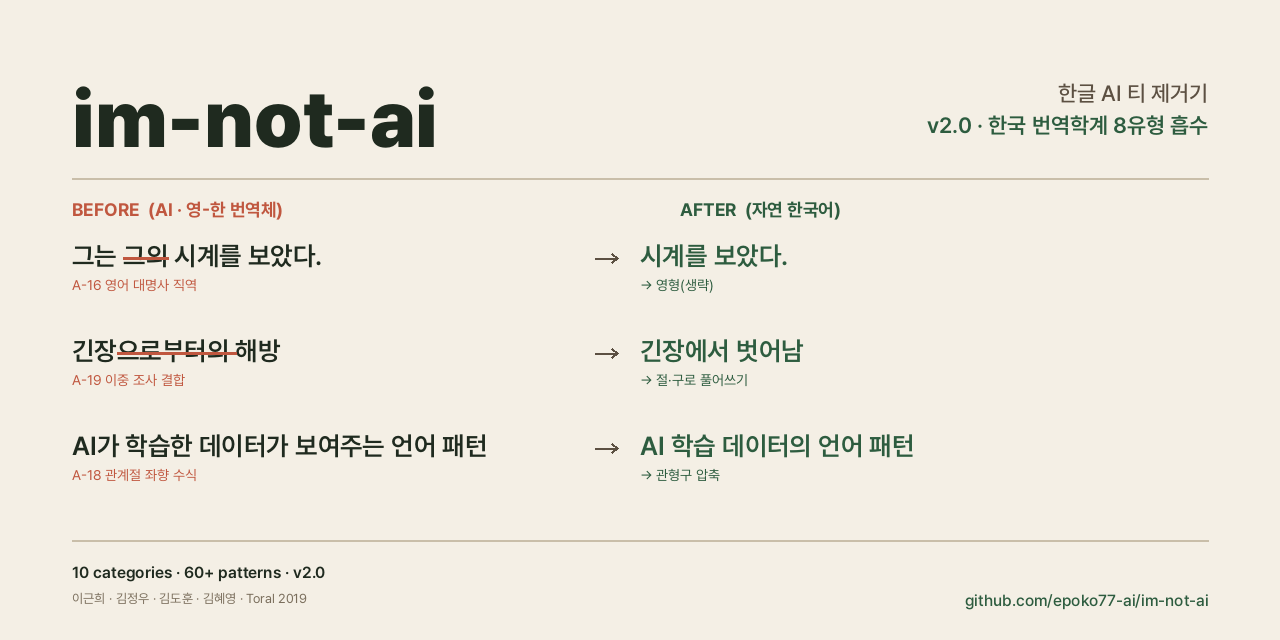
im-not-ai
6Kepoko77-ai/im-not-ai · PythonThis is a Claude Skill that rewrites Korean text written by AI (ChatGPT, Claude, Gemini) so it reads like it was written by a human, removing translationese, mechanical parallelism and other 'AI tells' without changing the actual content.
- 30
asd-ste100-skill
5.1Kdanyuchn/asd-ste100-skill · PythonA Claude Code skill that rewrites dense, ambiguous English into ASD-STE100 Simplified Technical English (the controlled-language standard aerospace manuals use), but aimed at text an AI agent has to parse — tool descriptions, error messages, and inter-agent messages — instead of human readers.
- 31

gigatoken
4.1Kmarcelroed/gigatoken · RustGigatoken is an extremely fast tokenizer for language models, built as a near drop-in replacement for HuggingFace Tokenizers and tiktoken, encoding text at multi-GB/s speeds.
- 32
lieflat-less-ai-tone
2.8Klarashero3-dotcom/lieflat-less-ai-tone · PythonA research-backed skill that detects and removes 'AI tone' from Chinese writing, based on a statistical study of a 2.83-million-character corpus comparing AI-generated and human-written text.
- 33
yomiyasu
2.1Knanaism/yomiyasu · Pythonyomiyasu is an Agent Skill that revises AI-generated Japanese text into more natural, information-dense Japanese, meant to be loaded into AI coding environments such as Codex, Claude Code, and Cursor.
- 34
natural-japanese
1.9Kcoji/natural-japanese · PythonAn Agent Skill for writing and revising clear, natural Japanese for work documents — meeting minutes, reports, internal guides, proposals, blog posts. Its whole point is stripping the telltale 'AI smell' from machine-written prose.
- 35

marisa-trie
1.1Kpytries/marisa-trie · CythonStatic, memory-efficient trie-like data structures for Python, built on the marisa-trie C++ library. Strings stored inside can take up to 50x-100x less memory than in a standard Python dict, with comparable lookup speed and fast prefix search.
- 36
Evidence-Bound-Press-Conference-Revision-Skill
270lensback940701/Evidence-Bound-Press-Conference-Revision-Skill · PythonIt is an evidence-bound revision skill for academic manuscripts in social science research. It strips out defensive, self-protective prose (hedging, work-log narration, anticipatory rebuttals) while keeping every scope condition, evidence-status distinction, and rival explanation that the evidence actually supports.
- 37
iso-24495-skill
154danyuchn/iso-24495-skillA Claude Code skill that rewrites your text into plain language following ISO 24495-1:2023 — the standard that defines plain language by reader outcome: readers can find what they need, understand it on first reading, and use it. It works on English and Traditional Chinese.
- 38

claude-watermark-cleaner
151mikiane/claude-watermark-cleaner · PythonAn experimental Python CLI that tries to strip Claude's statistical text watermark: it removes suspicious invisible Unicode characters, then has a non-Claude model rewrite the text. It doubles as a critical demo arguing such watermarks are easy to circumvent.
- 39
paper-docx
122paper-instruments/paper-docx · Pythonpaper-docx is an agent-safe fork of python-docx for creating and editing Microsoft Word (.docx) documents, built to refuse unsupported operations instead of silently corrupting files.
- 40

roster-match
104charlenemercury/roster-match · JavaScriptA zero-dependency JavaScript library that matches a Chinese name heard through speech recognition (or any garbled transcript) to the correct entry in a roster, comparing by pinyin syllables and surfacing candidates with reasons instead of forcing a decision when it is unsure.
Related topics
Often tagged together
- open-source5,666
- mit3,312
- developer-tools2,924
- library1,587
- python2,383
- linux4,184
- macos3,544
- nlp214
- cli2,227
- windows3,403
- cross-platform2,623
- command-line424
- llm1,483
- natural-language-processing96
- tool1,295
- writing57
- ai1,955
- api1,094
- command-line-tool715
- machine-learning916
- parser60
- terminal1,101
- agent-skills553
- claude503