Topics / #agent-evaluation
Agent-evaluation projects on GitHub
Frameworks and benchmarks for measuring quality, reliability, and task success of AI agents.
As of , the most-starred Agent-evaluation projects on GitHub are iFixAi (29.7K stars), agents-cli (6.1K stars) and Tracely-ai (1K stars). GitHub.Locker tracks 9 Agent-evaluation repositories with 38.4K stars combined. The fastest-growing on October 18 was iFixAi, with +541 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +541
iFixAi
ifixai-ai/iFixAi · ★ 29.7KiFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
 +94
Tracely-ai
jwuthri-cloud/Tracely-ai · ★ 1KTracely is a trace-native CI/CD platform for AI agents: it grades every production agent trace, clusters failures into issues, freezes bad runs into hermetic regression tests, blocks the PR that would ship them again, and alerts you when it happens.
 +30
Harness-RSI
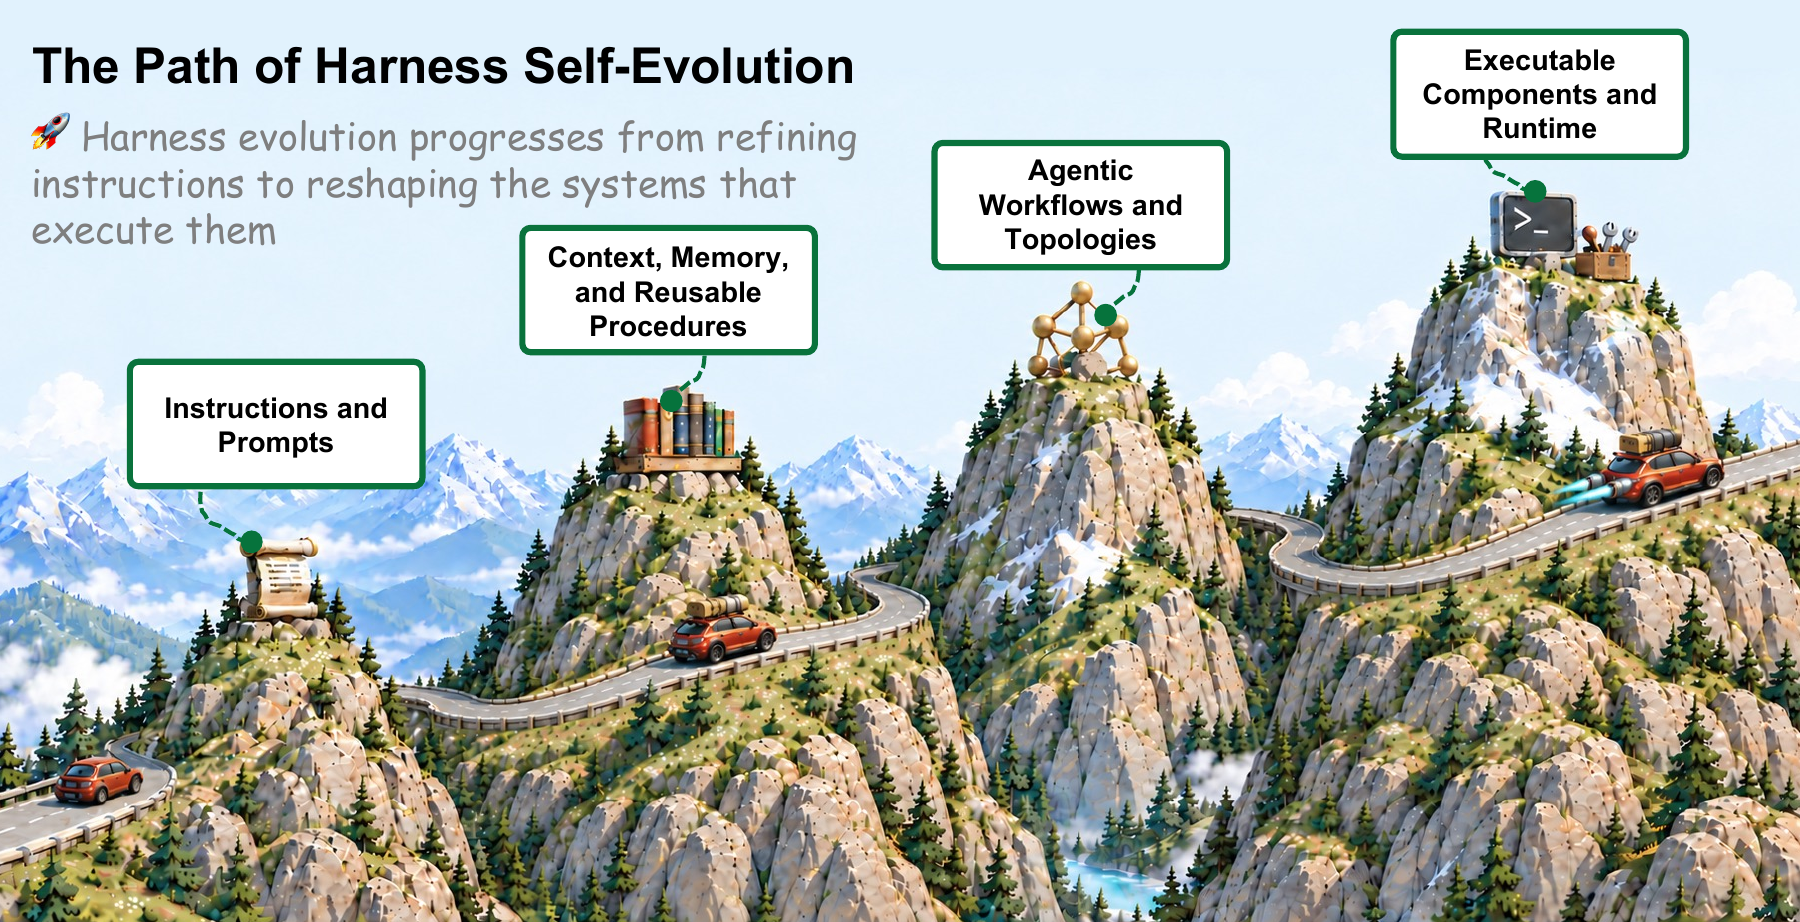
zgcagi/Harness-RSI · ★ 202It is the companion reading list and resource site for a survey on 'Harness Self-Evolution' — how LLM agent harnesses (prompts, memory, workflows) get updated from execution experience while the underlying model weights stay fixed.
 +1
agents-cli
google/agents-cli · ★ 6.1Kagents-cli gives your coding assistant (Claude Code, Codex, Antigravity CLI, etc.) the CLI commands and skill files it needs to build, evaluate, and deploy AI agents on Google Cloud using the Agent Development Kit (ADK).
The all-time top
9 projects · by stars
- 29.7K#1 · ifixai-ai/iFixAi
iFixAi
iFixAi is an independent auditing tool for AI agents: it runs a diagnostic suite against your agent and answers the core question — is the agent doing the job it is supposed to do — with an A-F grade in under 120 seconds.
- 6.1K#2 · google/agents-cli
agents-cli
agents-cli gives your coding assistant (Claude Code, Codex, Antigravity CLI, etc.) the CLI commands and skill files it needs to build, evaluate, and deploy AI agents on Google Cloud using the Agent Development Kit (ADK).
- 1K#3 · jwuthri-cloud/Tracely-ai
Tracely-ai
Tracely is a trace-native CI/CD platform for AI agents: it grades every production agent trace, clusters failures into issues, freezes bad runs into hermetic regression tests, blocks the PR that would ship them again, and alerts you when it happens.
- 4

GamePhanes
462GamePhanesStudio/GamePhanes · PythonGameForgeBench is a benchmark that evaluates coding agents on building, debugging, and repairing real game projects (Godot and other engines) through terminal workflows, judged by actual runtime behavior rather than just file diffs.
- 5
ASI-Bench
301apexin-ai/ASI-Bench · PythonASI-Bench is a benchmark for evaluating AI agents on long-horizon scientific research: it jointly tests general intelligence, innovation, and autonomous execution across 60 project-level tasks in 11 domains.
- 6
Recuris
242Gen-Verse/Recuris · PythonRecuris is a recursive self-improvement framework that boosts long-horizon LLM agents by evolving their memory instead of their weights or prompt. A frozen agent is paired with a structured Skill Memory, and a meta-agent patches it based on execution traces, only keeping changes that pass a validation gate.
- 7
AgentMeasure
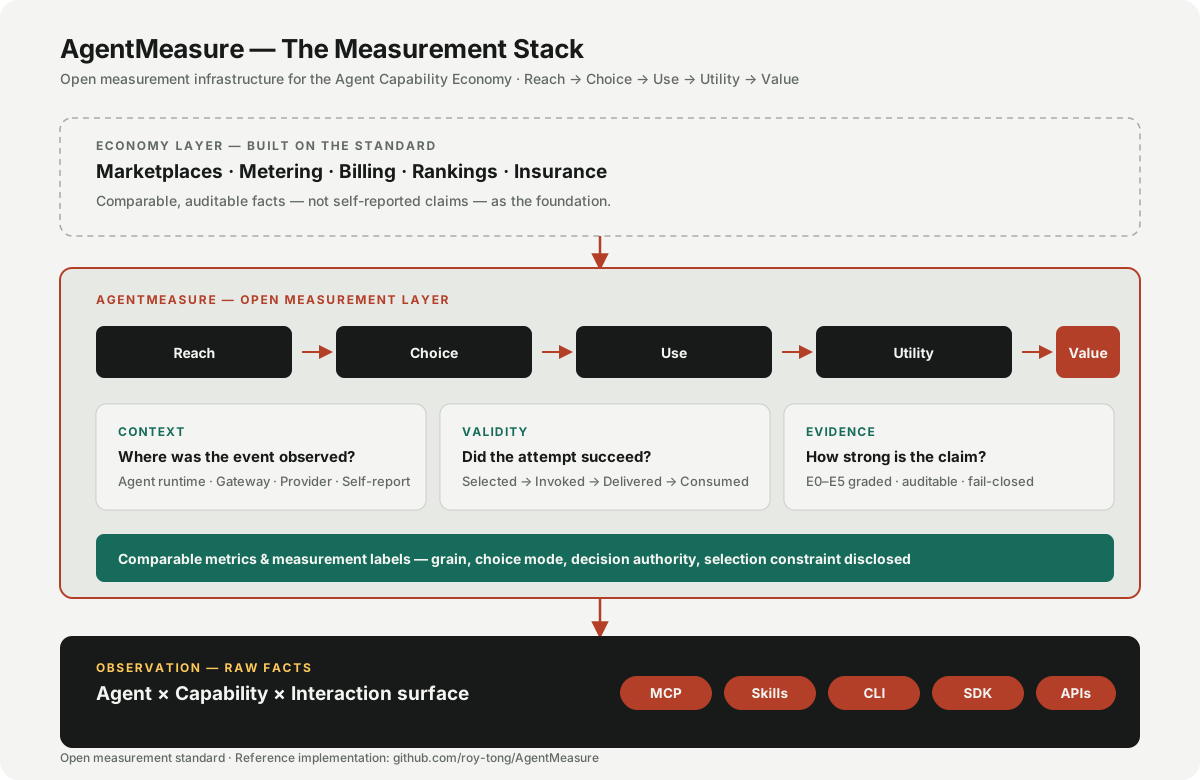
218roy-tong/AgentMeasure · PythonAgentMeasure is an open measurement layer for AI-agent usage: a free CLI and SDK that audit Codex and Claude Code session logs and verify that agent metrics and metering numbers mean what their labels claim.
- 8
Harness-RSI
202zgcagi/Harness-RSI · TeXIt is the companion reading list and resource site for a survey on 'Harness Self-Evolution' — how LLM agent harnesses (prompts, memory, workflows) get updated from execution experience while the underlying model weights stay fixed.
- 9

egma
145egma-ai/egma · TypeScriptEgma is an open-source platform for testing voice agents before you ship them and monitoring them in production — simulated regression suites plus live analytics of real conversations.
Related topics
Often tagged together
- ai-agents1,322
- cli2,275
- evaluation159
- llm1,516
- python2,425
- ai1,993
- developer-tools2,981
- linux4,248
- llm-evaluation37
- macos3,608
- open-source5,748
- windows3,480
- agent839
- agents430
- apache-2.01,452
- benchmark444
- docker1,684
- mit3,387
- observability238
- academic-research220
- agent-observability13
- agentic-ai319
- claude-code928
- codex732