11K ·GitHub
What is this?
 A generator for fresh, original ARC-AGI-1-style puzzle tasks whose statistical distribution matches the public ARC-AGI-1 evaluation set, so models can be tested on problems they haven't seen before.
Is this a dataset or a task-generation tool?It's a generator script, not a static dataset: it produces a tasks.json file on demand that follows the standard ARC format and plugs into existing ARC evaluation harnesses.
It's a generator script, not a static dataset: it produces a tasks.json file on demand that follows the standard ARC format and plugs into existing ARC evaluation harnesses.How do I generate the tasks?Follow the step-by-step instructions in the repo's instructions.md file to produce a tasks.json set.
Follow the step-by-step instructions in the repo's instructions.md file to produce a tasks.json set.Why not just reuse the existing public ARC-AGI-1 test set?The public set can't fully rule out models having prior familiarity with its tasks, so this tool creates a private, distribution-matched set to give a cleaner comparison point.
The public set can't fully rule out models having prior familiarity with its tasks, so this tool creates a private, distribution-matched set to give a cleaner comparison point.Who is this generator meant for?Researchers and model evaluators who want to benchmark reasoning models like BDH-CQ (or others) on ARC-style problems without contamination from publicly known tasks.
Researchers and model evaluators who want to benchmark reasoning models like BDH-CQ (or others) on ARC-style problems without contamination from publicly known tasks.What is BDH-CQ?BDH-CQ is a reasoning model built on the Dragon Hatchling (BDH) post-Transformer recurrent architecture; it uses continuously updated recurrent memory and solves queries through iterative latent-space computation instead of generating a text chain of thought.
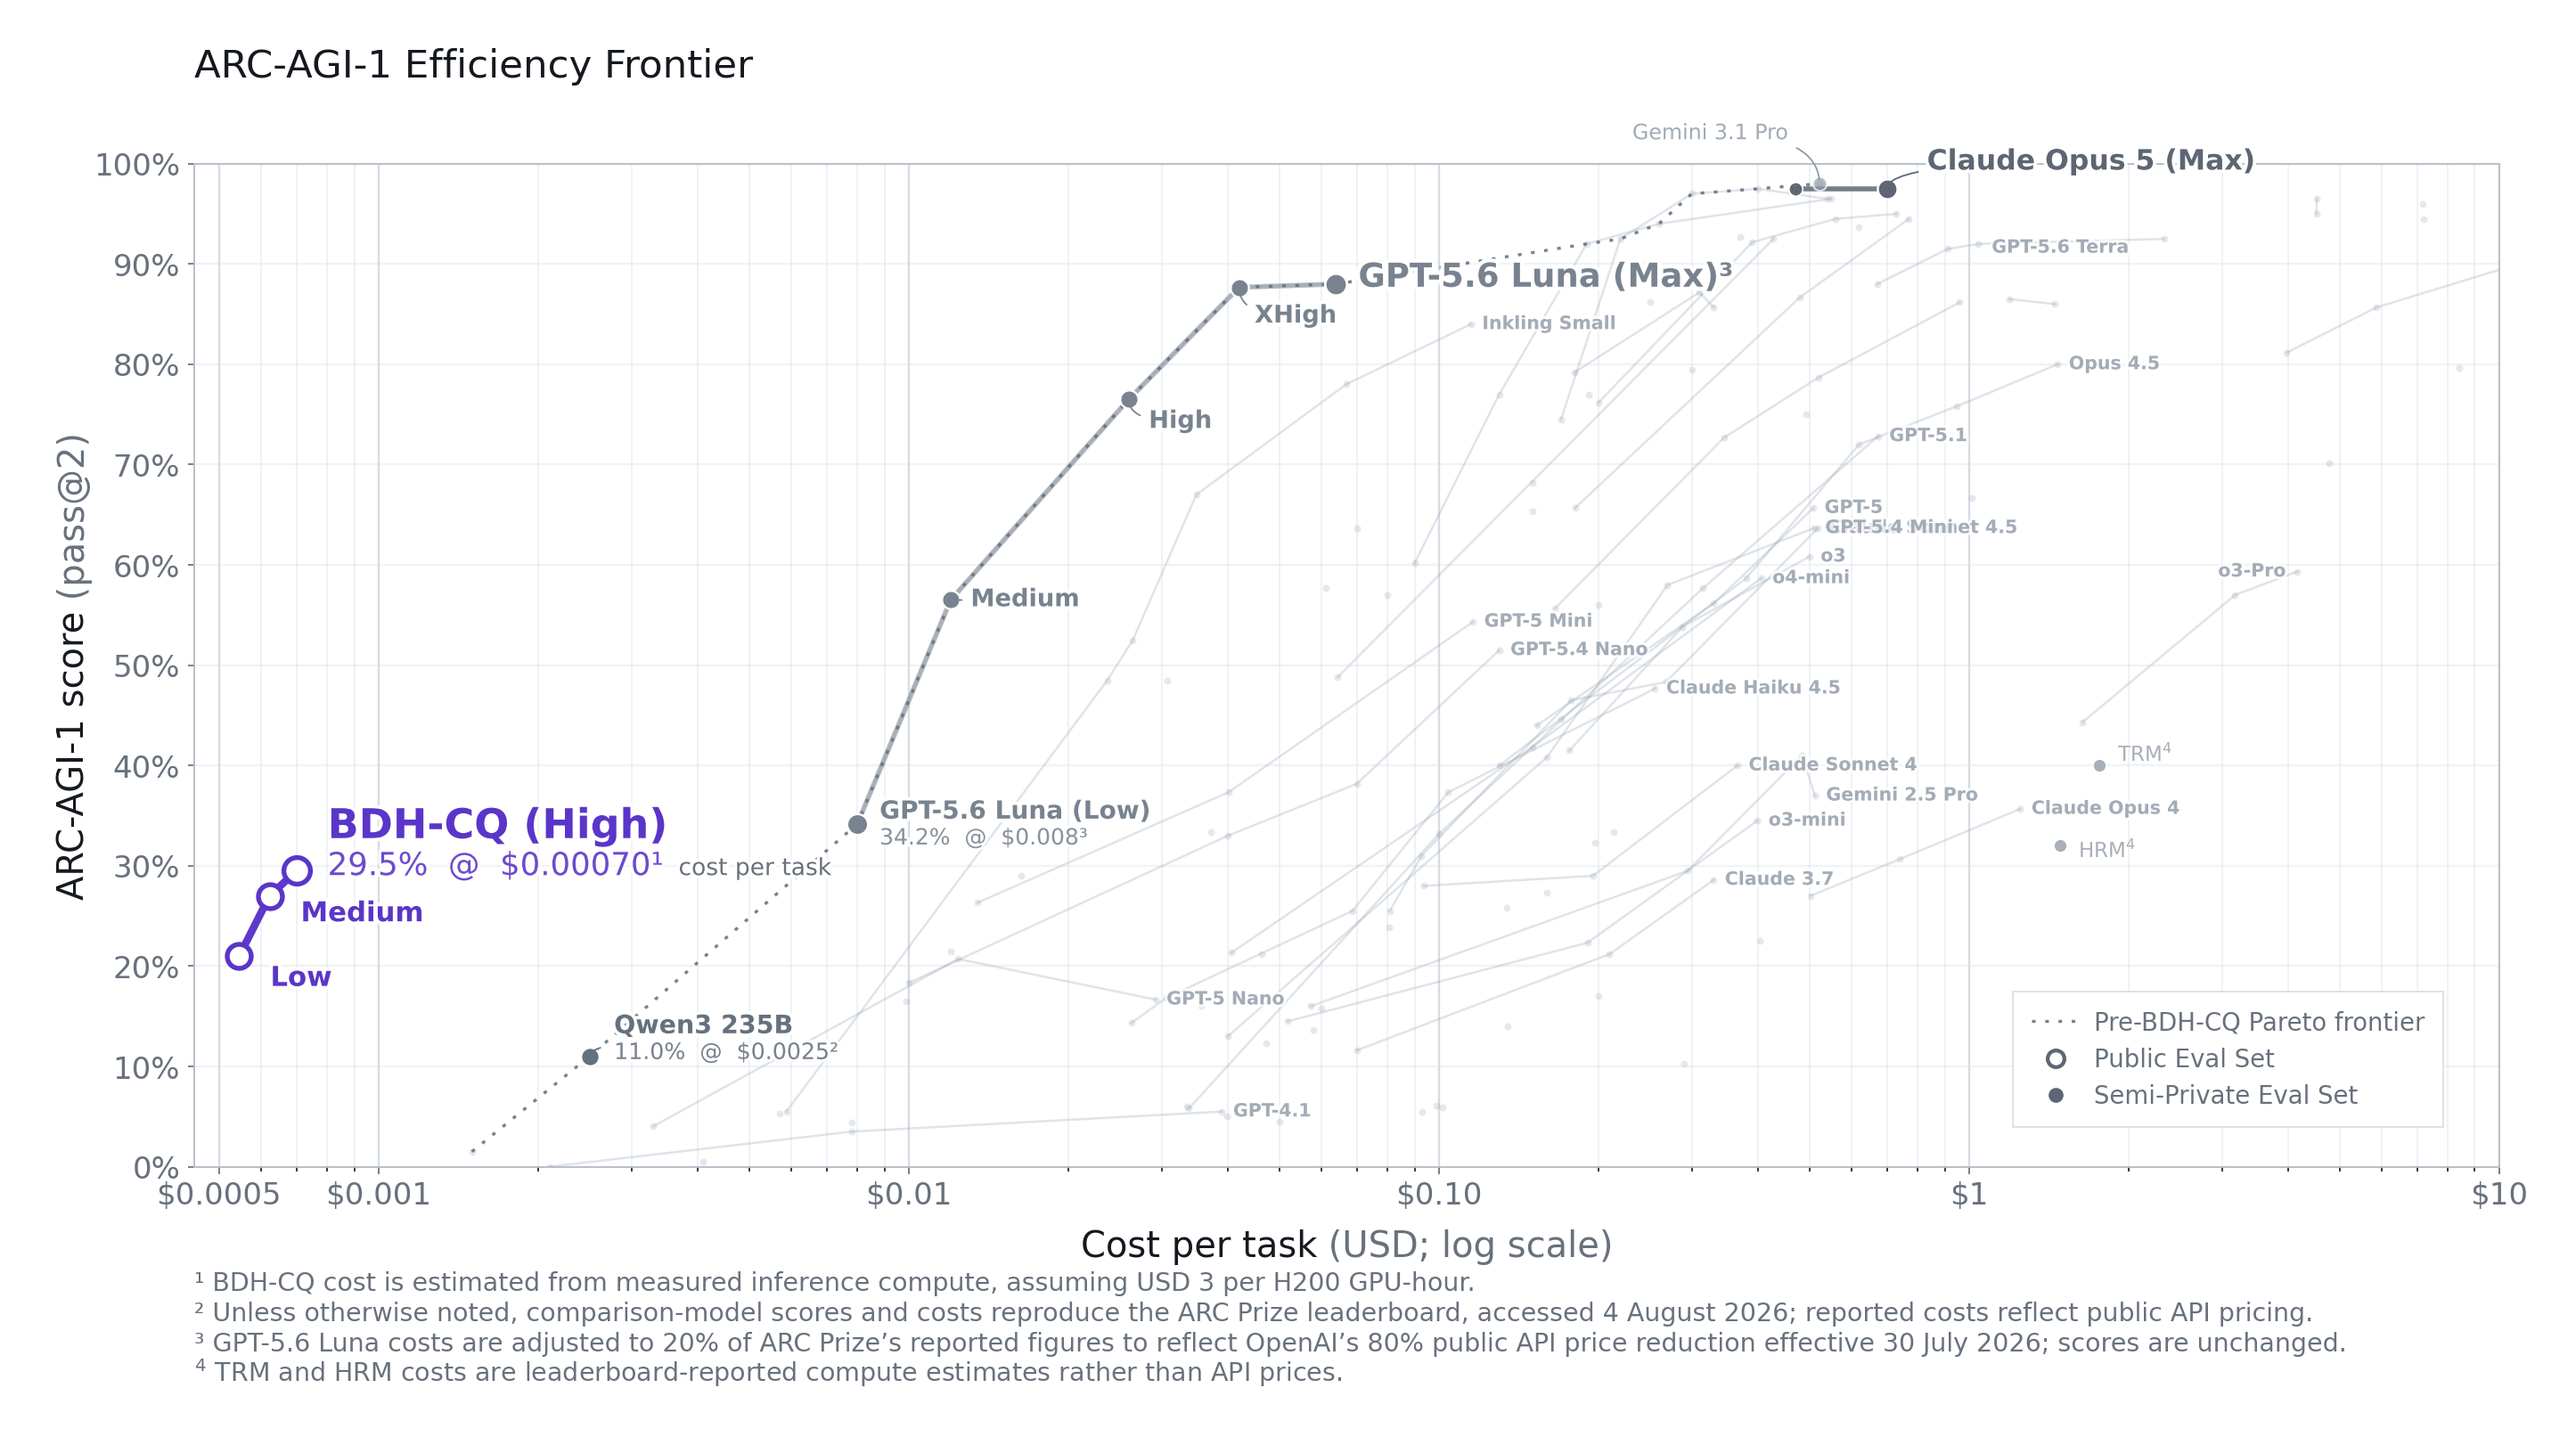
BDH-CQ is a reasoning model built on the Dragon Hatchling (BDH) post-Transformer recurrent architecture; it uses continuously updated recurrent memory and solves queries through iterative latent-space computation instead of generating a text chain of thought.How well does BDH-CQ perform on ARC-AGI-1?A 150M-parameter BDH-CQ configuration reaches 29.5% pass@2 on the public ARC-AGI-1 evaluation set at roughly $0.0007 per task, about 11x cheaper per task than GPT-5.6 Luna (Low).
A 150M-parameter BDH-CQ configuration reaches 29.5% pass@2 on the public ARC-AGI-1 evaluation set at roughly $0.0007 per task, about 11x cheaper per task than GPT-5.6 Luna (Low).Have the reported results been independently checked?Yes, they were reproduced by Łukasz Kaiser (Transformer/TensorFlow co-author), Remigiusz Kinas (Bielik contributor), and Richard Zhong (NYU researcher), focusing on evaluation and benchmark robustness.
Yes, they were reproduced by Łukasz Kaiser (Transformer/TensorFlow co-author), Remigiusz Kinas (Bielik contributor), and Richard Zhong (NYU researcher), focusing on evaluation and benchmark robustness.Is there a paper or write-up explaining this work?Yes, the repo accompanies the paper 'BDH-CQ: Introducing In-Context Learning with Recurrent Latent Reasoning' plus a companion blog post.
Yes, the repo accompanies the paper 'BDH-CQ: Introducing In-Context Learning with Recurrent Latent Reasoning' plus a companion blog post.What are similar projects?bdh, MSA, Attention-Residuals, math, APSD, ParseBench, timeseries-atlas, High-Angle_Robust_Fast_FaceAlignment
bdh, MSA, Attention-Residuals, math, APSD, ParseBench, timeseries-atlas, High-Angle_Robust_Fast_FaceAlignmentWhich topics is it in?llm-evaluation, reasoning, paper, dataset, evaluation, neural-network, academic-research, transformer, benchmark, deep-learning, research, machine-learning
llm-evaluation, reasoning, paper, dataset, evaluation, neural-network, academic-research, transformer, benchmark, deep-learning, research, machine-learning