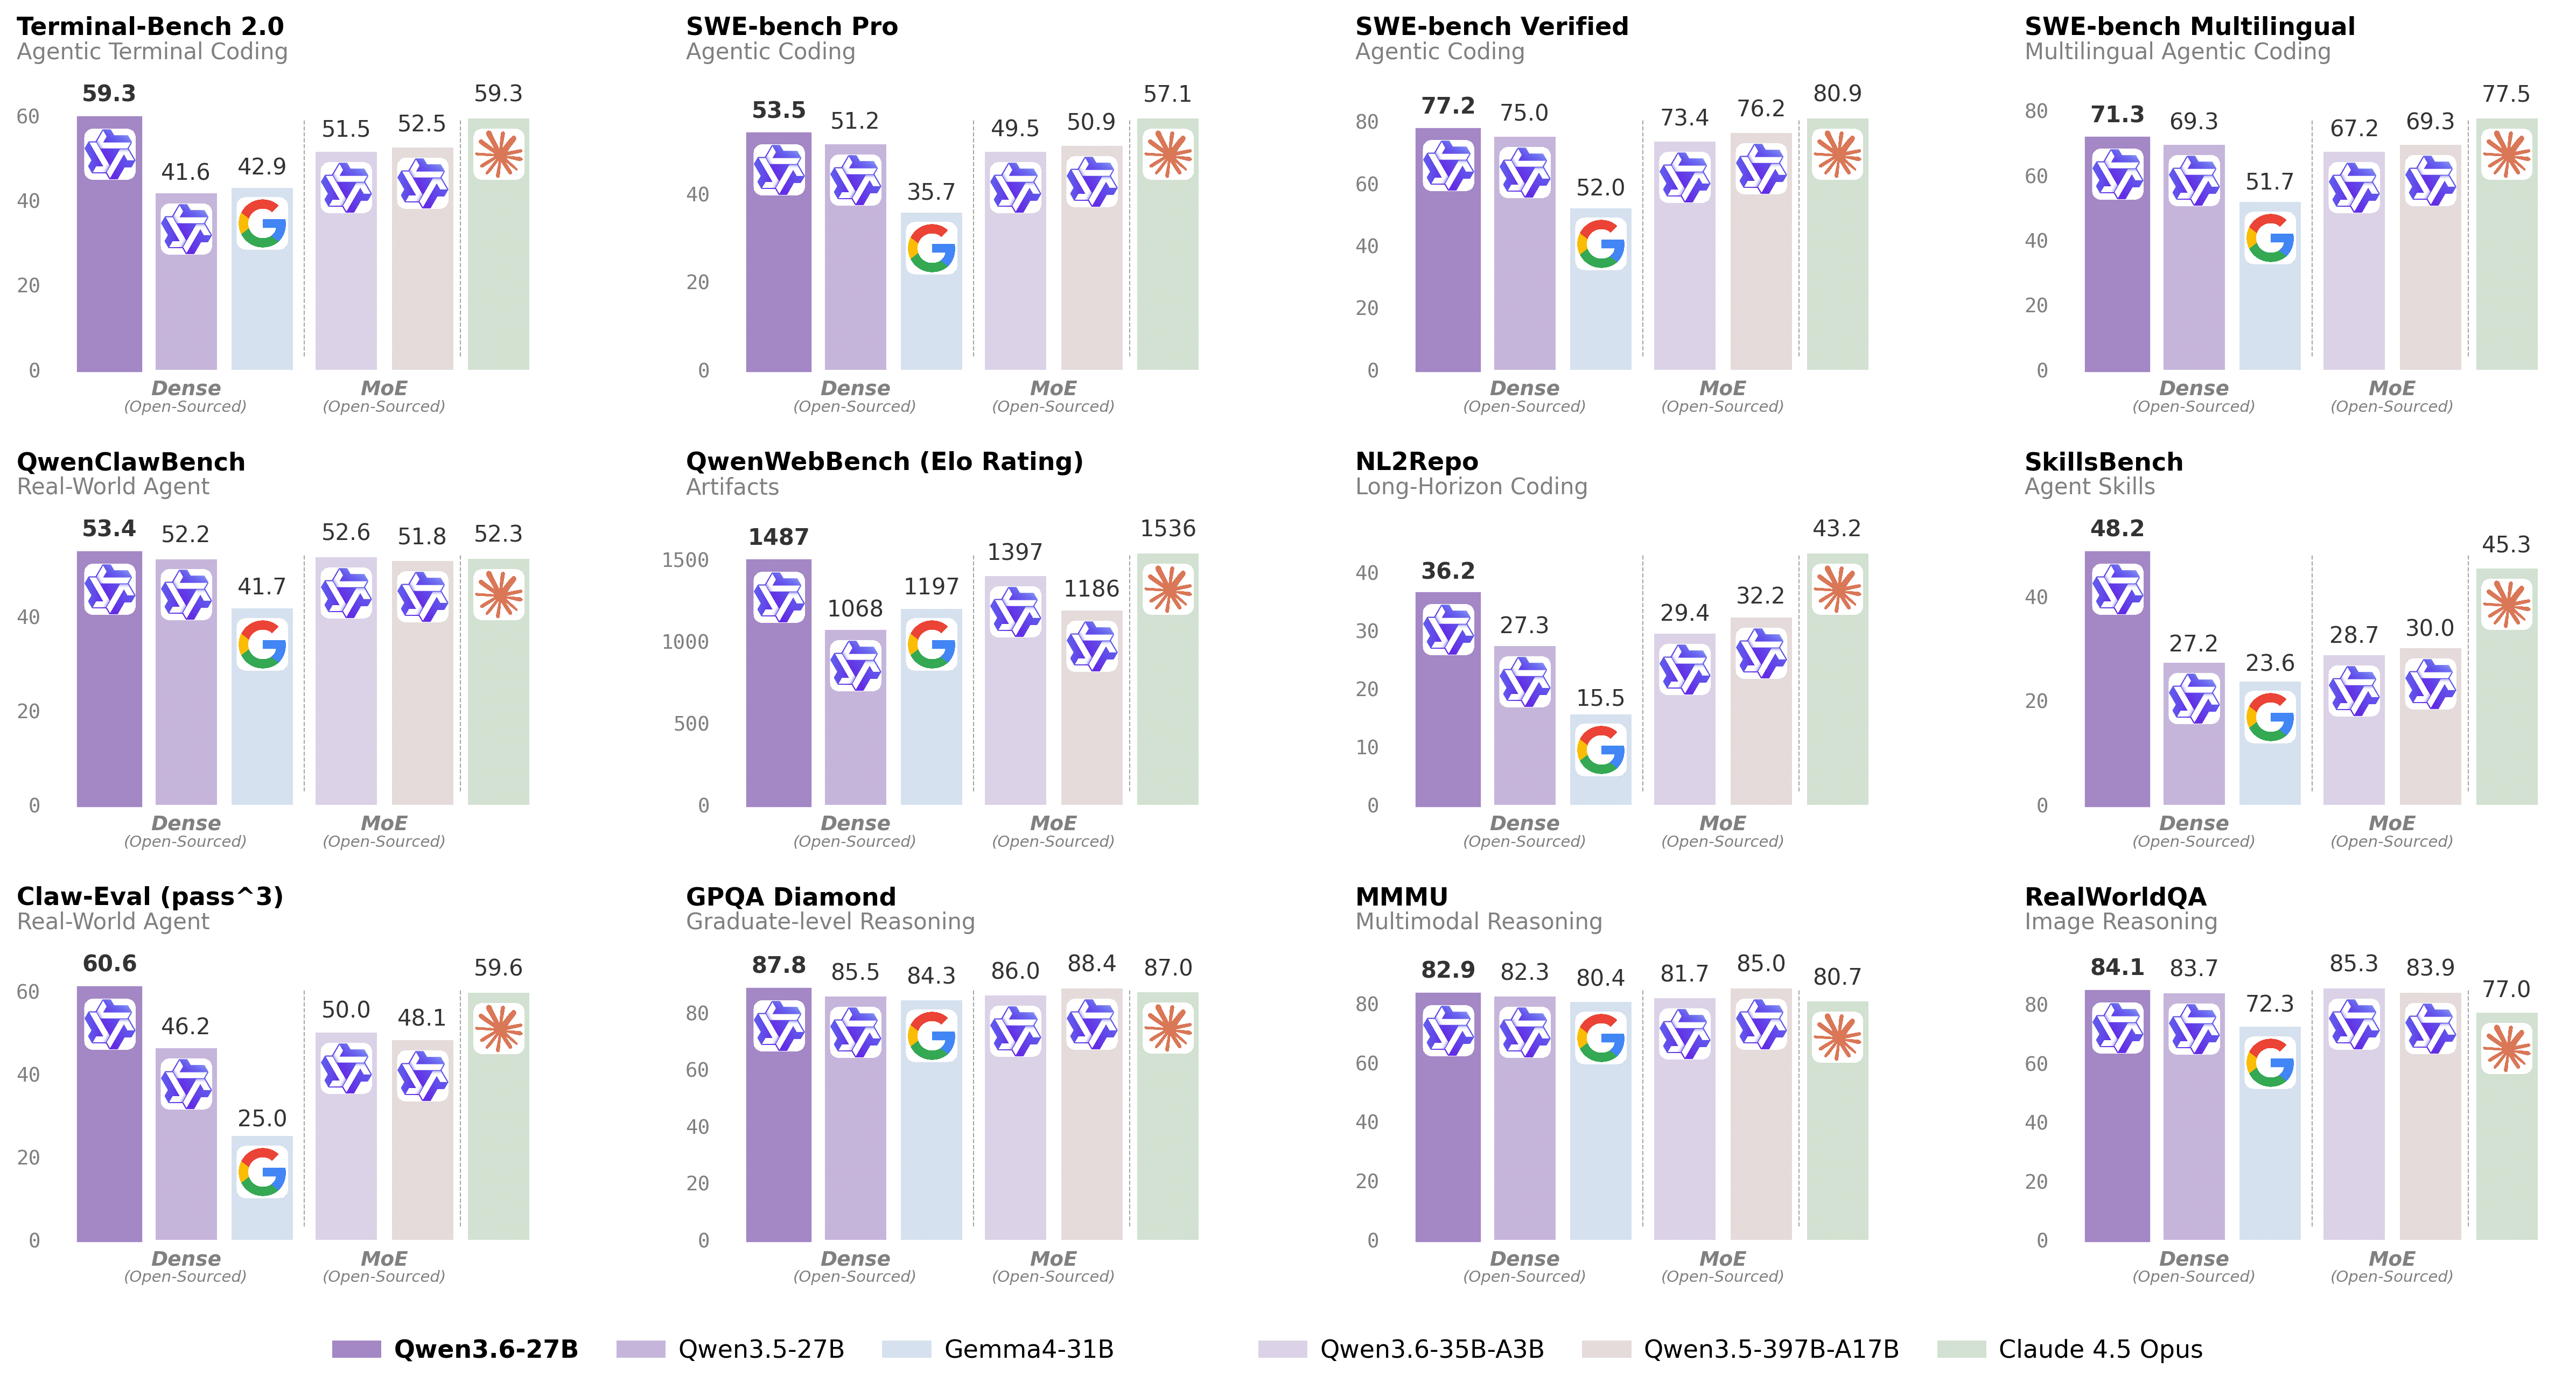


What is this?
 Qwen3.8 is the latest open large language model release from Alibaba's Qwen team, part of the Qwen3.5 series that also includes Qwen3.5 and Qwen3.6, aimed at coding, professional work, research, and long-horizon agentic tasks.
Is this a ready-to-use chatbot app, or just model weights I load myself?This repo is documentation around open model weights, not a packaged app. You download the weights (e.g. Qwen/Qwen3.8-27B) and run them yourself through a framework, or use Alibaba's hosted tools like Qwen Studio, Qwen API, or Qwen Code.
This repo is documentation around open model weights, not a packaged app. You download the weights (e.g. Qwen/Qwen3.8-27B) and run them yourself through a framework, or use Alibaba's hosted tools like Qwen Studio, Qwen API, or Qwen Code.How do I start using Qwen3.8?Pull the weights from Hugging Face Hub or ModelScope and serve them locally with Hugging Face Transformers (transformers serve), vLLM, or SGLang to get an OpenAI-compatible API endpoint; alternatively, use the hosted Qwen Studio or Qwen API without running anything yourself.
Pull the weights from Hugging Face Hub or ModelScope and serve them locally with Hugging Face Transformers (transformers serve), vLLM, or SGLang to get an OpenAI-compatible API endpoint; alternatively, use the hosted Qwen Studio or Qwen API without running anything yourself.Which inference tools can actually run Qwen3.8?The model is supported by SGLang, vLLM, and TokenSpeed for server deployment, llama.cpp for lightweight local inference, and mlx-lm/mlx-vlm on Apple Silicon; fine-tuning is supported via Unsloth, Swift, and Llama-Factory.
The model is supported by SGLang, vLLM, and TokenSpeed for server deployment, llama.cpp for lightweight local inference, and mlx-lm/mlx-vlm on Apple Silicon; fine-tuning is supported via Unsloth, Swift, and Llama-Factory.Does it run on Apple Silicon Macs, or do I need an Nvidia GPU?Apple Silicon Macs are supported via mlx-lm (text-only) and mlx-vlm (vision + text); for other hardware you'd use GGUF quantized builds with llama.cpp or full-precision weights with vLLM/SGLang, though the README doesn't specify minimum GPU requirements.
Apple Silicon Macs are supported via mlx-lm (text-only) and mlx-vlm (vision + text); for other hardware you'd use GGUF quantized builds with llama.cpp or full-precision weights with vLLM/SGLang, though the README doesn't specify minimum GPU requirements.Is the Apache-2.0 license on this repo the license for the actual model weights too?No — the Apache-2.0 license covers the repository itself, but the model weights ship with their own license file hosted alongside the weights on Hugging Face Hub or ModelScope, which you need to check separately.
No — the Apache-2.0 license covers the repository itself, but the model weights ship with their own license file hosted alongside the weights on Hugging Face Hub or ModelScope, which you need to check separately.What sizes does Qwen3.8 come in?Released sizes include Qwen3.8-27B and the much larger Qwen3.8-2.4T-A95B mixture-of-experts model, both published on Hugging Face Hub and ModelScope.
Released sizes include Qwen3.8-27B and the much larger Qwen3.8-2.4T-A95B mixture-of-experts model, both published on Hugging Face Hub and ModelScope.How is Qwen3.8 different from Qwen3.6 and Qwen3.5?Qwen3.8 is the first open release to reach Qwen-Max-class capability, built on the Qwen3.5 architecture with stronger agentic execution; Qwen3.6 focused on agentic coding stability and thinking preservation; Qwen3.5 introduced the unified vision-language MoE foundation with hybrid attention.
Qwen3.8 is the first open release to reach Qwen-Max-class capability, built on the Qwen3.5 architecture with stronger agentic execution; Qwen3.6 focused on agentic coding stability and thinking preservation; Qwen3.5 introduced the unified vision-language MoE foundation with hybrid attention.Can I fine-tune Qwen3.8 myself?Yes, the team recommends using Unsloth, Swift, or Llama-Factory to fine-tune the models with methods like SFT, DPO, or GRPO.
Yes, the team recommends using Unsloth, Swift, or Llama-Factory to fine-tune the models with methods like SFT, DPO, or GRPO.Does Qwen3.8 understand images, or just text?The underlying Qwen3.5 architecture was trained with early fusion on trillions of multimodal tokens, giving it vision-language understanding alongside text, with vision-capable builds available through mlx-vlm and llama.cpp GGUF releases.
The underlying Qwen3.5 architecture was trained with early fusion on trillions of multimodal tokens, giving it vision-language understanding alongside text, with vision-capable builds available through mlx-vlm and llama.cpp GGUF releases.What are similar projects?Qwen3.8-Flash-Next, NeoHorse, Hy-MT2, DeepSeek-V3, halo, unsloth, Qwen3, Hy4-preview
Qwen3.8-Flash-Next, NeoHorse, Hy-MT2, DeepSeek-V3, halo, unsloth, Qwen3, Hy4-previewWhich topics is it in?alibaba, sglang, open-weights, mlx, mixture-of-experts, moe, gguf, pretrained-models, transformers, vllm, quantization, fine-tuning
alibaba, sglang, open-weights, mlx, mixture-of-experts, moe, gguf, pretrained-models, transformers, vllm, quantization, fine-tuning