Topics / #retrieval
Retrieval projects on GitHub
Techniques and engines for retrieving relevant documents and context, often for RAG systems.
As of , the most-starred Retrieval projects on GitHub are llama_index (52.5K stars), PageIndex (39.2K stars) and qmd (30.5K stars). GitHub.Locker tracks 12 Retrieval repositories with 162K stars combined. The fastest-growing on October 16 was agent-memory, with +165 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +165
agent-memory
tigerless-labs/agent-memory · ★ 4.1Kagent-memory is a long-term memory runtime for AI agents — it stores memories as plain Markdown files (the source of truth) with a local SQLite/FTS5 index for fast ranked retrieval, so agents like Claude Code and Codex CLI keep what they learned across sessions.
PageIndex
VectifyAI/PageIndex · ★ 39.2KPageIndex is a vectorless, reasoning-based RAG (Retrieval-Augmented Generation) engine. Instead of a vector database and chunking, it builds a hierarchical tree index that mirrors a document's structure and lets an LLM reason its way through that tree to find relevant sections, the way a human expert flips to the right part of a report.
 +31
qmd
tobi/qmd · ★ 30.5KQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
 +21
llama_index
run-llama/llama_index · ★ 52.5KLlamaIndex is an open-source Python framework for building agentic applications that augment LLMs with your own private data, letting you ingest, index, and query documents with LLM-powered pipelines.
The all-time top
12 projects · by stars
- 52.5K#1 · run-llama/llama_index
llama_index
LlamaIndex is an open-source Python framework for building agentic applications that augment LLMs with your own private data, letting you ingest, index, and query documents with LLM-powered pipelines.
- 39.2K
#2 · VectifyAI/PageIndex
PageIndex
PageIndex is a vectorless, reasoning-based RAG (Retrieval-Augmented Generation) engine. Instead of a vector database and chunking, it builds a hierarchical tree index that mirrors a document's structure and lets an LLM reason its way through that tree to find relevant sections, the way a human expert flips to the right part of a report.
- 30.5K#3 · tobi/qmd
qmd
QMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 4
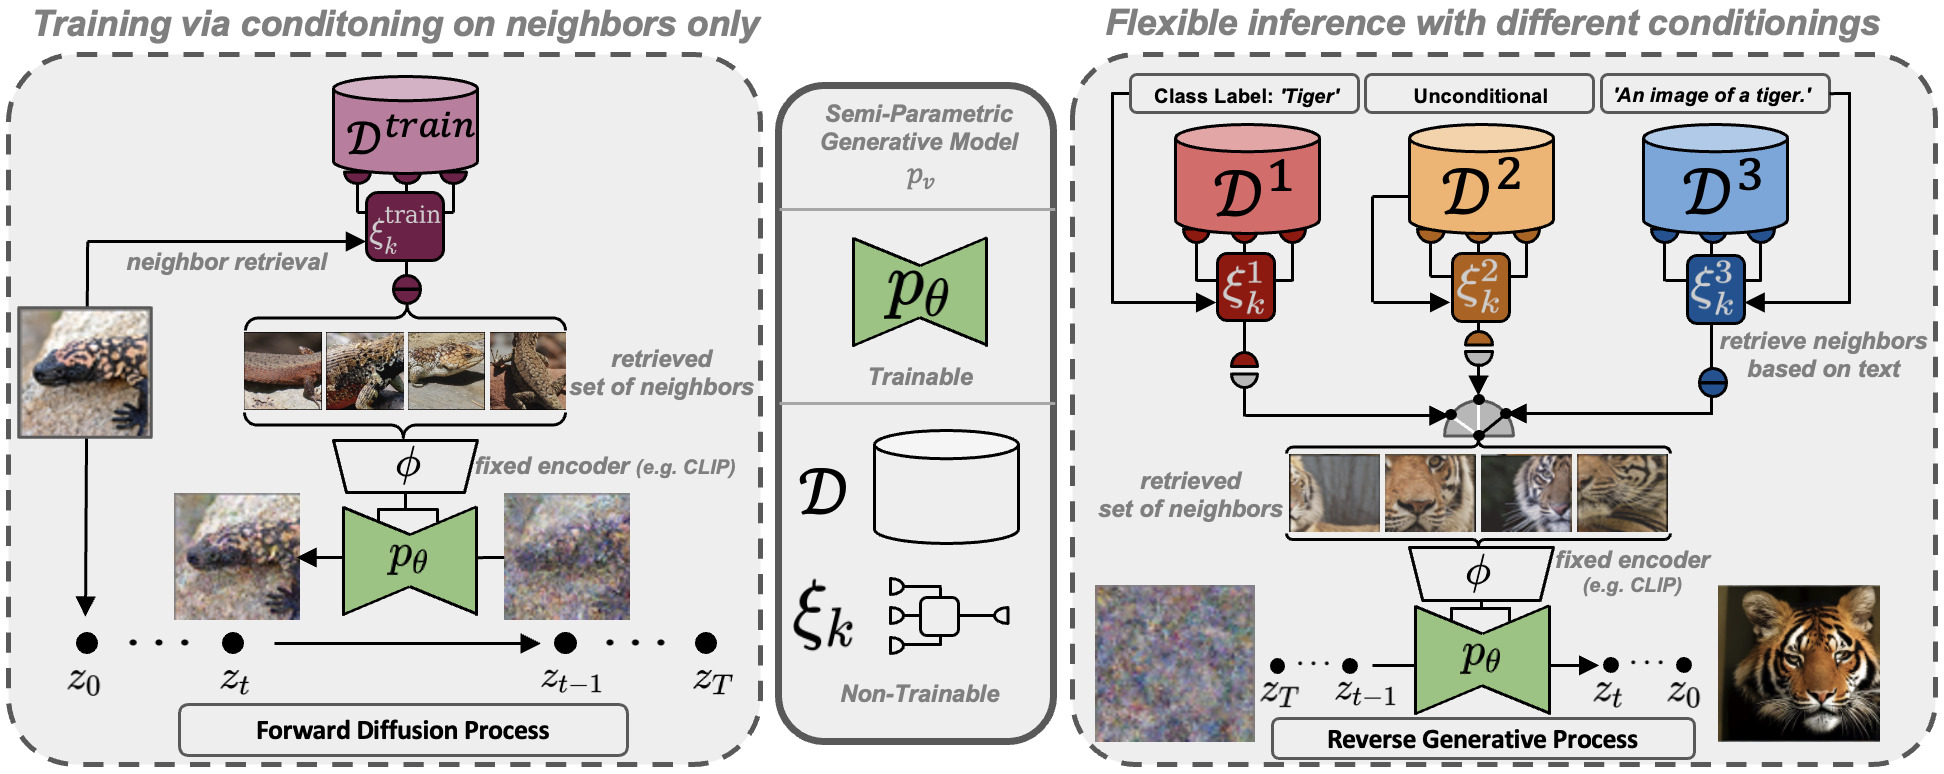
latent-diffusion
14.2KCompVis/latent-diffusion · Jupyter NotebookThis is the official research codebase for the paper 'High-Resolution Image Synthesis with Latent Diffusion Models' by CompVis, which introduced Latent Diffusion Models (LDMs) - diffusion models trained in a compressed latent space instead of raw pixel space for efficient, high-resolution image synthesis.
- 5
semble
6.2KMinishLab/semble · PythonSemble is a code search library built for coding agents. It returns the exact relevant code snippets for a query instead of making the agent grep and read full files, using about 99% fewer tokens than grep+read.
- 6
OpenKB
4.8KVectifyAI/OpenKB · PythonOpenKB is an open-source CLI system that compiles raw documents into a structured, interlinked wiki-style knowledge base using LLMs, so knowledge accumulates over time instead of being re-derived on every query.
- 7
agent-memory
4.1Ktigerless-labs/agent-memory · Pythonagent-memory is a long-term memory runtime for AI agents — it stores memories as plain Markdown files (the source of truth) with a local SQLite/FTS5 index for fast ranked retrieval, so agents like Claude Code and Codex CLI keep what they learned across sessions.
- 8
SimpleMem
3.8Kaiming-lab/SimpleMem · PythonSimpleMem is a lifelong memory stack for LLM agents that stores, compresses, and retrieves long-term memories across text, image, audio, and video, so agents keep context without reprocessing redundant history.
- 9
heartlib
3.8KHeartMuLa/heartlib · PythonHeartMuLa is a family of open-source music foundation models for generating music from lyrics and tags, shipped together with codec, transcription and audio-text retrieval companion models.
- 10
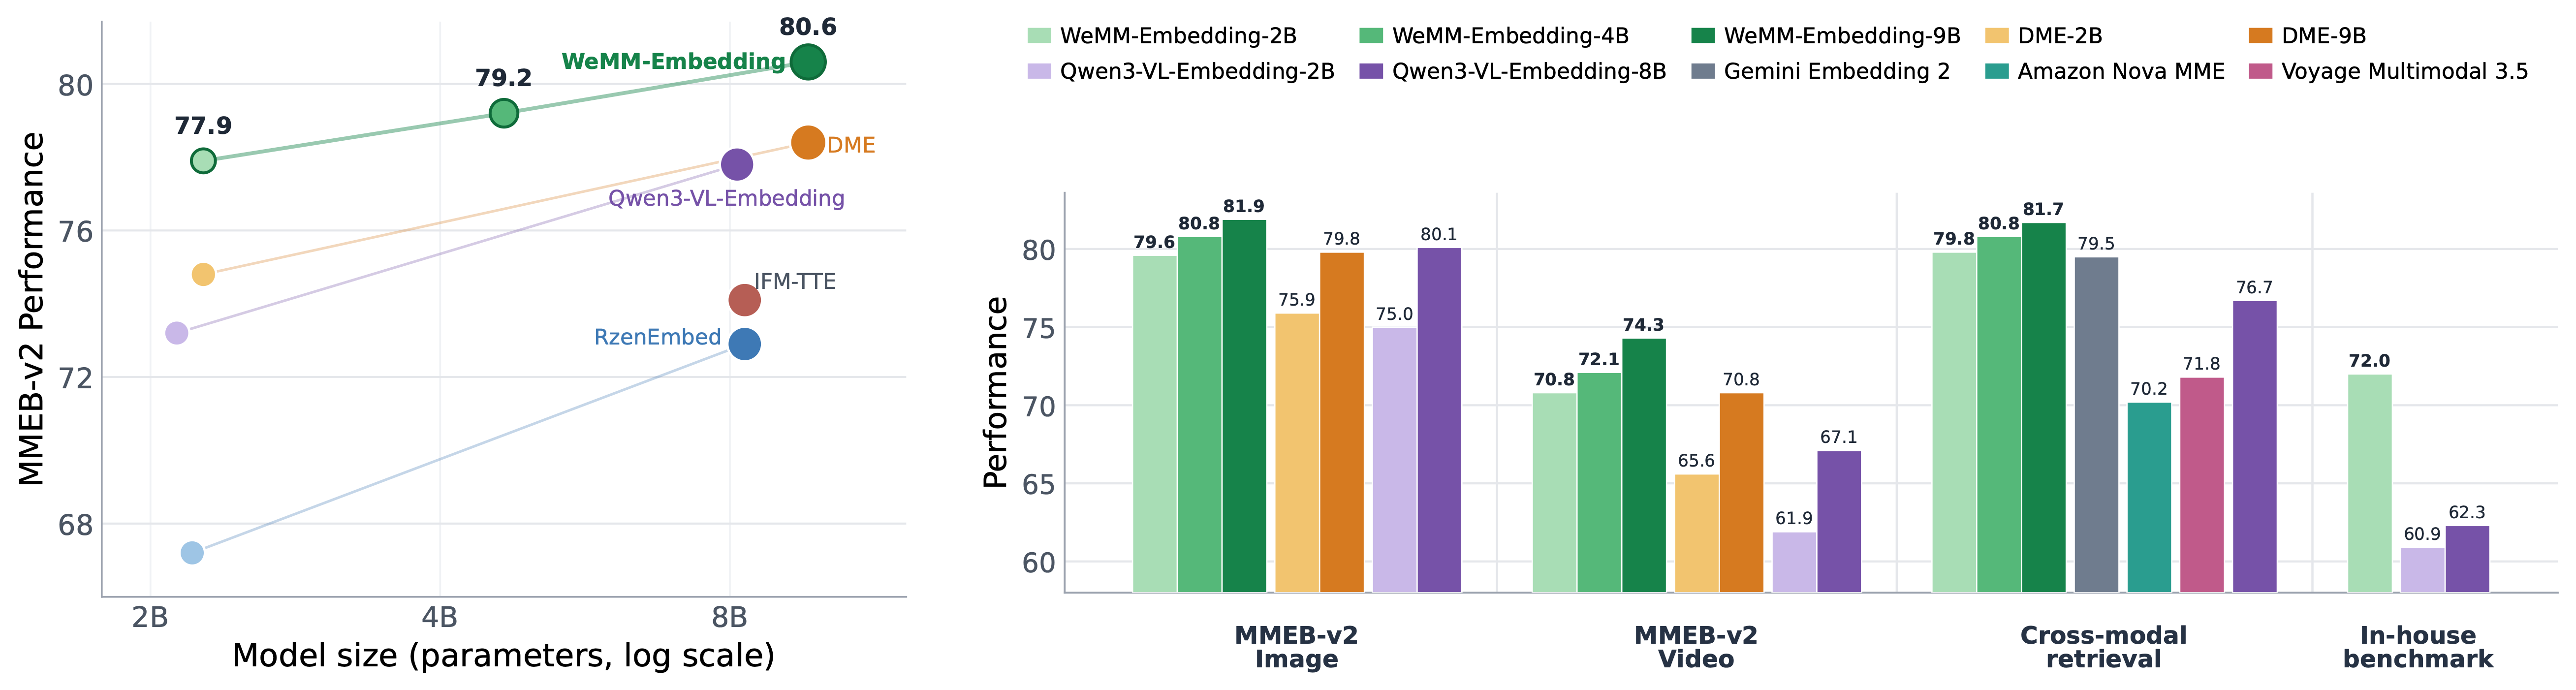
WeMM-Embedding
1.8KTencent/WeMM-Embedding · PythonWeMM-Embedding is a family of multimodal embedding models (2B, 4B, 9B) built by the WeChat Vision Team at Tencent that produce unified embeddings for text, images, videos, visual documents, and interleaved multimodal inputs for search and retrieval tasks.
- 11

fastembed-rs
1Kanush008/fastembed-rs · RustA Rust library that generates vector embeddings and reranks results entirely locally — no external API calls. It covers dense and sparse text embeddings, image embeddings, multimodal models, and rerankers.
- 12
memoket-kite
144memoket/memoket-kite · PythonKITE is an open-source, vector-free long-term memory engine for AI agents: it turns conversations into structured, topic-indexed facts and answers questions with inspectable retrieval plans instead of embedding similarity search, topping the LoCoMo and LongMemEval benchmarks.
Related topics
Often tagged together