Topics / #voice-cloning
Voice-cloning projects on GitHub
Replicating human voices from short audio samples
As of , the most-starred Voice-cloning projects on GitHub are VoiceStudio (71.2K stars), GPT-SoVITS (63K stars) and Real-Time-Voice-Cloning (60.2K stars). GitHub.Locker tracks 55 Voice-cloning repositories with 880.4K stars combined. The fastest-growing on October 16 was VoiceStudio, with +2.1K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +2.1K
VoiceStudio
debpalash/VoiceStudio · ★ 71.2KVoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
 +837
Concat
jub0t/Concat · ★ 7.8KConcat is a free, open-source, cross-platform video editor built as a CapCut alternative, with no watermark, no account and no subscription.
 +58
GPT-SoVITS
RVC-Boss/GPT-SoVITS · ★ 63KGPT-SoVITS is a few-shot voice cloning and text-to-speech WebUI: feed it a short voice sample and it can clone that voice to read out any text, including in languages the speaker never recorded.
 +49
Easel
ZJU-REAL/Easel · ★ 3.7KEasel is an open-source content workbench built around an AI agent that discovers trends, plans topics, creates text/image/audio/video content, publishes it to Chinese social platforms, and learns from performance data to improve future content.
The all-time top
55 projects · by stars
- 71.2K#1 · debpalash/VoiceStudio
VoiceStudio
VoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
- 63K#2 · RVC-Boss/GPT-SoVITS
GPT-SoVITS
GPT-SoVITS is a few-shot voice cloning and text-to-speech WebUI: feed it a short voice sample and it can clone that voice to read out any text, including in languages the speaker never recorded.
- 60.2K
 #3 · CorentinJ/Real-Time-Voice-Cloning
Real-Time-Voice-Cloning
It's an implementation of SV2TTS, a deep learning framework that lets you clone a voice from just a few seconds of audio and then generate arbitrary speech in that voice in real time.
- 4

TTS
46.1Kcoqui-ai/TTS · PythonCoqui TTS is a deep learning toolkit for Text-to-Speech, shipping 1100+ pretrained models plus tools for training, fine-tuning, and curating datasets for new voices.
- 5
VoxCPM
39.4KOpenBMB/VoxCPM · PythonVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
- 6
bark
39.3Ksuno-ai/bark · Jupyter NotebookBark is a transformer-based text-to-audio model from Suno that generates realistic, multilingual speech plus music, background noise, and sound effects from text prompts.
- 7
Retrieval-based-Voice-Conversion-WebUI
38.8KRVC-Project/Retrieval-based-Voice-Conversion-WebUI · PythonRVC WebUI is a web-based tool for training and running voice conversion (voice-changing) models, letting you clone a target voice's timbre using as little as about 10 minutes of audio.
- 8
OpenVoice
37.9Kmyshell-ai/OpenVoice · PythonOpenVoice is an audio foundation model for instant voice cloning, built by MIT and MyShell; it clones a reference speaker's tone color and generates speech in multiple languages and accents.
- 9
MockingBird
36.9Kbabysor/MockingBird · PythonMockingBird is a PyTorch voice-cloning toolbox: it learns a voice from a short audio clip and generates arbitrary Mandarin speech in real time. The repo is no longer actively updated — the author is building an optimized cloud-hosted version instead.
- 10
fish-speech
33.2Kfishaudio/fish-speech · PythonFish Speech (Fish Audio S2) is a state-of-the-art open-source text-to-speech system that generates natural, emotionally rich speech in 80+ languages, led by the flagship S2-Pro model that combines a Dual-AR architecture with reinforcement-learning alignment.
- 11
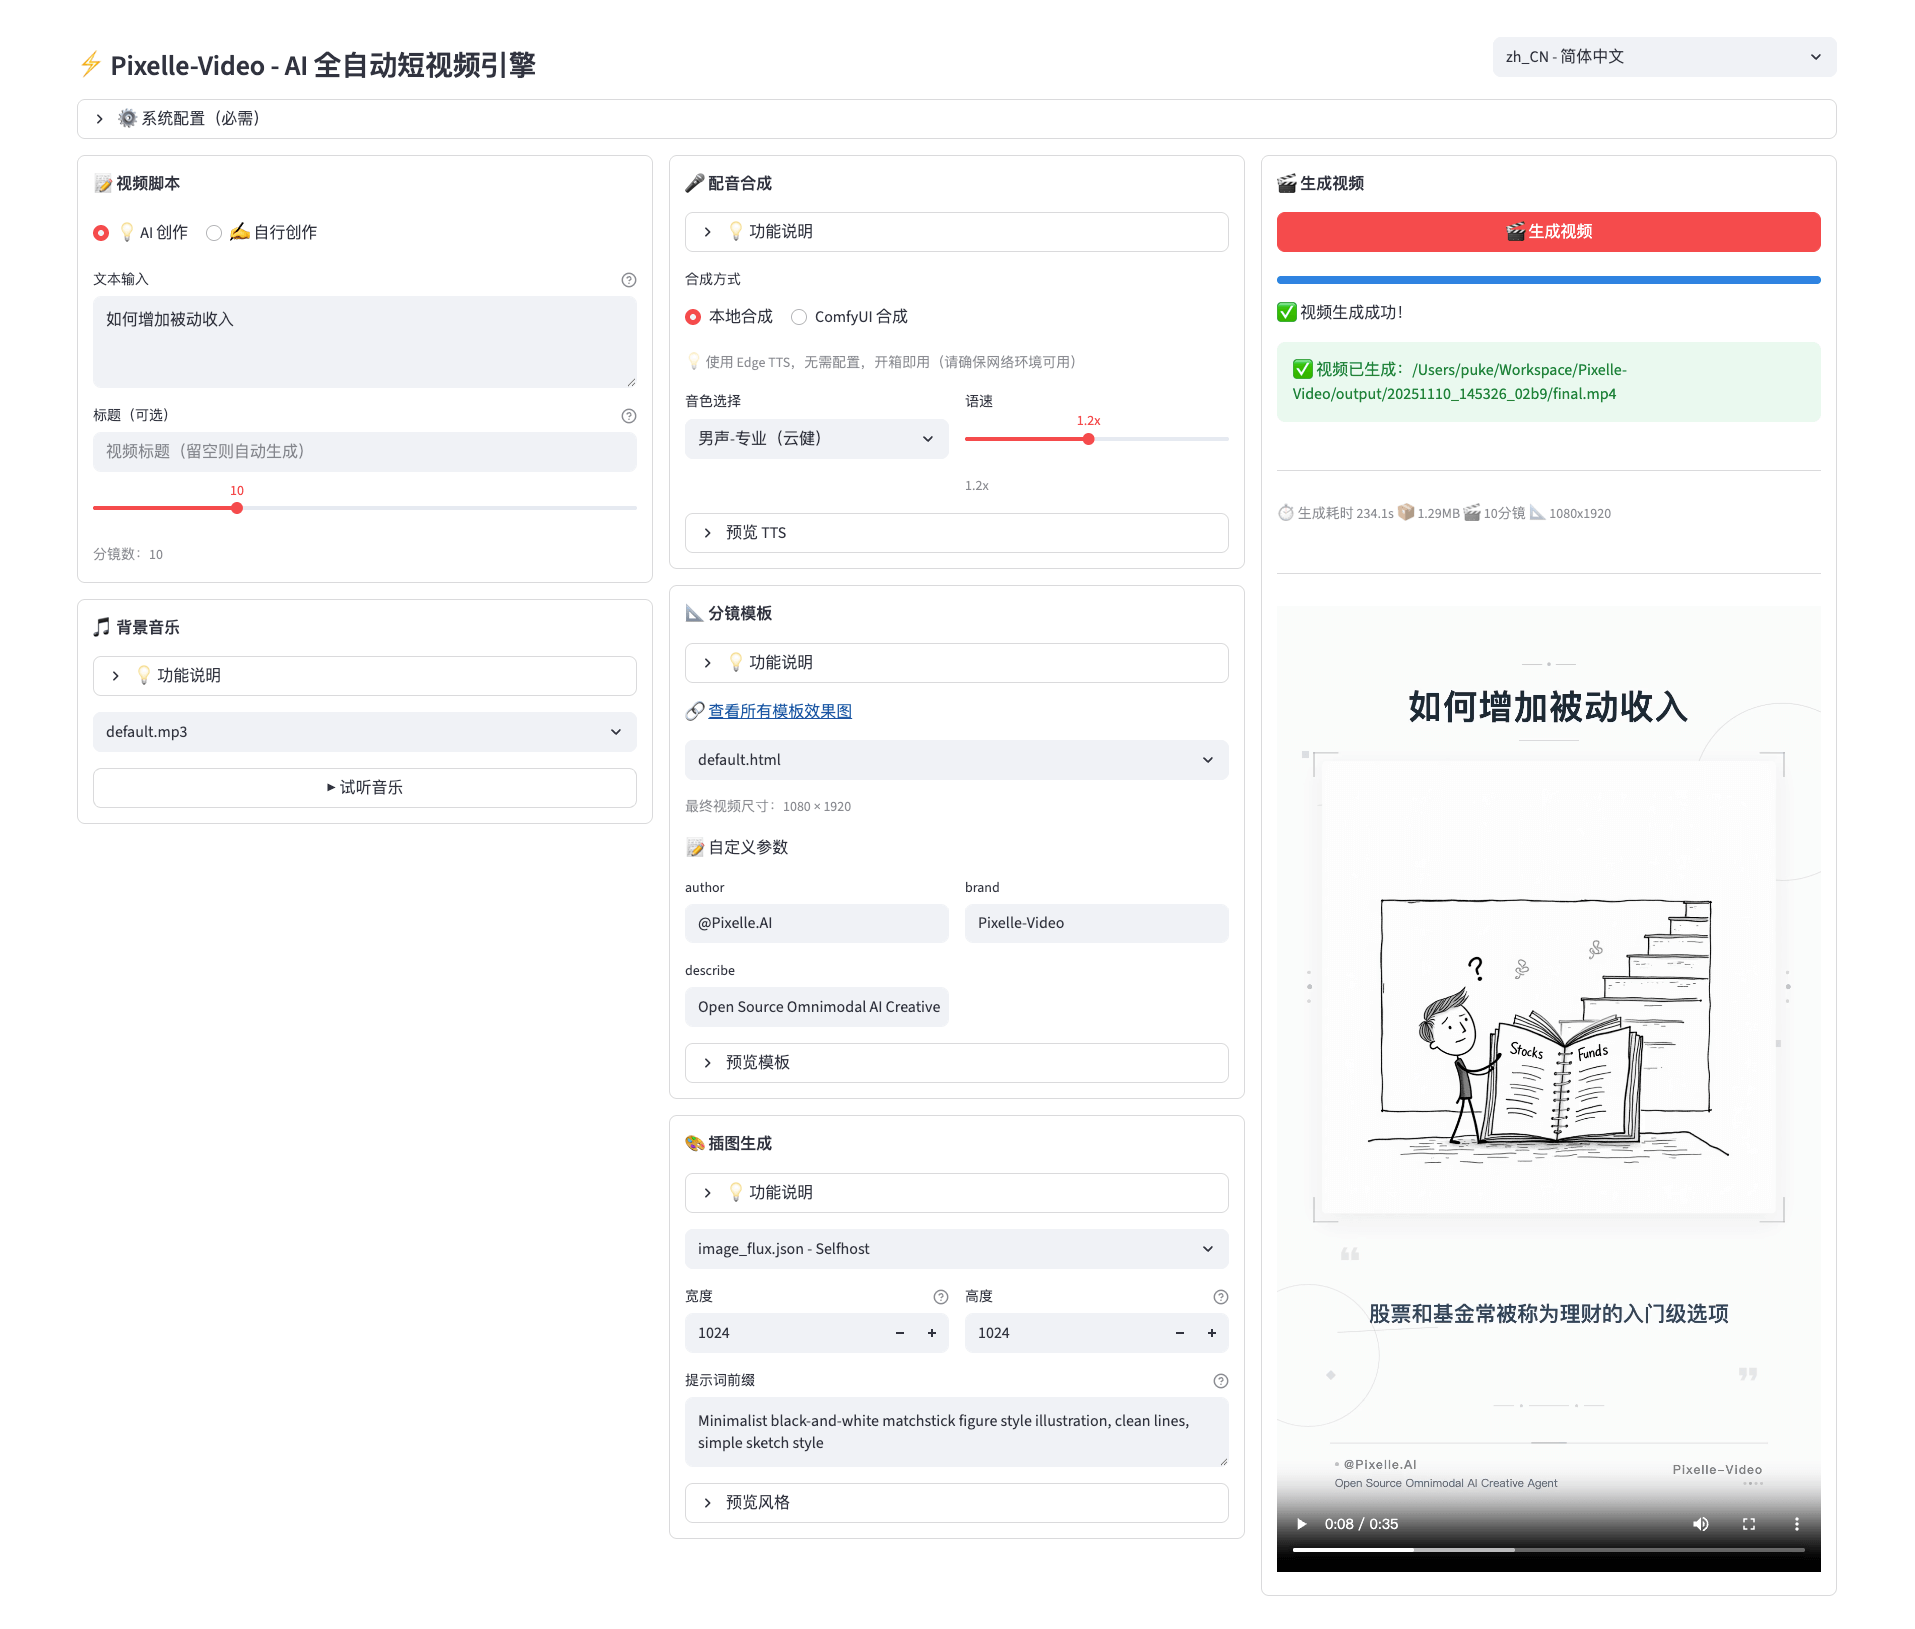
Pixelle-Video
29.1KATH-MaaS/Pixelle-Video · PythonPixelle-Video is an open-source AI short-video engine: give it one topic and it automatically writes the script, generates AI images or video clips, synthesizes the voiceover, adds background music and assembles a finished video — no editing experience needed.
- 12
chatterbox
27Kresemble-ai/chatterbox · PythonChatterbox is a family of state-of-the-art, open-source text-to-speech (TTS) models from Resemble AI, including multilingual and low-latency voice-agent variants.
- 13
CosyVoice
24KQwenAudio/CosyVoice · PythonCosyVoice is Alibaba's open-source, LLM-based text-to-speech system. It generates natural speech in 9 languages plus 18+ Chinese dialects, supports zero-shot voice cloning, and ships inference, training and deployment code.
- 14
ebook2audiobook
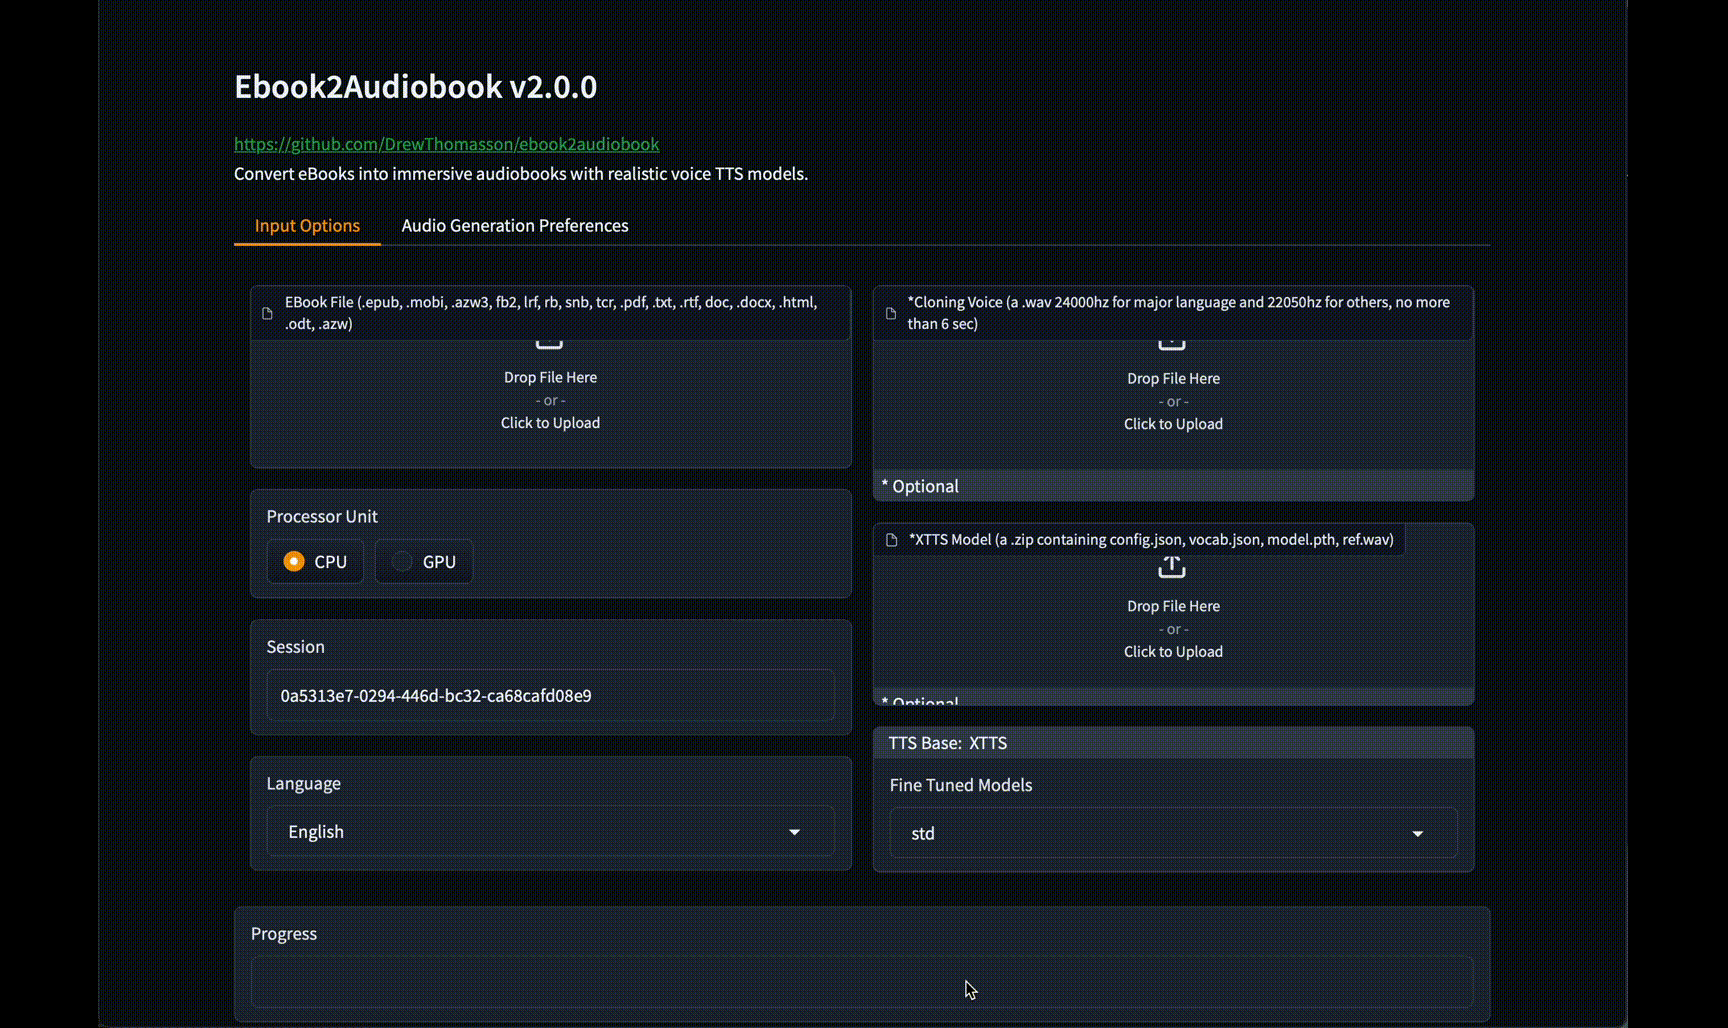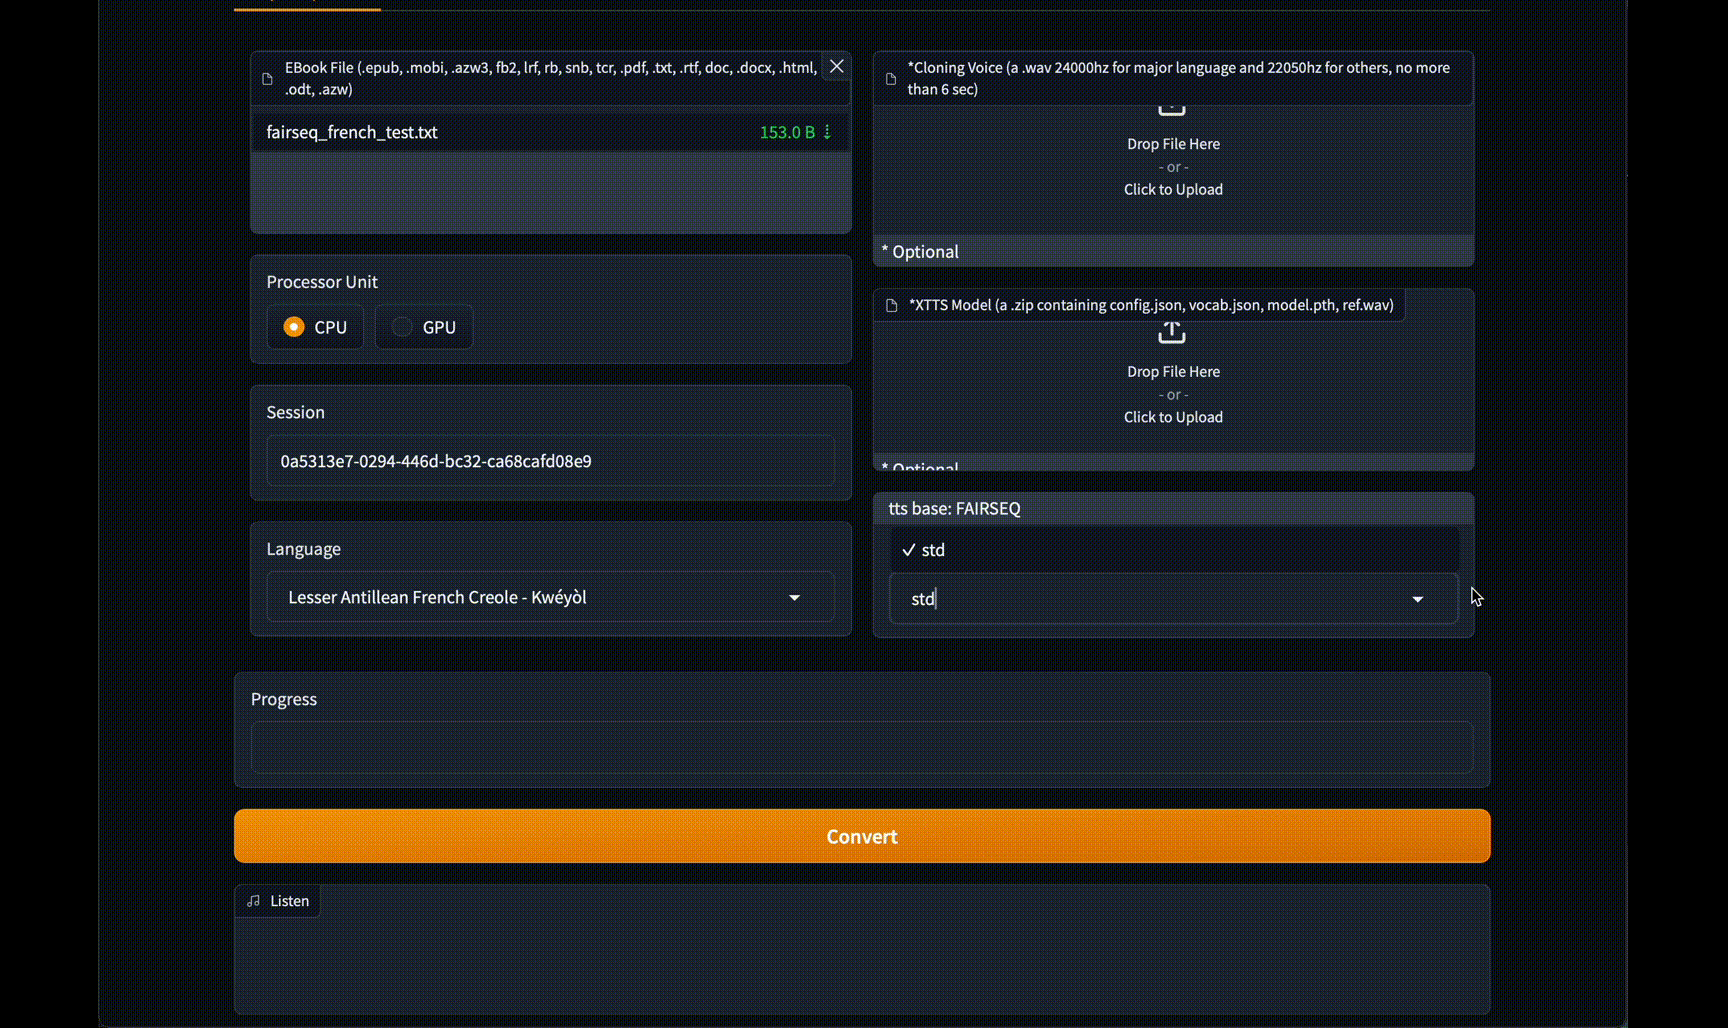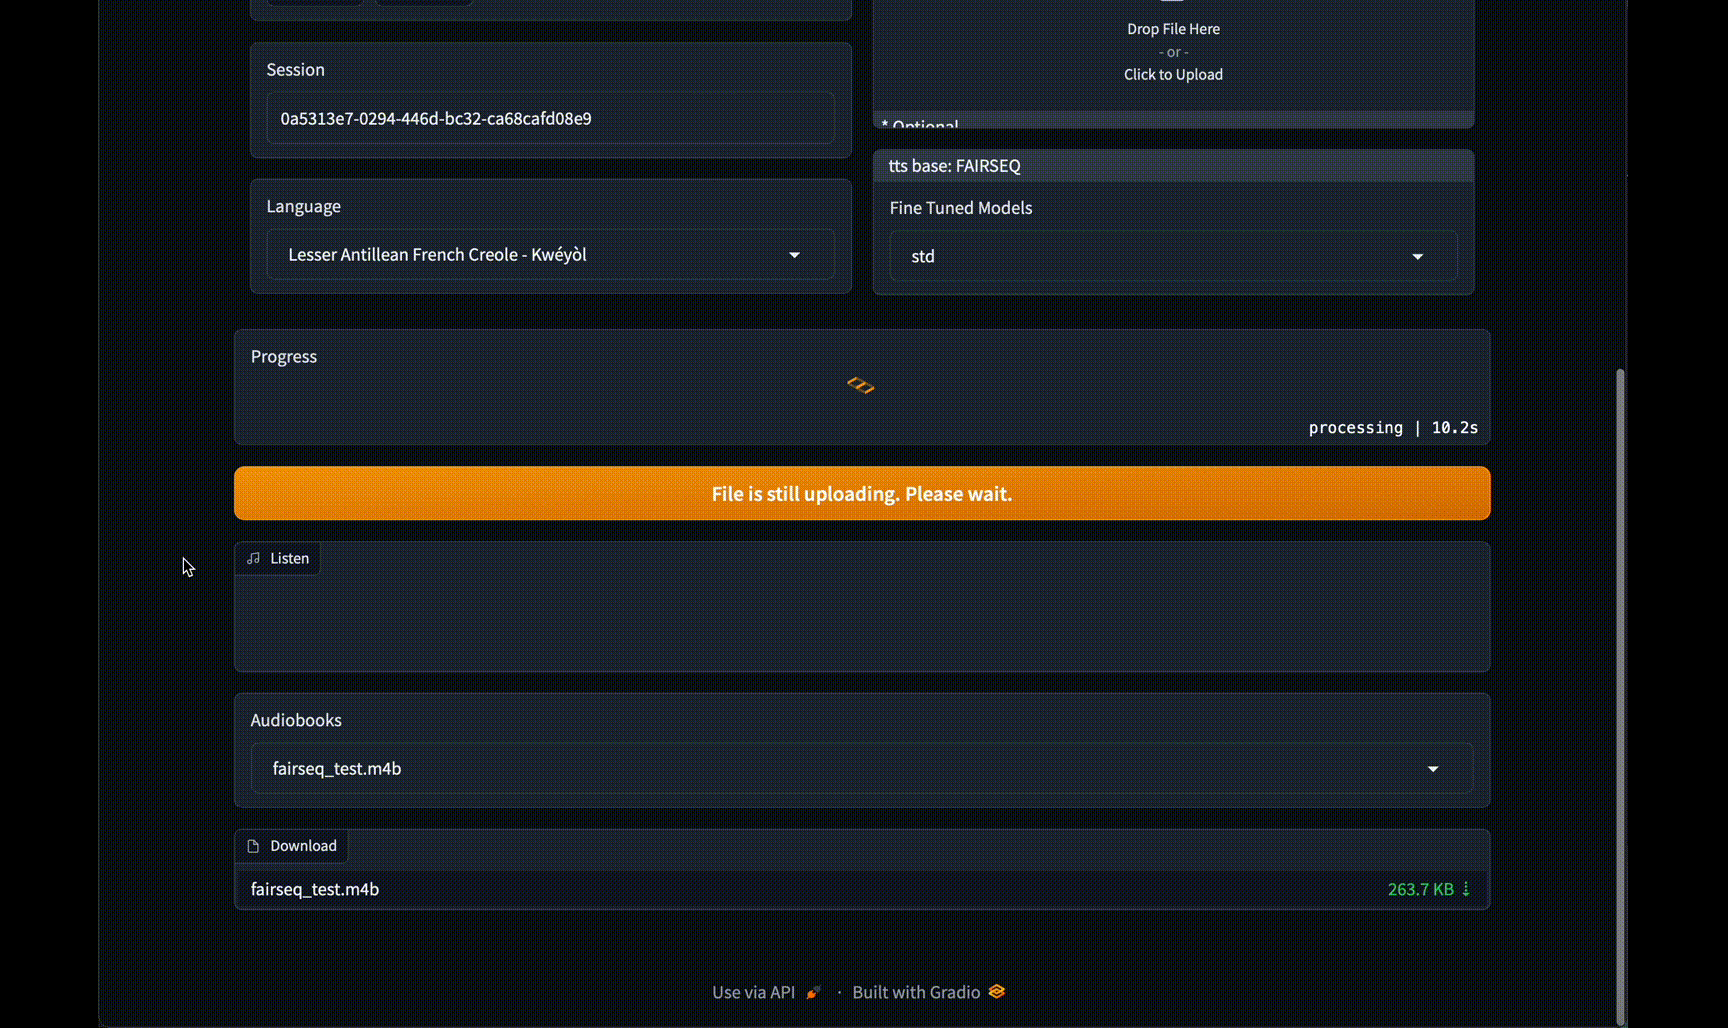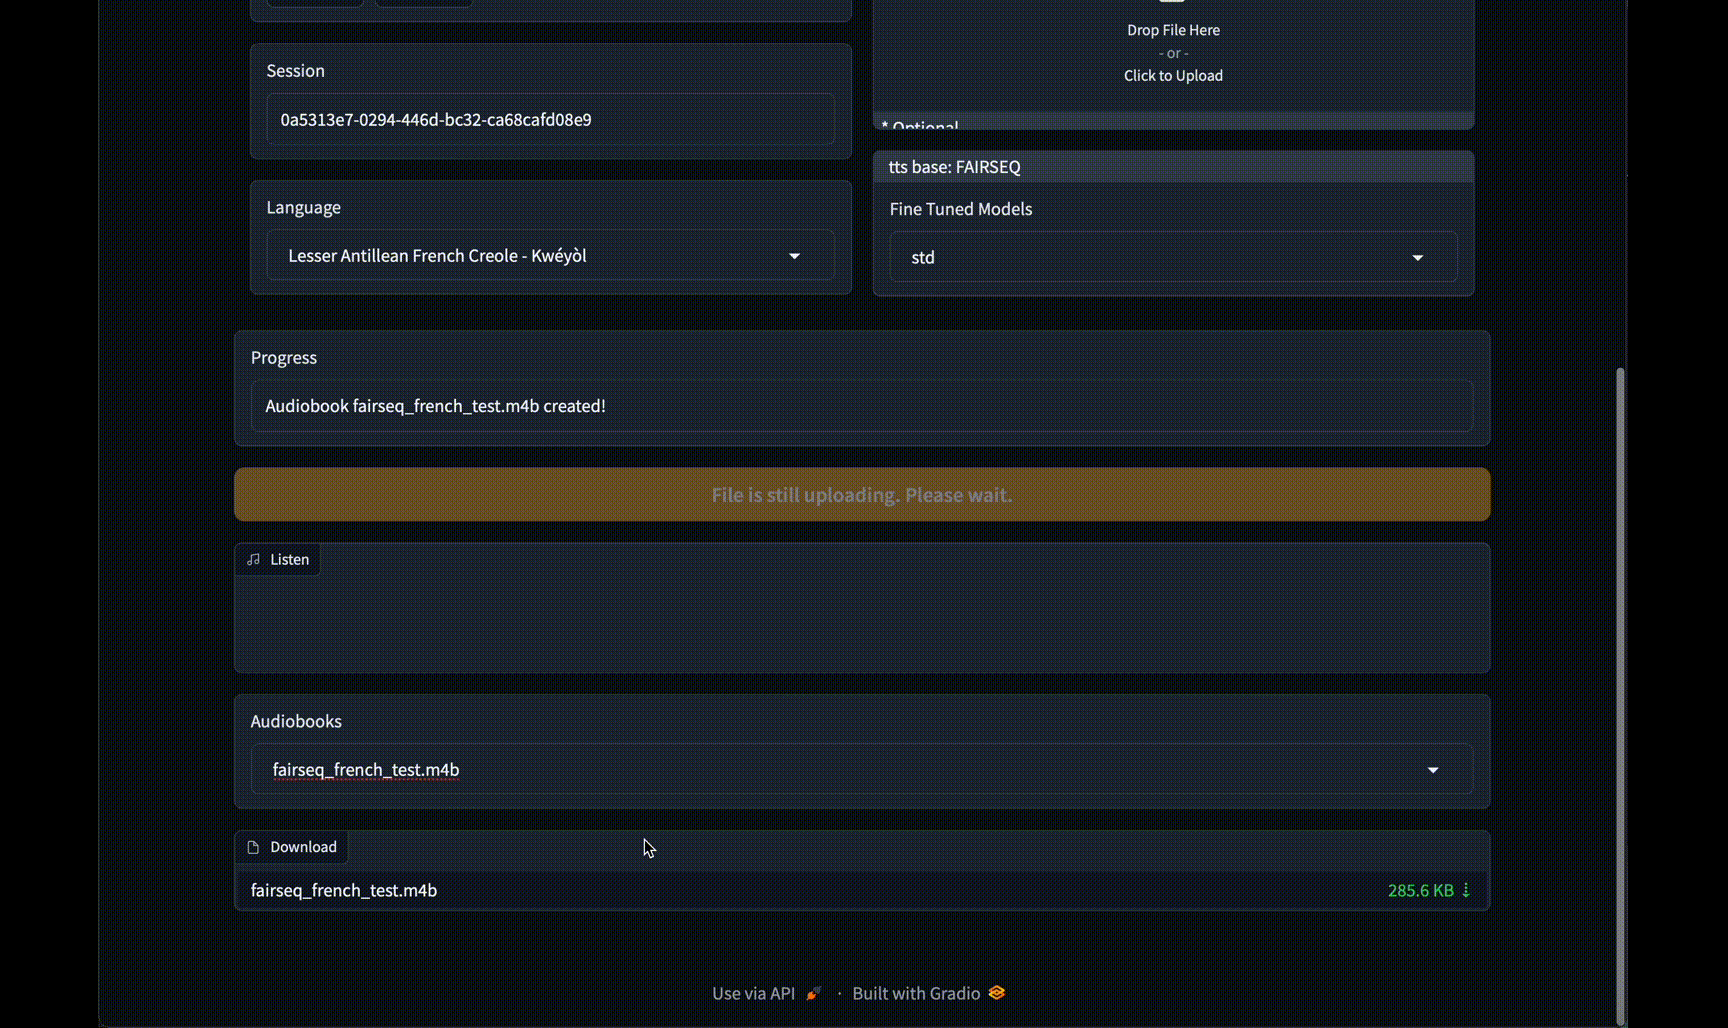
20.4KDrewThomasson/ebook2audiobook · PythonA converter that turns DRM-free e-books into audiobooks with chapters and metadata, using TTS engines with optional voice cloning, in 1158+ languages. It runs locally on modest hardware or in Docker.
- 15
pyvideotrans
19.4Kjianchang512/pyvideotrans · PythonAn open-source video translation and dubbing tool: it converts a video from one language to another through a one-click pipeline of speech recognition, subtitle translation, TTS dubbing, and video synthesis.
- 16

dia
19.4Knari-labs/dia · PythonDia is a 1.6B-parameter open-weights text-to-speech model from Nari Labs that generates ultra-realistic multi-speaker dialogue from a transcript in a single pass.
- 17
VideoLingo
18.8KHuanshere/VideoLingo · PythonVideoLingo is an all-in-one AI tool for video translation, localization, and dubbing. It generates Netflix-quality single-line subtitles and can add high-quality dubbing, fully automated in one click.
- 18

aimoneyhunter
18.3Kbleedline/aimoneyhunterThis is a curated Chinese-language collection of ideas, tutorials, and tools for making money with AI side hustles - covering AI video, images, text, audio, and live streaming projects.
- 19
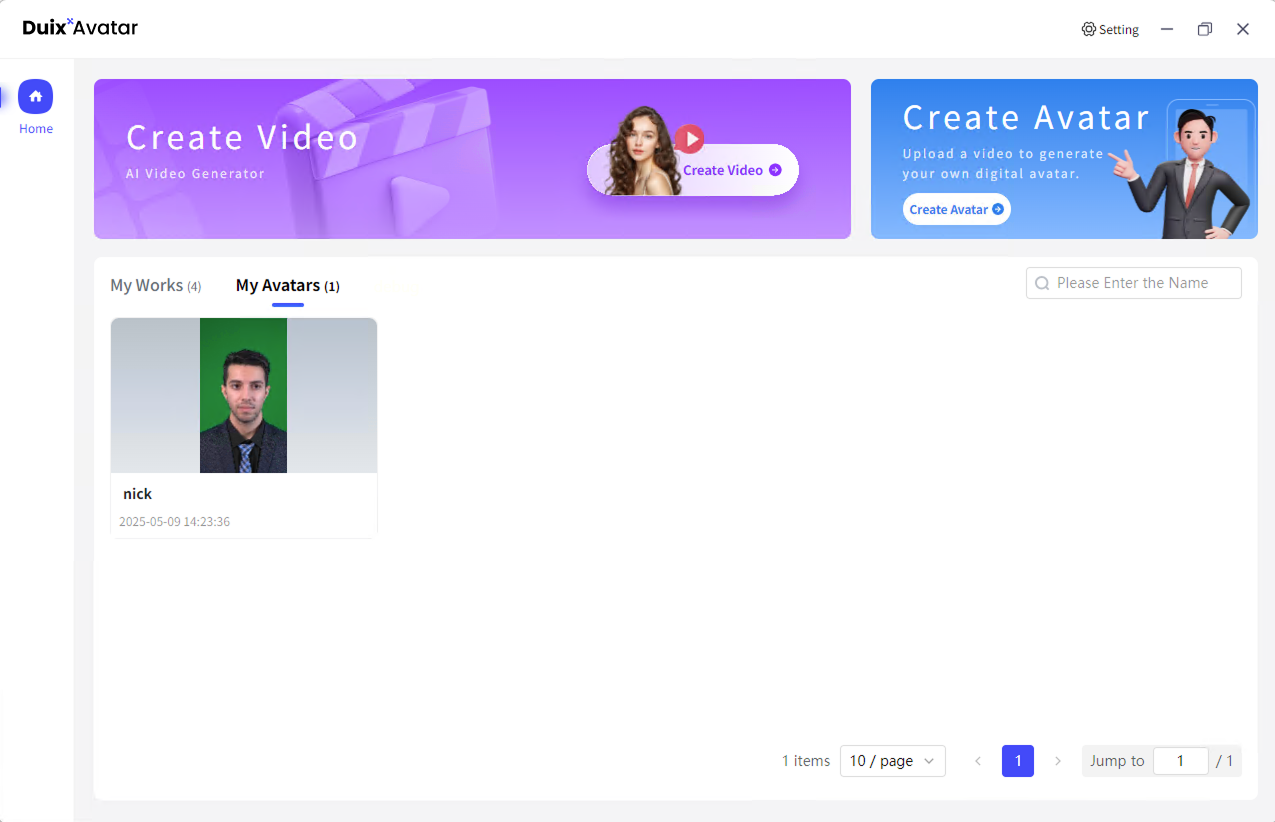
Duix-Avatar
15.9Kduixcom/Duix-Avatar · CDuix.Avatar is a free, open-source AI digital human toolkit that clones your face and voice to generate fully offline avatar videos driven by text or speech.
- 20

F5-TTS
15.4KSWivid/F5-TTS · PythonF5-TTS is a text-to-speech system that generates fluent, faithful speech using flow matching with a Diffusion Transformer (ConvNeXt V2 backbone), and it supports cloning a speaker's voice from a short reference clip.
- 21

sherpa-onnx
15.3Kk2-fsa/sherpa-onnx · C++sherpa-onnx is an offline toolkit for speech-to-text, text-to-speech, speaker diarization, speaker identification/verification, spoken language identification, audio tagging, VAD, speech enhancement, keyword spotting and source separation, built on next-gen Kaldi and ONNX Runtime, with no internet connection required.
- 22
OmniVoice
14.7Kk2-fsa/OmniVoice · PythonOmniVoice is a zero-shot text-to-speech model that supports over 600 languages, built on a diffusion language model-style architecture, with voice cloning and voice design capabilities.
- 23
Qwen3-TTS
13.8KQwenLM/Qwen3-TTS · PythonQwen3-TTS is an open-source text-to-speech model series from Alibaba's Qwen team that generates stable, expressive speech, supports voice design from text descriptions, and can clone voices from a short audio sample.
- 24
skills
13.7KMiniMax-AI/skills · C#MiniMax Skills is a collection of plug-in 'skill' packages that give AI coding agents (Claude Code, Cursor, Codex, OpenCode) structured, production-quality guidance for frontend, fullstack, Android, iOS, Flutter, React Native, shader work, and MiniMax-API-powered media generation (images, video, music, TTS, documents).
- 25
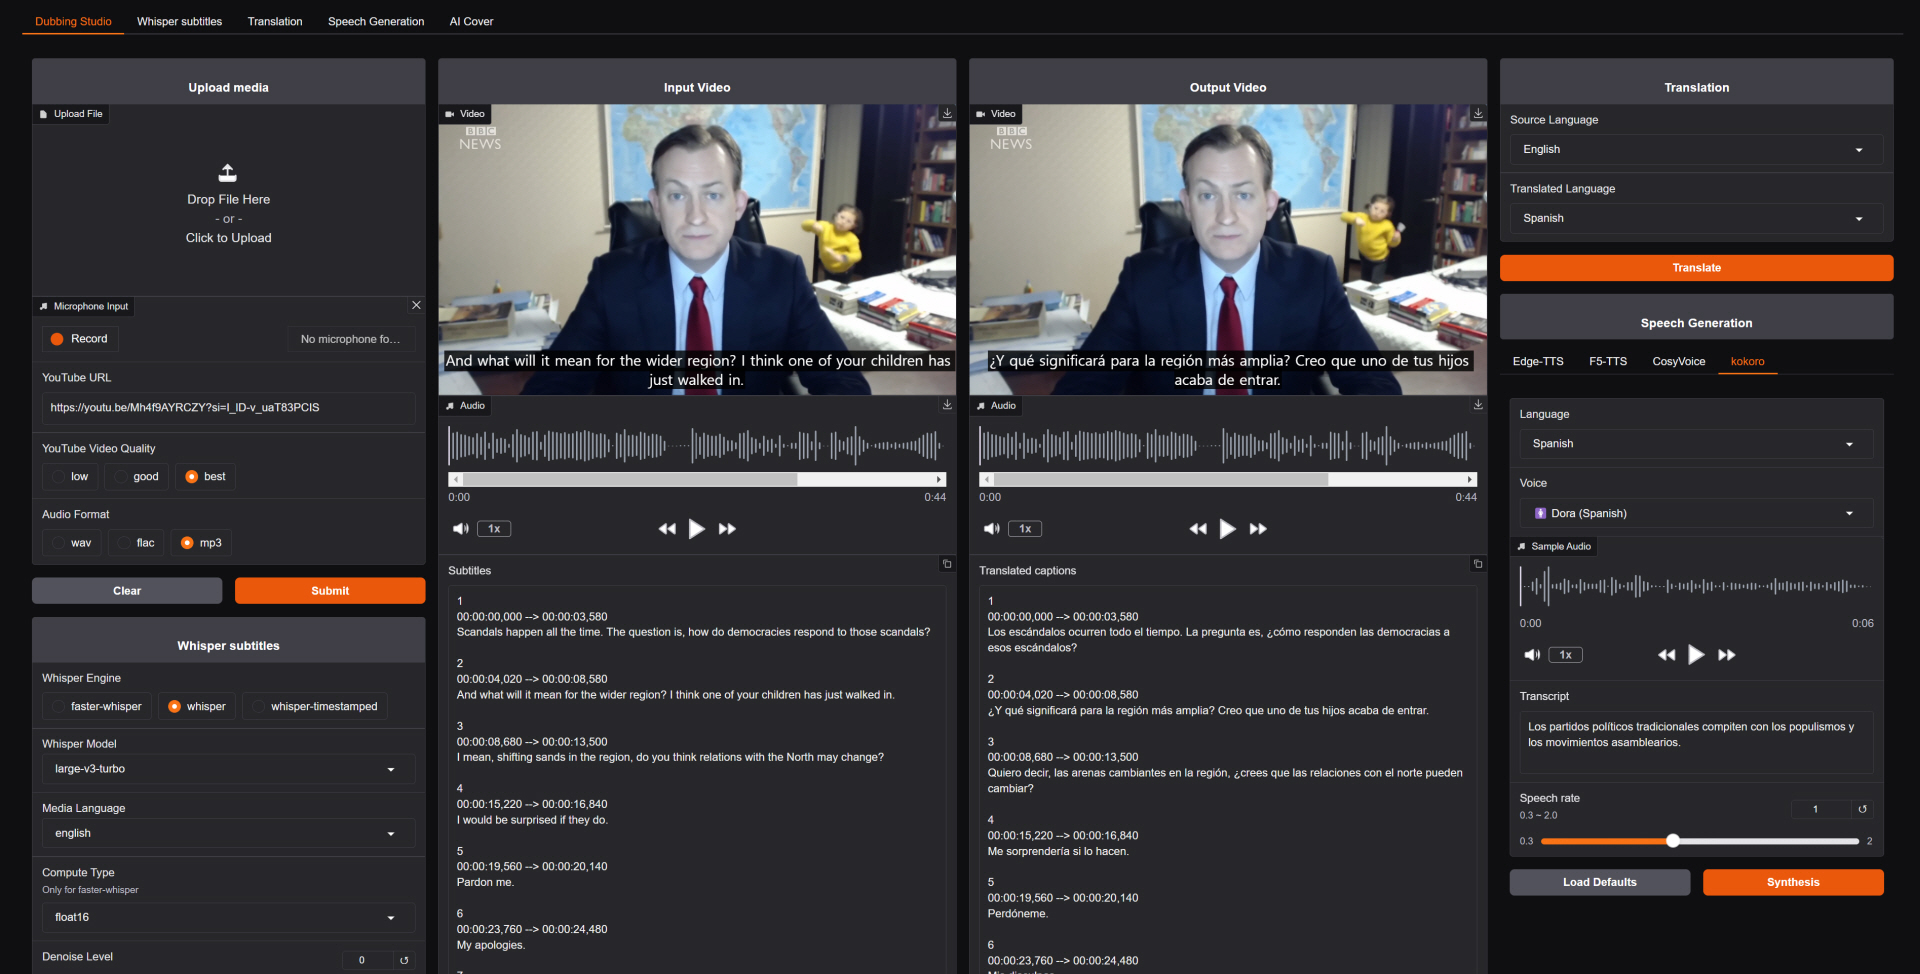
voice-pro
13Kabus-aikorea/voice-pro · PythonVoice-Pro is a free, open-source AI web app (built with Gradio) that combines speech recognition, zero-shot voice cloning, text-to-speech, YouTube downloading, vocal isolation, and multilingual translation into one tool for creators and researchers.
- 26
PaddleSpeech
12.7KPaddlePaddle/PaddleSpeech · PythonPaddleSpeech is an open-source speech and audio toolkit built on the PaddlePaddle platform, covering tasks like Automatic Speech Recognition (ASR), Text-to-Speech (TTS), Speaker Verification, Speech Translation, Keyword Spotting and Punctuation Restoration. It won the NAACL2022 Best Demo Award.
- 27
YuE
12.1Kmultimodal-art-projection/YuE · PythonYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
- 28
NarratoAI
11.4Klinyqh/NarratoAI · PythonNarratoAI is an all-in-one AI tool for film/show narration and automated video editing: it uses an LLM to write the narration script, then automatically edits the footage, generates voice-over, and adds subtitles.
- 29
personaplex
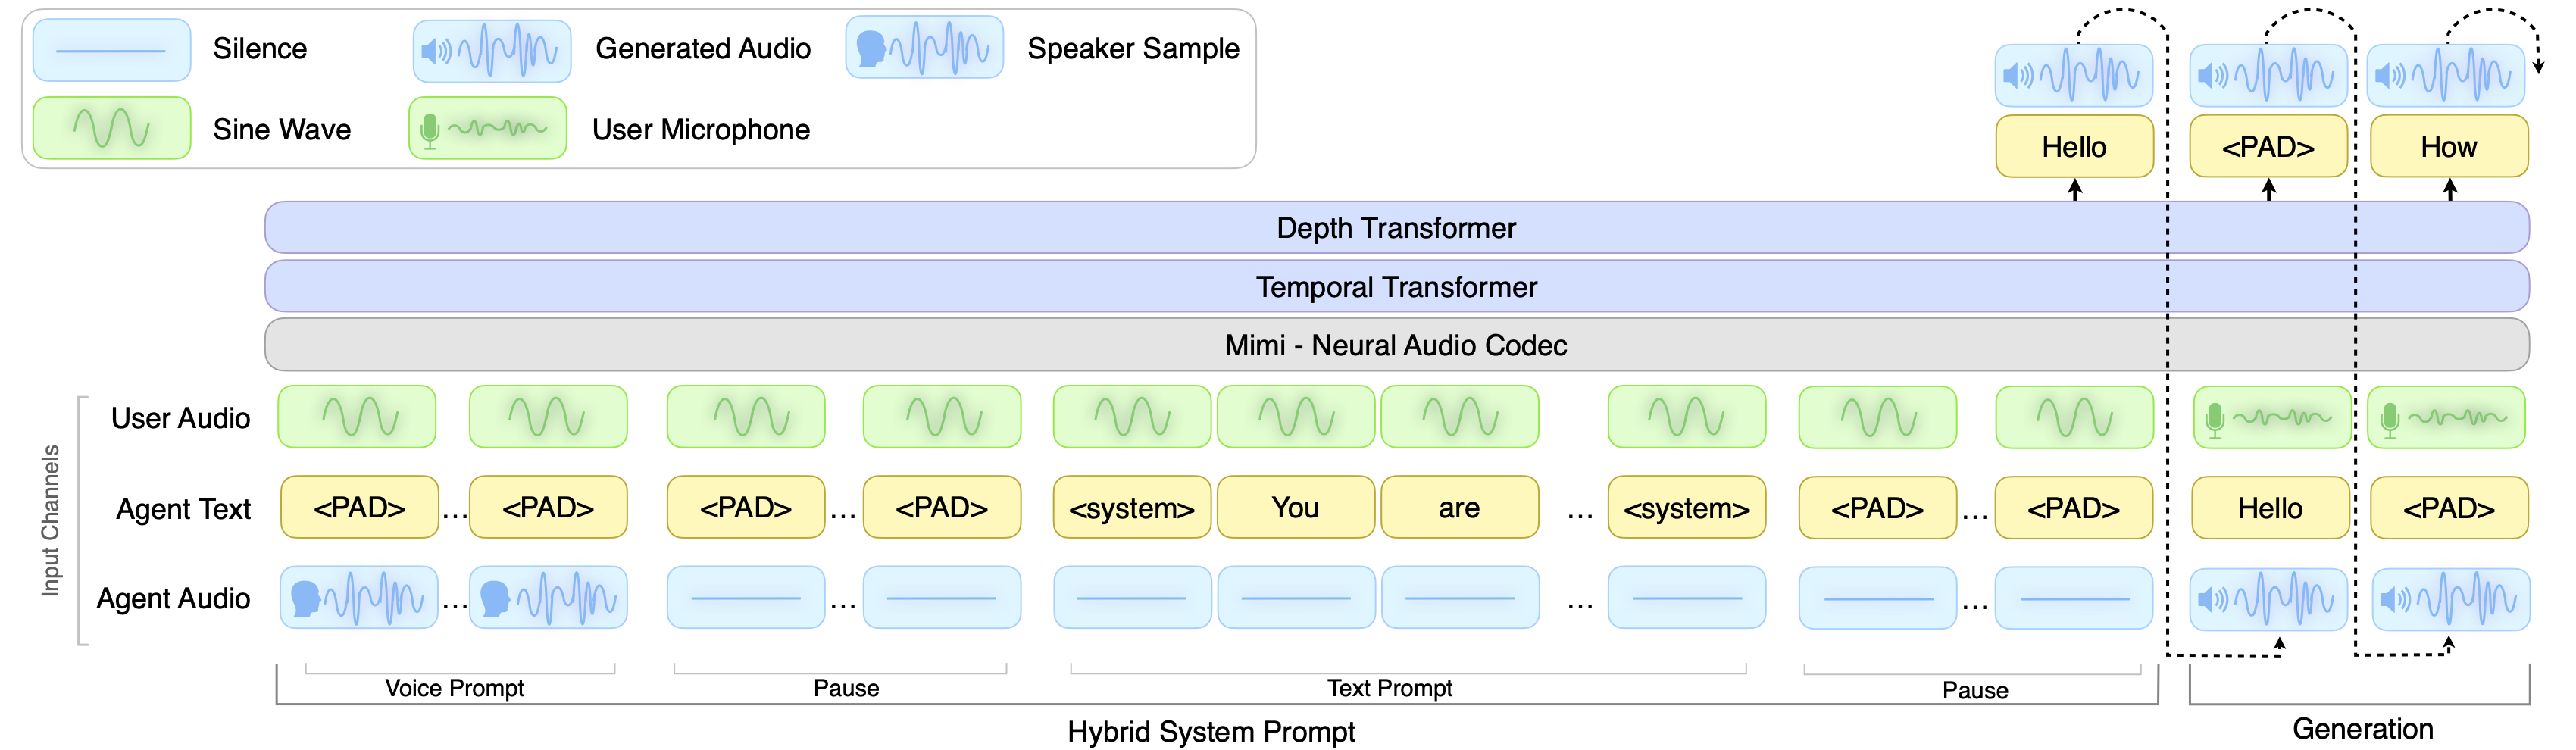
11.2KNVIDIA/personaplex · PythonPersonaPlex is a real-time, full-duplex speech-to-speech conversational AI model from NVIDIA. It lets you control the assistant's persona through text role prompts and condition its voice on an audio sample, producing natural low-latency spoken conversations.
- 30
Spark-TTS
11KSparkAudio/Spark-TTS · PythonSpark-TTS is a text-to-speech system that uses a large language model (built on Qwen2.5) to generate highly natural, accurate speech, including zero-shot voice cloning.
- 31

WanGP
10.6Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 32

pocket-tts
9.9Kkyutai-labs/pocket-tts · PythonPocket TTS is a lightweight text-to-speech engine from Kyutai that runs efficiently on CPU only, using a tiny 100M-parameter model with streaming audio output and voice cloning.
- 33
Concat
7.8Kjub0t/Concat · RustConcat is a free, open-source, cross-platform video editor built as a CapCut alternative, with no watermark, no account and no subscription.
- 34

neutts
6.3Kneuphonic/neutts · PythonNeuTTS is a collection of open-source, on-device text-to-speech language models that can clone a voice from just a few seconds of reference audio.
- 35

LuxTTS
5.5Kysharma3501/LuxTTS · PythonLuxTTS is a lightweight text-to-speech model built on the ZipVoice architecture, designed for high-quality voice cloning and fast speech generation.
- 36
MOSS-TTS-Nano
4.5KOpenMOSS/MOSS-TTS-Nano · PythonMOSS-TTS-Nano is an open-source, 100M-parameter multilingual text-to-speech model from MOSI.AI and OpenMOSS that supports voice cloning, 48kHz stereo output, and real-time generation directly on CPU.
- 37
MOSS-TTS
4.2KOpenMOSS/MOSS-TTS · PythonMOSS-TTS Family is an open-source speech and sound generation model family from OpenMOSS, covering long-form narration, multi-speaker dialogue, voice design, sound effects, and real-time streaming text-to-speech.
- 38
Rapid-MLX
4Kraullenchai/Rapid-MLX · PythonRapid-MLX is a local LLM inference server for Apple Silicon Macs, built on MLX, that exposes OpenAI- and Anthropic-compatible APIs and focuses on reliable tool calling for coding agents like Claude Code and Codex CLI.
- 39
Easel
3.7KZJU-REAL/Easel · PythonEasel is an open-source content workbench built around an AI agent that discovers trends, plans topics, creates text/image/audio/video content, publishes it to Chinese social platforms, and learns from performance data to improve future content.
- 40
narrator-ai-cli-skill
3KNarratorAI-Studio/narrator-ai-cli-skillThis is a machine-readable skill file (SKILL.md) that teaches AI agents like Claude Code, Codex, or OpenClaw how to use the narrator-ai-cli tool to automatically produce movie narration videos.
- 41
lanshu-create-ai-presenter-video
2.7Kcclank/lanshu-create-ai-presenter-video · HTMLThis is a Codex Skill that turns a topic or script plus an authorized photo of a person into a full AI presenter video: it writes the script, generates voiceover, creates the character, syncs lips, adds subtitles and keyword animations, edits, renders and runs quality checks.
- 42
FireRedAudio
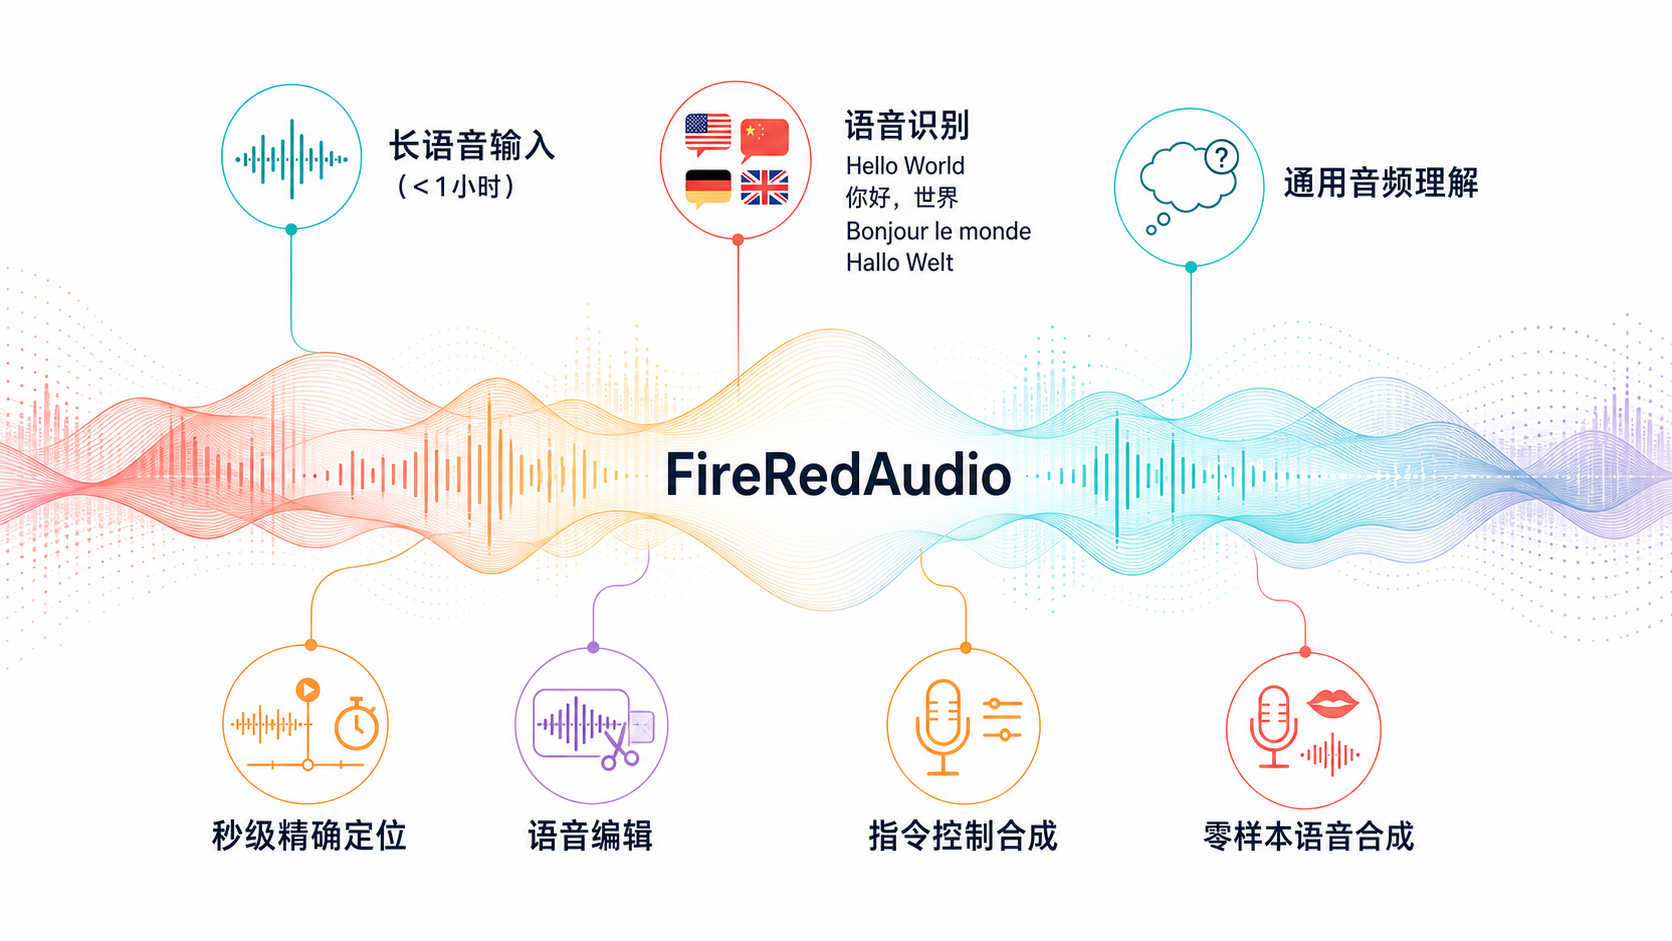
2KFireRedTeam/FireRedAudio · PythonFireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM that can transcribe speech (ASR), understand audio, do zero-shot and instruct text-to-speech, and edit speech, all from one model.
- 43
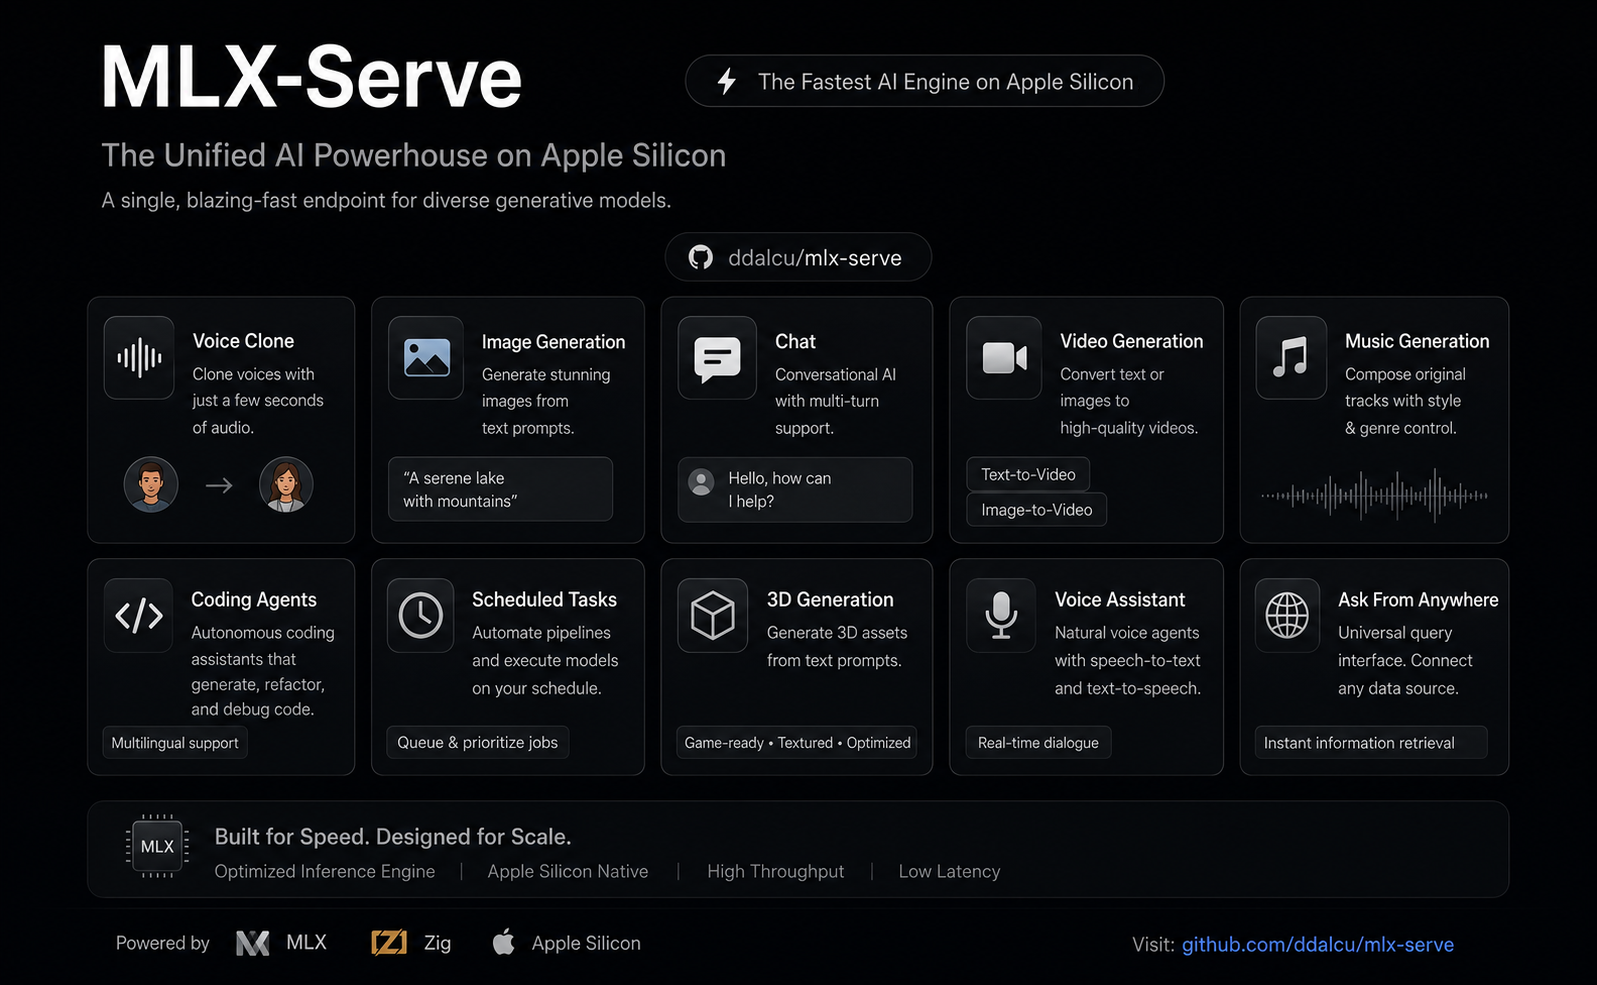
mlx-serve
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 44
VideoAgent
2KHKUDS/VideoAgent · PythonVideoAgent is an all-in-one agentic framework that understands, edits, and remakes videos from natural-language requests, handling everything from summarization to meme remixes and cross-lingual comedy adaptations.
- 45
FireRedTTS3
1.8KFireRedTeam/FireRedTTS3 · PythonFireRedTTS3 is a unified speech generation and editing model: it clones voices across 24 languages and 21 Chinese dialects, can design brand-new voices from a text description, and can edit existing speech (semantic and acoustic) using natural-language instructions.
- 46
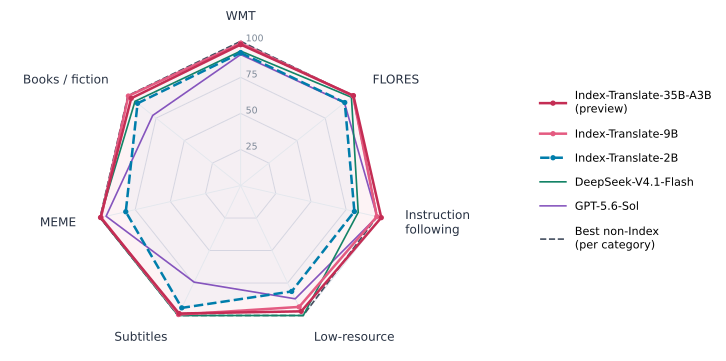
Index-Translate
1.6Kbilibili/Index-Translate · PythonIndex-Translate is a family of multilingual translation models built on Qwen3.5, covering text translation across 150 languages plus speech, syllable-controlled, and full-document translation variants.
- 47
yovoice
1.6Kleemysw/yovoice · TypeScriptyovoice is an open-source desktop app for macOS and Windows that turns text into natural, expressive speech locally, with voice cloning and emotion control, and no cloud API calls or per-character fees.
- 48
gufo
781gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 49
cs-board
776ChenShuo2004/cs-board · Pythoncs-board (白板声画工坊, Whiteboard Voice-Animation Workshop) is a local AI tool that turns a reference voice sample and Chinese text into a narrated whiteboard-style animation video, automating voice cloning, scene breakdown, illustration, hand-drawn strokes, subtitles and final MP4 export.
- 50
breeze-tts
604breezeblue-ai/breeze-tts · PythonBreeze TTS 2 is an open-weight text-to-speech model built for real-time interaction, and this repo is the official PyTorch inference code for it. It ranks #1 among open-weight models on the Artificial Analysis TTS leaderboard and outperforms some proprietary systems.
- 51
Colab-notebooks
556TeamAIQ/Colab-notebooks · Jupyter NotebookA curated collection of free, ready-to-run Google Colab and Kaggle notebooks, each wrapping a different AI tool for text-to-speech, voice cloning, image generation, video generation, or music generation.
- 52
DramaBox
505resemble-ai/DramaBox · PythonDramaBox is Resemble AI's expressive text-to-speech model with voice cloning, fine-tuned on top of Lightricks' LTX-2.3 audio model. The prompt itself controls speaker identity, emotion, delivery style, laughs, sighs, pauses and transitions, and an optional 10-second voice reference clones the target voice timbre.
- 53

LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
- 54

ComfyUI-MiniMaxH3Mod
441Luisacaotica/ComfyUI-MiniMaxH3Mod · PythonA ComfyUI custom node pack that adds 'RefMod' reference adapters for the MiniMax H3 model. It compresses reference images, videos or audio into small reusable .safetensors files that can be loaded and applied to influence generation without any training of the H3 model.
- 55
creator-flow
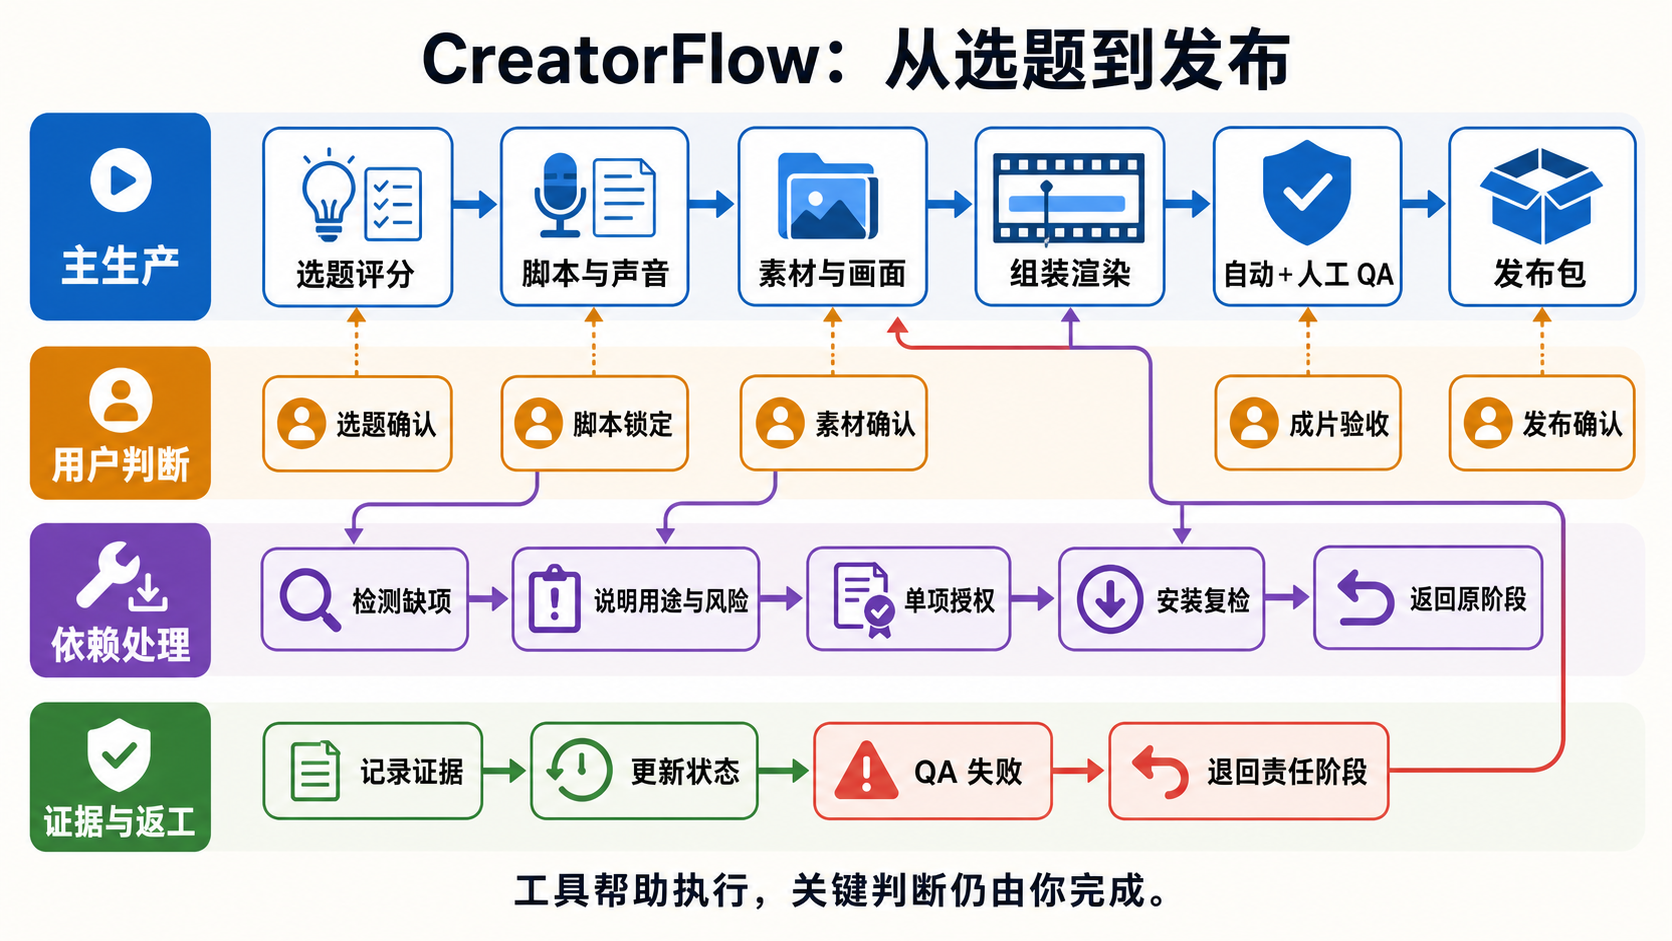
273Damonhhh/creator-flow · PowerShellCreatorFlow is an Agent Skills workflow that takes a video topic all the way through scoring, scripting, voiceover, materials, assembly, rendering, QA and a publish package, meant to be driven by a coding agent.
Related topics
Often tagged together