Topics / #speech
Speech projects on GitHub
Speech recognition and audio voice processing
As of , the most-starred Speech projects on GitHub are Real-Time-Voice-Cloning (60.2K stars), TTS (46.1K stars) and VoxCPM (39.4K stars). GitHub.Locker tracks 25 Speech repositories with 479.7K stars combined. The fastest-growing on October 16 was VoxCPM, with +40 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +40
VoxCPM
OpenBMB/VoxCPM · ★ 39.4KVoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
 +29
whisperX
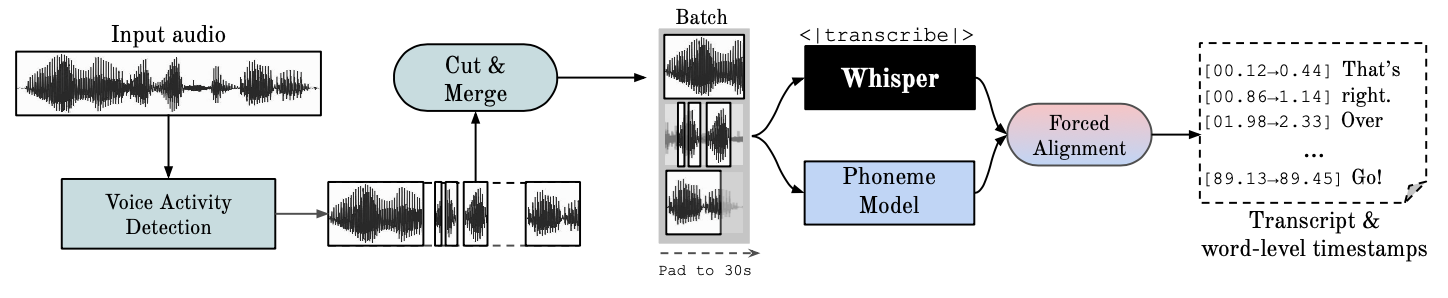
m-bain/whisperX · ★ 24.6KWhisperX is an open-source speech recognition tool that transcribes audio with accurate word-level timestamps and optional speaker diarization. It builds on OpenAI's Whisper and came out of PhD research at the University of Oxford.
chatterbox
resemble-ai/chatterbox · ★ 27KChatterbox is a family of state-of-the-art, open-source text-to-speech (TTS) models from Resemble AI, including multilingual and low-latency voice-agent variants.
 +24
faster-whisper
SYSTRAN/faster-whisper · ★ 25.9KA Python reimplementation of OpenAI's Whisper model on CTranslate2, a fast Transformer inference engine — up to 4x faster than the original at the same accuracy, using less memory, with optional 8-bit quantization on CPU and GPU.
The all-time top
25 projects · by stars
- 60.2K
 #1 · CorentinJ/Real-Time-Voice-Cloning
Real-Time-Voice-Cloning
It's an implementation of SV2TTS, a deep learning framework that lets you clone a voice from just a few seconds of audio and then generate arbitrary speech in that voice in real time.
- 46.1K
 #2 · coqui-ai/TTS
TTS
Coqui TTS is a deep learning toolkit for Text-to-Speech, shipping 1100+ pretrained models plus tools for training, fine-tuning, and curating datasets for new voices.
- 39.4K#3 · OpenBMB/VoxCPM
VoxCPM
VoxCPM is a tokenizer-free Text-to-Speech system that directly generates continuous speech representations through an end-to-end diffusion autoregressive architecture, skipping discrete tokenization for more natural, expressive speech. VoxCPM2 is the latest 2B-parameter release trained on 2M+ hours of multilingual audio.
- 4
OpenVoice
37.9Kmyshell-ai/OpenVoice · PythonOpenVoice is an audio foundation model for instant voice cloning, built by MIT and MyShell; it clones a reference speaker's tone color and generates speech in multiple languages and accents.
- 5
MockingBird
36.9Kbabysor/MockingBird · PythonMockingBird is a PyTorch voice-cloning toolbox: it learns a voice from a short audio clip and generates arbitrary Mandarin speech in real time. The repo is no longer actively updated — the author is building an optimized cloud-hosted version instead.
- 6
so-vits-svc
28.1Ksvc-develop-team/so-vits-svc · PythonAn open-source AI singing voice conversion (SVC) framework: it trains PyTorch models that make one voice sing the lines of another, using SoftVC speech features fed into VITS with an NSF-HiFiGAN vocoder.
- 7
chatterbox
27Kresemble-ai/chatterbox · PythonChatterbox is a family of state-of-the-art, open-source text-to-speech (TTS) models from Resemble AI, including multilingual and low-latency voice-agent variants.
- 8
faster-whisper
25.9KSYSTRAN/faster-whisper · PythonA Python reimplementation of OpenAI's Whisper model on CTranslate2, a fast Transformer inference engine — up to 4x faster than the original at the same accuracy, using less memory, with optional 8-bit quantization on CPU and GPU.
- 9
whisperX
24.6Km-bain/whisperX · PythonWhisperX is an open-source speech recognition tool that transcribes audio with accurate word-level timestamps and optional speaker diarization. It builds on OpenAI's Whisper and came out of PhD research at the University of Oxford.
- 10

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 11

Grounded-Segment-Anything
17.8KIDEA-Research/Grounded-Segment-Anything · Jupyter NotebookGrounded SAM, a research demo project that combines Grounding DINO with Segment Anything to detect and segment any object in an image from a plain text prompt, extended with Stable Diffusion, RAM, Whisper and more.
- 12

kaldi
15.5Kkaldi-asr/kaldi · ShellKaldi is an open-source speech recognition toolkit: C++ code plus example recipes for building speech-to-text, speaker-ID and speaker-verification systems.
- 13

speech-to-speech
13.5Khuggingface/speech-to-speech · PythonIt's a low-latency, fully modular voice-agent pipeline (VAD -> STT -> LLM -> TTS) for building voice agents with open-source speech and language models, exposed over WebSocket and WebRTC via the OpenAI Realtime API event set.
- 14
Wav2Lip
13.2KRudrabha/Wav2Lip · PythonWav2Lip is the open-source code and pretrained models behind an ACM Multimedia 2020 paper: it lip-syncs any video to any target speech audio with high accuracy, for research, academic, and personal use.
- 15
PaddleSpeech
12.7KPaddlePaddle/PaddleSpeech · PythonPaddleSpeech is an open-source speech and audio toolkit built on the PaddlePaddle platform, covering tasks like Automatic Speech Recognition (ASR), Text-to-Speech (TTS), Speaker Verification, Speech Translation, Keyword Spotting and Punctuation Restoration. It won the NAACL2022 Best Demo Award.
- 16
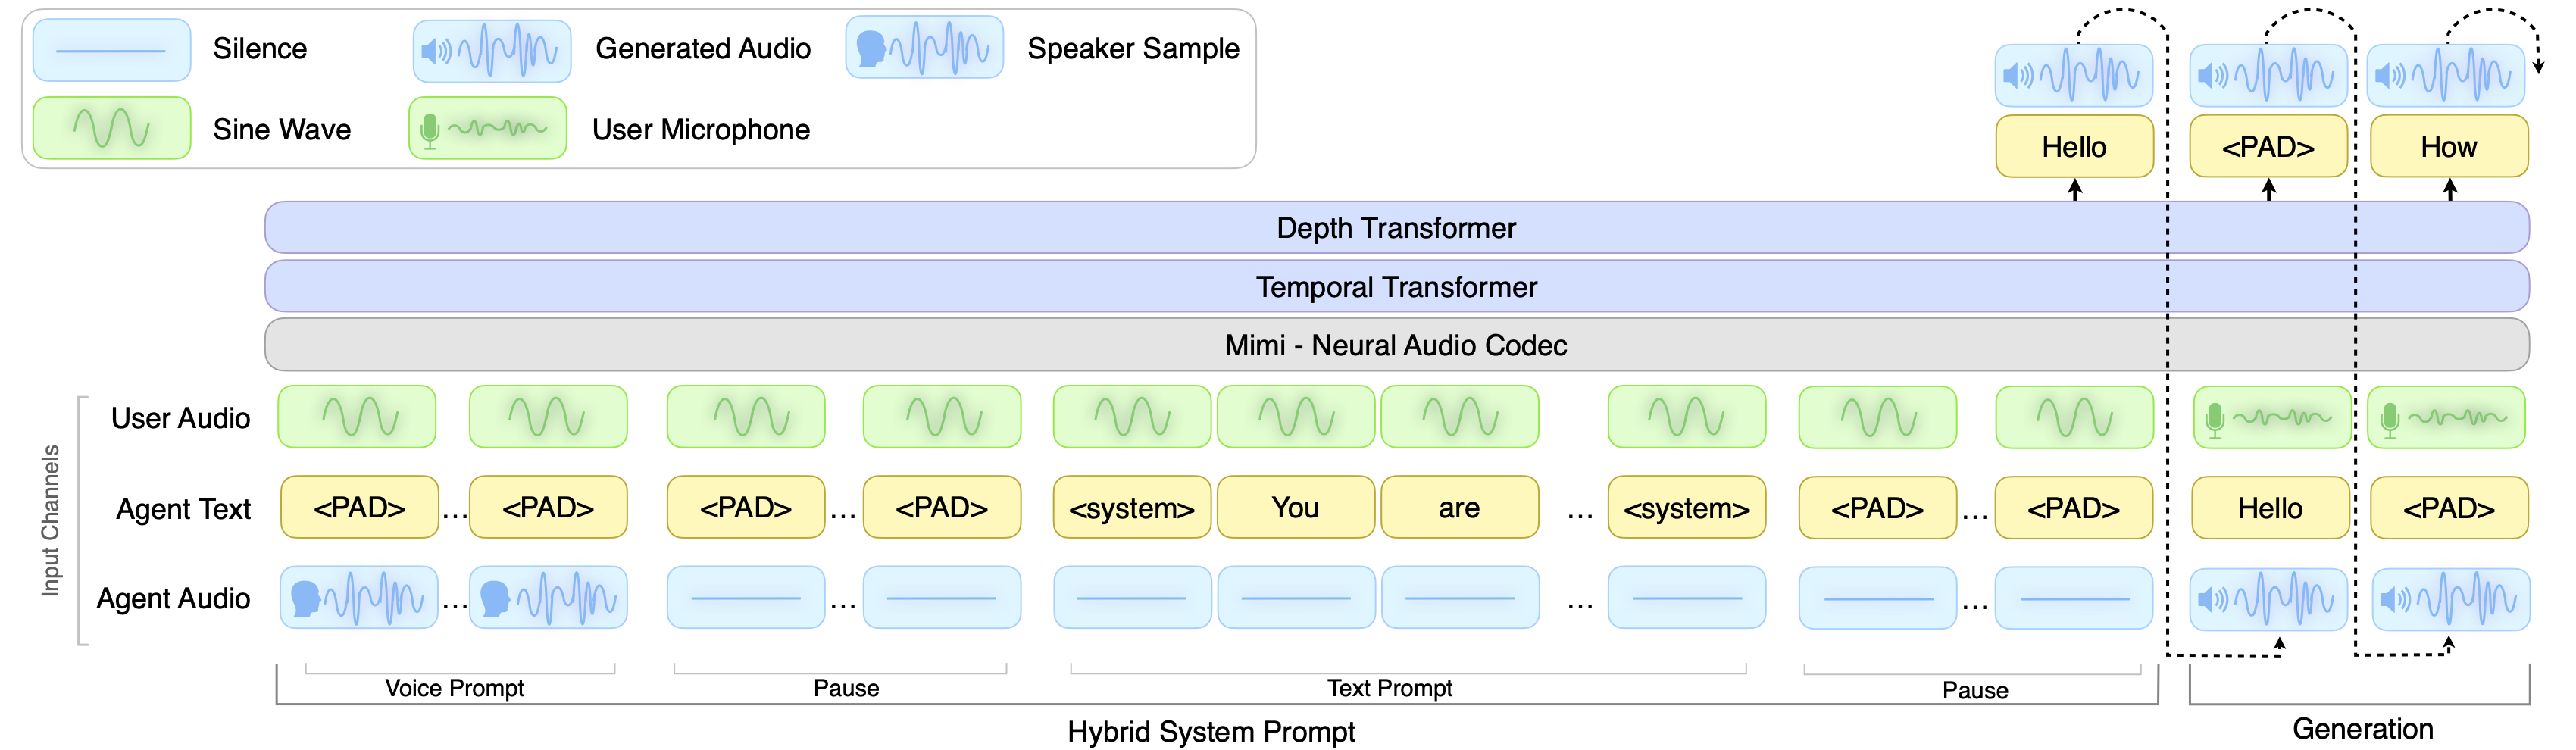
personaplex
11.2KNVIDIA/personaplex · PythonPersonaPlex is a real-time, full-duplex speech-to-speech conversational AI model from NVIDIA. It lets you control the assistant's persona through text role prompts and condition its voice on an audio sample, producing natural low-latency spoken conversations.
- 17
silero-vad
10.5Ksnakers4/silero-vad · PythonSilero VAD is a pre-trained, enterprise-grade Voice Activity Detector: a compact model that tells you which parts of an audio stream contain speech.
- 18

TTS
10.2Kmozilla/TTS · Jupyter NotebookAn open-source deep learning library for text-to-speech: pretrained models, vocoders, a speaker encoder and dataset tools, already used in 20+ languages for products and research.
- 19

AudioGPT
10.2KAIGC-Audio/AudioGPT · PythonAudioGPT is an open-source research system for understanding and generating speech, music, sound, and talking heads — pretrained foundation models wrapped behind prompt-driven audio tasks.
- 20
MOSS-TTS-Nano
4.5KOpenMOSS/MOSS-TTS-Nano · PythonMOSS-TTS-Nano is an open-source, 100M-parameter multilingual text-to-speech model from MOSI.AI and OpenMOSS that supports voice cloning, 48kHz stereo output, and real-time generation directly on CPU.
- 21
Qwen3-ASR
3.7KQwenLM/Qwen3-ASR · PythonQwen3-ASR is Alibaba's open-source family of speech recognition models: two all-in-one models (0.6B and 1.7B) that do language identification and transcription for 52 languages and dialects, plus a separate forced-alignment model that produces word-level timestamps.
- 22
SoulX-Podcast
3.6KSoul-AILab/SoulX-Podcast · PythonSoulX-Podcast is an inference codebase that generates realistic, long-form, multi-speaker podcast-style dialogue from text, including paralinguistic effects and several Chinese dialects.
- 23
FireRedTTS3
1.8KFireRedTeam/FireRedTTS3 · PythonFireRedTTS3 is a unified speech generation and editing model: it clones voices across 24 languages and 21 Chinese dialects, can design brand-new voices from a text description, and can edit existing speech (semantic and acoustic) using natural-language instructions.
- 24
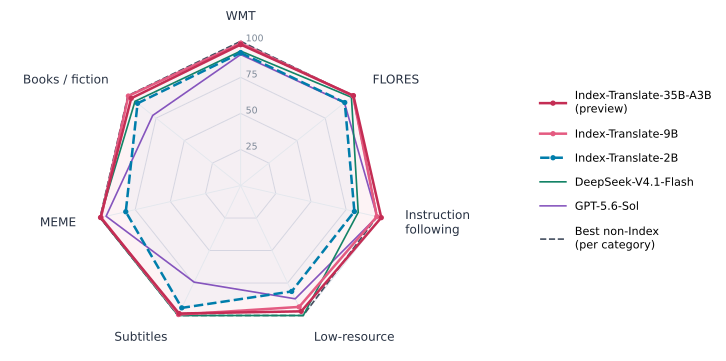
Index-Translate
1.6Kbilibili/Index-Translate · PythonIndex-Translate is a family of multilingual translation models built on Qwen3.5, covering text translation across 150 languages plus speech, syllable-controlled, and full-document translation variants.
- 25

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.

Related topics
Often tagged together