NeoHorse
Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness.
NeoHorse is TokenRhythm's family of open-weight models for agent workflows. NeoHorse-1 provides 4B and 9B language models for tool use, coding, and instruction following. NeoHorse-Jev builds on NeoHorse-1-4B to make structured decisions through prefill-only inference.
News
[2026-09-24] 🚀 NeoHorse-Jev-4B is here! Our new decision model brings Choice, Noul, and Score to the NeoHorse family. Explore the release.
[2026-09-09] 📄 Technical report on arXiv! Our technical report is now available, covering the routing harness, agentic post-training, and evaluation of NeoHorse-1.
[2026-09-08] 📦 GGUF and quantized models on Hugging Face! We release NeoHorse-1-4B-GGUF and NeoHorse-1-9B-GGUF. Both include 16-bit (BF16) weights and smaller 8-bit, 5-bit, and 4-bit quantized versions that use less disk space and memory, making it easier to run NeoHorse on your own hardware. MLX versions for Apple silicon are also available.
[2026-09-08] 🚀 Now on ModelScope! NeoHorse-1-4B and NeoHorse-1-9B are now available on ModelScope.
[2026-09-07] 🎉 NeoHorse-1 is here! We release NeoHorse-1-4B and NeoHorse-1-9B under the Apache 2.0 license.
Introduction
NeoHorse-Jev
NeoHorse-Jev-4B turns application state into decisions and probabilities. Built on NeoHorse-1-4B, it uses prefill-only inference to select an action with Choice, check a condition with Noul, or assign a rating with Score. Applications define the questions and possible answers, then use the results to route requests, select tools, or control a workflow.
In our evaluation, it scores 77.70 across six text benchmark groups, the highest among the four open-weight decision models with complete results in the comparison. Across Nimble, VitaminC, and MASSIVE, it reaches 83.26% mean accuracy, 11.50 percentage points above NeoHorse-1-4B. See the full comparison and evaluation protocols.
Text Decision Benchmarks
Scores are on a 0–100 scale; higher is better. Bold scores mark the best result and underlined scores the second-best among the listed entries. AVG is the equal-weight mean of the six benchmark groups. -- indicates unavailable results; only models with all six groups are ranked by AVG.
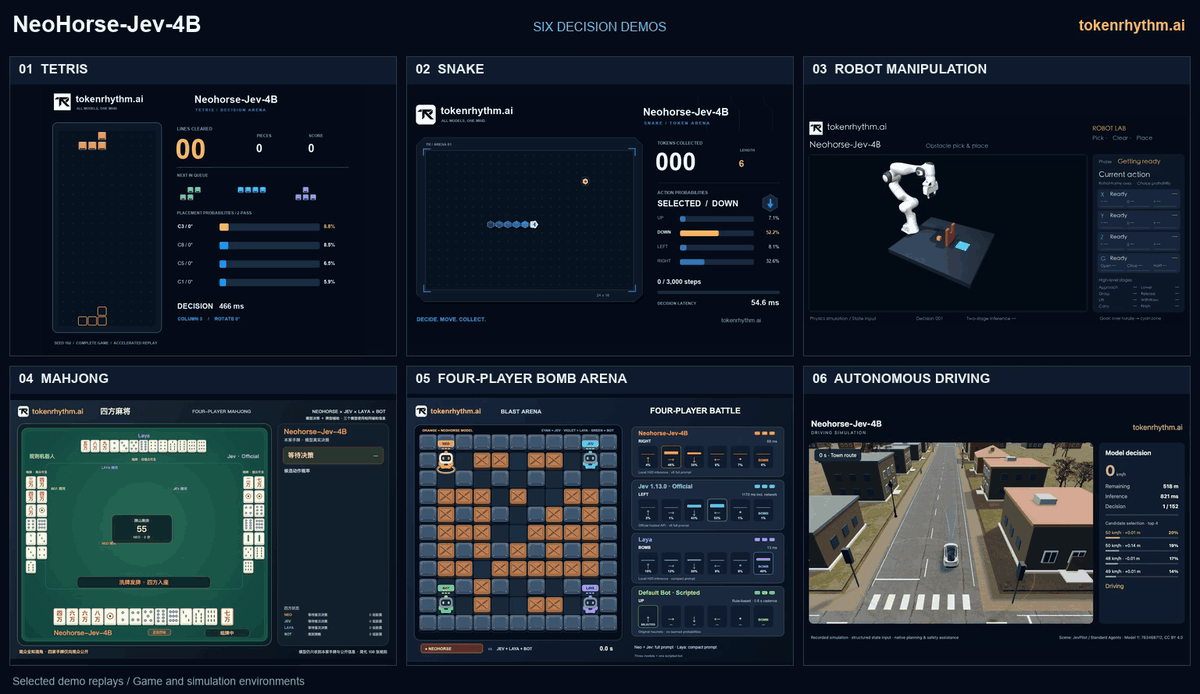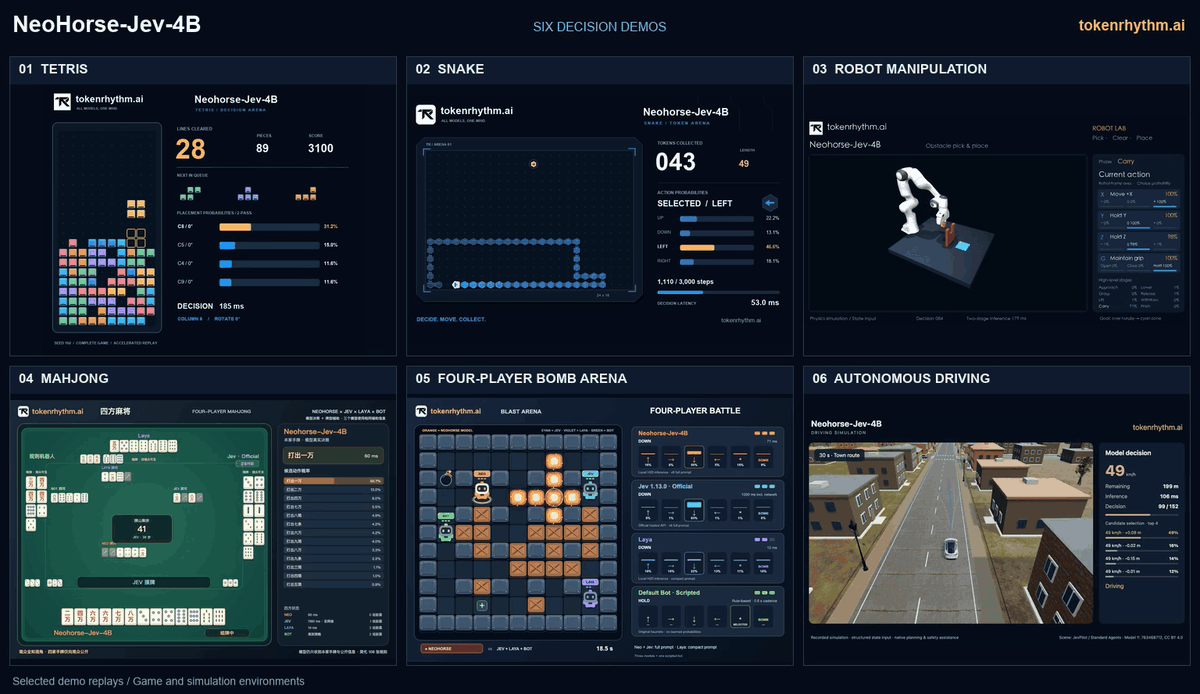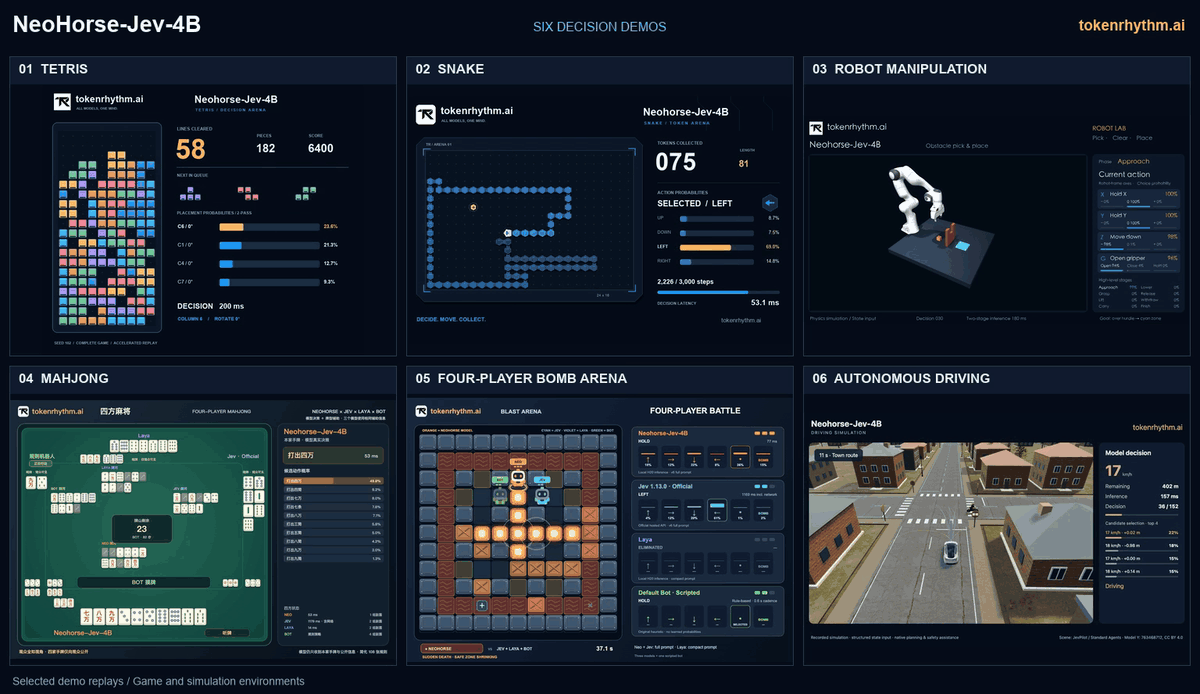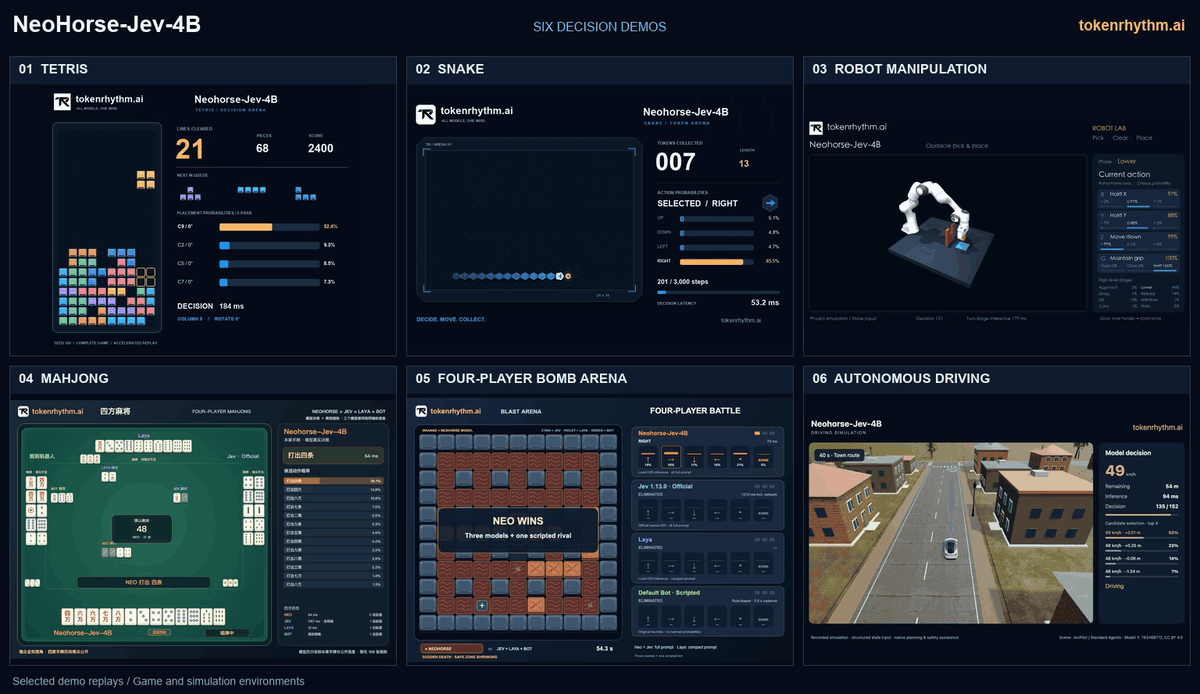
Tetris, Snake, robot manipulation, Mahjong, four-player bomb arena, and autonomous driving — left to right, top to bottom.
NeoHorse-1
NeoHorse-1 is a family of causal language models and an initial prototype on the path toward recursive self-improvement (RSI). The 4B and 9B checkpoints are post-trained from Qwen3.5 for text-based agent harnesses, tool use, coding, and instruction following.
The routing harness assigns tasks to a heterogeneous model pool, records tool interactions and outcomes, estimates capability demand, and feeds capability-level feedback into the next training mixture. Updated models can return to the harness, forming a prototype evaluation–selection–update loop; extending this loop across successive iterations is the next step toward RSI.
Highlights
- Agentic post-training framework: routing-guided curriculum SFT and routing-guided on-policy distillation turn execution trajectories into training signal while preserving execution and harness context.
- Data quality: exact and near-duplicate removal, evaluation decontamination, structural validation, six-dimensional semantic evaluation, and subscene-level Scene/Goal/Outcome labeling.
- Two release sizes: 4B for a lighter local deployment footprint and 9B for higher capacity on the same text-first serving interface.
Model Downloads
NeoHorse-1 checkpoints use a text input/text output interface. NeoHorse-Jev returns structured decisions and probabilities; download its complete model bundle and use the matching runtime or backend adapter. Each model card contains evaluation results and deployment instructions for that model.
Model Details
The specifications below cover NeoHorse-1-4B and NeoHorse-1-9B. Details for the decision model are in the NeoHorse-Jev documentation.
| Property | NeoHorse-1-4B | NeoHorse-1-9B |
|---|
| Model family | NeoHorse Agent-Native Causal Language Model | NeoHorse Agent-Native Causal Language Model |
| Parameters | Approximately 4B | Approximately 9B |
| Post-training | Routing-guided agentic post-training | Routing-guided agentic post-training |
| Interface | Text input and text output | Text input and text output |
| Context length | 262,144 natively; base capability extensible up to 1,010,000 tokens | 262,144 natively; base capability extensible up to 1,010,000 tokens |
| Weight format / precision | Safetensors / BF16 | Safetensors / BF16 |
Evaluation
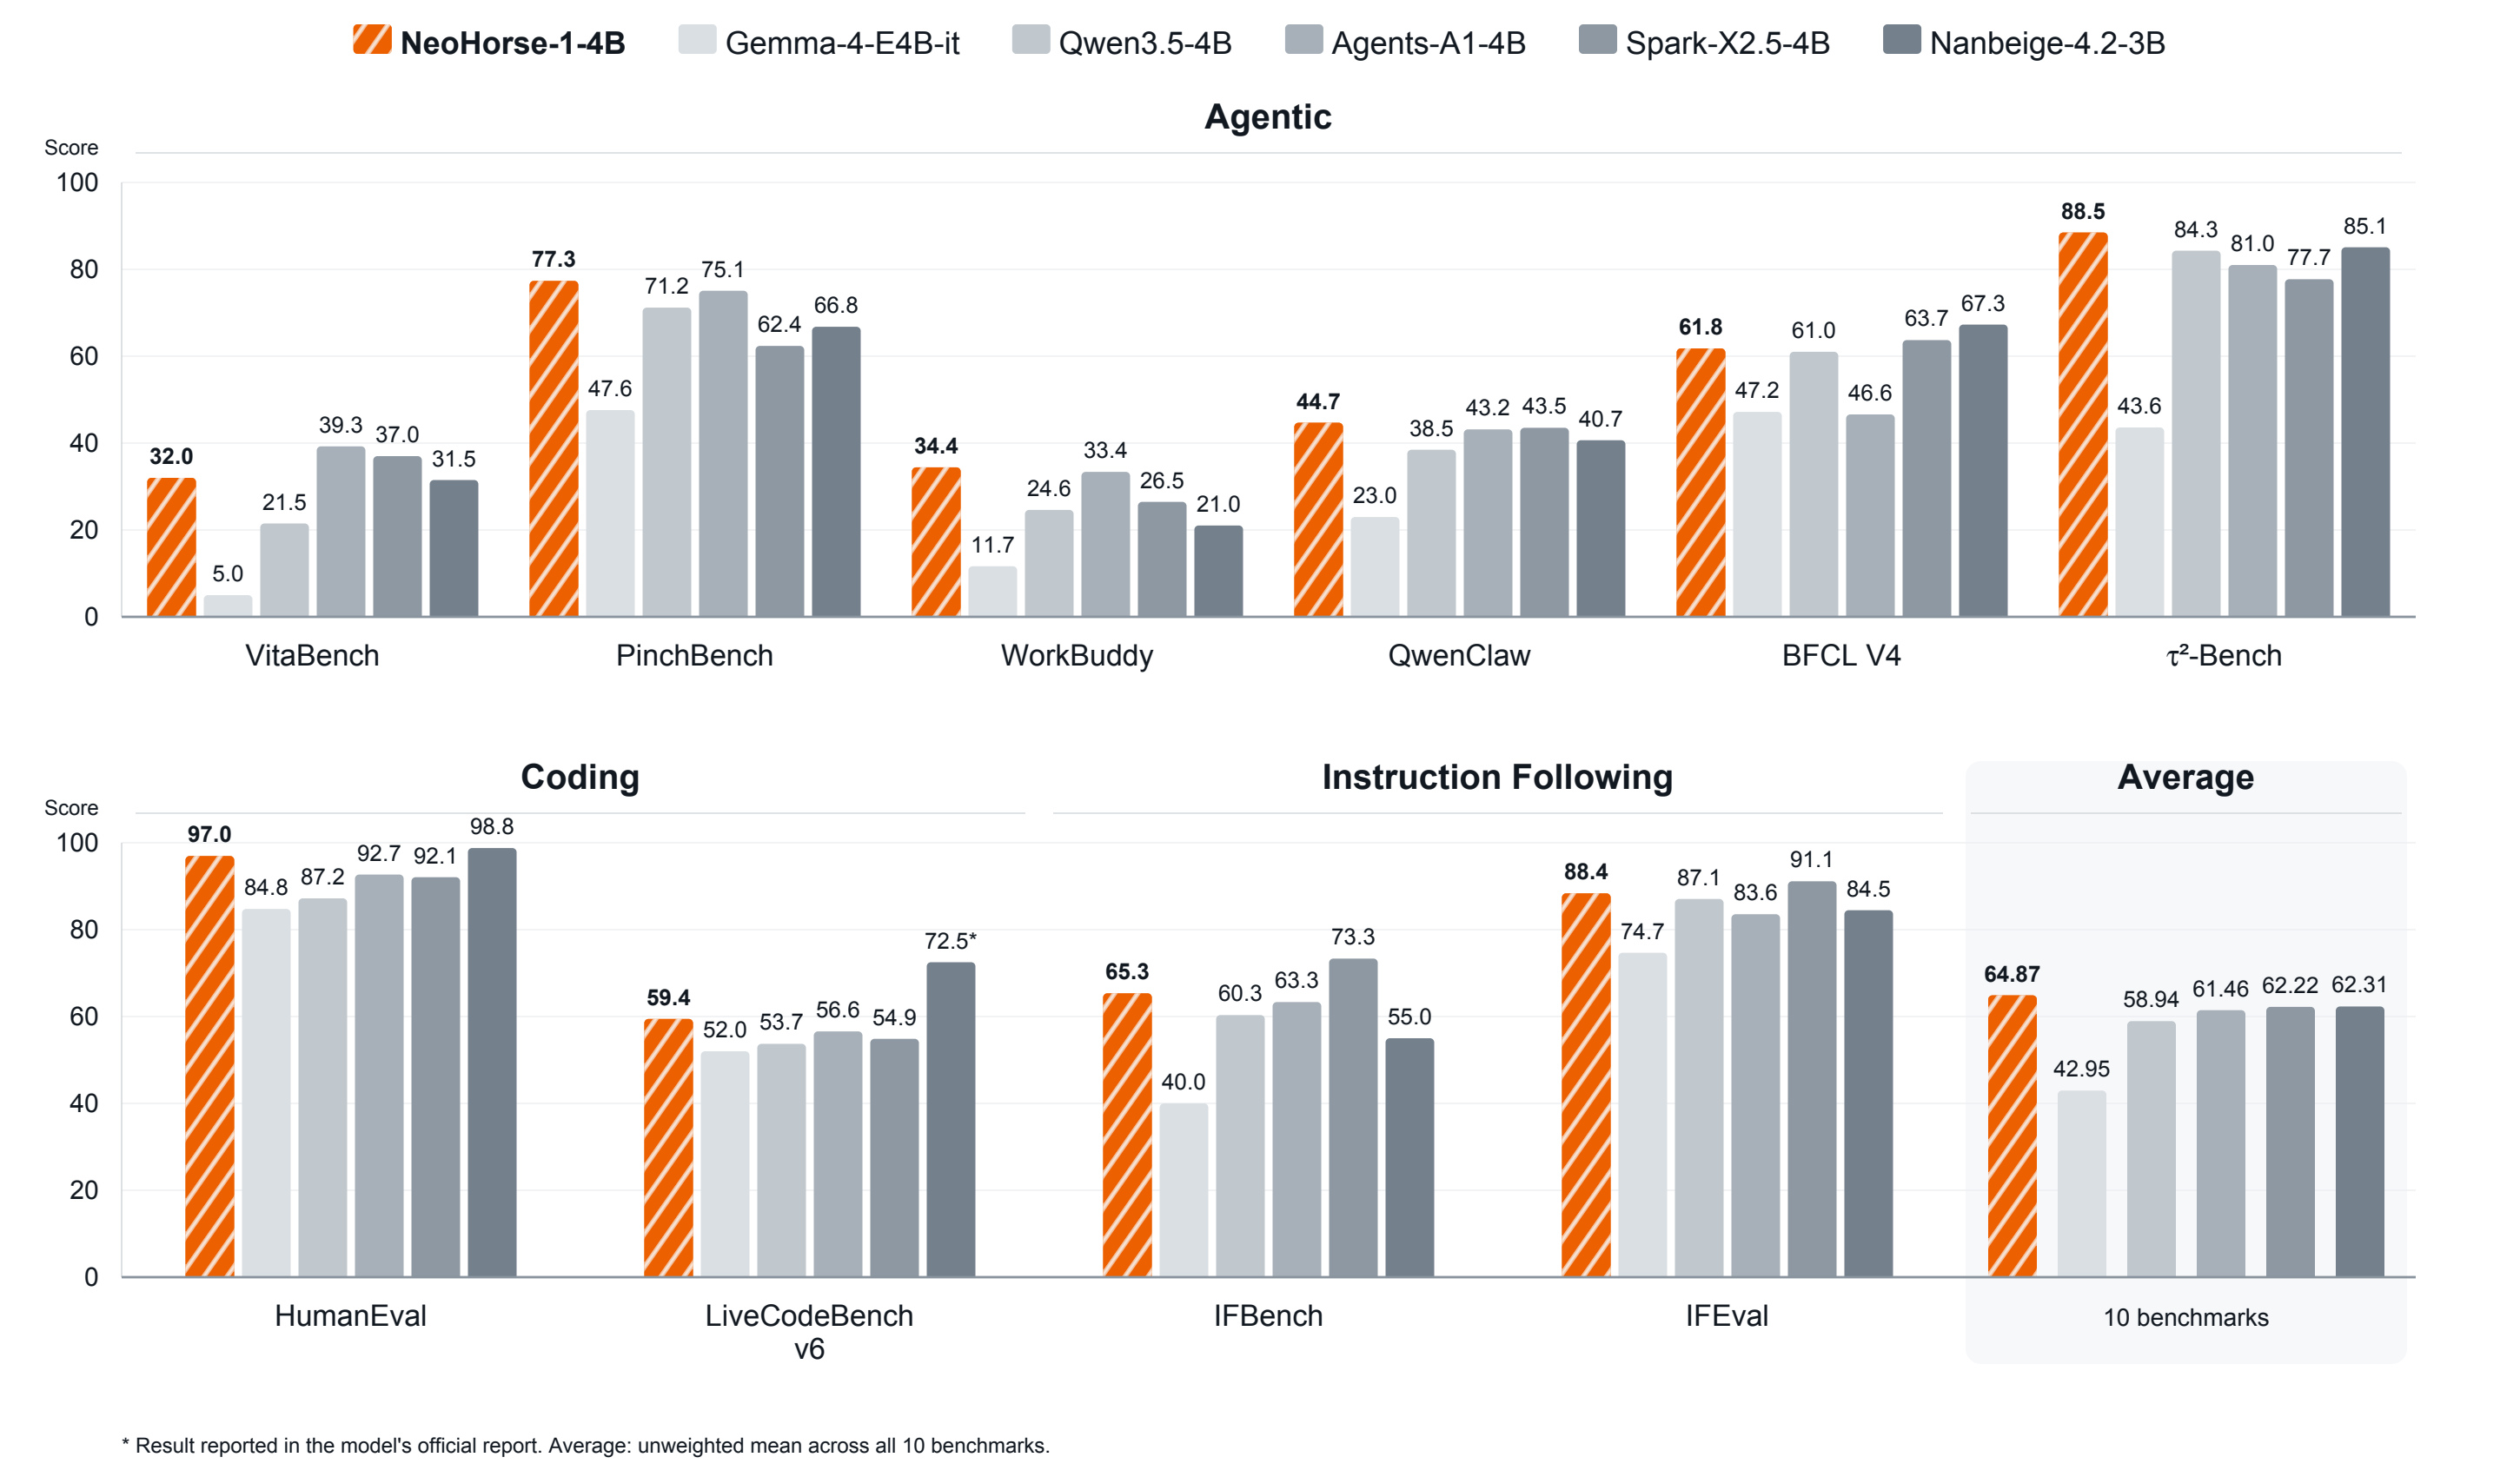
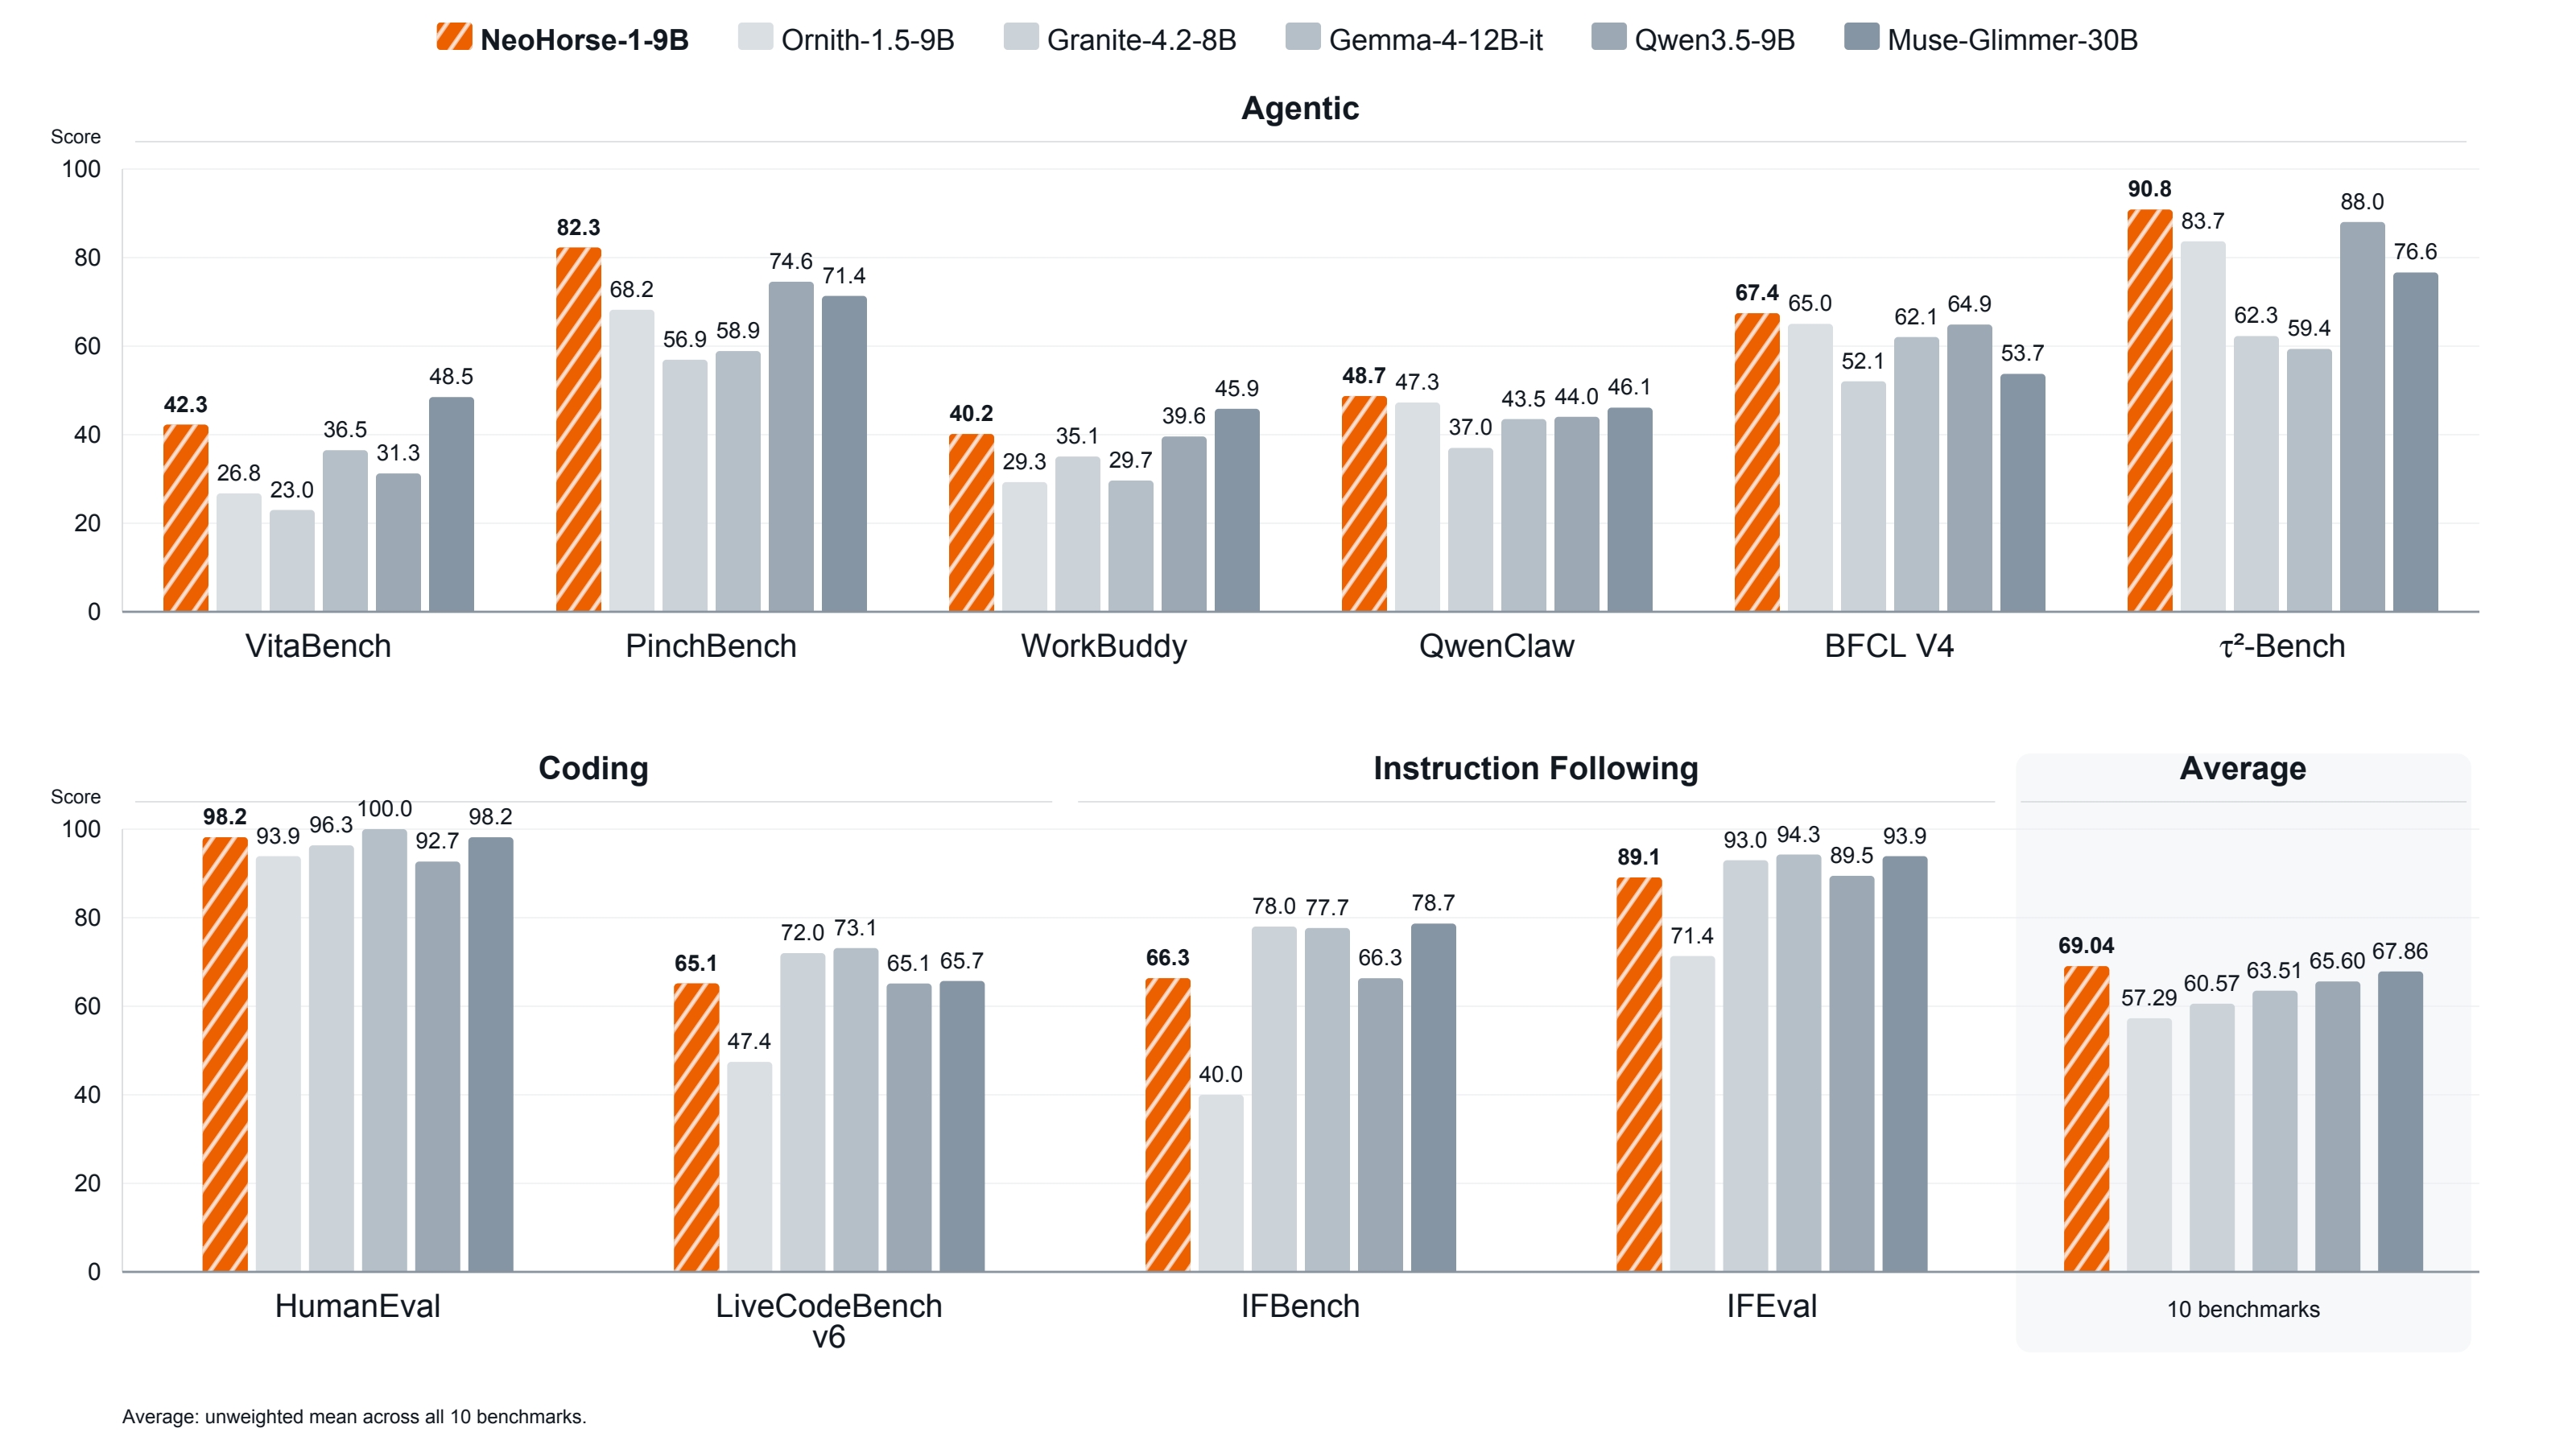
The tables report NeoHorse-1 results under the ten-benchmark protocol from the technical report. Results are grouped by capability. Higher is better; Δ is NeoHorse minus the same-size Qwen baseline. Bold marks the best result in each benchmark row; ties share the same formatting. For structured decision benchmarks, see the NeoHorse-Jev evaluation.
4B track
The 4B comparison includes five representative open-weight baselines. Underline marks the second-best result in each benchmark row.
| Benchmark | Qwen3.5-4B | Gemma-4-E4B-it | Nanbeige-4.2-3B | Agents-A1-4B | Spark-X2.5-4B | NeoHorse-1-4B | Δ vs Qwen3.5-4B |
|---|
| 🤖 Agentic |
| QwenClawBench | 38.47 | 22.98 | 40.66 | 43.16 | 43.52 | 44.68 | +6.21 |
| WorkBuddy Bench | 24.62 | 11.65 | 21.03 | 33.37 | 26.47 | 34.41 | +9.79 |
| PinchBench | 71.19 | 47.60 | 66.78 | 75.07 | 62.37 | 77.33 | +6.14 |
| VitaBench | 21.50 | 5.00 | 31.50 | 39.25 | 37.00 | 32.00 | +10.50 |
| BFCL v4 | 61.02 | 47.18 | 67.28 | 46.60 | 63.71 | 61.79 | +0.77 |
| tau2-Bench | 84.29 | 43.60 | 85.08 | 81.00 | 77.72 | 88.46 | +4.17 |
| 💻 Coding |
| HumanEval | 87.20 | 84.76 | 98.78 | 92.68 | 92.07 | 96.95 | +9.75 |
| LiveCodeBench v6 | 53.71 | 52.00 | 72.50* | 56.57 | 54.86 | 59.43 | +5.72 |
| 📚 Instruction Following |
| IFBench | 60.33 | 40.00 | 55.00 | 63.33 | 73.33 | 65.33 | +5.00 |
| IFEval | 87.06 | 74.68 | 84.47 | 83.55 | 91.13 | 88.35 | +1.29 |
| 📊 Overall |
| Ten-benchmark average | 58.94 | 42.95 | 62.31 | 61.46 | 62.22 | 64.87 | +5.93 |
9B track
The 9B comparison includes five representative open-weight baselines from the technical report. Underline marks the second-best result in each benchmark row.
| Benchmark |
Granite-4.2-8B |
Qwen3.5-9B |
Ornith-1.5-9B |
Gemma-4-12B-it |
Muse-Glimmer-30B |
NeoHorse-1-9B |
Δ vs Qwen3.5-9B |
|---|
| 🤖 Agentic |
| QwenClawBench | 37.01 | 44.04 | 47.27 | 43.53 | 46.11 | 48.73 | +4.69 |
| WorkBuddy Bench | 35.07 | 39.60 | 29.29 | 29.65 | 45.85 | 40.15 | +0.55 |
| PinchBench | 56.93 | 74.55 | 68.22 | 58.89 | 71.35 | 82.25 | +7.70 |
| VitaBench | 23.00 | 31.25 | 26.75 | 36.50 | 48.50 | 42.25 | +11.00 |
| BFCL v4 | 52.06 | 64.88 | 65.03 | 62.06 | 53.74 | 67.43 | +2.55 |
| tau2-Bench | 62.28 | 88.04 | 83.68 | 59.37 | 76.64 | 90.82 | +2.78 |
| 💻 Coding |
| HumanEval | 96.34 | 92.68 | 93.90 | 100.00 | 98.17 | 98.17 | +5.49 |
| LiveCodeBench v6 | 72.00 | 65.14 | 47.43 | 73.14 | 65.71 | 65.14 | +0.00 |
| 📚 Instruction Following |
| IFBench | 78.00 | 66.33 | 40.00 | 77.67 | 78.67 | 66.33 | +0.00 |
| IFEval | 92.98 | 89.46 | 71.35 | 94.27 | 93.90 | 89.09 | -0.37 |
| 📊 Overall |
| Ten-benchmark average | 60.57 | 65.60 | 57.29 | 63.51 | 67.86 | 69.04 | +3.44 |
* Nanbeige-4.2-3B LiveCodeBench v6 result is reported from its official blog post or technical report.
Reported protocol: SGLang v0.5.17 · temperature=1.0 · top_p=0.95 · top_k=20 · min_p=0.0 · presence_penalty=1.5 · repetition_penalty=1.0 · thinking mode enabled with enable_thinking=true and force_nonempty_content=true. QwenClawBench, WorkBuddy Bench, and tau2-Bench use three runs; PinchBench and VitaBench use one run; the remaining benchmarks follow their official protocols. VitaBench uses the DeepSeek-V4-Flash simulator and judge.
Deployment
For NeoHorse-Jev-4B, follow its deployment guide for vLLM, SGLang, or the native Python runtime, including Choice, Noul, and Score examples.
The examples below serve NeoHorse-1-4B or NeoHorse-1-9B downloaded to local disk. Set MODEL_PATH to the directory containing config.json, tokenizer files, and weights. The request model value is the served alias (neohorse-1-4B or neohorse-1-9B), not the filesystem path.
SGLang
pip install "sglang==0.5.17"
MODEL_PATH="/path/to/NeoHorse-1-4B"  # or /path/to/NeoHorse-1-9B
python3 -m sglang.launch_server \
  --model-path "$MODEL_PATH" \
  --served-model-name neohorse-1-4B \
  --host 0.0.0.0 --port 30000 \
  --context-length 262144 \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
vLLM
pip install -U vllm
MODEL_PATH="/path/to/NeoHorse-1-4B"  # or /path/to/NeoHorse-1-9B
vllm serve "$MODEL_PATH" \
  --served-model-name neohorse-1-4B \
  --host 0.0.0.0 --port 8000 \
  --max-model-len 262144 \
  --reasoning-parser qwen3 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_coder
The 262,144-token setting is a configured limit; actual capacity depends on GPU memory and serving settings. Reduce it if needed.
The examples below target vLLM at http://127.0.0.1:8000. For SGLang, use http://127.0.0.1:30000. For the 9B checkpoint, use --model neohorse-1-9B and launch the server with --served-model-name neohorse-1-9B.
Send a Request
Install the client dependency:
pip install requests
Run the provided chat example from the repository root:
python examples/chat.py \
  --url http://127.0.0.1:8000 \
  --model neohorse-1-4B
This example sends a predefined prompt to the deployed model and prints the generated response.
Alternatively, send an OpenAI-compatible request directly:
curl http://127.0.0.1:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"neohorse-1-4B","messages":[{"role":"user","content":"Write a Python function that returns the first n Fibonacci numbers."}],"max_tokens":512}'
Run the provided tool-calling example from the repository root:
python examples/tool_call.py \
  --url http://127.0.0.1:8000 \
  --model neohorse-1-4B
This example sends a predefined weather query and prints the tool call generated by the model.
License
NeoHorse-1 is released under the Apache License 2.0. The upstream models are Qwen3.5-4B and Qwen3.5-9B.
NeoHorse-Jev-4B is also released under Apache License 2.0. Its inference package includes components adapted from Kev; see the NeoHorse-Jev license and acknowledgments for attribution and bundled third-party notices.
Citation
@misc{neohorse2026,
  title        = {NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness},
  author       = {NeoHorse Team},
  year         = {2026},
  howpublished = {arXiv preprint},
  eprint       = {2609.08183},
  archivePrefix = {arXiv},
  primaryClass = {cs.CL},
  url          = {https://arxiv.org/abs/2609.08183}
}


 NeoHorse is TokenRhythm's family of open-weight language models built for agent workflows, with the 4B and 9B NeoHorse-1 checkpoints handling tool use, coding, and instruction following, plus a companion decision model called NeoHorse-Jev.