Topics / #table-extraction
Table-extraction projects on GitHub
Extracting tabular data from PDFs and documents.
As of , the most-starred Table-extraction projects on GitHub are docling (69K stars), surya (21.5K stars) and chandra (12.5K stars). GitHub.Locker tracks 8 Table-extraction repositories with 135.9K stars combined. The fastest-growing on October 17 was docling, with +43 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +43
docling
docling-project/docling · ★ 69KDocling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
 +8
PyMuPDF
pymupdf/PyMuPDF · ★ 10.9KPyMuPDF is a high-performance Python library for extracting, analyzing, converting, rendering, and manipulating PDF and other document formats, built on the MuPDF C engine.
 +6
surya
datalab-to/surya · ★ 21.5KSurya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
 +6
chandra
datalab-to/chandra · ★ 12.5KChandra OCR 2 is a state-of-the-art OCR model that converts images and PDFs into structured HTML, Markdown, or JSON while preserving the original layout. It handles complex tables, forms, handwriting, and math, and supports over 90 languages.
The all-time top
8 projects · by stars
- 69K#1 · docling-project/docling
docling
Docling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
- 21.5K#2 · datalab-to/surya
surya
Surya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
- 12.5K#3 · datalab-to/chandra
chandra
Chandra OCR 2 is a state-of-the-art OCR model that converts images and PDFs into structured HTML, Markdown, or JSON while preserving the original layout. It handles complex tables, forms, handwriting, and math, and supports over 90 languages.
- 4
PyMuPDF
10.9Kpymupdf/PyMuPDF · PythonPyMuPDF is a high-performance Python library for extracting, analyzing, converting, rendering, and manipulating PDF and other document formats, built on the MuPDF C engine.
- 5

pdfplumber
10.8Kjsvine/pdfplumber · Pythonpdfplumber is a Python library that inspects PDFs in detail, exposing each character, line, rectangle, and curve, and makes it easy to extract text and tables from them.
- 6

PDF-Extract-Kit
10Kopendatalab/PDF-Extract-Kit · PythonPDF-Extract-Kit is an open-source Python toolkit that bundles state-of-the-art models for layout detection, formula detection, formula recognition, OCR, and table recognition to pull high-quality content out of complex PDF documents.
- 7
ParseBench
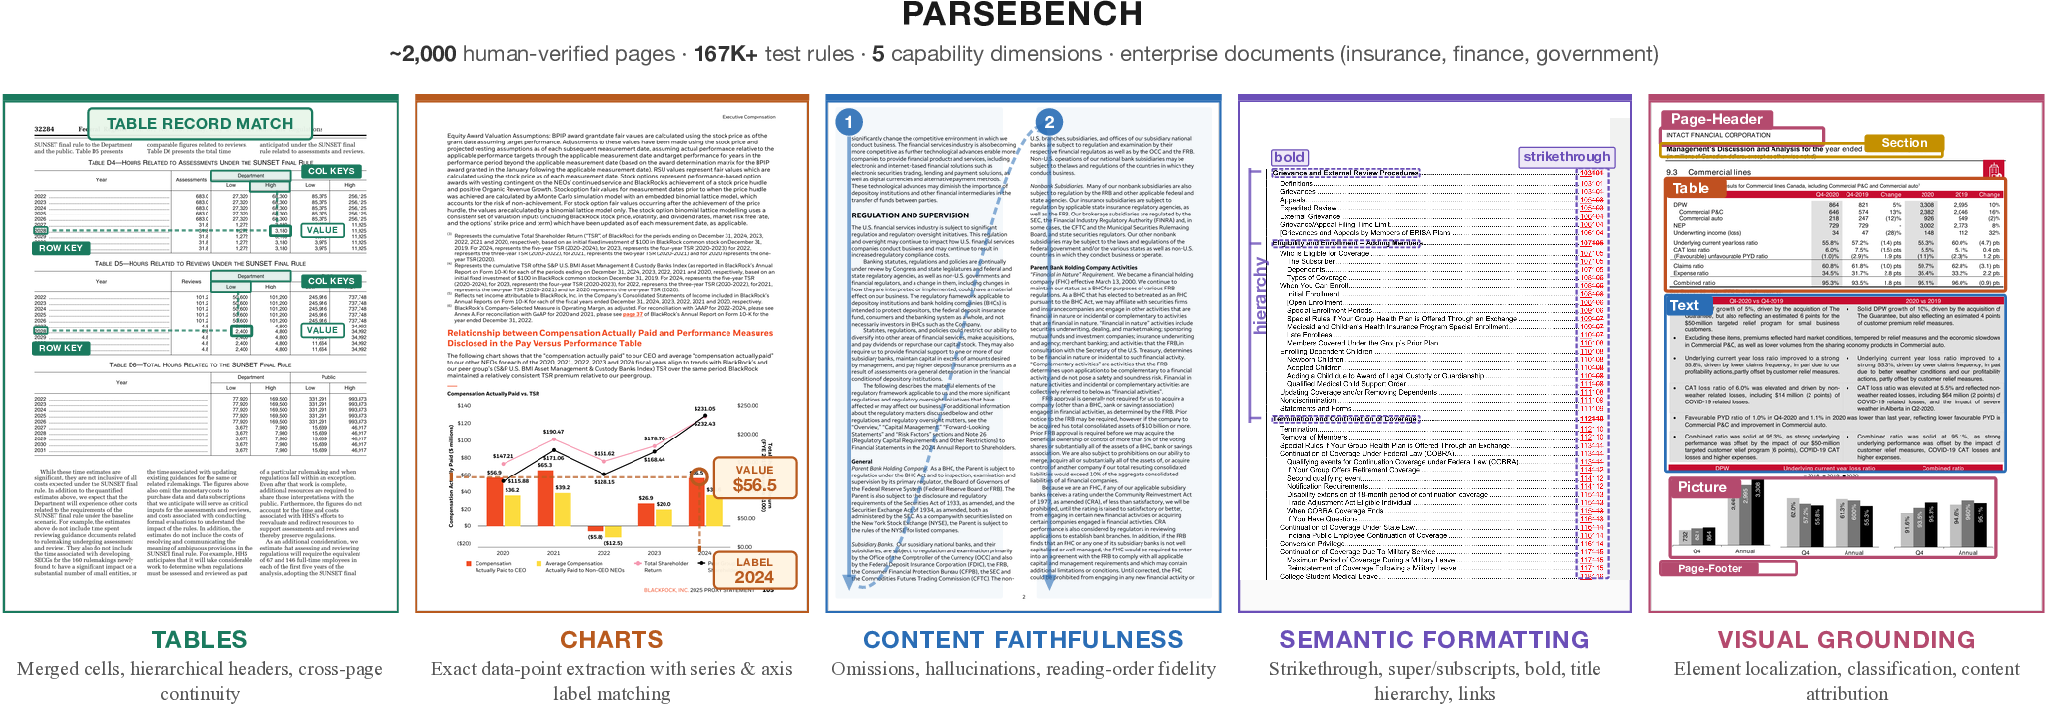
603run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 8
nativePDF-structurer
409crunz-ai/nativePDF-structurer · PythonNativePDF Structurer converts large digital-native PDFs — equipment manuals, repair manuals, technical catalogs — into structured Markdown, images and table CSVs without using OCR or any machine-learning model, so long vendor documents can reliably feed into RAG pipelines.
Related topics
Often tagged together