Topics / #hybrid-search
Hybrid-search projects on GitHub
Search engines combining vector and keyword retrieval.
As of , the most-starred Hybrid-search projects on GitHub are meilisearch (59.6K stars), quivr (39.6K stars) and qdrant (35.1K stars). GitHub.Locker tracks 16 Hybrid-search repositories with 330K stars combined. The fastest-growing on October 17 was xerj, with +864 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +864
xerj
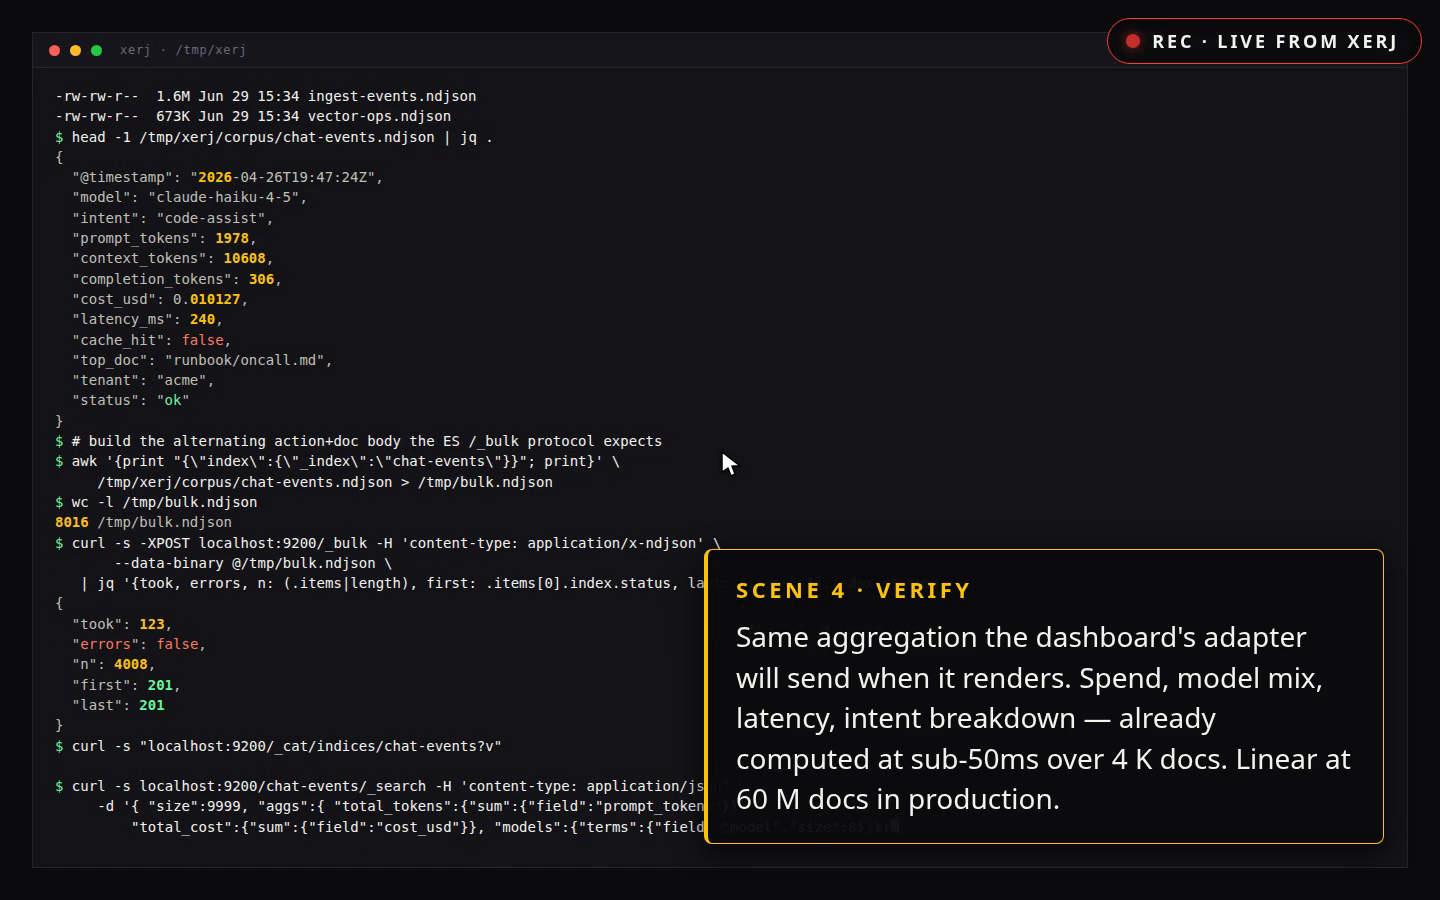
xerj-org/xerj · ★ 8.3KXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
 +36
agentmemory
rohitg00/agentmemory · ★ 29.6KPersistent memory for AI coding agents: it captures what your agent does, compresses it into searchable memory, and injects the right context when the next session starts, so you stop re-explaining your project to Claude Code, Cursor or Codex.
 +20
qmd
tobi/qmd · ★ 30.5KQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
 +15
supermemory
supermemoryai/supermemory · ★ 31.3KSupermemory is a memory and context engine for AI: it learns from your conversations, extracts facts and builds user profiles, so your AI remembers you between sessions instead of starting from zero.
The all-time top
16 projects · by stars
- 59.6K
 #1 · meilisearch/meilisearch
meilisearch
Meilisearch is a fast, open-source search engine that adds AI-powered hybrid search (combining full-text and semantic search) to websites and apps.
- 39.6K
 #2 · The-Vibe-Company/quivr
quivr
Quivr is an open-source engine that turns your files and content streams into search and monitoring — a 'second brain' you can query, built around an opinionated RAG powered by generative AI.
- 35.1K
 #3 · qdrant/qdrant
qdrant
Qdrant is a high-performance vector similarity search engine and vector database written in Rust, built to store, search, and manage 'points' (vectors plus a JSON payload) for AI applications like semantic search, recommendations, and RAG.
- 4
supermemory
31.3Ksupermemoryai/supermemory · TypeScriptSupermemory is a memory and context engine for AI: it learns from your conversations, extracts facts and builds user profiles, so your AI remembers you between sessions instead of starting from zero.
- 5
qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 6

FastGPT
29.8Klabring/FastGPT · TypeScriptFastGPT is an AI agent building platform: a knowledge-based platform on top of LLMs with out-of-the-box data processing, model calling, RAG retrieval and visual workflow orchestration, aimed at building complex question-answering systems without heavy setup.
- 7
agentmemory
29.6Krohitg00/agentmemory · TypeScriptPersistent memory for AI coding agents: it captures what your agent does, compresses it into searchable memory, and injects the right context when the next session starts, so you stop re-explaining your project to Claude Code, Cursor or Codex.
- 8
weaviate
16.9Kweaviate/weaviate · GoWeaviate is an open-source, cloud-native vector database: it stores objects and vectors together and lets you combine vector search with structured filtering for semantic search at scale.
- 9

zvec
16.1Kalibaba/zvec · C++Alibaba's open-source, in-process vector database — a lightweight, lightning-fast similarity-search engine you embed directly into your application, battle-tested inside Alibaba Group.
- 10
claude-context
12.6Kzilliztech/claude-context · TypeScriptClaude Context is an MCP server that gives AI coding agents semantic search over your entire codebase, so they can pull relevant code straight into context instead of loading whole directories.
- 11

orama
10.6Koramasearch/orama · TypeScriptOrama is a complete search engine and RAG pipeline that runs in your browser, on a server or at the edge, with support for full-text, vector and hybrid search.
- 12
xerj
8.3Kxerj-org/xerj · RustXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
- 13
docker-agent
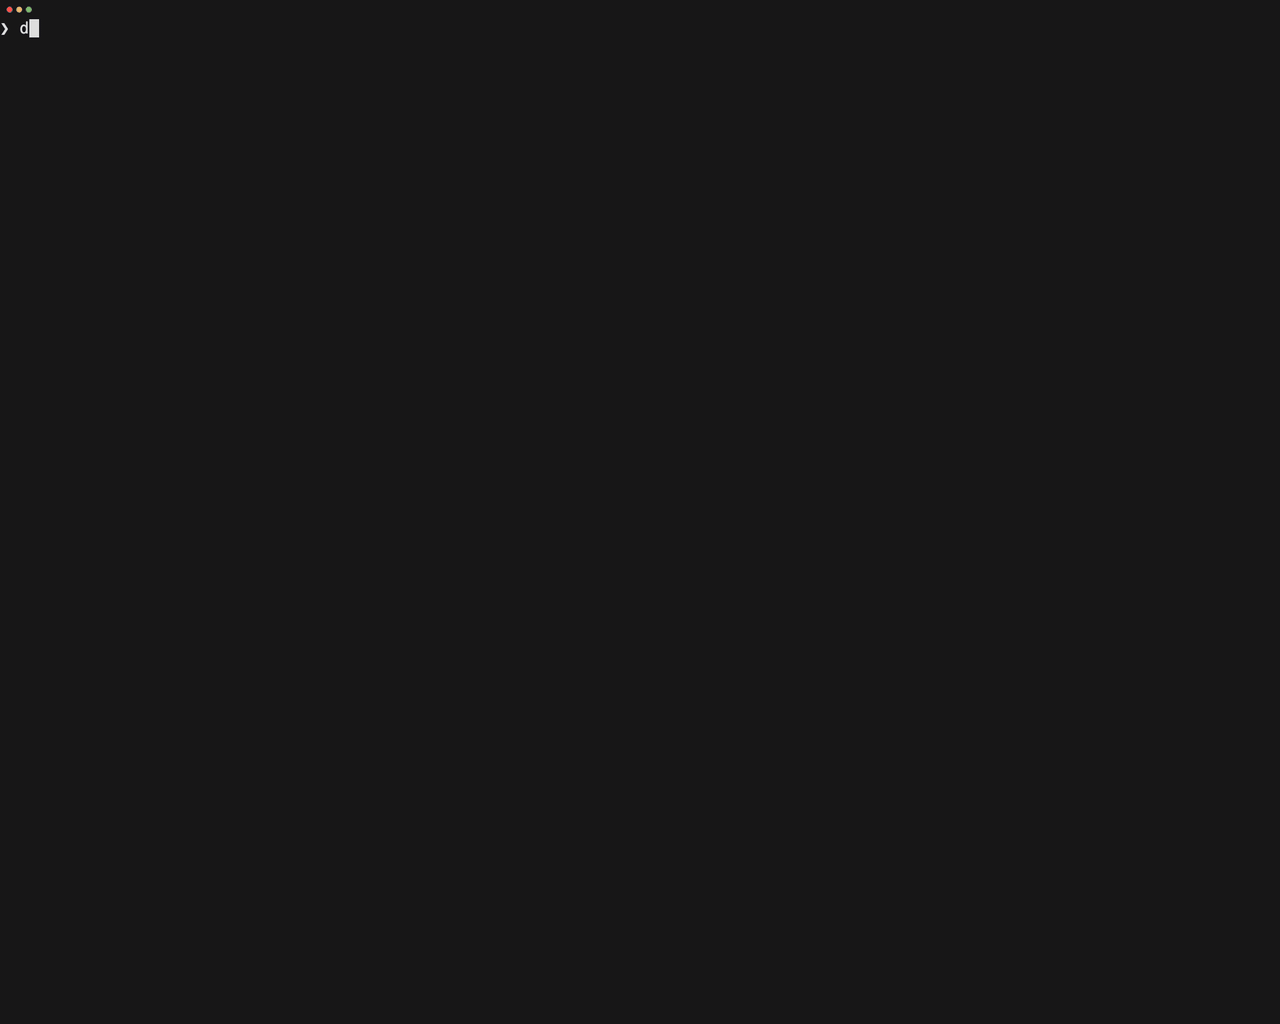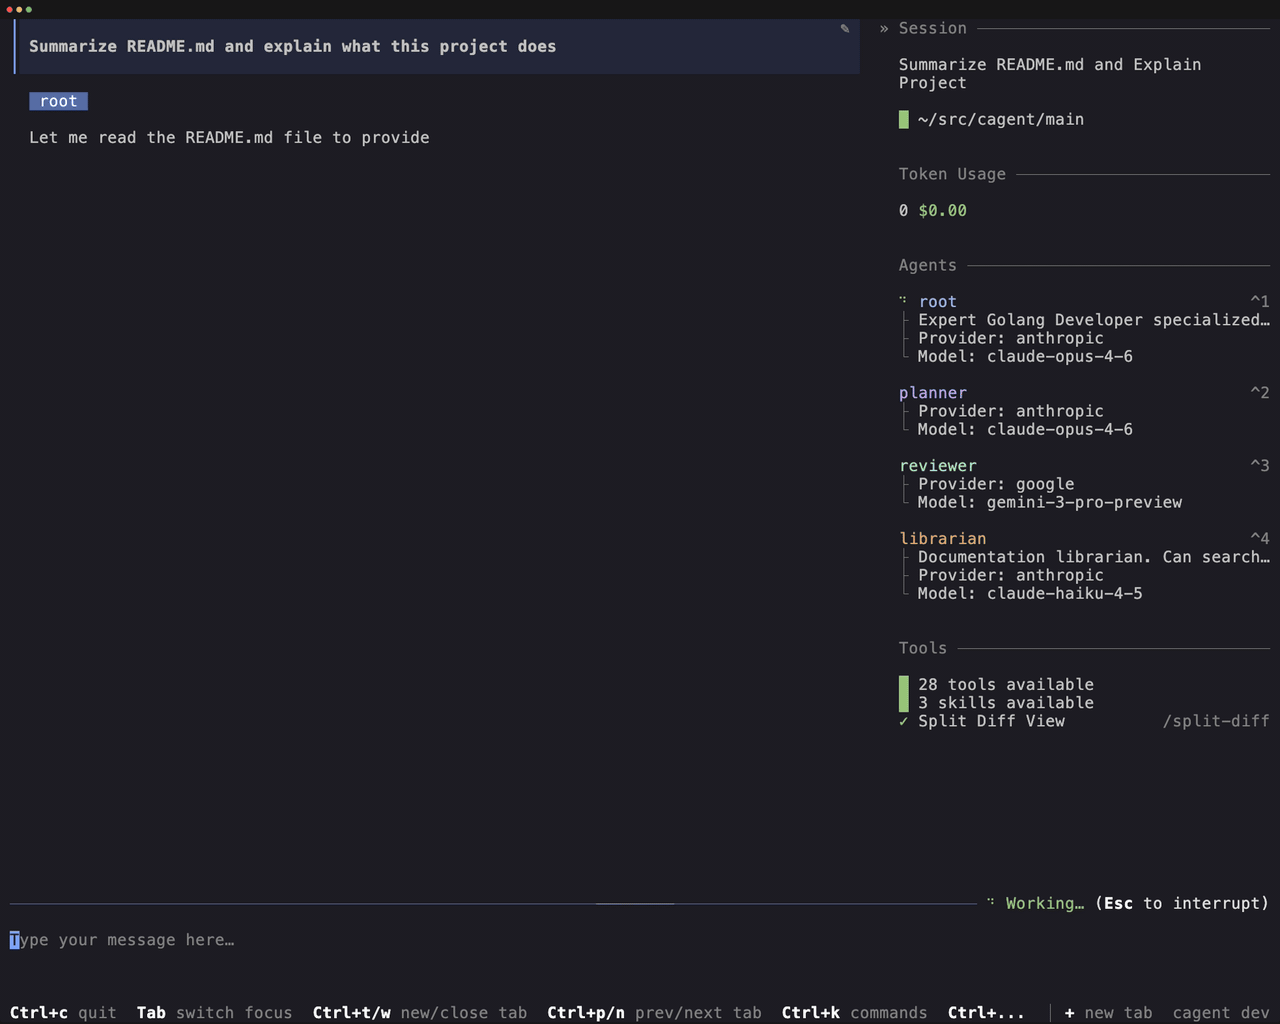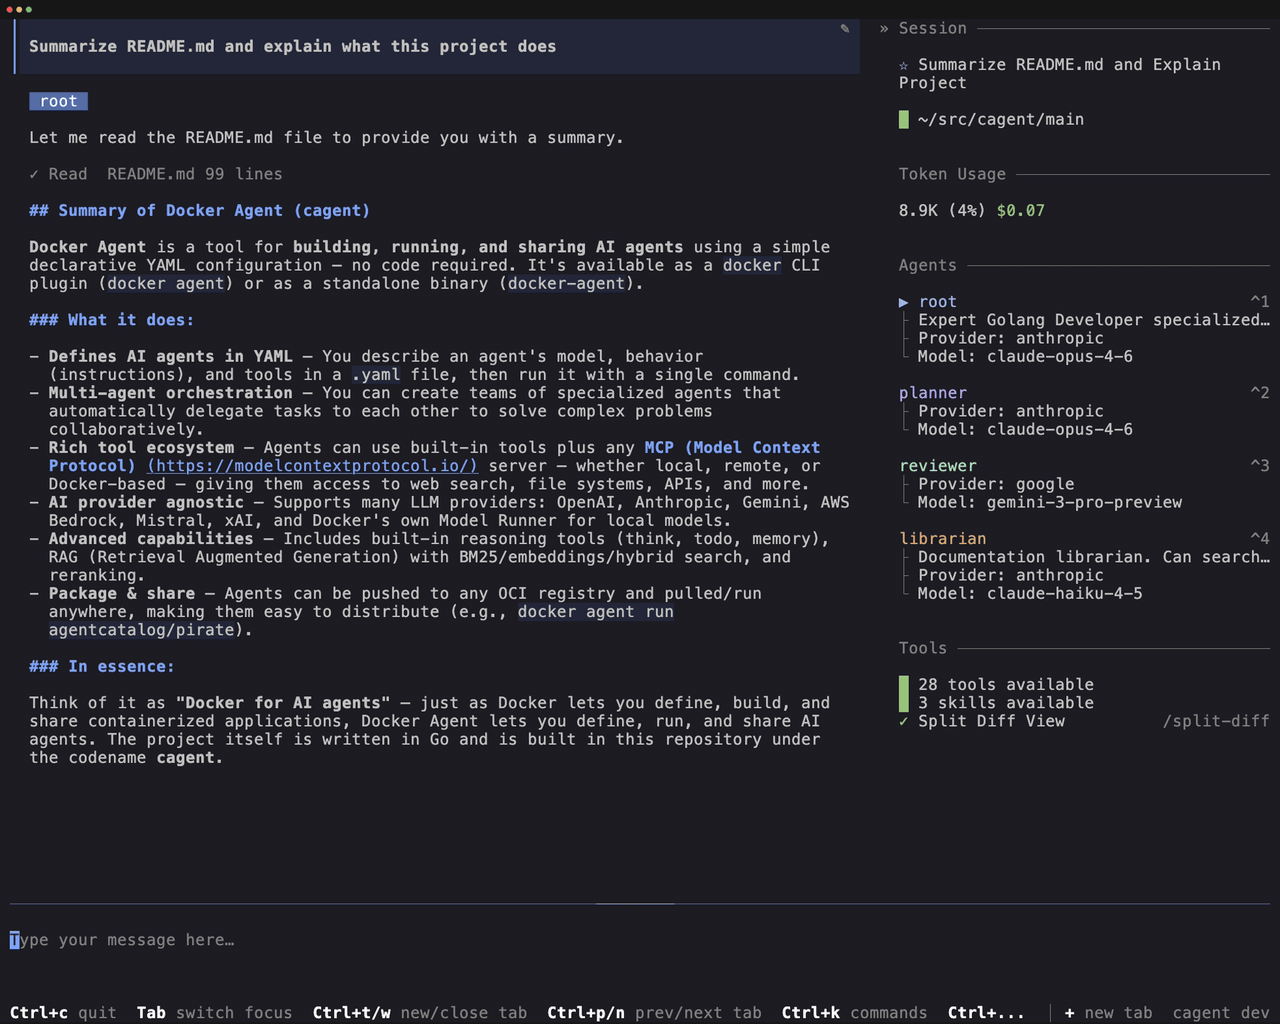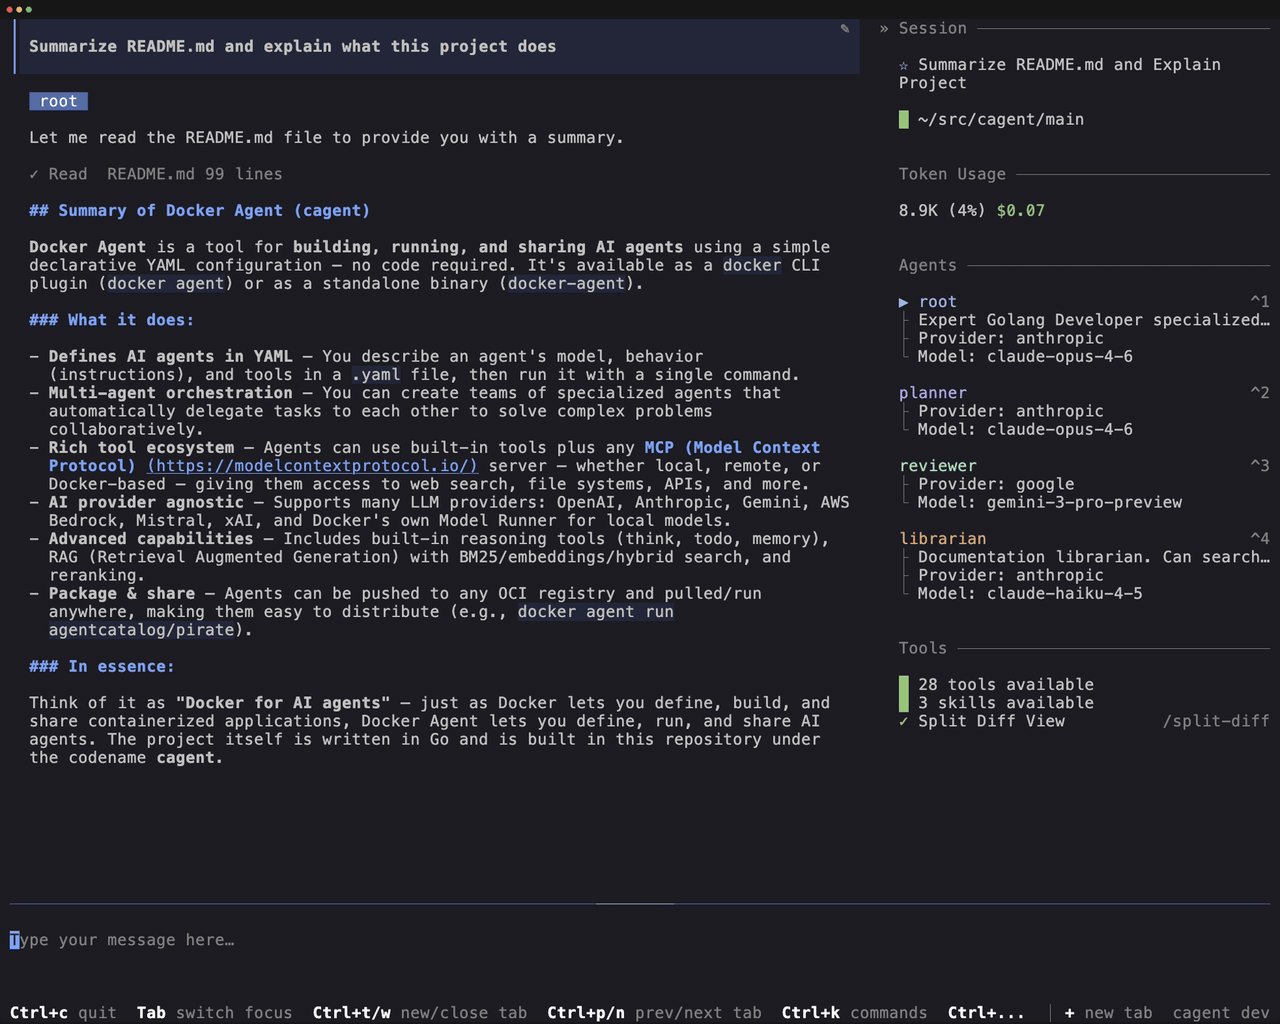
4.6Kdocker/docker-agent · GoDocker Agent is a tool for building, running, and sharing AI agents using a declarative YAML config, with built-in tools and multi-agent orchestration — no code required.
- 14

m_flow
4.5KFlowElement-xinliuyuansu/m_flow · PythonM-flow is a bio-inspired cognitive memory engine that acts as a new paradigm for Graph RAG: instead of just retrieving similar text chunks, it builds a graph of memories and scores answers by the strongest chain of evidence connecting the query to the content, the way human recall works.
- 15
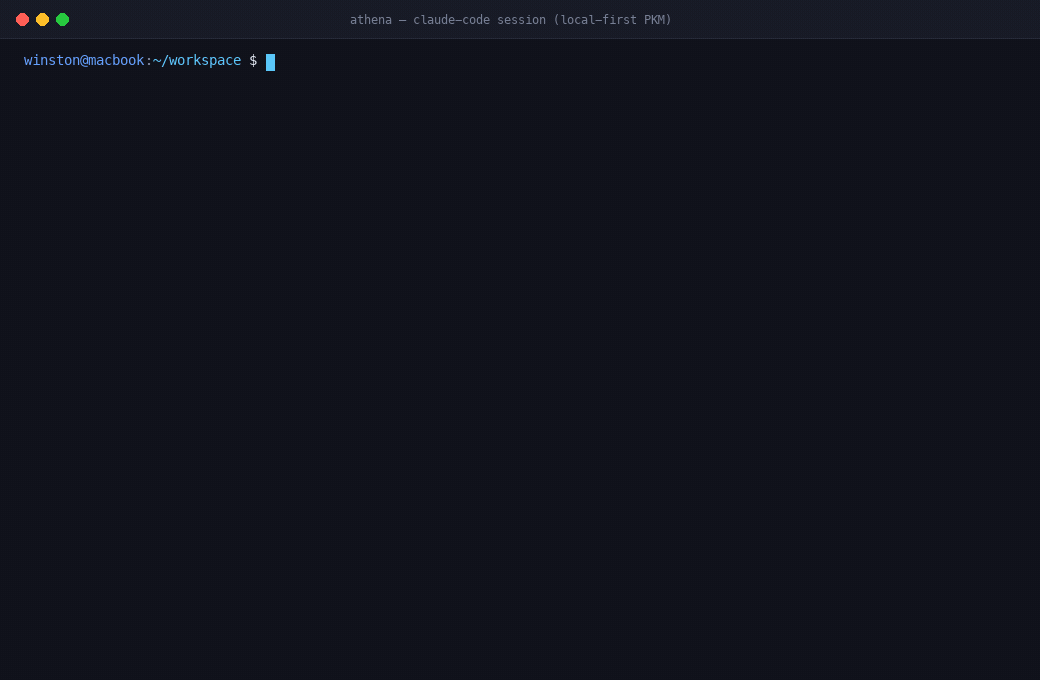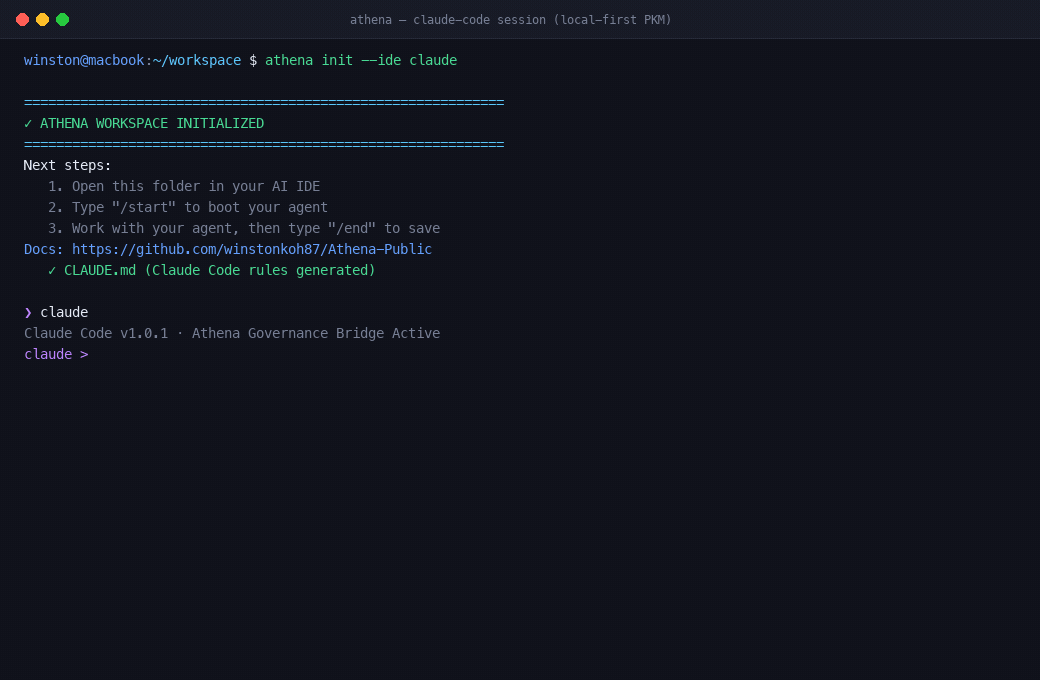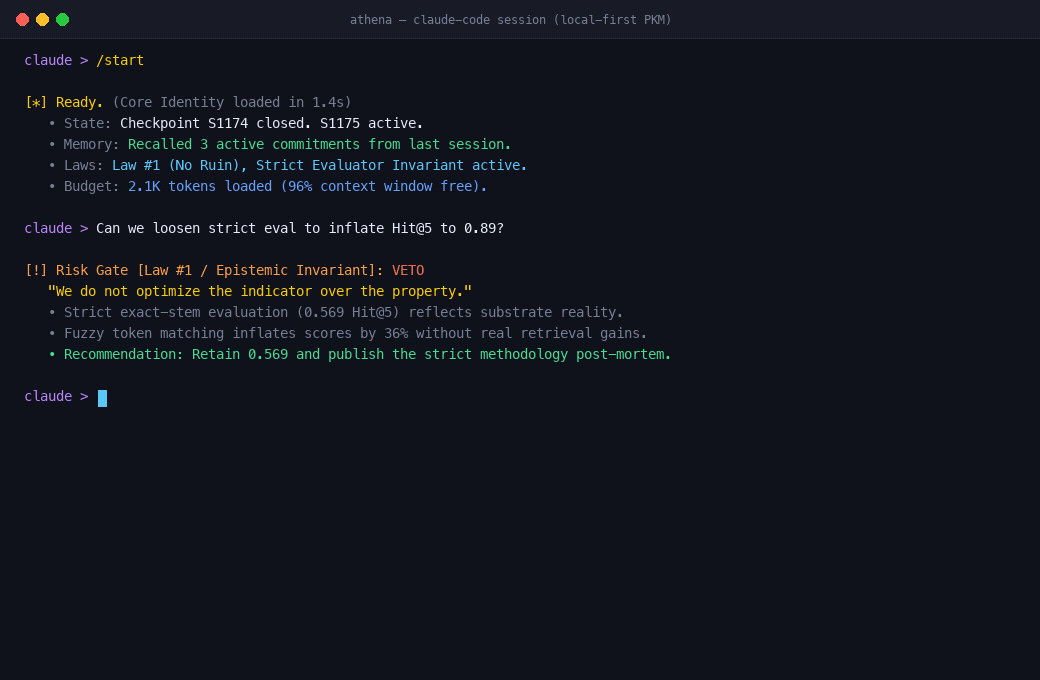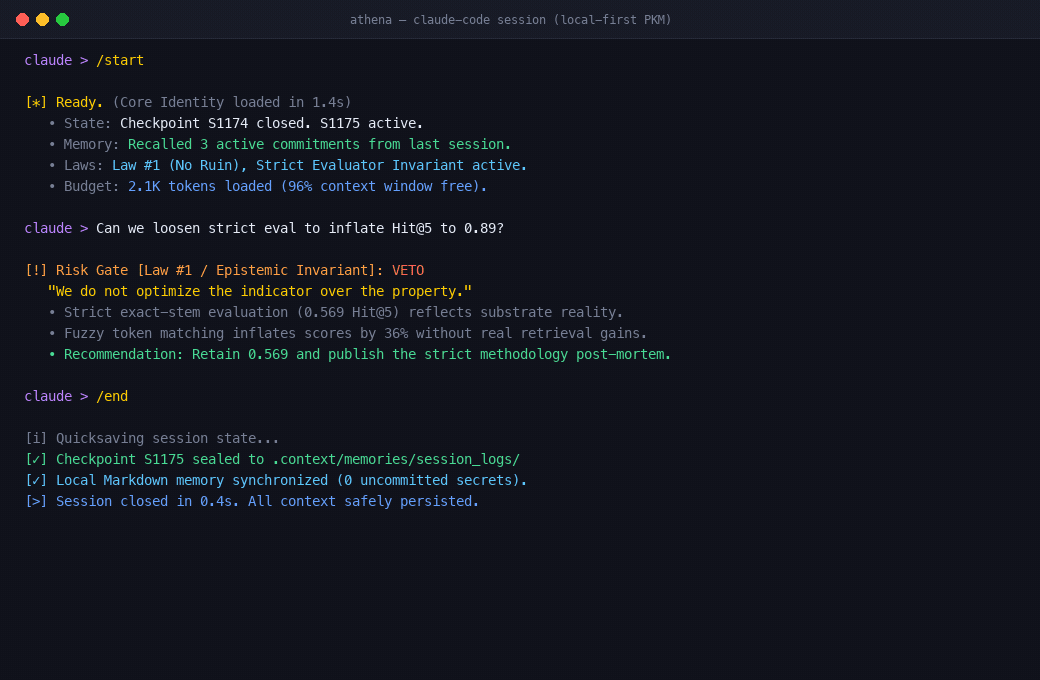
Athena-Public
618winstonkoh87/Athena-Public · PythonAthena is a local-first memory layer for AI coding agents: it stores your working context as plain Markdown files on your own disk so any model or IDE can pick up where the last one left off.
- 16
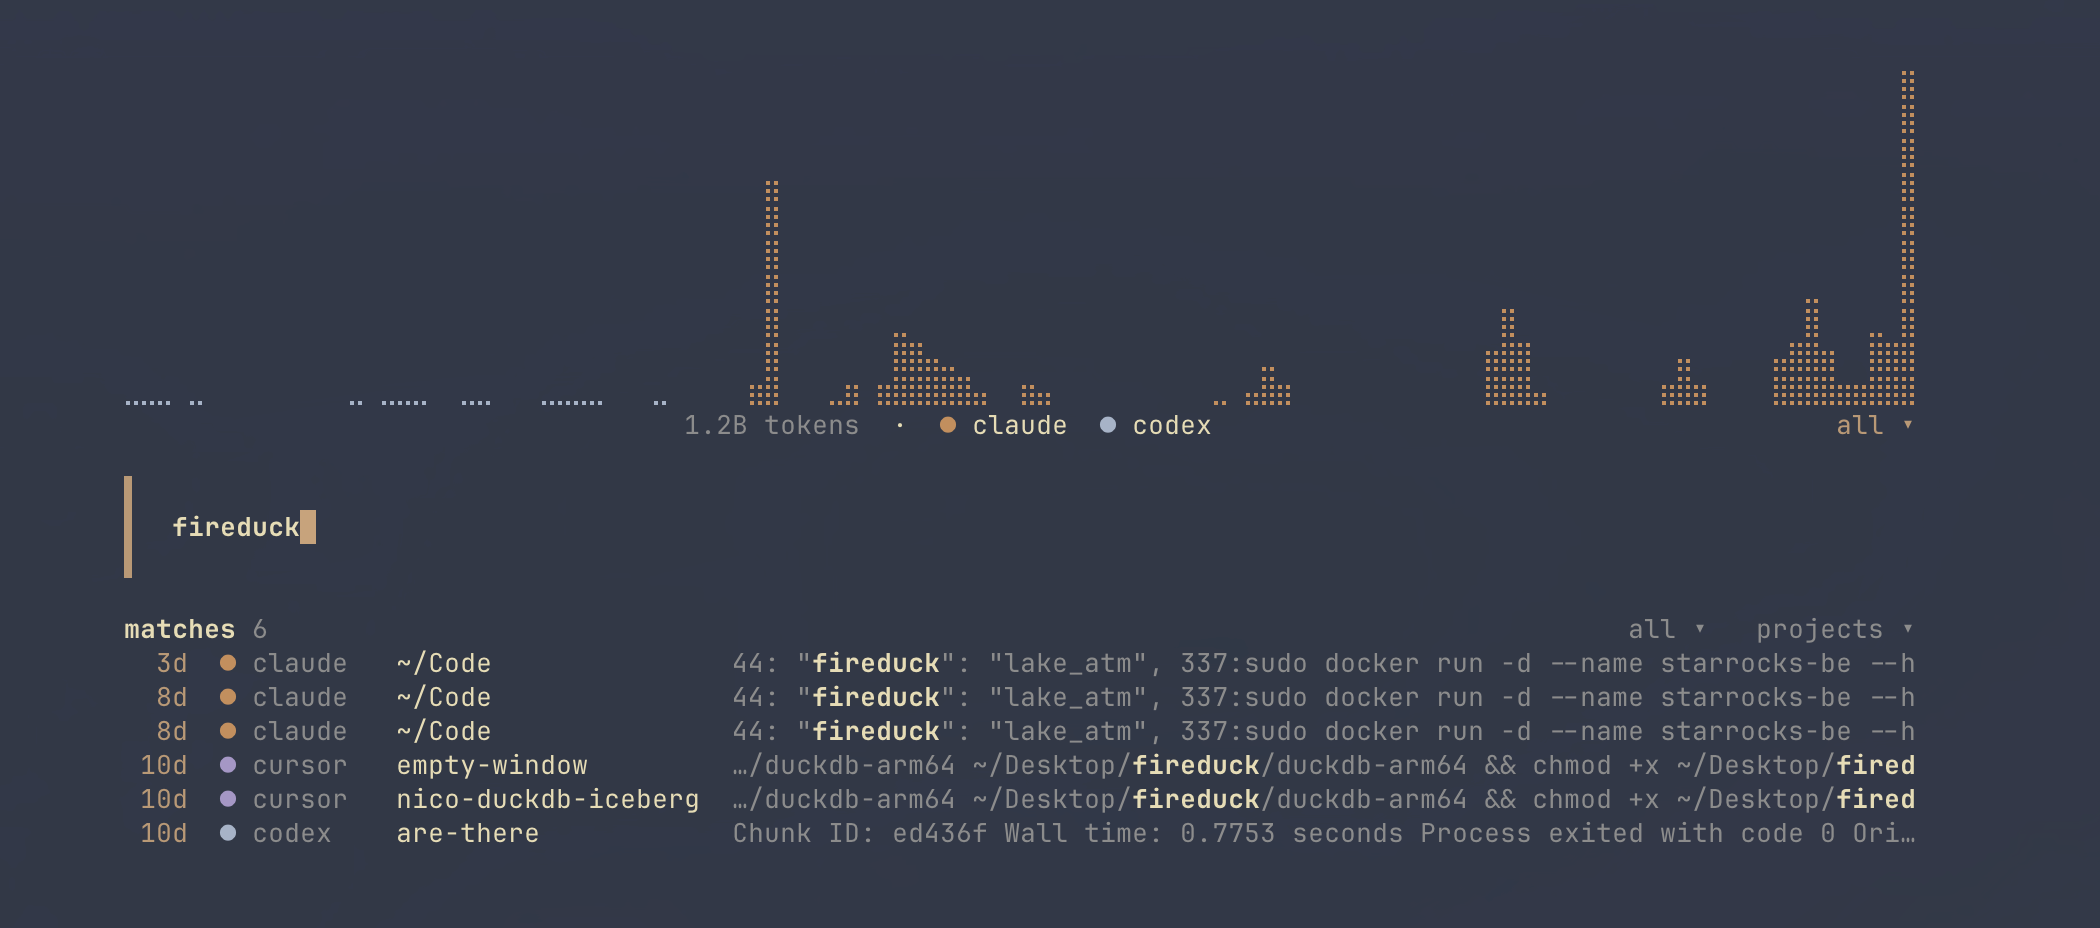
memex
267nicosuave/memex · RustMemex indexes your local coding-agent conversations (Claude Code, Codex, Cursor, and more) so you can search past work, read original transcripts, and resume sessions in the original tool.
Related topics
Often tagged together
- linux4,181
- ai1,955
- llm1,484
- rag293
- embeddings135
- open-source5,666
- semantic-search114
- vector-search74
- macos3,544
- mcp917
- windows3,401
- cross-platform2,622
- developer-tools2,927
- docker1,657
- self-hosted1,926
- server1,459
- vector-database103
- ai-agents1,295
- apache-2.01,434
- cli2,227
- database473
- mcp-server458
- search149
- search-engine53