What is this?
 Qwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
Is this a chatbot app or just raw model weights I have to serve myself?It is just released model weights, not a packaged app. You download them from Hugging Face Hub or ModelScope and run them with an inference framework such as transformers, vLLM, SGLang or llama.cpp.
It is just released model weights, not a packaged app. You download them from Hugging Face Hub or ModelScope and run them with an inference framework such as transformers, vLLM, SGLang or llama.cpp.How do I get it running locally?Download the weights with huggingface download or git clone (or modelscope download), then launch a server with the transformers serve CLI, vLLM, or SGLang to get an OpenAI-compatible API endpoint.
Download the weights with huggingface download or git clone (or modelscope download), then launch a server with the transformers serve CLI, vLLM, or SGLang to get an OpenAI-compatible API endpoint.What hardware or framework do I need to run it?You need a serving framework such as transformers, vLLM, SGLang, llama.cpp, MLX (Apple Silicon) or Unsloth, plus enough GPU memory for a 125B-parameter MoE model with 6B parameters active per token.
You need a serving framework such as transformers, vLLM, SGLang, llama.cpp, MLX (Apple Silicon) or Unsloth, plus enough GPU memory for a 125B-parameter MoE model with 6B parameters active per token.Can I run the full model on a single consumer GPU?Not in full precision - it's a 125B-parameter MoE model meant to be served through frameworks like vLLM or SGLang on serious hardware, though GGUF quantized builds for llama.cpp and MLX quantized builds for Apple Silicon are available for lighter setups.
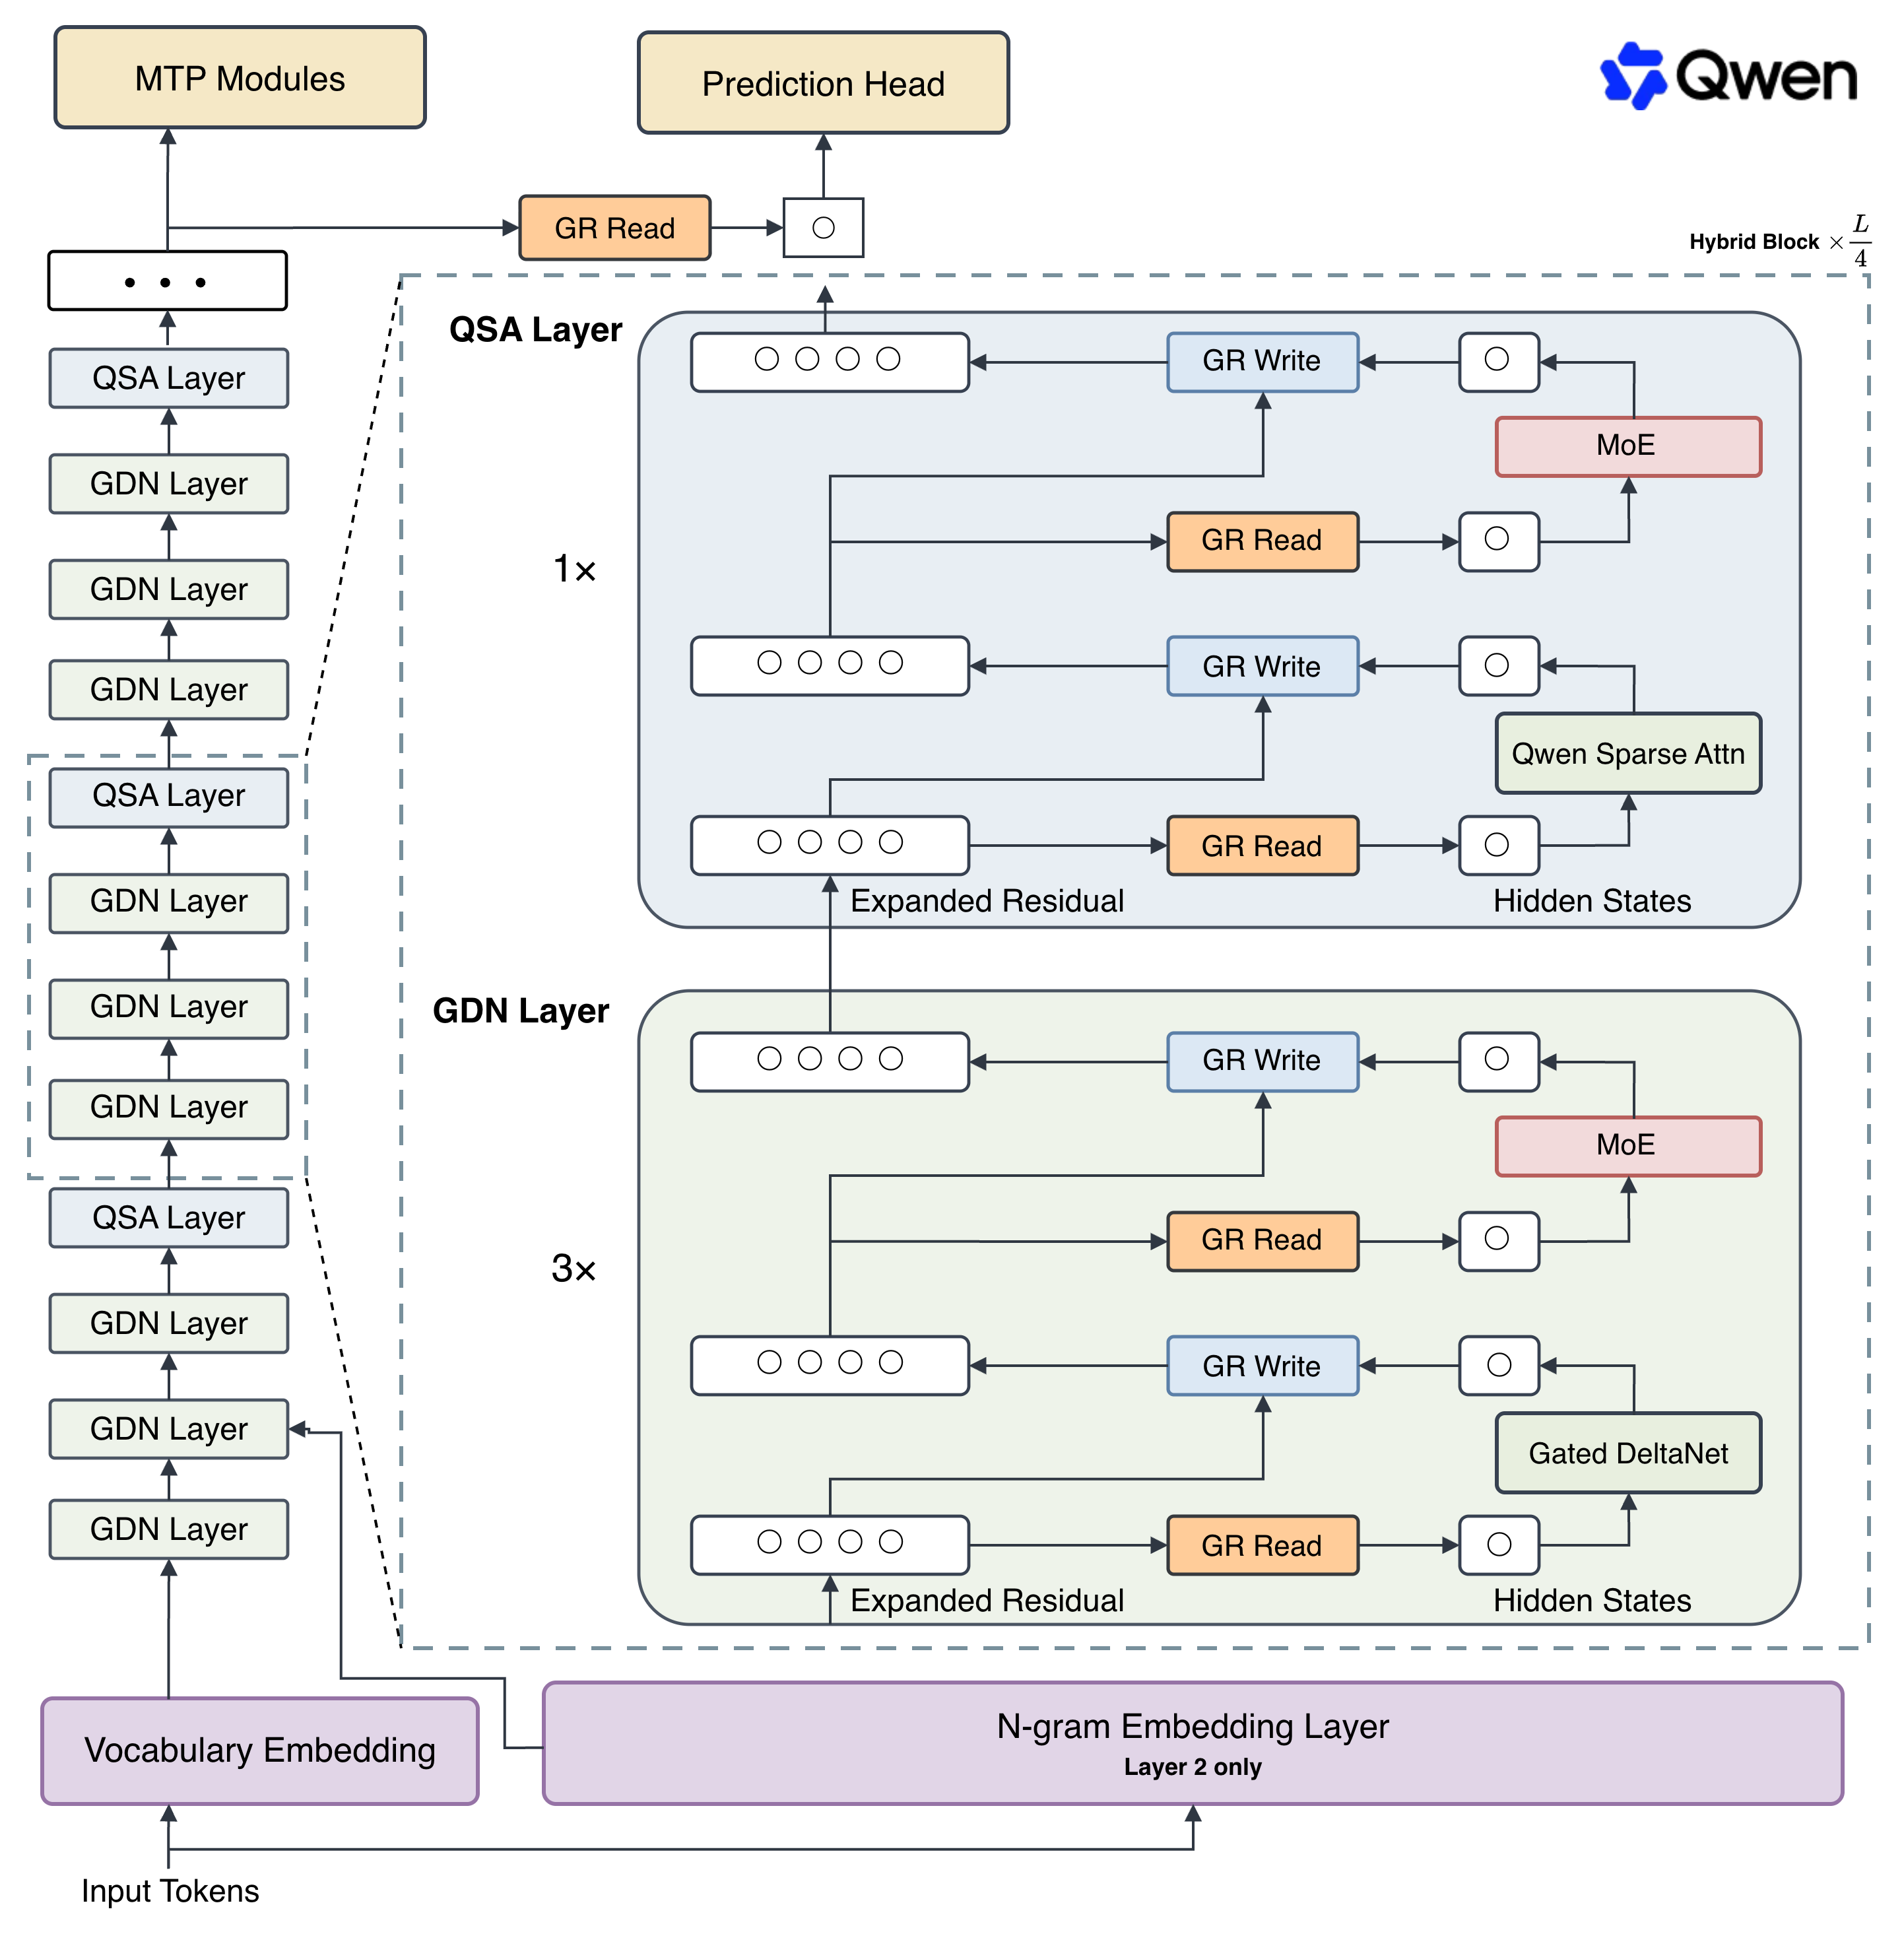
Not in full precision - it's a 125B-parameter MoE model meant to be served through frameworks like vLLM or SGLang on serious hardware, though GGUF quantized builds for llama.cpp and MLX quantized builds for Apple Silicon are available for lighter setups.What makes the architecture different from earlier Qwen models?It upgrades attention with a Gated DeltaNet + Qwen Sparse Attention hybrid, widens the residual stream into 4 gated branches (Gated Residual), adds an N-gram Embedding table to cheaply scale capacity, and trains with the Muon optimizer for better stability.
It upgrades attention with a Gated DeltaNet + Qwen Sparse Attention hybrid, widens the residual stream into 4 gated branches (Gated Residual), adds an N-gram Embedding table to cheaply scale capacity, and trains with the Muon optimizer for better stability.Can I try it without hosting it myself?Yes - it powers the new 'Standard' mode on QwenWork, is available through the OpenAI/Anthropic-compatible Qwen API on QwenCloud, and can be used via the Qwen Code terminal agent.
Yes - it powers the new 'Standard' mode on QwenWork, is available through the OpenAI/Anthropic-compatible Qwen API on QwenCloud, and can be used via the Qwen Code terminal agent.How does it compare to Qwen3.7-Plus?Training costs only about 1/9 as much as Qwen3.7-Plus while delivering superior coding and office-task capabilities.
Training costs only about 1/9 as much as Qwen3.7-Plus while delivering superior coding and office-task capabilities.Can I fine-tune this model myself?Yes, the README recommends training frameworks like Unsloth, Swift, or Llama-Factory to fine-tune it with SFT, DPO, or GRPO.
Yes, the README recommends training frameworks like Unsloth, Swift, or Llama-Factory to fine-tune it with SFT, DPO, or GRPO.What are similar projects?Qwen3.8, vllm, Qwen3, unsloth, StartLux-Decision, Hy4-preview, airllm, jeeves
Qwen3.8, vllm, Qwen3, unsloth, StartLux-Decision, Hy4-preview, airllm, jeevesWhich topics is it in?dpo, sft, grpo, qwen3, alibaba, open-weights, model, mlx, foundation-models, inference-engine, mixture-of-experts, attention-mechanism
dpo, sft, grpo, qwen3, alibaba, open-weights, model, mlx, foundation-models, inference-engine, mixture-of-experts, attention-mechanism