Topics / #data-processing
Data-processing projects on GitHub
Frameworks and utilities for transforming and processing data at scale.
As of , the most-starred Data-processing projects on GitHub are scrapy (64.9K stars), pathway (62.1K stars) and pandas (50.1K stars). GitHub.Locker tracks 28 Data-processing repositories with 543.5K stars combined. The fastest-growing on October 16 was mihomo, with +29 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +29
mihomo
MetaCubeX/mihomo · ★ 34.9KIt is a Python library built on Pydantic that models and parses the data returned by the Mihomo API for Honkai: Star Rail, giving you typed, autocomplete-friendly access to a player's parsed character and showcase info.
 +20
scrapy
scrapy/scrapy · ★ 64.9KScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
 +15
pandas
pandas-dev/pandas · ★ 50.1Kpandas is a Python library providing fast, flexible data structures (Series and DataFrame) for working with labeled/relational data, aiming to be the fundamental building block for practical data analysis in Python.
 +7
polars
pola-rs/polars · ★ 40.1KPolars is an extremely fast analytical query engine for DataFrames, written in Rust and designed to be fast, easy to use and expressive.
The all-time top
28 projects · by stars
- 64.9K#1 · scrapy/scrapy
scrapy
Scrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 62.1K
 #2 · pathwaycom/pathway
pathway
Pathway is a Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG, with the same code usable for batch jobs, CI/CD tests, and live data streams.
- 50.1K#3 · pandas-dev/pandas
pandas
pandas is a Python library providing fast, flexible data structures (Series and DataFrame) for working with labeled/relational data, aiming to be the fundamental building block for practical data analysis in Python.
- 4
polars
40.1Kpola-rs/polars · RustPolars is an extremely fast analytical query engine for DataFrames, written in Rust and designed to be fast, easy to use and expressive.
- 5

sheetjs
36.3KSheetJS/sheetjsSheetJS Community Edition is an open-source JavaScript toolkit for spreadsheet data: it extracts useful data from almost any complex spreadsheet and generates new spreadsheets that work with legacy and modern software alike.
- 6
mihomo
34.9KMetaCubeX/mihomo · PythonIt is a Python library built on Pydantic that models and parses the data returned by the Mihomo API for Honkai: Star Rail, giving you typed, autocomplete-friendly access to a player's parsed character and showcase info.
- 7
flink
26.4Kapache/flink · JavaApache Flink is an open source stream processing framework with powerful stream- and batch-processing capabilities, running your programs on its own distributed runtime.
- 8

pydata-book
25Kwesm/pydata-book · Jupyter NotebookThis is the companion repository of Jupyter notebooks and materials for the book 'Python for Data Analysis' by Wes McKinney, covering pandas, NumPy, and data analysis techniques.
- 9

normalizr
20.8Kpaularmstrong/normalizr · JavaScriptNormalizr is an open-source JavaScript library that normalizes nested JSON according to a schema you define: hand it a deeply nested API response and it returns a flat, normalized structure. It is typically used in React, Redux and Flux apps.
- 10

luigi
18.8Kspotify/luigi · PythonLuigi is a Python package for building complex pipelines of batch jobs. It handles dependency resolution, workflow management, visualization, failure handling and command line integration.
- 11

rocketride-server
17.8Krocketride-org/rocketride-server · PythonAn open-source AI Development Environment: a data pipeline builder and runtime for AI/ML workloads. It turns the IDE you already use into one place to compose, debug, observe, and deploy AI workflows on a multithreaded C++ engine.
- 12
arrow
17.2Kapache/arrow · C++Apache Arrow is a universal columnar format plus a multi-language toolbox for fast data interchange and in-memory analytics — technologies that let data systems store, process, and move tabular data efficiently.
- 13
hadoop
15.7Kapache/hadoop · JavaApache Hadoop is the open-source big data platform for reliable, distributed storage and processing of very large data sets across clusters of machines.
- 14

exceljs
15.5Kexceljs/exceljs · JavaScriptExcelJS is a JavaScript library for reading, manipulating and writing Excel spreadsheets — data and styles — in XLSX and JSON. It was built by reverse engineering real Excel spreadsheet files.
- 15

logstash
15Kelastic/logstash · JavaLogstash is a server-side data processing pipeline, part of the Elastic Stack, that ingests data from many sources at once, transforms it, and sends it to a destination like Elasticsearch.
- 16

PapaParse
13.6Kmholt/PapaParse · JavaScriptPapa Parse is a fast CSV (delimited text) parser for JavaScript that runs in the browser. It is RFC 4180 compliant and handles large files and malformed input gracefully.
- 17

cocoindex
11.7Kcocoindex-io/cocoindex · RustCocoIndex is an incremental engine that turns codebases, meeting notes, inboxes, Slack, PDFs, and videos into live, continuously fresh context for AI agents and LLM apps, using minimal incremental processing instead of stale batch jobs.
- 18
prql
10.9KPRQL/prql · RustPRQL (pronounced 'Prequel') is a modern language for transforming data — a simple, powerful, pipelined replacement for SQL.
- 19

Bash-Oneliner
10.8Konceupon/Bash-OnelinerA curated collection of handy Bash one-liners and terminal tricks for data processing and Linux system maintenance, covering variables, grep, sed, awk, xargs, find, and more.
- 20

xsv
10.8KBurntSushi/xsv · Rustxsv is a fast command-line toolkit written in Rust for working with CSV files: it indexes, slices, analyzes, splits and joins them right in the terminal.
- 21
modin
10.4Kmodin-project/modin · PythonModin is a drop-in replacement for pandas: you keep the same API and syntax, but your workflows run on all of your CPU cores instead of a single thread. Change one import line and your existing pandas code just runs faster.
- 22
miller
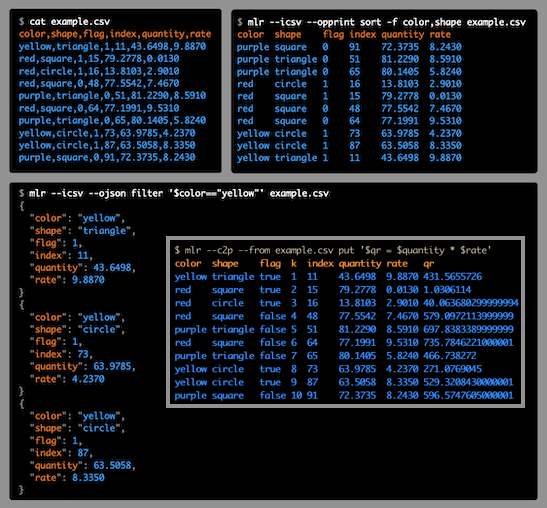
10Kjohnkerl/miller · GoMiller is a command-line toolkit like awk, sed, cut, join, and sort, but built for name-indexed data such as CSV, TSV, JSON, and JSON Lines: you address fields by name instead of counting column positions.
- 23

gigatoken
4.1Kmarcelroed/gigatoken · RustGigatoken is an extremely fast tokenizer for language models, built as a near drop-in replacement for HuggingFace Tokenizers and tiktoken, encoding text at multi-GB/s speeds.
- 24

SolidityScanLegend
118whitakeroliver/SolidityScanLegend · PHPSolidityScanLegend is described as a tool for real-time, high-performance data extraction and analysis built on a scalable, auto-scaling architecture with efficient query processing.
- 25

NFTAPIInfinite
117lgomesappj/NFTAPIInfinite · JavaScriptNFTAPIInfinite is described as a simple real-time system built for real-time processing, aimed at developers who want a straightforward, dependable backend solution.
- 26

MetaBridgeDiamond
114minseochoj/MetaBridgeDiamond · PHPMetaBridgeDiamond is a lightweight tool described as enabling high-performance real-time data processing and auto-scaling, deploying scalable agents as a 'robust manager'.
- 27

roster-match
104charlenemercury/roster-match · JavaScriptA zero-dependency JavaScript library that matches a Chinese name heard through speech recognition (or any garbled transcript) to the correct entry in a roster, comparing by pinyin syllables and surfacing candidates with reasons instead of forcing a decision when it is unsure.
- 28

BloomBeacon
83vinamega/BloomBeacon · PythonBloomBeacon is a Python tool for real-time data processing and auto-scaling of cloud-based systems, built to be cloud-agnostic rather than tied to one provider.
Related topics
Often tagged together