Topics / #vector-search
Vector-search projects on GitHub
Finding similar items by comparing embedding vectors, often approximate nearest neighbor.
As of , the most-starred Vector-search projects on GitHub are elasticsearch (78.3K stars), redis (76.9K stars) and ruflo (75.8K stars). GitHub.Locker tracks 74 Vector-search repositories with 1.4M stars combined. The fastest-growing on October 16 was xerj, with +1.2K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +1.2K
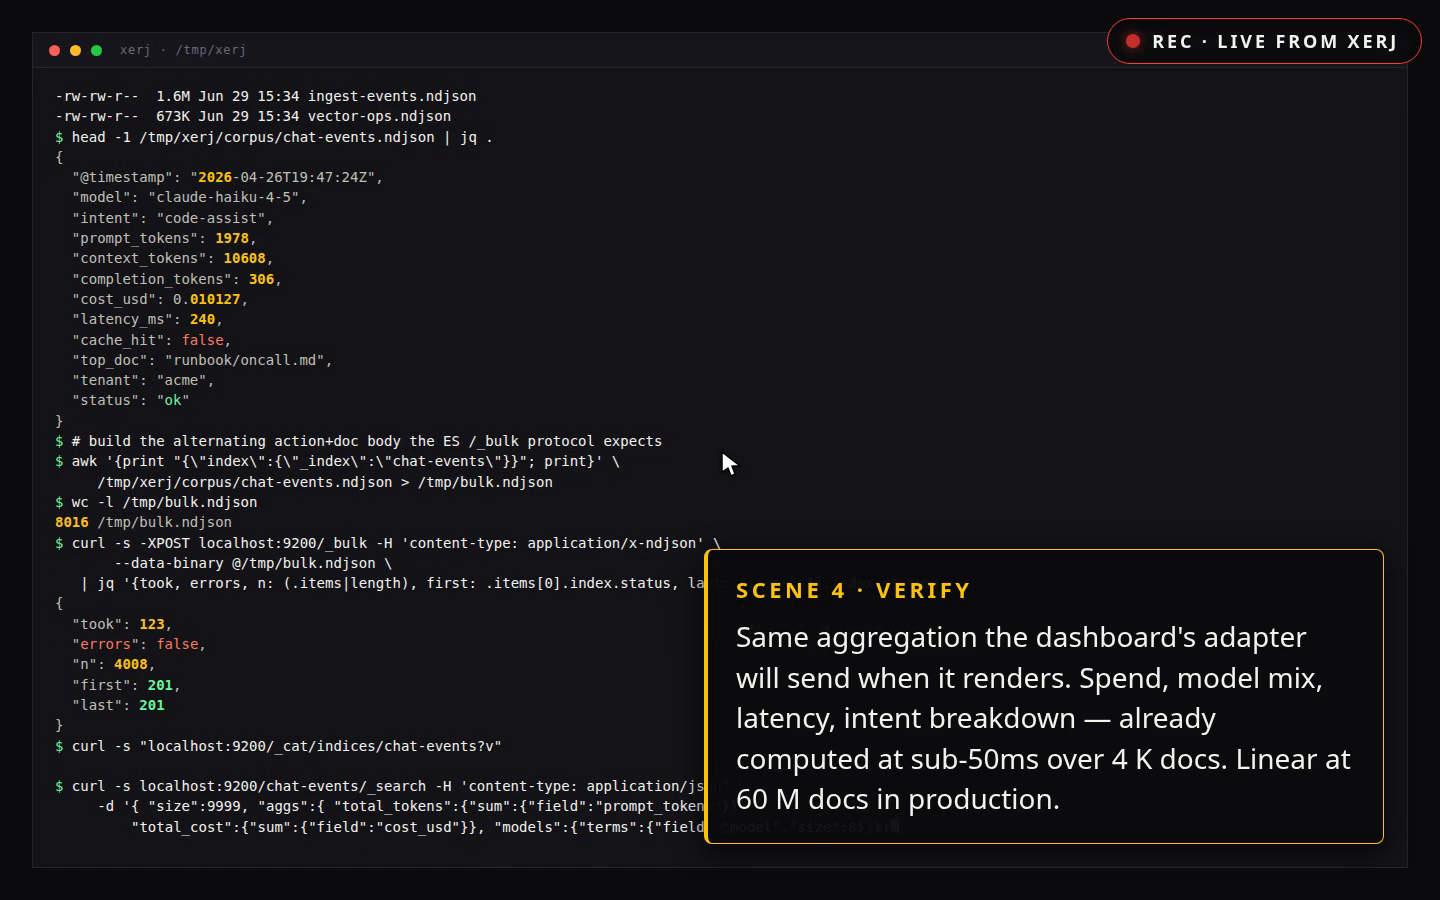
xerj
xerj-org/xerj · ★ 6.9KXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
 +461
ruflo
ruvnet/ruflo · ★ 75.8KRuflo is an agent meta-harness for Claude Code and Codex: it adds 100+ specialized agents, coordinated swarms, self-learning memory, and cross-machine federation on top of those coding agents so they can collaborate instead of running solo.
 +215
DigUp
ARahim3/DigUp · ★ 4.3KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
 +171
TencentDB-Agent-Memory
TencentCloud/TencentDB-Agent-Memory · ★ 29.5KA team-level memory hub for AI agents. It turns conversations, docs, and code into four reusable memory assets — Chat Memory, Skills, Wiki, and CodeGraph — that agents across a team can share, govern, and equip.
The all-time top
74 projects · by stars
- 78.3K
 #1 · elastic/elasticsearch
elasticsearch
Elasticsearch is a distributed search and analytics engine, scalable data store, and vector database built for near real-time full-text search, vector search, and generative AI (RAG) use cases on production-scale data; it's the core of Elastic's Stack platform.
- 76.9K
 #2 · redis/redis
redis
Redis is an in-memory server used as a cache, data structure store, and document/vector query engine for building real-time, data-driven applications.
- 75.8K#3 · ruvnet/ruflo
ruflo
Ruflo is an agent meta-harness for Claude Code and Codex: it adds 100+ specialized agents, coordinated swarms, self-learning memory, and cross-machine federation on top of those coding agents so they can collaborate instead of running solo.
- 4

meilisearch
59.6Kmeilisearch/meilisearch · RustMeilisearch is a fast, open-source search engine that adds AI-powered hybrid search (combining full-text and semantic search) to websites and apps.
- 5

serviette
58.8Kpathwaycom/serviette · PythonThis repo provides ready-to-run cloud templates for RAG pipelines, AI pipelines, and enterprise search, built on the Pathway Live Data Framework and kept in sync with live data sources.
- 6
milvus
46.4Kmilvus-io/milvus · GoMilvus is a high-performance, cloud-native vector database built to store and search embedding vectors at scale for AI applications like semantic search, RAG, and recommendation systems.
- 7

faiss
41.2Kfacebookresearch/faiss · C++Faiss is a library for efficient similarity search and clustering of dense vectors, developed primarily at Meta's Fundamental AI Research group. It can search collections of vectors of any size, even ones that do not fit in RAM.
- 8
tidb
40.6Kpingcap/tidb · GoTiDB is an open-source, cloud-native distributed SQL database written in Go — MySQL-compatible and built for high availability, horizontal scalability, strong consistency, and mixing transactions with analytics.
- 9
LightRAG
40.2KHKUDS/LightRAG · PythonLightRAG is an open-source, graph-based RAG framework (EMNLP 2025) by HKUDS. It indexes your documents into a knowledge graph plus vector embeddings so you can query them — a lighter, faster alternative to Microsoft GraphRAG.
- 10
quivr
39.6KThe-Vibe-Company/quivr · GoQuivr is an open-source engine that turns your files and content streams into search and monitoring — a 'second brain' you can query, built around an opinionated RAG powered by generative AI.
- 11
PageIndex
39.2KVectifyAI/PageIndex · PythonPageIndex is a vectorless, reasoning-based RAG (Retrieval-Augmented Generation) engine. Instead of a vector database and chunking, it builds a hierarchical tree index that mirrors a document's structure and lets an LLM reason its way through that tree to find relevant sections, the way a human expert flips to the right part of a report.
- 12

qdrant
35.1Kqdrant/qdrant · RustQdrant is a high-performance vector similarity search engine and vector database written in Rust, built to store, search, and manage 'points' (vectors plus a JSON payload) for AI applications like semantic search, recommendations, and RAG.
- 13

WeKnora
34.4KTencent/WeKnora · GoWeKnora is an open-source, self-hosted knowledge platform that turns raw documents into a queryable RAG knowledge base, an autonomous ReAct agent, and a self-maintaining Wiki with an interactive knowledge graph.
- 14
onyx
32.5Konyx-dot-app/onyx · PythonOnyx is an open source AI platform that gives you a full-featured chat interface on top of any LLM, with built-in RAG, web search, agents, and more.
- 15

dragonfly
31.8Kdragonflydb/dragonfly · C++An in-memory data store built as a modern replacement for Redis and Memcached — fully compatible with both APIs, so no code changes needed; it claims 25X more throughput on up to 80% fewer resources.
- 16

qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 17

chroma
29.5Kchroma-core/chroma · RustChroma is open-source data infrastructure for AI: a vector database that powers search for embeddings, used for things like retrieval-augmented generation (RAG) and AI agent memory.
- 18
TencentDB-Agent-Memory
29.5KTencentCloud/TencentDB-Agent-Memory · TypeScriptA team-level memory hub for AI agents. It turns conversations, docs, and code into four reusable memory assets — Chat Memory, Skills, Wiki, and CodeGraph — that agents across a team can share, govern, and equip.
- 19
Resume-Matcher
28.7Ksrbhr/Resume-Matcher · PythonResume Matcher is a free, open-source AI harness for tailoring your resume to each job application, working with Claude, ChatGPT, DeepSeek, Kimi, GLM, Gemma and other LLMs, both local and remote.
- 20

typesense
27Ktypesense/typesense · C++An open-source, typo-tolerant in-memory search engine for building fast search experiences — a self-hostable Algolia alternative and an easier-to-use Elasticsearch alternative.
- 21
RAG-Anything
23.6KHKUDS/RAG-Anything · PythonAn all-in-one multimodal RAG framework built on LightRAG: it ingests real-world documents that mix text, images, tables and equations, then answers queries across all content types through one pipeline instead of separate specialized tools.
- 22

pgvector
23.4Kpgvector/pgvector · Cpgvector is an open-source extension that adds vector similarity search to Postgres, so embeddings are stored and queried right next to your relational data. It supports exact and approximate nearest neighbor search.
- 23

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 24
llm_wiki
20.7Knashsu/llm_wiki · TypeScriptLLM Wiki is a cross-platform desktop app that turns your documents into a persistent, interlinked knowledge base. Instead of re-deriving answers from scratch every time like traditional RAG, the LLM incrementally builds and keeps a wiki of your sources up to date.
- 25
Toonflow-app
18KHBAI-Ltd/Toonflow-app · TypeScriptToonflow is an open-source AI workbench for producing short dramas and motion comics: scriptwriting, storyboarding, character and scene assets, and image and video generation chained into one pipeline on an infinite canvas.
- 26
turbovec
17.4KRyanCodrai/turbovec · RustA vector index for nearest-neighbor search over embeddings, written in Rust with Python bindings. It is built on Google Research's TurboQuant quantization and aimed at RAG where memory, latency and privacy matter.
- 27
weaviate
16.9Kweaviate/weaviate · GoWeaviate is an open-source, cloud-native vector database: it stores objects and vectors together and lets you combine vector search with structured filtering for semantic search at scale.
- 28
memvid
16.6Kmemvid/memvid · RustMemvid is a single-file memory layer for AI agents: it packs your data, embeddings and search index into one portable .mv2 file, so agents get instant retrieval and long-term memory without a RAG pipeline or a vector database server.
- 29

doris
16.1Kapache/doris · JavaApache Doris is an open-source, real-time analytics and search database built on MPP architecture. It serves fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
- 30

annoy
14.3Kspotify/annoy · C++Annoy (Approximate Nearest Neighbors Oh Yeah) is a C++ library with Python bindings that finds the points in space closest to a given query point. It is optimized for memory usage and for saving and loading indexes to disk.
- 31
QAnything
14.2Knetease-youdao/QAnything · PythonA local knowledge base question-answering system: load your own documents into it and ask questions — you get accurate answers drawn from your files instead of the open web.
- 32
redis-py
13.7Kredis/redis-py · Pythonredis-py is the official Python client for the Redis key-value store — the interface your Python code uses to talk to a Redis server.
- 33
LEANN
13KStarTrail-org/LEANN · PythonLEANN is a vector database that lets you run retrieval-augmented generation (RAG) over millions of personal documents on your own laptop using 97% less storage than traditional vector databases, with no accuracy loss.
- 34
txtai
13Kneuml/txtai · Pythontxtai is an all-in-one AI framework for semantic search, LLM orchestration and language model workflows. Its core is an embeddings database that combines vector indexes, graph networks and relational databases to power search or serve as a knowledge source for LLM apps.
- 35
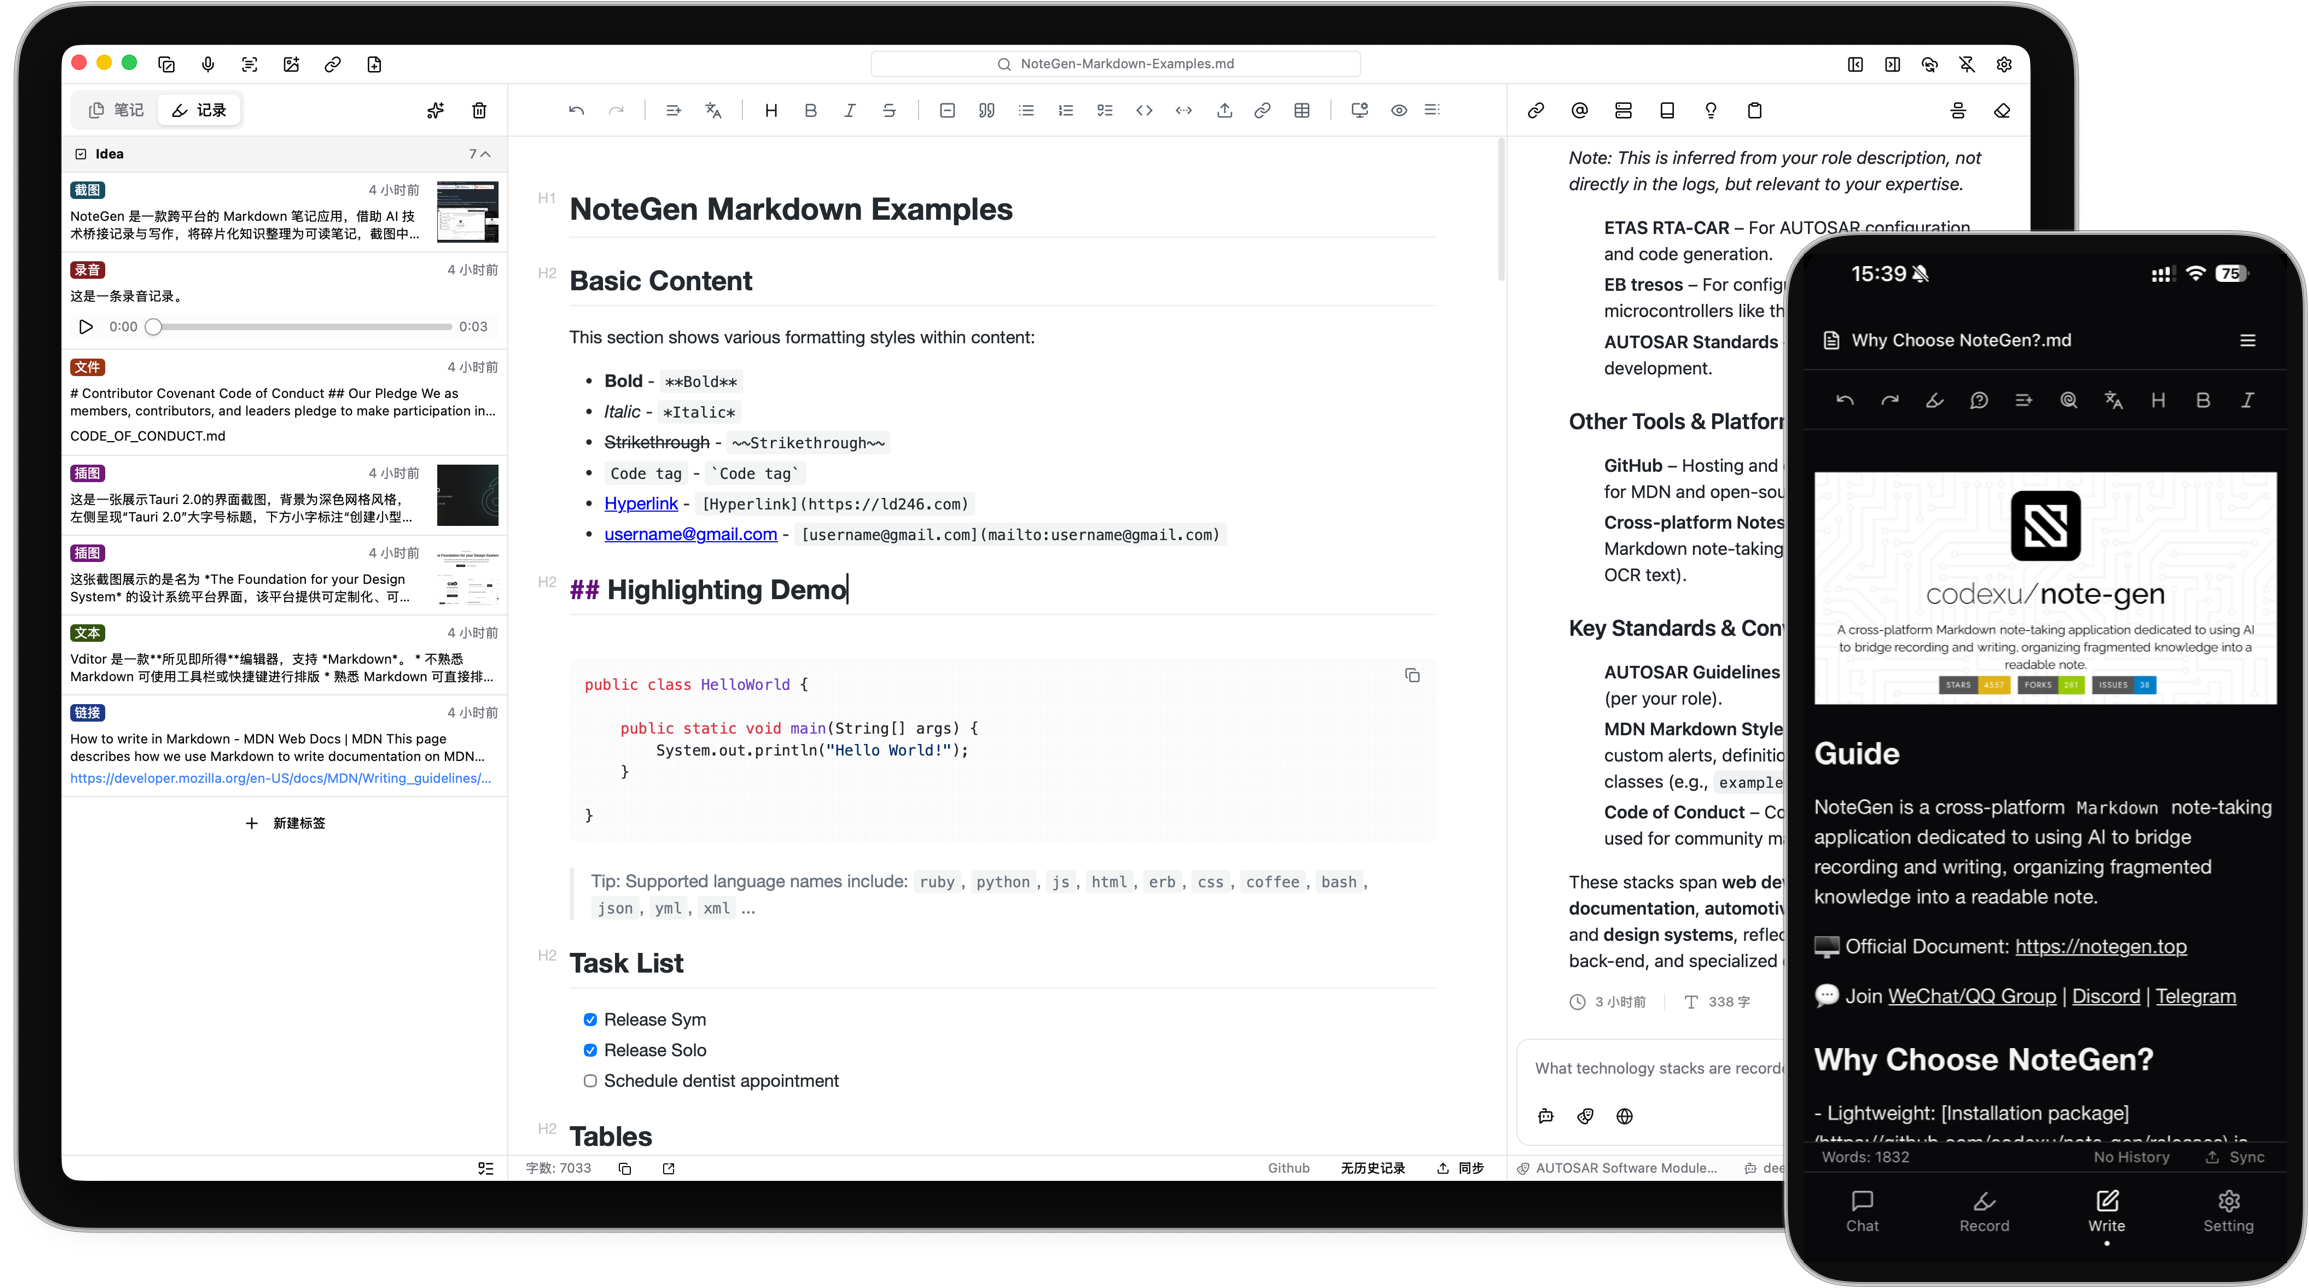
note-gen
12.9Kcodexu/note-gen · TypeScriptNoteGen is a local-first Markdown note app that lets you quickly capture scattered fragments like text, voice recordings, screenshots, links, or files, then use AI later to organize them into structured notes.
- 36
clip-as-service
12.8Kjina-ai/clip-as-service · PythonCLIP-as-service is a low-latency, high-scalability service for embedding images and text with CLIP models, so you can plug it into neural search or cross-modal retrieval apps as a microservice.
- 37
claude-context
12.6Kzilliztech/claude-context · TypeScriptClaude Context is an MCP server that gives AI coding agents semantic search over your entire codebase, so they can pull relevant code straight into context instead of loading whole directories.
- 38
FlagEmbedding
12.3KFlagOpen/FlagEmbedding · PythonFlagEmbedding (BGE) is a one-stop toolkit from BAAI for retrieval and retrieval-augmented LLMs, providing embedding models, rerankers, finetuning scripts, and evaluation tools for search and RAG.
- 39
manticoresearch
12.1Kmanticoresoftware/manticoresearch · C++Manticore Search is an open-source search database built for full-text, vector, and hybrid search with real-time indexing and SQL support. It's positioned as a fast, cost-efficient alternative to Elasticsearch.
- 40

garnet
12.1Kmicrosoft/garnet · C#Garnet is a remote cache-store from Microsoft Research: a key-value server that existing Redis clients can talk to, built for high throughput, low latency, persistence, and cluster sharding.
- 41

bleve
11.2Kblevesearch/bleve · GoBleve is a modern full-text, numeric, geo-spatial, and vector indexing and search library written in Go, inspired by Apache Lucene.
- 42
fiftyone
11.2Kvoxel51/fiftyone · TypeScriptFiftyOne is an open-source tool for building high-quality datasets and computer vision models: you use it to visualize and label your visual data, evaluate models, and find and fix data quality issues.
- 43

orama
10.6Koramasearch/orama · TypeScriptOrama is a complete search engine and RAG pipeline that runs in your browser, on a server or at the edge, with support for full-text, vector and hybrid search.
- 44

oceanbase
10.3Koceanbase/oceanbase · C++OceanBase Database is a distributed relational database developed entirely by Ant Group. It runs on a cluster of commodity servers and uses Paxos to provide high availability and linear scalability.
- 45

PixelRAG
10.3KStarTrail-org/PixelRAG · PythonAn open-source research codebase from Berkeley for pixel-native search: PixelRAG renders web pages, PDFs and images as screenshots and retrieves over the images directly, instead of parsing pages into text.
- 46
production-agentic-rag-course
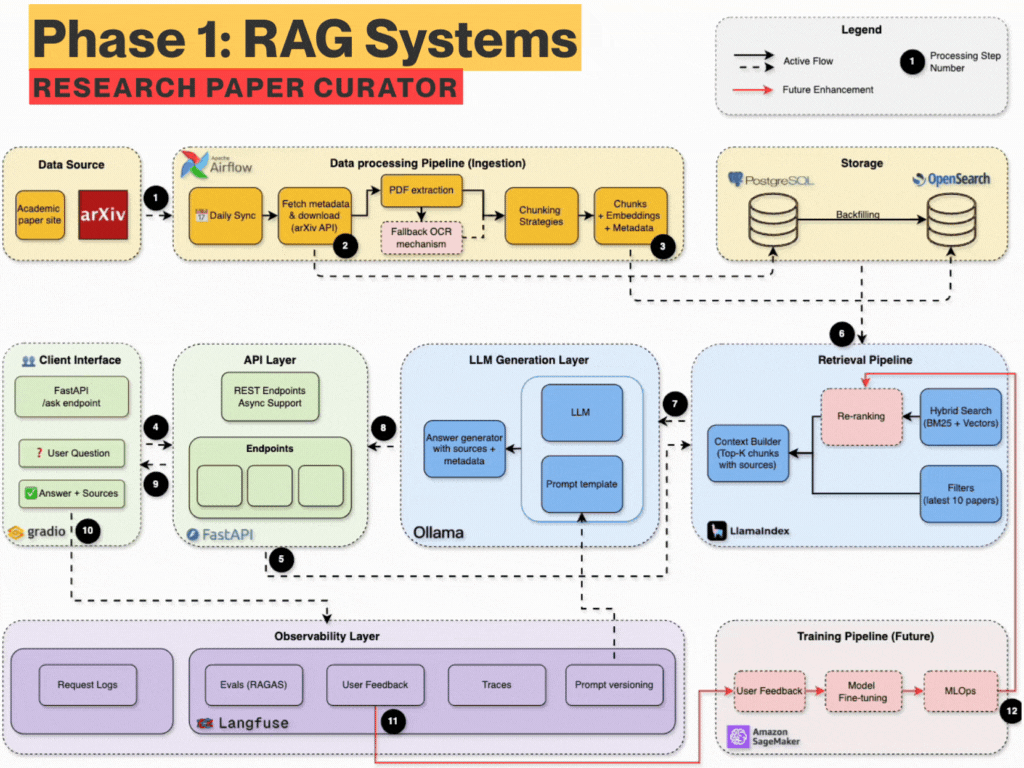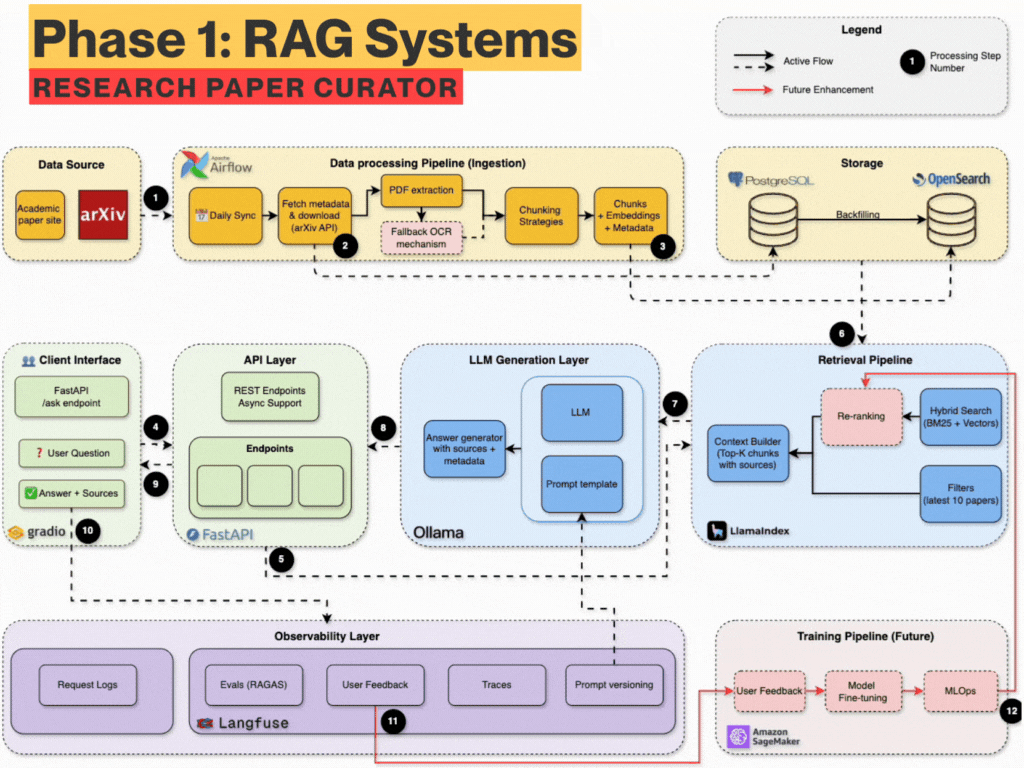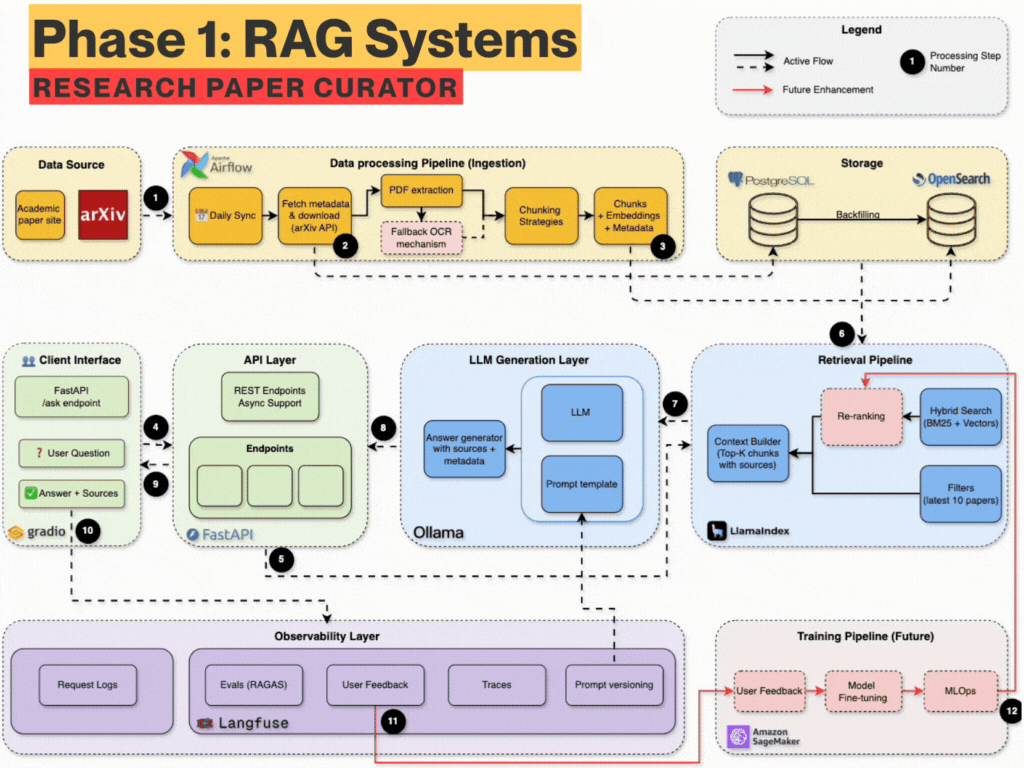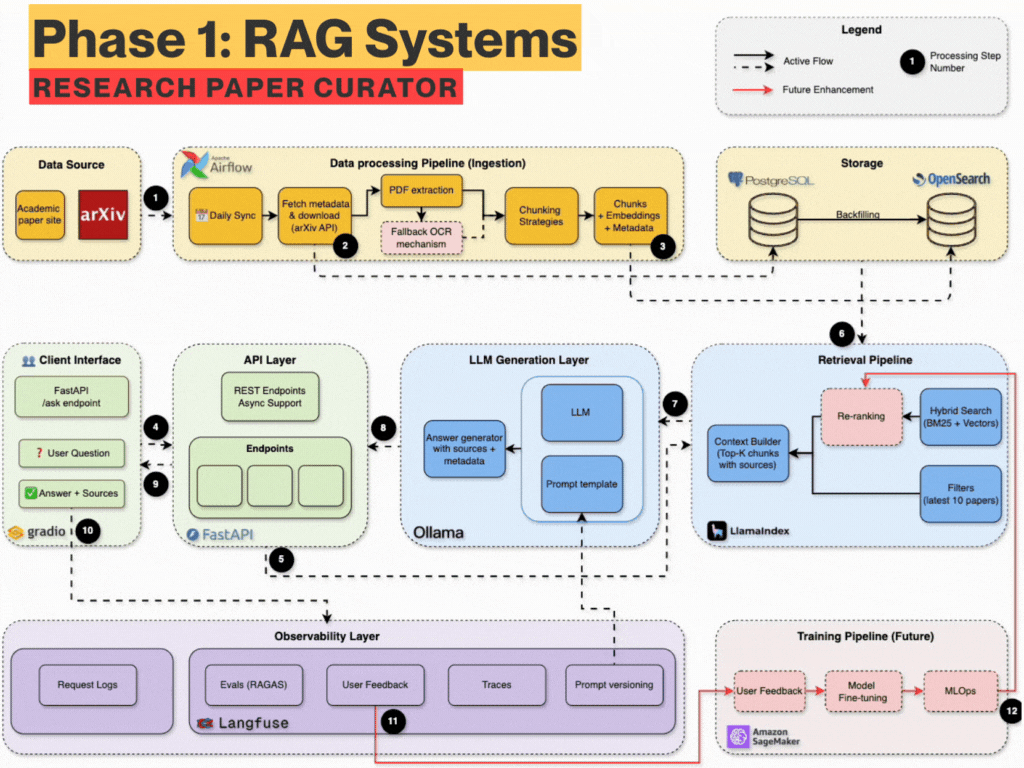
9.8Kjamwithai/production-agentic-rag-course · PythonThis is a hands-on, week-by-week course that teaches you to build 'arXiv Paper Curator', a production-grade Retrieval-Augmented Generation (RAG) system that fetches academic papers, indexes them, and answers research questions about them.
- 47
clawhub
9.5Kopenclaw/clawhub · TypeScriptClawHub is the public skill registry for OpenClaw: a place to publish, version, and search text-based agent skills (a SKILL.md plus supporting files), plus a catalog of OpenClaw code and bundle plugins.
- 48
utopia
8.4Kdeeplethe/utopia · RustUtopia is an open-source enterprise world model from DeepLethe: a self-hosted knowledge system that turns documents into a bitemporal knowledge graph you can search, chat with and reason over, running entirely on hardware you control.
- 49
AIHOT
7.9KKKKKhazix/AIHOT · TypeScriptAIHOT is a framework for building an AI-curated news site: it pulls items from your sources, has an LLM filter and score each one twice, writes Chinese headlines and summaries, clusters reports of the same story into one event, ranks events by how many independent sources cover them, and publishes a daily briefing.
- 50
MemoryBear
7.8KSuanmoSuanyangTechnology/MemoryBear · PythonMemoryBear is an AI memory system that gives AI agents human-like memory: instead of just storing knowledge statically, it perceives, extracts, associates and forgets information over time.
- 51

webnovel-writer
7.5KlingfengQAQ/webnovel-writer · PythonWebnovel Writer is a Claude Code plugin that helps you write long serialized Chinese web novels (up to roughly 2 million characters) while keeping characters, timelines, and foreshadowing consistent instead of forgetting or contradicting earlier chapters.
- 52
xerj
6.9Kxerj-org/xerj · RustXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
- 53
semble
6.2KMinishLab/semble · PythonSemble is a code search library built for coding agents. It returns the exact relevant code snippets for a query instead of making the agent grep and read full files, using about 99% fewer tokens than grep+read.
- 54
hister
6.1Kasciimoo/hister · GoHister is a private, self-hosted search engine that fully indexes the pages you visit and the files you keep, so you can search their content later from a web interface, terminal, or an AI assistant via MCP.
- 55

OB1
4.7KNateBJones-Projects/OB1 · TypeScriptOpen Brain (OB1) is an infrastructure layer that gives every AI tool you use — Claude, ChatGPT, Cursor, Claude Code, and whatever ships next — shared, persistent access to the same memory of you, through one database and one AI gateway.
- 56

m_flow
4.5KFlowElement-xinliuyuansu/m_flow · PythonM-flow is a bio-inspired cognitive memory engine that acts as a new paradigm for Graph RAG: instead of just retrieving similar text chunks, it builds a graph of memories and scores answers by the strongest chain of evidence connecting the query to the content, the way human recall works.
- 57

memory-lancedb-pro
4.5KCortexReach/memory-lancedb-pro · JavaScriptIt is a LanceDB-backed memory plugin for OpenClaw agents that stores preferences, decisions, and project context, then auto-recalls them in future sessions instead of letting the agent forget everything between chats.
- 58
DigUp
4.3KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 59
ragent
4.3Knageoffer/ragent · JavaRagent is a production-grade Java platform for Agentic RAG, covering the full chain from document ingestion to intelligent Q&A — including hybrid retrieval, query rewriting, intent recognition, session memory, MCP tool calling and deep thinking.
- 60
vault-ai
3.4Kpashpashpash/vault-ai · JavaScriptOP Vault gives ChatGPT long-term memory over your own documents: you upload a knowledge base of books, letters or PDFs and ask questions about their contents, powered by OpenAI and the Pinecone vector database.
- 61
hotdata-cli
1.8Khotdata-dev/hotdata-cli · RustHotdata CLI is a command-line client that lets you query, search, and join data from one place — external databases, APIs, cloud storage, Iceberg catalogs, and uploaded files — using plain SQL and a handful of commands.
- 62
open-glean
1.6Khydra-db/open-glean · TypeScriptOpen Glean is an open-source AI workspace built on Hydra DB: a 'second brain' you ask questions across your memories, files, and connected apps, with answers written from retrieved context and cited sources.
- 63

omnigraph
1.3KModernRelay/omnigraph · RustOmnigraph is a lakehouse-native graph database that acts as the operational state and coordination layer for fleets of AI agents, combining graph traversal, vector search, and full-text search with Git-style branching so many agents can enrich a shared knowledge graph safely.
- 64

nautilus-compass
1.3Kchunxiaoxx/nautilus-compass · Pythonnautilus-compass is an open-source memory and reliability layer for AI coding agents: it gives them long-term memory, catches cases where the agent ignores recalled rules (drift detection), and ships its own benchmark suite to verify the claims independently.
- 65

fastembed-rs
1Kanush008/fastembed-rs · RustA Rust library that generates vector embeddings and reranks results entirely locally — no external API calls. It covers dense and sparse text embeddings, image embeddings, multimodal models, and rerankers.
- 66
XRAG
807DocAILab/XRAG · PythonXRAG is a benchmarking framework that dissects and evaluates the foundational components of Retrieval-Augmented Generation (RAG) systems, such as retrievers, embeddings, and LLMs, to show how different configurations affect overall RAG performance.
- 67
SkillCorpus
686EverMind-AI/SkillCorpus · PythonSkillCorpus is EverMind's open-source pipeline that aggregates scattered SKILL.md files from public repos, applies safety/license/quality gates, and exports a curated, retrieval-ready corpus plus two fine-tuned retrieval models so agents can fetch the right skill at answer time.
- 68

Athena-Public
615winstonkoh87/Athena-Public · PythonAthena is a local-first memory layer for AI coding agents: it stores your working context as plain Markdown files on your own disk so any model or IDE can pick up where the last one left off.
- 69
witchcraft
524dropbox/witchcraft · RustWitchcraft (formerly Rust-Warp) is a from-scratch, safe-Rust reimplementation of Stanford's XTR-Warp semantic search engine that stores its index in a single-file SQLite database, built for fast, fully local client-side search.
- 70
AI-Engineering-Lab
318zorost/AI-Engineering-Lab · Jupyter NotebookA free, self-paced 24-week AI engineering course by Zorost Intelligence AI Lab that takes a motivated beginner from Python to production-grade AI systems: ML, LLMs, RAG, fine-tuning, agents and MCP, the major clouds, and Databricks.
- 71
sgrep
307context-dot-dev/sgrep · Pythonsgrep is a local search tool that finds code and document passages using plain-English intent, combining semantic embeddings with ripgrep-style lexical matching, without any account or hosted index.
- 72
openhikmah-web
181OpenHikmah/openhikmah-web · TypeScriptOpen Hikmah is an AI-grounded Quran knowledge graph: you search for a verse, drop it on an infinite canvas, and expand it to surface thematic, linguistic (shared Arabic root), and theological connections to other verses.
- 73
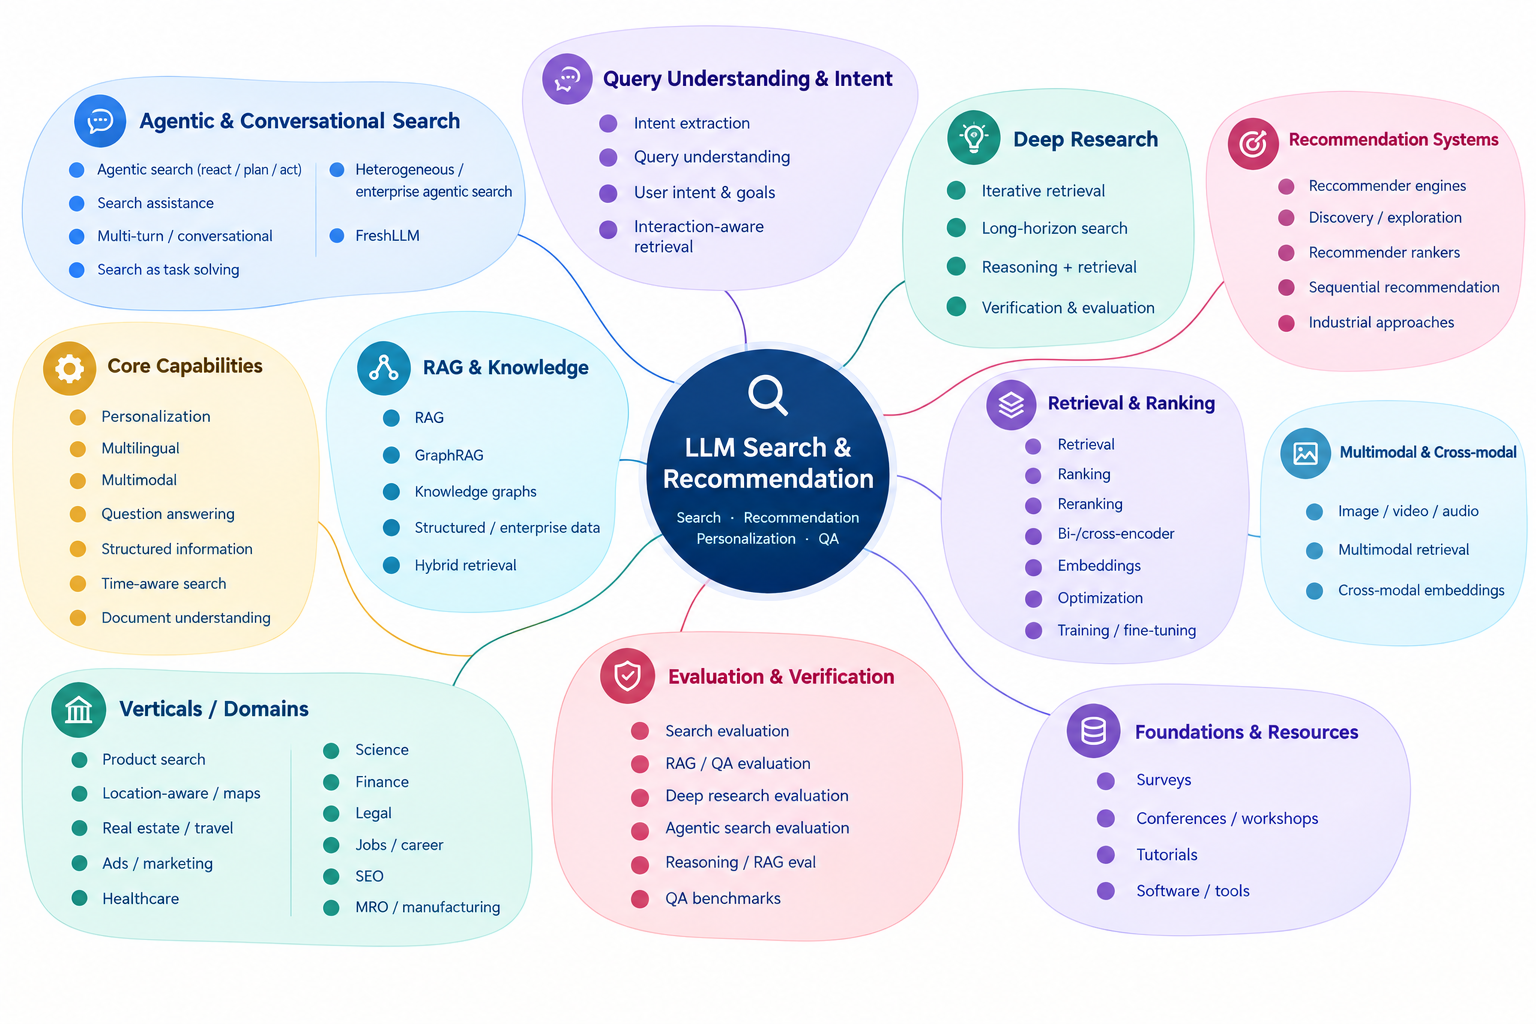
LLMSearchRecommender
124alopatenko/LLMSearchRecommenderA curated compendium of research papers, surveys, and industry engineering practices on using Generative AI and LLMs to build search engines, recommender systems, personalization engines, and question-answering systems.
- 74

dsh-reddit-radar
0reddapidev/dsh-reddit-radar · TypeScriptThis is a dsh (deepseek-harness) plugin that periodically scans reddapi.dev for new Reddit leads matching a one-sentence description of your ideal customer, filters out leads you've already seen, and writes the new ones to a dated markdown report in your workspace.

Related topics
Often tagged together