Topics / #kafka
Kafka projects on GitHub
Distributed event streaming platform for high-throughput message pipelines.
As of , the most-starred Kafka projects on GitHub are system-design-101 (90.5K stars), advanced-java (79.2K stars) and pathway (62.1K stars). GitHub.Locker tracks 44 Kafka repositories with 951.6K stars combined. The fastest-growing on October 16 was system-design-101, with +22 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +22
system-design-101
ByteByteGoHq/system-design-101 · ★ 90.5KA free, visual collection of short explainers and cheat sheets covering core system design concepts (APIs, databases, caching, message queues, real-world company architectures) to help you understand how production systems work and prepare for system design interviews.
 +17
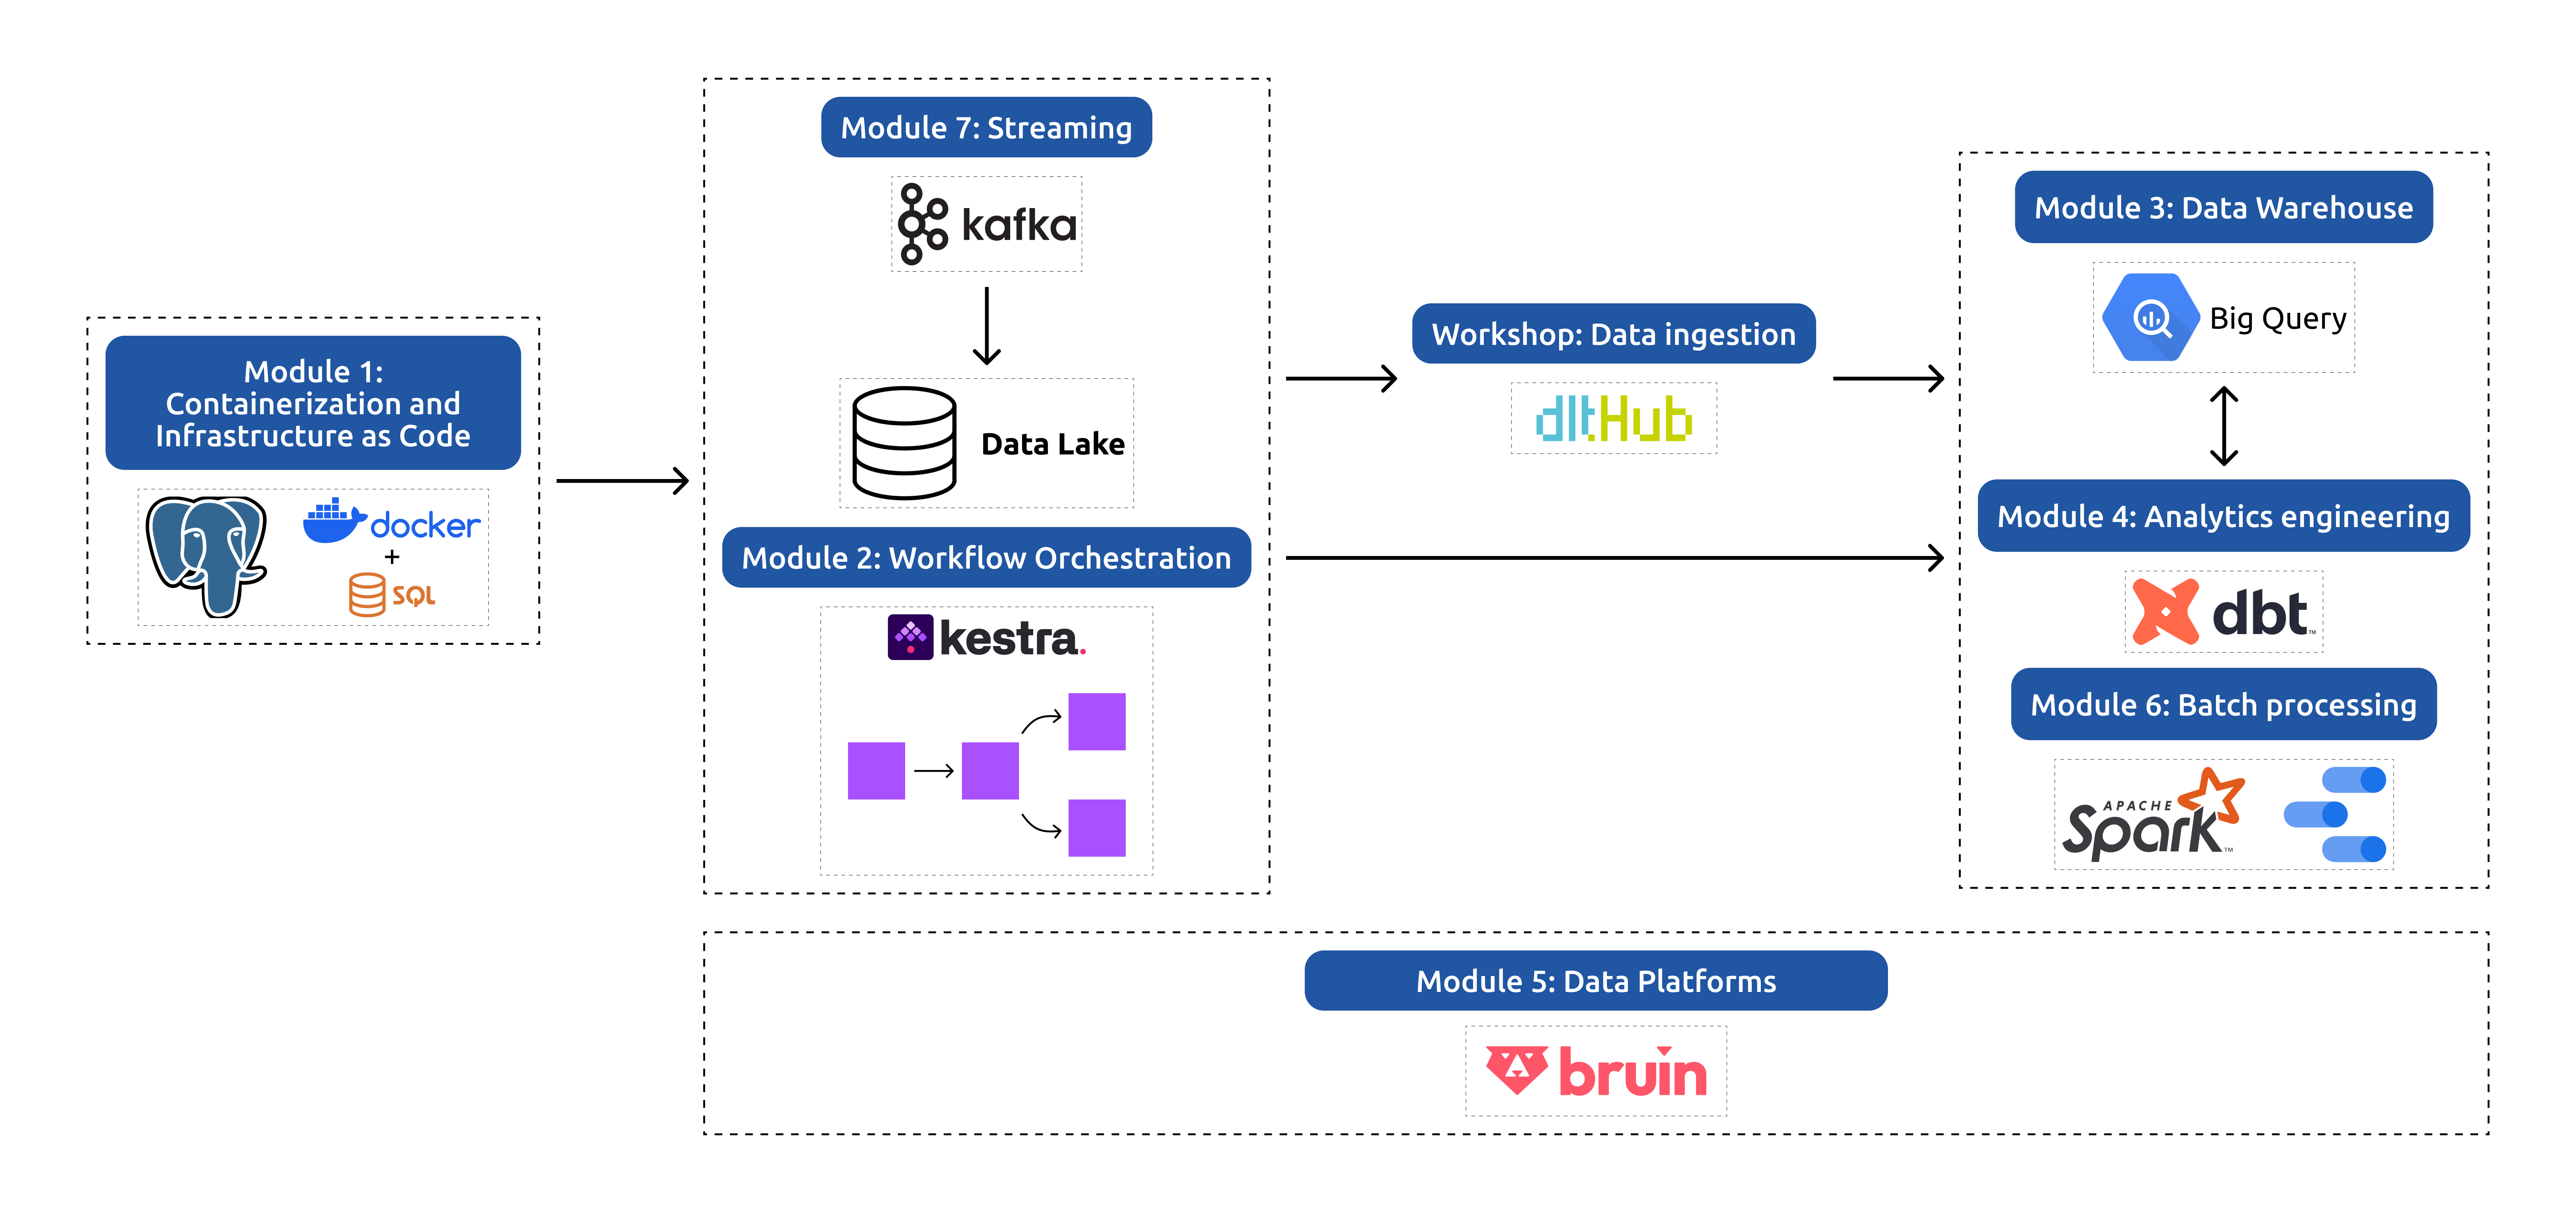
data-engineering-zoomcamp
DataTalksClub/data-engineering-zoomcamp · ★ 46.2KThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
 +10
kafka
apache/kafka · ★ 34KApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
 +9
vector
vectordotdev/vector · ★ 22.7KAn open-source, high-performance observability data pipeline: it collects, transforms, and routes your logs and metrics to any vendors you choose, so you keep control of your observability data. It is maintained by Datadog's Community Open Source Engineering team.
The all-time top
44 projects · by stars
- 90.5K#1 · ByteByteGoHq/system-design-101
system-design-101
A free, visual collection of short explainers and cheat sheets covering core system design concepts (APIs, databases, caching, message queues, real-world company architectures) to help you understand how production systems work and prepare for system design interviews.
- 79.2K
#2 · doocs/advanced-java
advanced-java
A free, community-curated collection of in-depth Java backend interview questions and answers, covering message queues, search engines, caching, sharding, distributed systems, high availability, microservices, and big-data processing.
- 62.1K
 #3 · pathwaycom/pathway
pathway
Pathway is a Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG, with the same code usable for batch jobs, CI/CD tests, and live data streams.
- 4

architect-awesome
60.8Kxingshaocheng/architect-awesomeA curated technical roadmap in Chinese for backend engineers aiming to become architects, mapping out data structures, algorithms, concurrency, databases, middleware, and system design.
- 5

serviette
58.8Kpathwaycom/serviette · PythonThis repo provides ready-to-run cloud templates for RAG pipelines, AI pipelines, and enterprise search, built on the Pathway Live Data Framework and kept in sync with live data sources.
- 6
data-engineering-zoomcamp
46.2KDataTalksClub/data-engineering-zoomcamp · Jupyter NotebookThis is 'Data Engineering Zoomcamp', a free 9-week course that teaches the fundamentals of data engineering by building an end-to-end data pipeline from scratch.
- 7

spring-boot-demo
34.1Kxkcoding/spring-boot-demo · JavaA large collection of hands-on Spring Boot demos: 66 planned integration modules (55 finished) covering ORM, caching, messaging, security, databases, logging and more, meant for learning Spring Boot by example.
- 8
kafka
34Kapache/kafka · JavaApache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications.
- 9

canal
29.7Kalibaba/canal · JavaCanal is Alibaba's MySQL binlog incremental subscription and consumption component. It disguises itself as a MySQL slave, pulls binlog events from a MySQL master, and lets you consume the parsed changes for things like cache refresh, index building, or database synchronization.
- 10

SpringAll
28.9Kwuyouzhuguli/SpringAll · JavaA large collection of hands-on Spring tutorials in Chinese covering Spring Boot, Spring Boot & Shiro, Spring Batch, Spring Cloud, Spring Cloud Alibaba, and Spring Security & OAuth2, each paired with runnable example code and a companion blog post.
- 11
JCSprout
26.8KcrossoverJie/JCSprout · JavaJCSprout ('Java Core Sprout') is a Chinese-language knowledge base of core Java topics: a curated collection of articles on collections, multithreading, JVM internals, distributed systems, frameworks, algorithms and Netty, with over 26k GitHub stars.
- 12
flink
26.4Kapache/flink · JavaApache Flink is an open source stream processing framework with powerful stream- and batch-processing capabilities, running your programs on its own distributed runtime.
- 13
vector
22.7Kvectordotdev/vector · RustAn open-source, high-performance observability data pipeline: it collects, transforms, and routes your logs and metrics to any vendors you choose, so you keep control of your observability data. It is maintained by Datadog's Community Open Source Engineering team.
- 14

SpringBoot-Labs
20.1Kyudaocode/SpringBoot-Labs · JavaA large Java learning repository packed with hands-on example modules covering six Spring-related technology stacks: Spring Boot 2.X, Spring Cloud, Spring Cloud Alibaba, Dubbo, distributed message queues, and distributed transactions.
- 15

athena
18.9KZhongFuCheng3y/athenaAthena is a Chinese-language Java backend 'knowledge graph' (知识图谱) — a huge curated collection of articles, interview-prep columns, and e-books meant to help Java beginners learn core backend topics like concurrency, the JVM, Spring, Redis, Kafka, and MySQL.
- 16

telegraf
17.9Kinfluxdata/telegraf · GoTelegraf is an open-source agent for collecting, processing, aggregating, and writing metrics, logs, and other arbitrary data. It ships with 300+ plugins covering system monitoring, cloud services, and messaging.
- 17
zipkin
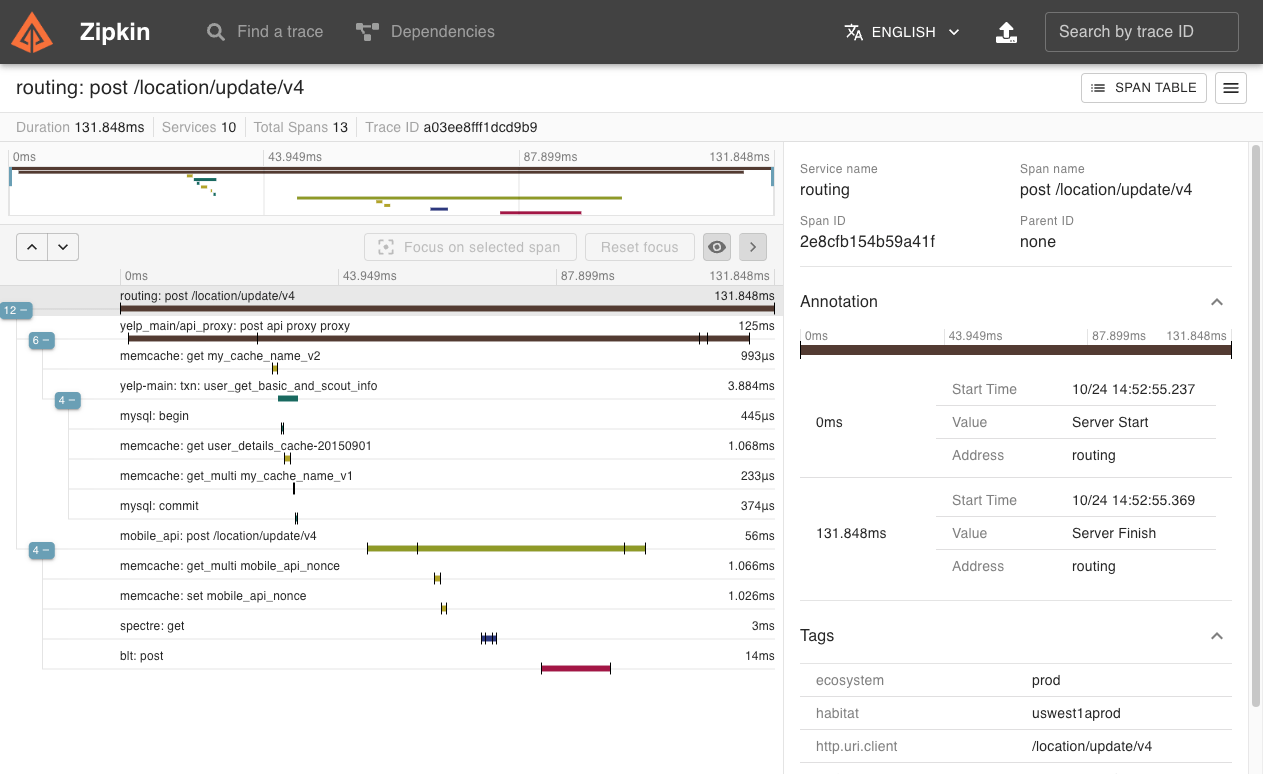
17.5Kopenzipkin/zipkin · JavaZipkin is a distributed tracing system. It gathers timing data from your services to help troubleshoot latency problems, offering both collection and lookup of that data.
- 18

questdb
17.4Kquestdb/questdb · JavaQuestDB is an open-source, low-latency time-series database on open formats: it ingests millions of events per second, computes on live data in milliseconds, and keeps years of history queryable through one SQL engine.
- 19

BigData-Notes
17Kheibaiying/BigData-Notes · JavaThis is a comprehensive Chinese-language study guide covering the big data ecosystem: Hadoop, Hive, Spark, Storm, Flink, HBase, Kafka, Zookeeper, Flume, Sqoop, Azkaban, and Scala.
- 20

emqx
16.8Kemqx/emqx · ErlangEMQX is an MQTT broker and messaging platform for IoT: it connects millions of devices, routes messages in real time, and bridges them into backend data systems. Aimed at AI, IoT, IIoT, connected vehicles and smart cities.
- 21

doris
16.1Kapache/doris · JavaApache Doris is an open-source, real-time analytics and search database built on MPP architecture. It serves fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
- 22

Cookbook
15.5Kandkret/Cookbook · PythonA free online book (the Data Engineering Cookbook) that covers everything a data engineer needs to know, from basic engineering skills to advanced platform design, case studies and interview prep.
- 23

flink-learning
15.1Kzhisheng17/flink-learning · JavaA companion repo to a Chinese-language Apache Flink learning blog, packed with runnable example code, source-code analysis articles, and real-world project case studies (PV/UV stats, log storage, large-scale dedup, monitoring/alerting).
- 24
technology-talk
14.7Kaalansehaiyang/technology-talkA curated Chinese knowledge base of Java interview prep articles, system architecture notes, middleware deep-dives, and career advice, written by a self-described Alibaba P7 architect who goes by 'Tom哥'.
- 25

workflow
14.4Ksogou/workflow · C++Sogou C++ Workflow is an enterprise-grade C++ engine for asynchronous networking and parallel computing, used internally by Sogou to power search, cloud input method, and ad services, handling billions of requests daily.
- 26

pinpoint
13.9Kpinpoint-apm/pinpoint · JavaPinpoint is an APM (Application Performance Management) tool for large-scale distributed systems, mainly written for Java (with PHP and Python agent support), inspired by Google's Dapper paper.
- 27

metersphere
13.6Kmetersphere/metersphere · JavaMeterSphere is an open-source continuous testing platform with a built-in AI assistant, designed to make software testing simpler and faster so it stops being the bottleneck of continuous delivery.
- 28

debezium
13.2Kdebezium/debezium · JavaDebezium is an open source change data capture (CDC) platform that monitors databases and streams row-level change events to applications in real time.
- 29
redpanda
12.6Kredpanda-data/redpanda · C++Redpanda is a streaming data platform that is wire-compatible with the Apache Kafka API but is built from the ground up in C++ to be lighter, faster, and simpler to operate.
- 30
sarama
12.5KIBM/sarama · GoSarama is a Go client library for Apache Kafka, letting Go applications produce and consume Kafka messages.
- 31

kafka-ui
12.3Kprovectus/kafka-ui · JavaA free, open-source web UI for monitoring and managing Apache Kafka clusters — a lightweight dashboard that makes your data flows observable and helps find and troubleshoot issues faster. Built by developers, for developers.
- 32
CMAK
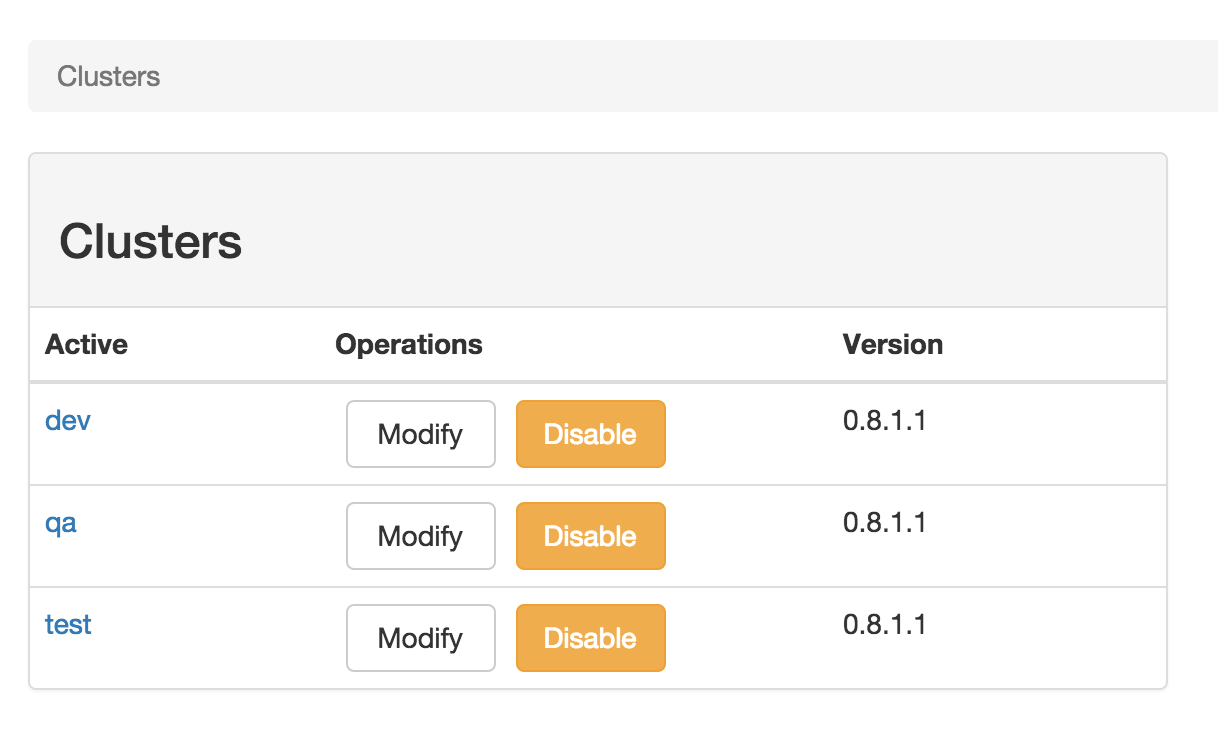
11.9Kyahoo/CMAK · ScalaCMAK (Cluster Manager for Apache Kafka, formerly known as Kafka Manager) is a self-hosted web tool for managing Apache Kafka clusters, and it can handle multiple clusters from one interface.
- 33
automq
10.9KAutoMQ/automq · JavaAutoMQ is a diskless, stateless fork of Apache Kafka that stores all log data on S3 or S3-compatible object storage instead of local disks, cutting cloud costs by up to 10x and removing cross-AZ traffic fees.
- 34
centrifugo
10.9Kcentrifugal/centrifugo · GoCentrifugo is an open-source, language-agnostic real-time messaging server that lets any backend push messages to connected clients over WebSocket, HTTP-streaming, SSE, GRPC or WebTransport. It acts as a self-hosted alternative to Pubnub, Pusher, Ably, Socket.IO, Phoenix.PubSub and SignalR.
- 35

keda
10.6Kkedacore/keda · GoKEDA is a Kubernetes-based event driven autoscaling component — it automatically scales any container running in a Kubernetes cluster based on events.
- 36
God-Of-BigData
10.6Kwangzhiwubigdata/God-Of-BigDataA curated Chinese-language knowledge base for learning big data engineering and passing big data interviews, covering Java fundamentals, distributed systems theory, and deep dives into Hadoop, Hive, Spark, Flink, HBase, Kafka, and Zookeeper.
- 37

flexprice
6.9Kflexprice/flexprice · GoAn open-source usage-based billing platform: your app sends usage events, Flexprice meters them in real time, applies plans, credits and feature limits, and generates invoices automatically.
- 38

The-Accidental-CTO
3.9Ksubhashchy/The-Accidental-CTO · TypeScriptThis is 'The Accidental CTO', a story-driven system design handbook by Subhash Choudhary about scaling the Dukaan e-commerce platform from zero to over a million stores without a formal CS degree.
- 39
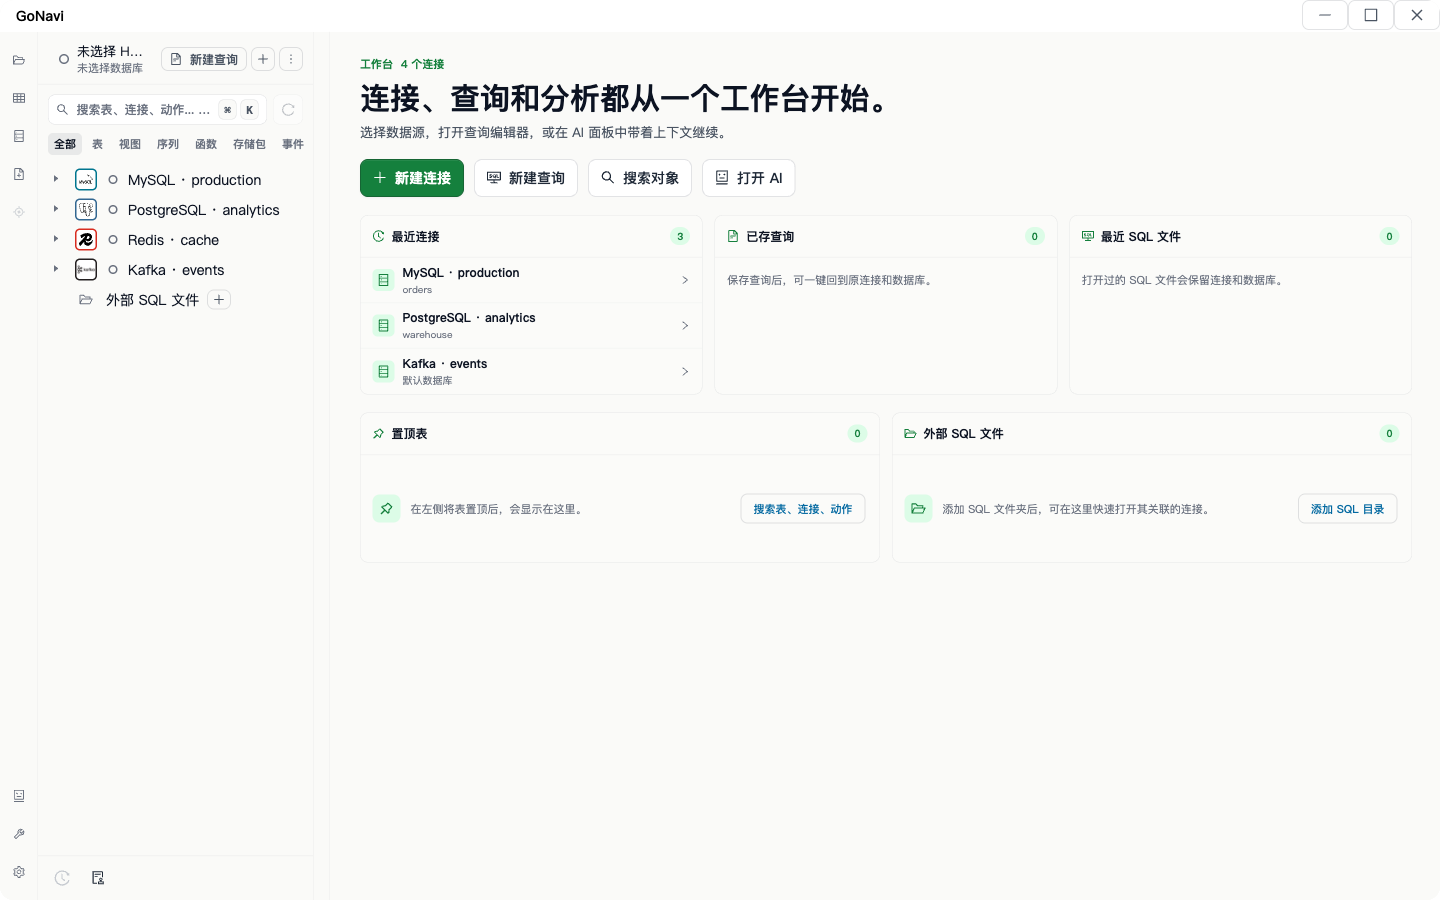
GoNavi
2.1KSyngnat/GoNavi · TypeScriptGoNavi is a high-performance, cross-platform database GUI client that connects to many different data sources (SQL, cache, vector, message queue, search, time-series, domestic DBs) and is built with AI assistants and MCP in mind.
- 40
hotdata-cli
1.8Khotdata-dev/hotdata-cli · RustHotdata CLI is a command-line client that lets you query, search, and join data from one place — external databases, APIs, cloud storage, Iceberg catalogs, and uploaded files — using plain SQL and a handful of commands.
- 41
openframe-oss-tenant
1.1Kflamingo-stack/openframe-oss-tenant · ShellOpenFrame OSS Tenant is the open-source, multi-tenant foundation of OpenFrame, an AI-powered MSP (Managed Service Provider) platform that replaces expensive proprietary RMM/support software with intelligent automation, device management, and AI-assisted support.
- 42

kafgres
417RayElg/kafgres · Rustkafgres is a PostgreSQL extension that embeds a full Kafka broker inside Postgres: unmodified Kafka clients connect on port 9092 and Postgres stores all topics, partitions, offsets, and the log itself, giving transactional coupling between the database and the event stream.
- 43

picomq
373PicoMQ/picomq · RustPicoMQ is a durable, real-time streaming system that stores its data on S3-compatible object storage instead of local disks, while speaking both a native HTTP protocol and the Kafka wire protocol.
- 44

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.

Related topics
Often tagged together