Hyper-Extract README

The project's README from github.com/yifanfeng97/Hyper-Extract. As one markdown file: README.md.

Hyper-Extract Logo

Smart Knowledge Extraction CLI

Transform documents into structured knowledge with one command.

📖 English Version · 中文版

Trendshift

PyPI Version Python Version License Docs GitHub Stars


"Stop reading. Start understanding."
"告别文档焦虑,让信息一目了然"


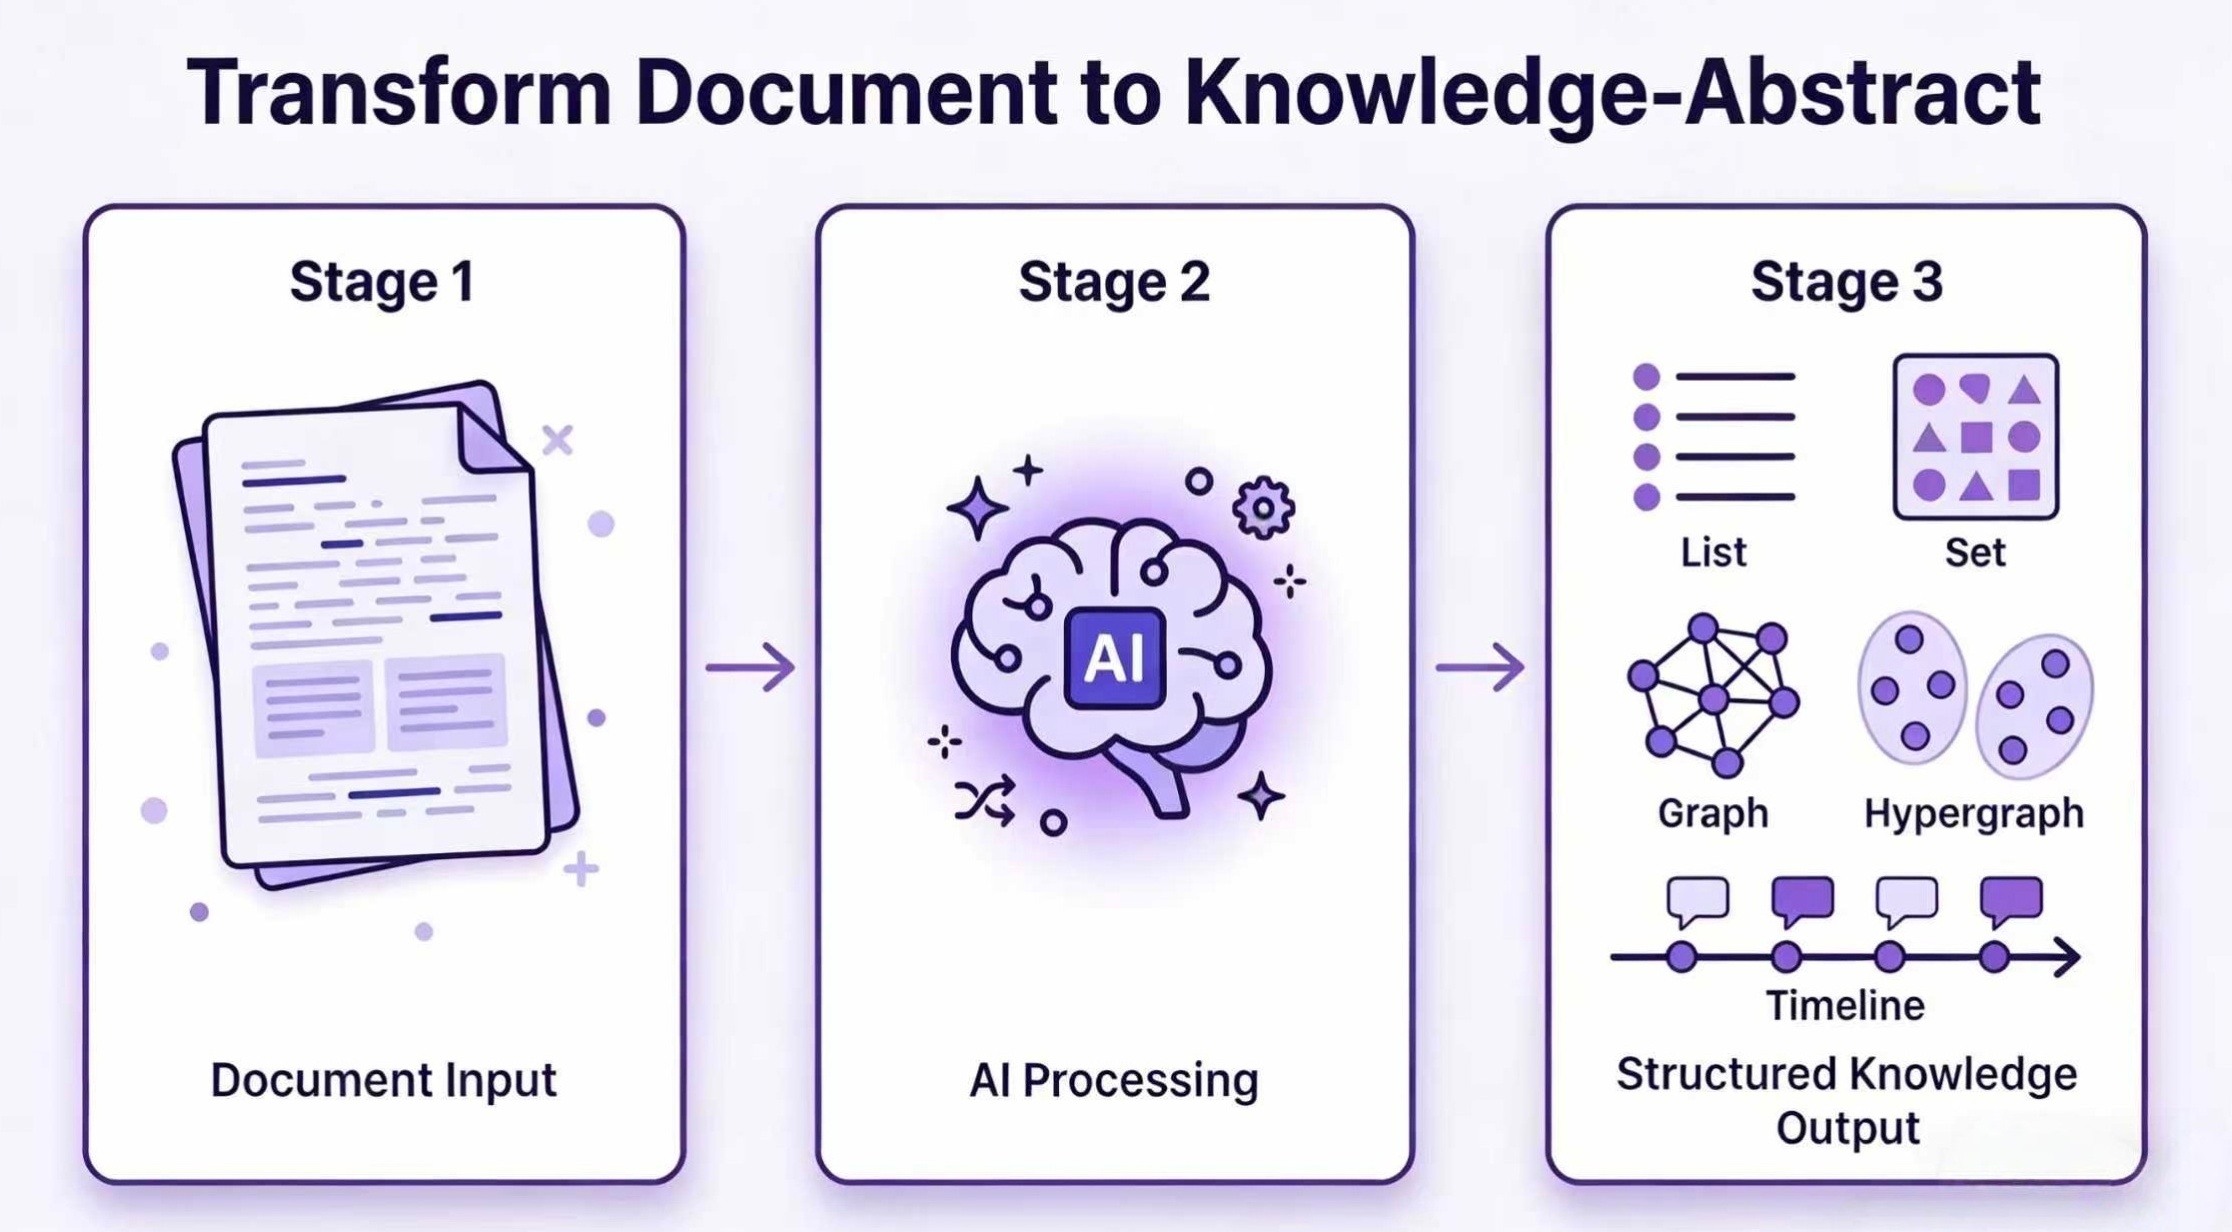
Hero & Workflow

⚡ 30-Second Quick Start

1. Install:

# Install uv first (if you haven't)
curl -LsSf https://astral.sh/uv/install.sh | sh

# Install Hyper-Extract CLI
uv tool install hyperextract
# or: pipx install hyperextract

2. Configure your provider (pick one):

# OpenAI (LLM + embeddings in one key)
he config init -p openai -k YOUR_OPENAI_API_KEY

# DeepSeek (LLM only — pair with an OpenAI embedder, most cost-effective)
he config llm -p deepseek -k YOUR_DEEPSEEK_API_KEY
he config embedder -p openai -k YOUR_OPENAI_API_KEY

# Local vLLM (free, on-premise)
he config llm -p vllm -u http://localhost:8000/v1 -k dummy -m Qwen/Qwen3.5-9B
he config embedder -p vllm -u http://localhost:8001/v1 -k dummy -m BAAI/bge-m3
More providers — Anthropic (Claude), Alibaba Bailian, OrcaRouter…
# Anthropic (Claude) — LLM only
he config llm -p anthropic -k YOUR_ANTHROPIC_API_KEY
he config embedder -p openai -k YOUR_OPENAI_API_KEY

# Alibaba Bailian (Qwen, LLM + embeddings in one key)
he config init -p bailian -k YOUR_BAILIAN_API_KEY

OpenAI and Bailian provide both LLM and embedding models in one API. Anthropic and DeepSeek are LLM-only (pair them with an OpenAI-compatible embedder). DeepSeek is the most cost-effective option (~$0.001-0.005/page).

3. Extract, query & visualize:

# Extract knowledge from a document
he parse examples/en/tesla.md -t general/biography_graph -o ./output/ -l en

# Query it
he search ./output/ "What are Tesla's major achievements?"

# Visualize
he show ./output/

# Export to an Obsidian vault (Markdown notes + [[wikilinks]])
he export obsidian ./output/ -o ./vault/

# Your sources change? Feed updates under the same source — old facts roll back automatically
he feed ./output/ updated-tesla.md --source tesla.md

# Tag and scope your searches
he tag ./output/ --source tesla.md --add biography
he search ./output/ "inventions" --tag biography

# Audit: which documents contributed what?
he info ./output/ --sources

Which provider should I use? OpenAI and Bailian provide both LLM and embedding models in one API; Anthropic and DeepSeek are LLM-only (pair with an OpenAI embedder); local vLLM is free but needs a GPU. Full guide: Provider System.

🐍 Python API (click to expand)
uv pip install hyperextract
from hyperextract import Template

ka = Template.create("general/biography_graph")

with open("examples/en/tesla.md") as f:
    result = ka.parse(f.read())

result.show()

🔗 More examples: examples/en

✨ Core Features

📄 Rich Document Ingestion Feed PDF, Word, PowerPoint, Excel, HTML, EPUB and more — not just .txt/.md (pip install "hyperextract[ingest]")
🔷 9 Knowledge Structures From raw chunk corpora and simple Lists to advanced Graphs, Hypergraphs, and Spatio-Temporal Graphs
🧠 11+ Extraction Engines chunk_rag (zero-cost baseline), GraphRAG, LightRAG, Hyper-RAG, KG-Gen, and more — ready to use
📝 80+ YAML Templates Zero-code extraction across Finance, Legal, Medical, TCM, Industry, and General domains
🔄 Incremental Evolution & Provenance Feed new documents anytime — every source is attributed and the index updates incrementally; audit (he info --sources), roll back (he remove --document), or upsert updated versions as your sources change
📤 Obsidian Export Turn any extracted graph into an Obsidian vault — Markdown notes linked by [[wikilinks]]

🎯 What Can You Do With It?

📄 Researcher — Turn papers into knowledge graphs

Feed a 20-page academic paper, get an interactive graph of key concepts, authors, and citations.

he parse paper.pdf -t general/academic_graph -o ./paper_kb/
he show ./paper_kb/
🏦 Financial Analyst — Extract entities from earnings reports

Automatically identify companies, executives, financial metrics, and their relationships from unstructured reports.

he parse earnings.md -t finance/earnings_graph -o ./finance_kb/
he search ./finance_kb/ "What are the key risk factors?"
🔒 Local Deployment — Keep data on-premise with vLLM

Run Qwen3.5-9B + bge-m3 locally via vLLM. No data leaves your machine.

from hyperextract import create_client
llm, emb = create_client(
    llm="vllm:Qwen3.5-9B@http://localhost:8000/v1",
    embedder="vllm:bge-m3@http://localhost:8001/v1",
    api_key="dummy",
)
📜 Knowledge Base Manager — Keep your KB in sync with reality

Documents change. Hyper-Extract tracks every source so you can update, roll back, or audit without starting over.

# Ingest with attribution — every fact is traceable to its source
he feed ./ka/ contract-v1.md --source contract-v1
he tag ./ka/ --source contract-v1 --add legal --add acme

# Document updated? Re-feed under the same source — old facts roll back automatically
he feed ./ka/ contract-v2.md --source contract-v1

# Document is obsolete? Roll back everything it contributed
he remove ./ka/ --document contract-v1

# Remove a single wrong fact (LLM-assisted, with dry-run preview)
he remove ./ka/ --edit-node Apple --fact "founded by Steve Jobs" --dry-run

# Search only within legal-tagged documents
he search ./ka/ "termination clause" --tag legal

# Audit: which documents contributed what?
he info ./ka/ --sources

🚀 Supported Platforms & Models

Hyper-Extract uses LangChain structured output with function calling. The model must support tool/function calling.

Platform Verified Models
OpenAI gpt-4o, gpt-4o-mini, gpt-5
Anthropic claude-opus-4-8, claude-sonnet-4-6, claude-haiku-4-5
DeepSeek deepseek-v4-flash, deepseek-v4-pro
阿里云百炼 qwen-plus, qwen-turbo, deepseek-r1
Local vLLM Qwen3.5-9B (GPTQ-Marlin)

Embedding models (semantic search) work with any OpenAI-compatible endpoint: text-embedding-3-small, text-embedding-v4 (Bailian), bge-m3 (local vLLM).

Provider notes — DeepSeek & Anthropic pairing

DeepSeek: V4 models default to "thinking" mode, which Hyper-Extract auto-disables so structured extraction works. Set DEEPSEEK_API_KEY. DeepSeek has no embeddings API:

from hyperextract import create_client
llm, emb = create_client(llm="deepseek", embedder="openai:text-embedding-3-small")

Anthropic: Claude is used for the LLM (set ANTHROPIC_API_KEY, extra: pip install 'hyperextract[anthropic]'). No embeddings API:

from hyperextract import create_client
llm, emb = create_client(llm="anthropic", embedder="openai:text-embedding-3-small")

📖 Full guide: Provider System & Local Model Support

📈 Why Hyper-Extract?

Feature GraphRAG LightRAG KG-Gen ATOM Hyper-Extract
Knowledge Graph ✅ ✅ ✅ ✅ ✅
Temporal Graph ✅ ❌ ❌ ✅ ✅
Spatial Graph ❌ ❌ ❌ ❌ ✅
Hypergraph ❌ ❌ ❌ ❌ ✅
Domain Templates ❌ ❌ ❌ ❌ ✅
Interactive CLI ✅ ❌ ❌ ❌ ✅
Multi-language ✅ ❌ ❌ ❌ ✅

🧩 Supported Knowledge Structures

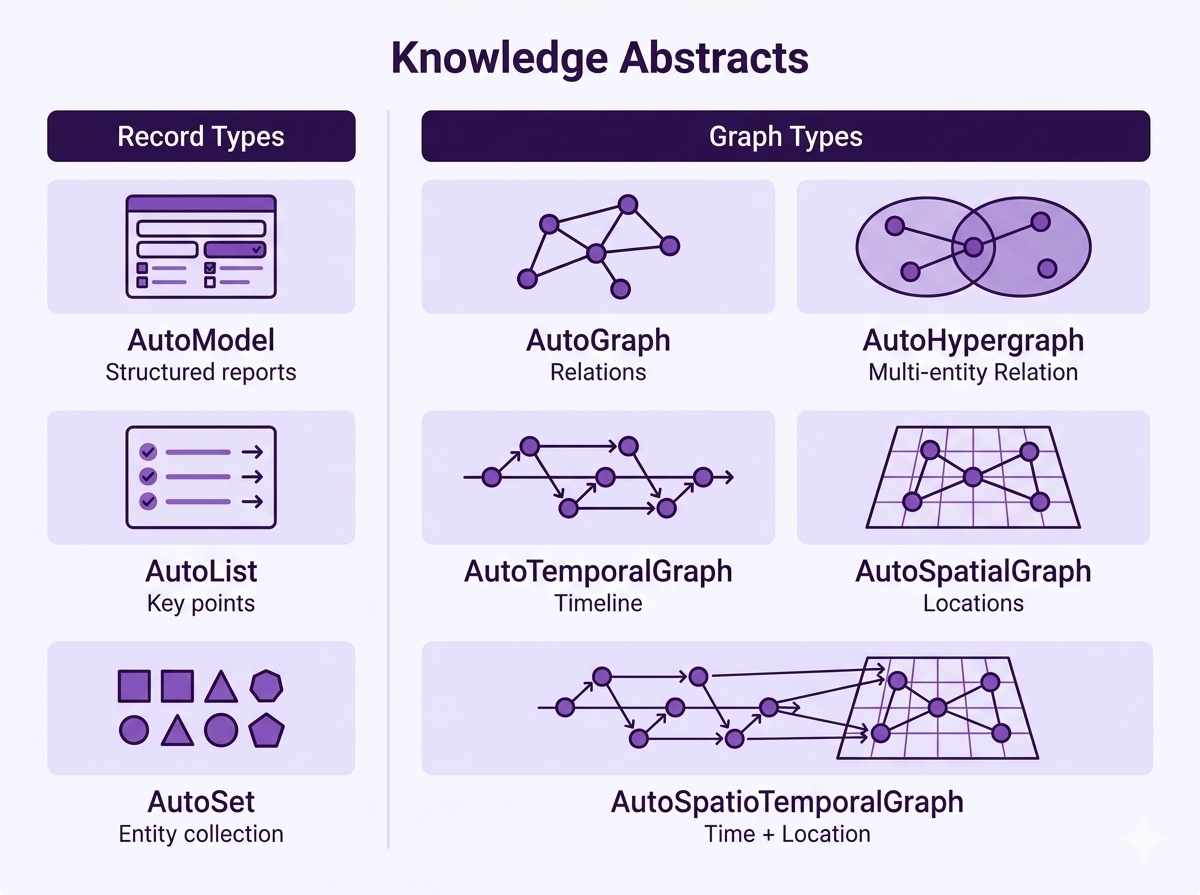
From simple to complex — pick the right structure for your data:

Knowledge Structures Matrix

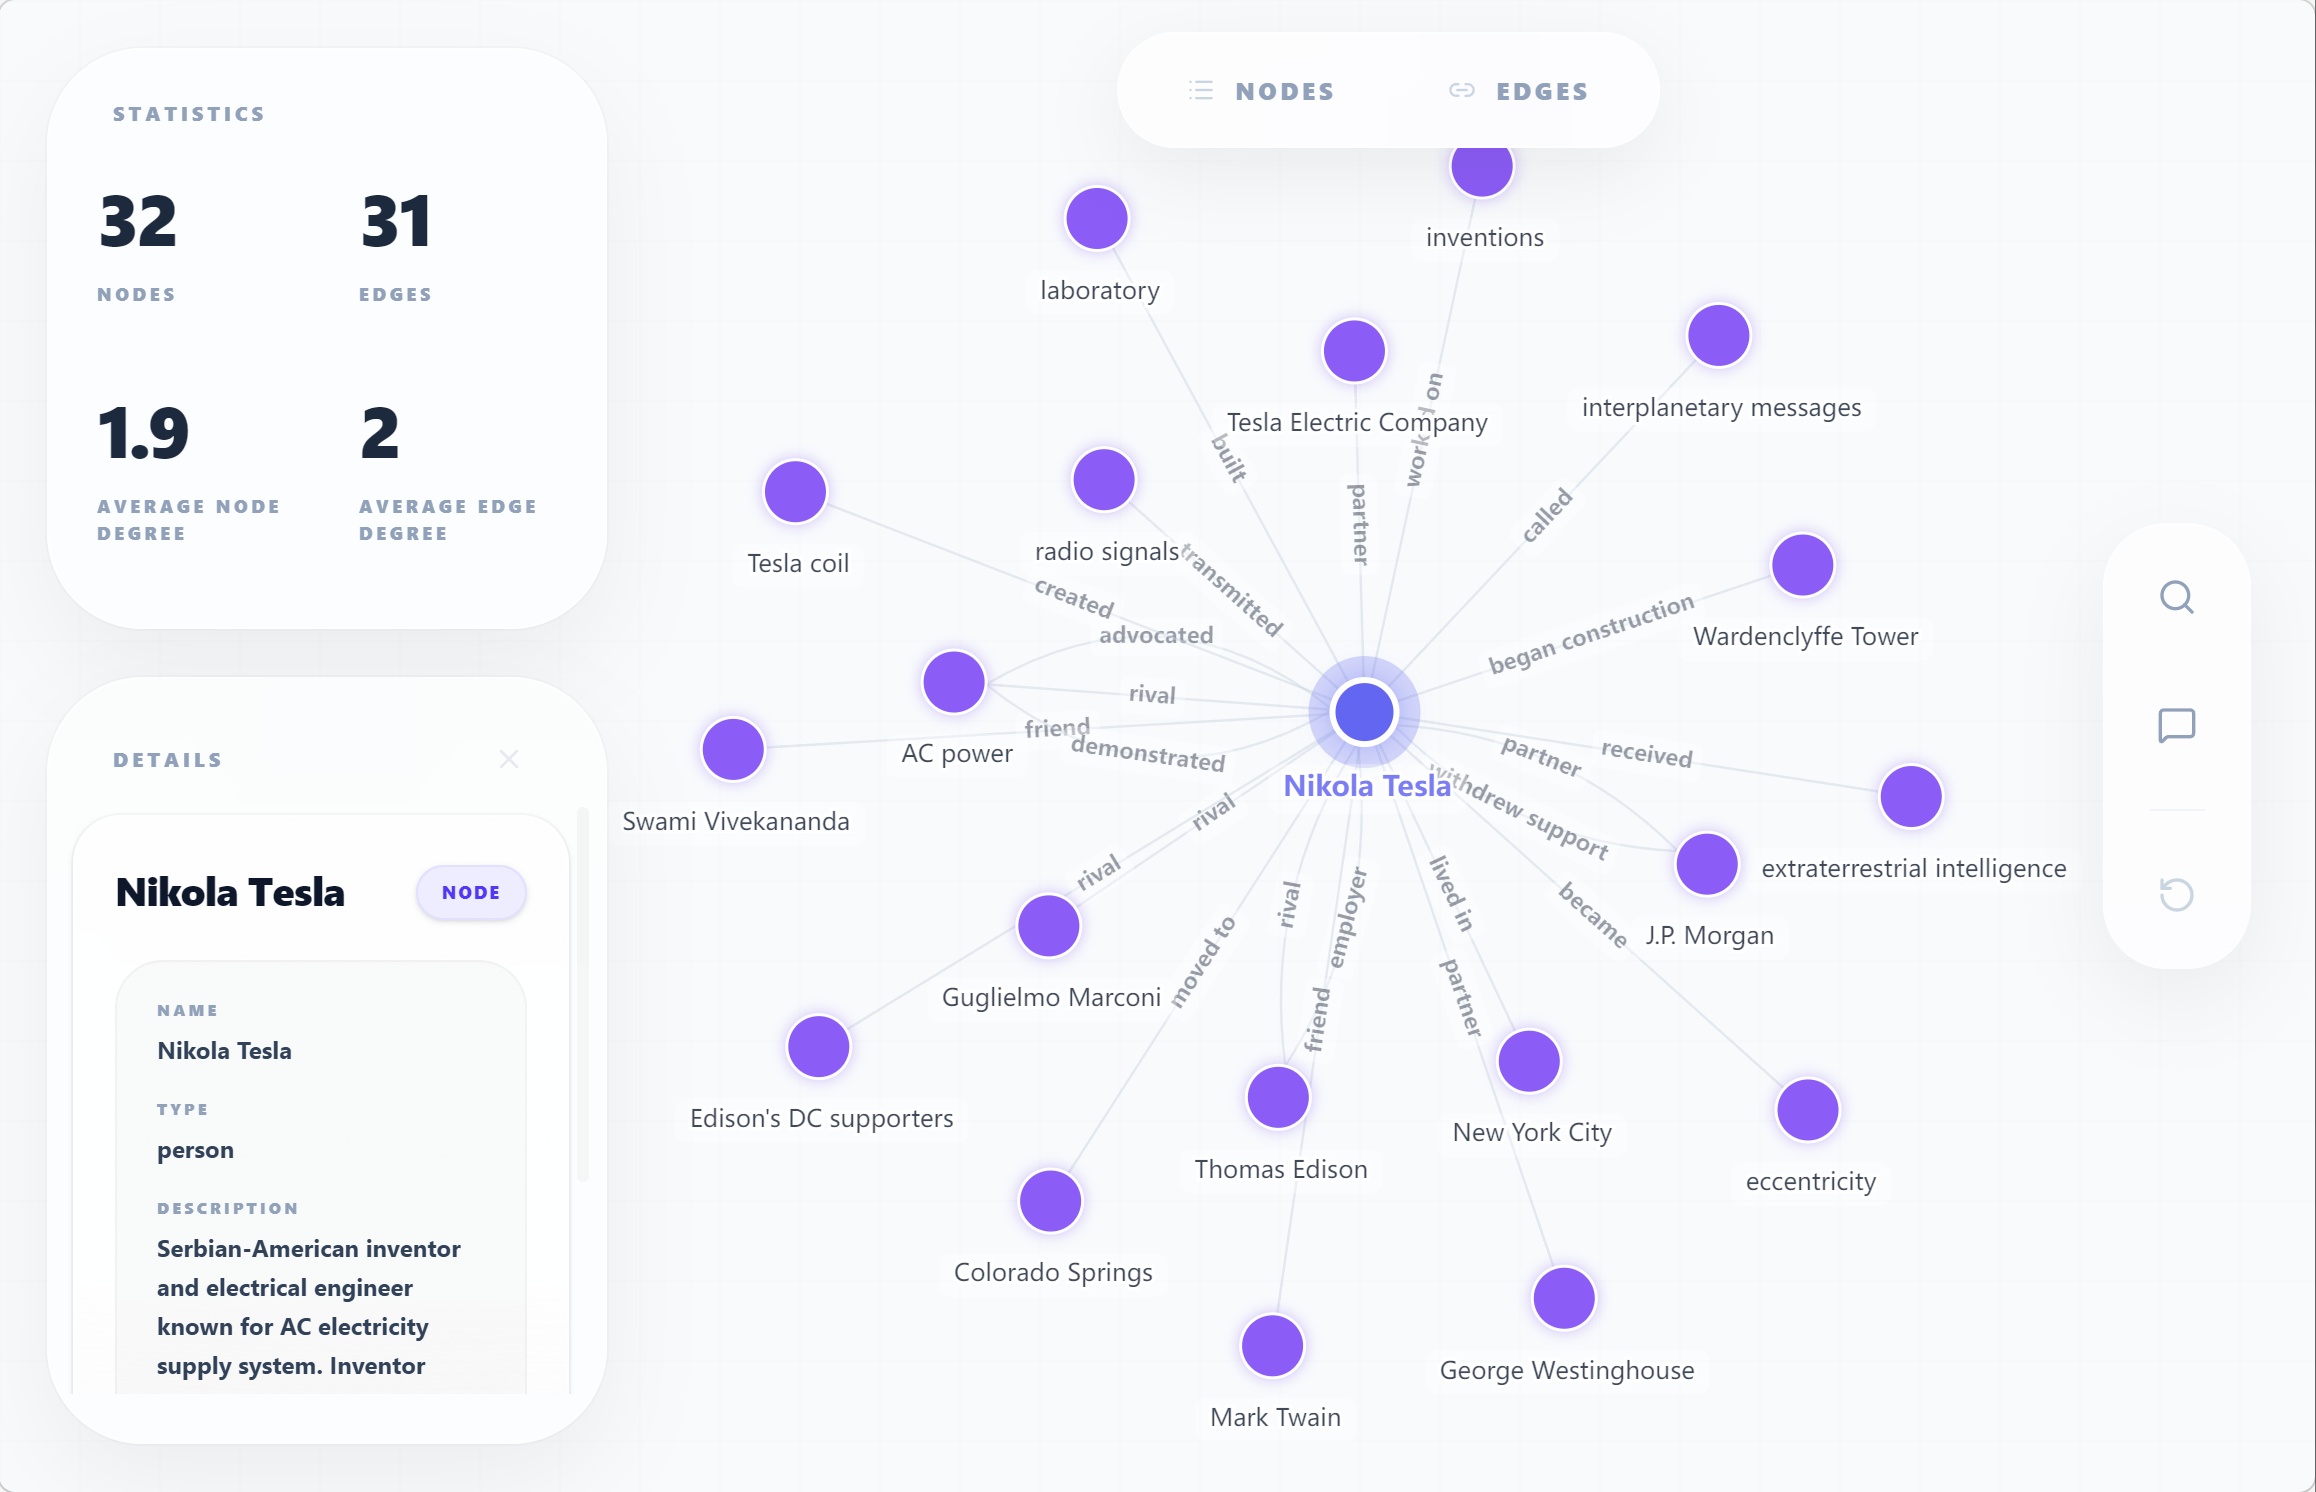
Example — AutoGraph visualization:

AutoGraph Visualization
📋 What's under the hood? (Architecture & Templates)

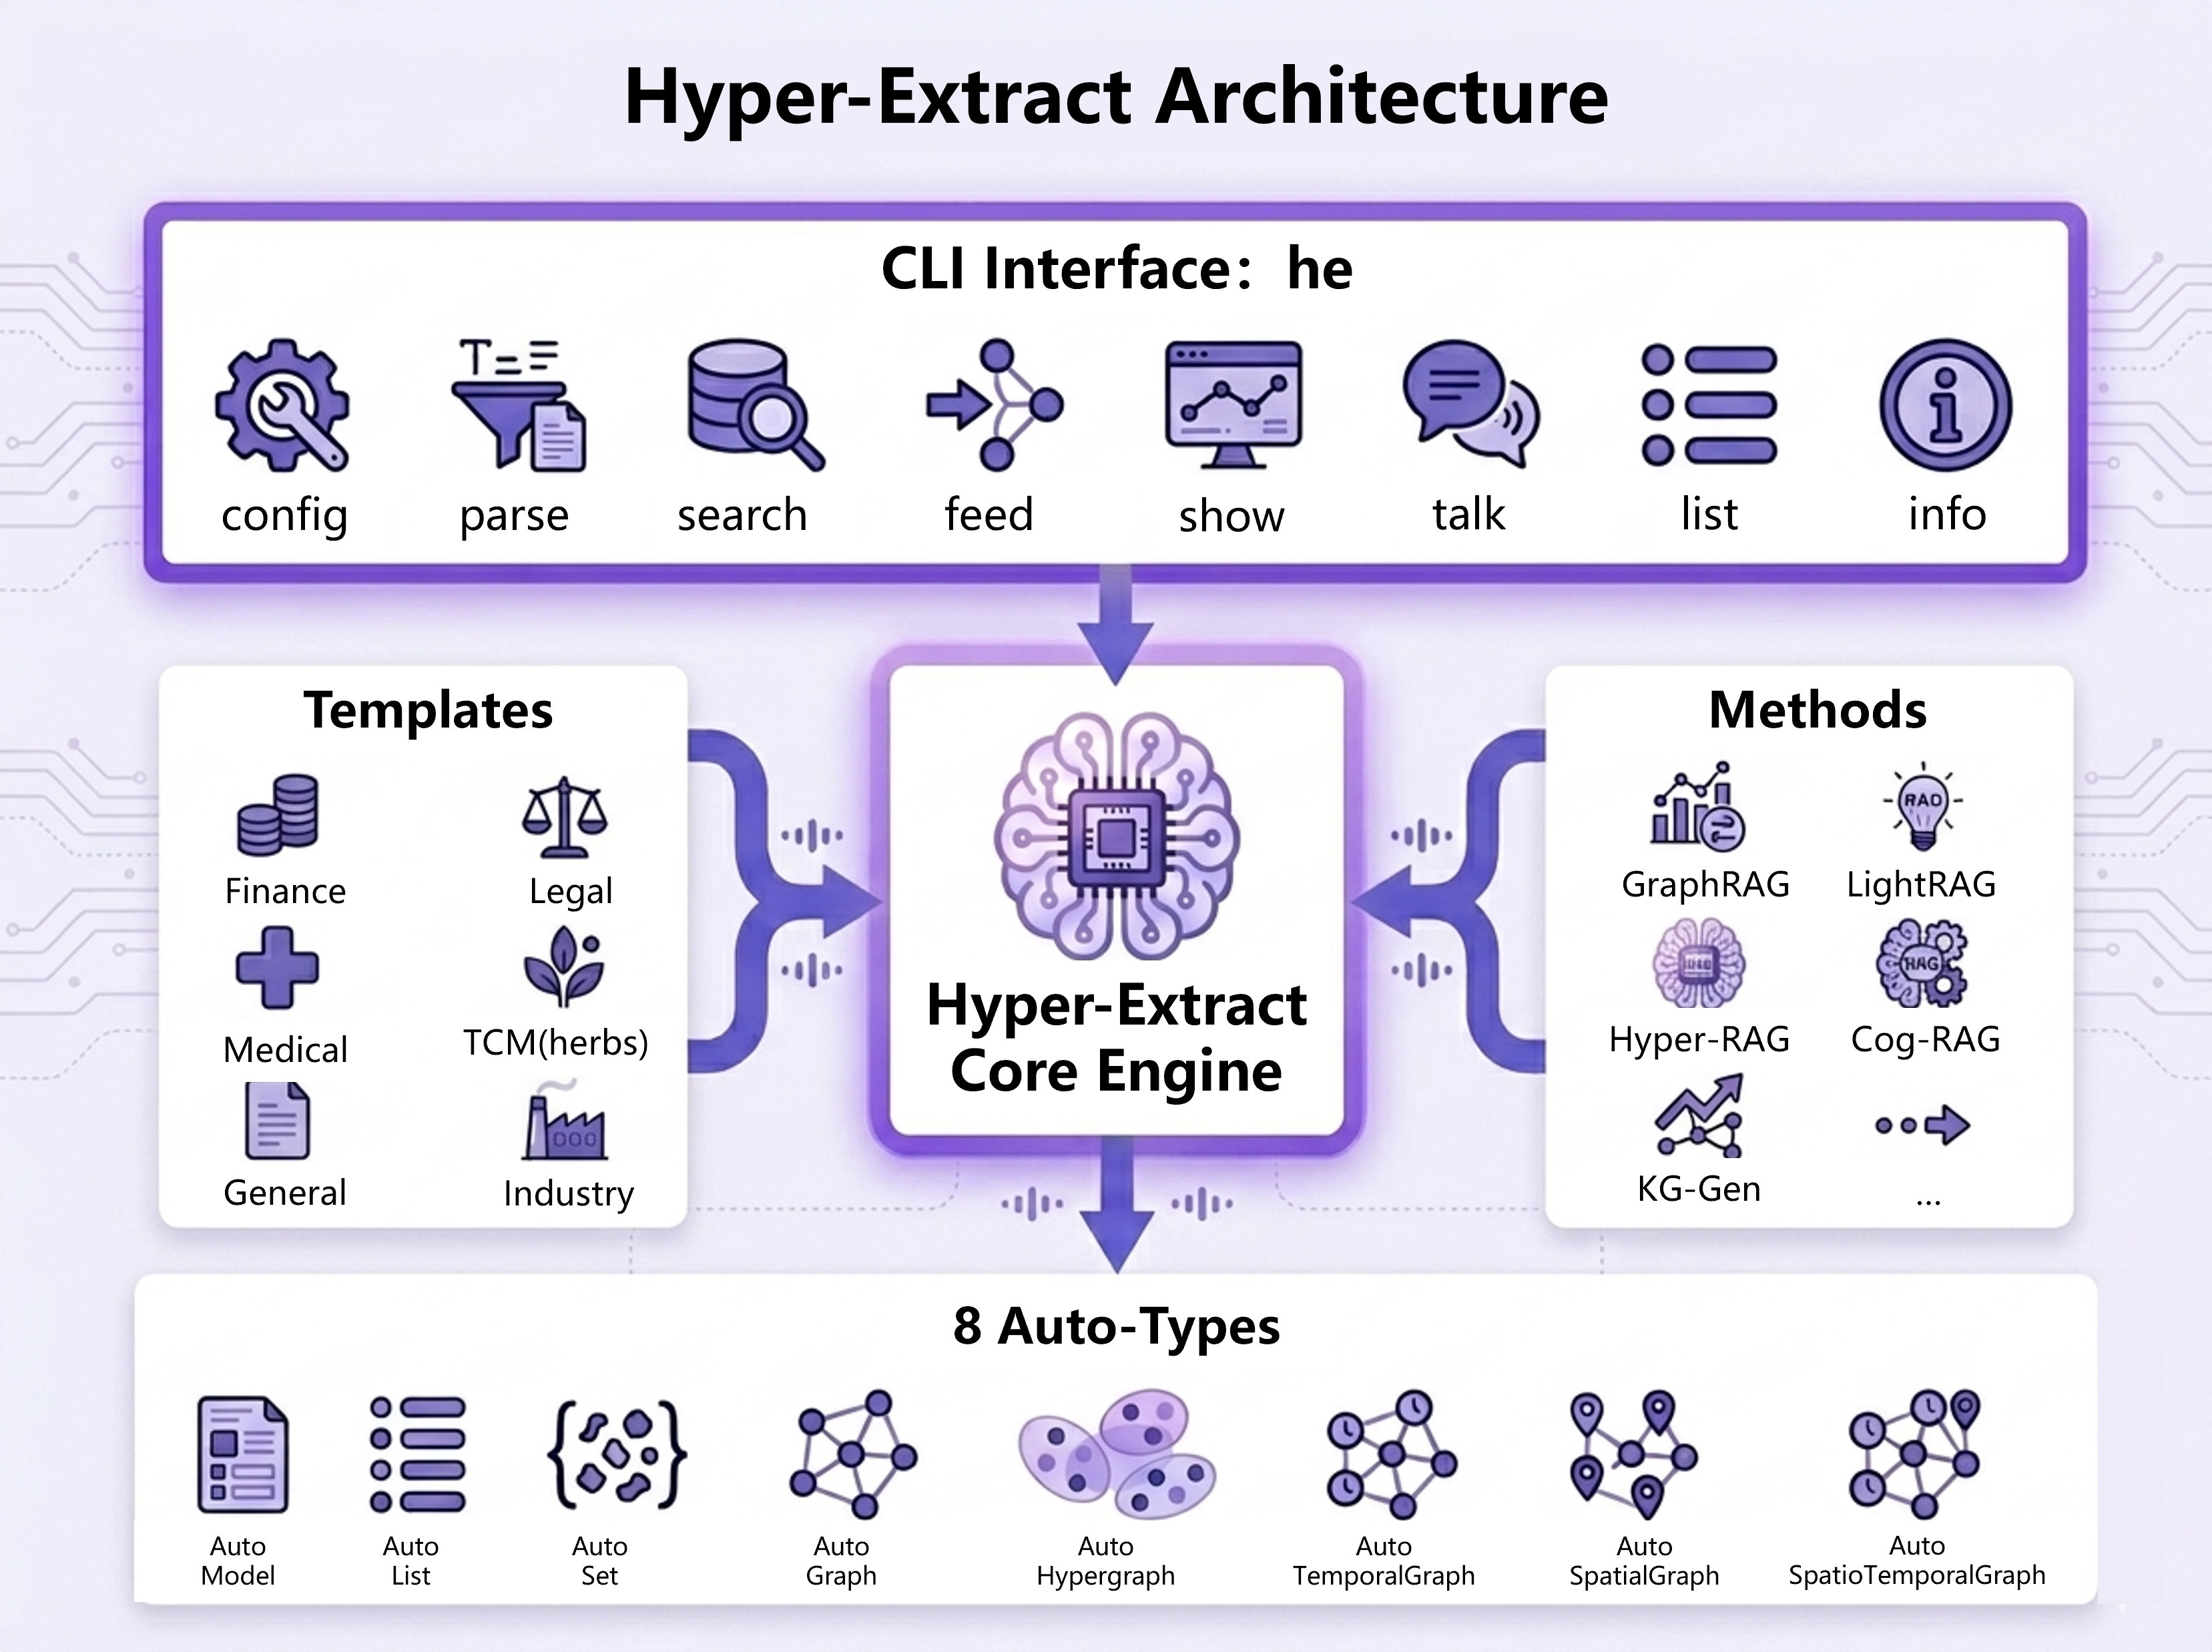
Hyper-Extract follows a three-layer architecture:

  • Auto-Types — 9 strongly-typed data structures (Model, List, Set, Graph, Hypergraph, Temporal Graph, Spatial Graph, Spatio-Temporal Graph, Document corpus)
  • Methods — Extraction & retrieval algorithms: Chunk-RAG baseline, KG-Gen, GraphRAG, LightRAG, Hyper-RAG, Cog-RAG, and more
  • Templates — 80+ presets across 6 domains. Zero-code setup.
Architecture

Template example (Graph type):

language: en
name: Knowledge Graph
type: graph
tags: [general]
description: 'Extract entities and their relationships.'
output:
  entities:
    fields:
    - name: name
      type: str
    - name: type
      type: str
    - name: description
      type: str
  relations:
    fields:
    - name: source
      type: str
    - name: target
      type: str
    - name: type
      type: str
identifiers:
  entity_id: name
  relation_id: '{source}|{type}|{target}'

📰 What's New

v0.9.0 — 📄 Rich document ingestion: he parse / he feed now take PDF, Word, PowerPoint, Excel, HTML, EPUB and more (pip install "hyperextract[ingest]") · 🧱 New chunk_rag method: zero-extraction chunk baseline with full provenance · 🐛 he tag and method-KA command fixes.

📰 Full release notes · All releases

📚 Documentation & Resources

Resource Link
Full Documentation yifanfeng97.github.io/Hyper-Extract
CLI Guide Command-line interface
Provider System Model compatibility & local deployment
News Release notes & highlights
Template Gallery 80+ presets
Examples Working code

🔌 MCP Server

Expose your knowledge abstracts to MCP-capable assistants (Claude Desktop, IDE agents) via the Model Context Protocol — read + export only.

pip install 'hyperextract[mcp]'
he-mcp        # stdio MCP server

Tools: list_templates, info, search, ask (RAG), export_obsidian. Full guide: MCP Server docs.

🤝 Contributing & License

Contributions are welcome! Please submit Issues and PRs.
Licensed under Apache-2.0.

🔒 Security

This project has been security assessed by MseeP.ai.

AtomGit Mirror

AtomGit mirror - a synchronized AtomGit mirror of Agent Reach for easier access and cloning in China. Hosted on AtomGit: https://atomgit.com/yifanfeng97/Hyper-Extract

Hyper-Extract (yifanfeng97/Hyper-Extract)

Searching Database…

What is this?Hyper-Extract is a CLI tool that turns unstructured documents (PDFs, Word, text, etc.) into structured knowledge — chunk corpora, lists, graphs, hypergraphs, and spatio-temporal graphs — using LLMs, all from a single command.
Is this a CLI tool or a library?It's primarily a Python CLI (the `he` command), but it also ships a Python API and an MCP server mode so AI assistants like Claude Desktop can query the extracted knowledge directly.
How do I get it running?Install the package, configure one LLM provider (OpenAI, Anthropic, DeepSeek, Alibaba Bailian, or a local vLLM model), then run extract/query/visualize commands.
Do I need an API key from one of the LLM providers?Yes, unless you run a local model via vLLM. The model you choose must support tool/function calling, since Hyper-Extract relies on LangChain structured output.
Any gotchas when picking a provider?DeepSeek and Anthropic are LLM-only and have no embeddings API, so you must pair them with an OpenAI-compatible embedding model; DeepSeek's 'thinking' mode is also auto-disabled since it breaks structured extraction.
Can this run fully offline with my own data staying local?Yes, you can run everything locally with vLLM (e.g. Qwen3.5-9B plus a bge-m3 embedder), so no documents or extracted data leave your machine.
What document formats can it ingest besides plain text?With the ingest extra installed, it can parse PDF, Word, PowerPoint, Excel, HTML, EPUB and more, not just .txt/.md files.
What knowledge structures can it build?Nine typed structures ranging from simple lists and chunk corpora up to Graphs, Hypergraphs, and Spatio-Temporal Graphs, each backed by dedicated extraction engines like GraphRAG, LightRAG, Hyper-RAG, and KG-Gen.
How does it differ from tools like GraphRAG or LightRAG?Hyper-Extract adds spatial graphs, hypergraphs, and 80+ ready-made domain templates that those tools lack, plus an interactive CLI and multi-language support.
Can I export my extracted knowledge to Obsidian?Yes, any extracted graph can be exported as an Obsidian vault with Markdown notes linked by wikilinks.
Size
35.9 MB
Stars
4.2K
Age
9mo
Commits · 90 Days
