Topics / #token-optimization
Token-optimization projects on GitHub
Reducing token usage and context size in LLM workflows.
As of , the most-starred Token-optimization projects on GitHub are rtk (83.8K stars), headroom (75.6K stars) and OpenViking (40.2K stars). GitHub.Locker tracks 15 Token-optimization repositories with 252.7K stars combined. The fastest-growing on October 17 was billion-context, with +213 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +213
billion-context
ranxianglei/billion-context · ★ 1.9Kbillion-context is a context-compression proxy that sits between any coding agent and its model API, rewriting Anthropic/OpenAI streams so a 100K context window is enough and a single session can run for months across billions of tokens.
 +167
rtk
rtk-ai/rtk · ★ 83.8Krtk is a CLI proxy that filters and compresses command outputs before they reach your LLM context, cutting 60-90% of the bash output your coding agent reads and lowering token costs.
 +113
answer-me-with-html
QingYunA/answer-me-with-html · ★ 3.7KAnswer me with HTML is an agent skill that turns a coding agent's long text answers into a single-page HTML with diagrams, tables, or timelines instead of a wall of text. The model only writes a short Markdown draft and a bundled CLI renders the layout, CSS and SVG.
 +78
headroom
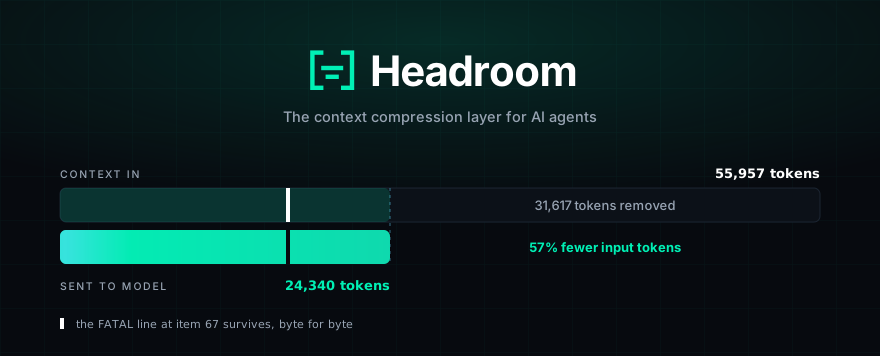
headroomlabs-ai/headroom · ★ 75.6KHeadroom compresses everything an AI agent reads - tool outputs, logs, RAG chunks, files, and conversation history - before it reaches the LLM, cutting tokens while keeping the same answers. It ships as a library, a local proxy, and an MCP server.
The all-time top
15 projects · by stars
- 83.8K
rtk
rtk is a CLI proxy that filters and compresses command outputs before they reach your LLM context, cutting 60-90% of the bash output your coding agent reads and lowering token costs.
- 75.6K#2 · headroomlabs-ai/headroom
headroom
Headroom compresses everything an AI agent reads - tool outputs, logs, RAG chunks, files, and conversation history - before it reaches the LLM, cutting tokens while keeping the same answers. It ships as a library, a local proxy, and an MCP server.
- 40.2K
 #3 · volcengine/OpenViking
OpenViking
An open-source context database for AI agents: memories, resources, and skills live in one virtual filesystem under the viking:// protocol, so the agent browses its own context with ls, tree, and find instead of querying a black-box vector store.
- 4
code-review-graph
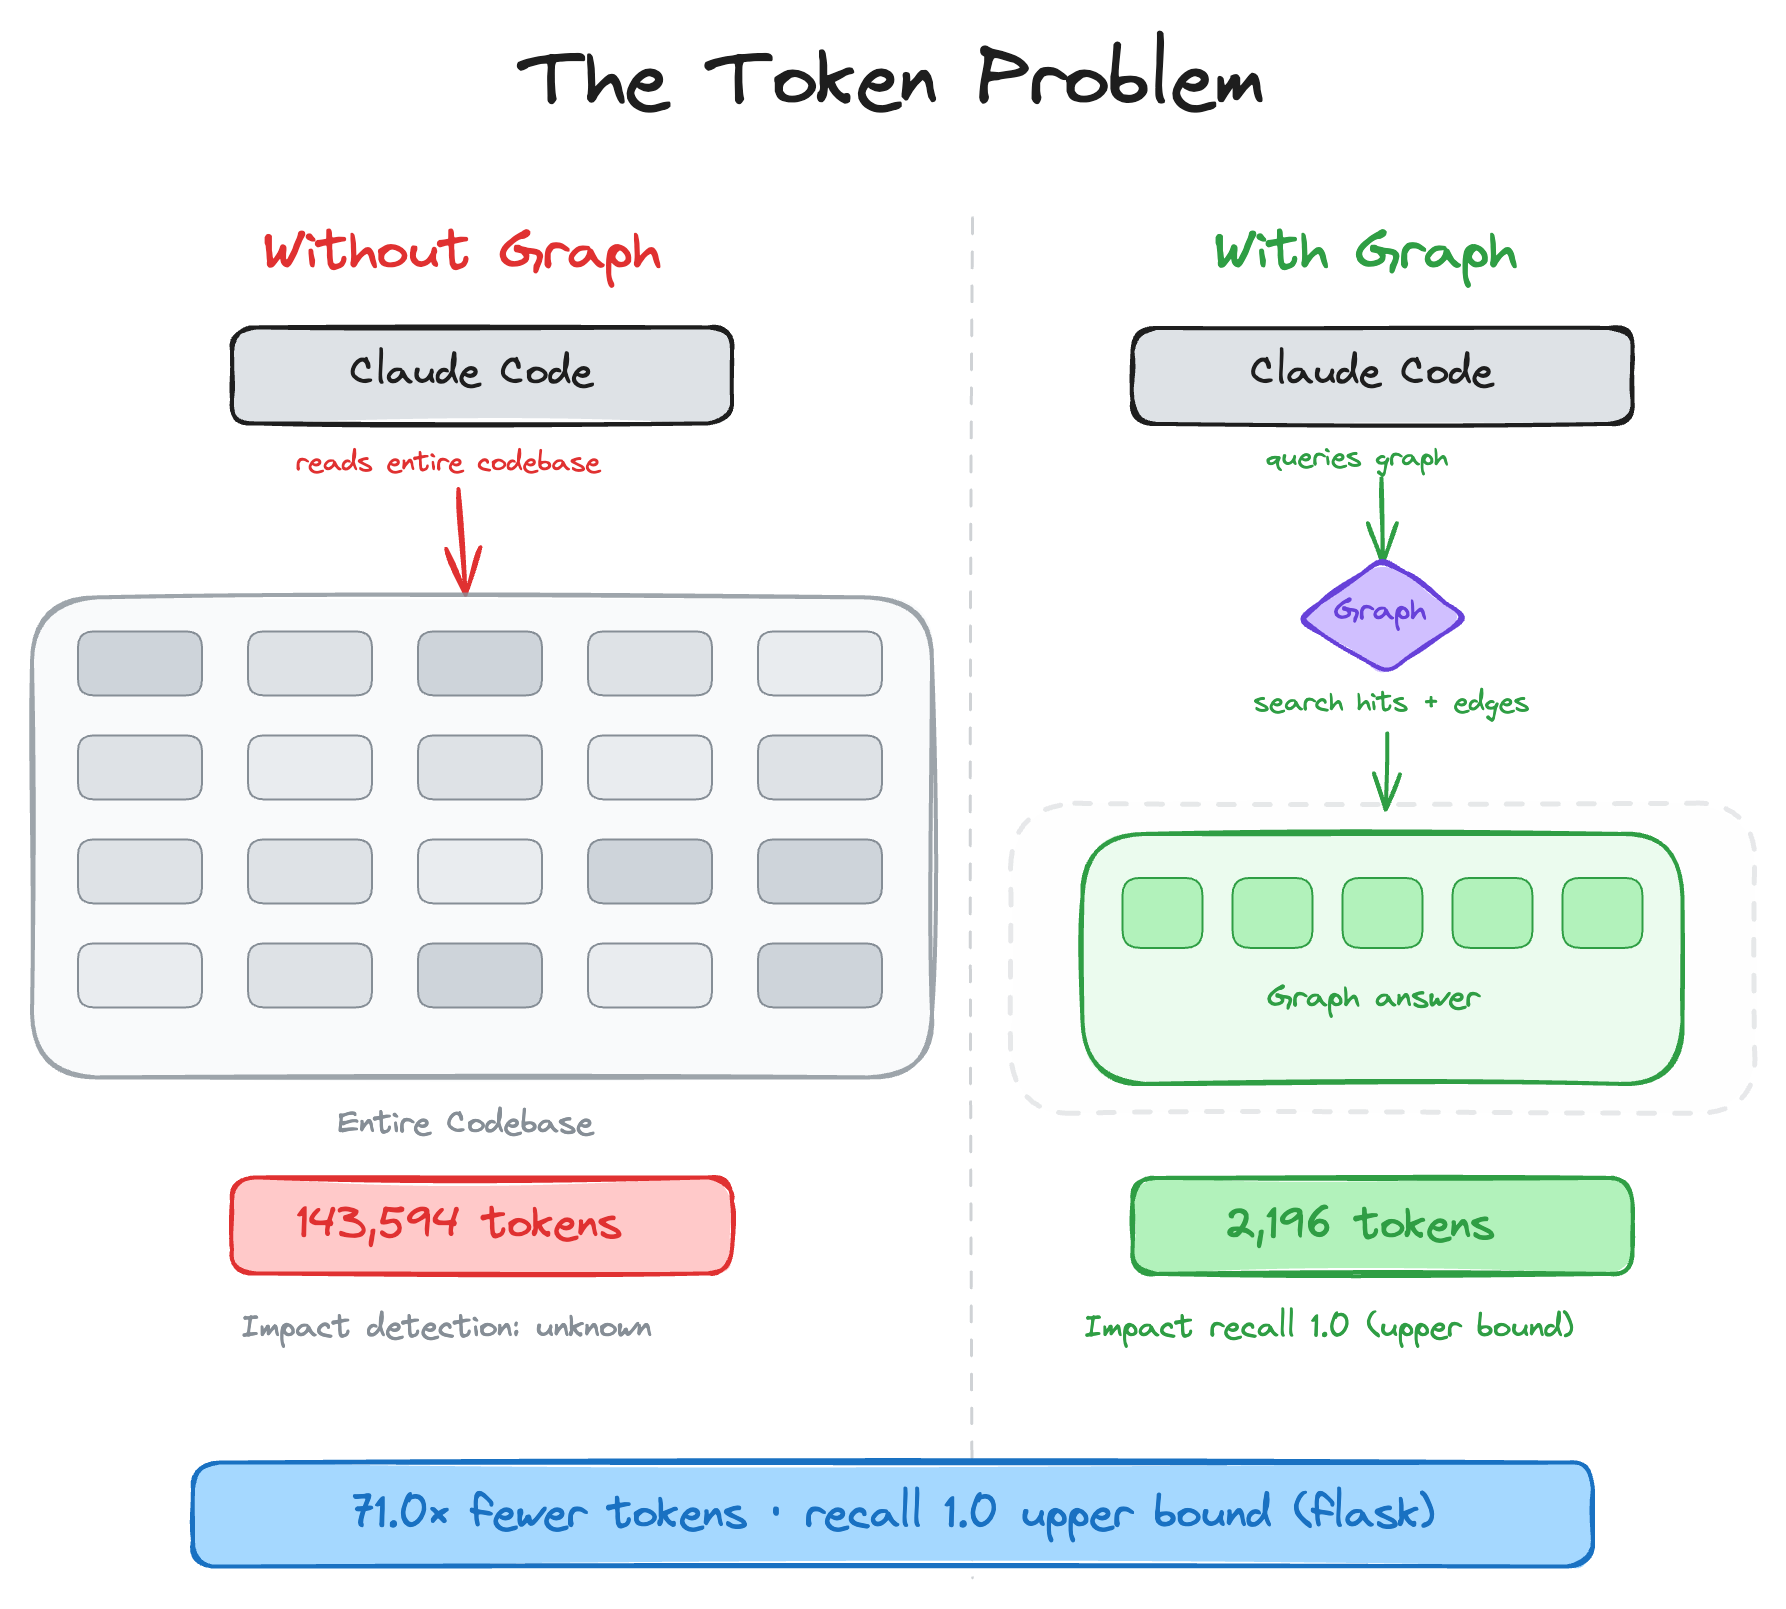
32.2Ktirth8205/code-review-graph · PythonA local-first code intelligence tool: it builds a persistent graph of your codebase so AI coding assistants read only the files that matter on review and large-repo tasks, instead of re-reading everything.
- 5
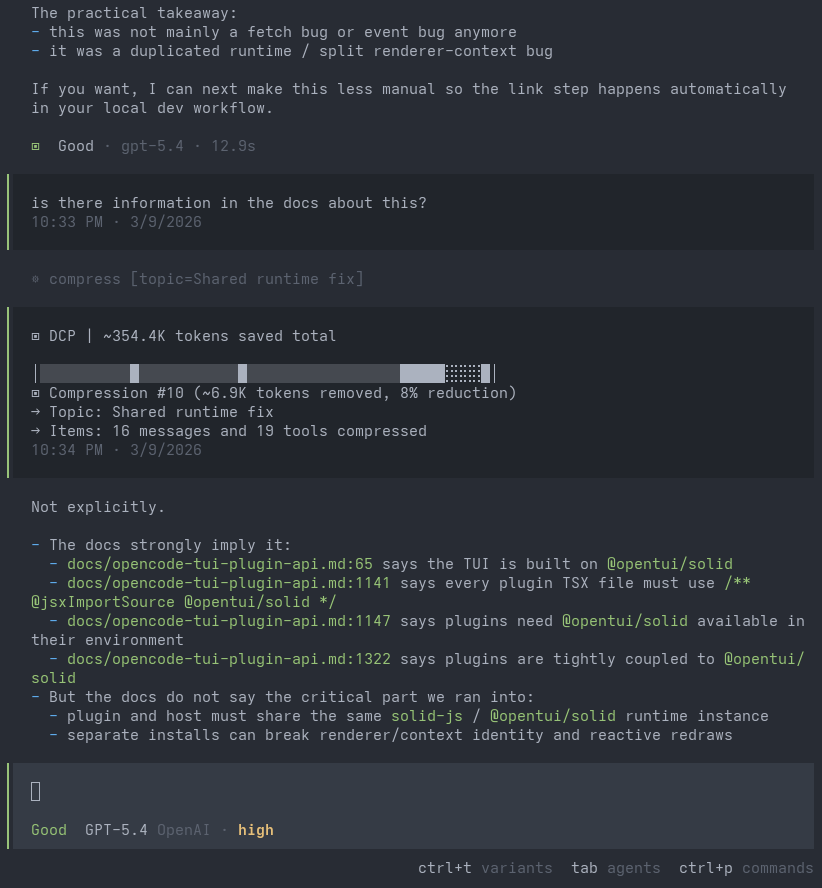
opencode-dynamic-context-pruning
4.4KTarquinen/opencode-dynamic-context-pruning · TypeScriptDynamic Context Pruning (DCP) is a plugin for OpenCode that automatically cuts token usage by intelligently managing conversation context — compressing stale history into summaries, deduplicating repeated tool calls, and purging failed tool-call inputs.
- 6
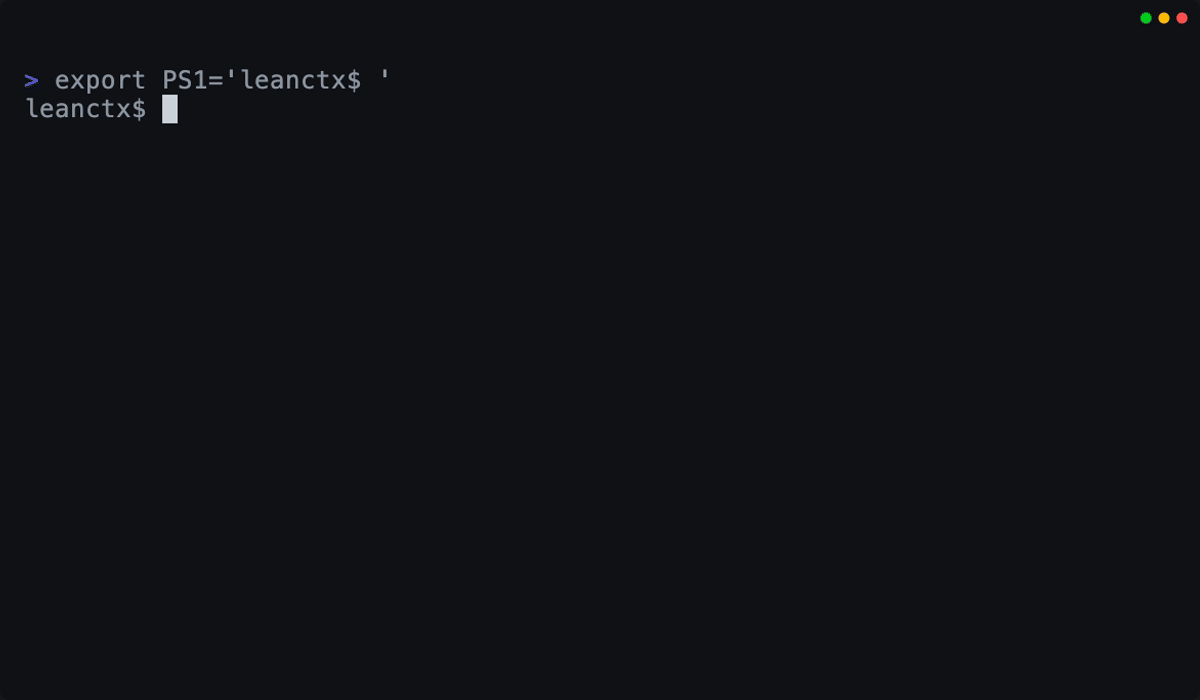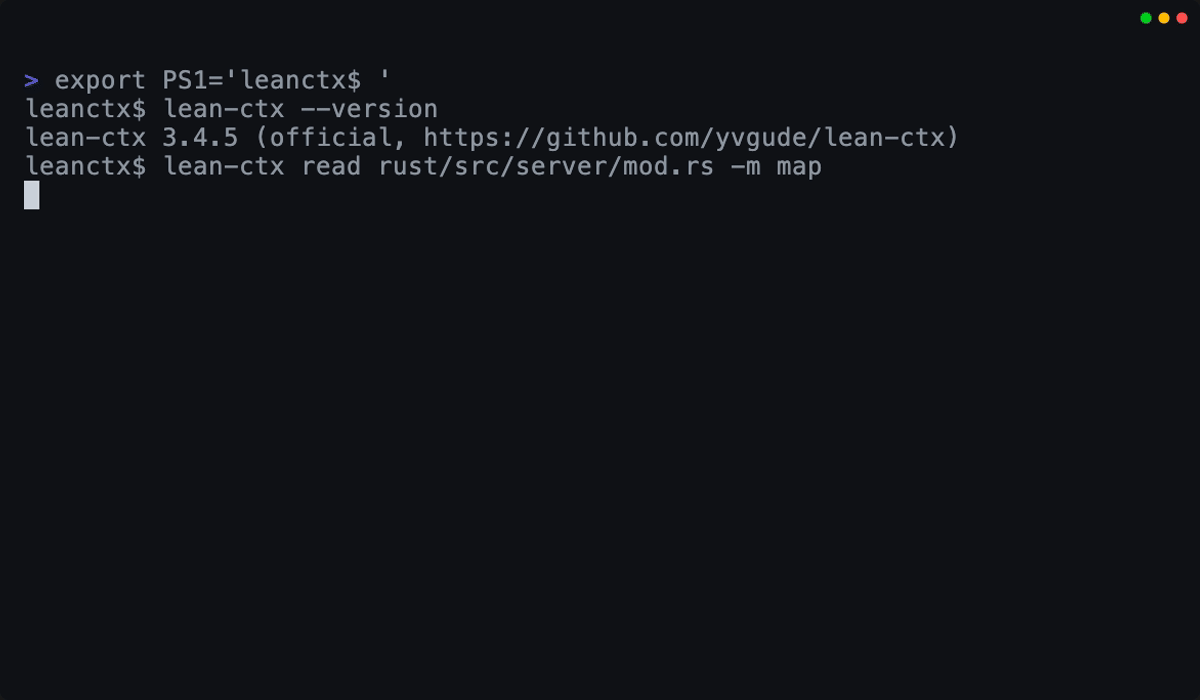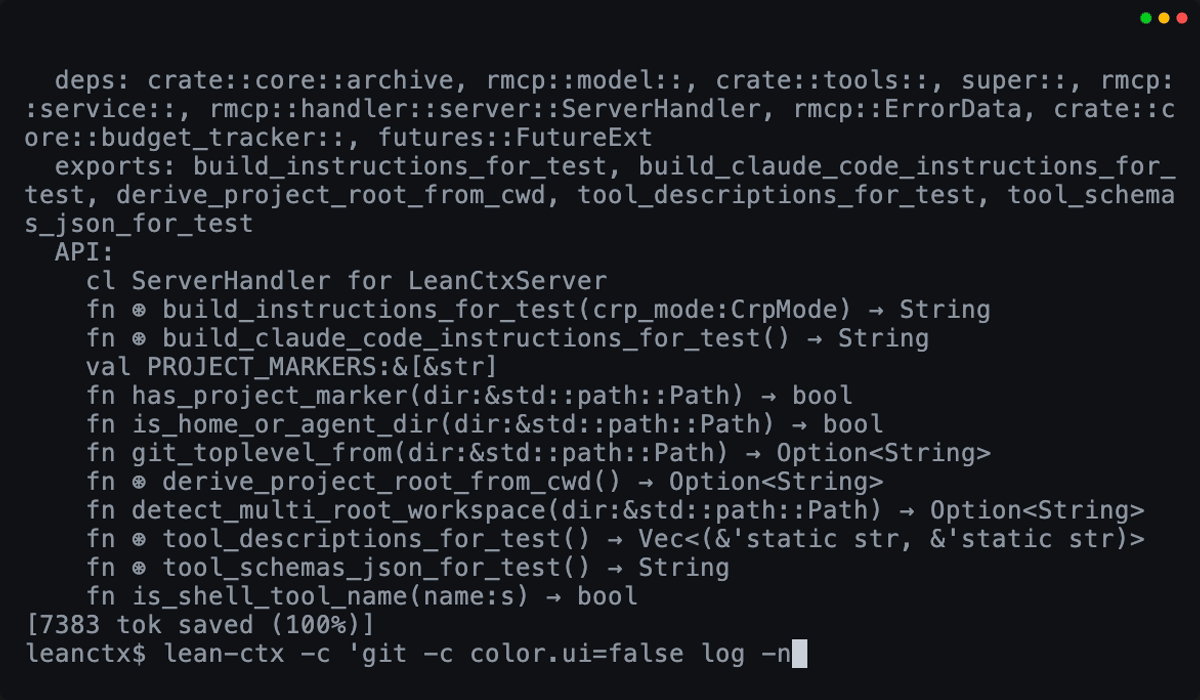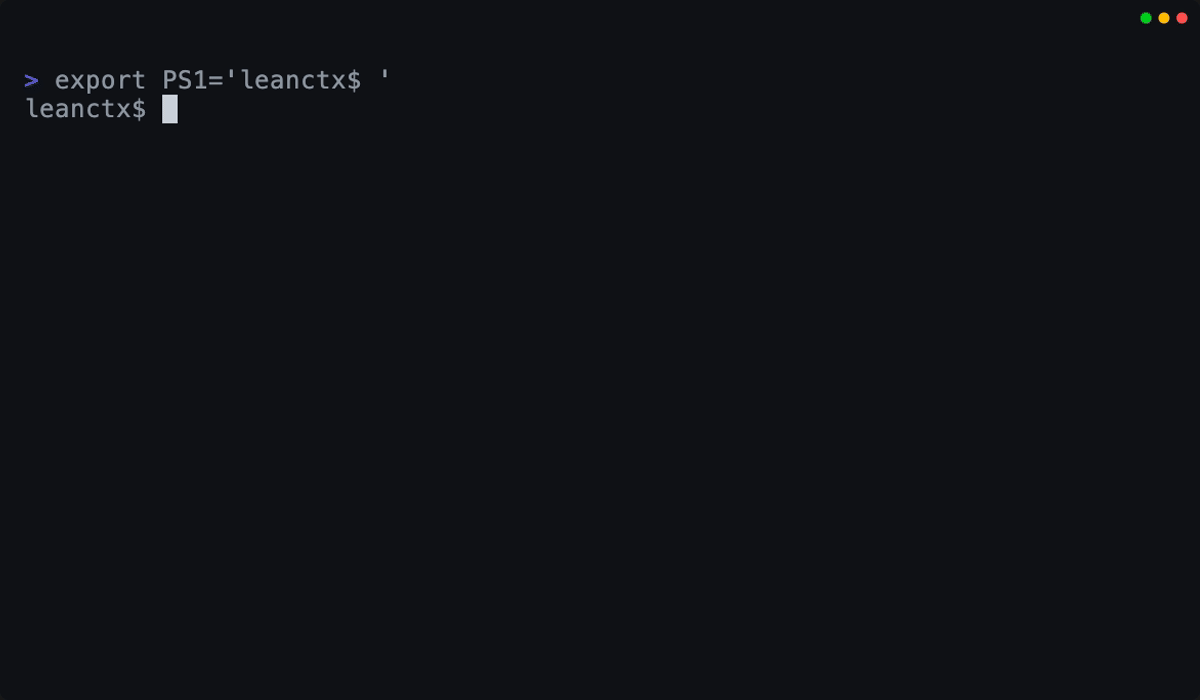
lean-ctx
3.9Kyvgude/lean-ctx · RustLeanCTX is a 'Context Gateway' that runs locally alongside your AI coding agent, deciding what context the model actually sees, compressing it, and tracking the cost and outcome of that work.
- 7
answer-me-with-html
3.7KQingYunA/answer-me-with-html · JavaScriptAnswer me with HTML is an agent skill that turns a coding agent's long text answers into a single-page HTML with diagrams, tables, or timelines instead of a wall of text. The model only writes a short Markdown draft and a bundled CLI renders the layout, CSS and SVG.
- 8
SoL-Pi
3.5KNVlabs/SoL-Pi · TypeScriptSoL-Pi is a standalone extension for the Pi coding agent that packages four efficiency mechanisms discovered through scaled auto-research loops. It cuts repeated model turns, context replay, oversized observations and long-log reading without dropping the work an agent needs.
- 9
billion-context
1.9Kranxianglei/billion-context · TypeScriptbillion-context is a context-compression proxy that sits between any coding agent and its model API, rewriting Anthropic/OpenAI streams so a 100K context window is enough and a single session can run for months across billions of tokens.
- 10
maki
1.2Ktontinton/maki · RustMaki is a terminal AI coding agent written in Rust, built to spend as few context tokens as possible, and extendable with neovim-style Lua plugins.
- 11
Step-Code
971stepfun-ai/Step-Code · TypeScriptStep Code is a terminal-based AI coding agent from StepFun: it handles the full task loop in your project — reading code, making changes, running tests — using Step models after you sign in.
- 12
jev-router
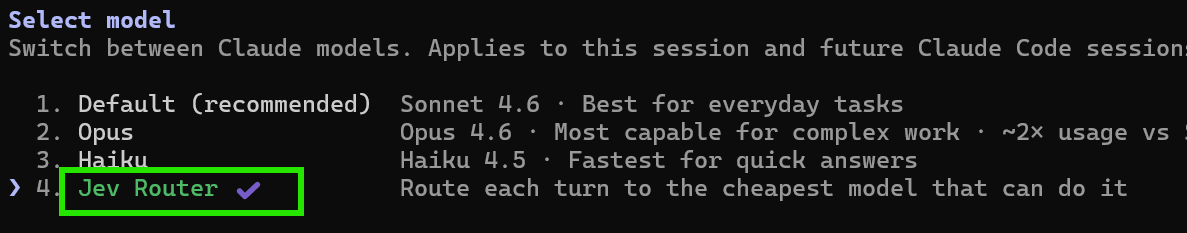
604gargpratyush/jev-router · JavaScriptjev-router automatically picks the cheapest capable AI model for each turn in Claude Code or OpenAI Codex, sending simple requests to a fast/cheap tier and hard requests to a stronger tier, while keeping each CLI's native interface, tools, and authentication untouched.
- 13
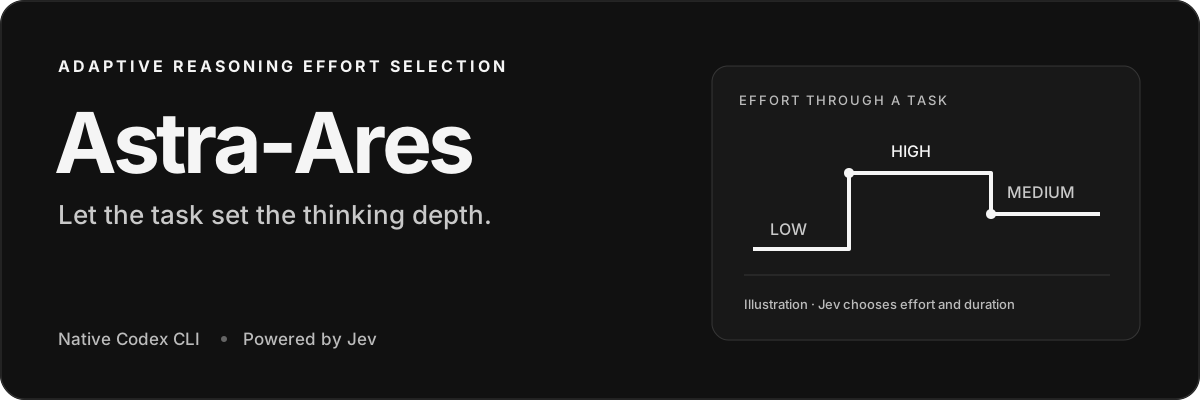
Astra-Ares
309miuuyy/Astra-Ares · JavaScriptAstra-Ares is an experimental tool that lets Jev, an AI evaluator, adapt GPT-6's reasoning effort while a Codex task runs, matching thinking depth to each next step to reduce token usage.
- 14
axiomcodegraph
200AxiomCodeAI/axiomcodegraph · TypeScriptAxiomCode Graph turns a codebase into a knowledge graph built with formal methods (compiler-style type resolution) rather than syntax guessing, so AI coding agents can look up exact callers, callees, call paths and affected tests instead of grepping through code.
- 15

Matryoshka
150yogthos/Matryoshka · TypeScriptMatryoshka (RLM) is an MCP server and CLI toolkit that lets LLM agents analyze documents up to 100x larger than their context window, by having the model emit symbolic 'Nucleus' commands that a logic engine called Lattice executes server-side, instead of chunking text into a vector database.
Related topics
Often tagged together