Agentic RAG for Dummies
Build a modular Agentic RAG system with LangGraph, conversation memory, and human-in-the-loop query clarification
Overview •
How It Works •
LLM Providers •
Implementation •
Installation & Usage •
Troubleshooting




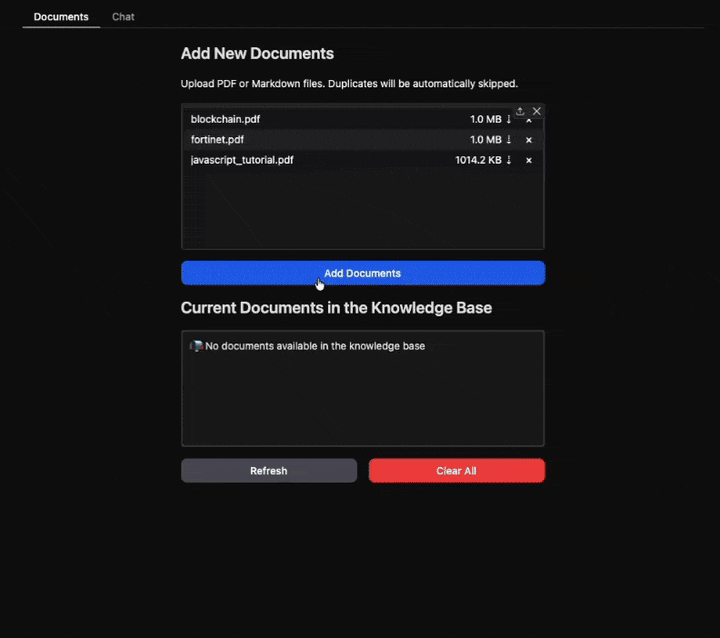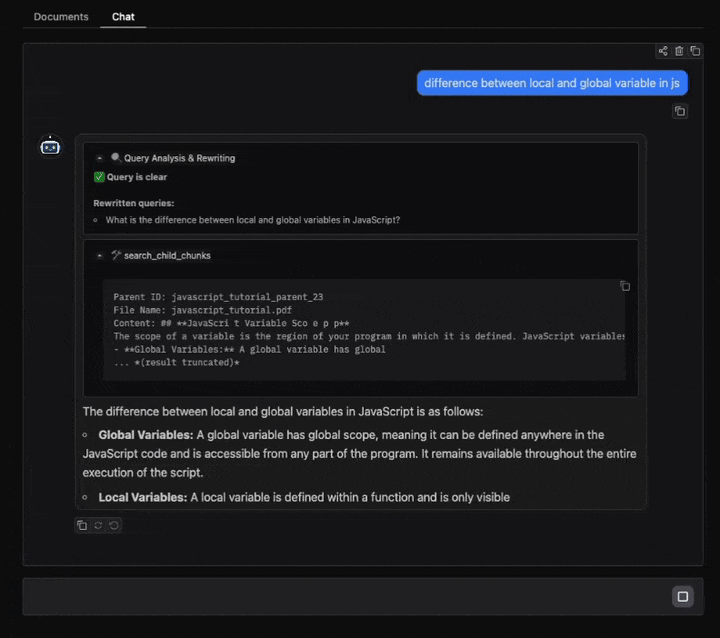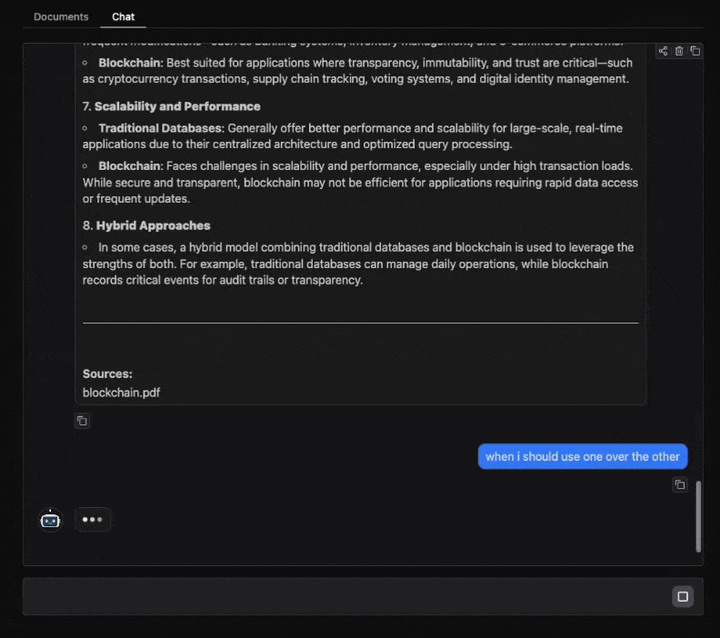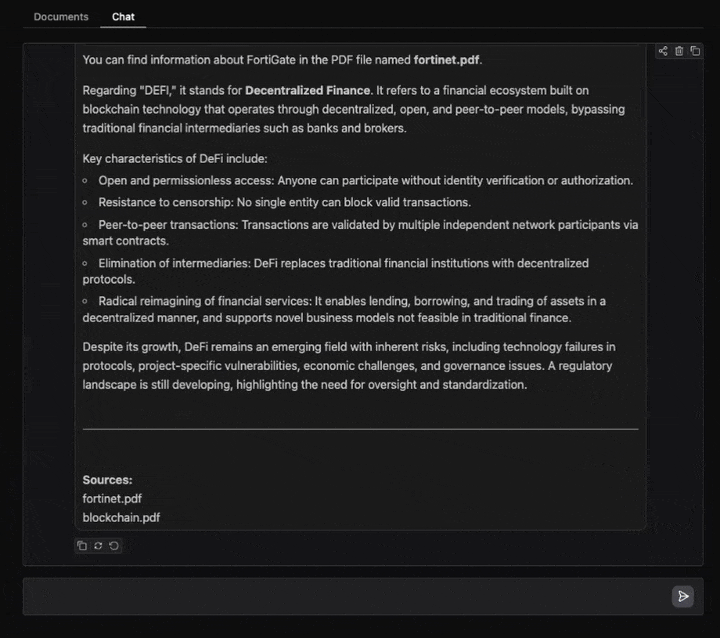
If you like this project, a star ⭐️ would mean a lot :)
Overview
This repository demonstrates how to build an Agentic RAG (Retrieval-Augmented Generation) system using LangGraph with minimal code. Most RAG tutorials show basic concepts but lack guidance on building modular, agent-driven systems — this project bridges that gap by providing both learning materials and an extensible architecture.
What's inside
| Feature |
Description |
| 🗂️ Hierarchical Indexing |
Search small chunks for precision, retrieve large Parent chunks for context |
| 🧠 Conversation Memory |
Maintains context across questions for natural dialogue |
| ❓ Query Clarification |
Rewrites ambiguous queries or pauses to ask the user for details |
| 🤖 Agent Orchestration |
LangGraph coordinates the full retrieval and reasoning workflow |
| 🔀 Multi-Agent Map-Reduce |
Decomposes complex queries into parallel sub-queries |
| ✅ Self-Correction |
Re-queries automatically if initial results are insufficient |
| 🗜️ Context Compression |
Keeps working memory lean across long retrieval loops |
| 🔍 Observability |
Track LLM calls, tool usage, and graph execution with Langfuse |
| 📊 Evaluation |
Evaluate retrieval and answer quality with RAGAS metrics |
🎯 Two Ways to Use This Repo
1️⃣ Learning Path: Interactive Notebook
Step-by-step tutorial perfect for understanding core concepts. Start here if you're new to Agentic RAG or want to experiment quickly.
2️⃣ Building Path: Modular Project
Flexible architecture where each component can be independently adapted — LLM provider, embedding model, PDF converter, and agent workflow. The runnable app is Ollama-first, and it can be adapted to any chat model provider supported by LangChain. Examples are included for Anthropic, OpenAI, and Google.
See Modular Architecture and Installation & Usage to get started.
How It Works
Document Preparation: Hierarchical Indexing
Before queries can be processed, documents are split twice for optimal retrieval:
- Parent Chunks: Bounded large sections based on Markdown headers (H1, H2, H3)
- Child Chunks: Small, fixed-size pieces derived from parents
Optional: 🐿️ Chunky is an open-source toolkit for reliable RAG pipelines: convert PDFs to Markdown, clean documents, inspect chunks, compare chunking strategies, and enrich metadata before building the vector store.
This combines the precision of small chunks for search with the contextual richness of large chunks for answer generation.
Query Processing: Four-Stage Intelligent Workflow
User Query → Conversation Summary → Query Rewriting → Query Clarification →
Parallel Agent Reasoning → Aggregation → Final Response
Stage 1 — Conversation Understanding: Maintains a rolling summary and recent conversation history to preserve continuity without indefinitely increasing context size.
Stage 2 — Query Clarification: Resolves references ("How do I update it?" → "How do I update SQL?"), splits multi-part questions into focused sub-queries, detects unclear inputs, and rewrites queries for optimal retrieval. Pauses for human input when clarification is needed.
Stage 3 — Intelligent Retrieval (Multi-Agent Map-Reduce): Spawns parallel agent subgraphs — one per sub-query. Each agent searches child chunks, fetches parent chunks for context, self-corrects if results are insufficient, compresses context to avoid redundant fetches, and falls back gracefully if the search budget is exhausted.
Example: "What is JavaScript? What is Python?" → 2 parallel agents execute simultaneously.
Stage 4 — Response Generation: Aggregates all agent responses into a single coherent answer.
LLM Provider Configuration
This system is provider-agnostic: the runnable app uses Ollama by default, and the chat model initialization can be adapted to any LLM provider available in LangChain. The examples below cover the most common options, but the same pattern applies to any other supported provider.
Note: Model names change frequently. Always check the official documentation for the latest available models and their identifiers before deploying.
Ollama (Local)
# Install Ollama from https://ollama.com
ollama pull granite4.1:8b
from langchain_ollama import ChatOllama

llm = ChatOllama(model="granite4.1:8b", temperature=0, seed=42)
⚠️ For reliable tool calling and instruction following, prefer models 8B+. Smaller models may ignore retrieval instructions or hallucinate. See Troubleshooting.
Cloud Providers
Click to expand
OpenAI GPT:
pip install -qU langchain-openai
from langchain_openai import ChatOpenAI
import os

os.environ["OPENAI_API_KEY"] = "your-api-key-here"
llm = ChatOpenAI(model="gpt-4o-mini", temperature=0)
Anthropic Claude:
pip install -qU langchain-anthropic
from langchain_anthropic import ChatAnthropic
import os

os.environ["ANTHROPIC_API_KEY"] = "your-api-key-here"
llm = ChatAnthropic(model="claude-sonnet-4-5-20250929", temperature=0)
Google Gemini
pip install -qU langchain-google-genai
import os
from langchain_google_genai import ChatGoogleGenerativeAI

os.environ["GOOGLE_API_KEY"] = "your-api-key-here"
llm = ChatGoogleGenerativeAI(model="gemini-2.5-flash", temperature=0)
Implementation
Additional details, extended explanations, and Langfuse observability are available in the notebook and full project. The companion evaluation notebook scores the final answers and the actual child/parent tool outputs used by the agent with direct RAGAS metric calls.
Step 1: Initial Setup and Configuration
Define paths and initialize core components.
import os
from pathlib import Path
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_qdrant.fastembed_sparse import FastEmbedSparse
from qdrant_client import QdrantClient

DOCS_DIR = "docs"  # Directory containing your pdf files
MARKDOWN_DIR = "markdown_docs" # Directory containing the pdfs converted to markdown
PARENT_STORE_PATH = "parent_store"  # Directory for parent chunk JSON files
CHILD_COLLECTION = "document_child_chunks"
DEFAULT_RETRIEVAL_K = 7
CHILD_CHUNK_SEPARATOR = "\n\n<CHILD_CHUNK_BOUNDARY>\n\n"

os.makedirs(DOCS_DIR, exist_ok=True)
os.makedirs(MARKDOWN_DIR, exist_ok=True)
os.makedirs(PARENT_STORE_PATH, exist_ok=True)

from langchain_ollama import ChatOllama
llm = ChatOllama(model="granite4.1:8b", temperature=0, seed=42)

dense_embeddings = HuggingFaceEmbeddings(model_name="Qwen/Qwen3-Embedding-0.6B")
sparse_embeddings = FastEmbedSparse(model_name="Qdrant/bm25")

client = QdrantClient(path="qdrant_db")
Set up Qdrant to store child chunks with hybrid search capabilities.
from qdrant_client.http import models as qmodels
from langchain_qdrant import QdrantVectorStore
from langchain_qdrant.qdrant import RetrievalMode

embedding_dimension = len(dense_embeddings.embed_query("test"))

def ensure_collection(collection_name):
    if not client.collection_exists(collection_name):
        client.create_collection(
            collection_name=collection_name,
            vectors_config=qmodels.VectorParams(
                size=embedding_dimension,
                distance=qmodels.Distance.COSINE
            ),
            sparse_vectors_config={
                "sparse": qmodels.SparseVectorParams()
            },
        )
Step 3: PDFs to Markdown
Convert the PDFs to Markdown. For more details about other techniques use this companion notebook.
import os
import pymupdf.layout
import pymupdf4llm
from pathlib import Path
import glob

os.environ["TOKENIZERS_PARALLELISM"] = "false"

def pdf_to_markdown(pdf_path, output_dir):
    doc = pymupdf.open(pdf_path)
    md = pymupdf4llm.to_markdown(doc, header=False, footer=False, page_separators=True, ignore_images=True, write_images=False, image_path=None)
    md_cleaned = md.encode('utf-8', errors='surrogatepass').decode('utf-8', errors='ignore')
    output_path = Path(output_dir) / Path(doc.name).stem
    Path(output_path).with_suffix(".md").write_bytes(md_cleaned.encode('utf-8'))

def pdfs_to_markdowns(path_pattern, overwrite: bool = False):
    output_dir = Path(MARKDOWN_DIR)
    output_dir.mkdir(parents=True, exist_ok=True)

    for pdf_path in map(Path, glob.glob(path_pattern)):
        md_path = (output_dir / pdf_path.stem).with_suffix(".md")
        if overwrite or not md_path.exists():
            pdf_to_markdown(pdf_path, output_dir)

pdfs_to_markdowns(f"{DOCS_DIR}/*.pdf")
Step 4: Hierarchical Document Indexing
Process documents with the Parent/Child splitting strategy.
import os
import glob
import json
from pathlib import Path
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
Parent & Child chunk processing functions
def merge_metadata(target, source, prepend=False):
    for key, value in source.items():
        if key not in target:
            target[key] = value
        else:
            first, second = (value, target[key]) if prepend else (target[key], value)
            values = [
                item.strip()
                for raw in (first, second)
                for item in str(raw).split(" -> ")
                if item.strip()
            ]
            target[key] = " -> ".join(dict.fromkeys(values))

def merge_small_parents(chunks, min_size):
    if not chunks:
        return []

    merged, current = [], None

    for chunk in chunks:
        if current is None:
            current = chunk
        else:
            current.page_content += "\n\n" + chunk.page_content
            merge_metadata(current.metadata, chunk.metadata)

        if len(current.page_content) >= min_size:
            merged.append(current)
            current = None

    if current:
        if merged:
            merged[-1].page_content += "\n\n" + current.page_content
            merge_metadata(merged[-1].metadata, current.metadata)
        else:
            merged.append(current)

    return merged

def split_large_parents(chunks, max_size, overlap):
    split_chunks = []

    for chunk in chunks:
        if len(chunk.page_content) <= max_size:
            split_chunks.append(chunk)
        else:
            large_splitter = RecursiveCharacterTextSplitter(
                chunk_size=max_size,
                chunk_overlap=overlap
            )
            sub_chunks = large_splitter.split_documents([chunk])
            split_chunks.extend(sub_chunks)

    return split_chunks

def rebalance_pair(first, second, min_size, max_size):
    combined = first.page_content.rstrip() + "\n\n" + second.page_content.lstrip()
    lower = max(1, len(combined) - max_size)
    upper = min(max_size, len(combined) - 1)
    if len(combined) >= 2 * min_size:
        lower = max(lower, min_size)
        upper = min(upper, len(combined) - min_size)
    preferred = min(max(len(combined) // 2, lower), upper)

    split_at = preferred
    for separator in ("\n\n", "\n", " "):
        before = combined.rfind(separator, lower, preferred + 1)
        after = combined.find(separator, preferred, upper + 1)
        if before >= lower:
            split_at = before
            break
        if after != -1:
            split_at = after
            break

    left_text = combined[:split_at].rstrip()
    right_text = combined[split_at:].lstrip()
    if len(combined) >= 2 * min_size and (len(left_text) < min_size or len(right_text) < min_size):
        split_at = preferred
        left_text, right_text = combined[:split_at], combined[split_at:]
    if not left_text or not right_text:
        return first, second

    metadata = dict(first.metadata)
    merge_metadata(metadata, second.metadata)
    first.page_content, first.metadata = left_text, dict(metadata)
    second.page_content, second.metadata = right_text, dict(metadata)
    return first, second

def clean_small_chunks(chunks, min_size, max_size):
    cleaned = []

    for i, chunk in enumerate(chunks):
        if len(chunk.page_content) < min_size:
            if cleaned and len(cleaned[-1].page_content) + 2 + len(chunk.page_content) <= max_size:
                cleaned[-1].page_content += "\n\n" + chunk.page_content
                merge_metadata(cleaned[-1].metadata, chunk.metadata)
            elif i < len(chunks) - 1 and len(chunk.page_content) + 2 + len(chunks[i + 1].page_content) <= max_size:
                chunks[i + 1].page_content = chunk.page_content + "\n\n" + chunks[i + 1].page_content
                merge_metadata(chunks[i + 1].metadata, chunk.metadata, prepend=True)
            else:
                cleaned.append(chunk)
        else:
            cleaned.append(chunk)

    for i, chunk in enumerate(cleaned):
        if len(chunk.page_content) >= min_size or len(cleaned) == 1:
            continue
        if i < len(cleaned) - 1:
            cleaned[i], cleaned[i + 1] = rebalance_pair(chunk, cleaned[i + 1], min_size, max_size)
        else:
            cleaned[i - 1], cleaned[i] = rebalance_pair(cleaned[i - 1], chunk, min_size, max_size)

    return cleaned
if client.collection_exists(CHILD_COLLECTION):
    client.delete_collection(CHILD_COLLECTION)
    ensure_collection(CHILD_COLLECTION)
else:
    ensure_collection(CHILD_COLLECTION)

child_vector_store = QdrantVectorStore(
    client=client,
    collection_name=CHILD_COLLECTION,
    embedding=dense_embeddings,
    sparse_embedding=sparse_embeddings,
    retrieval_mode=RetrievalMode.HYBRID,
    sparse_vector_name="sparse"
)

def index_documents():
    headers_to_split_on = [("#", "H1"), ("##", "H2"), ("###", "H3")]
    parent_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on, strip_headers=False)
    child_chunk_size = 500
    child_chunk_overlap = 100
    min_parent_size = 2000
    max_parent_size = 4000
    if min_parent_size <= 0 or max_parent_size < min_parent_size:
        raise ValueError("Parent chunk sizes must be positive and min_parent_size <= max_parent_size.")
    if not 0 <= child_chunk_overlap < child_chunk_size:
        raise ValueError("child_chunk_overlap must be smaller than child_chunk_size.")
    child_splitter = RecursiveCharacterTextSplitter(
        chunk_size=child_chunk_size,
        chunk_overlap=child_chunk_overlap,
    )

    all_parent_pairs, all_child_chunks = [], []
    md_files = sorted(glob.glob(os.path.join(MARKDOWN_DIR, "*.md")))

    if not md_files:
        return

    for doc_path_str in md_files:
        doc_path = Path(doc_path_str)
        try:
            with open(doc_path, "r", encoding="utf-8") as f:
                md_text = f.read()
        except Exception as e:
            continue

        parent_chunks = parent_splitter.split_text(md_text)
        merged_parents = merge_small_parents(parent_chunks, min_parent_size)
        split_parents = split_large_parents(merged_parents, max_parent_size, child_chunk_overlap)
        cleaned_parents = clean_small_chunks(split_parents, min_parent_size, max_parent_size)
        if any(len(chunk.page_content) > max_parent_size for chunk in cleaned_parents):
            raise ValueError("Parent chunking produced an oversized chunk.")

        for i, p_chunk in enumerate(cleaned_parents):
            parent_id = f"{doc_path.stem}_p{i}"
            p_chunk.metadata.update({"source": doc_path.stem + ".pdf", "parent_id": parent_id})
            all_parent_pairs.append((parent_id, p_chunk))
            children = child_splitter.split_documents([p_chunk])
            all_child_chunks.extend(children)

    if not all_child_chunks:
        return

    try:
        child_vector_store.add_documents(all_child_chunks)
    except Exception as e:
        return

    for item in os.listdir(PARENT_STORE_PATH):
        os.remove(os.path.join(PARENT_STORE_PATH, item))

    for parent_id, doc in all_parent_pairs:
        doc_dict = {"page_content": doc.page_content, "metadata": doc.metadata}
        filepath = os.path.join(PARENT_STORE_PATH, f"{parent_id}.json")
        with open(filepath, "w", encoding="utf-8") as f:
            json.dump(doc_dict, f, ensure_ascii=False, indent=2)

index_documents()
Create the retrieval tools the agent will use.
import json
from typing import List
from langchain_core.tools import tool

RETRIEVAL_SCORE_THRESHOLD = 0.4

@tool
def search_child_chunks(query: str, limit: int = DEFAULT_RETRIEVAL_K) -> str:
    """Search document excerpts for evidence related to the user question.

    Use this as the first retriev

 It is a learning project and modular codebase that shows how to build an Agentic RAG (Retrieval-Augmented Generation) system using LangGraph, including conversation memory and human-in-the-loop query clarification.