
1.8K ·GitHub
What is this?
 WeMM-Embedding is a family of multimodal embedding models (2B, 4B, 9B) built by the WeChat Vision Team at Tencent that produce unified embeddings for text, images, videos, visual documents, and interleaved multimodal inputs for search and retrieval tasks.
Is this an app I run, or a model I load into my own code?It is a set of pretrained model checkpoints released on Hugging Face plus example code — you load it like any Transformers or Sentence Transformers model, there is no standalone application.
It is a set of pretrained model checkpoints released on Hugging Face plus example code — you load it like any Transformers or Sentence Transformers model, there is no standalone application.How do I get embeddings out of it?Load a checkpoint such as tencent/WeMM-Embedding-2B with Transformers or Sentence Transformers and call encode() on text, image, or video inputs; the last-layer hidden state at a dedicated token is L2-normalized to produce the embedding vector.
Load a checkpoint such as tencent/WeMM-Embedding-2B with Transformers or Sentence Transformers and call encode() on text, image, or video inputs; the last-layer hidden state at a dedicated token is L2-normalized to produce the embedding vector.Which library versions does it need?The README recommends transformers==5.2.0 for correct preprocessing, and for serving it has been tested with vLLM 0.27.0 or SGLang 0.5.9.
The README recommends transformers==5.2.0 for correct preprocessing, and for serving it has been tested with vLLM 0.27.0 or SGLang 0.5.9.Can I embed audio with this too?No — all three model sizes handle text, images, videos, and visual documents, but audio input is explicitly not supported yet.
No — all three model sizes handle text, images, videos, and visual documents, but audio input is explicitly not supported yet.What sizes does WeMM-Embedding come in, and how do the dimensions work?It ships in 2B, 4B, and 9B parameter sizes, each trained with Matryoshka Representation Learning so embeddings can be truncated down to as few as 64 dimensions while keeping most of the accuracy — the 2B model at 256 dimensions retains 98.7% of its full image/video performance on MMEB-v2.
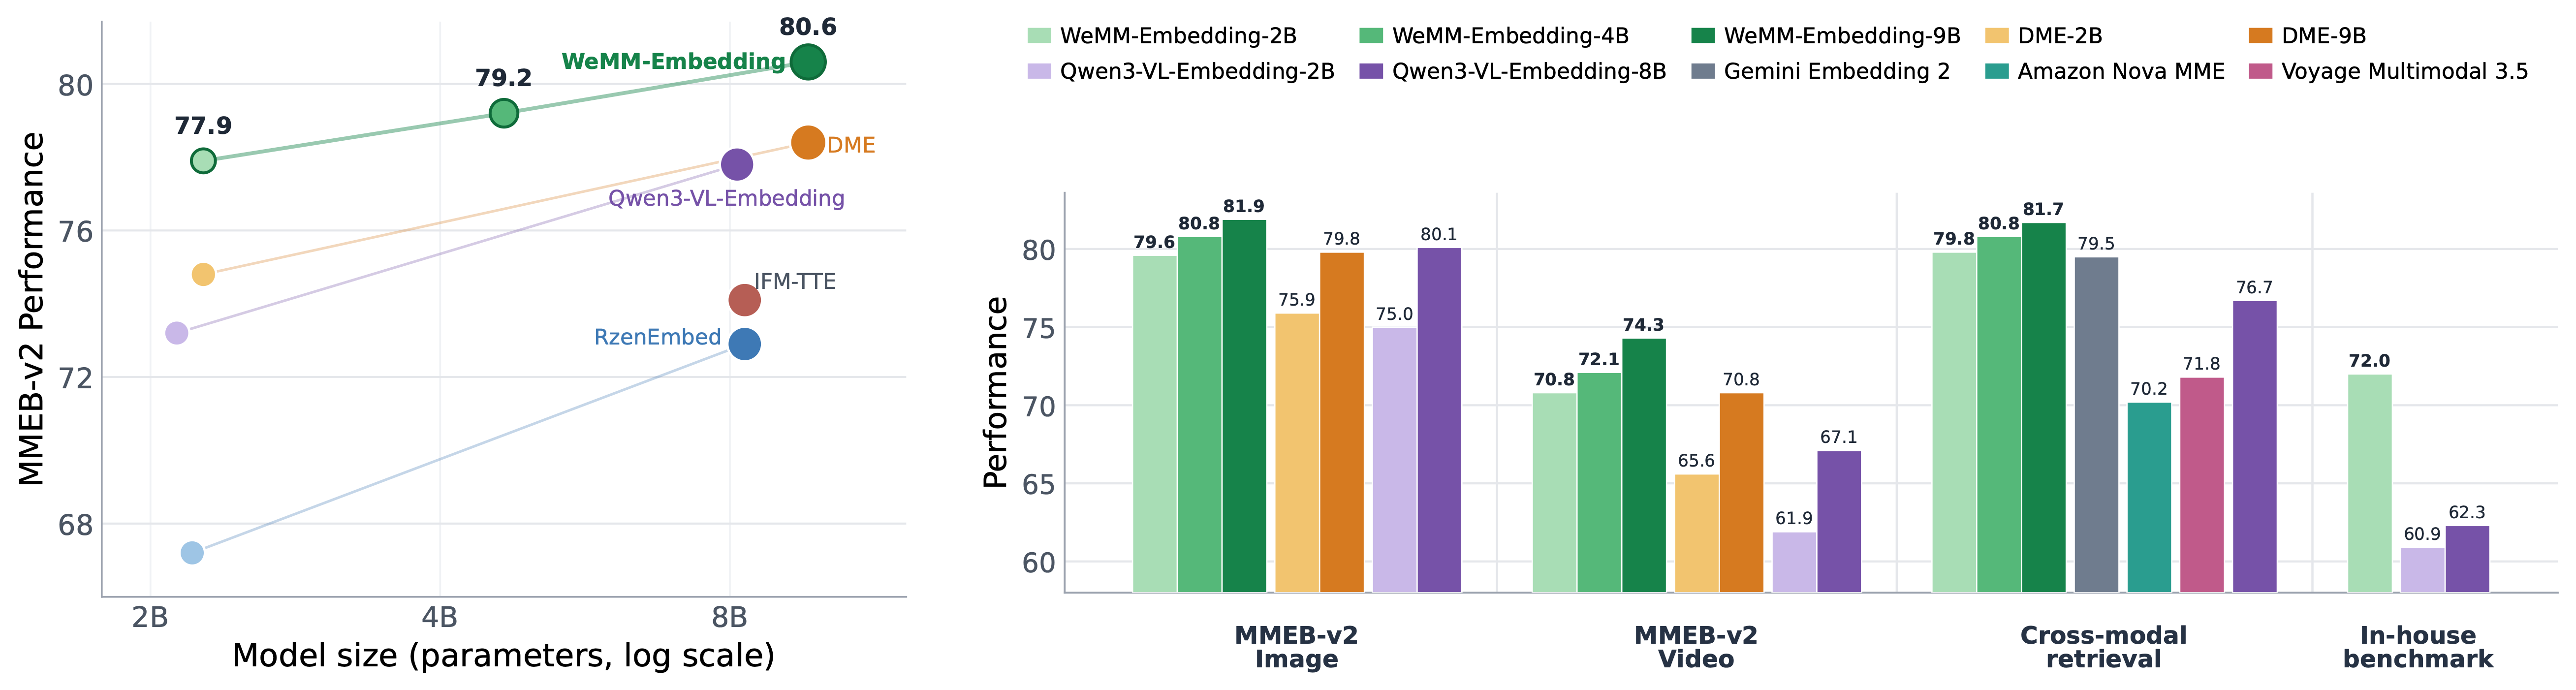
It ships in 2B, 4B, and 9B parameter sizes, each trained with Matryoshka Representation Learning so embeddings can be truncated down to as few as 64 dimensions while keeping most of the accuracy — the 2B model at 256 dimensions retains 98.7% of its full image/video performance on MMEB-v2.How does it compare to other multimodal embedding models?On MMEB-v2 (78 datasets) the 9B model scores 80.6 average versus 77.8 for Qwen3-VL-Embedding-8B and 59.2 for GME-8B, and it also leads on the broader 190-task MMEB-v3 benchmark.
On MMEB-v2 (78 datasets) the 9B model scores 80.6 average versus 77.8 for Qwen3-VL-Embedding-8B and 59.2 for GME-8B, and it also leads on the broader 190-task MMEB-v3 benchmark.Can I serve it as an API instead of running it inline?Yes — the repo ships ready-made wrapper scripts (scripts/servevllm.sh and scripts/servesglang.sh) to stand up the models behind vLLM or SGLang for serving.
Yes — the repo ships ready-made wrapper scripts (scripts/servevllm.sh and scripts/servesglang.sh) to stand up the models behind vLLM or SGLang for serving.What are similar projects?SimpleMem, Hy-MT2, Qwen3.8, NeoHorse, Hy4-preview, OraRL, halo, Unlimited-OCR
SimpleMem, Hy-MT2, Qwen3.8, NeoHorse, Hy4-preview, OraRL, halo, Unlimited-OCRWhich topics is it in?retrieval, sglang, image, transformers, wechat, semantic-search, vllm, embeddings, multimodal, video, rag, inference
retrieval, sglang, image, transformers, wechat, semantic-search, vllm, embeddings, multimodal, video, rag, inference