Topics / #data-quality
Data-quality projects on GitHub
Profiling, validating and monitoring the quality of datasets.
As of , the most-starred Data-quality projects on GitHub are Made-With-ML (49.8K stars), data-engineer-handbook (44.5K stars) and applied-ml (30.6K stars). GitHub.Locker tracks 12 Data-quality repositories with 189.9K stars combined. The fastest-growing on October 16 was OpenMetadata, with +14 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +14
OpenMetadata
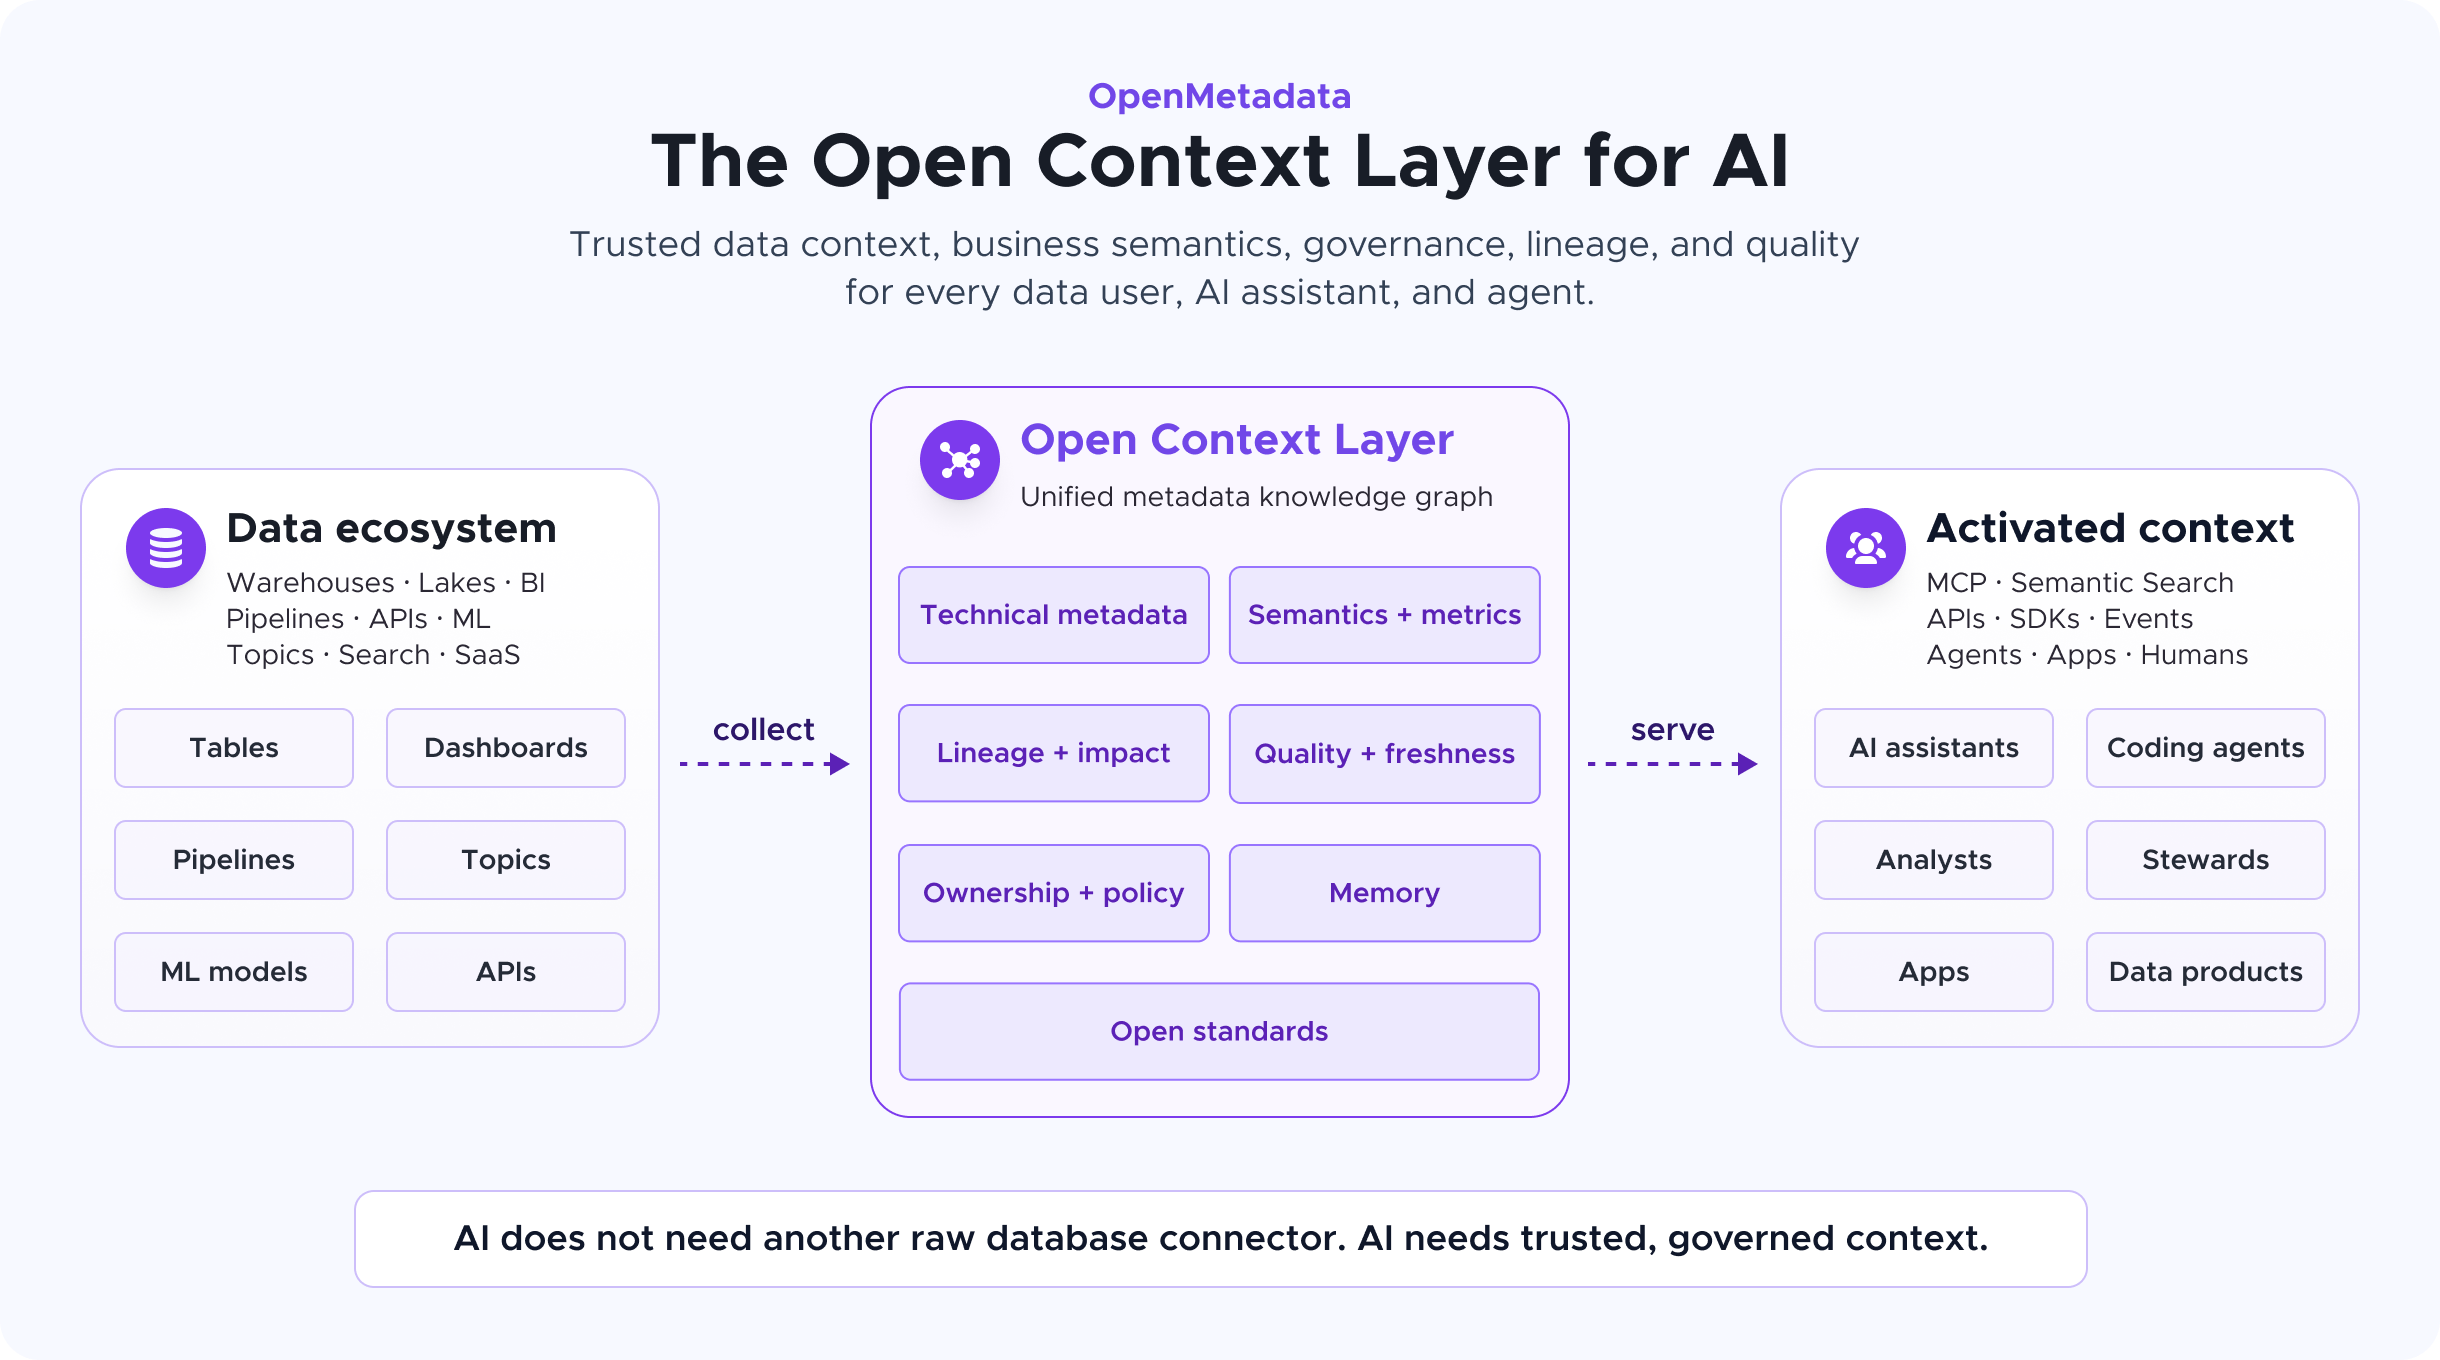
open-metadata/OpenMetadata · ★ 15.5KOpenMetadata is an open platform that unifies technical metadata, lineage, data quality, ownership and business glossaries into one knowledge graph so both humans and AI agents can discover, trust and reuse context about enterprise data.
 +10
Made-With-ML
GokuMohandas/Made-With-ML · ★ 49.8KMade-With-ML is a free hands-on course that teaches how to design, develop, deploy, and iterate on production-grade machine learning applications, combining ML with software engineering best practices.
 +9
data-engineer-handbook
DataExpert-io/data-engineer-handbook · ★ 44.5KA curated handbook of links and resources for learning data engineering: roadmaps, bootcamp materials, books, communities, company tooling lists, blogs, whitepapers, and a directory of data engineering content creators.
 +8
applied-ml
eugeneyan/applied-ml · ★ 30.6Kapplied-ml is a curated collection of papers, articles, and tech blogs where companies like Airbnb, Uber, Netflix, Google, and DoorDash share how they run data science and machine learning in production.
The all-time top
12 projects · by stars
- 49.8K#1 · GokuMohandas/Made-With-ML
Made-With-ML
Made-With-ML is a free hands-on course that teaches how to design, develop, deploy, and iterate on production-grade machine learning applications, combining ML with software engineering best practices.
- 44.5K#2 · DataExpert-io/data-engineer-handbook
data-engineer-handbook
A curated handbook of links and resources for learning data engineering: roadmaps, bootcamp materials, books, communities, company tooling lists, blogs, whitepapers, and a directory of data engineering content creators.
- 30.6K#3 · eugeneyan/applied-ml
applied-ml
applied-ml is a curated collection of papers, articles, and tech blogs where companies like Airbnb, Uber, Netflix, Google, and DoorDash share how they run data science and machine learning in production.
- 4
OpenMetadata
15.5Kopen-metadata/OpenMetadata · TypeScriptOpenMetadata is an open platform that unifies technical metadata, lineage, data quality, ownership and business glossaries into one knowledge graph so both humans and AI agents can discover, trust and reuse context about enterprise data.
- 5
fg-data-profiling
13.7KData-Centric-AI-Community/fg-data-profiling · Pythonfg-data-profiling (formerly ydata-profiling / pandas-profiling) is a Python package that generates a one-line exploratory data analysis (EDA) report for pandas or Spark DataFrames, similar to df.describe() but far more detailed.
- 6

great_expectations
11.9Kfivetran/great_expectations · PythonGX Core (Great Expectations) is a Python framework for testing, validating, and documenting the quality of your data. Its core concept is the 'Expectation' — an expressive unit test for your data, built from the collective experience of thousands of data quality deployments.
- 7
cleanlab
11.7Kcleanlab/cleanlab · PythonCleanlab is an open-source Python library that automatically finds issues in ML datasets — label errors, outliers, duplicates — using your existing models, so that fixing the data trains better models.
- 8
fiftyone
11.2Kvoxel51/fiftyone · TypeScriptFiftyOne is an open-source tool for building high-quality datasets and computer vision models: you use it to visualize and label your visual data, evaluate models, and find and fix data quality issues.
- 9

huashu-excel
439alchaincyf/huashu-excel · PythonThis is a Skill for AI coding agents that handles the entire Excel/data-analysis workflow: it profiles a messy spreadsheet, cleans it, aligns with the user on what to actually analyze, runs the analysis, reconciles the numbers against the sheet's own totals, and only then delivers a report.
- 10
hflow
298Hebbian-Robotics/hflow · PythonHFlow is an open source SDK from Hebbian Robotics (YC S26) for building scalable multimodal data pipelines for robotics and physical AI, letting teams verify the quality of the data they use to train AI models.
- 11

full-stack-data-engineering
145schumannx/full-stack-data-engineering · PythonA full reference implementation of a streaming data warehouse on AWS: playback events flow from Kafka into a five-zone S3 Iceberg lake, get modeled with Kimball dimensional design, and are served through Athena SQL and HTML reports, all orchestrated by self-hosted Apache Airflow 3.
- 12

workbooklens
142chenweixin123/workbooklens · PythonWorkbookLens is a local-first tool that lints, regression-tests, semantic-diffs, and conservatively repairs Excel workbooks, running entirely on your machine without Excel, LibreOffice, an AI key, or a cloud service.
Related topics
Often tagged together
- python2,383
- data-engineering56
- open-source5,666
- data-science231
- developer-tools2,924
- apache-2.01,434
- linux4,184
- machine-learning916
- cli2,227
- deep-learning737
- macos3,544
- windows3,403
- ai1,955
- data-cleaning5
- library1,587
- orchestration218
- big-data59
- cross-platform2,623
- data-analysis73
- data-validation8
- docker1,660
- mit3,312
- mlops47
- self-hosted1,929