Topics / #crawler
Crawler projects on GitHub
Web crawlers and scrapers that systematically fetch site content.
As of , the most-starred Crawler projects on GitHub are firecrawl (192.2K stars), Scrapling (88.1K stars) and crawl4ai (85.7K stars). GitHub.Locker tracks 54 Crawler repositories with 1.2M stars combined. The fastest-growing on October 16 was firecrawl, with +334 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +334
firecrawl
firecrawl/firecrawl · ★ 192.2KFirecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
 +201
Scrapling
D4Vinci/Scrapling · ★ 88.1KScrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
 +159
apify-mcp-server
apify/apify-mcp-server · ★ 11.6KThe Apify MCP Server lets AI agents and assistants extract data from websites like social media, search engines, maps, and e-commerce sites by giving them access to thousands of ready-made scrapers and automation tools from the Apify Store.
 +71
creatorhub
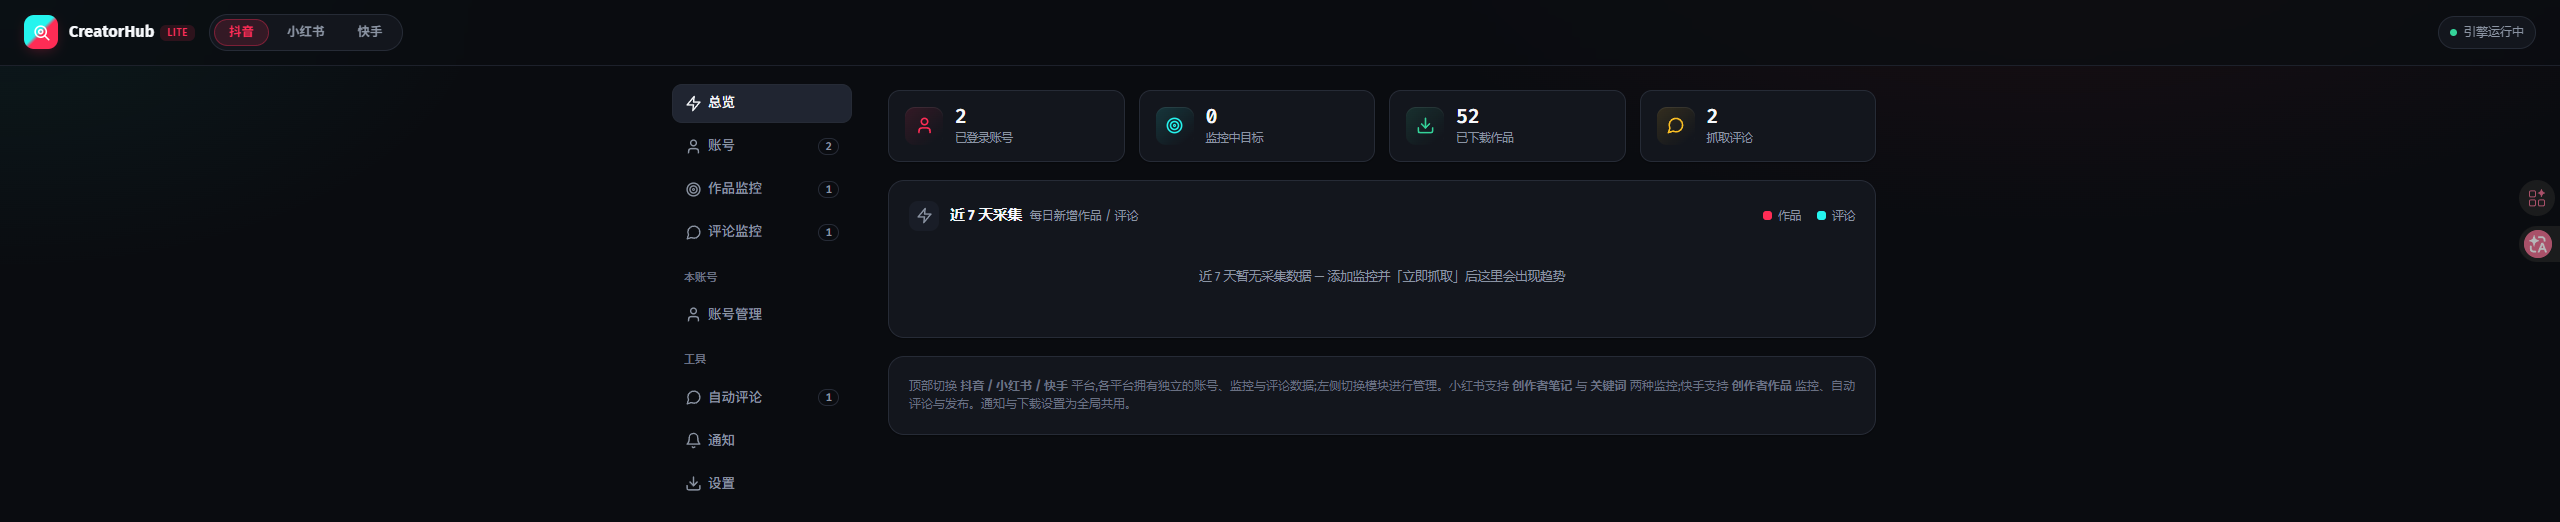
3441293738/creatorhub · ★ 2.4KCreatorHub 可以把开源的 fingerprint-chromium 作为其他平台的可插拔 Chromium 运行时。账号、Profile、Cookie、代理、LRU 和风控仍由 CreatorHub 管理,不需要外部商业浏览器或云端账号。小红书始终使用系统 Chrome/CDP: 第三方指纹内核与既有 Profile 混用容易造成 UA/Client Hints、GPU 和站点持久状态不一致, 从而增加设备安全验证;后端、登录接口和账号设置页都会拒绝该组合。
The all-time top
54 projects · by stars
- 192.2K#1 · firecrawl/firecrawl
firecrawl
Firecrawl turns any website into clean, LLM-ready data by crawling, scraping, and searching the web, delivering markdown, structured JSON, or screenshots that AI agents can consume directly.
- 88.1K#2 · D4Vinci/Scrapling
Scrapling
Scrapling is an adaptive web scraping framework for Python that handles everything from a single HTTP request to a full-scale concurrent crawl, with built-in anti-bot bypass.
- 85.7K
 #3 · unclecode/crawl4ai
crawl4ai
Crawl4AI is an open-source web crawler and scraper that turns any website into clean, LLM-ready Markdown for RAG pipelines, AI agents, and data extraction workflows.
- 4
MediaCrawler
67KNanmiCoder/MediaCrawler · PythonA multi-platform crawler for Chinese social media: it collects keyword search results, specific posts, and their comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu.
- 5

scrapy
64.9Kscrapy/scrapy · PythonScrapy is a fast, high-level web scraping and crawling framework for Python that extracts structured data from websites.
- 6
EasySpider
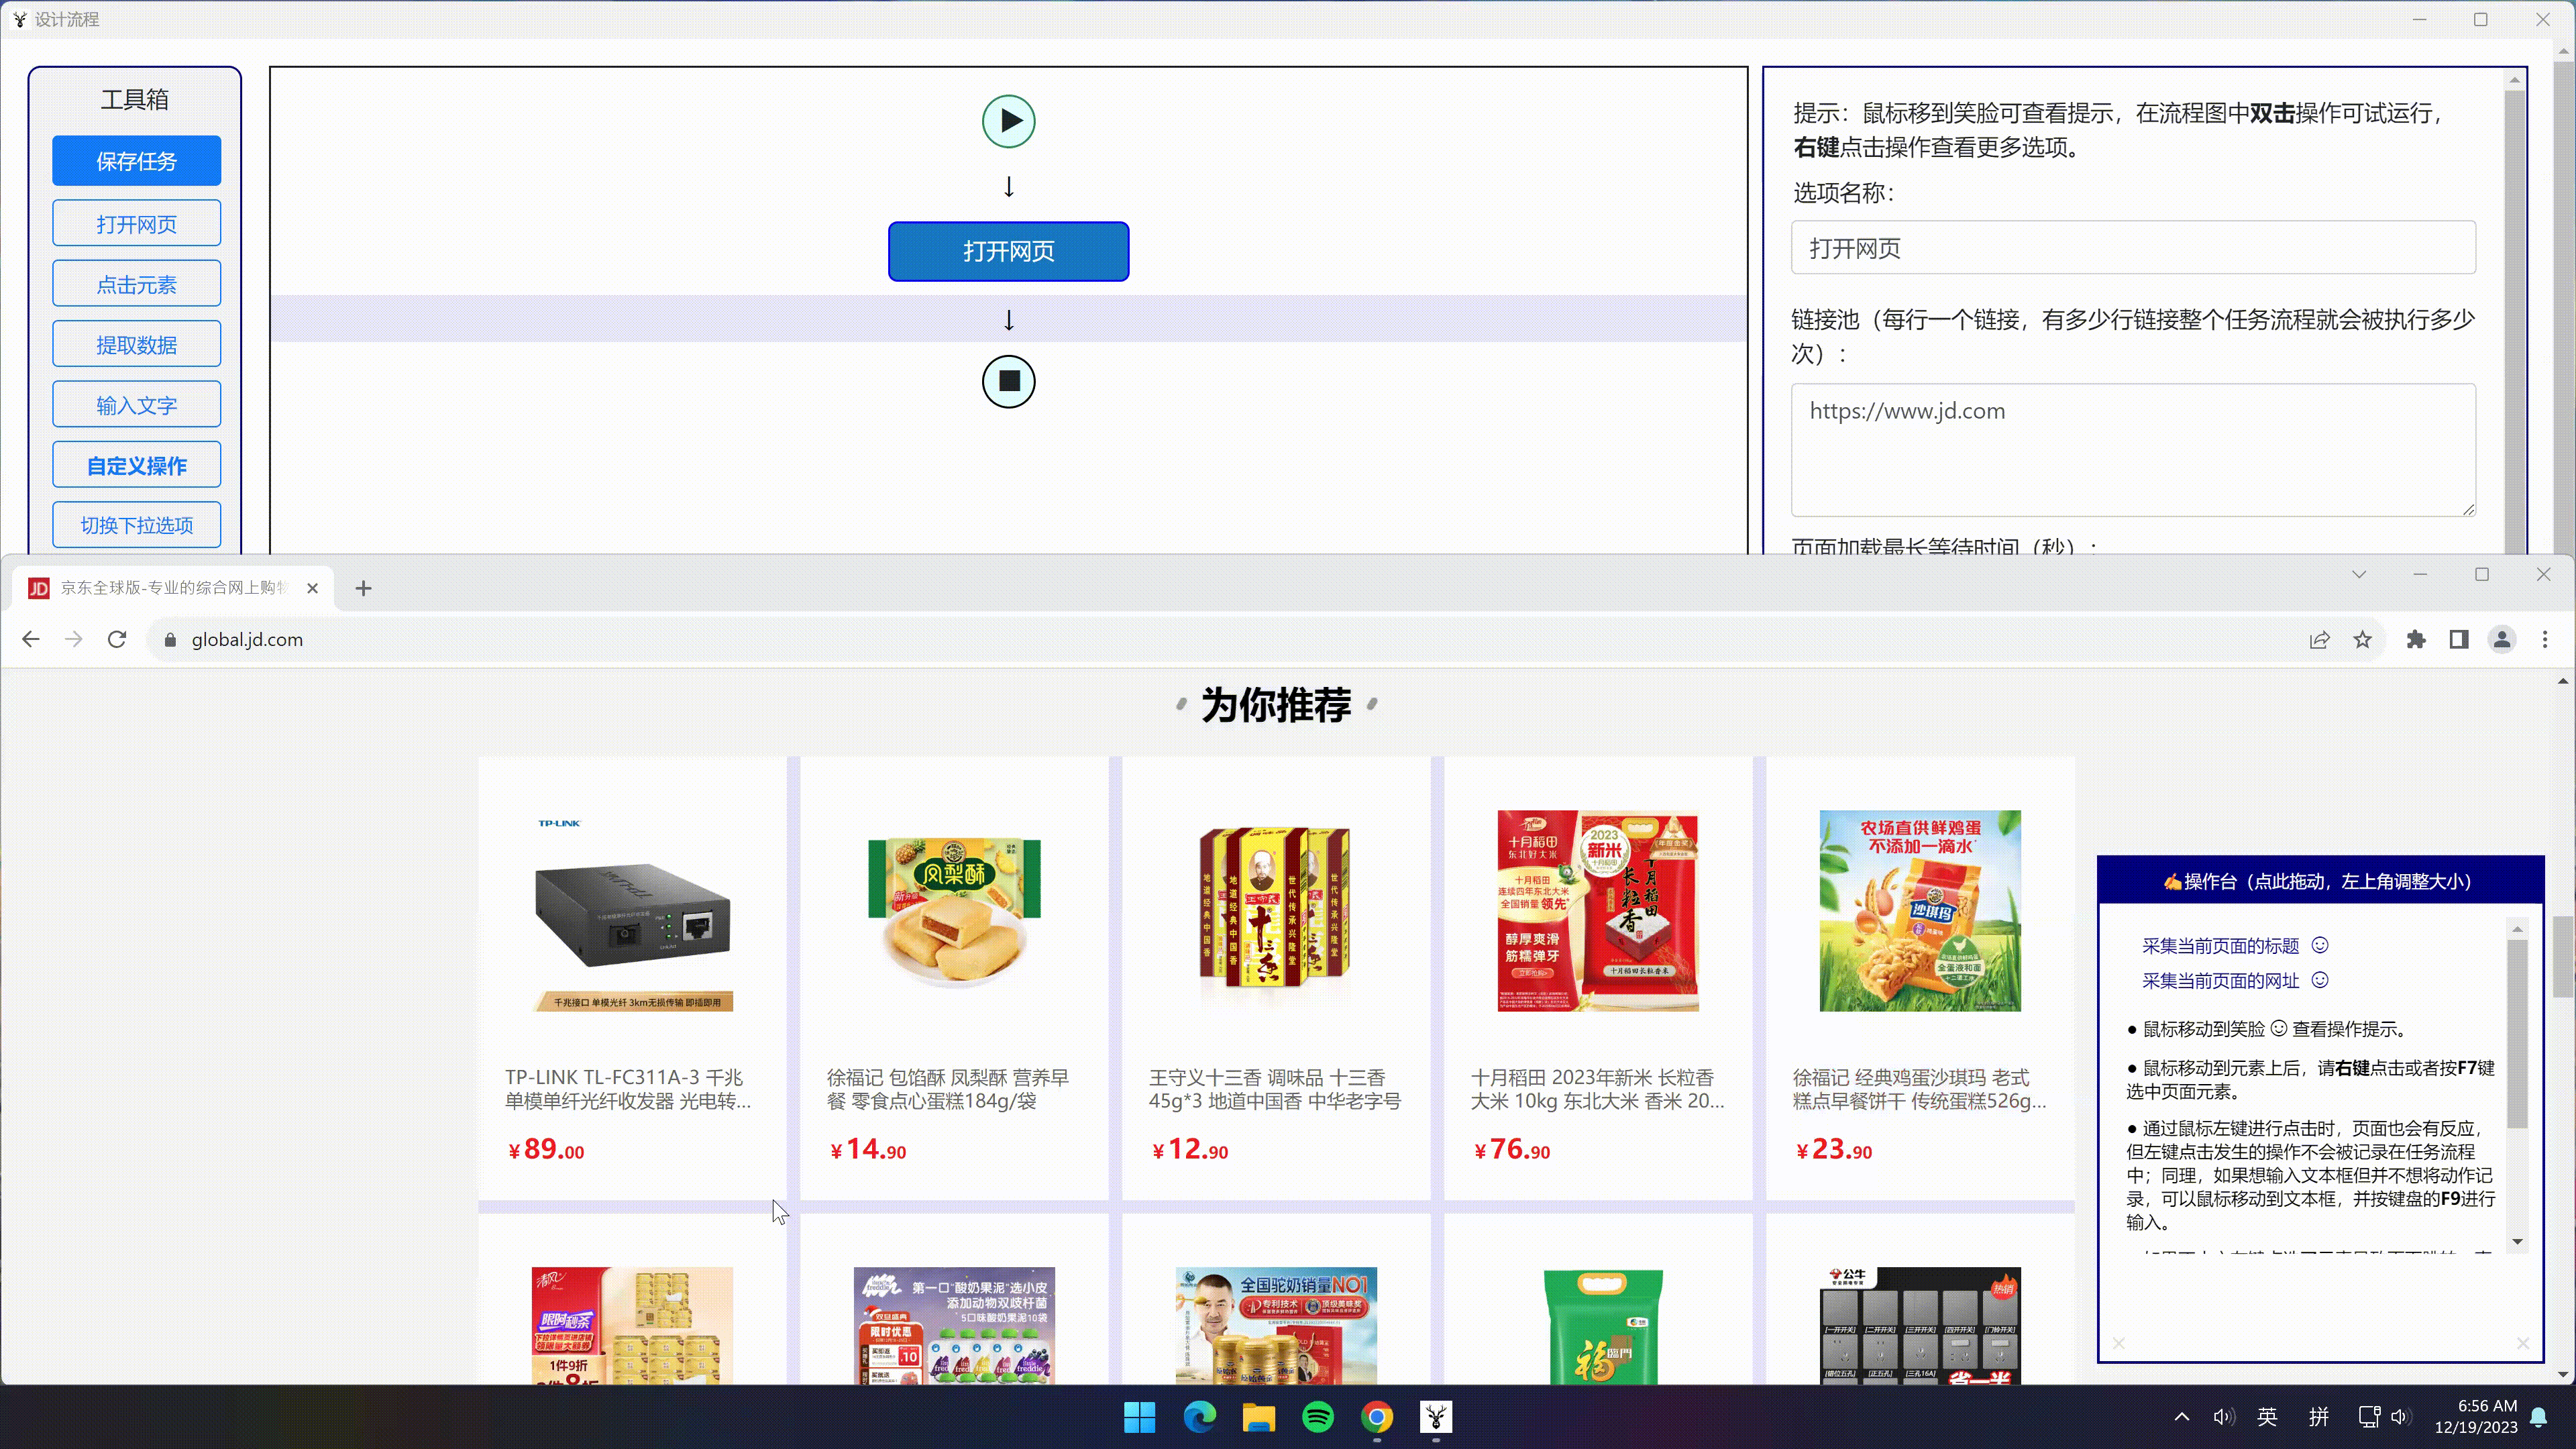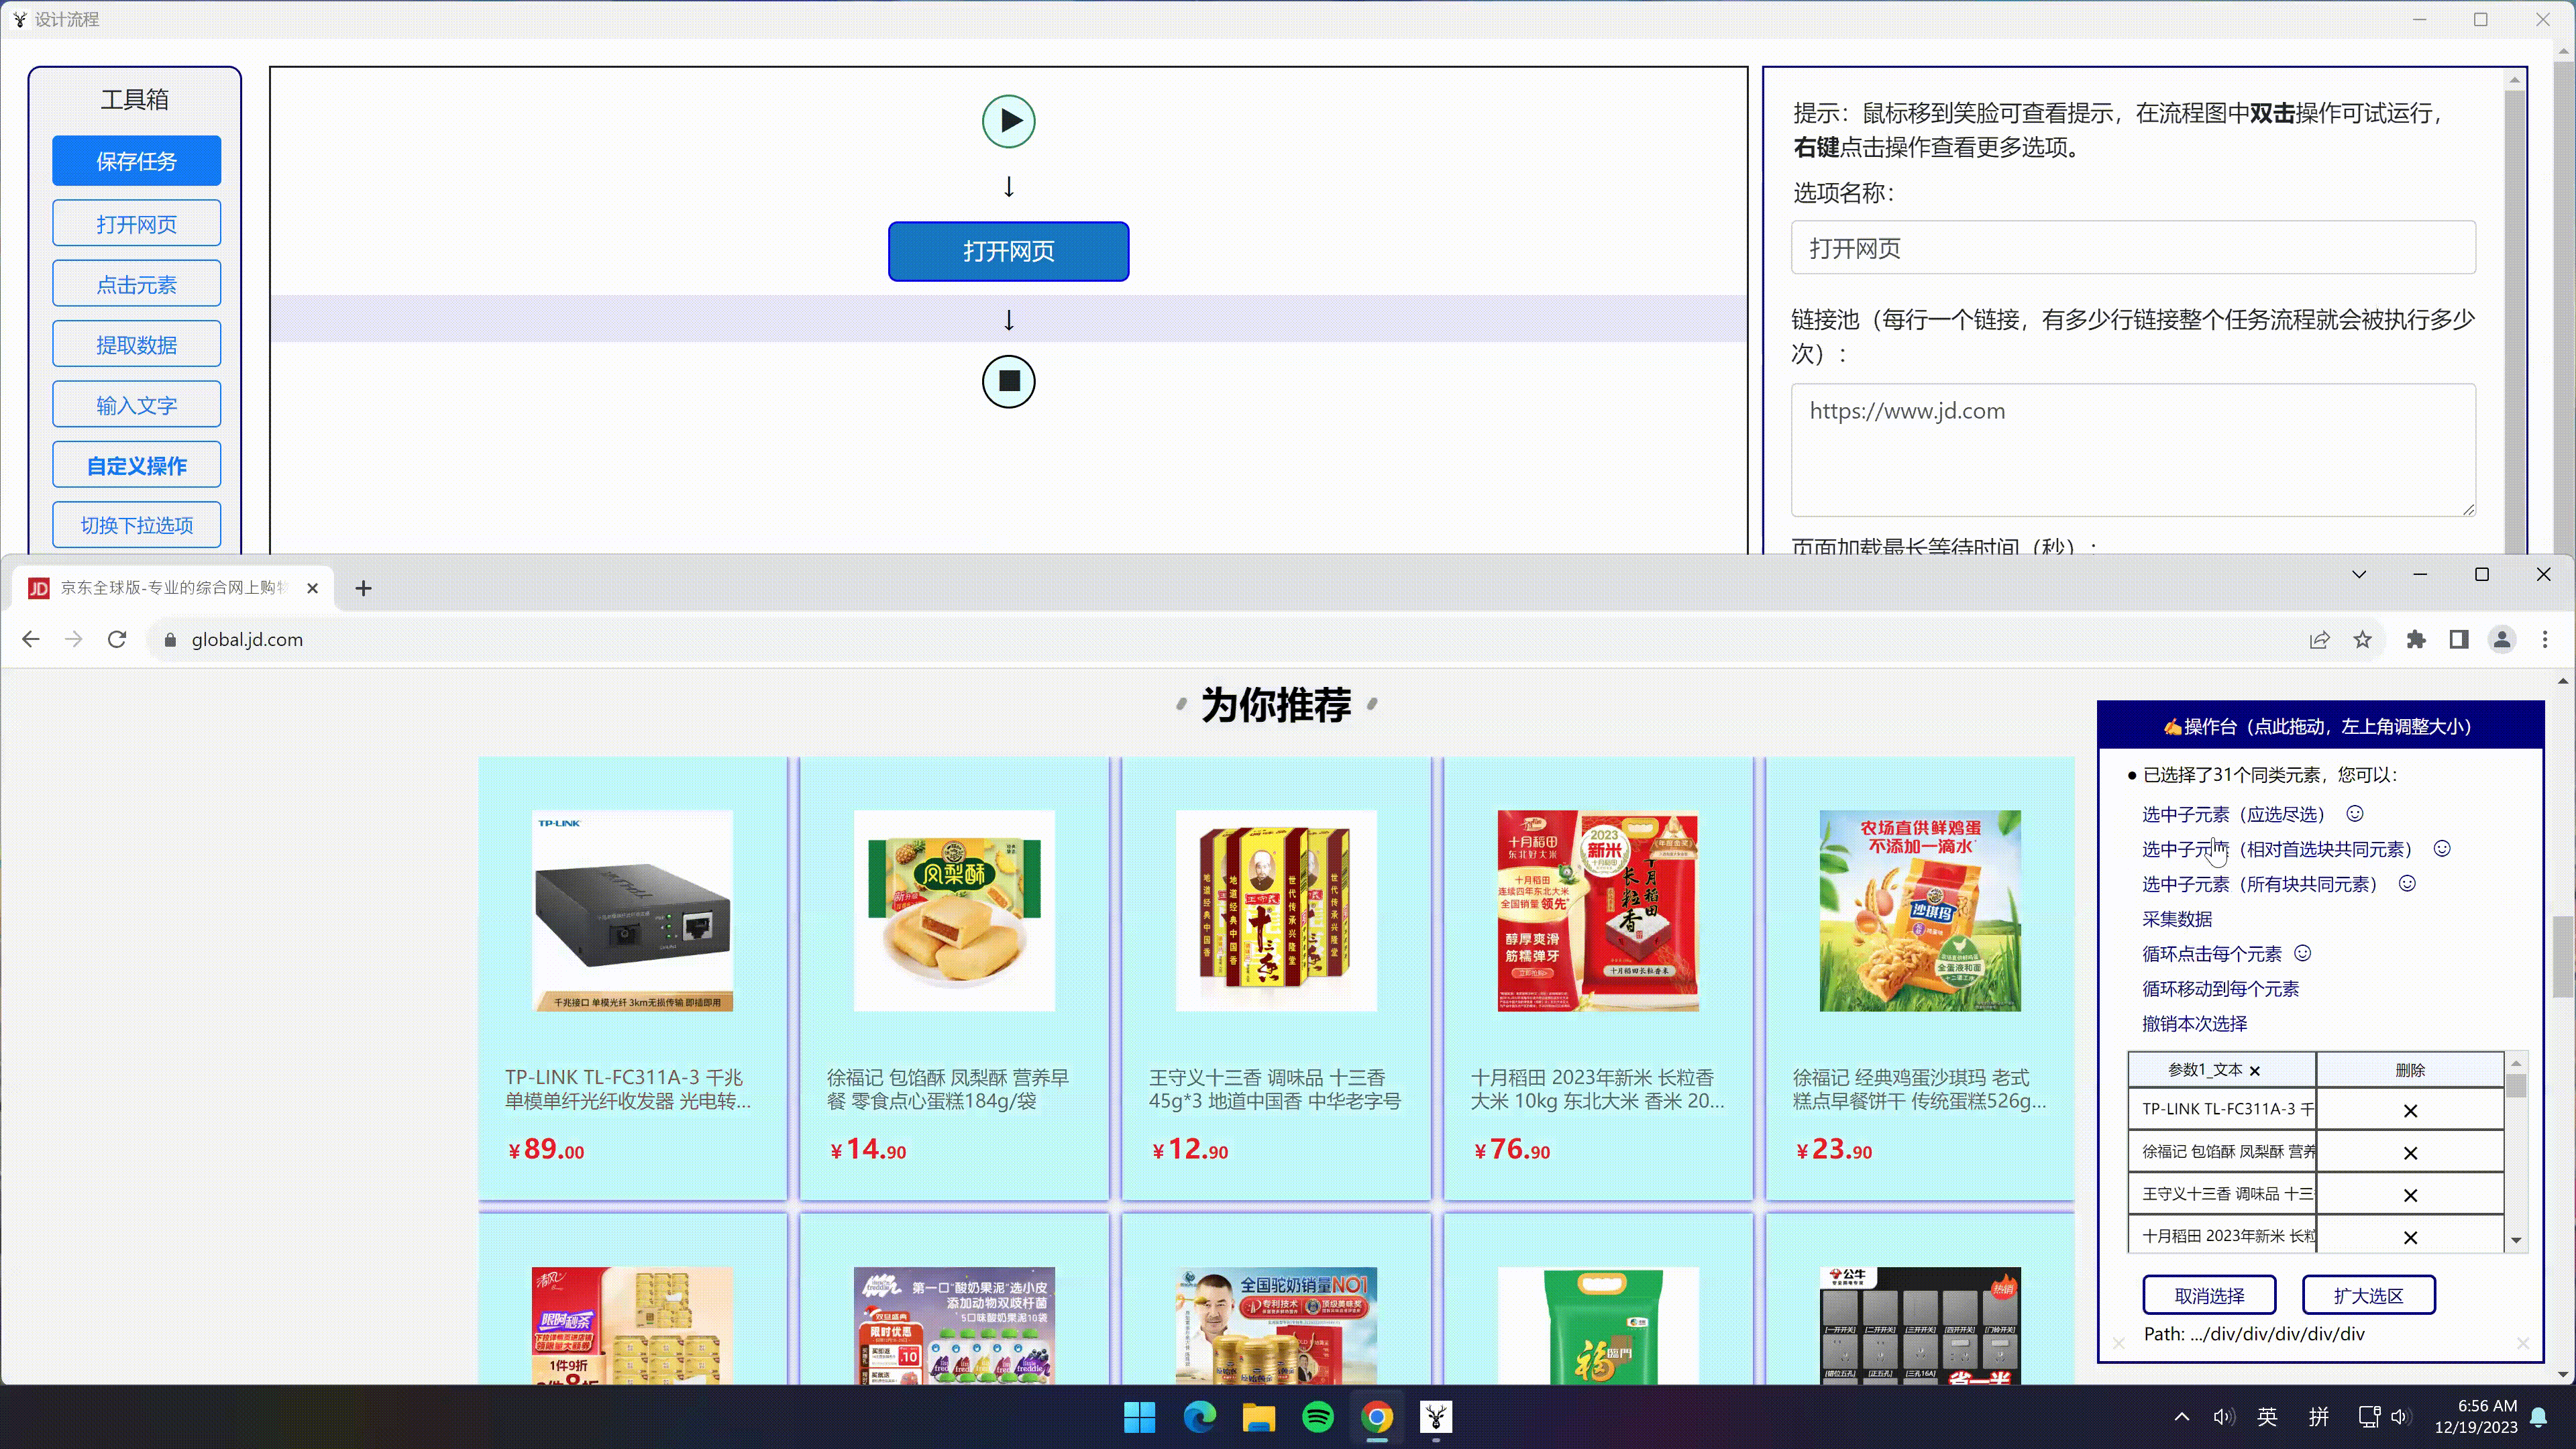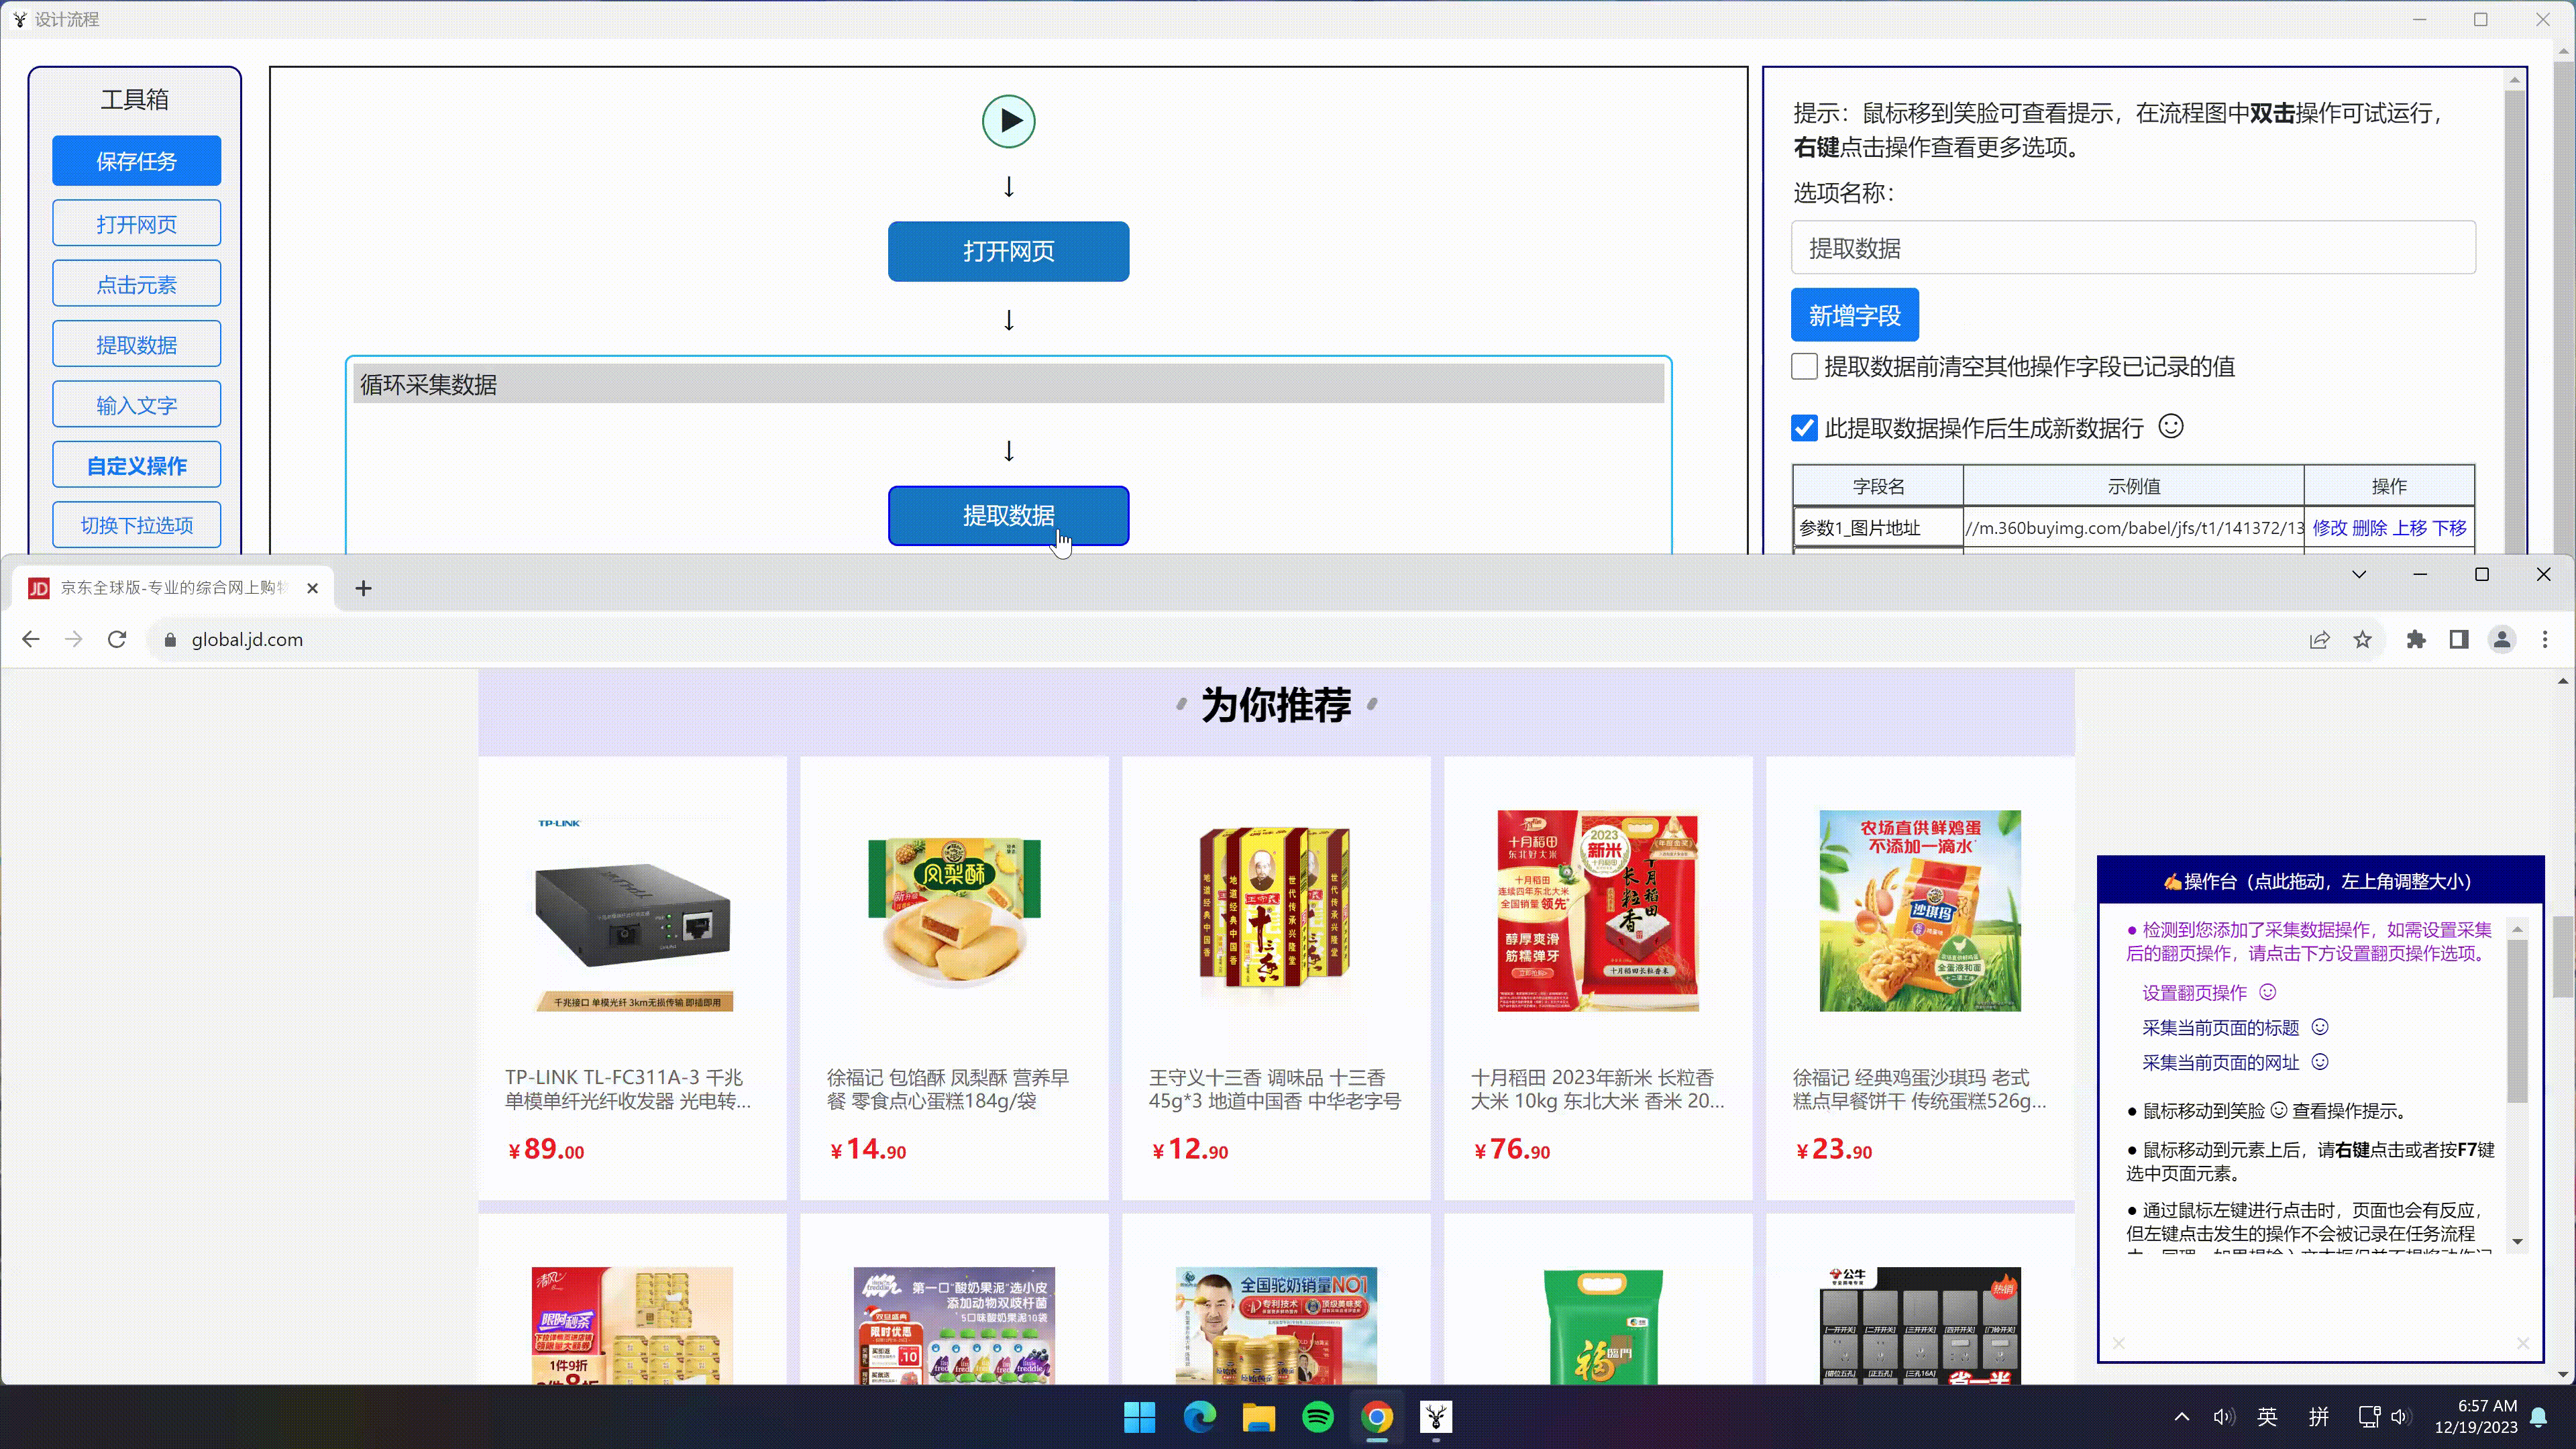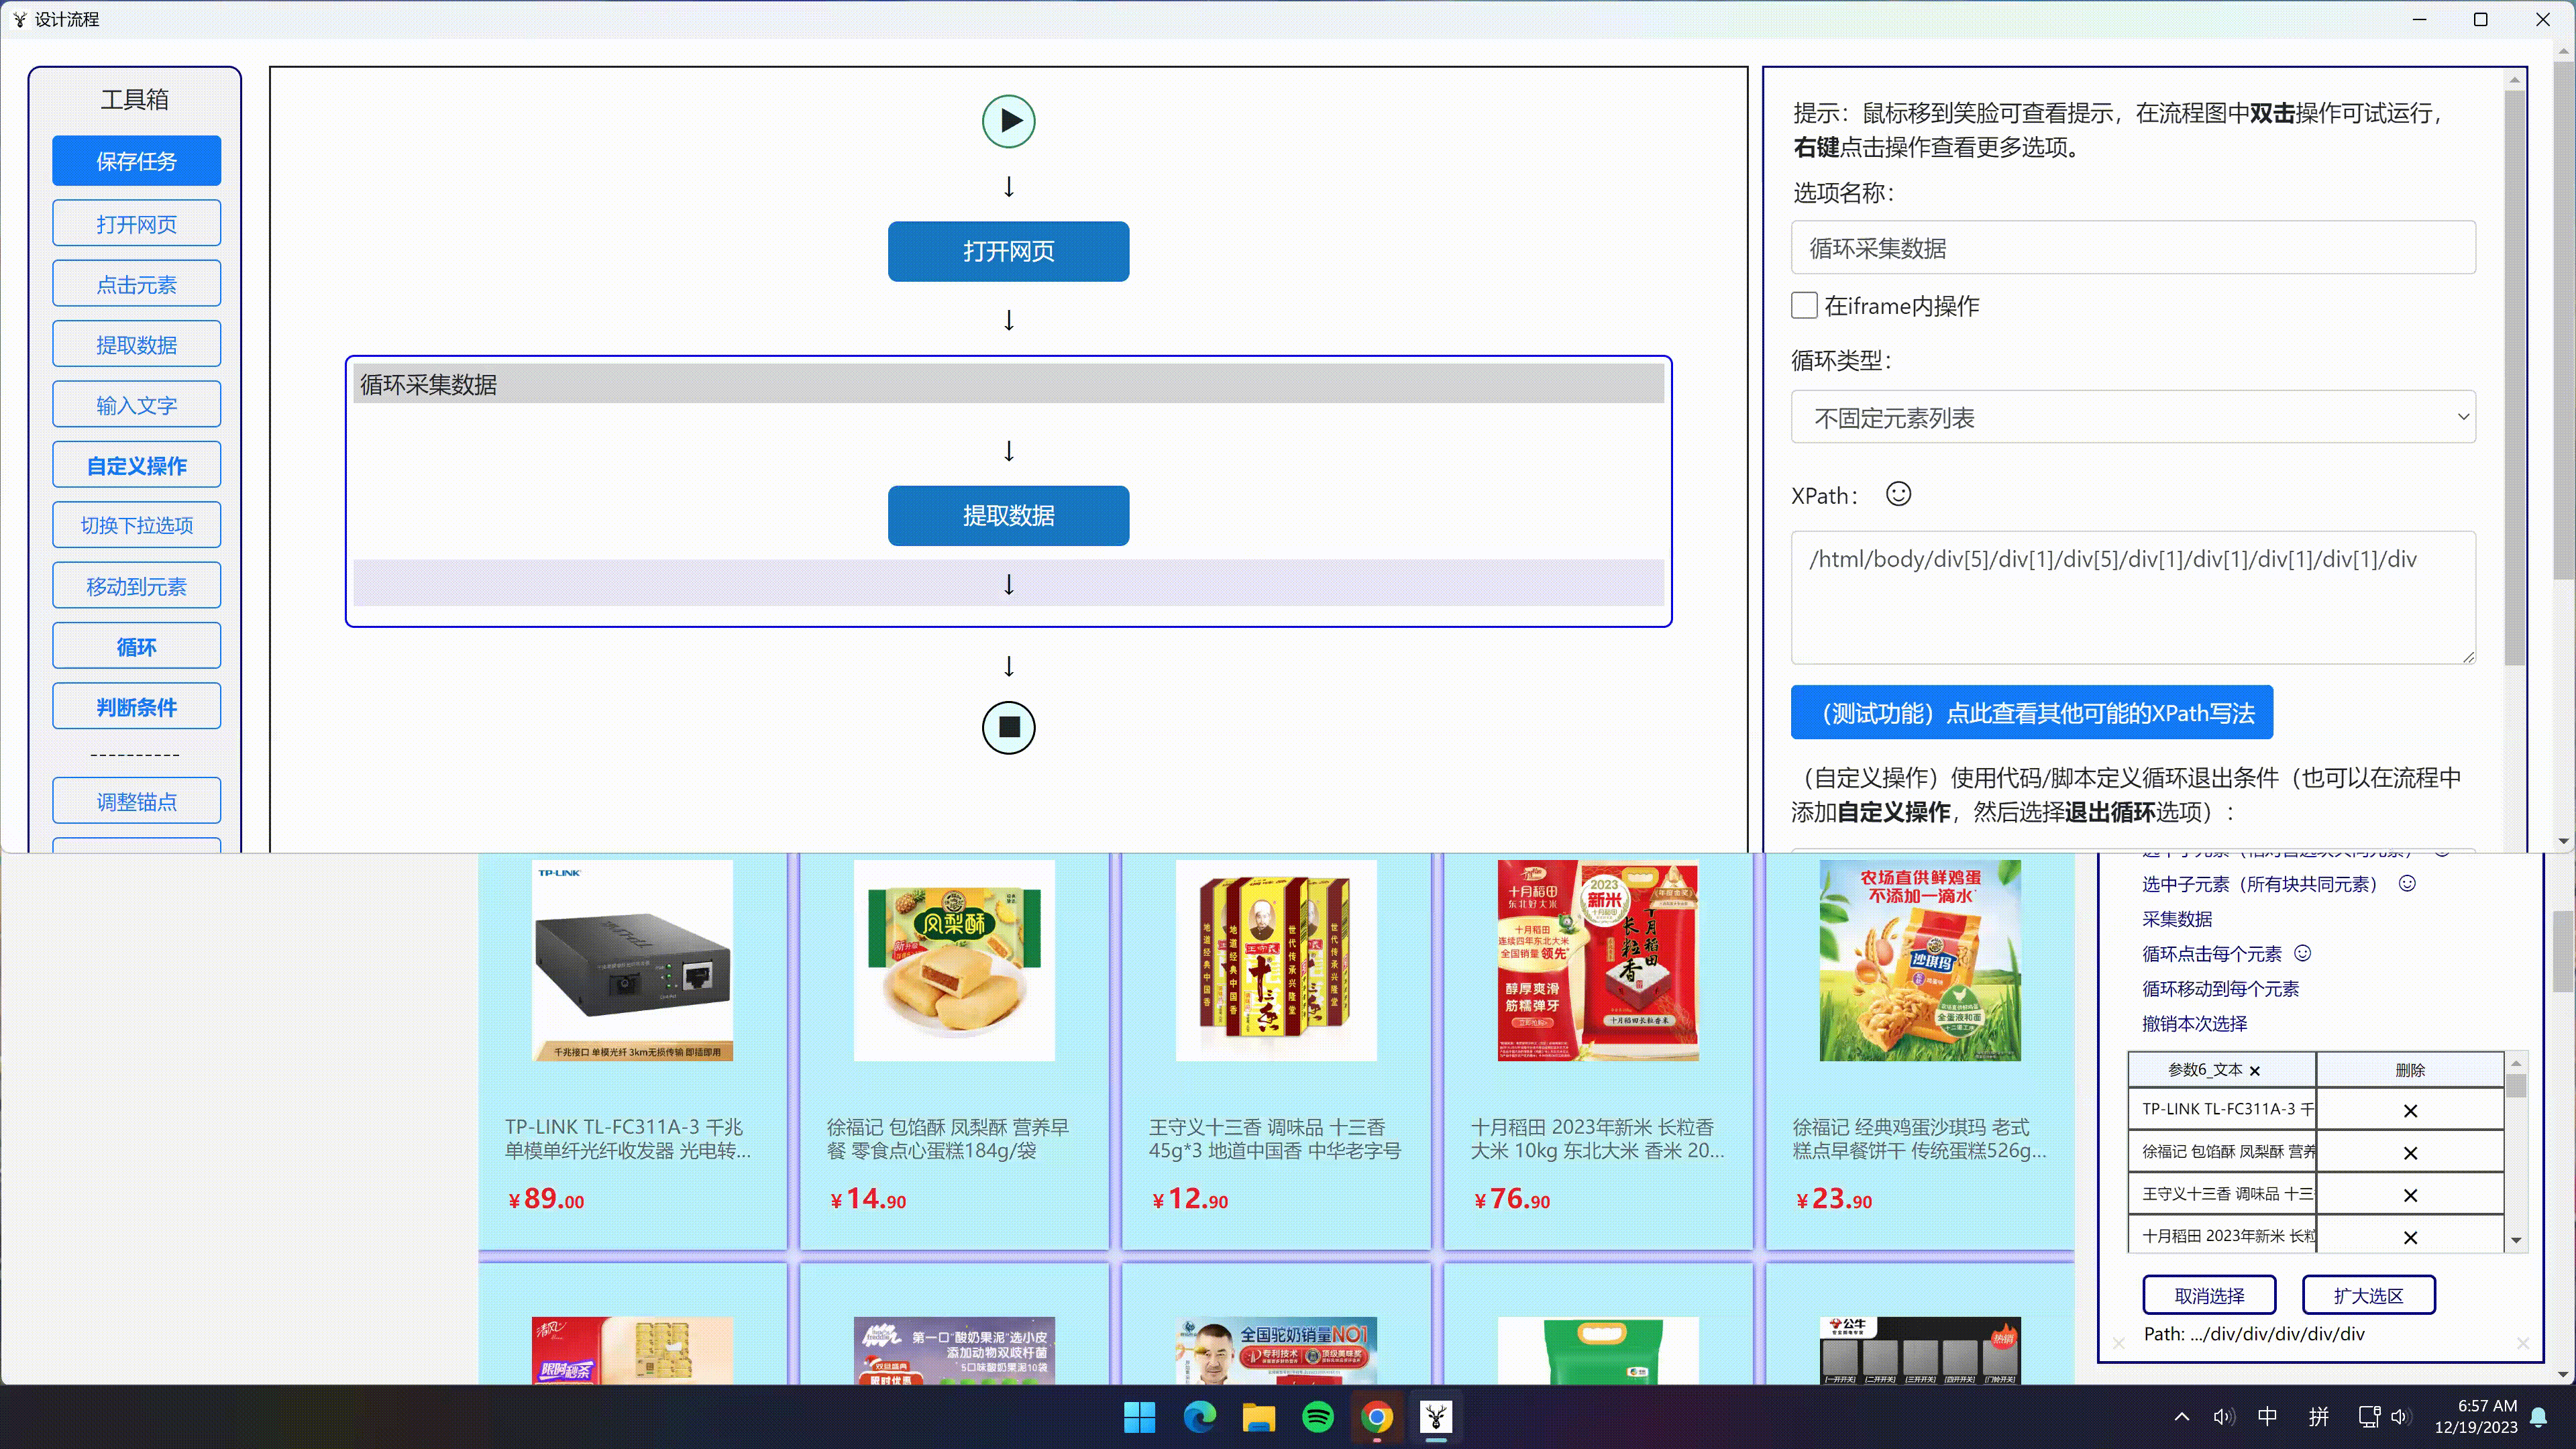
44.7KNaiboWang/EasySpider · JavaScriptEasySpider (易采集) is a visual, no-code web crawler and browser automation tool. You select elements on a webpage with clicks instead of writing code, and it designs and runs the scraping/testing task for you.
- 7
BettaFish
42.4K666ghj/BettaFish · PythonBettaFish (Chinese name 'Weiyu'/微舆) is a from-scratch multi-agent public opinion analysis system that monitors social media and large volumes of public comments, then produces reports to help break information bubbles and support decision-making.
- 8
onyx
32.5Konyx-dot-app/onyx · PythonOnyx is an open source AI platform that gives you a full-featured chat interface on top of any LLM, with built-in RAG, web search, agents, and more.
- 9
Scrapegraph-ai
31.8KScrapeGraphAI/Scrapegraph-ai · PythonScrapeGraphAI is a Python web scraping library that uses LLMs and direct graph logic to build scraping pipelines for websites and local documents (XML, HTML, JSON, Markdown). You just say which information you want to extract and it does the rest.
- 10

lux
31.8Kiawia002/lux · GoLux is a fast and simple video downloader built with Go — a CLI tool that grabs videos, images and audio from sites like YouTube, bilibili, Douyin, Youku and iQiyi.
- 11

obscura
29Kh4ckf0r0day/obscura · RustAn open-source headless browser engine written in Rust, built for web scraping and AI agent automation. It runs real JavaScript via an embedded V8 and supports the Chrome DevTools Protocol.
- 12
ArchiveBox
28.8KArchiveBox/ArchiveBox · PythonArchiveBox is a free, open source, self-hosted web archiving tool: you feed it URLs — bookmarks, browser history, Pocket/Pinboard saves, RSS feeds — and it preserves durable, long-term-readable copies of pages that you control.
- 13

crawlee
26.2Kapify/crawlee · TypeScriptA web scraping and browser automation library for Node.js: you write crawlers in JavaScript or TypeScript to crawl sites, extract data (e.g. for AI, LLM and RAG pipelines) and save it to disk or cloud.
- 14

colly
25.6Kgocolly/colly · GoColly is a scraping and crawling framework for Go: a clean interface for writing any kind of crawler, scraper or spider that extracts structured data from websites, for things like data mining, processing or archiving.
- 15

proxy_pool
23.8Kjhao104/proxy_pool · PythonProxyPool is an open-source proxy IP pool for web spiders: it keeps harvesting free proxies from the web, checks that they work, stores the good ones in Redis and serves them to your crawler over a small HTTP API.
- 16

gpt-crawler
22.4KBuilderIO/gpt-crawler · TypeScriptA crawler that scrapes a website (one or multiple URLs) and turns the pages into a knowledge file you can upload to OpenAI to build a custom GPT or assistant.
- 17
learn_python3_spider
22.2Kwistbean/learn_python3_spider · PythonA free Chinese-language tutorial series that teaches Python web scraping from zero — 30+ numbered lessons and mitmproxy guides, from first packet capture to distributed crawling, with source code for the practice projects.
- 18
automa
21.7KAutomaApp/automa · VueAutoma is a browser extension that automates your browser by connecting blocks into workflows — auto-fill forms, take screenshots, repeat tedious tasks, or scrape website data.
- 19

Douyin_TikTok_Download_API
20.7KEvil0ctal/Douyin_TikTok_Download_API · PythonA self-hosted data API for Douyin and TikTok: it pulls posts, author profiles, comments, search and playlists, downloads videos and image albums without a watermark, and exposes it all through a REST API, an MCP server, a CLI and a web console.
- 20

python-spider
19.8KJack-Cherish/python-spider · PythonA collection of real-world Python web scraping projects, each targeting a specific Chinese site or app: Taobao, JD, NetEase Music, Bilibili, 12306 train tickets, Douyin, novel sites, manga sites and more.
- 21
maxun
17.9Kgetmaxun/maxun · TypeScriptMaxun is an open-source no-code web data platform that turns any website into structured, reliable data: it handles extraction, crawling, scraping, search and AI-powered data extraction.
- 22

katana
17.7Kprojectdiscovery/katana · GoKatana is a next-generation crawling and spidering framework from ProjectDiscovery: point it at URLs and it discovers endpoints, links and forms across a site.
- 23
Awesome-GitHub-Repo
17.3KWechat-ggGitHub/Awesome-GitHub-RepoA hand-curated Chinese-language collection of interesting and high-quality open-source GitHub projects, organized into thematic categories (AI, fun hacks, real-world practice projects, tools, learning resources) rather than by programming language.
- 24

pyspider
16.8Kbinux/pyspider · Pythonpyspider is a powerful web spider (crawler) system written in Python: you write crawling scripts in Python and manage your scraping projects through a built-in web interface.
- 25

ChineseBQB
16.3Kzhaoolee/ChineseBQB · PythonChineseBQB is a huge open collection of Chinese internet memes and sticker images (emoji packs), organized into themed folders covering pop culture, celebrities, games, anime, and historical internet memes, plus an online tool to search and share them.
- 26
awesome-python-login-model
16.2KKr1s77/awesome-python-login-model · PythonA collection of Python 3 example scripts that simulate logging into popular websites — mostly Chinese ones like Zhihu, Bilibili, Weibo, JD (JingDong) and Taobao, plus Facebook and GitHub — together with a few simple crawlers. It is meant as a learning resource for login simulation and scraping techniques.
- 27

tushare
15.5Kwaditu/tushare · PythonTuShare is a Python utility for crawling, cleaning and storing historical and realtime data for China's stock and futures markets, built for quant analysts and anyone learning data analysis.
- 28

XSStrike
15.2Ks0md3v/XSStrike · PythonXSStrike is a Cross Site Scripting (XSS) detection suite built around four hand-written parsers, an intelligent payload generator, a fuzzing engine, and a fast crawler. Instead of just firing generic payloads like most scanners, it analyzes the live response and crafts payloads guaranteed to work through context analysis.
- 29

newspaper
15.2Kcodelucas/newspaper · PythonNewspaper3k is a Python 3 library that downloads, parses, and extracts the article text, authors, publish date, top image, and keywords/summary from news articles and news sites.
- 30

examples-of-web-crawlers
14.7Kshengqiangzhang/examples-of-web-crawlers · HTMLA collection of beginner-friendly Python web-scraping examples, mostly targeting Chinese sites like Taobao, Tmall, WeChat, WeChat Reading, Douban and QQ.
- 31

Photon
13.3Ks0md3v/Photon · PythonPhoton is a fast web crawler built for OSINT (open-source intelligence) gathering, extracting URLs, emails, social media accounts, secret keys, subdomains and more while it crawls a target site.
- 32

chromeless
13.2Kschickling/chromeless · TypeScriptChromeless is a TypeScript library for automating Chrome from code: open sites, click elements, fill forms, take screenshots. Note that it is now deprecated in favor of Puppeteer.
- 33
SeleniumBase
13.1Kseleniumbase/SeleniumBase · PythonSeleniumBase is an all-in-one Python framework for browser automation — web crawling, testing, scraping, and stealth. Its CDP Mode bypasses bot-detection in Chromium-based browsers, and a Stealthy Playwright Mode extends that to Playwright.
- 34

Yuedu
12.5KXIU2/YueduThis is a personal collection of 'book sources' (JSON parsing rule files) for the Chinese novel-reading app '阅读' (Legado). The sources tell the app how to search, list chapters, and extract text from various free novel websites.
- 35
crawlab
12.3Kcrawlab-team/crawlab · GoCrawlab is an open-source distributed web crawler management platform: you upload spiders written in any language, run them across a cluster of machines, and manage tasks, schedules and results from a web UI.
- 36
reader
12.2Kjina-ai/reader · TypeScriptReader is a service that converts any URL into clean, LLM-friendly markdown by simply prefixing it with https://r.jina.ai/, and it also offers a web-search endpoint at https://s.jina.ai/ that returns readable content for the top search results instead of just titles and snippets.
- 37

webmagic
11.7Kcode4craft/webmagic · JavaWebMagic is a scalable web crawler framework for Java. It covers the whole crawler lifecycle — downloading, URL management, content extraction and persistence — to simplify building a specific crawler.
- 38
apify-mcp-server
11.6Kapify/apify-mcp-server · TypeScriptThe Apify MCP Server lets AI agents and assistants extract data from websites like social media, search engines, maps, and e-commerce sites by giving them access to thousands of ready-made scrapers and automation tools from the Apify Store.
- 39

spider-flow
11.4Kssssssss-team/spider-flow · JavaSpider-flow is a next-generation crawler platform that lets you design web scraping workflows as flowcharts instead of writing code.
- 40

Python
10.9Kinjetlee/Python · PythonA personal grab-bag of standalone Python scripts and short tutorials the author wrote alongside blog posts: web scraping, WeChat official account development, Excel automation, SQL practice, and small utility hacks like remote shutdown.
- 41
avbook
10.1Kguyueyingmu/avbook · PHPA self-hosted AV (Japanese adult video) library: a PHP/Laravel web app with built-in crawlers for avmoo, javbus and javlibrary that builds a local, searchable database of movies and magnet links.
- 42
hister
6.1Kasciimoo/hister · GoHister is a private, self-hosted search engine that fully indexes the pages you visit and the files you keep, so you can search their content later from a web interface, terminal, or an AI assistant via MCP.
- 43
botasaurus
5.8Komkarcloud/botasaurus · PythonBotasaurus is an all-in-one Python web scraping framework built to make scrapers that pass bot-detection checks, including Cloudflare WAF, BrowserScan, Fingerprint, Datadome, and Cloudflare Turnstile CAPTCHA.
- 44
wigolo
5.5KKnockOutEZ/wigolo · TypeScriptwigolo is a local-first web toolkit for AI coding agents: one surface for search, fetch, crawl, extraction, caching, find-similar, and research, served over MCP, REST, SDKs, and a CLI. No API keys, no cloud, $0 per query.
- 45
scraping-apis-for-devs
3.9Kcporter202/scraping-apis-for-devs · JavaScriptA giant categorized directory of 2,622 ready-to-use scraping APIs for pulling data from websites, social media, e-commerce sites, job boards, real estate listings and more, so you don't have to build scrapers from scratch.
- 46
creatorhub
2.4K3441293738/creatorhub · PythonCreatorHub 可以把开源的 fingerprint-chromium 作为其他平台的可插拔 Chromium 运行时。账号、Profile、Cookie、代理、LRU 和风控仍由 CreatorHub 管理,不需要外部商业浏览器或云端账号。小红书始终使用系统 Chrome/CDP: 第三方指纹内核与既有 Profile 混用容易造成 UA/Client Hints、GPU 和站点持久状态不一致, 从而增加设备安全验证;后端、登录接口和账号设置页都会拒绝该组合。
- 47
fredy
1.6Korangecoding/fredy · JavaScriptFredy is a self-hosted tool that continuously watches 26 real estate portals across Germany, Austria, Switzerland, Spain, Italy and Portugal (e.g. ImmoScout24, Immowelt, eBay Kleinanzeigen) and pushes new listings to you via Slack, Telegram, Email, Discord or ntfy the moment they appear.
- 48
deepcrawl
690lumpinif/deepcrawl · TypeScriptAn open-source, agent-oriented web data extraction platform — a self-deployable Firecrawl alternative that turns public pages into clean Markdown, a links tree, and LLM-friendly metadata.
- 49

elosys
458YuriRDev/elosys · TypeScriptElosys builds a consolidated database of Brazilian political candidates (2014-2026) from official government sources, cross-referenced by CPF/CNPJ, to investigate relationships between politicians and surface indicia of suspicious patterns like circular donations, shell companies, and wealth incompatible with declared income.
- 50
catbus
431cv-cat/catbus · TypeScriptcatbus is a command-line tool that lets you talk to 10 major Chinese and international platforms (Xiaohongshu, Douyin, TikTok, Bilibili, Kuaishou, Weibo, Xianyu, Taobao, JD, X) through one consistent set of commands and JSON output, instead of learning each platform's own API.
- 51

tiktok-signature
399n1tr00-10/tiktok-signature · PythonThis is a Python library that generates the signatures TikTok's Web API requires on requests — X-Gnarly, X-Bogus, and X-Dynosaur — matching SDK version 5.1.2 (build 1.0.0.316).
- 52
AinanPlayer
329Ainanya21/AinanPlayerA native Windows media aggregation and streaming client: it pulls film and TV streams from TVBox/CatVod-style sources and plays them with 4K hardware acceleration in a WinUI 3 Fluent interface.
- 53

agent-control
195loulanyue/agent-control · PythonAgent Control is a production-grade control plane and orchestration engine for autonomous AI agents, handling distributed task dispatching, heartbeat leasing, DAG workflow execution and data-crawling pipelines, with a built-in MCP server for LLM clients like Claude Desktop and Cursor.
- 54

agent-fleet-manager
147dreamers-laboratory/agent-fleet-manager · PythonIt is an engine that schedules, leases, and tracks large-scale repeated checks of sources (web pages, feeds, listings) by a fleet of workers — plain fetchers, scrapers, or LLM agents — detecting changes by content hash and keeping an auditable ledger of every write.
Related topics
Often tagged together