


What is this?
 Kimi K2 is a large language model series from Moonshot AI: a mixture-of-experts model with 1 trillion total parameters (32B activated per token), trained for frontier knowledge, reasoning, coding and especially agentic tool-use tasks.
Is this a single model or does it come in variants?There are two variants: Kimi-K2-Base, the raw pretrained foundation model for researchers who want to fine-tune, and Kimi-K2-Instruct, the post-trained chat/agentic model meant for drop-in use without long thinking.
There are two variants: Kimi-K2-Base, the raw pretrained foundation model for researchers who want to fine-tune, and Kimi-K2-Instruct, the post-trained chat/agentic model meant for drop-in use without long thinking.Is Kimi-K2-Instruct a 'thinking' model like reasoning-focused competitors?No, it is described as a reflex-grade model without long thinking, unlike extended-thinking modes in some competitor models.
No, it is described as a reflex-grade model without long thinking, unlike extended-thinking modes in some competitor models.Who is this model aimed at?Researchers and developers who need either a base model to fine-tune or a ready-to-use chat/agent model for tool-use and coding tasks.
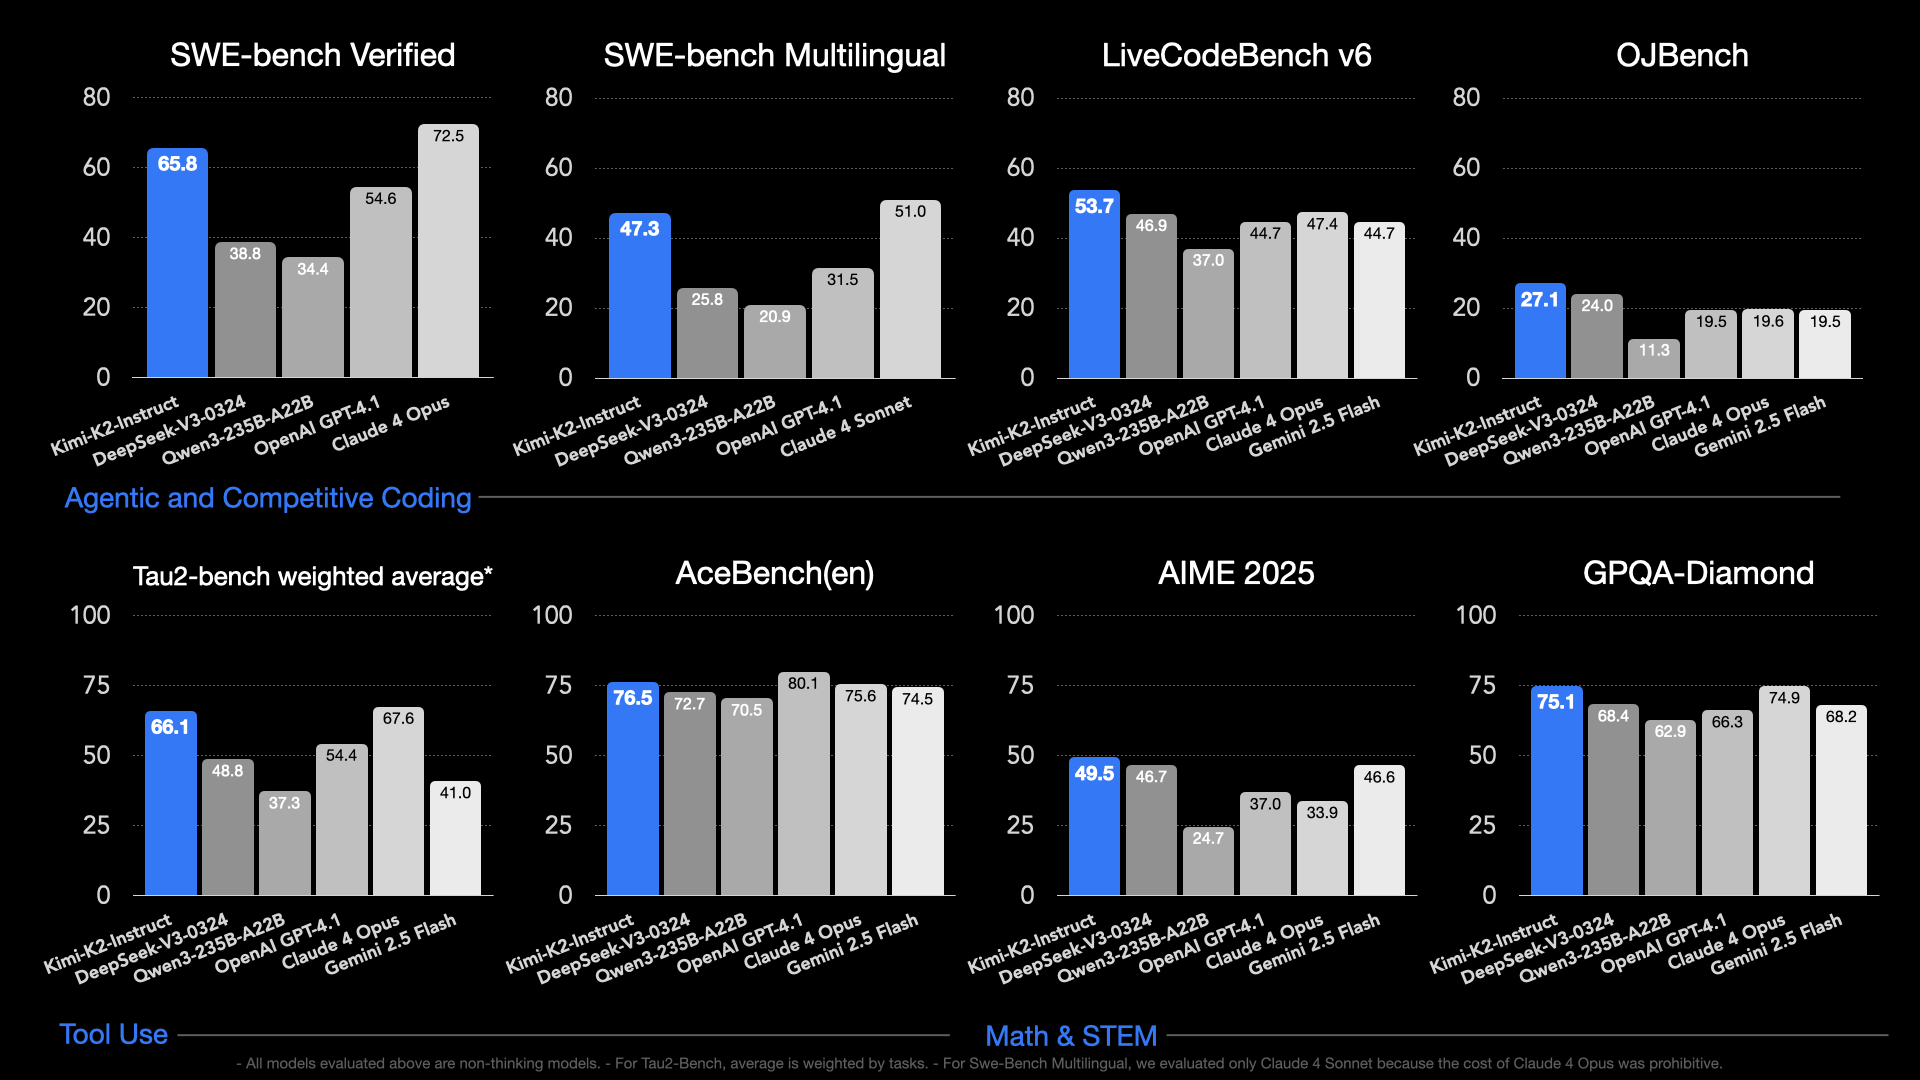
Researchers and developers who need either a base model to fine-tune or a ready-to-use chat/agent model for tool-use and coding tasks.How does Kimi K2 compare to models like DeepSeek-V3 or Claude on coding benchmarks?On SWE-bench Verified agentic coding, Kimi K2 Instruct scores 65.8% pass@1 (single attempt), well above DeepSeek-V3-0324's 38.8% and Qwen3-235B's 34.4%, though below Claude Opus 4's 72.5%.
On SWE-bench Verified agentic coding, Kimi K2 Instruct scores 65.8% pass@1 (single attempt), well above DeepSeek-V3-0324's 38.8% and Qwen3-235B's 34.4%, though below Claude Opus 4's 72.5%.What optimizer was used to train such a huge model stably?Moonshot AI used the Muon optimizer at unprecedented scale, with a novel 'MuonClip' technique developed to resolve training instabilities while scaling to 1T parameters.
Moonshot AI used the Muon optimizer at unprecedented scale, with a novel 'MuonClip' technique developed to resolve training instabilities while scaling to 1T parameters.How large is the training data and context window?Kimi K2 was pretrained on 15.5 trillion tokens with zero training instability, and supports a 128K token context length.
Kimi K2 was pretrained on 15.5 trillion tokens with zero training instability, and supports a 128K token context length.How many experts does the MoE architecture use?It has 384 experts total, with 8 experts selected per token plus 1 shared expert, across 61 layers using MLA attention and SwiGLU activations.
It has 384 experts total, with 8 experts selected per token plus 1 shared expert, across 61 layers using MLA attention and SwiGLU activations.What are similar projects?DeepSeek-V3, Kimi-K3, MiniCPM, Qwen3.8, DeepSeek-R1, Hy4-preview, minimind, StartLux-Decision
DeepSeek-V3, Kimi-K3, MiniCPM, Qwen3.8, DeepSeek-R1, Hy4-preview, minimind, StartLux-DecisionWhich topics is it in?open-weights, tool-calling, mixture-of-experts, reasoning, coding, language-model, moe, agentic, fine-tuning, transformer, large-language-models, artificial-intelligence
open-weights, tool-calling, mixture-of-experts, reasoning, coding, language-model, moe, agentic, fine-tuning, transformer, large-language-models, artificial-intelligence