Topics / #tabular-data
Tabular-data projects on GitHub
Processing and rendering tabular data from ML to virtualized tables.
As of , the most-starred Tabular-data projects on GitHub are polars (40.1K stars), fastai (28.2K stars) and react-virtualized (27.1K stars). GitHub.Locker tracks 10 Tabular-data repositories with 178.8K stars combined. The fastest-growing on October 16 was polars, with +7 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +7
polars
pola-rs/polars · ★ 40.1KPolars is an extremely fast analytical query engine for DataFrames, written in Rust and designed to be fast, easy to use and expressive.
 +3
fastbook
fastai/fastbook · ★ 25.4KThis repo contains the official Jupyter Notebooks for 'the fastai book', an introduction to deep learning, the fastai library, and PyTorch.
 +2
react-virtualized
bvaughn/react-virtualized · ★ 27.1Kreact-virtualized is a set of React components for efficiently rendering large lists and tabular data by only rendering the rows or cells currently visible in the viewport.
 +2
lime
marcotcr/lime · ★ 12.2KLIME (Local Interpretable Model-agnostic Explanations) is a Python package that explains individual predictions of any machine learning classifier, whether it works on text, tabular data, or images.
The all-time top
10 projects · by stars
- 40.1K#1 · pola-rs/polars
polars
Polars is an extremely fast analytical query engine for DataFrames, written in Rust and designed to be fast, easy to use and expressive.
- 28.2K
 #2 · fastai/fastai
fastai
It's a deep learning library: high-level components that reach state-of-the-art results quickly in standard domains, plus low-level pieces researchers can mix and match to build new approaches.
- 27.1K#3 · bvaughn/react-virtualized
react-virtualized
react-virtualized is a set of React components for efficiently rendering large lists and tabular data by only rendering the rows or cells currently visible in the viewport.
- 4
fastbook
25.4Kfastai/fastbook · Jupyter NotebookThis repo contains the official Jupyter Notebooks for 'the fastai book', an introduction to deep learning, the fastai library, and PyTorch.
- 5

exceljs
15.5Kexceljs/exceljs · JavaScriptExcelJS is a JavaScript library for reading, manipulating and writing Excel spreadsheets — data and styles — in XLSX and JSON. It was built by reverse engineering real Excel spreadsheet files.
- 6
lime
12.2Kmarcotcr/lime · JavaScriptLIME (Local Interpretable Model-agnostic Explanations) is a Python package that explains individual predictions of any machine learning classifier, whether it works on text, tabular data, or images.
- 7
autogluon
10.8Kautogluon/autogluon · PythonAutoGluon is an open-source Python library that automates machine learning: feed it your data and it delivers strong predictive performance in about three lines of code.
- 8
miller
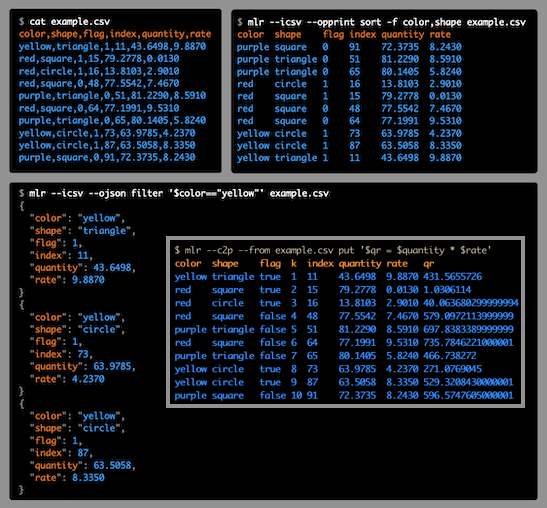
10Kjohnkerl/miller · GoMiller is a command-line toolkit like awk, sed, cut, join, and sort, but built for name-indexed data such as CSV, TSV, JSON, and JSON Lines: you address fields by name instead of counting column positions.
- 9

visidata
9.3Ksaulpw/visidata · PythonVisiData is a terminal spreadsheet multitool for exploring, cleaning, and arranging tabular data, supporting formats like CSV, TSV, SQLite, JSON, Excel (xlsx), and HDF5.
- 10

AutoLOGIC
209sethGu/AutoLOGIC · PythonAutoLOGIC is an agentic framework for automated tabular machine learning across classification, regression, and clustering. It turns a task specification into coordinated feature, model, optimization, and output-control plans and then executes them with task-specific tools.
Related topics
Often tagged together