Topics / #diffusion-models
Diffusion-models projects on GitHub
Diffusion-based generative models for images and video
As of , the most-starred Diffusion-models projects on GitHub are stable-diffusion-webui (165.1K stars), unsloth (78.2K stars) and stable-diffusion (73.5K stars). GitHub.Locker tracks 80 Diffusion-models repositories with 1.1M stars combined. The fastest-growing on October 16 was qwen21-nsfw-pose-skill, with +350 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +350
qwen21-nsfw-pose-skill
Arekejoker/qwen21-nsfw-pose-skill · ★ 2.5KA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
 +59
ComfyUI-Ref2VA-VSA
Kablex/ComfyUI-Ref2VA-VSA · ★ 570It's a ComfyUI custom node that dramatically speeds up Reference-to-Video (Ref2VA) generation for the MiniMax H3 model, producing a full 5-second, 24fps character video in about 72 seconds on a single RTX 4090 instead of over 10 minutes.
 +56
unsloth
unslothai/unsloth · ★ 78.2KUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
 +45
Fooocus
lllyasviel/Fooocus · ★ 53.6KFooocus is an open-source AI image generator built on Stable Diffusion XL: an offline GPT-2 engine expands your prompt so results look good without prompt engineering or parameter tuning.
The all-time top
80 projects · by stars
- 165.1K
 #1 · AUTOMATIC1111/stable-diffusion-webui
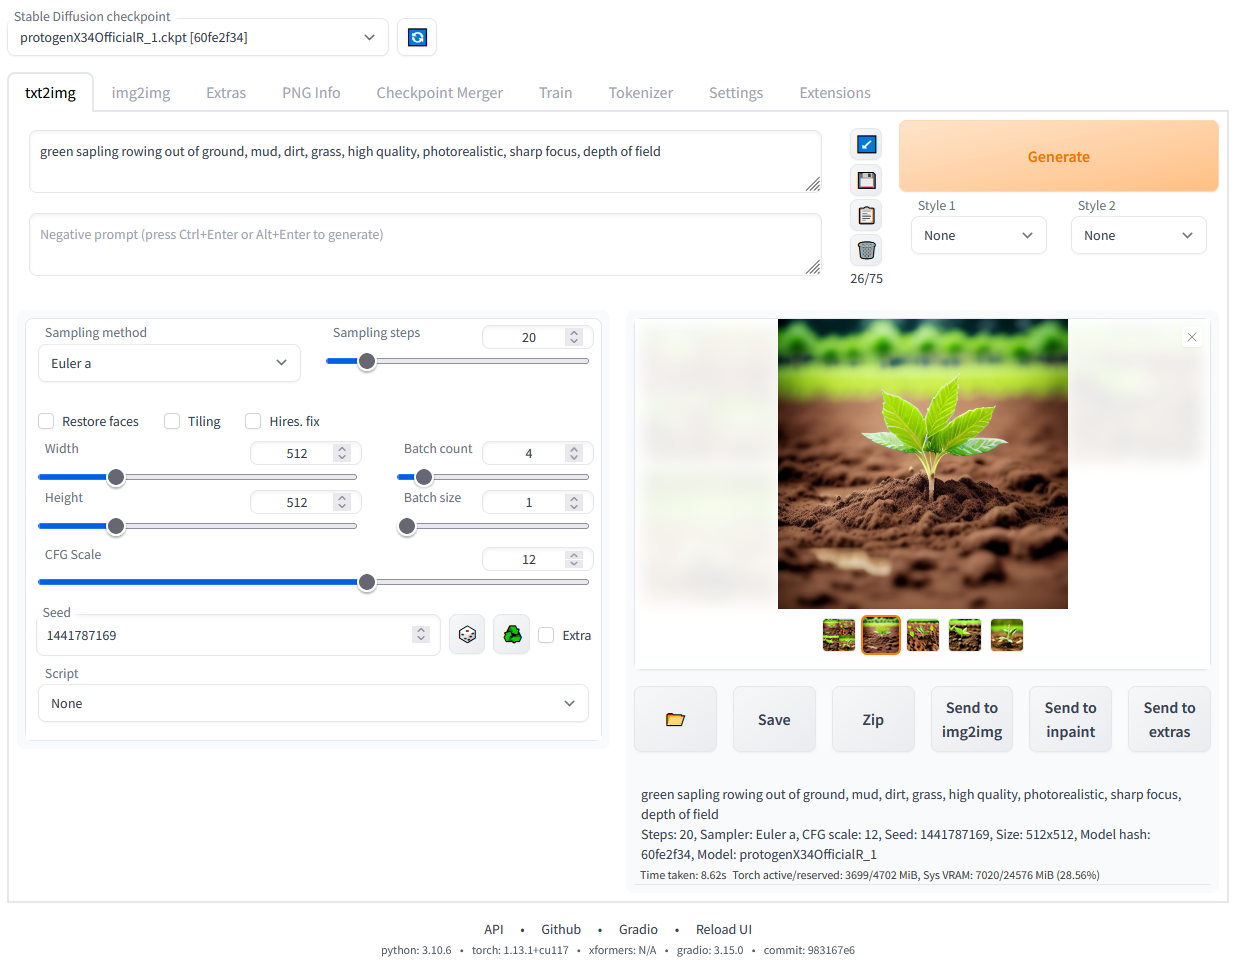
stable-diffusion-webui
A browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
- 78.2K#2 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 73.5K
 #3 · CompVis/stable-diffusion
stable-diffusion
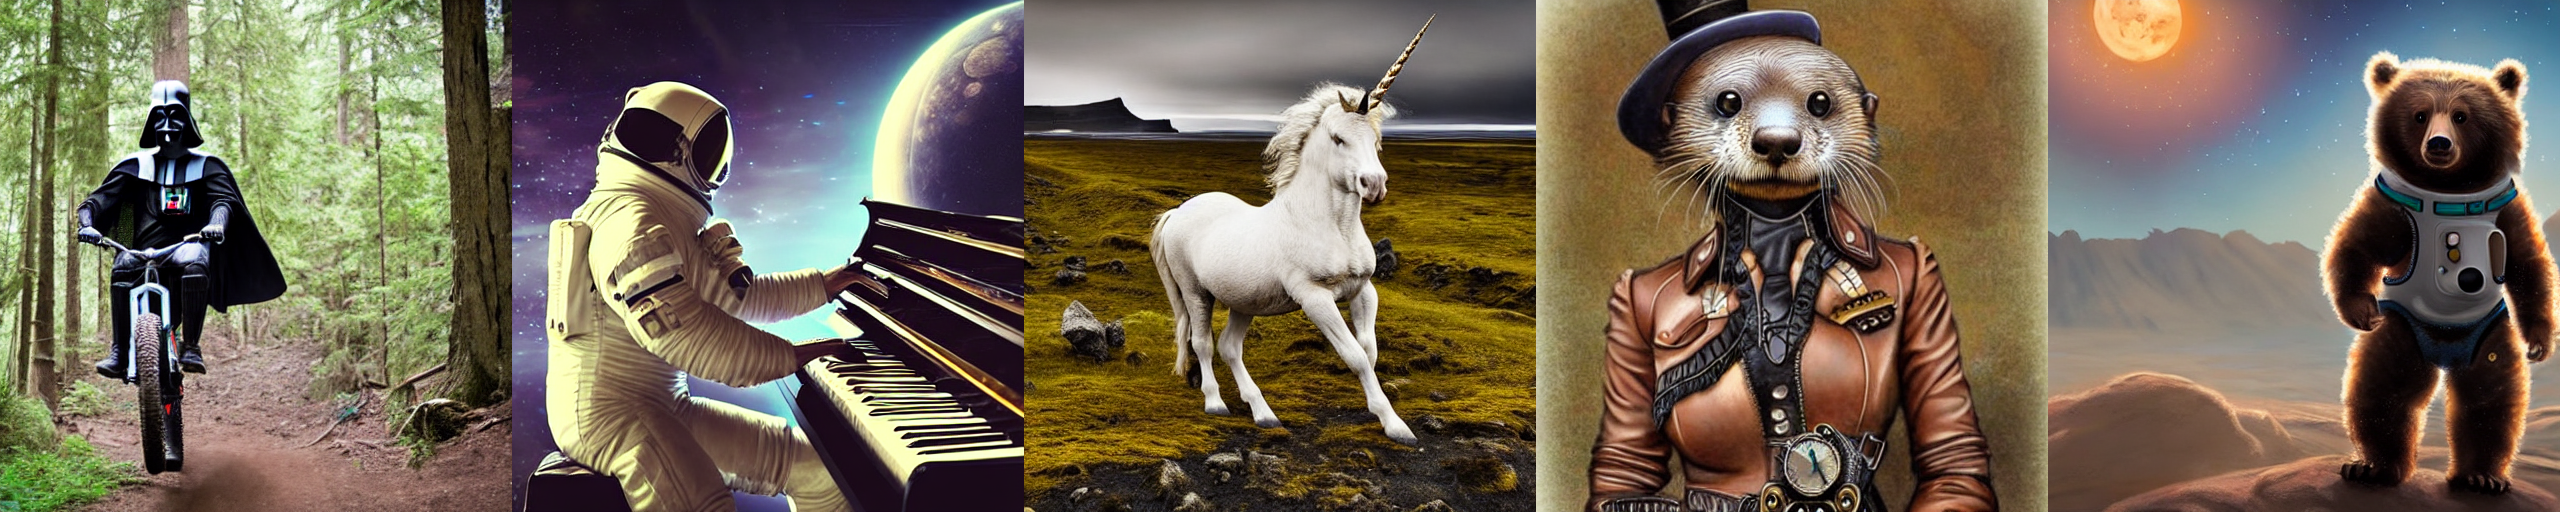
Stable Diffusion is a latent text-to-image diffusion model that generates images from text prompts, built by CompVis with Stability AI and Runway, based on the Latent Diffusion Models work from CVPR '22.
- 4
Fooocus
53.6Klllyasviel/Fooocus · PythonFooocus is an open-source AI image generator built on Stable Diffusion XL: an offline GPT-2 engine expands your prompt so results look good without prompt engineering or parameter tuning.
- 5
diffusers
34.7Khuggingface/diffusers · PythonDiffusers is Hugging Face's Python library for state-of-the-art pretrained diffusion models that generate images, audio, and even 3D molecule structures, all in PyTorch.
- 6
ControlNet
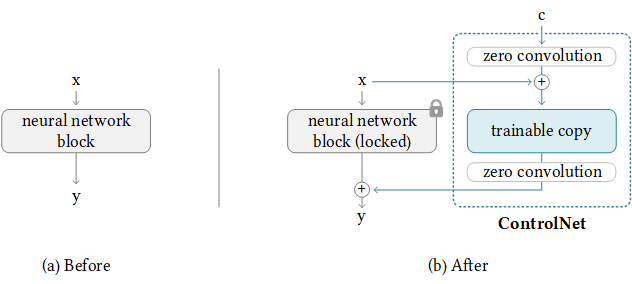
34.1Klllyasviel/ControlNet · PythonControlNet is a neural network structure that adds extra conditions to diffusion models like Stable Diffusion: instead of a text prompt alone, you steer generation with an edge map, depth map, pose skeleton or scribble. This repo is the official implementation.
- 7
Open-Sora
29.9Khpcaitech/Open-Sora · PythonOpen-Sora is an open-source initiative for efficiently producing high-quality video: it releases video generation models together with the tools, checkpoints and all training details.
- 8

InvokeAI
28.7Kinvoke-ai/InvokeAI · TypeScriptInvoke is a leading creative engine for Stable Diffusion models: a locally hosted web app for generating and editing images with AI, aimed at professionals, artists, and enthusiasts.
- 9

generative-models
27.3KStability-AI/generative-models · PythonThis is Stability AI's research codebase for a family of generative diffusion models, covering text-to-image (SDXL, SDXL-Turbo), image-to-video (Stable Video Diffusion), image-to-3D-video (SV3D), and video-to-4D (SV4D, SV4D 2.0) synthesis.
- 10

audiocraft
23.7Kfacebookresearch/audiocraft · Jupyter NotebookAudioCraft is a PyTorch library for deep learning research on audio generation, built around generative models like MusicGen (text-to-music) and AudioGen (text-to-sound), plus the EnCodec neural audio codec.
- 11

IOPaint
23.3KSanster/IOPaint · PythonA free, open-source AI photo tool: it erases unwanted objects, defects, watermarks or people from pictures, and can replace or generate content with Stable Diffusion.
- 12
learnopencv
23.2Kspmallick/learnopencv · Jupyter NotebookThis is the companion code repository for the LearnOpenCV.com blog, containing C++ and Python examples that accompany articles on computer vision, deep learning, and AI research.
- 13
Wan2.2
18KWan-Video/Wan2.2 · PythonAn open-source family of large-scale video generation models: text-to-video, image-to-video, speech-to-video and character animation, with inference code and model weights released under Apache-2.0.
- 14
ml-stable-diffusion
18Kapple-aiml-research/ml-stable-diffusion · PythonThis is Apple's toolkit for running Stable Diffusion image generation on Apple Silicon using Core ML, so it can run efficiently on Mac, iPad, and iPhone.
- 15

Grounded-Segment-Anything
17.8KIDEA-Research/Grounded-Segment-Anything · Jupyter NotebookGrounded SAM, a research demo project that combines Grounding DINO with Segment Anything to detect and segment any object in an image from a plain text prompt, extended with Stable Diffusion, RAM, Whisper and more.
- 16
FramePack
17.3Klllyasviel/FramePack · PythonFramePack is a next-frame-section prediction neural network for video diffusion, shipped as the official desktop app that turns an image and a short text prompt into a progressively generated video.
- 17
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 18

stable-diffusion-webui-colab
15.9Kcamenduru/stable-diffusion-webui-colab · Jupyter NotebookA set of ready-made Google Colab notebooks that install and run the Stable Diffusion WebUI in the cloud — one notebook per popular model, from SD 1.5 to waifu-diffusion and style fine-tunes.
- 19
Hunyuan3D-2
15.1KTencent-Hunyuan/Hunyuan3D-2 · PythonHunyuan3D 2.0 is a large-scale 3D generation system from Tencent that turns a single image (or text) into a high-resolution textured 3D mesh, using a two-stage pipeline: a shape diffusion model (Hunyuan3D-DiT) followed by a texture synthesis model (Hunyuan3D-Paint).
- 20

tortoise-tts
14.9Kneonbjb/tortoise-tts · Jupyter NotebookTortoise is a text-to-speech system built with an emphasis on quality: strong multi-voice capabilities and highly realistic prosody and intonation. This repo contains everything needed to run it in inference mode.
- 21
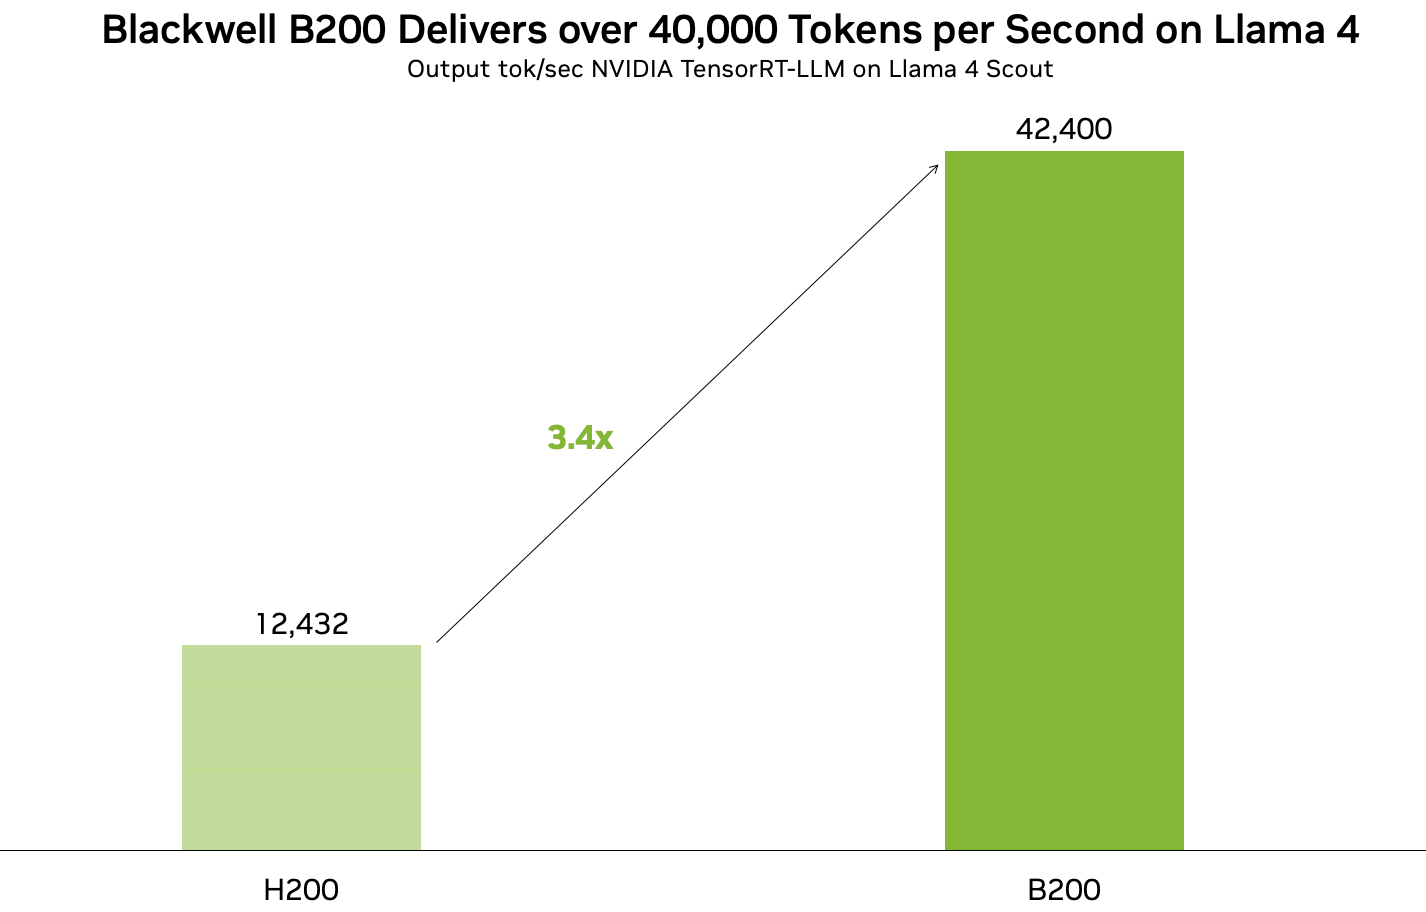
TensorRT-LLM
14.8KNVIDIA/TensorRT-LLM · PythonTensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
- 22
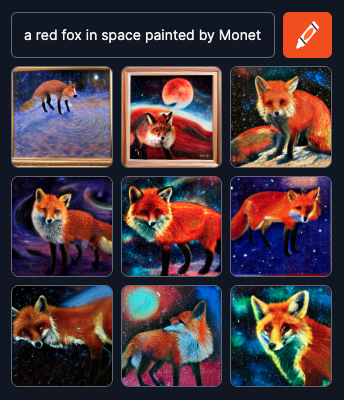
dalle-mini
14.7Kborisdayma/dalle-mini · PythonDALL·E Mini is an open-source model that generates images from a text prompt, built as a smaller, reproducible version of OpenAI's DALL·E.
- 23
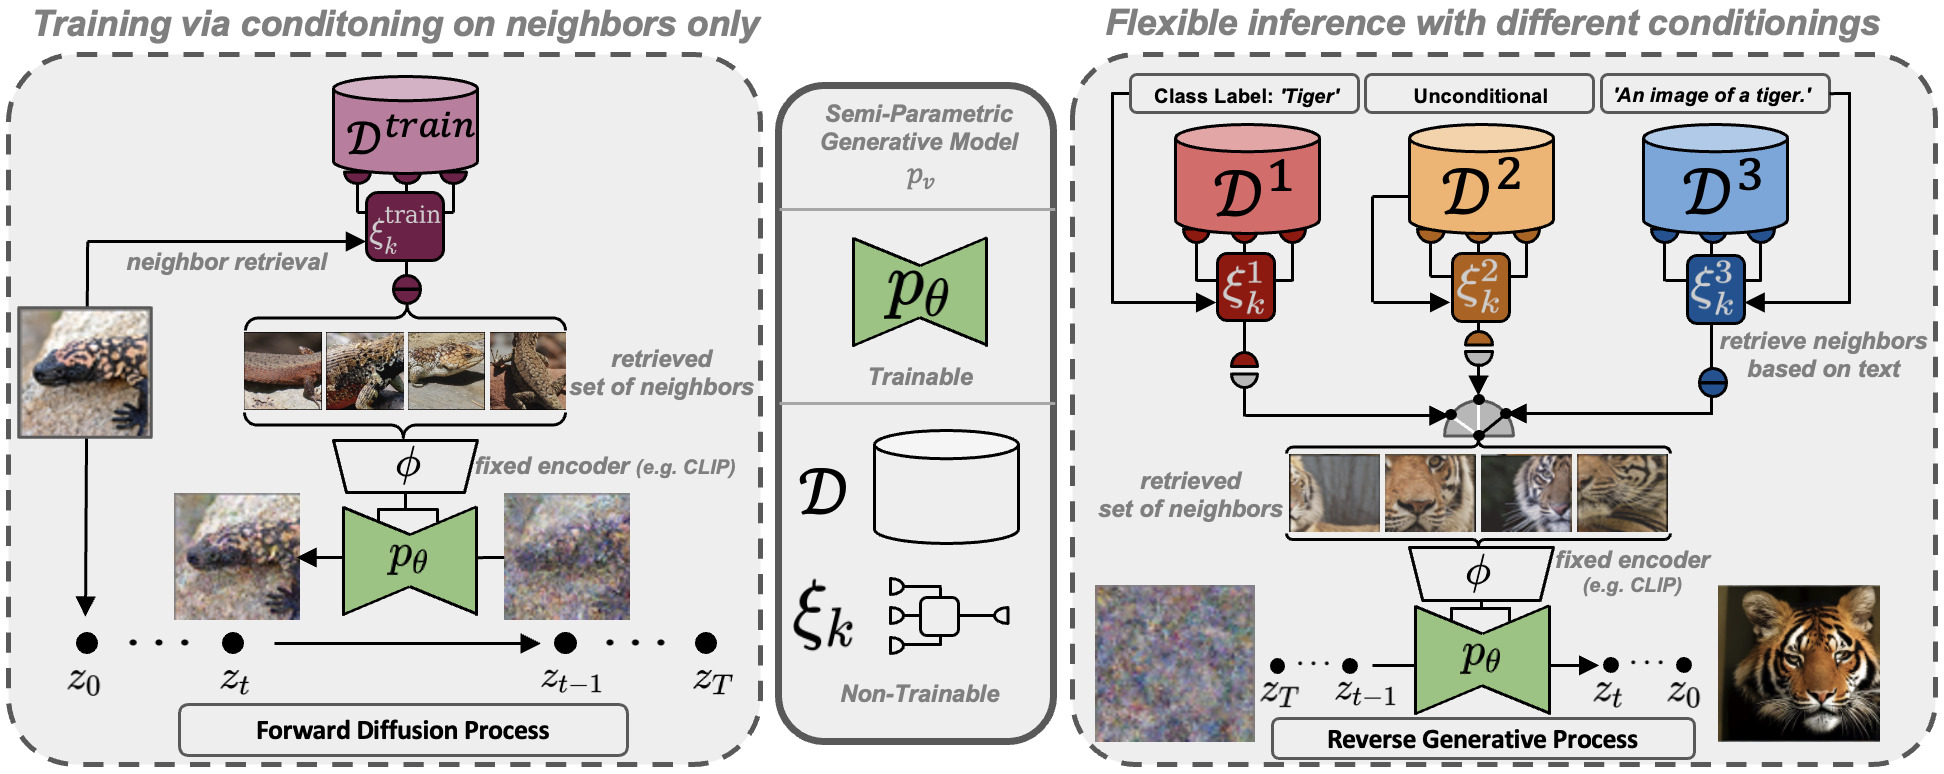
latent-diffusion
14.2KCompVis/latent-diffusion · Jupyter NotebookThis is the official research codebase for the paper 'High-Resolution Image Synthesis with Latent Diffusion Models' by CompVis, which introduced Latent Diffusion Models (LDMs) - diffusion models trained in a compressed latent space instead of raw pixel space for efficient, high-resolution image synthesis.
- 24

CogVideo
13.1Kzai-org/CogVideo · PythonAn open-source family of text-to-video and image-to-video models: CogVideoX (2024) and its CogVideoX1.5 upgrade, following CogVideo (ICLR 2023), the first open-source large Transformer-based text-to-video model.
- 25

kohya_ss
12.6Kbmaltais/kohya_ss · PythonKohya's GUI is a Gradio-based graphical interface (plus CLI) for Kohya's Stable Diffusion training scripts, letting you fine-tune diffusion models, train LoRA/LoHa/LoKr, Dreambooth, Textual Inversion, and full fine-tuning without hand-writing training commands.
- 26
HunyuanVideo
12.6KTencent-Hunyuan/HunyuanVideo · PythonHunyuanVideo is Tencent's open-source video foundation model, a 13B+ parameter diffusion transformer that generates videos from text (and images) at quality the authors claim matches or beats closed-source competitors like Runway Gen-3 and Luma 1.6.
- 27

Awesome-Diffusion-Models
12.4Kdiff-usion/Awesome-Diffusion-Models · HTMLA curated collection of papers and resources on Diffusion Models, covering theory, applications, and related research.
- 28
ai-toolkit
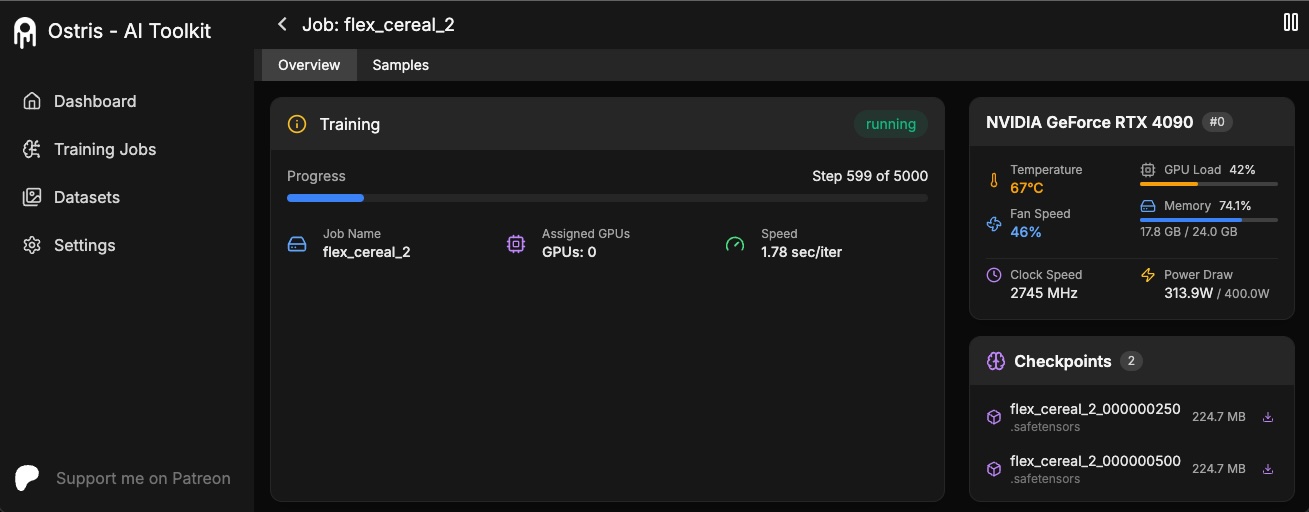
12.3Kostris/ai-toolkit · PythonAI Toolkit is an all-in-one training suite for finetuning diffusion models, covering image, video, and audio generation models, with support for the latest models like FLUX, Qwen-Image, Wan 2.1/2.2, and Ace-Step on consumer GPUs.
- 29

AnimateDiff
12.3Kguoyww/AnimateDiff · PythonAnimateDiff is the official implementation of a research method that turns personalized text-to-image Stable Diffusion models into animation (text-to-video) generators without any extra fine-tuning of those models.
- 30
Open-Sora-Plan
12.2KPKU-YuanGroup/Open-Sora-Plan · PythonOpen-Sora Plan is an open-source community project that aims to reproduce OpenAI's Sora text-to-video model, led by a PKU-affiliated AIGC lab with contributions from Huawei and Pengcheng Lab.
- 31
Z-Image
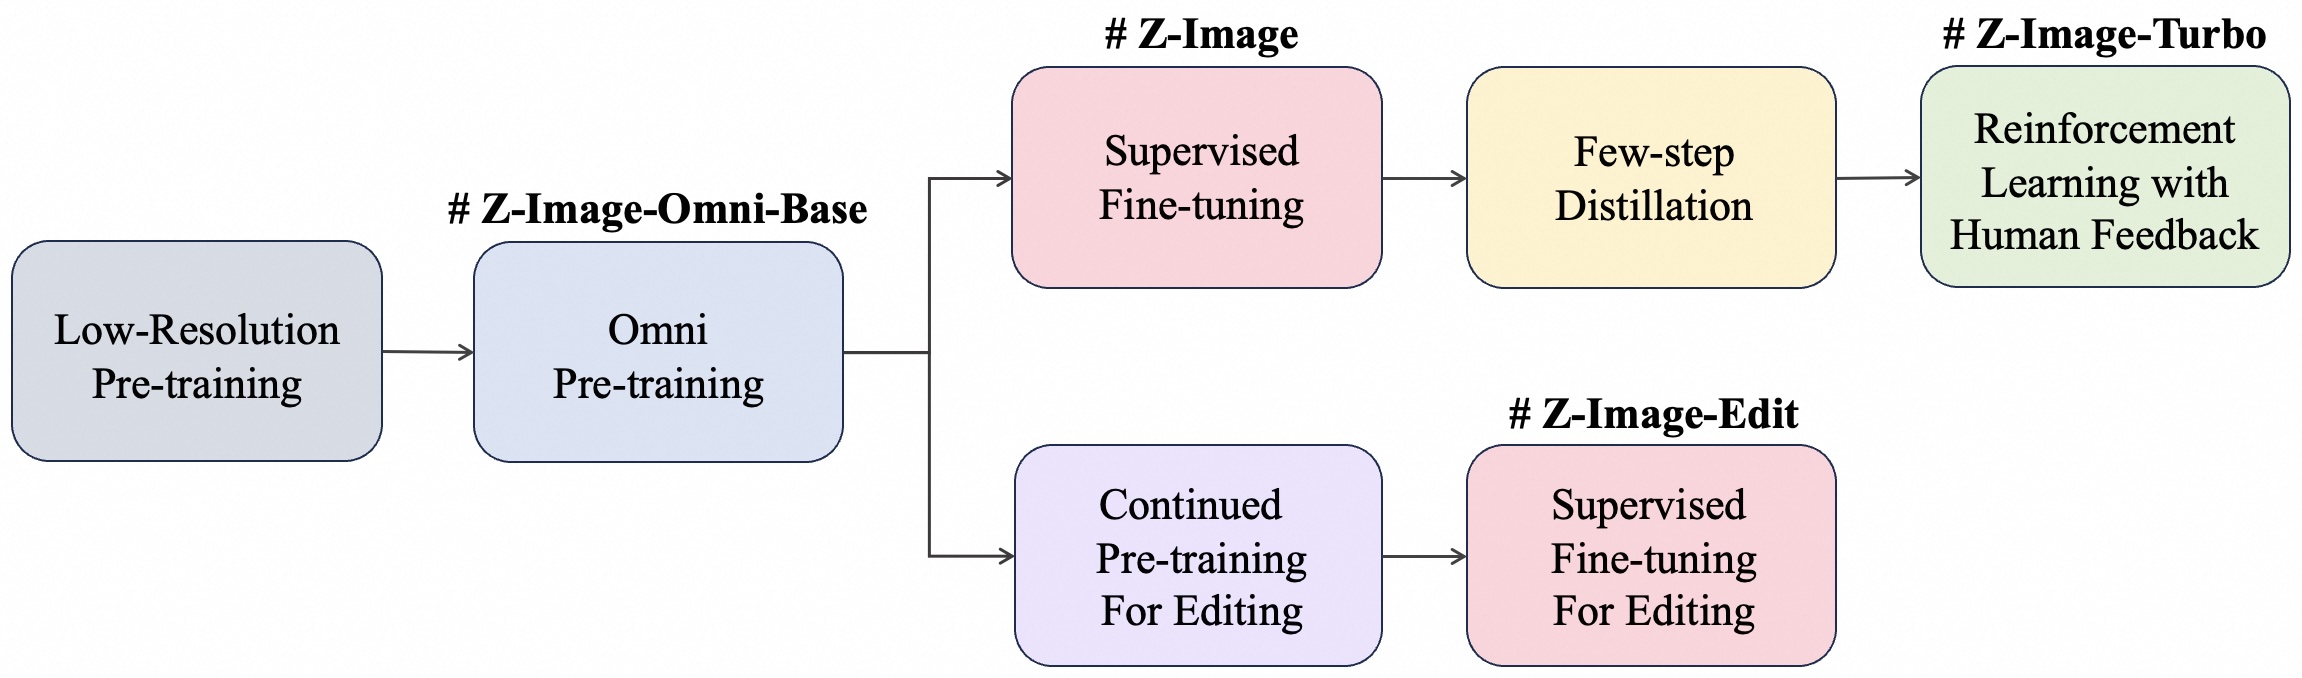
12.1KTongyi-MAI/Z-Image · PythonZ-Image is a family of efficient image generation models with 6B parameters, built around a single-stream diffusion transformer architecture, developed by Alibaba's Tongyi team.
- 32
TRELLIS.2
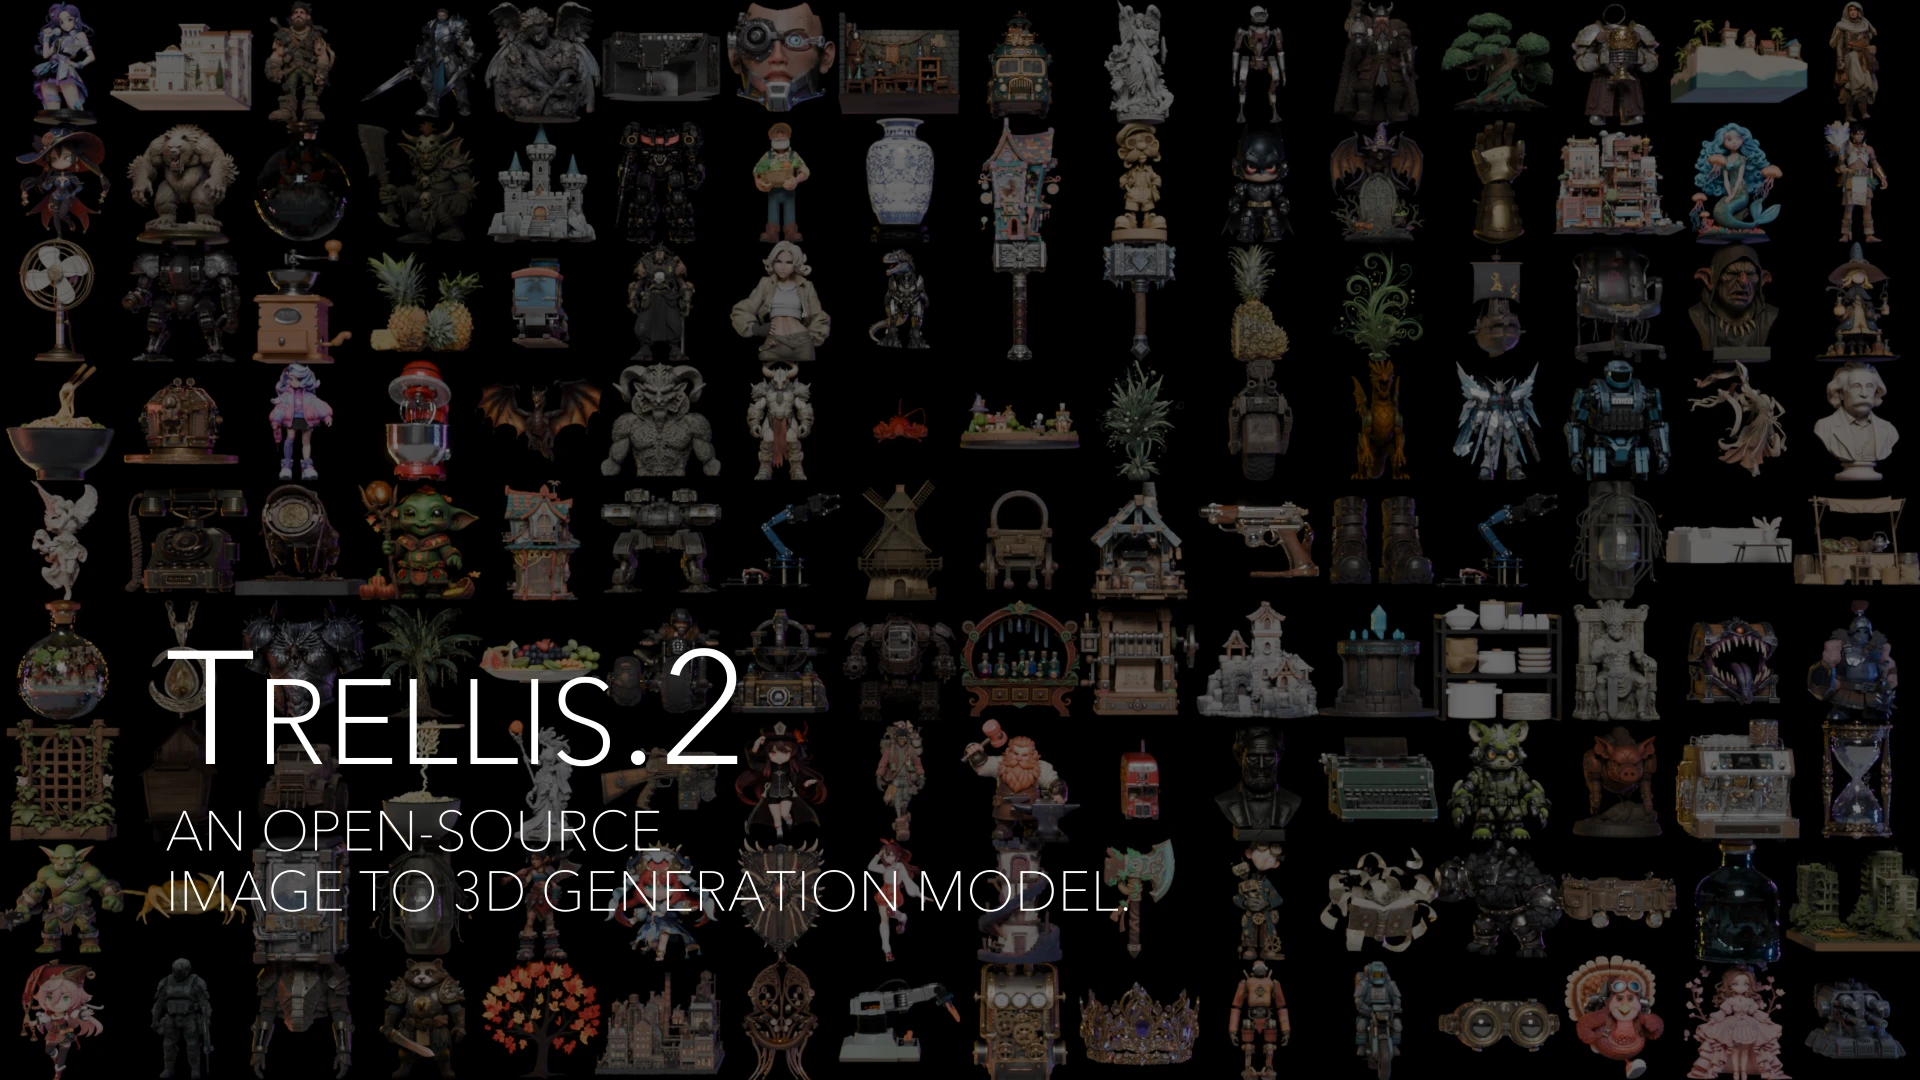
12.1Kmicrosoft/TRELLIS.2 · PythonTRELLIS.2 is a 4-billion-parameter 3D generative model for high-fidelity image-to-3D generation, using a novel field-free sparse voxel representation (O-Voxel) to produce assets with complex topology and full PBR materials.
- 33
cosmos
12.1KNVIDIA/cosmos · Jupyter NotebookNVIDIA Cosmos is an open platform of world models, datasets, and tools for building Physical AI — systems that understand and generate the physical world for robots, autonomous vehicles, and smart infrastructure.
- 34
InstantID
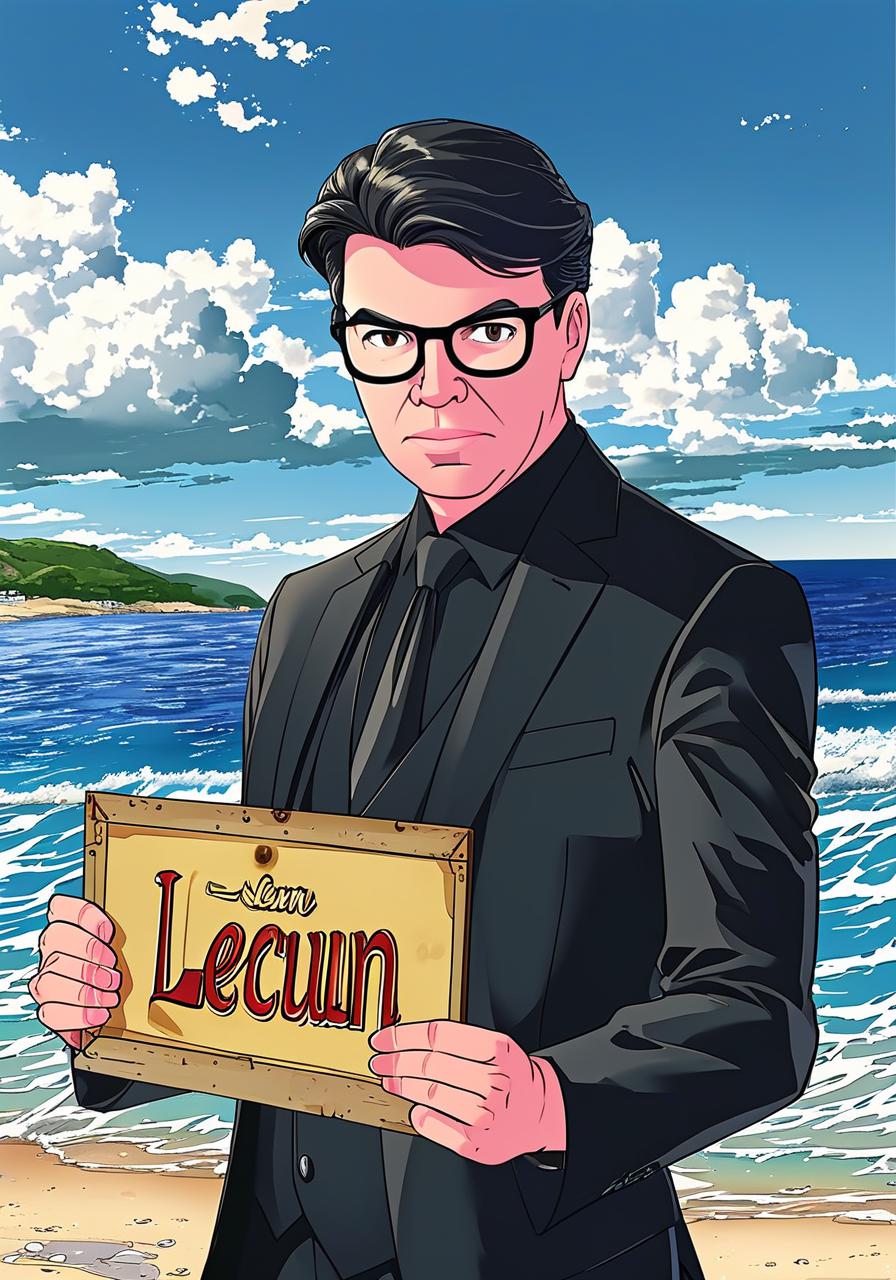
12KinstantX-research/InstantID · PythonInstantID is a tuning-free method for identity-preserving image generation: a single reference photo of a face plus a text prompt is enough to create new images that keep the person's likeness, in seconds.
- 35

DALLE2-pytorch
11.3Klucidrains/DALLE2-pytorch · PythonIt is a PyTorch implementation of DALL-E 2, OpenAI's text-to-image synthesis model, built by a third-party community author (lucidrains).
- 36

LTX-Video
11.1KLightricks/LTX-Video · PythonLTX-Video is the official repo for Lightricks' DiT-based video generation model, which generates synchronized audio+video, supports text-to-video and image-to-video, keyframe conditioning, video extension, and video-to-video transformations.
- 37
openvino
11Kopenvinotoolkit/openvino · C++OpenVINO is Intel's open-source toolkit for optimizing and deploying AI inference — it takes trained deep learning models for vision, speech, NLP, and generative AI and runs them faster, from edge devices to cloud servers.
- 38

WanGP
10.6Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 39

machine-learning-notes
10.4Kroboticcam/machine-learning-notes · Jupyter NotebookA continuously updated, free collection of over 2000 slides and lecture notes covering machine learning, probabilistic models, deep learning, and related mathematics, written by the author over more than a decade.
- 40
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 41
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 42

LongCat-Video
9.2Kmeituan-longcat/LongCat-Video · PythonLongCat-Video is a 13.6B-parameter foundational video generation model that unifies Text-to-Video, Image-to-Video, and Video-Continuation generation in a single architecture, aimed at efficient long-video generation and framed as a first step toward world models.
- 43
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 44
maths-cs-ai-compendium
7.7KHenryNdubuaku/maths-cs-ai-compendium · TypeScriptAn open, unconventional online textbook covering maths, computing and AI from the ground up — intuition first, real-world context, for practitioners who want deep understanding rather than exam survival.
- 45
remove-ai-watermarks
6Kwiltodelta/remove-ai-watermarks · PythonA Python library and CLI that removes visible and invisible AI watermarks and provenance metadata (SynthID, C2PA, EXIF, IPTC, XMP, and vendor marks like Gemini's sparkle) from images and videos you generated yourself.
- 46
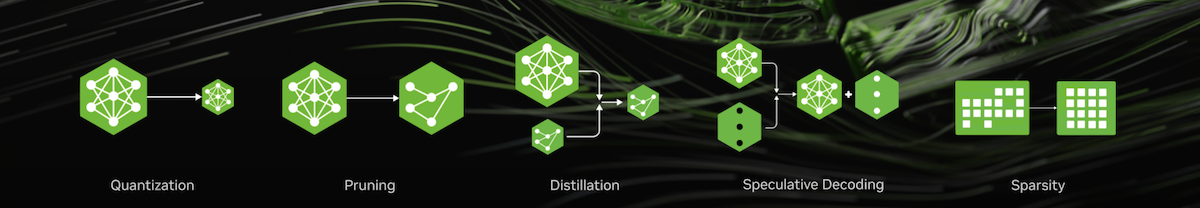
Model-Optimizer
5.3KNVIDIA/Model-Optimizer · PythonNVIDIA Model Optimizer (ModelOpt) is a Python library that bundles state-of-the-art model-compression techniques - quantization, pruning, neural architecture search, distillation, speculative decoding and sparsity - to shrink and speed up deep learning models before deployment.
- 47

see-through
4.7Kshitagaki-lab/see-through · PythonIt is the open-source code for a SIGGRAPH 2026 paper: a framework that turns a single static anime illustration into a manipulatable 2.5D model by decomposing it into fully inpainted, semantically distinct layers with inferred drawing order.
- 48

HunyuanVideo-1.5
4.6KTencent-Hunyuan/HunyuanVideo-1.5 · PythonHunyuanVideo-1.5 is a video generation model from Tencent that creates text-to-video and image-to-video clips, achieving top-tier quality with only 8.3B parameters so it runs on consumer-grade GPUs.
- 49

PersonaLive
4KGVCLab/PersonaLive · PythonPersonaLive is a real-time, streamable diffusion framework that animates a single portrait image into an infinite-length talking video, designed for live-streaming use cases. It was accepted to CVPR 2026.
- 50
TurboDiffusion
3.9Kthu-ml/TurboDiffusion · PythonTurboDiffusion is a video generation acceleration framework that speeds up end-to-end video diffusion generation by 100-200x on a single RTX 5090 while keeping video quality, using SageAttention, Sparse-Linear Attention (SLA), and rCM timestep distillation.
- 51
kimodo
3.8Knv-tlabs/kimodo · PythonKimodo is NVIDIA's kinematic motion diffusion model that generates high-quality 3D human and robot motion from text prompts and kinematic constraints like keyframes, end-effector positions, and 2D paths.
- 52
qwen21-nsfw-pose-skill
2.5KArekejoker/qwen21-nsfw-pose-skill · PythonA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
- 53
FreeVideo
2KFlashML-org/FreeVideo · PythonFreeVideo is a local inference engine that lets you run the MiniMax H3 video generation model on your own consumer GPU instead of a cloud service, adapting its memory and compute strategy to your hardware.
- 54
UniMate
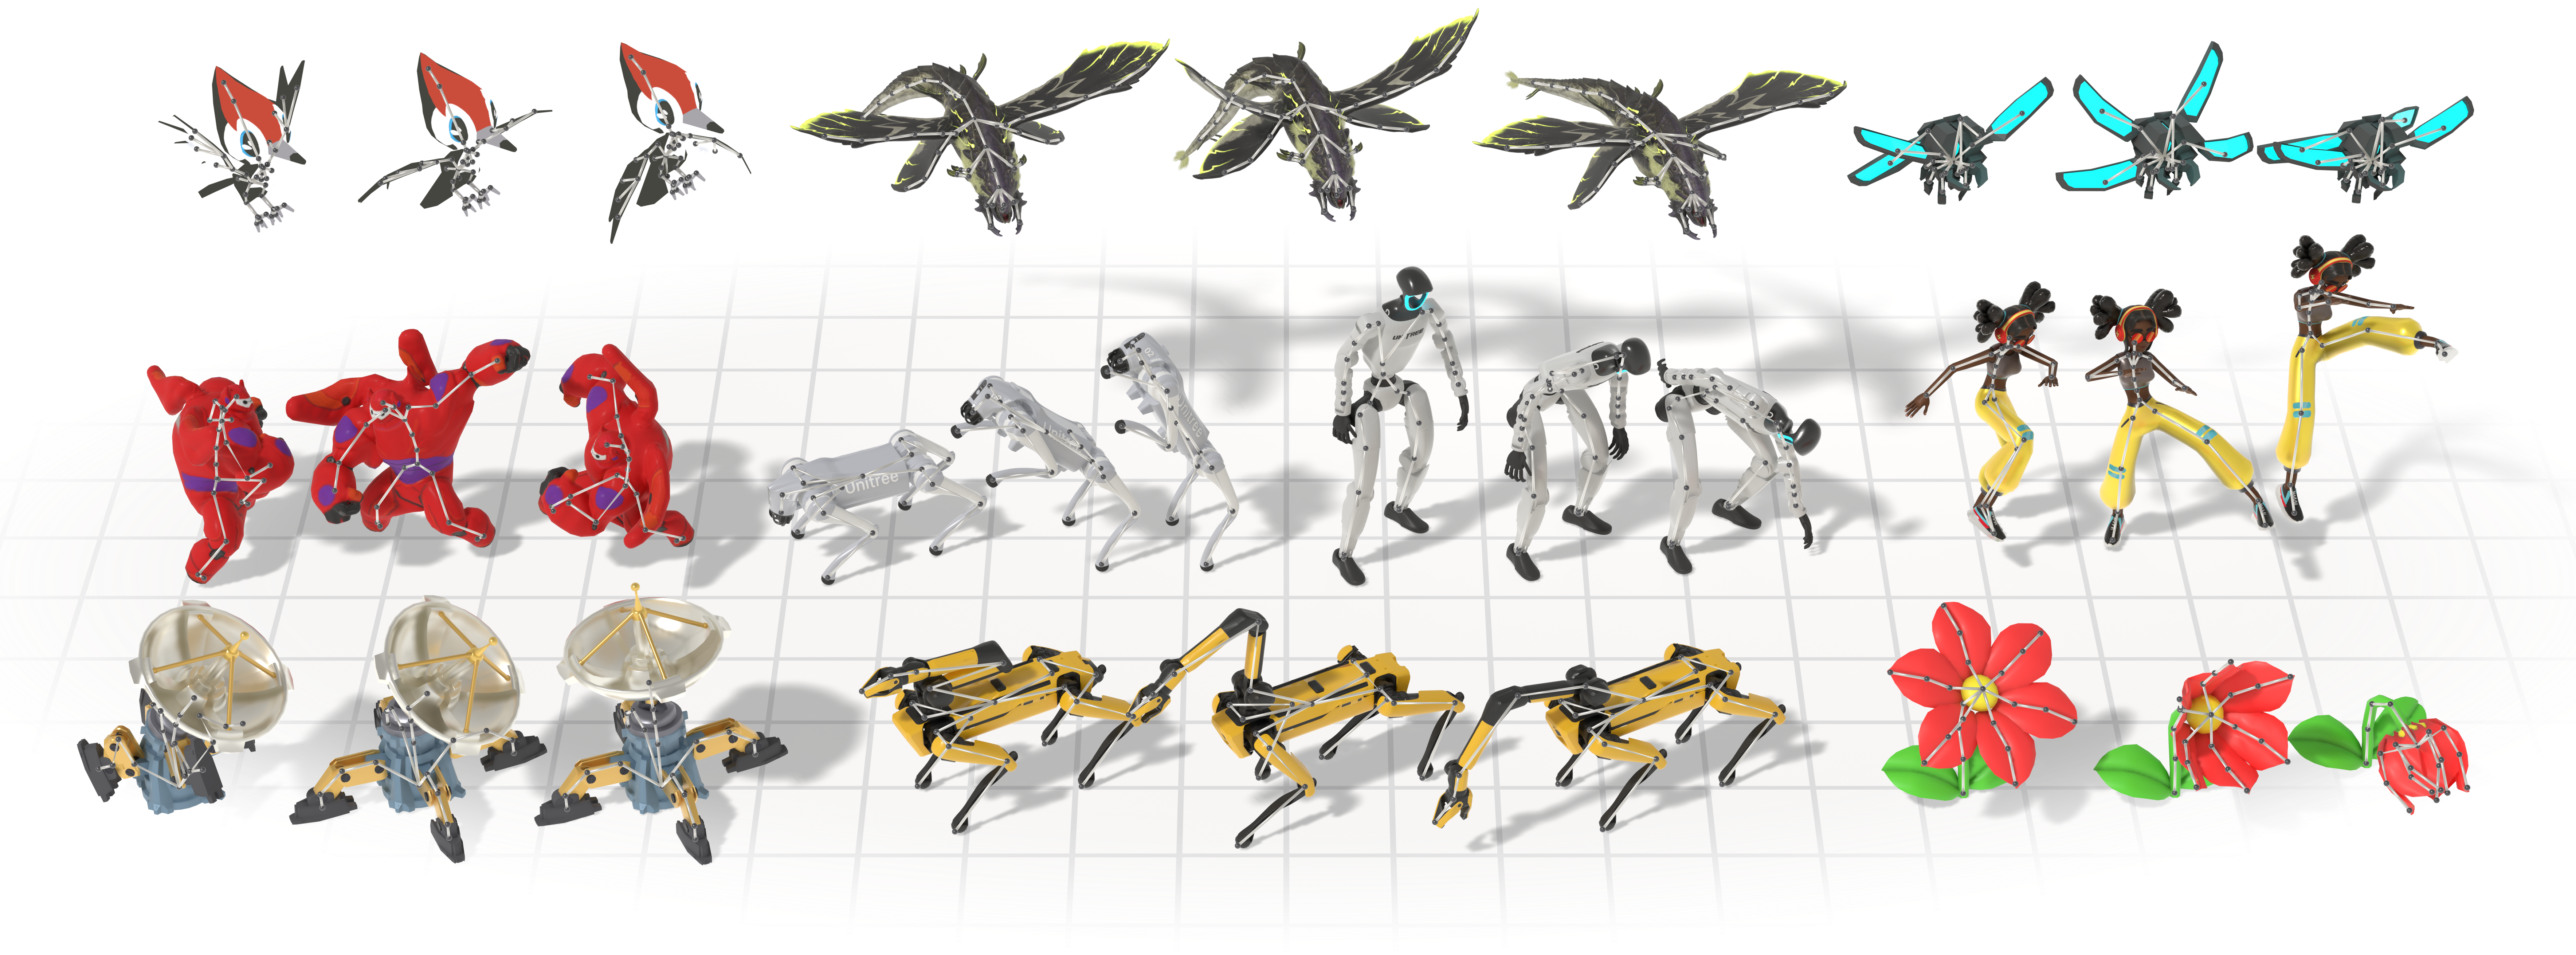
1.8KFriedrich-M/UniMate · PythonUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
- 55
workflow_templates
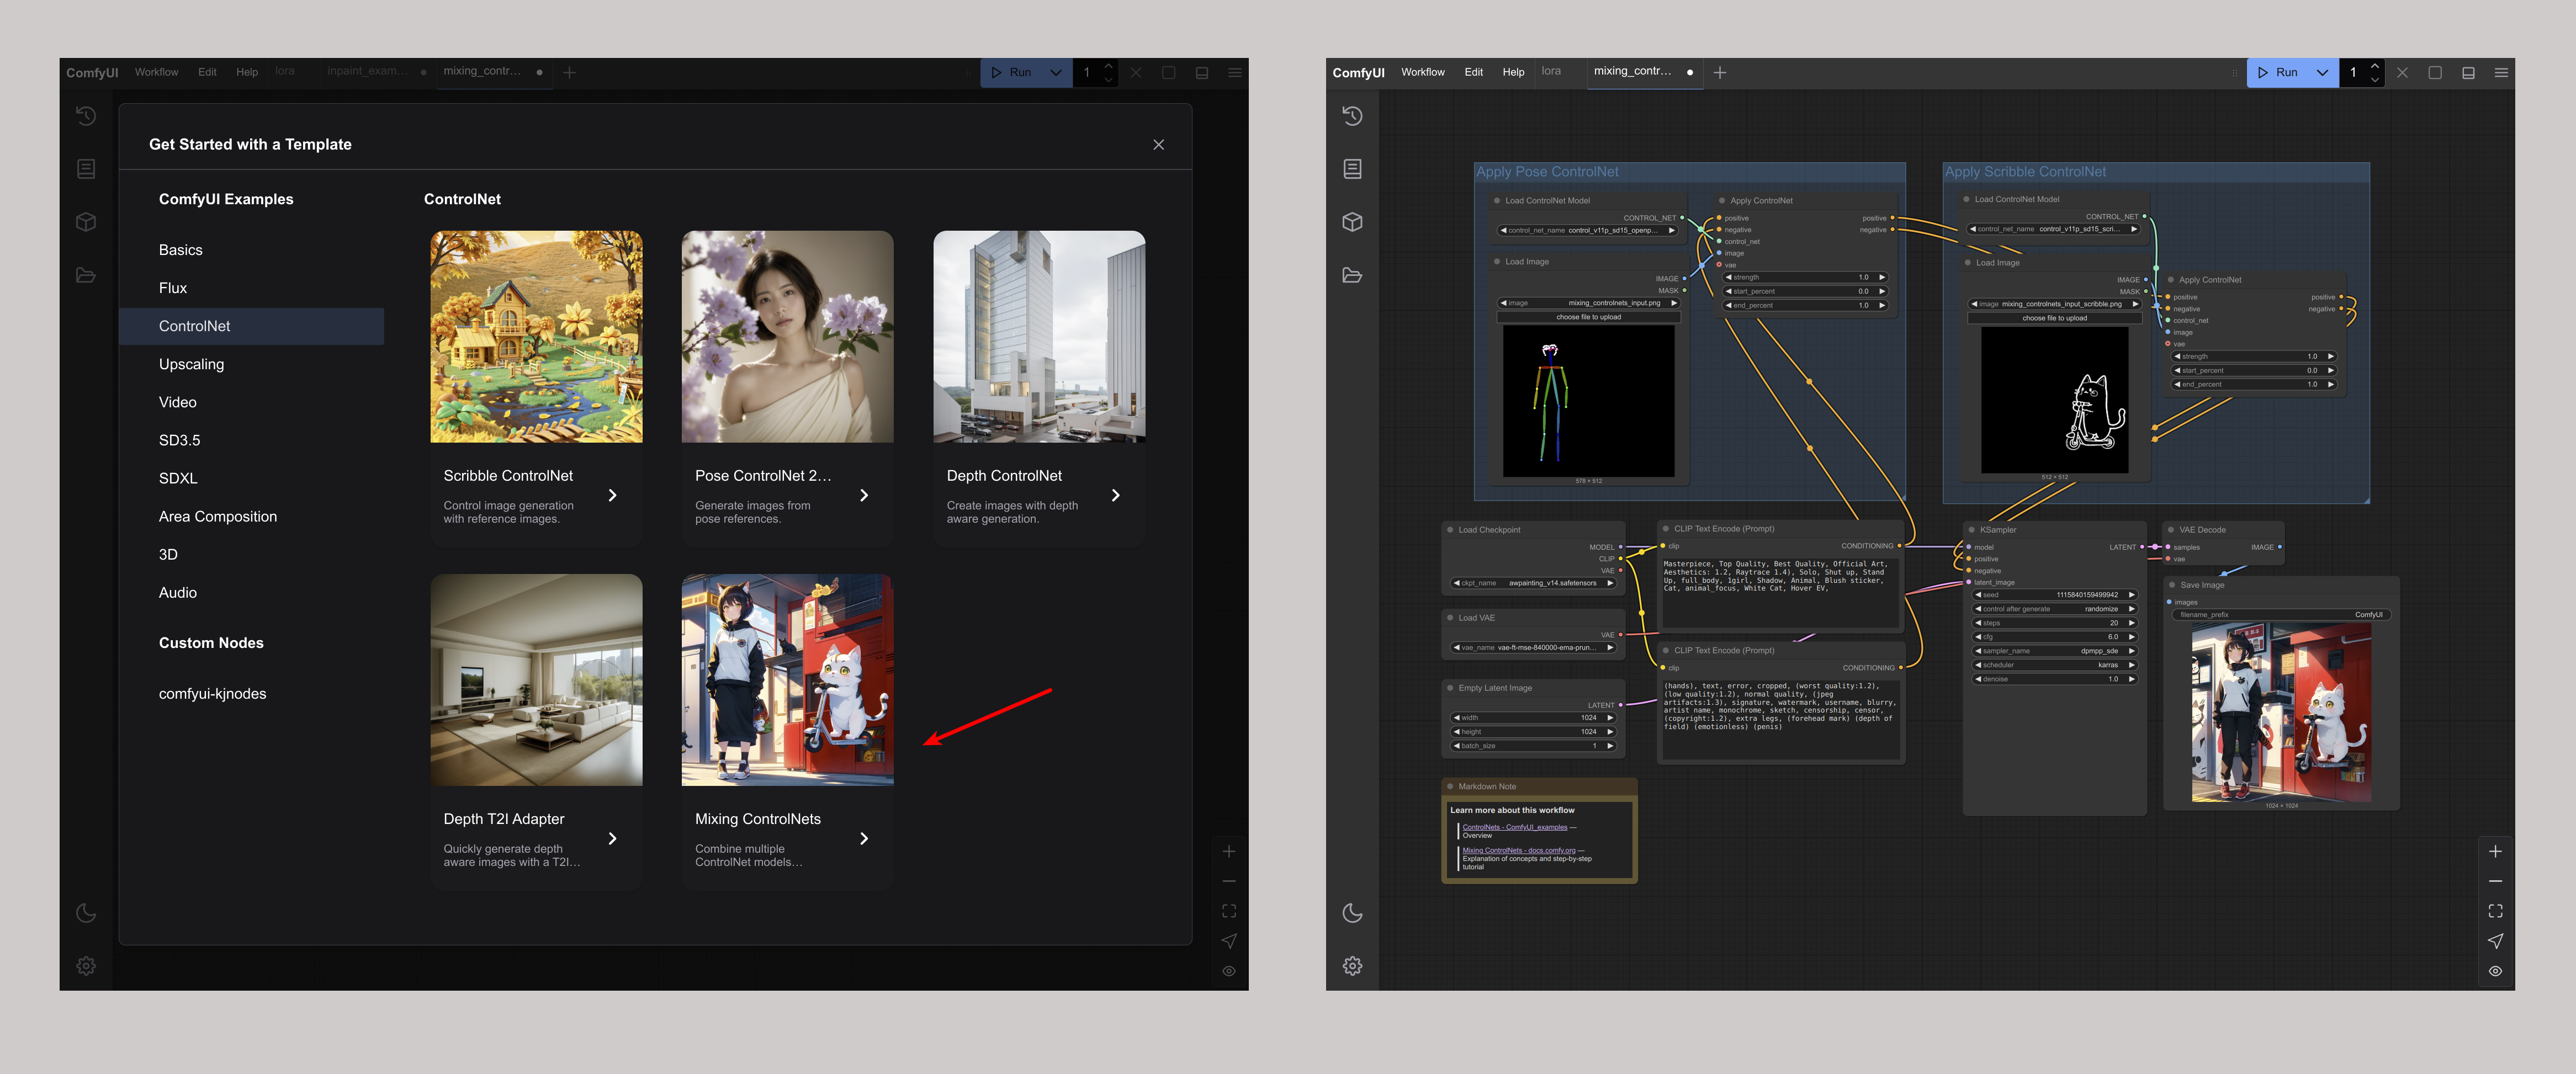
1.3KComfy-Org/workflow_templates · TypeScriptThe official collection of ComfyUI workflow templates: ready-made image, video and audio generation workflows that appear in ComfyUI's template picker and on comfy.org/workflows, plus reusable subgraph blueprints.
- 56

marigold-v2
913huawei-bayerlab/marigold-v2 · PythonMarigold V2 is a family of models and a cost-effective fine-tuning protocol that repurposes a pretrained diffusion transformer into single-step dense predictors: depth, see-through depth, surface normals, albedo, and other dense modalities.
- 57
Evoke
861AlayaLab/Evoke · PythonEVOKE is a research implementation of an interactive 'world model' that generates endless, controllable video: a three-step, CFG-free system that remembers where it has already been, lets you redirect it mid-rollout, and is state-of-the-art on the WBench long-horizon benchmark.
- 58
SolarWM
777Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 59
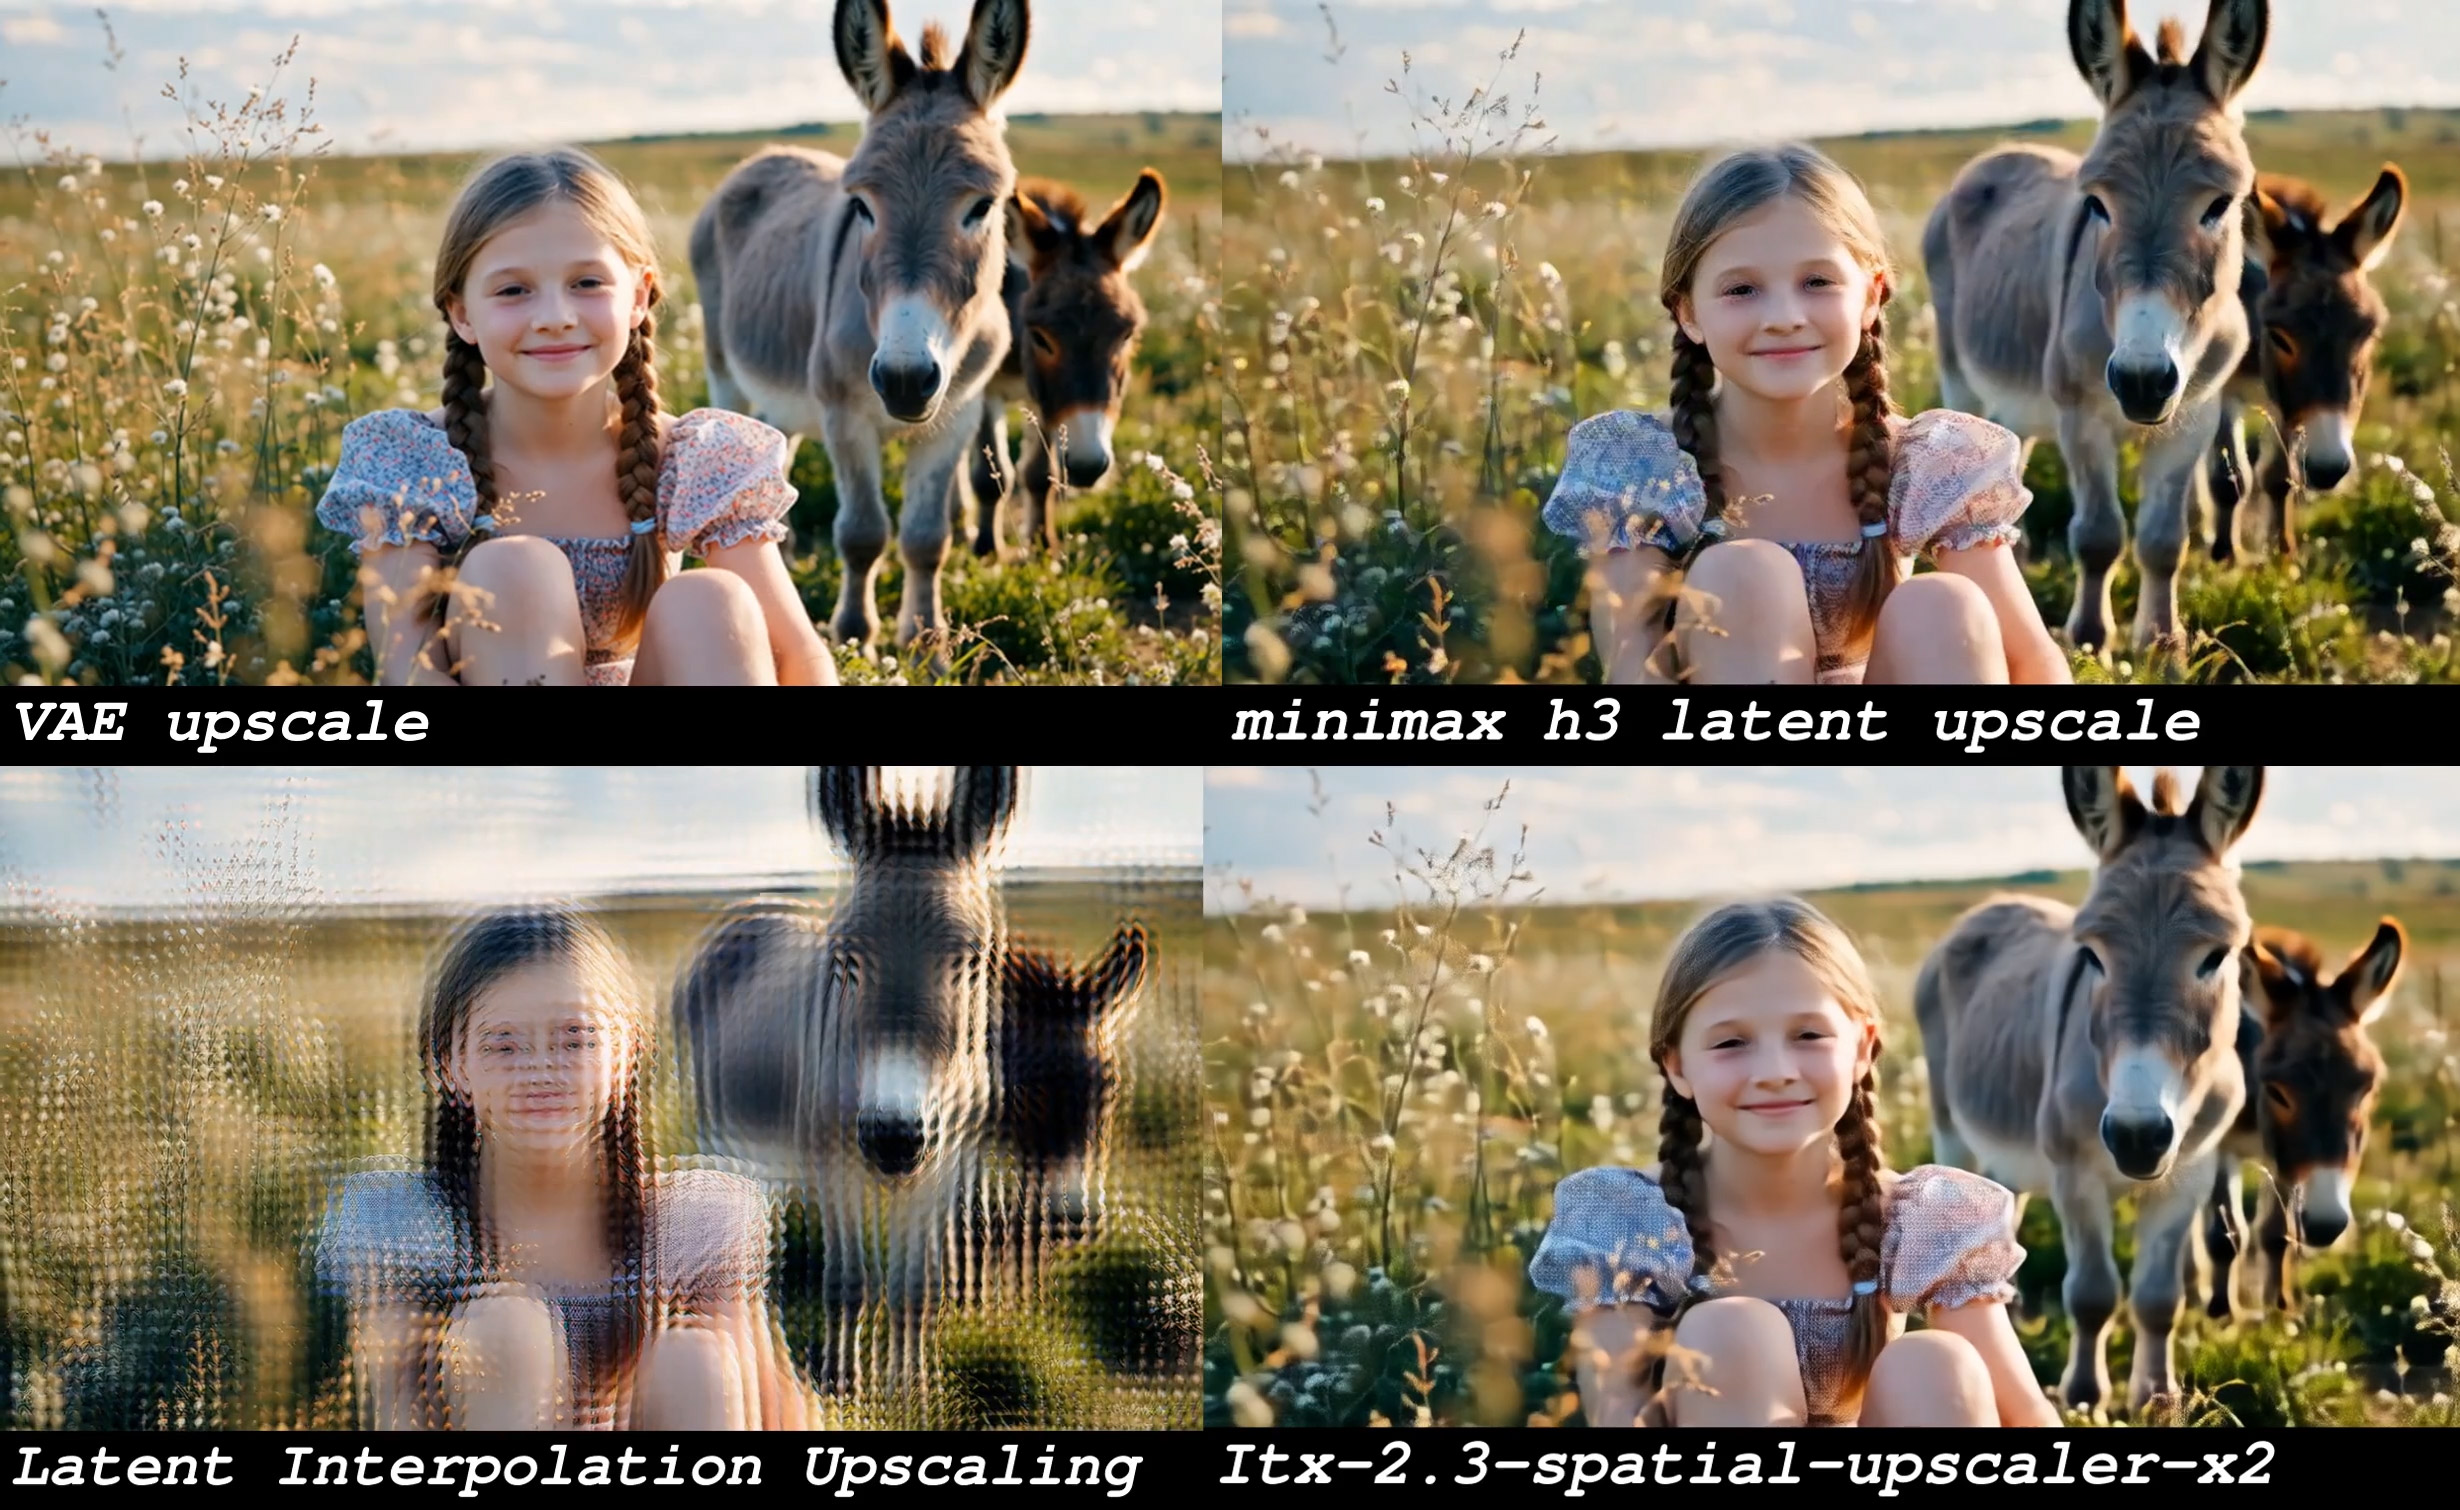
Comfyui_Minimax_h3_latent_Upscaler
750LBH-123-AI/Comfyui_Minimax_h3_latent_Upscaler · PythonA custom ComfyUI node that upscales Minimax H3 video latents (24 channels) using a trained neural network instead of naive bilinear/bicubic interpolation, so you can generate at low resolution and upscale in latent space before refining.
- 60
vdn-minimax-h3
617OpenVDN/vdn-minimax-h3 · PythonVDN-Minimax-H3 is a hybrid-attention video generation model built on MiniMax H3 that renders video faster than it plays, supporting text-to-video-audio, image-to-video-audio, first/last-frame-to-video and more from one checkpoint.
- 61
ComfyUI-Ref2VA-VSA
570Kablex/ComfyUI-Ref2VA-VSA · PythonIt's a ComfyUI custom node that dramatically speeds up Reference-to-Video (Ref2VA) generation for the MiniMax H3 model, producing a full 5-second, 24fps character video in about 72 seconds on a single RTX 4090 instead of over 10 minutes.
- 62
Colab-notebooks
556TeamAIQ/Colab-notebooks · Jupyter NotebookA curated collection of free, ready-to-run Google Colab and Kaggle notebooks, each wrapping a different AI tool for text-to-speech, voice cloning, image generation, video generation, or music generation.
- 63
ComfyUI-H3-FaceRefine
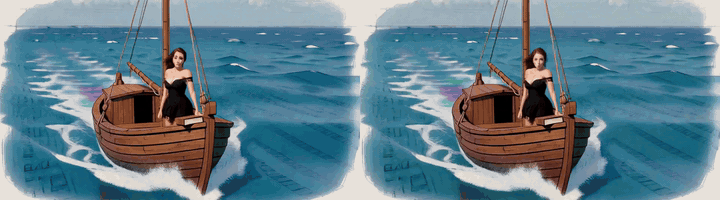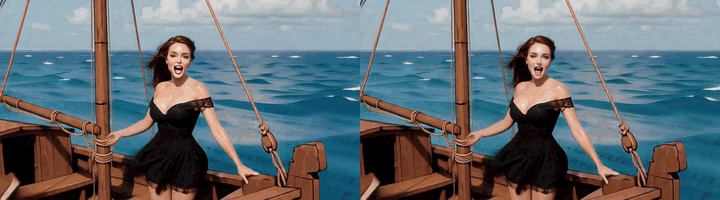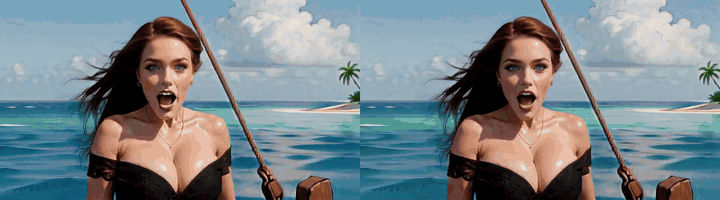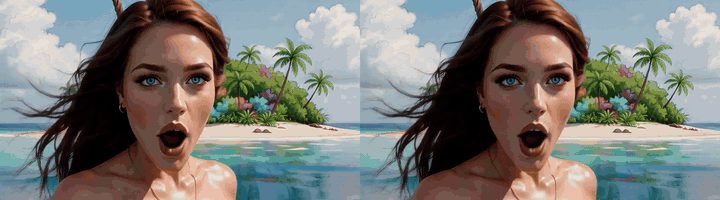
516Carasibana/ComfyUI-H3-FaceRefine · PythonThis is a ComfyUI custom node pack that fixes small, blurry faces in MiniMax H3 generated video by tracking each face per frame, cropping it to fill a canvas, letting H3 re-render the crop in detail, and compositing the refined face back into the original video.
- 64
SparkDiffusion
511AlibabaResearch/SparkDiffusion · PythonSparkDiffusion is an acceleration framework for Diffusion Transformer (DiT) video-generation models. It combines sparse low-rank attention (RoLa), few-step distillation (CrossDistill), and custom GPU operators to deliver 200x+ faster inference than a dense multi-step baseline while preserving generation quality.
- 65
awesome-minimax-h3-integration
442MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 66

ComfyUI-MiniMaxH3Mod
441Luisacaotica/ComfyUI-MiniMaxH3Mod · PythonA ComfyUI custom node pack that adds 'RefMod' reference adapters for the MiniMax H3 model. It compresses reference images, videos or audio into small reusable .safetensors files that can be loaded and applied to influence generation without any training of the H3 model.
- 67
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 68
EasyWAM
401OpenMOSS/EasyWAM · PythonEasyWAM is a unified research codebase for training, fine-tuning, and evaluating World Action Models (WAMs) — models that jointly predict future video and robot actions for embodied-AI and robotics research.
- 69

H3-World
318Danzer1xxxxChan/H3-World · PythonH3-World is an interactive world model built on MiniMax-H3: give it one initial frame and it generates video you steer with keyboard actions, like driving a game world with your keys.
- 70
ComfyUI-VOSR2
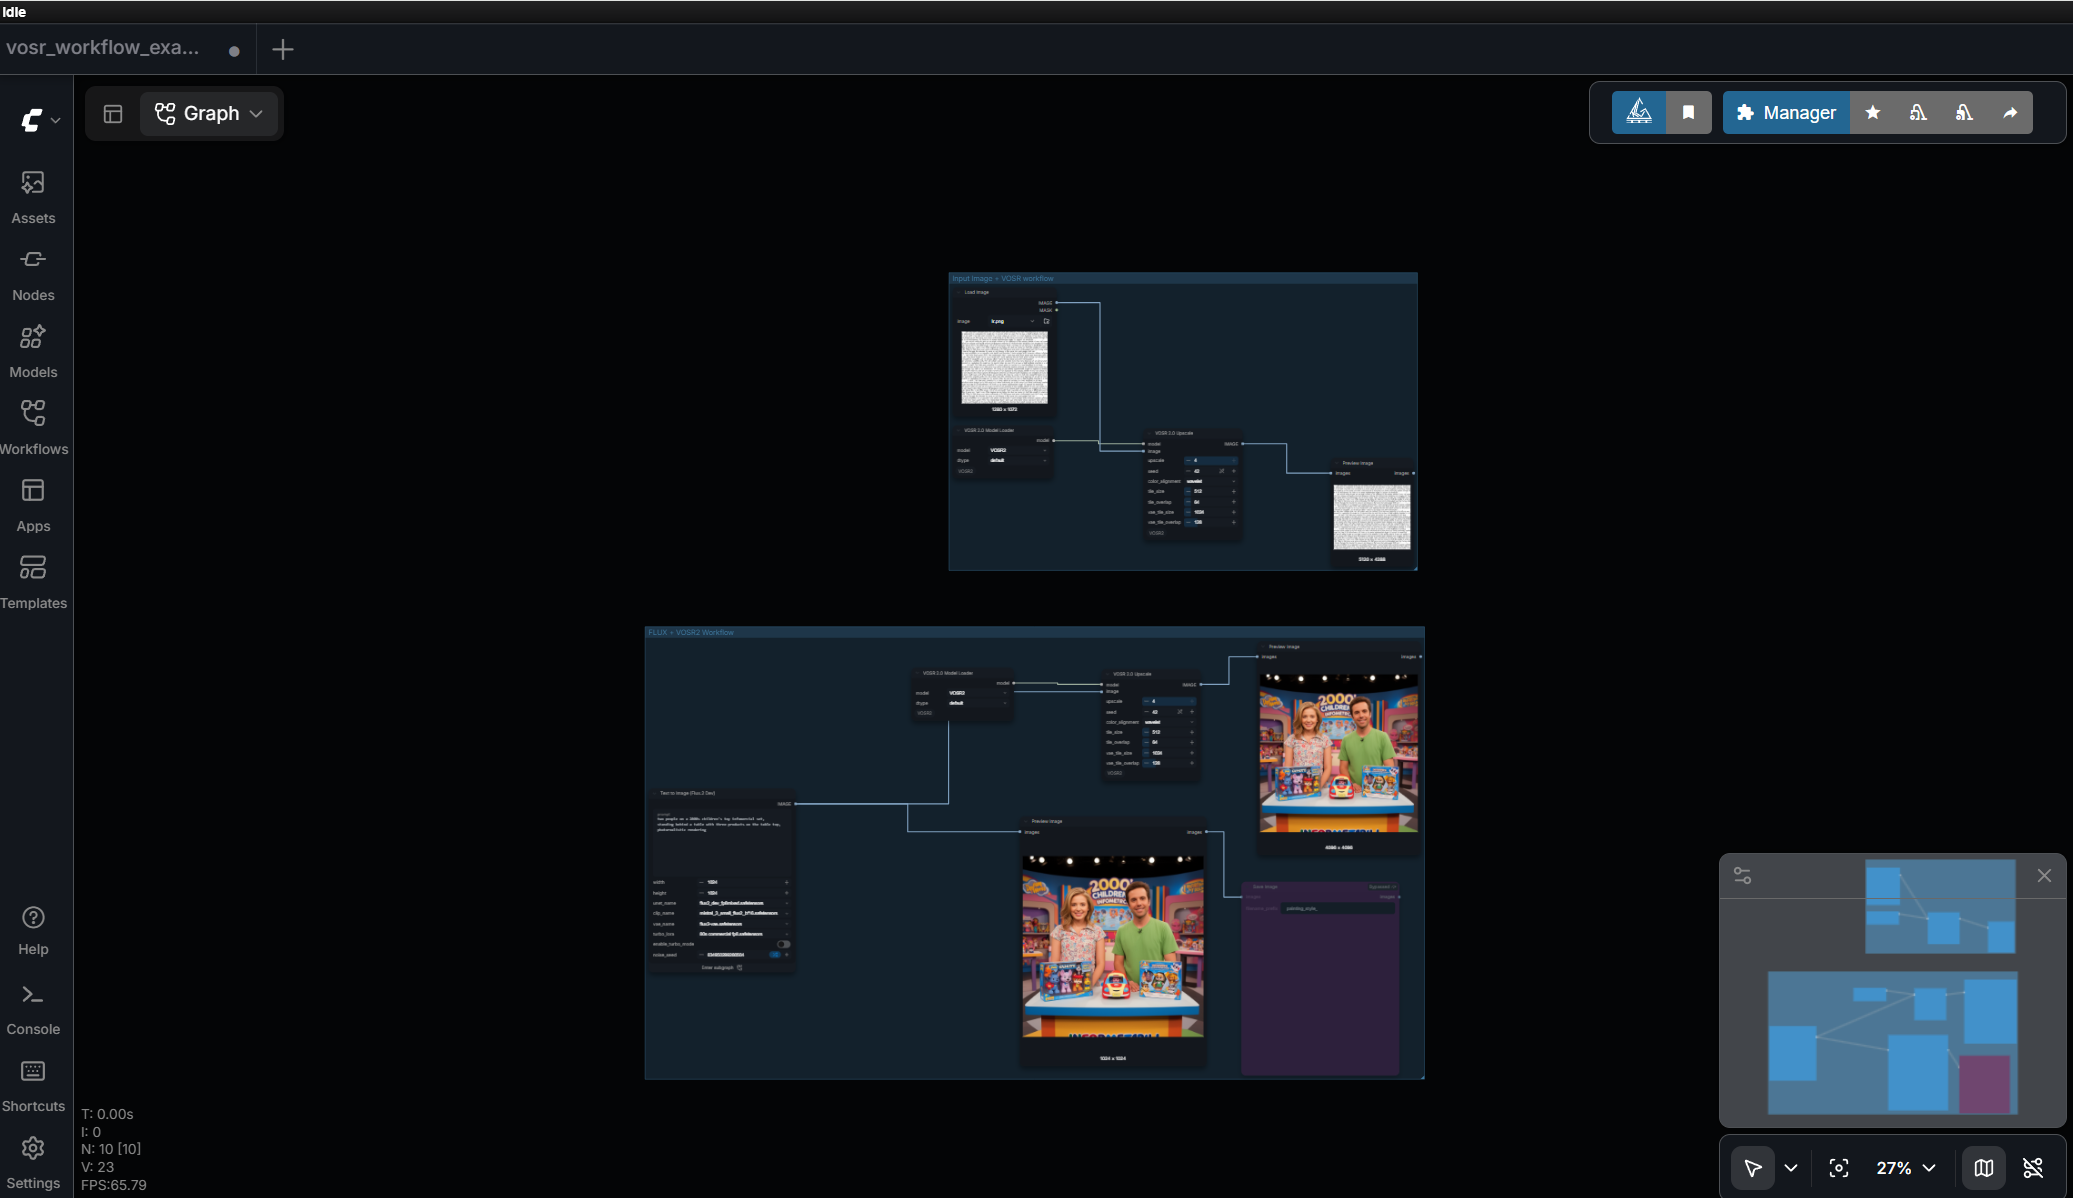
291ylchen333/ComfyUI-VOSR2 · PythonComfyUI-VOSR2 is a ComfyUI custom node wrapper for VOSR 2.0, a one-step, 1.4B-parameter image super-resolution model built on LightningDiT, a Qwen-Image 2D VAE, and DINOv2-L conditioning.
- 71
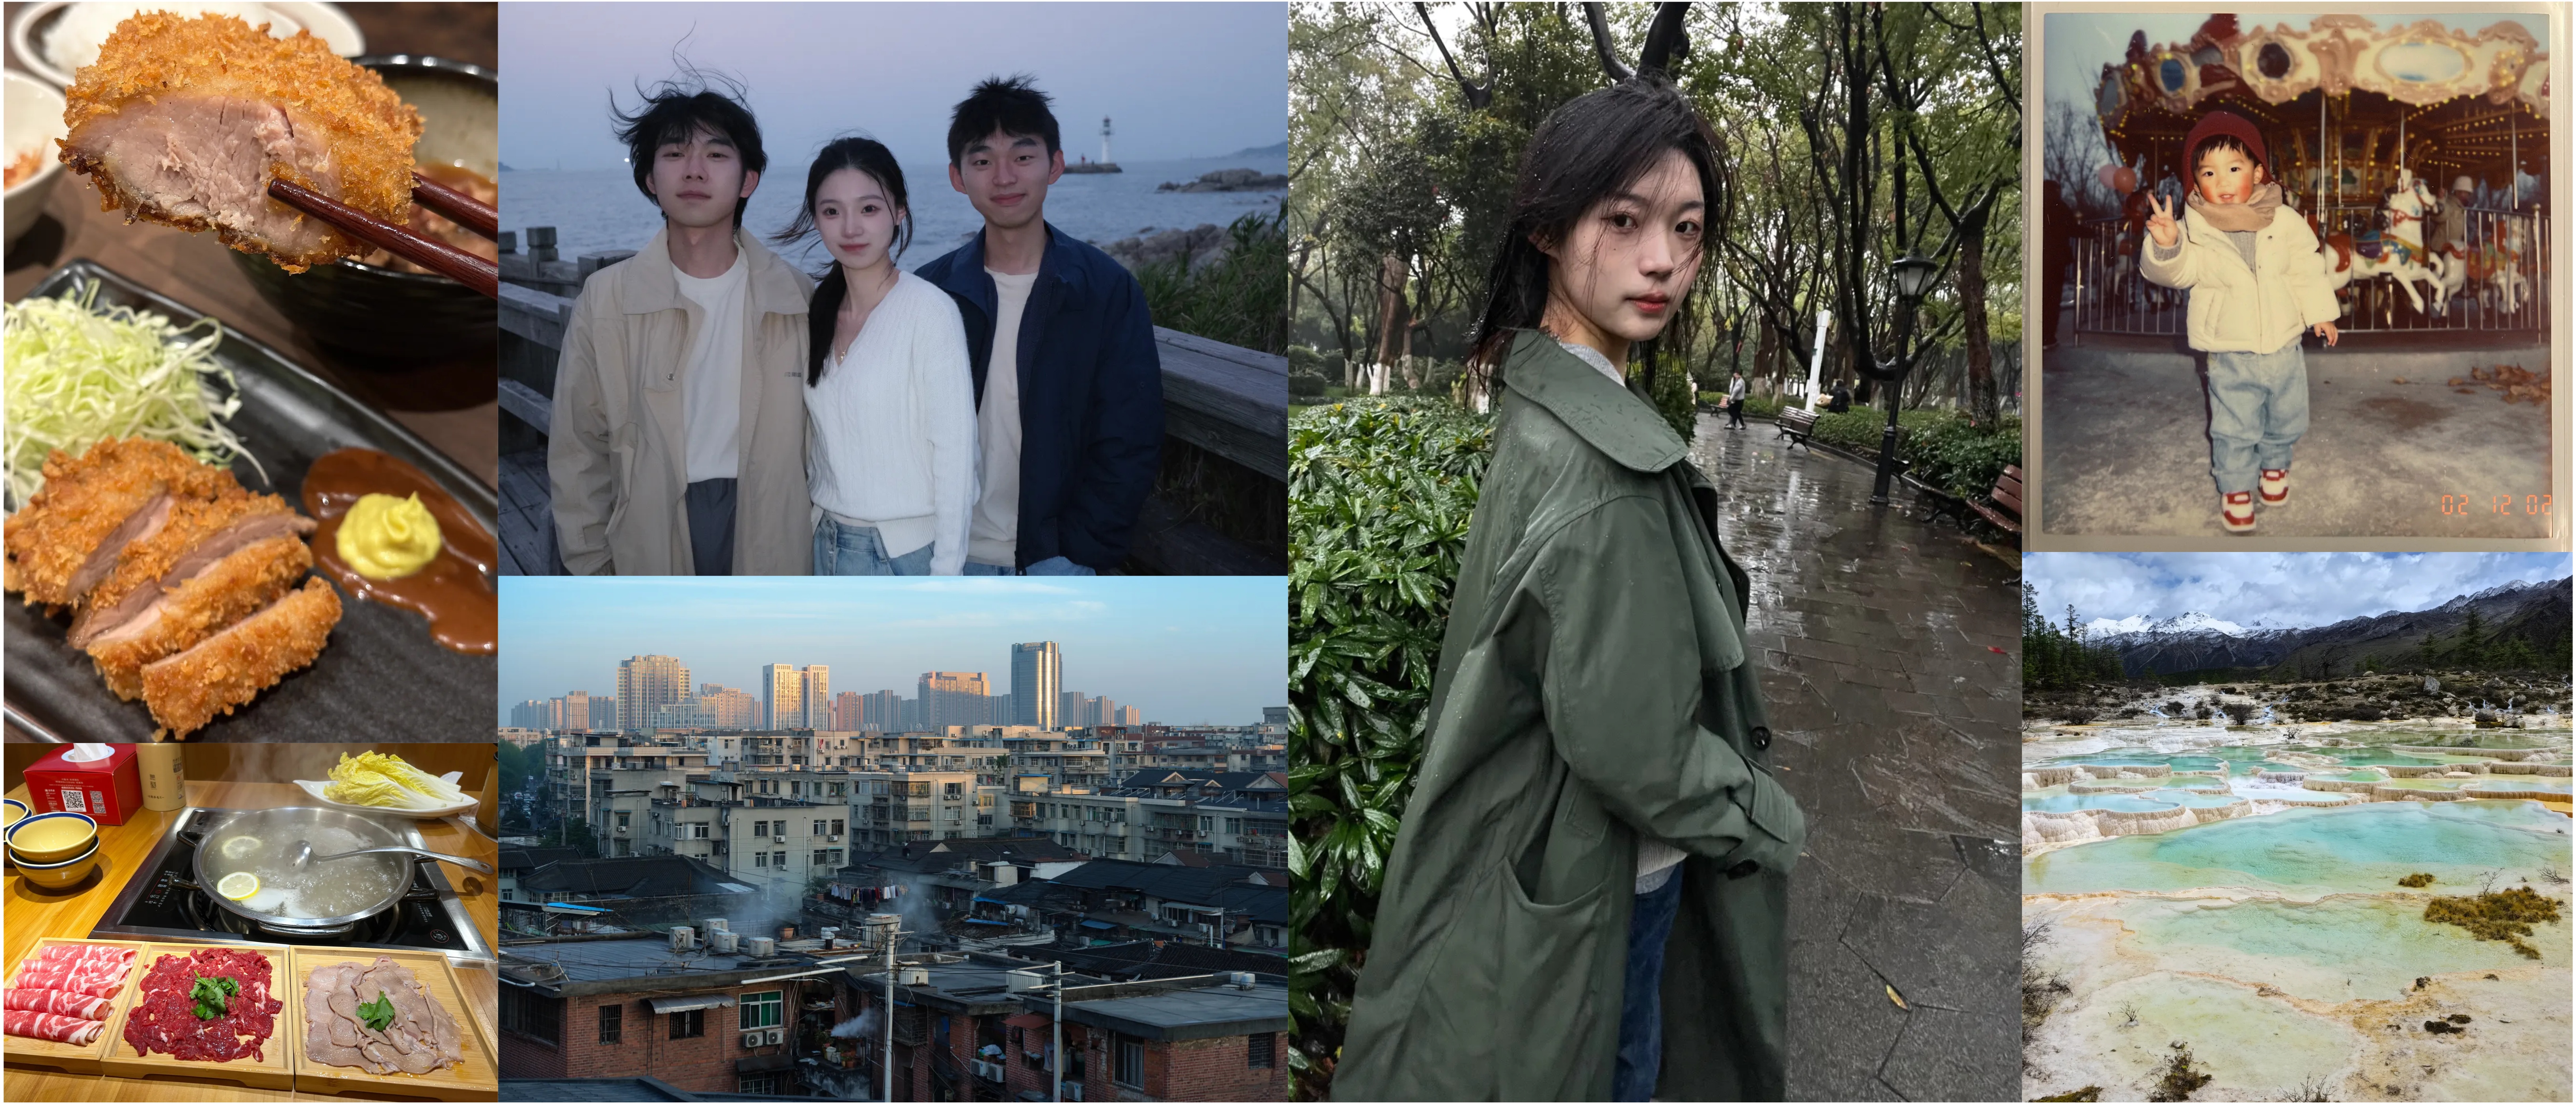
LLaDA-Image
261inclusionAI/LLaDA-Image · PythonLLaDA-Image is an open-source 6B-parameter unified model family for high-quality text-to-image generation and instruction-guided image editing, released as a 50-step Base model and a 4-step distilled Turbo model.
- 72
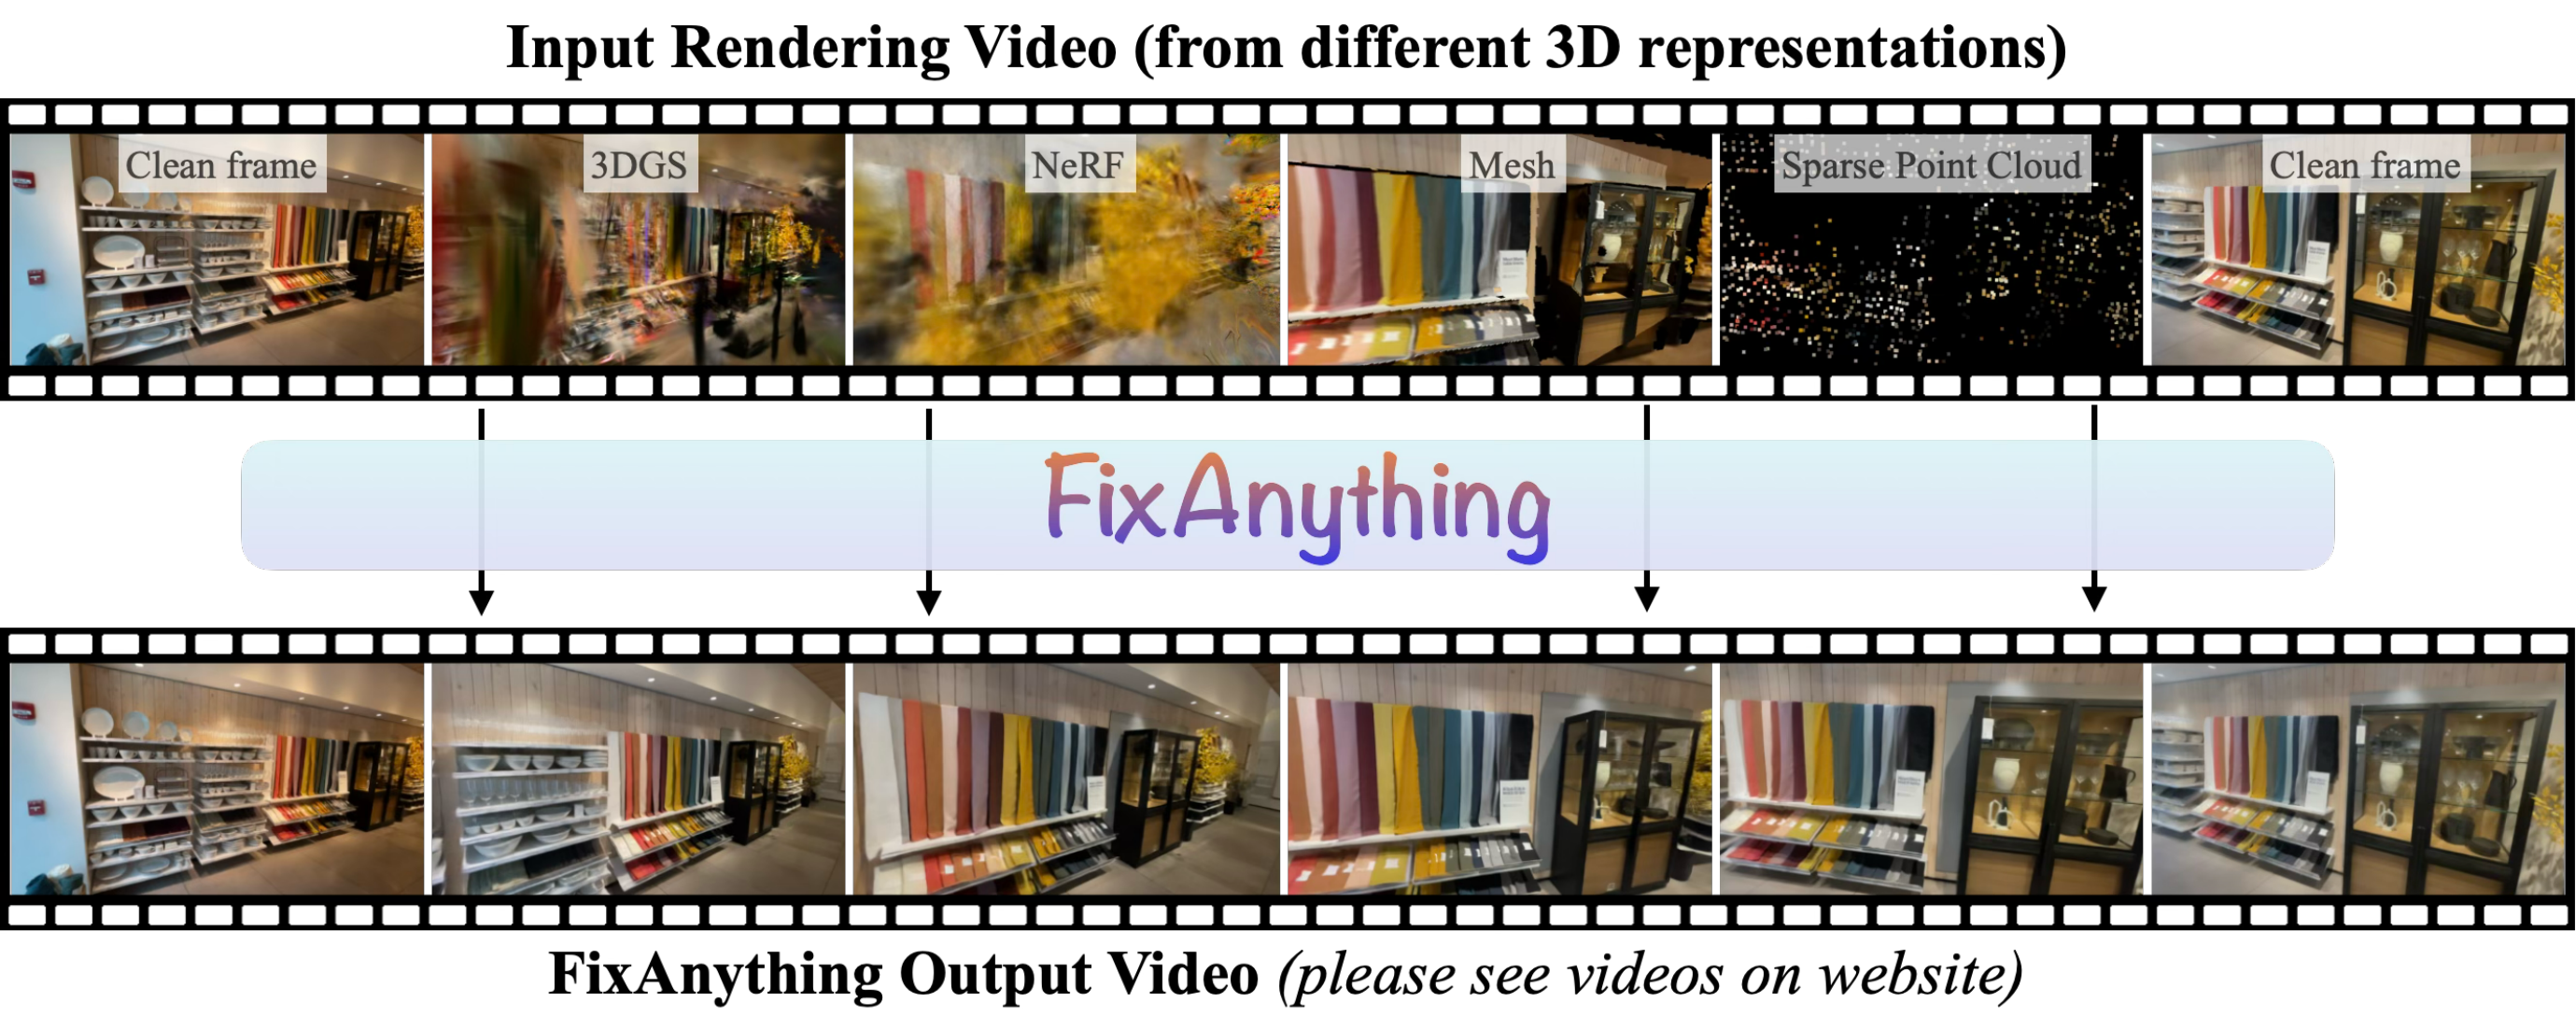
fix-anything
245kvuong2711/fix-anything · PythonA research tool from an ECCV 2026 paper: a video diffusion model fine-tuned to repair rendering artifacts from any 3D representation — 3DGS, NeRF, meshes, or sparse point clouds. The repo holds the inference code.
- 73

ComfyUI-YCNodes-MiniMax-H3
243yichengup/ComfyUI-YCNodes-MiniMax-H3 · PythonThis is a ComfyUI custom node pack built specifically for the MiniMax H3 video model, adding 6 nodes for second-pass conditioning, timed prompt control, attention-field constraints, dynamic CFG scheduling, low-noise detail refinement and tiled sampling.
- 74

Comfyui-MMH3-UltimateUpscale
236bbaudio-2025/Comfyui-MMH3-UltimateUpscale · PythonA ComfyUI custom node that upscales long, high-resolution MiniMax H3 AV video latents on VRAM-limited GPUs, using temporal chunking and spatial tiling inside a single node while keeping the audio track intact.
- 75
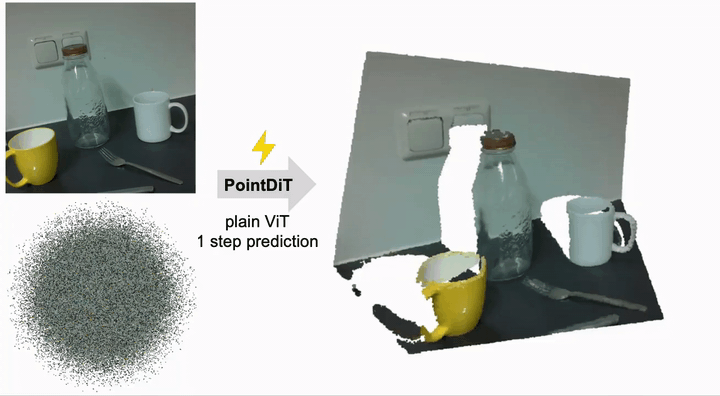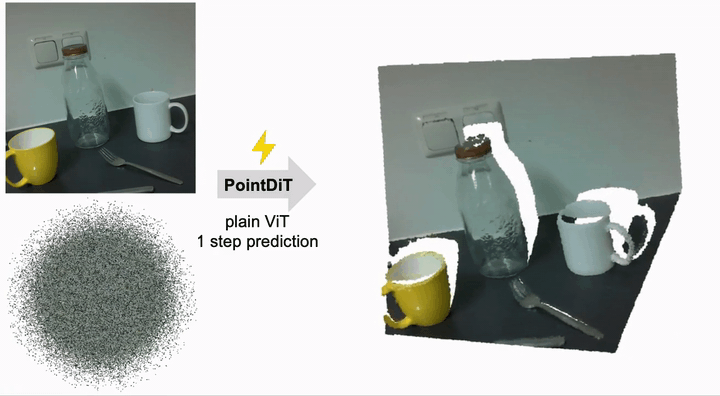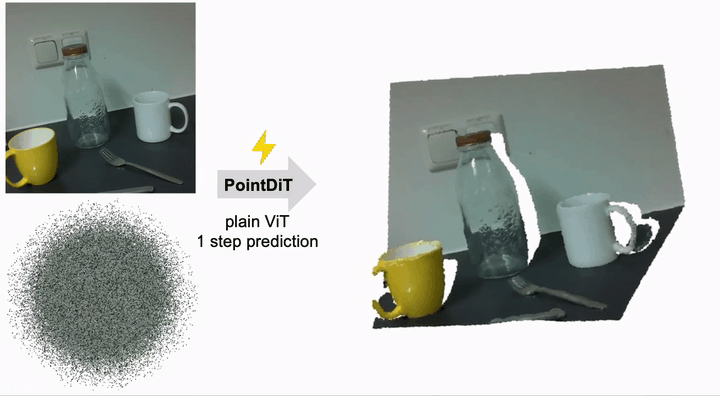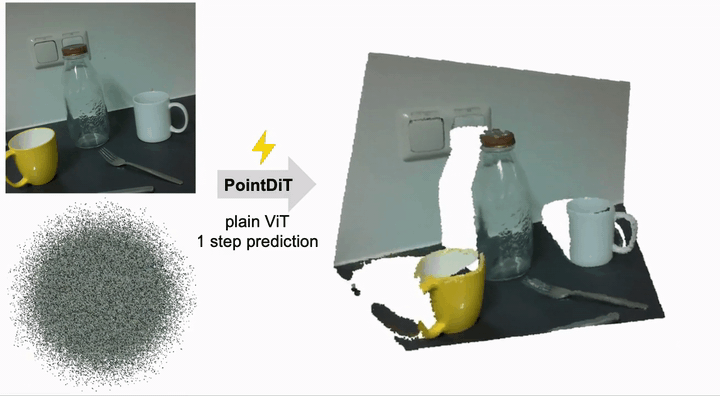
pointdit
233google-research/pointdit · PythonPointDiT is a research codebase for a minimalist pixel-space Diffusion Transformer that estimates 3D geometry (point maps) from a single monocular image.
- 76
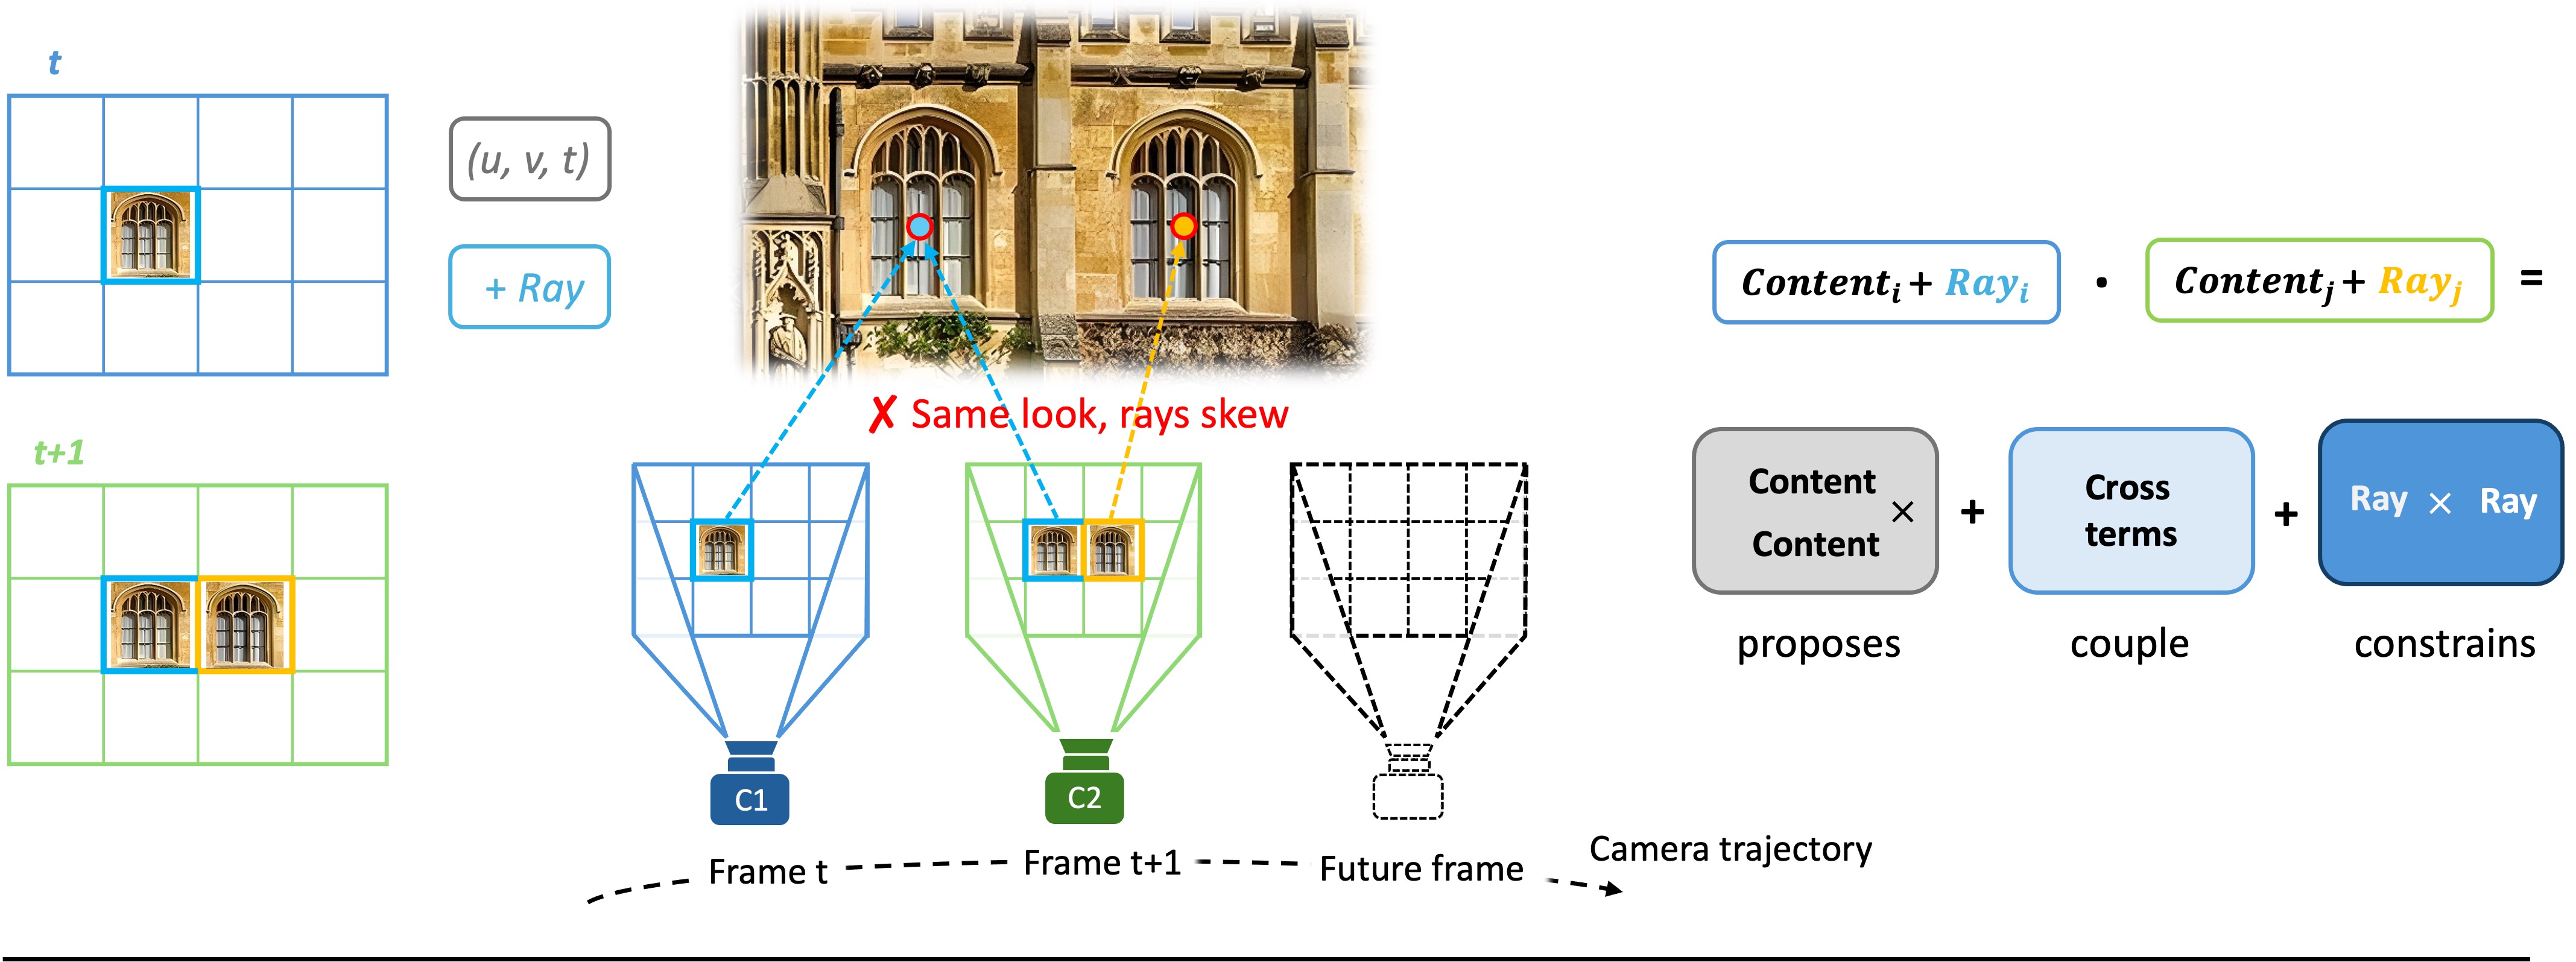
SCoPE
214TencentARC/SCoPE · PythonSCoPE is a research release that adds camera control to a pretrained video diffusion transformer (Wan2.2-I2V-A14B): given a first frame, a text prompt and a camera trajectory, it generates a video that follows the requested camera motion.
- 77
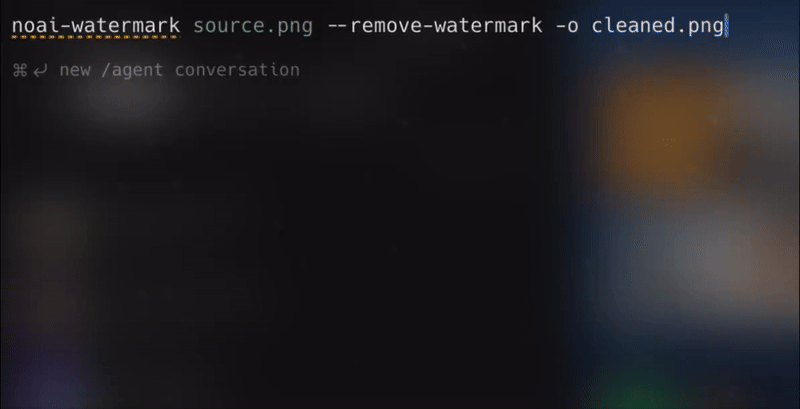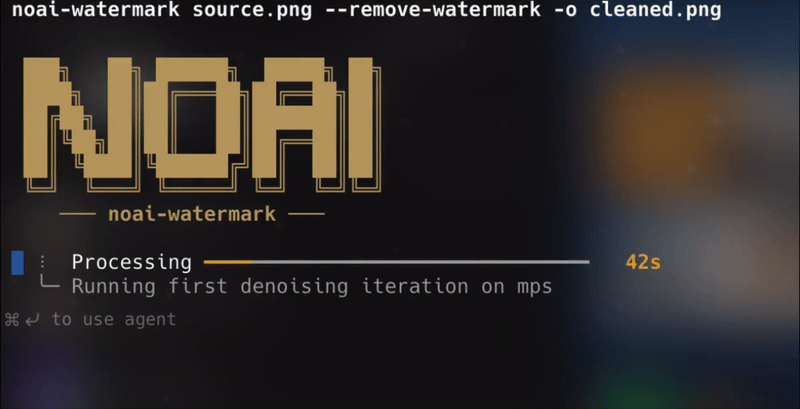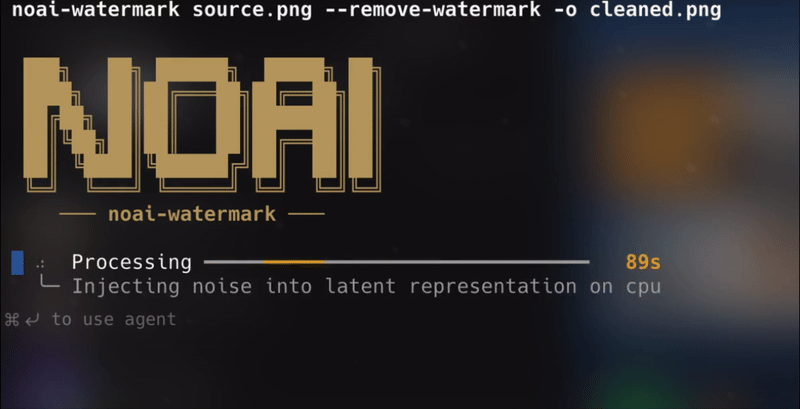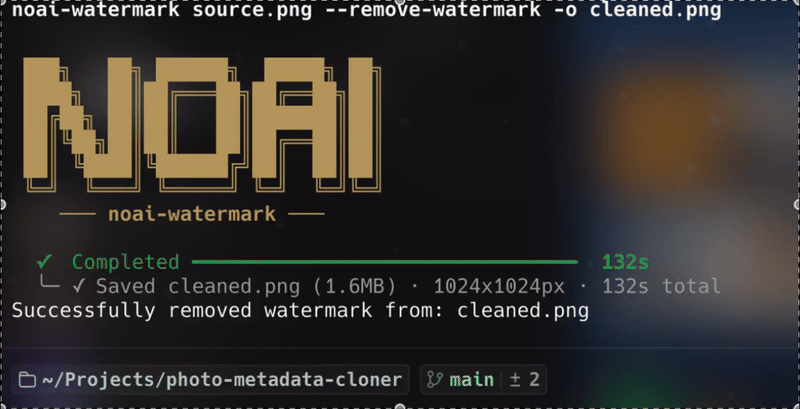
noai-watermark
209mertizci/noai-watermark · Pythonnoai-watermark is an open-source CLI and Python toolkit that uses diffusion-based image regeneration to disrupt invisible AI watermarks (like Google SynthID, StableSignature, TreeRing) embedded in generated images, and it also inspects/strips AI metadata (EXIF, PNG text chunks, C2PA manifests).
- 78
ComfyUI_MinimaxH3HybridLoader
180scottmudge/ComfyUI_MinimaxH3HybridLoader · PythonA custom ComfyUI node that loads a MiniMax H3 (audio+video DiT) checkpoint by merging selected tensor groups from a second 'overlay' checkpoint onto a 'base' checkpoint, producing a hybrid that ComfyUI treats exactly like a normal loaded model.
- 79
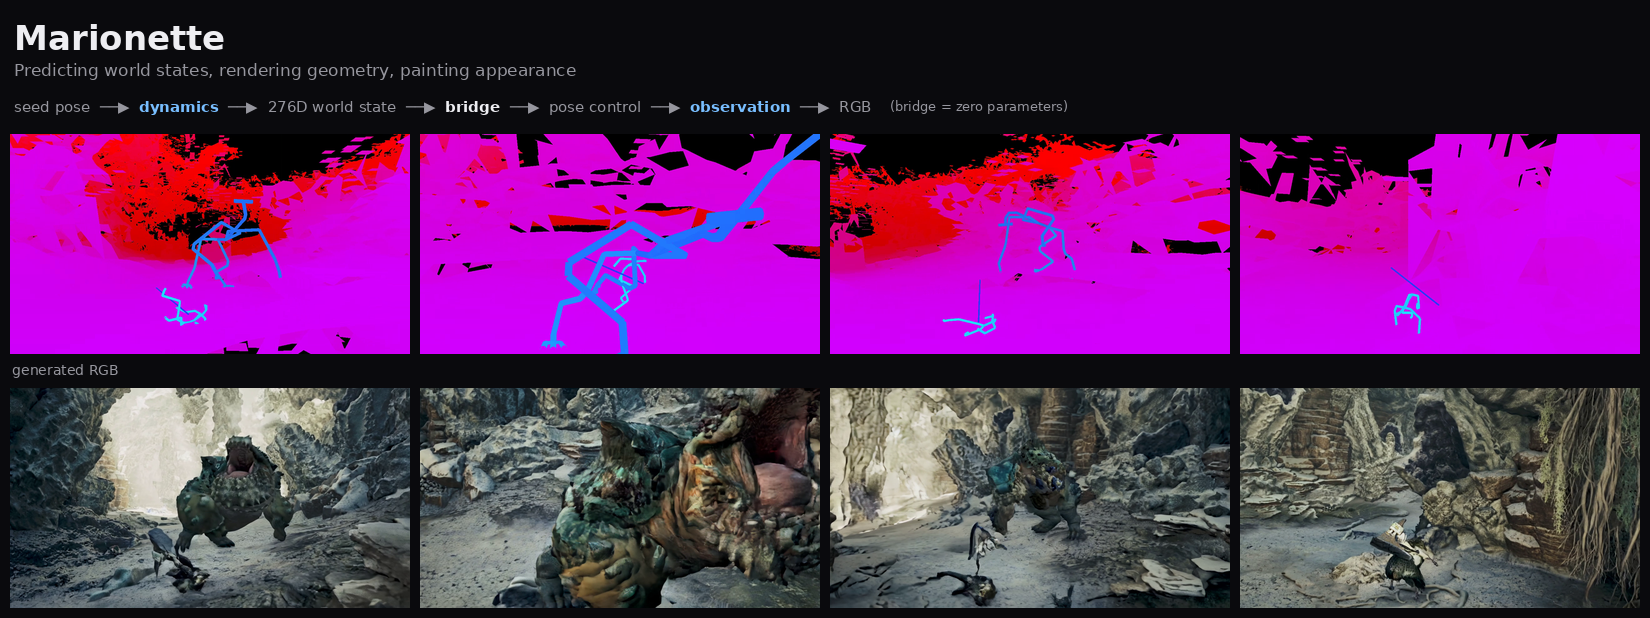
Marionette
147AlayaLab/Marionette · PythonA research world model for interactive 3D worlds. Instead of predicting pixels, it predicts an explicit 276D articulated state, turns that state into geometry with a parameter-free bridge, and lets a video diffusion model paint appearance on top.
- 80

hyperflow
146Video-Rebirth/hyperflow · PythonAn 8-step LoRA adapter for MiniMax-H3, a video+audio generation model, trained by data-free flow self-distillation. This repository holds the loader and example scripts that run it on the diffusers Modular Pipeline.
Related topics
Often tagged together
- python2,383
- gpu789
- deep-learning737
- generative-ai339
- ai1,955
- pytorch419
- machine-learning916
- huggingface362
- linux4,184
- cuda396
- video-generation191
- research764
- open-source5,666
- windows3,403
- image-generation225
- inference327
- computer-vision384
- macos3,544
- apache-2.01,434
- nvidia328
- transformer212
- stable-diffusion54
- text-to-image72
- text-to-video62