What is this?
 Iris is a pair of open-weight search agent models (Iris-mini, 35B-A3B, and Iris-pro, 397B-A17B) post-trained from the Qwen3.5/3.6 series to decide what to search, how to read results, when to keep searching, and when enough evidence has been gathered.
Is this a trained model or a framework?Both: Iris is a pair of released model checkpoints, and the repo also ships Iris-Harness, the agent loop, tools, and context-management code used to run and evaluate them.
Both: Iris is a pair of released model checkpoints, and the repo also ships Iris-Harness, the agent loop, tools, and context-management code used to run and evaluate them.How do I get it running?Download the Iris-mini or Iris-pro weights from Hugging Face, then run them through Iris-Harness, which works against any OpenAI-compatible endpoint.
Download the Iris-mini or Iris-pro weights from Hugging Face, then run them through Iris-Harness, which works against any OpenAI-compatible endpoint.Do I need a specific base model to use Iris?Iris is post-trained on top of Qwen3.6-35B-A3B (for Iris-mini) and Qwen3.5-397B-A17B (for Iris-pro), so it inherits those base architectures.
Iris is post-trained on top of Qwen3.6-35B-A3B (for Iris-mini) and Qwen3.5-397B-A17B (for Iris-pro), so it inherits those base architectures.Can I reproduce how Iris was trained?Not yet - only the model weights and evaluation harness are out; the data construction and training pipelines are still unreleased.
Not yet - only the model weights and evaluation harness are out; the data construction and training pipelines are still unreleased.What is the 'discard-all' context management setting?It clears the accumulated tool-call history and restarts the agent from the original question once the running context crosses a set threshold, used as Iris's headline reported setting.
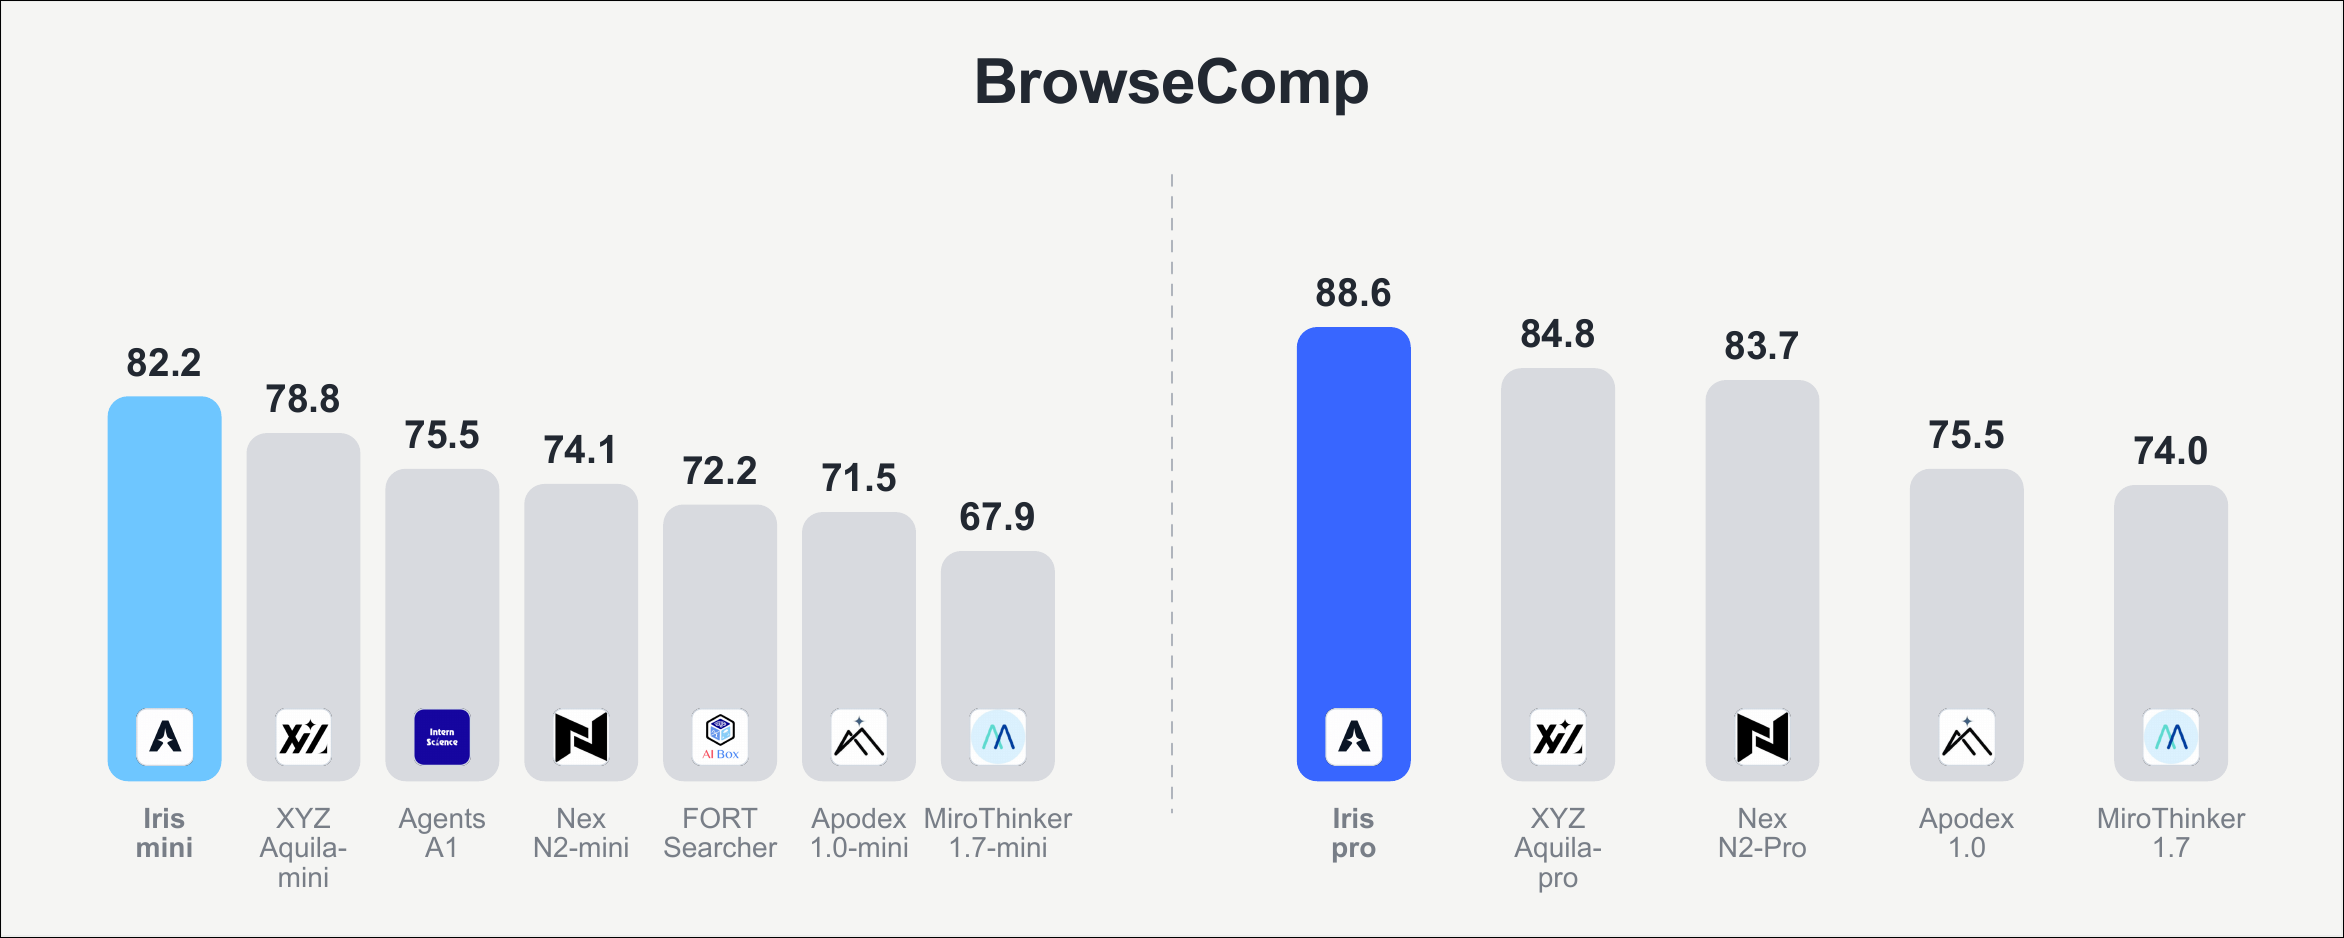
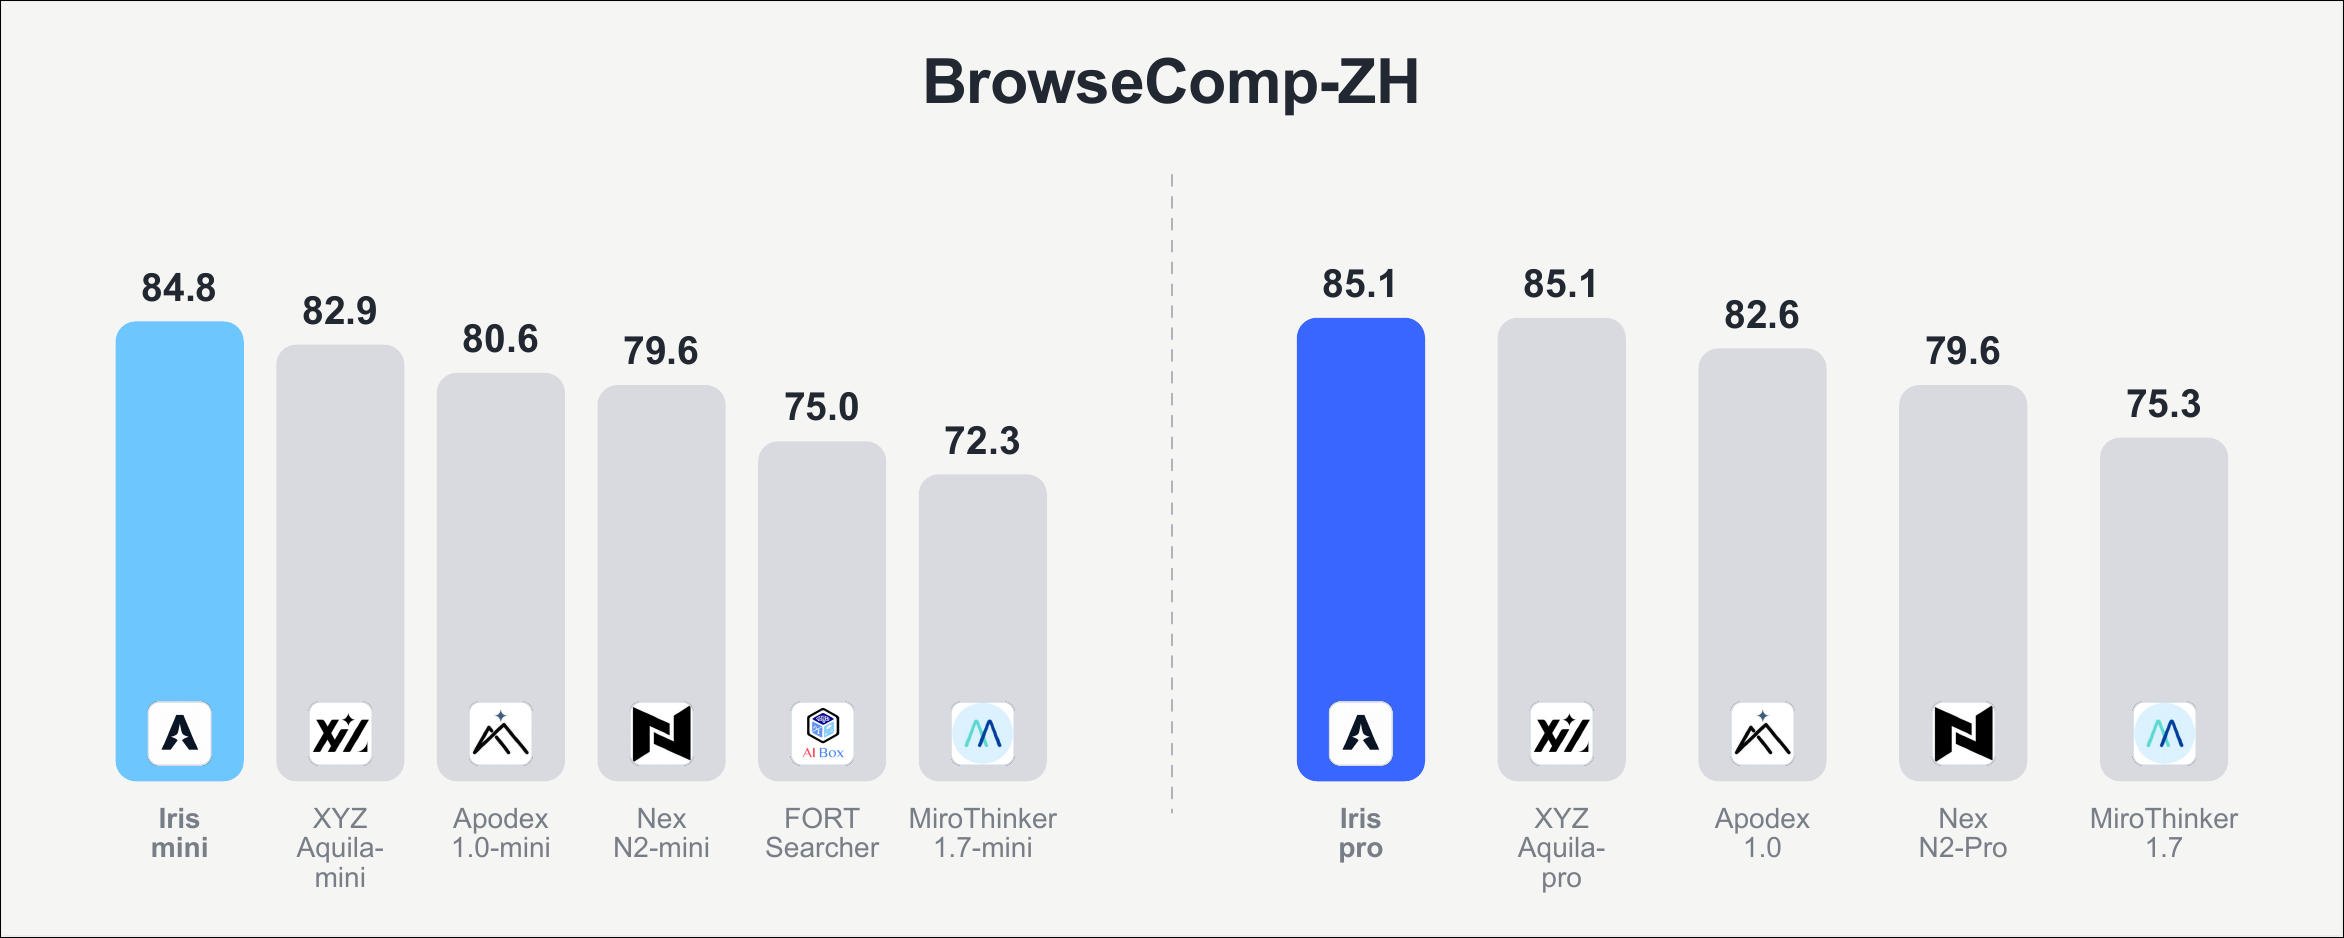
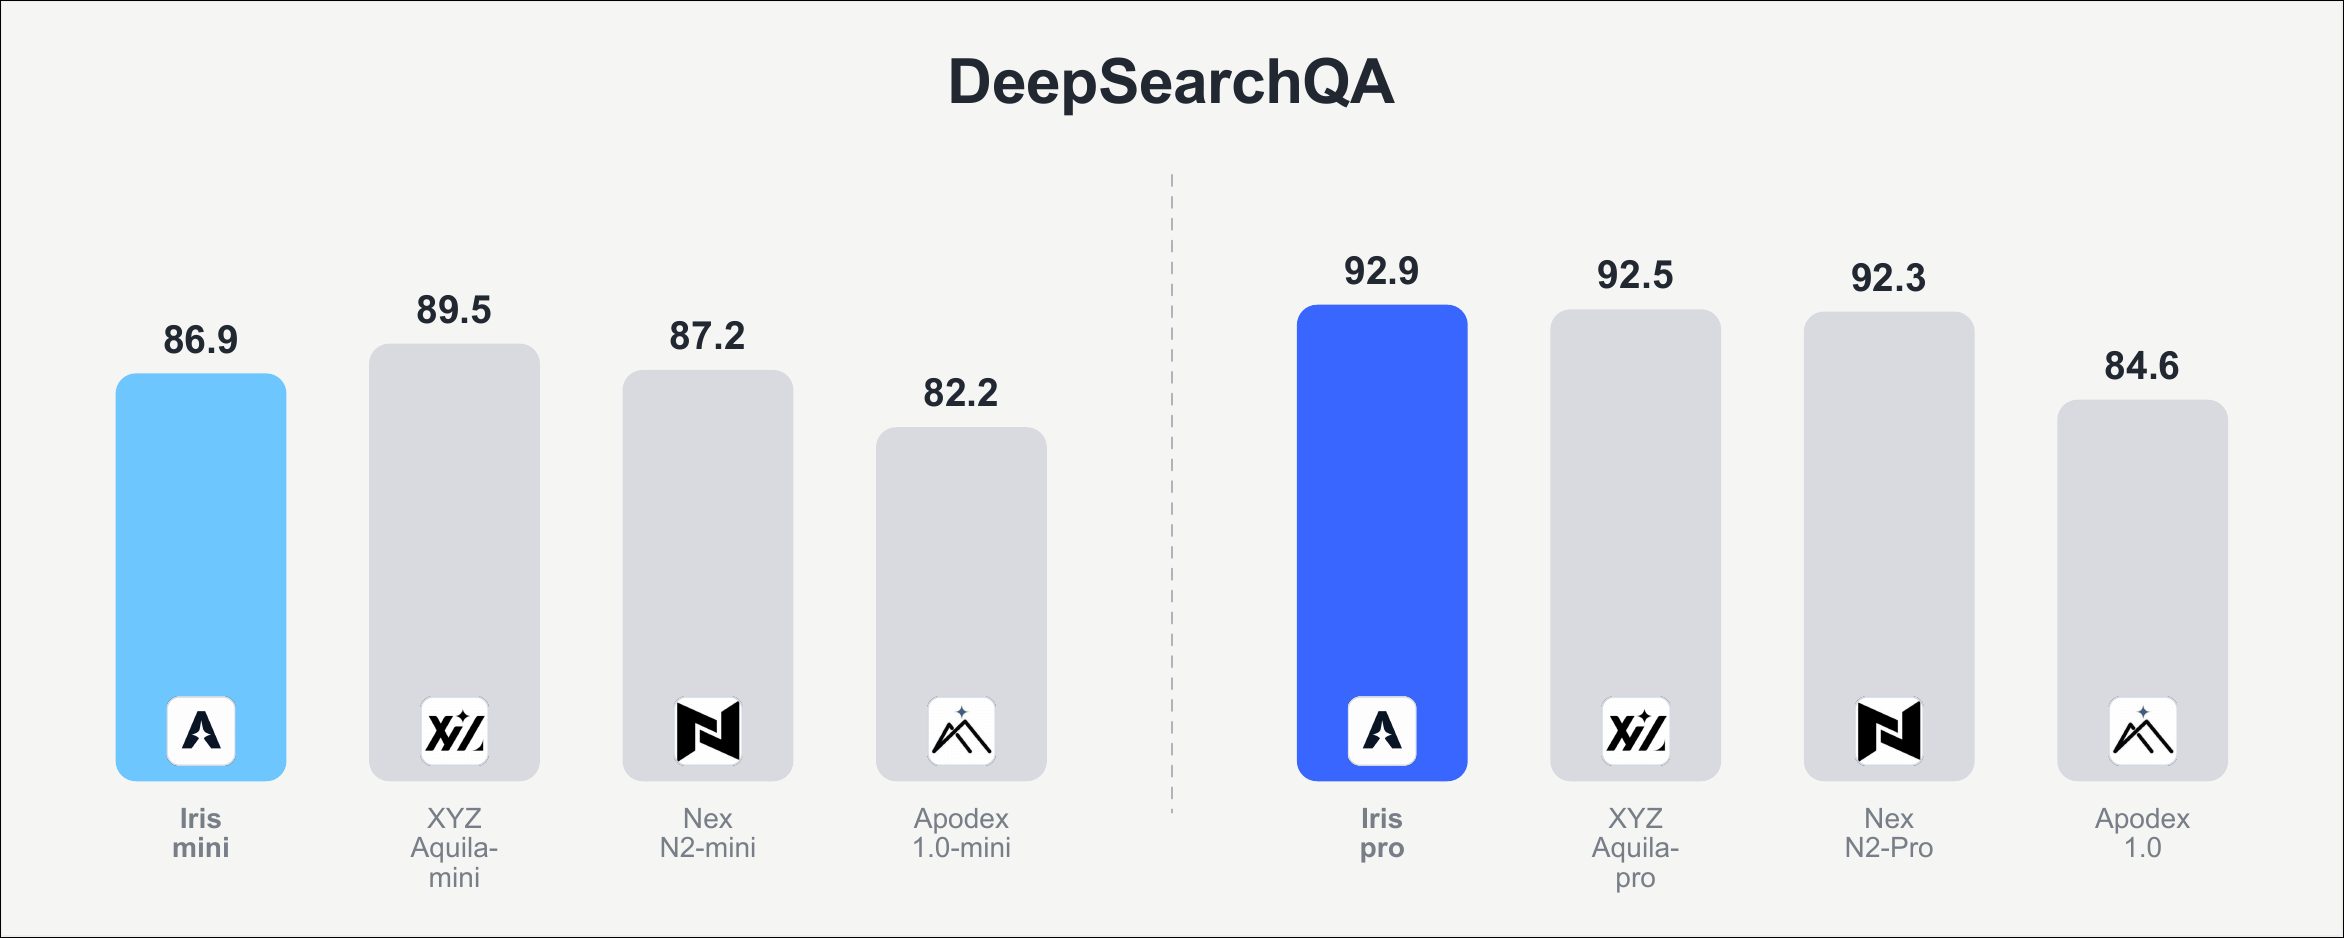
It clears the accumulated tool-call history and restarts the agent from the original question once the running context crosses a set threshold, used as Iris's headline reported setting.What benchmarks is Iris evaluated on?BrowseComp, BrowseComp-ZH, DeepSearchQA, and HLE (Humanity's Last Exam, text-only subset), with DeepSearchQA scored by F1 and the rest by accuracy.
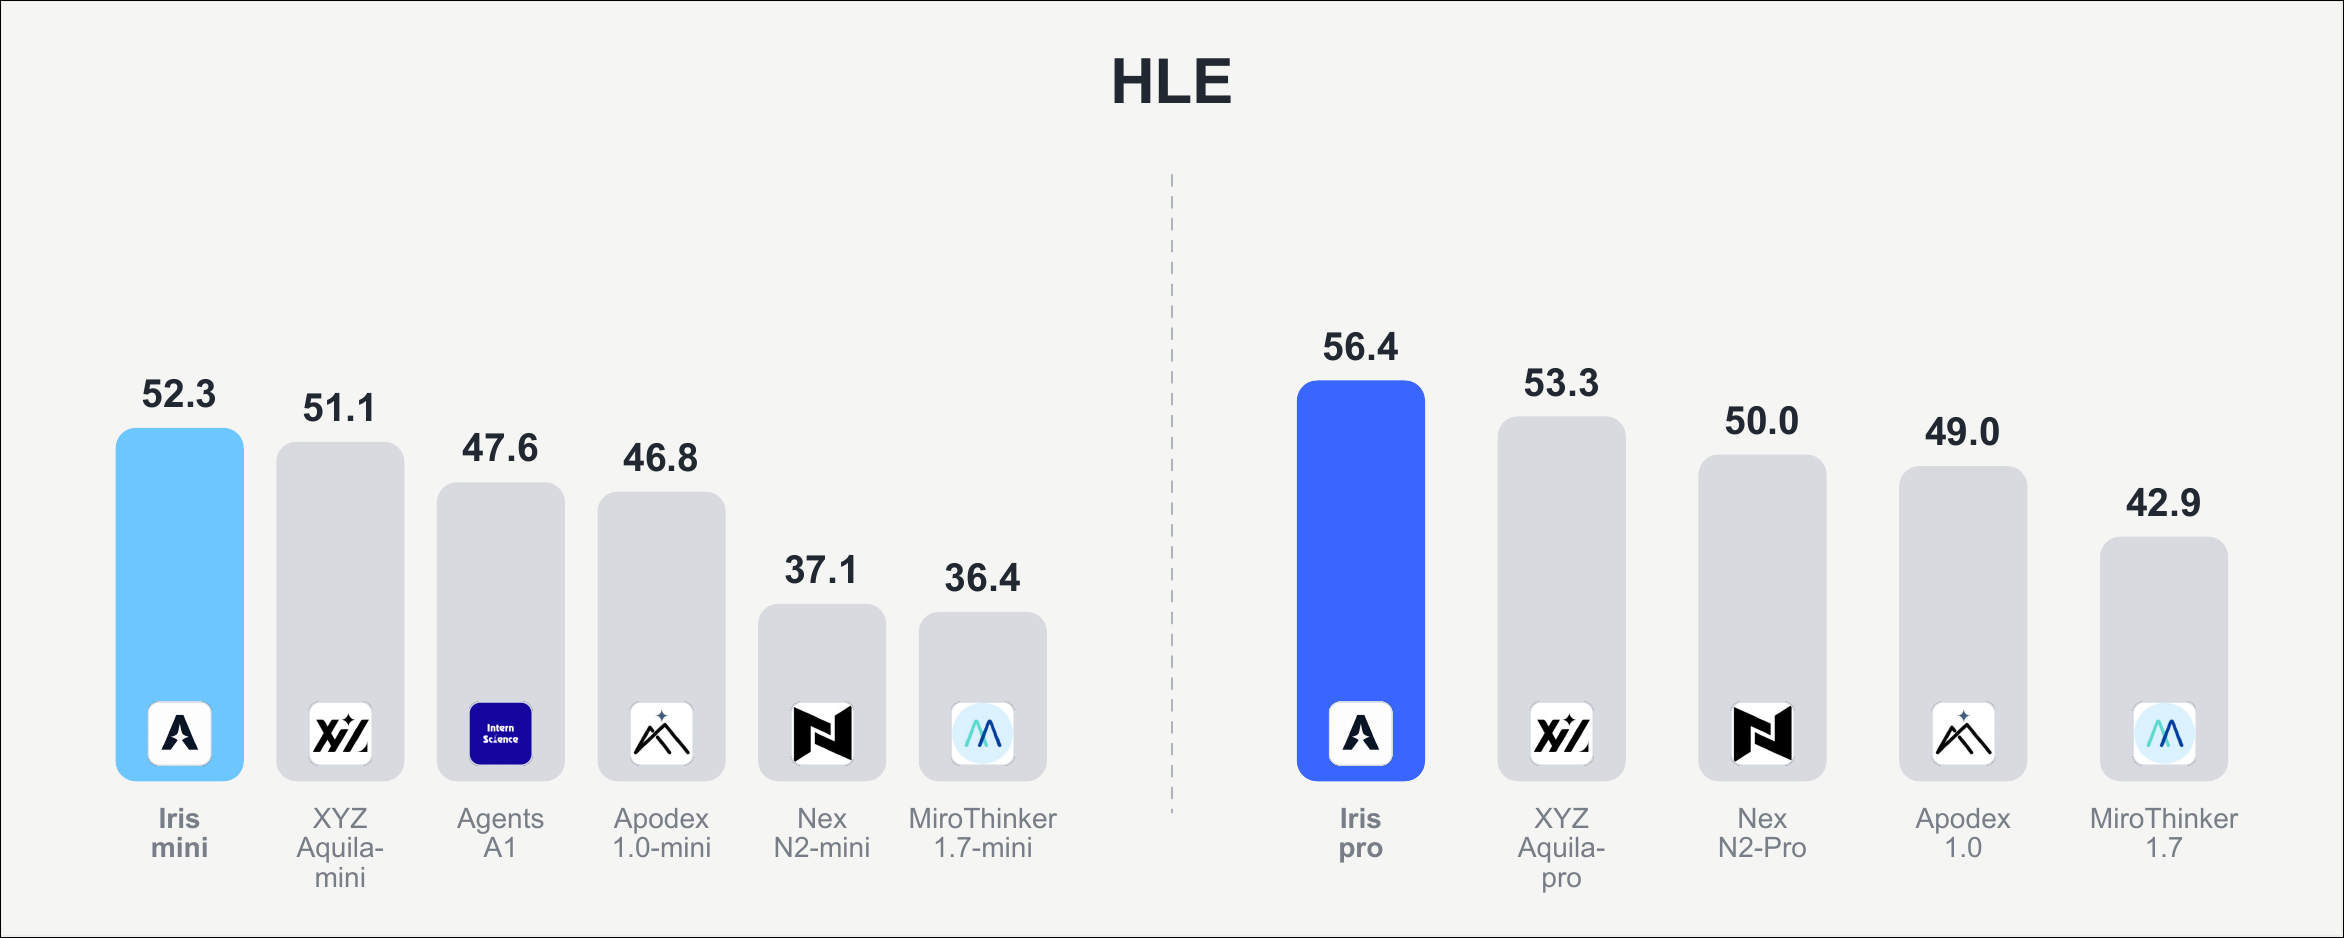
BrowseComp, BrowseComp-ZH, DeepSearchQA, and HLE (Humanity's Last Exam, text-only subset), with DeepSearchQA scored by F1 and the rest by accuracy.What's the difference between Iris-mini and Iris-pro?Iris-mini is a 35B parameter model with 3B active (built on Qwen3.6), while Iris-pro is a much larger 397B model with 17B active (built on Qwen3.5); both support a 256K context window and Iris-pro scores higher across every benchmark.
Iris-mini is a 35B parameter model with 3B active (built on Qwen3.6), while Iris-pro is a much larger 397B model with 17B active (built on Qwen3.5); both support a 256K context window and Iris-pro scores higher across every benchmark.What open-source projects does Iris build on?The authors credit MiroThinker, Relax, ms-swift, and slime as the open-source foundations Iris was built on.
The authors credit MiroThinker, Relax, ms-swift, and slime as the open-source foundations Iris was built on.What are similar projects?RSIGame, RSI-Anything, Kimi-K3, MSA, NeoHorse, jeeves, DeepAnalyze, ZDTaichu5.0-9B
RSIGame, RSI-Anything, Kimi-K3, MSA, NeoHorse, jeeves, DeepAnalyze, ZDTaichu5.0-9BWhich topics is it in?context-window, deep-research, mixture-of-experts, reasoning, llm-agents, autonomous-agents, search, qwen, evaluation, academic-research, large-language-models, agentic-ai
context-window, deep-research, mixture-of-experts, reasoning, llm-agents, autonomous-agents, search, qwen, evaluation, academic-research, large-language-models, agentic-ai