
trnrt README

The project's README from github.com/RunanywhereAI/trnrt. As one markdown file: README.md.

TrnRT: the open LLM inference engine for AWS Trainium, by RunAnywhere

CI OpenSSF Scorecard License: Apache 2.0 Python 3.13 AWS Trainium2 Neuron SDK 2.32

Quickstart · Benchmarks · Docs · Kernels · Blog post · runanywhere.ai

TrnRT is an open inference engine for large language models on AWS Trainium. It serves an OpenAI-compatible API from one trn2.48xlarge, runs decode as NKI megakernels (about one kernel per layer half), and keeps a prefix cache across device and host memory. GLM-5.3-Flash is the first supported model; more open models are on the way.

How we built it, with the AgentX results: Serving GLM-5.3-Flash on one Trainium2 box with NKI layer megakernels.

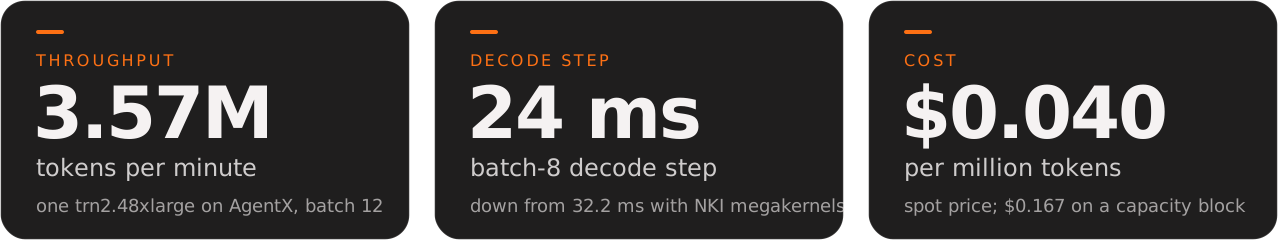
3.57M tokens per minute on one trn2.48xlarge (AgentX, batch 12). 24 ms batch-8 decode step, down from 32.2 ms with NKI megakernels. $0.040 per million tokens at the spot price, $0.167 on a capacity block.

Highlights

Feature What it does
NKI megakernels One fused kernel per layer half for decode: KDA attention, the fused DSA layer, mHC and the MoE FFN.
1M-token context Sparse attention (top 2,048) and linear attention, with fixed-size state.
Prefix cache A radix tree over FP8 KV pages, plus a host-memory tier for evicted pages and state checkpoints.
Two engines per box Each engine is tensor-parallel over 32 logical NeuronCores, behind a session-affine router.
OpenAI API Chat and completions, streaming, tool calls and reasoning output.
Offline compile Every graph is built on a CPU host; the serving box loads them and compiles nothing by default.

Quickstart

You need Docker, a trn2.48xlarge to serve on, and any x86_64 host to compile on. New to Trainium? Start with docs/AWS.md.

1. Build the image (Neuron SDK 2.32 (neuronx-cc 2.27), Python 3.13)

git clone https://github.com/RunanywhereAI/trnrt.git && cd trnrt
docker build -f docker/Dockerfile \
  --build-arg TRNRT_VERSION=$(python3 -c 'import trnrt; print(trnrt.__version__)') \
  --build-arg TRNRT_REVISION=$(git rev-parse HEAD) -t trnrt .

2. Build the compile cache (any x86_64 host, no NeuronCore needed; takes hours)

OUT=/data/trnrt REV=eb9eb208eb0d988989d07a6a12d0fdeb5f52574a
mkdir -p $OUT/nki $OUT/work
trnrt() { docker run --rm -e HF_TOKEN -v $OUT:$OUT \
  -v $OUT/nki:/var/tmp/nki-intermediate-cache trnrt "$@"; }
trnrt compile shapes zai-org/GLM-5.3-Flash --revision $REV --out $OUT
trnrt compile decisions --model zai-org/GLM-5.3-Flash --revision $REV --out $OUT
trnrt compile capture --out $OUT -- --model $OUT/shapes
trnrt compile compile --out $OUT --work-root $OUT/work
trnrt compile strip --out $OUT

3. Serve (on the trn2.48xlarge, with $OUT/cache and $OUT/nki copied over)

hf download zai-org/GLM-5.3-Flash --revision eb9eb208eb0d988989d07a6a12d0fdeb5f52574a \
  --local-dir /models/GLM-5.3-Flash
docker run --rm --privileged --network host --ipc=host \
  -v /data/trnrt/cache:/cache \
  -v /data/trnrt/nki:/var/tmp/nki-intermediate-cache \
  -v /models/GLM-5.3-Flash:/model \
  -e NEURON_LIBTORCH_CACHE_ROOT=/cache \
  trnrt serve --model /model --port 8000

4. Call it with any OpenAI client

from openai import OpenAI

client = OpenAI(base_url="http://localhost:8000/v1", api_key="unused")
reply = client.chat.completions.create(
    model="glm",
    messages=[{"role": "user", "content": "Write a haiku about Trainium."}],
    extra_body={"session_id": "my-session"},  # keeps a conversation on one engine's prefix cache
)
print(reply.choices[0].message.content)

The full guide covers what each step needs, start-up checks, the batch 4, 8 and 12 configurations and every flag: deploy · API · configuration.

Supported hardware and models

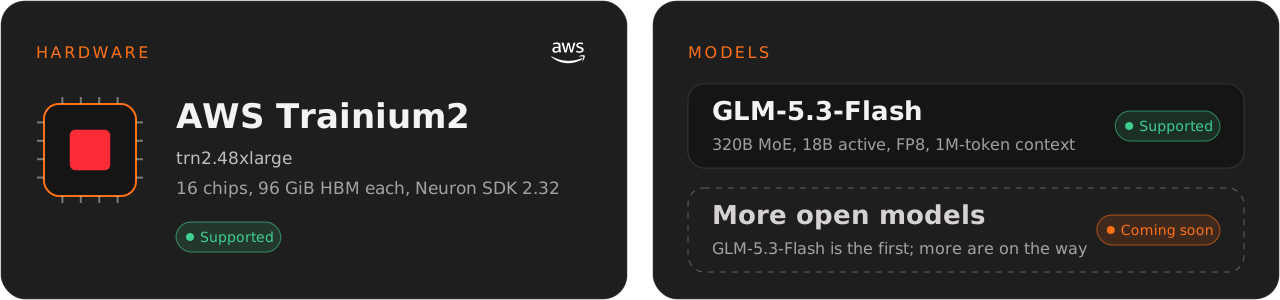
Hardware: AWS Trainium2 (trn2.48xlarge, 16 chips, 96 GiB HBM each, Neuron SDK 2.32), supported. Models: GLM-5.3-Flash (320B MoE, 18B active, FP8, 1M-token context), supported. More open models: coming soon.

Target Status
AWS Trainium2, trn2.48xlarge (16 chips, 2 engines × TP 32, LNC 2) ✅ Supported
GLM-5.3-Flash (320B MoE, 18B active, FP8, 1M-token context) ✅ Supported
More open models 🔜 Coming soon. Request a model

GLM-5.3-Flash is where TrnRT starts. The engine, router, caches and compile pipeline are built to carry more model families, and docs/ARCHITECTURE.md describes what a new one needs.

Benchmarks

SemiAnalysis AgentX replays real coding-agent sessions. One trn2.48xlarge ran it at a 1M-token context with 32 concurrent agents, for one hour per point:

Decode batch Requests / min Tokens / min Decode tok/s per user (p50) First token, cached (p50) $ / M tokens (spot)
4 19.3 2.36M 46.6 76.73 s $0.061
8 25.2 3.02M 29.4 28.82 s $0.047
12 (default) 28.9 3.57M 22.3 6.53 s $0.040

Tokens count input (cached input included) and output. Spot price: $8.60/h, us-east-2, 3 Nov 2026. On a capacity block at $35.76/h, the batch 12 cost is $0.167 per million tokens. Full tables, cold-prompt latencies, long prompts and methodology are in docs/RESULTS.md.

These numbers were measured with an earlier build of TrnRT. This repository passes these checks against that build (docs/KNOWN_ISSUES.md):

How it works

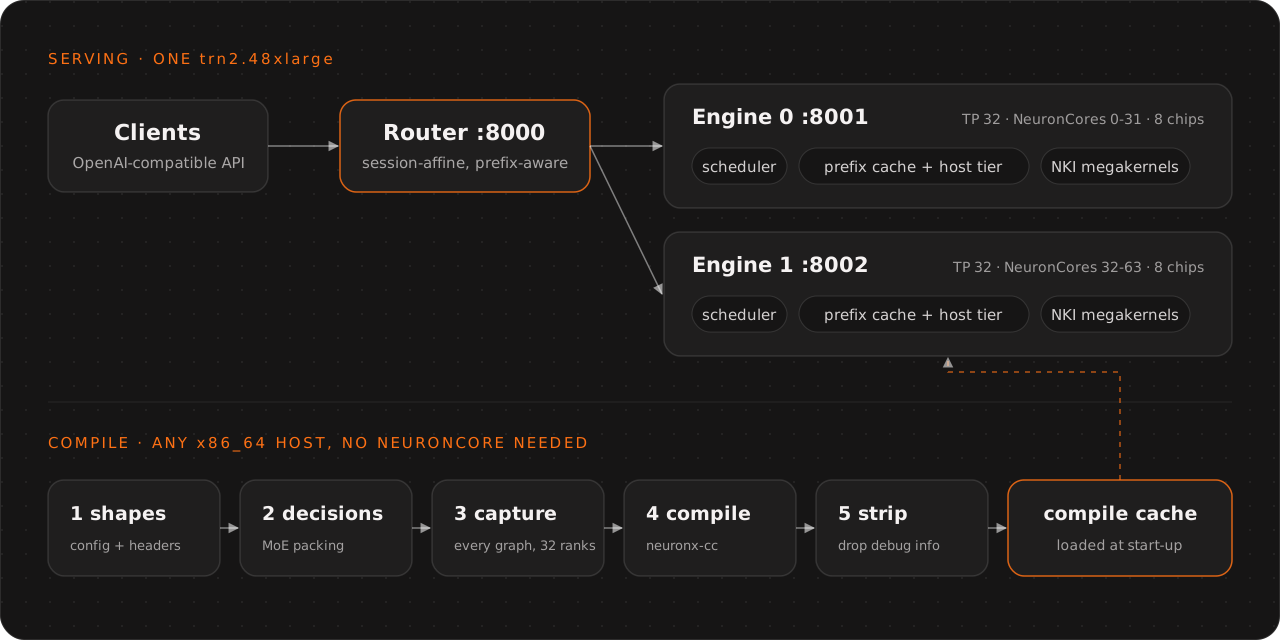
Clients reach a session-affine router on port 8000, which sends each session to one of two engines. Each engine is tensor-parallel over 32 logical NeuronCores on 8 chips. Offline, five steps build the compile cache the engines load.

Decode is not limited by memory bandwidth here; small instructions, kernel boundaries and exposed collectives dominate it. So each decode megakernel follows three rules: keep the working set in SBUF, use both physical cores symmetrically, and move the collectives into the kernel. docs/MEGAKERNELS.md walks through every kernel.

Repository layout

trnrt/
├── __main__.py   CLI: serve, engine, compile
├── serve/        OpenAI API, session-affine router, output parsers
├── engine/       scheduler, prefix caches, tensor parallelism
├── models/       GLM-5.3-Flash: KDA, DSA, mHC, MoE, FP8 loading
├── kernels/      NKI decode megakernels and prefill kernels
└── compile/      offline compile: shapes, capture, neuronx-cc, strip
docker/           the serving and compile image
tools/            graph-equivalence gate, device checks, doc checks
tests/            CPU test suite (no NeuronCore needed)
docs/             guides, results, kernel notes

More in docs/ARCHITECTURE.md.

Development

make dev     # editable install with test and lint tools (Python 3.13)
make check   # lint, type-check, then the CPU test suite

See docs/DEVELOPMENT.md for the test tiers and CI, CONTRIBUTING.md to send a change (pull requests target development), SUPPORT.md to get help, and SECURITY.md to report a vulnerability.

AWS resources

Resource Link
Trainium2 and trn2 instances aws.amazon.com/ec2/instance-types/trn2
AWS Neuron SDK documentation awsdocs-neuron.readthedocs-hosted.com
NKI (Neuron Kernel Interface) NKI documentation
Neuron deep learning containers github.com/aws-neuron/deep-learning-containers
EC2 Capacity Blocks for ML aws.amazon.com/ec2/capacityblocks

Acknowledgments

Thanks to the AWS Neuron team for NKI and its documentation, to Z.ai for releasing GLM-5.3-Flash, and to SemiAnalysis for AgentX and its public traces. TrnRT includes code derived from other Apache-2.0 projects: see NOTICE and THIRD_PARTY_NOTICES.md.

License

Apache License 2.0.


RunAnywhere
Built by RunAnywhere.

AWS, Amazon Web Services, Trainium, Inferentia and Neuron are trademarks of Amazon.com, Inc. or its affiliates. The AWS logo appears here as published in AWS's Architecture Icons. TrnRT is an independent open-source project, not affiliated with or endorsed by Amazon Web Services.

trnrt (RunanywhereAI/trnrt)

Searching Database…

1.6K ·GitHub
What is this?An open inference engine for large language models on AWS Trainium. It serves an OpenAI-compatible API from one trn2.48xlarge box, with GLM-5.3-Flash as the first supported model.
Is it a library I import or a server I run?A server you run. It exposes an OpenAI-compatible API, so any OpenAI client can call it once the engine is up.
How do I get it running?Build the Docker image (Neuron SDK 2.32, Python 3.13). Then build the compile cache on any x86-64 host, which takes hours and needs no NeuronCore. Finally serve on the trn2.48xlarge with the cache copied over.
Do I need special hardware?Yes. Serving requires an AWS trn2.48xlarge with Trainium2 chips, plus Docker. Compilation can run on any x86-64 host.
What are the main limits?Only GLM-5.3-Flash is supported right now. The benchmark numbers come from an earlier build of the engine, and this repo passes its checks against that build.
Can I build a product on top of this?Yes, under Apache License 2.0. Code derived from other Apache-2.0 projects keeps its own notices, listed in NOTICE and THIRDPARTYNOTICES.md.
What makes the decode path different?Each decode step runs as a fused NKI megakernel, one per layer half. The working set stays in on-chip SBUF, and collectives move inside the kernel to cut overhead.
How does it handle a 1M-token context?It combines sparse attention over the top 2,048 tokens with linear attention that has fixed-size state. A radix-tree prefix cache over FP8 KV pages adds a host-memory tier for evicted pages.
Why are the graphs compiled on a separate host?Every graph is built on a CPU host ahead of time. The serving box loads the prebuilt graphs and compiles nothing by default.
Can it run models other than GLM-5.3-Flash?The engine, router, caches and compile pipeline are built to carry more model families. docs/ARCHITECTURE.md describes what a new model needs.
Size
1.9 MB
Stars
1.6K
Age
19d
Commits · 90 Days