Topics / #hip
Hip projects on GitHub
Ambiguous acronym, possibly AMD's HIP GPU compute platform; context is limited.
As of , the most-starred Hip projects on GitHub are DLSS-NR-on-AMD (2.5K stars), halogen-flash-server (1K stars) and CUDA-for-AMD-Windows (321 stars). GitHub.Locker tracks 6 Hip repositories with 4.6K stars combined. The fastest-growing on October 16 was DLSS-NR-on-AMD, with +16 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +16
DLSS-NR-on-AMD
danielblnc/DLSS-NR-on-AMD · ★ 2.5KThis is a mod that lets you run DLSS 5 Neural Rendering on AMD Radeon GPUs (RX 7000/9000 series) in any DirectX 12 game that supports FSR, by reimplementing the DLSS neural network runtime for AMD hardware from scratch.
 +9
halogen-flash-server
peonist-ai/halogen-flash-server · ★ 1Khalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
 +3
d4r
countervolts/d4r · ★ 288d4r runs NVIDIA's official DLSS Super Resolution library inside Windows games on AMD Radeon GPUs under Linux and Proton, translating the DLSS network through ZLUDA (CUDA on ROCm/HIP) and replacing the heaviest kernels with hand-written RDNA3/RDNA4 code. It supports the DLSS 3 CNN model and the DLSS 4/4.5 transformer models; DLSS 5 is not supported.
 +2
Hyperloom
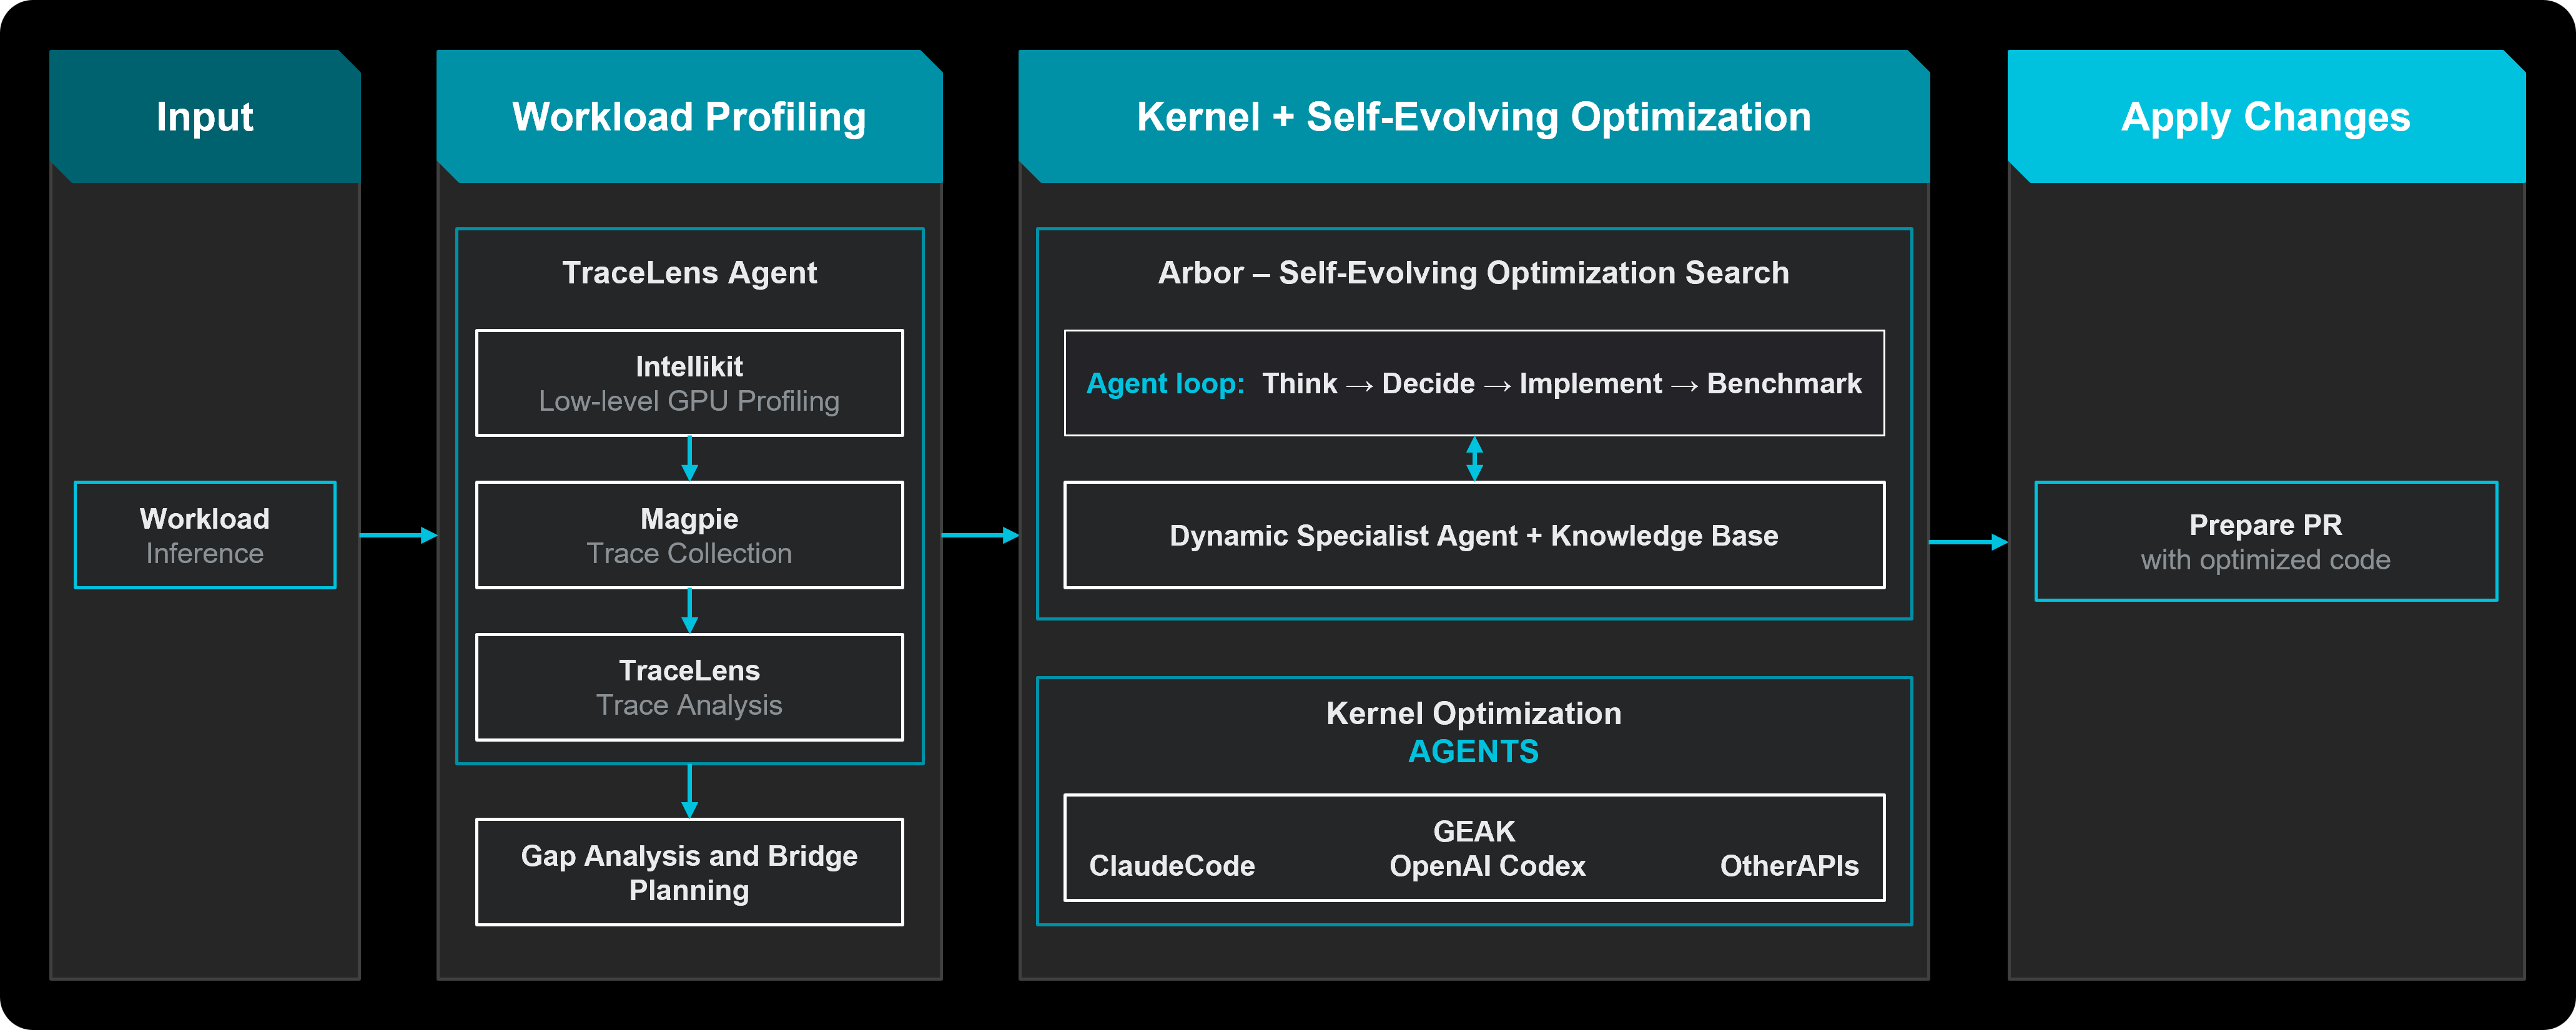
AMD-AGI/Hyperloom · ★ 241A multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
The all-time top
6 projects · by stars
- 2.5K#1 · danielblnc/DLSS-NR-on-AMD
DLSS-NR-on-AMD
This is a mod that lets you run DLSS 5 Neural Rendering on AMD Radeon GPUs (RX 7000/9000 series) in any DirectX 12 game that supports FSR, by reimplementing the DLSS neural network runtime for AMD hardware from scratch.
- 1K#2 · peonist-ai/halogen-flash-server
halogen-flash-server
halogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 321
 #3 · Speedstu/CUDA-for-AMD-Windows
CUDA-for-AMD-Windows
A Windows compatibility stack that runs CUDA-targeted applications on AMD GPUs via ZLUDA plus AMD ROCm/HIP, with tooling to verify the work truly executes on the GPU instead of silently falling back to CPU or producing wrong results.
- 4
d4r
288countervolts/d4r · C++d4r runs NVIDIA's official DLSS Super Resolution library inside Windows games on AMD Radeon GPUs under Linux and Proton, translating the DLSS network through ZLUDA (CUDA on ROCm/HIP) and replacing the heaviest kernels with hand-written RDNA3/RDNA4 code. It supports the DLSS 3 CNN model and the DLSS 4/4.5 transformer models; DLSS 5 is not supported.
- 5
Hyperloom
241AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
- 6

qxotic
175qxoticai/qxotic · JavaQxotic is an open-source AI stack built specifically for the JVM, giving Java applications local AI inference — chat, vision, audio, embeddings, reranking and text-to-speech — without needing Python or ONNX.
Related topics
Often tagged together