LLaDA-Image README

The project's README from github.com/inclusionAI/LLaDA-Image. As one markdown file: README.md.

LLaDA-Image: Building Strong Image Generators with Fully Open Training Recipes

Welcome to the official repository for LLaDA-Image, a unified model for high-quality image generation and editing.

GitHub arXiv
LLaDA-Image Base on Hugging Face LLaDA-Image Base FP8 Version on Hugging Face LLaDA-Image Turbo on Hugging Face LLaDA-Image Turbo FP8 Version on Hugging Face
LLaDA-Image Base on Modelscope LLaDA-Image Base FP8 Version on Modelscope LLaDA-Image Turbo on Modelscope LLaDA-Image Turbo FP8 Version on Modelscope

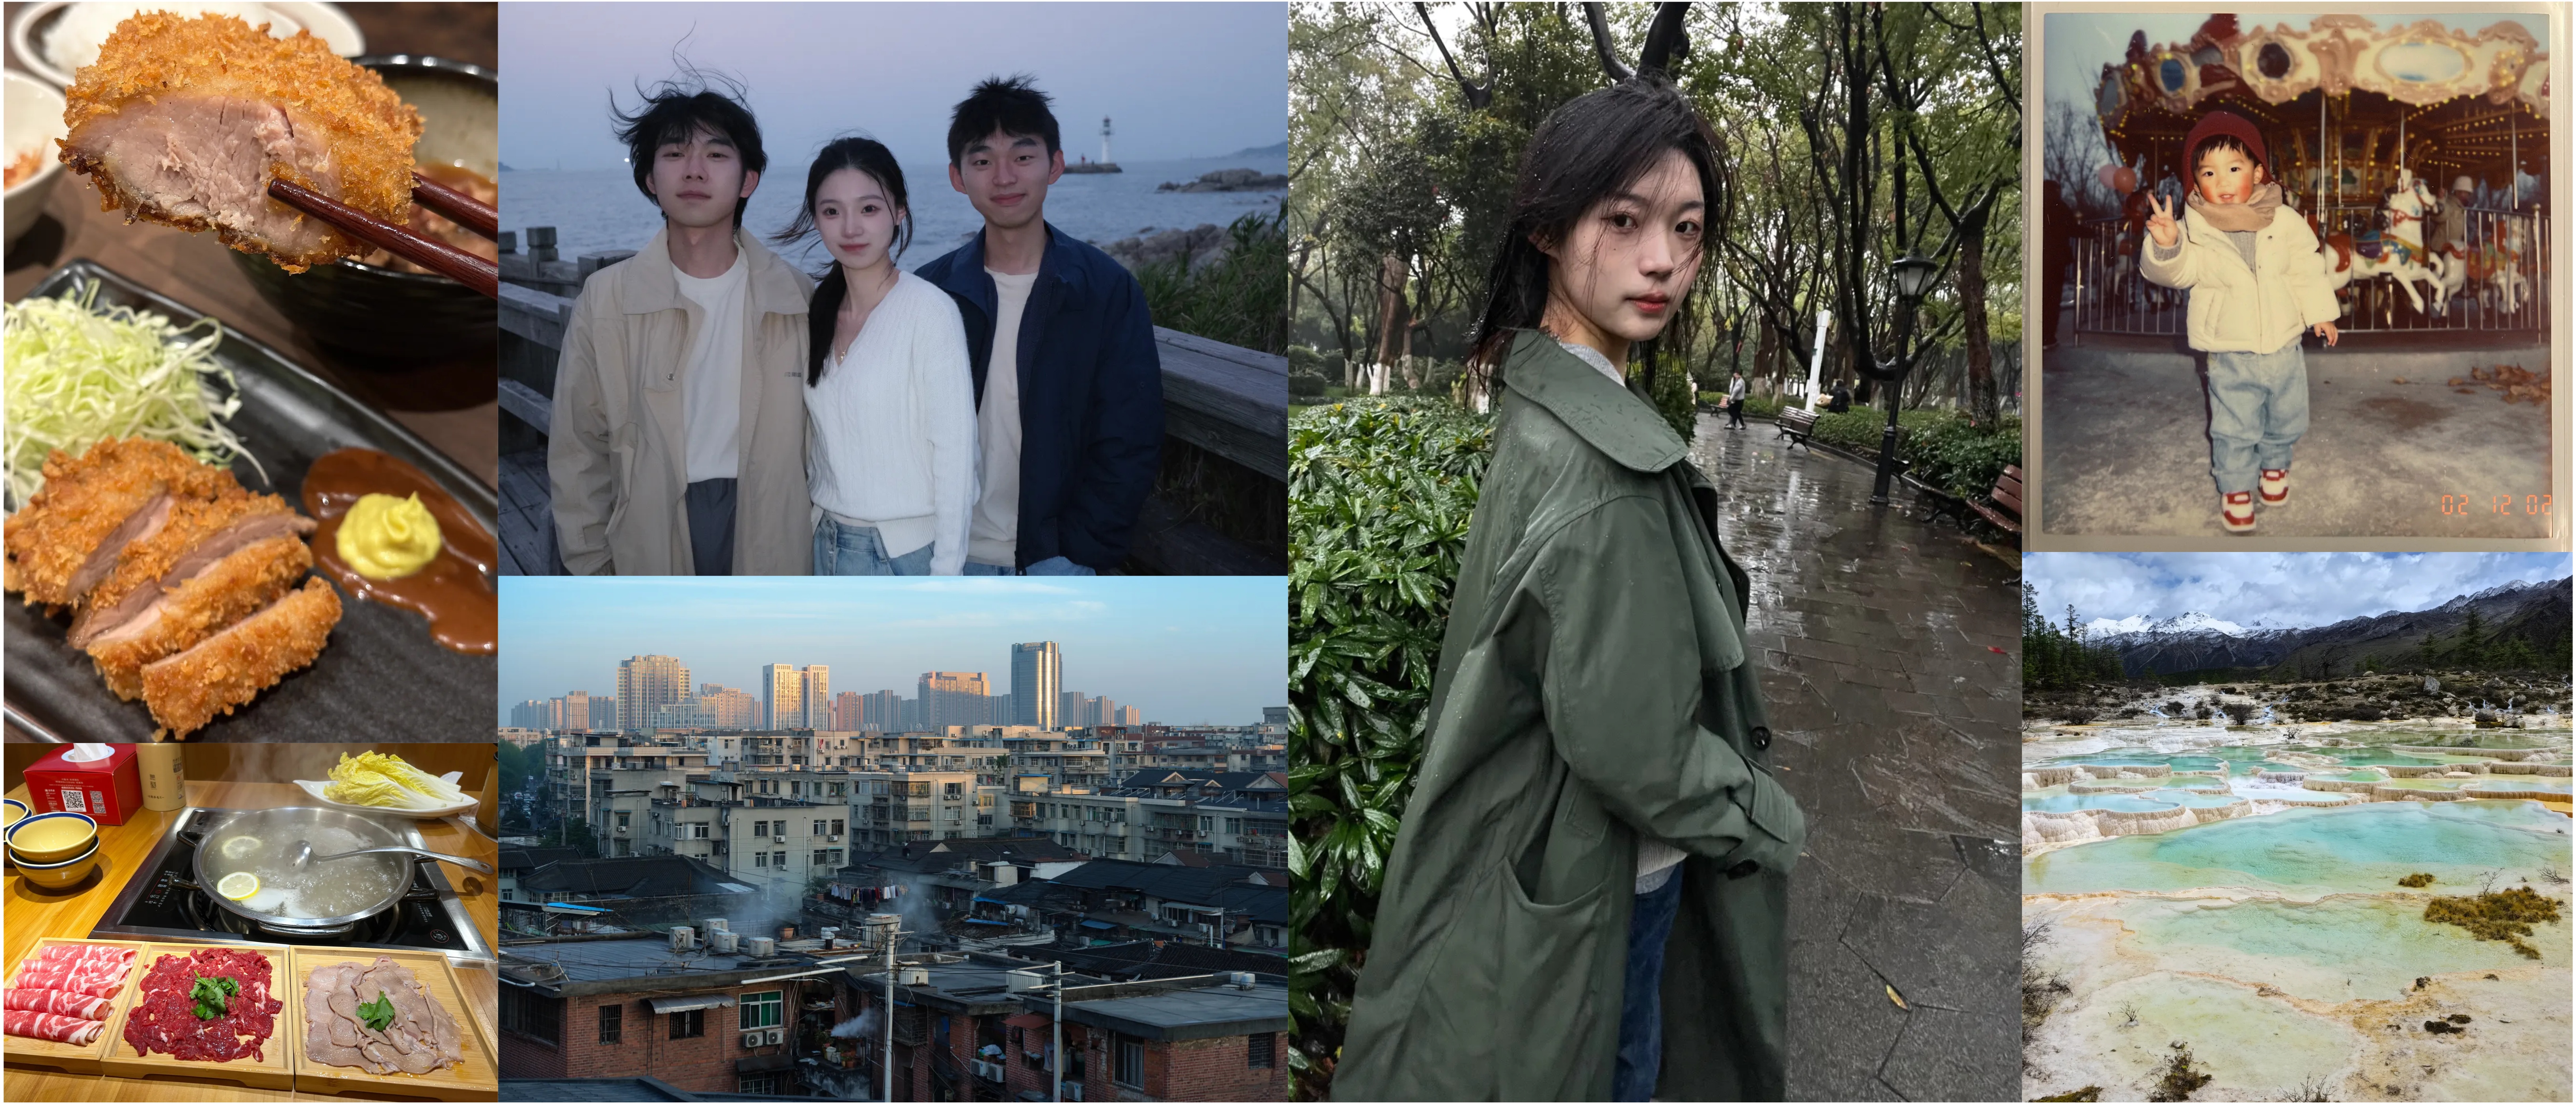
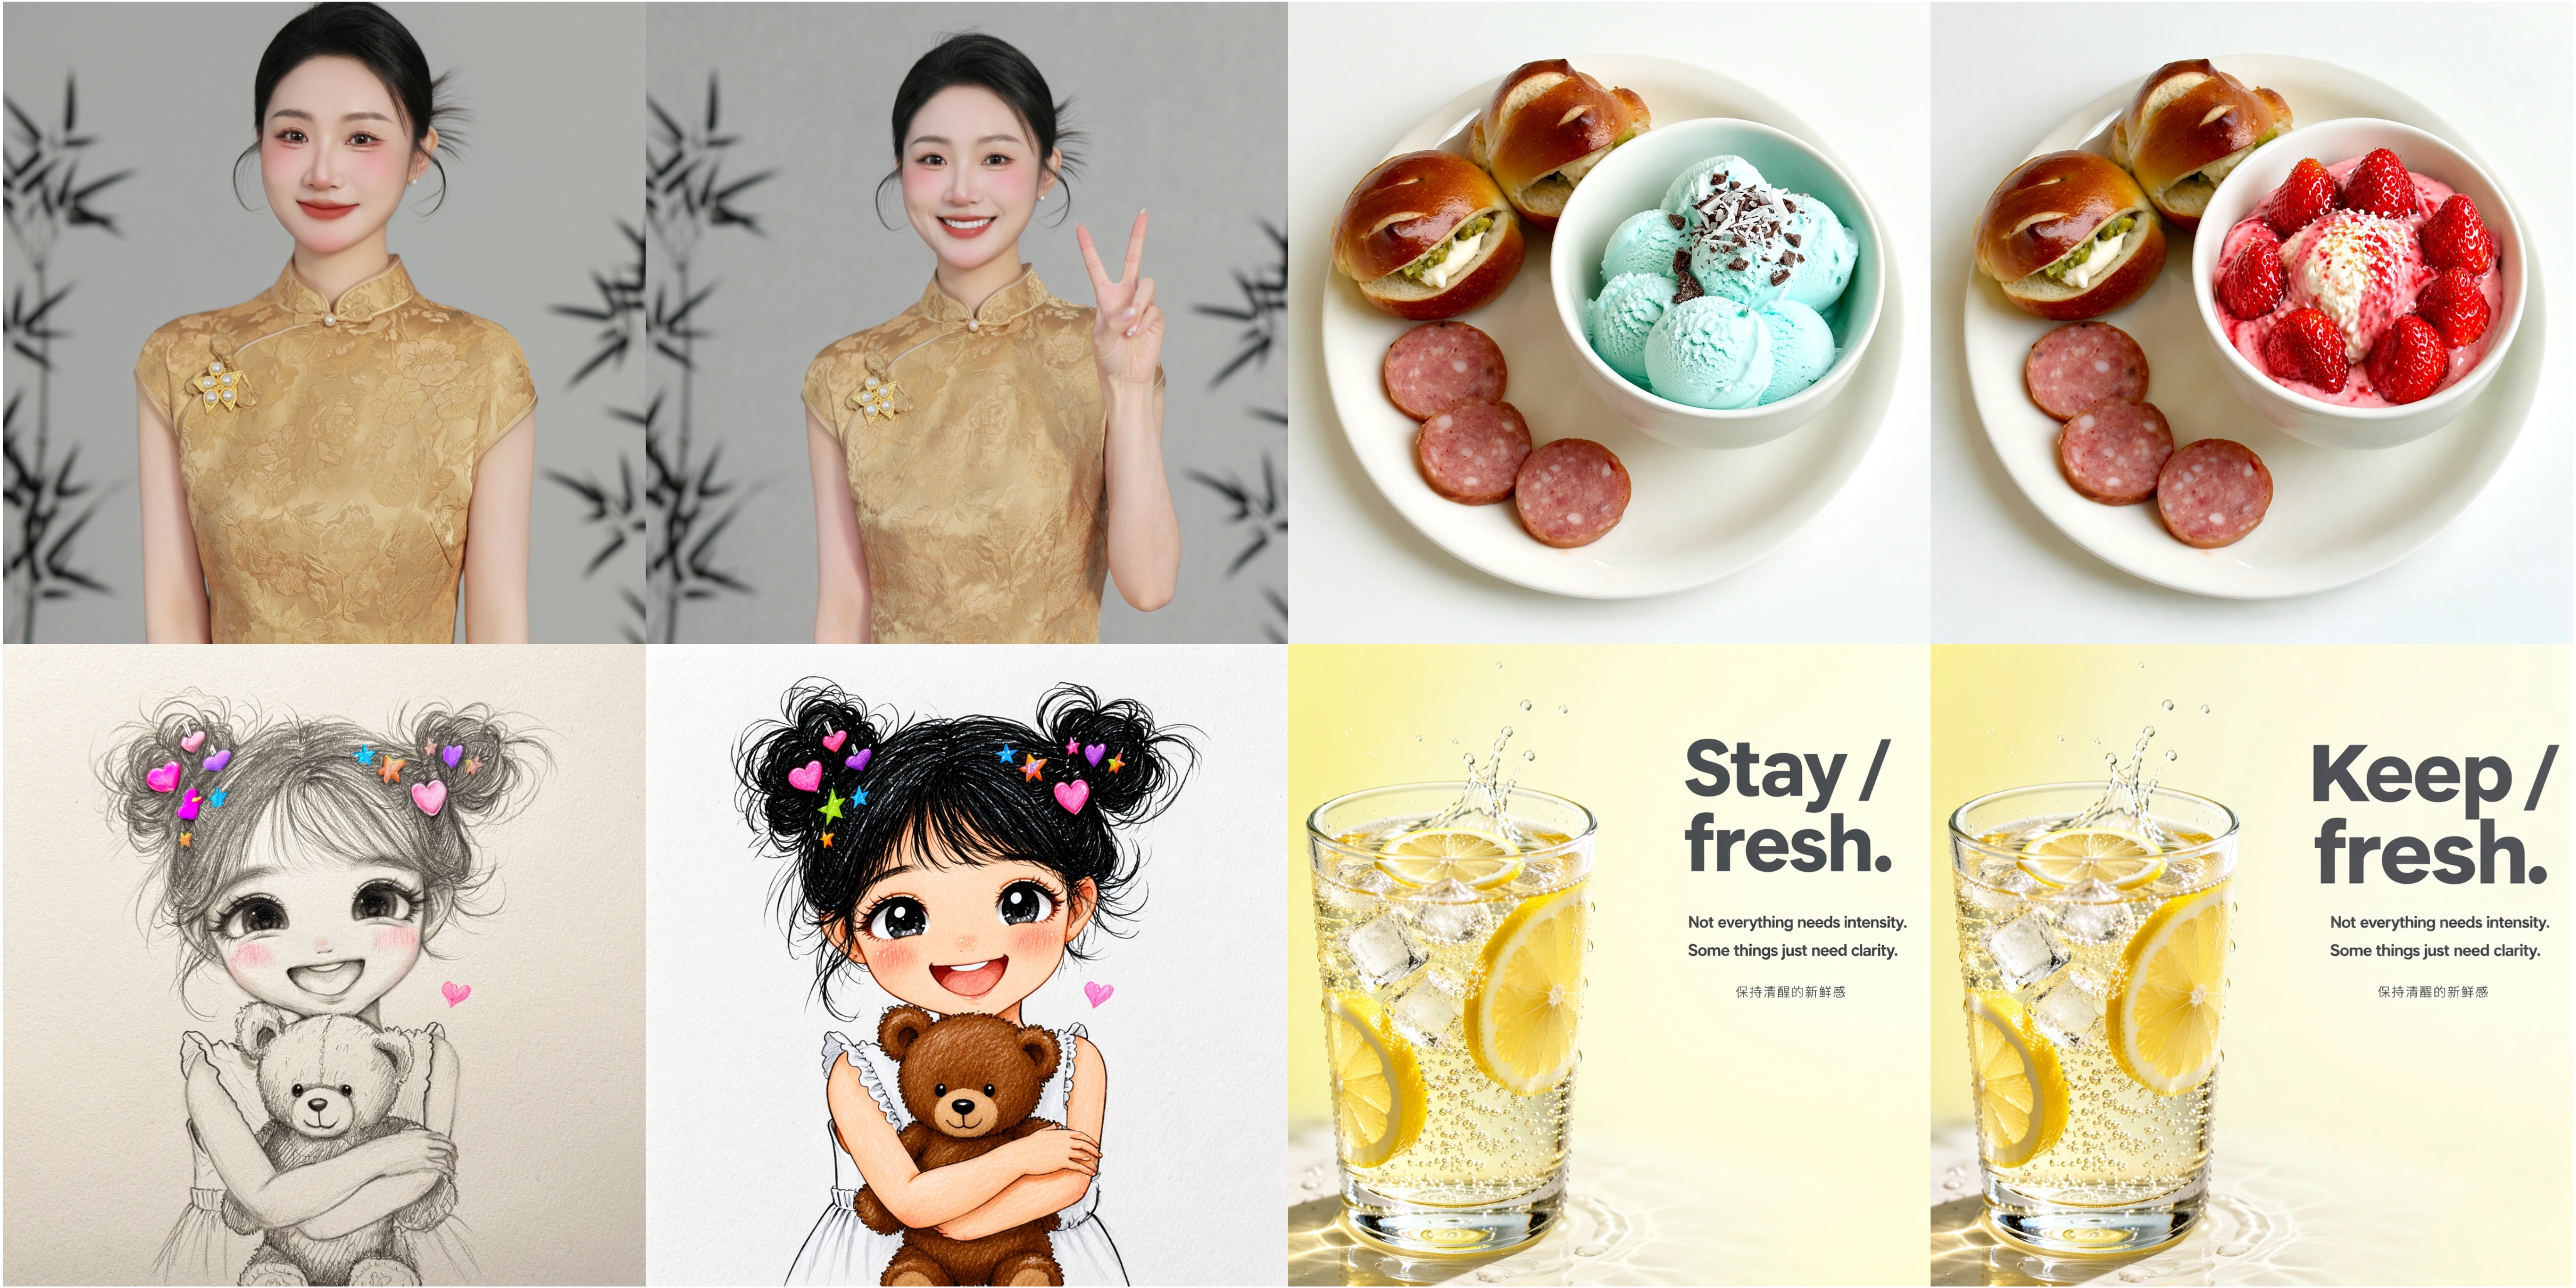
LLaDA-Image realistic image generation showcase
Photorealistic image generation with natural lighting, lifelike details, and coherent scenes.

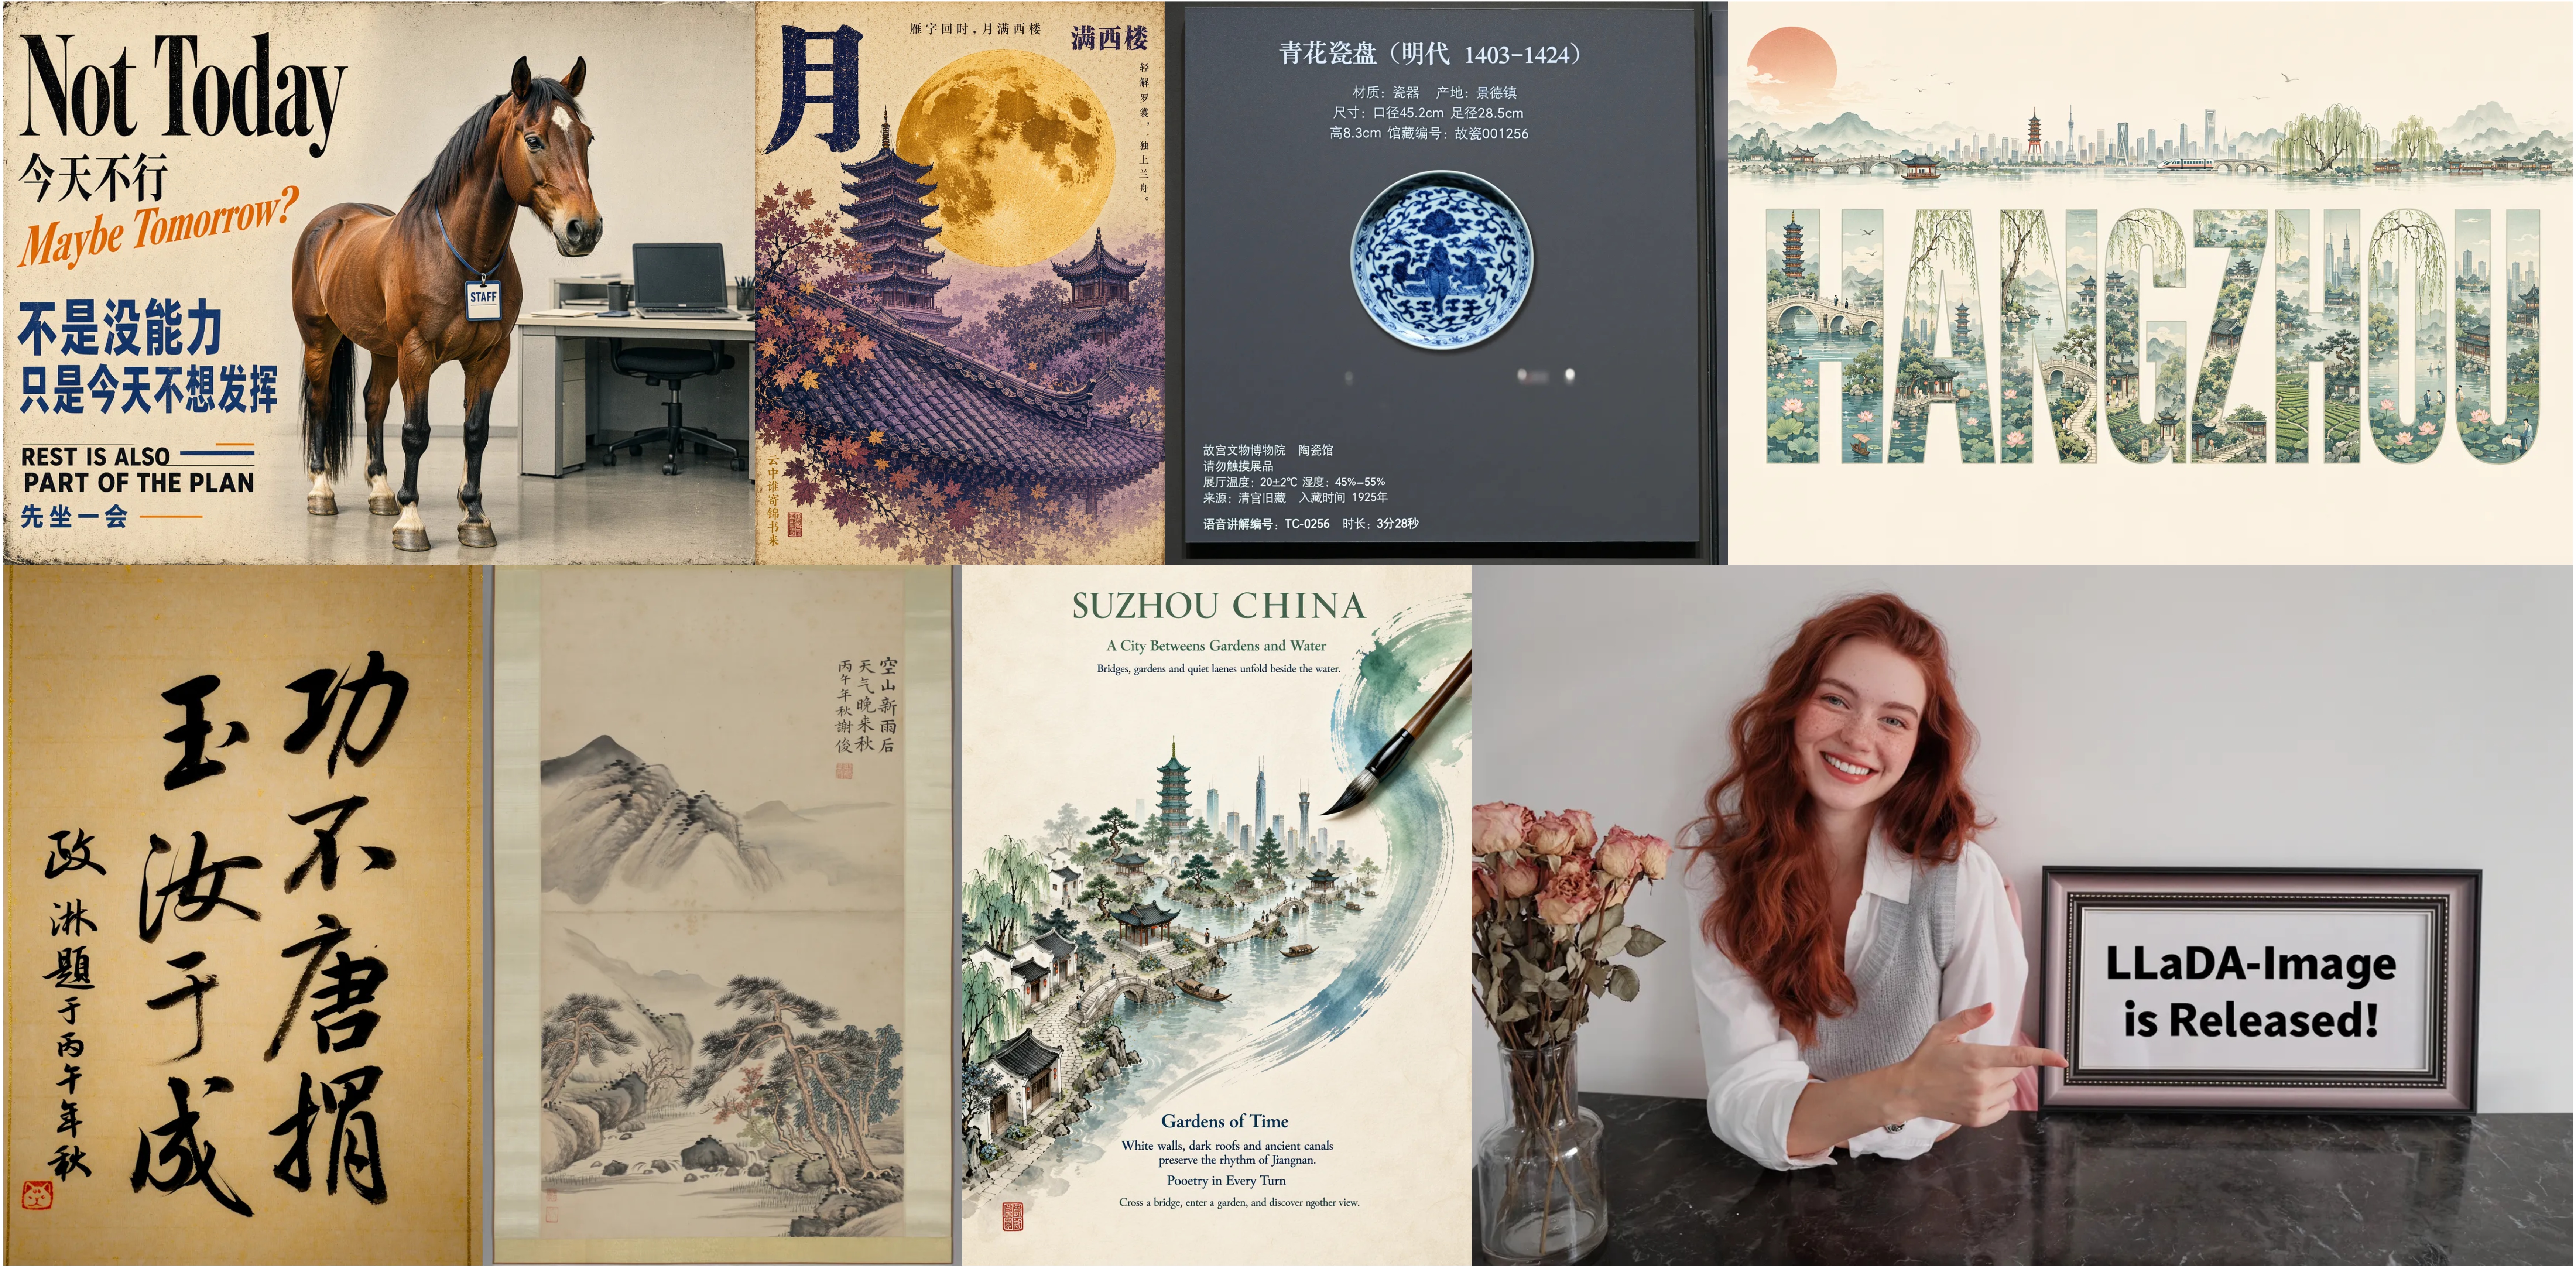
LLaDA-Image text rendering and poster generation showcase
High-quality text rendering and creative poster generation across diverse visual styles.

LLaDA-Image editing showcase
Instruction-guided image editing with faithful content preservation and precise visual changes.

Introduction

LLaDA-Image is a competitive 6B-parameter open-source unified image generation and editing model family. It includes LLaDA-Image, a 50-step Base model for high-quality text-to-image generation and instruction-guided editing, and LLaDA-Image-Turbo, a 4-step distilled model for fast generation and editing. Both variants support practical text-to-image generation, VQ-conditioned generation, reference-image editing, and Chinese--English text rendering.

This repository provides the checkpoints and Diffusers-based inference code for the LLaDA-Image model family.

News

Highlights

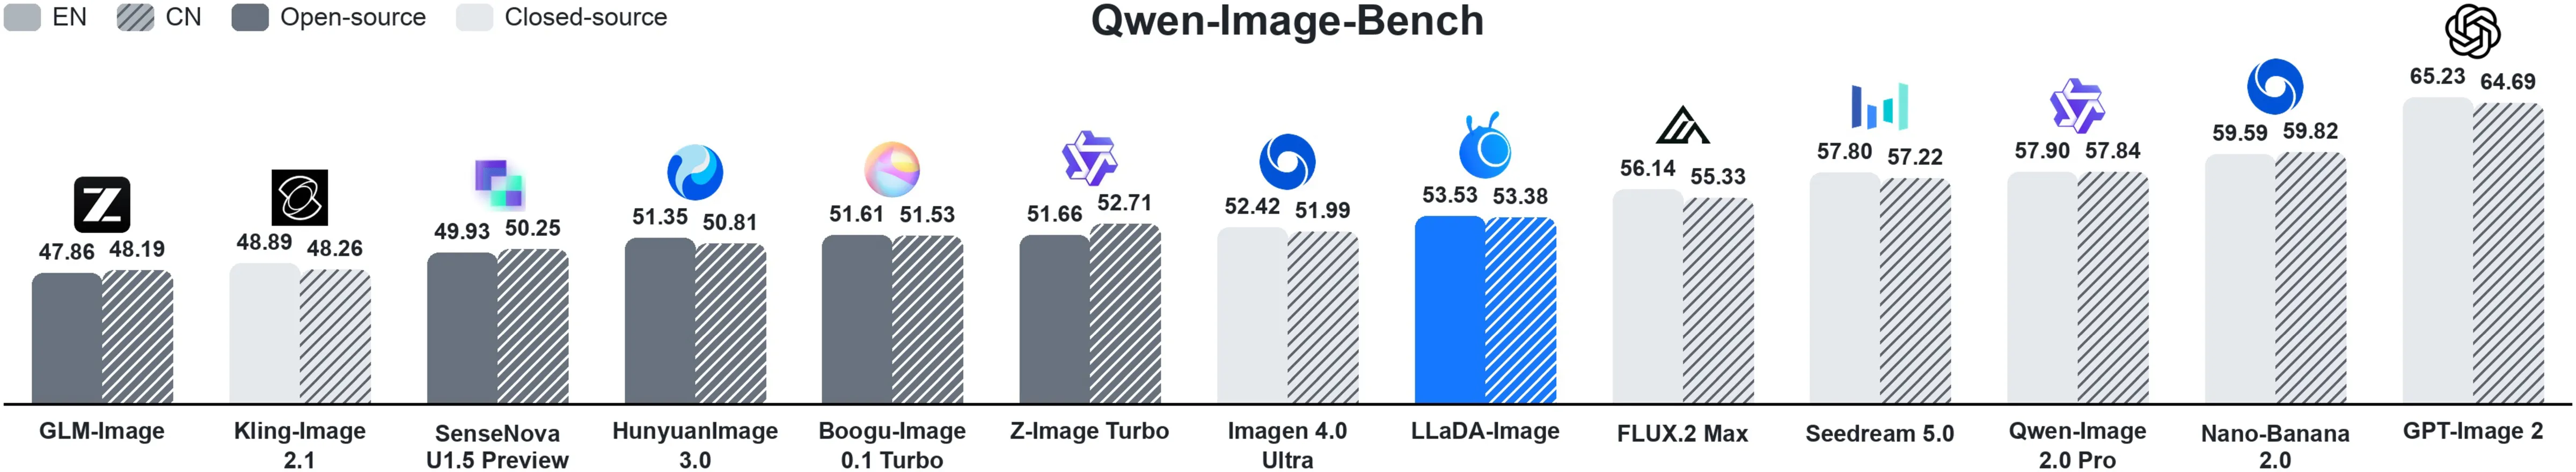
Qwen-image bench evaluation

Model Zoo

Model Description Sampling steps Hugging Face (Checkpoints) ModelScope (Checkpoints)
LLaDA-Image Base model for high-fidelity text-to-image generation and instruction-guided editing. 50 BF16: inclusionAI/LLaDA-Image
FP8: inclusionAI/LLaDA-Image-FP8
BF16: inclusionAI/LLaDA-Image
FP8: inclusionAI/LLaDA-Image-FP8
LLaDA-Image-Turbo Distilled model for fast generation and editing. 4 BF16: inclusionAI/LLaDA-Image-Turbo
FP8: inclusionAI/LLaDA-Image-Turbo-FP8
BF16: inclusionAI/LLaDA-Image-Turbo
FP8: inclusionAI/LLaDA-Image-Turbo-FP8

Opensource Plan

Quick Start

1. Create an environment

The implementation has been used with Python 3.11, PyTorch 2.8, Transformers 4.57.6, and Diffusers 0.39.0.

git clone https://github.com/inclusionAI/LLaDA-Image.git
cd LLaDA-Image

conda create -n llada-image python=3.11 -y
conda activate llada-image

pip install -r requirements.txt

2. Run inference

The pipeline accepts a prompt and, for editing, an optional reference image.

LLaDA-Image (Base)

Use the Base checkpoint for high-fidelity generation and editing. Its recommended sampling configuration is 50 steps.

import torch

from src import LLaDAImagePipeline

# Load the pipeline. The model is downloaded from Hugging Face on first use.
pipe = LLaDAImagePipeline.from_pretrained(
    "inclusionAI/LLaDA-Image",
    torch_dtype=torch.bfloat16,
    device="cuda",
)

# Generate an image.
prompt = (
    "A cinematic photograph of a red fox standing in fresh snow, "
    "soft winter light, detailed fur, shallow depth of field"
)
negative_prompt = ""

image = pipe(
    prompt=prompt,
    negative_prompt=negative_prompt,
    generation_mode="text",
    height=1024,
    width=1024,
    num_inference_steps=50,
    guidance_scale=5.0,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("llada-image-base.png")

LLaDA-Image-Turbo

Use the Turbo checkpoint for fast generation and editing. Its recommended sampling configuration is 4 steps.

[!NOTE] For LLaDA-Image-Turbo inference, you can try setting stochastic_sampling to false in scheduler/scheduler_config.json, which may produce sharper details in some cases.

import torch

from src import LLaDAImagePipeline

# Load the distilled Turbo checkpoint.
pipe = LLaDAImagePipeline.from_pretrained(
    "inclusionAI/LLaDA-Image-Turbo",
    torch_dtype=torch.bfloat16,
    device="cuda",
)

prompt = "A quiet observatory above a sea of clouds at sunrise, golden light, wide-angle photograph"

image = pipe(
    prompt=prompt,
    generation_mode="text",
    height=1024,
    width=1024,
    num_inference_steps=4,
    guidance_scale=1.0,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("llada-image-turbo.png")

Generation modes

Both checkpoints support the following modes. Text and VQ-conditioned generation require height and width divisible by 16; image editing requires dimensions divisible by 32.

VQ-conditioned generation uses the LLaDA2 model to produce image VQ tokens from the prompt, which SigVQ embeds before diffusion. Do not provide an input image in VQ mode.

image = pipe(
    prompt="A quiet observatory above a sea of clouds at sunrise",
    generation_mode="vq",
    height=1024,
    width=1024,
    num_inference_steps=50,  # Use 4 for LLaDA-Image-Turbo.
    guidance_scale=5.0,  # Use 1.0 for few-step inference.
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

Image editing requires a reference image:

from diffusers.utils import load_image

reference_image = load_image("/path/to/input.png")
image = pipe(
    prompt="Turn it into a watercolor painting",
    image=reference_image,
    generation_mode="editing",
    height=1024,
    width=1024,
    num_inference_steps=50,  # Use 4 for LLaDA-Image-Turbo.
    guidance_scale=5.0,  # Use 1.0 for few-step inference.
    generator=torch.Generator("cuda").manual_seed(43),
).images[0]

Acknowledgements

We thank the VeOmni project and its contributors for their valuable open-source work.

Citation

If you find LLaDA-Image useful for your research or applications, please consider citing our work.

@article{LLaDAImage,
title = {LLaDA-Image: Building Strong Image Generators with Fully Open Training Recipes},
author = {Chuyan Chen and Haoxing Chen and Kun Chen and Zhenglin Cheng and Long Cui and Ruishan Fang and Zhangxuan Gu and Zhicheng Huang and Zhenzhong Lan and Yuanting Lei and Haoquan Li and Jianguo Li and Rongchuan Li and Sidu Li and Tao Lin and Deyuan Liu and Jiacheng Liu and Lin Liu and Yuxuan Lou and Zhisheng Lu and Yuxin Ma and Shuheng Shen and Peng Sun and Chaoyang Wang and Hongjun Wang and Xiaomei Wang and Yongxin Wang and Chengzhang Wu and Hongru Wu and Jun Xie},
journal = {arXiv preprint arXiv:2609.03796},
year = {2026}
}

LLaDA-Image (inclusionAI/LLaDA-Image)

Searching Database…

What is this?LLaDA-Image is an open-source 6B-parameter unified model family for high-quality text-to-image generation and instruction-guided image editing, released as a 50-step Base model and a 4-step distilled Turbo model.
Is this a ready-made app, or a model I run with code?It's a set of model checkpoints on Hugging Face/ModelScope paired with Diffusers-based Python inference code — there is no built-in GUI, though community ComfyUI nodes exist for it.
How do I get it running?Set up a Python 3.11 environment matching the stated PyTorch/Transformers/Diffusers versions, download the Base or Turbo checkpoint, and run the Diffusers pipeline with a text prompt (plus an optional reference image for editing).
Any size restrictions when generating or editing images?Yes — text-to-image and VQ-conditioned generation require height and width divisible by 16, while image editing requires dimensions divisible by 32.
Is this meant for casual users or ML practitioners?It's aimed at researchers and developers comfortable running Python and Diffusers pipelines directly, since only checkpoints and inference code are provided, not a consumer app.
What's the difference between the Base and Turbo models?Base uses 50 sampling steps for the highest-fidelity generation and editing, while Turbo is a distilled model trained with Twin-DMD distillation that only needs 2-4 steps for much faster inference.
How good is LLaDA-Image compared to other models?It reports state-of-the-art overall scores on the Qwen-Image-Bench benchmark — 53.53 in English and 53.38 in Chinese.
Can I use LLaDA-Image inside ComfyUI?Yes, community-contributed ComfyUI support for both LLaDA-Image and LLaDA-Image-Turbo, including an FP8 version, is available per the project's news updates.
Is training code available?Not yet — only inference code and model weights have been released so far; training code is marked as 'coming soon' on the open-source roadmap.
Size
14.6 MB
Stars
261
Updated
CommitSep 07
Age
1mo
Commits · 90 Days
